Category: Doin’ DevOps

  • SauceCon Speaker Profile: Titus Fortner

    SauceCon Speaker Profile: Titus Fortner

    This is the third in a series of articles highlighting speakers at SauceCon 2019. SauceCon brings together the global community of Sauce Labs users and continuous testing experts to learn from each other and level up their automated testing and continuous delivery skills. This year’s event will be held April 23-25 in Austin, Texas.

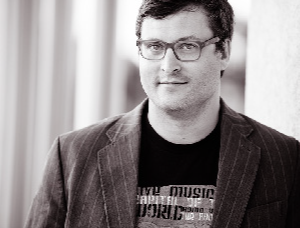
    The old adage says, “Third time’s a charm.” When it comes to SauceCon speaker Titus Fortner, the cliche proves true: Testing is his third career. Titus first went to the Naval Academy, studied nuclear engineering and became a submarine officer—traveling the world doing everything from launching ballistic missiles to helping automate and streamline communication among the senior staff of the commanding general in Iraq. When he left the Navy, Titus went back to school for a year to learn computer science, then got a job as a junior developer at a startup. Focusing on test automation was an accident, but the influence testing had on the overall system and process was immediately appealing to him.

    Titus then became a core contributor to the Selenium project and the project lead for Watir, an open source testing library built on top of Selenium, as well as numerous other testing related Ruby gems. He also implemented automated testing solutions at five different companies before joining Sauce Labs as a Senior Solutions Architect. Today, he works closely with customers to help improve their testing practices.

    At SauceCon 2019, Titus will present, “Page Objects: You’re Doing It Wrong.” Although Page Objects enable newer users to write sophisticated tests against an application, Titus has found that the Page Object Pattern is often misused. “There are lots of different ideas on what makes a good implementation, and I’ve actually tried most of them at one point or another and have personal experience that informs my recommendations of certain approaches over others,” he said. “Smart people disagree with me on some of these, and my goal at SauceCon is to present both sides while explaining my reasons for the preferences I have.”

    When he isn’t convincing customers how to better use Page Objects, Titus reads, writes open source code and takes day trips with his blind dog who loves car rides.

    You can hear from Titus and more than 30 other expert speakers at SauceCon 2019, the third-annual Sauce Labs user conference. To see a full list of presentations or to register, visit the SauceCon website.

    — Rebecca Cramer

  • Survey Sees Need for More Consistent Approaches to DevOps

    Survey Sees Need for More Consistent Approaches to DevOps

    DevOps is arguably one of the most disruptive forces driving transformation of IT processes in recent memory. But a new survey finds that while IT organizations are making progress, adoption of DevOps processes remains uneven at best.

    A survey of 2,419 IT professionals conducted by OverOps, a provider of code analysis tools, finds that 82 percent of organizations have partially adopted DevOps practices, while only 17 percent of respondents claim to have fully adopted DevOps. Obviously, not every workload requires an organization to embrace DevOps processes to manage it.

    But OverOps CTO Tal Weiss said the survey shows that as organizations increase the rate at which application workloads are being deployed, a fair amount of chaos is starting to reign. According to the results, more than 90 percent of companies deploy code at least once a month, and more than 60 percent release code at least once every two weeks. Nearly 40 percent, however, indicate that moving too quickly is a primary reason errors make it into production.

    Worse yet, more than 50 percent say they rely on customers to tell them about errors in production, even though 60 percent of respondents say they use automated tooling for error notification and to ensure application quality.

    Not surprisingly, IT teams are still spending an inordinate amount of time troubleshooting their environments. More than a quarter of respondents say they still spend at least roughly one full workday per week troubleshooting errors. Another 42 percent of respondents spend 10 percent to 20 percent of their time troubleshooting.

    The good news is that IT is increasingly being viewed as a team sport. A full 67 percent of respondents believe their entire team is to blame when an application breaks or has an error, and 73 percent said both developers and operations are equally accountable for ensuring the overall quality of an application.

    Weiss said more organizations need to implement a more structured approach to DevOps based around the same continuous integration/continuous deployment (CI/CD) platform. Too many organizations today are adopting DevOps processes from the bottom up when it’s become clear that top-down initiatives for driving consistent adoption of best DevOps practices are now required. One of the biggest challenges facing IT leaders, however, is identifying and implementing the metrics that will be employed to identify those best practices, he said.

    Change, of course, comes hard to any IT organization. It may take IT organizations years after acquiring new tools to define their processes. Inertia surrounding existing waterfall and ITIL-based processes can be incredibly high. But as the amount of software that needs to be deployed and updated continues to increase, risk levels associated with deploying applications also are starting to increase. Many organizations are now essentially experimenting on their end customers. How much tolerance customers have for trial-and-error approaches to applications development and deployment remains to be seen. In the meantime, IT organizations would be well-advised to resolve to do DevOps better in 2019.

    — Mike Vizard

  • 9 Pillars of Continuous Security Best Practices

    9 Pillars of Continuous Security Best Practices

    Without proper consideration given to security best practices, the continuous delivery of software changes facilitated by DevOps is risky. On the other hand, DevOps provides an opportunity to reduce security risks if security is integrated into the continuous delivery pipeline according to best practices.

    This blog enumerates best practices for security across nine pillars of DevOps: Leadership, Collaborative Culture, Design for DevOps, Continuous Integration, Continuous Testing, Continuous Monitoring, Elastic Infrastructure, Continuous Delivery/Deployment and Continuous Security. Examples of best practices for each pillar are listed. These practices can be used to assess an organization’s maturity within the journey to Continuous Security, often referred to as DevSecOps.

    Leadership

    Leaders need to understand and sponsor a clear vision for security.

    • Leadership demonstrates a vision for organizational direction, team direction and three-year horizon including security practices.
    • Leaders intellectually stimulate the team status quo by encouraging asking new questions and question the basic assumptions about the work including security practices.
    • Leaders promote personal recognition by commending teams for better-than-average work, acknowledging improvements in the quality of work and personally compliment individuals’ outstanding work including security practices.

    Collaborative Culture

    Culture in organizations that work well with DevOps have a collaborative continuous security mindset.

    • The culture encourages cross-functional collaboration, shared responsibilities and avoids silos between developers, operations, project management, quality assurance and security.
    • The DevOps system (toolchain) is created by an expert team and reviewed by a coalition of stakeholders including security.
    • Changes to end-to-end DevOps workflows are led by an expert team and reviewed by a coalition of stakeholders including security.
    • DevOps culture empowers and trains team members to take personal responsibility for security, compliance and privacy obligations.
    • Security engineers/architects are involved in the design for modular components, and also consulted when security patterns change within modules.

    Design for DevOps

    Designing software for DevOps at speed requires application designers to master the best practices for continuous security.

    • Software source code changes are pre-checked with static analysis tools, prior to commit to the integration branch. This assures that the modified source code does not introduce critical software faults and security vulnerabilities such as memory leaks, uninitialized variables, array-boundary problems and SQL injection.
    • Software component analysis scans third-party components for known security vulnerabilities and identifies risk during the build process.
    • Security frameworks for technology stacks that are used (such as Apache Shiro or Spring Security) are documented and shared with developers for their respective technology stacks.
    • Software code changes peer code reviews include checks for defensive coding and security vulnerabilities prior to committing code to the integration/trunk branch.
    • Common security components such as identity, authorization, key management, audit/log, cryptography, protocols, etc. are maintained, published, readily available and used within module development.

    Continuous Integration

    Continuous integration (CI) within organizations that have multiple teams working concurrently on a project and different code bases is challenging. During the integration stage it is critical to assess the application and understand the impact of code changes from a security point of view.

    • A software version management system is used to manage versions of all changes to source code, executable images and tools used to create and test the software.
    • Incremental static analysis pre-commit and commit checks are wired into CI to catch common mistakes and anti-patterns quickly by only scanning the code that was changed. These checks identify security vulnerabilities through control flow and data flow analysis, pattern analysis and other techniques. These techniques find security-related issues such as mistakes in using crypto functions, configuration errors and potential injection vulnerabilities.
    • Binary artifacts are digitally signed and stored in secure repositories.
    • Changes to security patterns used within software source such as session management, authentication, authorization and encryption code trigger a notification or pull request to security engineers.

    Continuous Testing

    Continuous testing (CT) with DevOps has significant advantages for continuous security when best practices are followed.

    • New security tests that are necessary to test a software change are created together with the code and integrated into the trunk branch at the same time the code is. The new tests are then used to test the code after integration.
    • Security tests for each DevOps pipeline stage are automated and may be selected automatically according predefined criteria.
    • Release regression tests include security tests. At least 85 percent of the security regression tests are fully automated and the remaining are auto-assisted if portions must be performed manually.
    • Test results that indicate possible security concerns are tagged for security analysis.
    • Dynamic or interactive application security tests exercise the application for security vulnerabilities. Results of these tests are delivered to developers through tools and feedback loops native to their organization.
    • If containers are used, image repositories are scanned for images with known vulnerabilities, hash checks for image drifts and run-time checks for vulnerabilities during image deploys.
    • Attack patterns, abuse cases and tests are built for application module profiles.
    • Unit, functional and integration tests around—and especially outside—boundary conditions are run during CT. Tests include error handling, exception handling logic and negative tests.
    • Automated security attack testing to include the OWASP Top 10 in integrated into automated testing.

    Continuous Monitoring

    Continuous monitoring (CM) of security considers the dynamic nature of artifacts and infrastructure and a proliferation of objects and services to secure.

    • Metrics and thresholds are automatically gathered, calculated and made visible to anyone on the team that subscribes to them. Example security metrics include:
      • Number of security defects identified pre-production
      • Percent of code coverage from security testing
      • Number of failed builds due to security checks
      • Mean time to detection
      • Mean time to resolution
    • Vulnerability information in consolidated to provide a comprehensive view into vulnerability risks and remediation across tools, pipelines and apps—and over time.
    • Metrics and events from production security controls such as WAF, RASP, etc., are used to improve security testing.
    • Insight into security threats and events are shared and visible across DevOps teams to enable “attack-driven defense” methodologies.

    Continuous Security

    Continuous security (CS) is itself a distinct pillar with standalone best practices that cross all of the other pillars.

    • All information security platforms that are in use expose full functionality via APIs.
    • Immutable infrastructure mindsets are adopted to ensure production systems are locked down.
    • Security controls are automated so as not to impede DevOps agility.
    • Security tools are integrated into the CI/CD pipeline.
    • Source code for key intellectual property on build or test machines are only accessible by trusted users with credentials. Build and test scripts do not contain credentials to any system that has intellectual property.
    • External penetration tests (done out of band) are scheduled either periodically or on a regular cadence are used to perform deep-dive analysis.
    • Telemetry from production security controls such as WAF and RASP are delivered back to development teams to inform application updates.
    • Accurate inventory of all software packages and version information is documented via infrastructure as code. Automated detection is used to identify whether any of the packages have known CVEs associated and define specific remediation actions.

    Elastic Infrastructure

    Elastic infrastructure environments offer advantages compared to legacy or traditional static infrastructure. However, elastic infrastructures need to follow best practices for continuous security because flexible infrastructures offer a broader range of attack surfaces.

    • Configuration code includes automated checks including:
      • Ensuring unnecessary services are disabled and only ports that need to be open are.
      • Permissions on files, audit and logging policies are enforced.
      • Development tools are not installed on production.
    • Security-approved OS, software versions and frameworks are used to compose required infrastructure. Security-related controls such as ACLs and FIM are defined as a part of infrastructure where applicable.
    • A least-privilege model is enforced for processes running on shared infrastructure.
    • Smaller clusters are used to reduce complexity between teams.
    • Service provider partners security controls are validated to ensure they meet business requirements in their domains of the shared security model.
    • IaaS or PaaS service provider security controls are validated to ensure that they meet business requirements in their domains of the shared security model.

    Continuous Delivery/Deployment

    While DevOps enables new feature deliveries to users quickly, to minimize risk during deployment the following best practices are important:

    • Release-to-production decisions are determined according to predetermined metrics, which include security metrics.
    • A whitelist policy for application segmentation is enforced during deployment for each environment, especially production.
    • Continuous deployment processes trigger run-time security and compliance checks including:
      • Ensuring unnecessary services are disabled and only ports that need to be open are.
      • Permissions on files, audit and logging policies are enforced.
      • Verify development tools are not installed on production.
    • All secrets used for deployment are vaulted and retrieved programmatically during run-time or initialization of the continuous delivery process.

    In this article we detailed best practices for nine pillars of continuous security, otherwise known as DevSecOps. While is it clear that DevOps offers immense value for software deployment, the adherence to best practices is essential to reduce risk and assure security. Each organization is different and has different security postures. The specific practices, security tools and metrics that are appropriate may vary according to a risk assessment for each organization.

    Aggregation of end-to-end security metrics, from planning through to operations, is important but beyond the scope of this blog. End-to-end security monitoring tools, such as value stream management applied to DevSecOps and enterprise security dashboards, is a topic that we intend to cover in a subsequent blog.

    This article was co-authored by Imran Chaudhari. Imran is a principal security consultant at Trace3, where he assists clients in assessing and designing cybersecurity initiatives from a strategic, organizational, and technical perspective. His experience covers expertise in secure software development, application and cloud security, as well as identity and access management and DevSecOps assessments.

    — Marc Hornbeek

  • DevOps and Agile: Your New Year’s Resolution

    DevOps and Agile: Your New Year’s Resolution

    Don’t apply Agile principles to DevOps. That’s not how it works.

    We in the west often celebrate the new year with a promise to do more or less of something in the coming year. While these promises are often broken, they can occasionally be transformational.

    And it’s time your organization had a transformational one: More DevOps, less Agile++.

    It is still a pervasive issue that people look at the successes of Agile development and attempt to apply them to the operations side. That’s not how it works. Really. There is a fundamental difference between DEVops and devOPS that means what is perfect for one is terribly imperfect for the other.

    While having a developer who specializes in the language du jour is important for a DevOps project—just like having a systems administrator that is proficient in given platform X—that really is where the similarity ends.

    Operations is a daily thing. It takes specialized knowledge and uses it to keep systems purring along on the chosen platform with vendor X, Y and Z. For a lot of organizations, storage has moved to the cloud. For a lot more it has not, and there is a difference there. But in the end, management of that massive blob of storage falls on your storage specialists. If your environment is internal, they’re worried about hardware and software both, but even if you’ve taken a massive leap to the cloud they have access and backup and hierarchy concerns.

    And given our worry about virtualization sprawl, a large number of organizations seem to have pitched that out the window when cloud and DevOps came along. Those instances still need monitoring and management, even if some of it is automated. In fact, the growth in numbers pretty much negates the automation goodness.

    So take a close look at the devOPS side of your operation. Think about it. Include it in DevOps from the start, rather than applying Agile principles to a group that it just doesn’t fit well. We’ve (mostly) gotten past the “Developer is Kingmaker” mentality, and have started to reintroduce standards so that we don’t have 50 different database products to support. But far too many have yet to truly approach DevOps as an integrated whole that relies on the wisdom of operations—even though operations is going to be involved with this project far longer and more intimately than development.

    And they are disparate functions. DevOps makes getting to market and maintaining the application far more streamlined, but when it comes down to it, 90-plus percent of you aren’t keeping a java developer watching an application for life. They’re moving on to the next project, and operations is left with more of development’s input and advice than previously, but all of the responsibility.

    So step up, apply DevOps in the manner it makes sense for a given bit. If you are running DevOps on VMware, operations input will be different than if it is on physical servers or public cloud or private cloud. Take that input and develop around it. Personally, I’m a fan of application release automation (ARA) for achieving the melding, but however you do it, don’t say, “We’re DevOps,” and mean, “We’re going to wedge Agile into the entire org,” anymore.

    And have a great year! Here’s to more apps, more responsiveness and more security!

    — Don Macvittie

  • What To Do When Your DevOps Initiative is Failing

    What To Do When Your DevOps Initiative is Failing

    These days, it is difficult to find someone who hasn’t heard of DevOps. Statistics show that in 2017, just 6 percent of developers worldwide had never heard of it, and in 2018 this number decreased to 3 percent. You have to wonder who these 3 percent of developers are!

    Companies have been embracing DevOps initiatives with two core objectives: to reduce their time to market by delivering and deploying software faster, and to receive quicker feedback from customers. Many of these implementations have been successful. However, undertaking DevOps requires a major shift in terms of an organization’s culture and mindset, and companies often face difficulties.

    I want to examine some of the common challenges we see organizations facing and provide some best practices for overcoming them.

    Why do DevOps Initiatives Fail?

    Some of the core reasons DevOps initiatives fail include:

    • Not spreading a DevOps culture across the entire organization.
    • Choosing the tools without conducting research about what they do and evaluating whether they are a fit in your organization.
    • Setting unrealistic goals.
    • Trying to apply the same recipe that other companies have.
    • Not training your people.
    • Implementing a hybrid approach to DevOps where you attempt to keep your old culture.

    DevOps Initiatives Require Time and Patience

    Measuring your goals and monitoring your progress are the only ways to detect early warning signs that your DevOps initiative is not living up to expectations. But it’s important to note that patience is also required, as in most cases you will not achieve your objectives straight away.

    Getting to a full DevOps environment is not easy, particularly in large organizations, which are used to having siloed structures in their development process. So, start from the bottom up. Establish small goals that should be achievable, such as increasing the unit test coverage, improving the automation suit, reducing the time from code-commit to testing-ready. Measure these and use the results as possible warning signs or alert signals.

    There are also a series of steps you can take to put an initiative back on course. First, re-evaluate the process or processes you are having difficulties with and evaluate if:

    • The right metrics have been set and you are monitoring them.
    • The people applying the initiative are engaged with the DevOps culture, particularly if they are in different areas.
    • You have chosen the right tools.

    The Entire Organization is Responsible for Achieving DevOps Success

    In DevOps, the whole organization should be responsible if the DevOps initiative fails. There shouldn’t be one DevOps department or one person in charge of it; DevOps should be adopted by everyone, following the same path as Agile development. After all, they complement each other.

    Those companies that have successfully implemented DevOps have developed a strategy that fits the specific needs and demands of their organization. Although I’m currently mentioning some strategies that help companies achieve success with their implementation, there is no “magic” DevOps formula. A common mistake companies make when trying to fix a sub-par DevOps initiative is to simply copy what other companies do. Most of these companies end up abandoning the initiative because the outcome is not what they expected.

    Finally, if you’re planning to start implementing DevOps, keep in mind that it’s a process in which technical tools are as important as spreading a new culture based on collaboration, multidisciplinary, autonomy and open-mindedness. As this article points out, in many cases, the blockers to achieving success with DevOps are human, not technical.

    — Gabriel Vasquez

  • Should Your Company Hire Remote Full-Stack Developers?

    Should Your Company Hire Remote Full-Stack Developers?

     Is your company seeking to hire a qualified full-stack developer? It seems like an easy enough task—create a job listing, read resumes, conduct technical interviews and make the hire. Finding engineers who understand every layer of the stack is difficult, however. Companies compete for the best and brightest full-stack developers and, unfortunately, they are in shockingly low supply.

    What’s the solution? One way to circumvent the full-stack developer talent shortage is to leverage telework. By seeking to hire remote full-stack developers, you can gain to a global pool of talent.

    There are many other benefits to hiring remote full-stack developers. However, hiring remote developers isn’t always the right fit. Read on to see if your company is ready to hire remote full-stack developers.

    Is Your Company Looking to Save Money on Office Space?

    Hiring remote full-stack developers is a major decision. When companies think about utilizing remote talent, they usually think of the headache of adopting a new form of work and of managing employees who work out of the office. However, it is also important to note one of the major benefits of leveraging remote developers: the cost savings.

    Other benefits to consider: boosted productivity, higher workplace satisfaction and lower incidences of interpersonal issues between coworkers. If you believe your company might be able to benefit from hiring and managing full-stack developers remotely, then you may want to consider beginning your hiring journey seriously.

    Does Your Company Prioritize Quality or Community?

    Finding the top full-stack developers can be extremely difficult. By opening up your search and tapping into global talent by seeking developers looking for remote work opportunities, you can put a greater emphasis on quality and technical excellence.

    If your company is more focused on creating a cohesive community or company culture, you may want to focus on hiring full-stack developers that can come into the office, interact with coworkers and build a rapport with managers, clients and fellow developers.

    However, this isn’t to say that it’s impossible to foster caring and authentic professional relationships with remote developers. It may simply prove more challenging.

    Are You a Brick-and-Mortar or a Click-and-Mortar Company?

    If you run a traditional brick-and-mortar organization that’s been around for a while, it may be more difficult to adjust to change. If you run an online business or if you’re a burgeoning small business or startup that is heavily reliant on tech, then it may be significantly easier for you to adopt telework.

    If you do run a traditional business with a traditional office and traditional approach to project management, it may take a bit of adjusting to accommodate for remote workers.

    You may want to try out remote work in a trial capacity by bringing on remote freelancers or allowing current full-time developers to work from home for a few days out of the week. If you find your company easily adjust to the changes, then you may want to consider hiring fully remote full-stack developers as well.

    Do You Want to Access Global or Local Full-Stack Development Talent?

    As mentioned earlier, full-stack developers are in incredibly high demand. Unless your business is headquartered in a major city, it’s going to be next to impossible to find the top full-stack developers. If your company is just starting or simply short on cash, then it can be difficult to bring on such an expensive full-time employee as well.

    If you want access to global talent, you’ll need to open up to remote work. Through telework, even companies in small cities and towns can gain access to top talent. If you’re more interested in fostering local talent, however, you might not be interested in leveraging telework.

    Conclusion

    Hiring remote full-stack developers isn’t always a simple process. It requires your company to remain open, adaptive and innovative. Without these traits, managing remote full-stack developers will prove challenging to say the least.

    How can you ascertain if your company is ready to bring on remote talent? First, it’s important to assess how much cost savings, boosted productivity and higher workplace satisfaction rank for you. In addition, it’s important to gauge whether  community outweighs the desire for the production of quality code.

    Finally, you’ll want to access your technological readiness and ability to adapt. Are you willing to search for global talent and leverage technologies, platforms and software programs that will assist you in this endeavor? If so, you may want to consider hiring remote full-stack developers.

    — Tania Brooks

  • What DevOps Can Learn from High Reliability Organizations

    What DevOps Can Learn from High Reliability Organizations

    High reliability organizations are organizations that work in areas that are very hazardous or complex, and yet manage to have a lower accident rate than what would be normal for that environment. So what can DevOps and DevOps practitioners learn from the research of high reliability organizations?

    David Woods and Sidney Dekker both have done great research on resilience engineering and high reliability organizations. They continually emphasize, “Safety is not something an organization is. Safety is something an organization does.”

    The first thing that DevOps practitioners can learn from high reliability organizations is that safety is not a sterile environment with no dangers or no hazards. Research into these organizations shows that safety is actually the presence of things that help manage or mitigate risk, such as systems, people and thought processes. For DevOps organizations, these could be a trusted CI/CD system, automated testing or a code review process that involves a larger portion of the organization early (such as infosec).

    Research shows that complex systems can’t be said to be safe merely by their component-level reliability. For instance, if you take one part in the system, such as a fan in a car, and this fan is performing exactly as you expected, that doesn’t mean the overall system is safe.

    Complex technological systems have developed to a degree where what used to be possible in looking at these components and putting them together in a safe system now creates an environment where the interactions between these components and their effects still potentially can be unsafe. Of course in our context, unlike nuclear power or aviation, our accidents are typically with software systems. From a financial perspective or a job or livelihood perspective, these accidents are potentially no less significant.

    Another lesson that DevOps can learn from HRO is not taking past success as a guarantee of future safety. Research has shown that even if you feel very confident in your training or in the tooling that you’re using, the people at the controls still need to look for signs that you could be overconfident or your confidence is misplaced.

    This might happen when you find yourself saying, “Well, we’ve done a deploy like this a million times. It will be fine.” That’s probably a good attitude from a morale perspective, but it would be a mistake: Although it looks like a task or project you’ve done before, there could still be risks involved. There’s a difference between assuming there’s no or very little risk and confidence that you could manage it and have practiced managing it and are still aware of those risks.

    The next lesson that can be learned is to not create differences where they don’t apply. Research has shown that people tend to see incidents in other organizations or other departments of the company as not applicable to their area. They’re far away. They’re different and have different restrictions. They have a different operational environment with different people operating them. It’s tempting to dismiss the potential learnings that are raised there, but organizations that want to increase their resilience and reliability purposely look deeper into the underlying patterns in those incidents and try to learn from the parts that do apply to them, as opposed to focusing on how different that other is.

    When investigating issues or problem-solving, people must have ways to communicate and share information freely as well as update their mental model of how the system works to avoid fragmented problem-solving. If instead, silos are enforced across an organization (regardless of how or where these artificial boundaries are drawn), then there is a high risk that with no one person or group will be able able to notice if the system design slowly trends away from safety.

    Fresh perspectives and diversity on teams matter. Research into high reliability organizations proves that people from different backgrounds who have different viewpoints actually generate more theories regarding why something might or might not work. They end up mitigating more risk situations, reveal more things that might be previously a hidden assumption and allow for minority viewpoints. These points of view also can provide new information or reveal pre-existing hazards that no one was looking at.

    We need to narrow the gap between how practitioners operate the system and how management imagines the system to be. The more accurate the non-practitioner view, the easier it is for those people—whether management or other stakeholders—to make decisions that help create safety.

    Most organizations typically don’t change until there’s some huge amount of evidence that says they should. This is usually something such as an incident, a disaster or an accident of some sort. If we continue that pattern, these organizations are always learning too late. By applying some of these resilience and high reliability organization principles to our practice, we’re able to move this learning forward and change earlier—and not have to incur the high costs for that learning.

    — Thai Wood

  • Cisco Looks to Build DevOps Community

    Cisco Looks to Build DevOps Community

    Cisco Systems is making a concerted effort to create an era of détente between networking professionals and the rest of the IT operations teams that have embraced DevOps practices.

    Susie Wee, senior vice president for the DevNet community at Cisco, said the goal is to provide network operations (NetOps) teams the skills required to programmatically expose a range of self-service capabilities to developers.

    At the same time, Cisco is encouraging developers to deploy applications directly on routers and switches that now incorporate general-purpose processors. Those processors would run applications in a way that significantly reduces network latency, while the custom ASICs that Cisco develops would continue to handle all the networking functions.

    Wee said that dichotomy is now driving Cisco to classify two classes of developers within its DevNet community. The first is aimed at traditional application developers and the second community is more focused on managing infrastructure as code.

    Cisco is now extending that latter initiative into the realm of software-defined wide area networks (SD-WANs). The company has added integrated firewall, intrusion prevention and URL-filtering technologies to its SD-WAN platform. In addition, there are code samples, videos, learning labs and sandboxes available on Cisco DevNet that are intended to make easier to learn how to programmatically manage Cisco SD-WANs using open application programming interfaces (APIs).

    Cisco claims to now have 530,000 developers participating in DevNet. One the one hand, the company is trying to entice NetOps teams that have been reluctant to give up legacy command line interfaces to modernize their networking environments. On the other hand, Cisco is trying to attract more application developers who increasingly find themselves encountering latency issues as they move to deploy applications in highly distributed computing environments, such as an Internet of Things (IoT) application.

    Over time, Cisco and other providers of network operating systems also will be moving away from monolithic architecture to embrace microservices, which would make it possible to programmatically invoke networking services on a more granular level.

    Of course, there may be some developers who would prefer to programmatically take control over networking along with the rest of the IT infrastructure. But Cisco is clearly betting most organizations will want to make it easier for their NetOps and DevOps teams to work more closely together. Today, most enterprise IT organizations can spin up a virtual machine in a matter of minutes; provisioning the network connections to that virtual machine, however, is still measured in days and weeks.

    Other networking infrastructure companies besides Cisco have realized the need to make networking more programmable. But in terms of the resources the company is making available to solve that problem, it would appear to ready to make a significantly larger commitment.

    — Mike Vizard

  • Back to DevOps School: What Tools are in Your Backpack?

    Back to DevOps School: What Tools are in Your Backpack?

    The 2018-19 school year is in full swing, and just like the kids are going to the bus stop with their new backpacks and shoes, it’s time to refresh your DevOps tool chain and look to the future. Remember, just like education, DevOps never ends. It’s a lifetime pursuit that constantly improves your life.

    The DevOps tool chain of the future must include:

    Trunk Releases

    Time to get your branch and merge skills down pat. Git is the best source code control to offer this to development teams. Companies should be actively moving to git to allow their development teams isolated feature development with pull merges and pushes to the trunk for releases.

    If you are not using git, it’s time to start justifying why you are not. Given the speed at which businesses are moving, it is time eliminate blockers for development to release features. Git is built for speed and large numbers of dispersed developers. Remember: it was built by Linus Torvalds to support Linux kernel development.

    Database Development Tools

    When planning for your DevOps tools, seriously consider database development tools as well. But, if you want comprehensive results when developing your database, you need tools with a DevOps flare.

    If we didn’t have the efficiency and speed that we got from Agile software development, we wouldn’t have created DevOps. So, bringing Agile to database development was a must for database DevOps to solve problems. One tool in particular that we use supports some incredible features for Agile development. A database is different than an application; because of this, a database will have state. So, having a database instance we can compare to with our team is critical. The tool we use has this functionality, which has allowed us to thrive. It also lets users work with existing source code control along with a live database to help database developers. Because of this, users can execute this functionality against database objects such as stored procedures and tables.

    Application Release Automation

    Application software can be difficult to manage. Often, they have too many components to manage easily, which is where automation can help. Application release automation helps your team move from learned and taught processes to basic scripts that are easily scalable and can help deploy applications rapidly. If you’re working with a team that cares about data and DevOps, Application release automation is a critical tool.

    Test Data Management

    No matter how rapidly you are able to deploy applications, you’ll need to test. The faster you deploy, the more tests you will need to run. But a massive problem with testing can be the lack of quality. Many applications pivot functionality depending on the data stored in a datbase. So, providing data that is or, at least, matches the production data is critical to guarantee high test quality. Without the right data, you could be running massive amounts of tests that are also providing bad/false results. And, with DevOps, you’re committed to improving your software and working to enable more testing for that software.

    Don’t Forget the Database

    A key finding of the “2018 State of DevOps Report” is that integrating database change management into your DevOps toolchain early in the process drives higher performance.

    This is obvious to anyone that has released software before. However, for large siloed enterprises, this is non-obvious. For too long, we have been told to leave the database to the DBAs. Well, it turns out that approach (though sensible in the ’90s, when we started it) is no longer working for us.

    Your application will not run without database schema and logic changes about 80 percent of the time. So, there is no reason to have a separate manual process. Here’s someone saying that exact same thing in 2017: https://www.youtube.com/watch?v=DDZIiGT3jzs

    Now What?

    Having all the right tools is a necessary first step, but it doesn’t stop there. To fully succeed with these tools, a few key strategies must be put in place as well:

    One Ring to Rule Them All

    DevOps has taught us to break down silos. Yet, we see silos now being created based on tool choices. Companies should standardize DevOps tools across the entire value chain. If some parts—say Dev and Test—are using Artifactory, for example, the operations team should also use it and not rely on the release teams to put the release on a shared network drive. Ops should use Artifactory, too.

    This will require some horse-trading. Some teams will dig their heels in on a tool because it provides value specifically to them. Well, so be it. As one of my favorite Venture Bros. character, Dr. Henry Kissinger, says, “Compromise, my friend, is the essence of diplomacy, and diplomacy is the cornerstone of love.”

    Cloud First

    When I hear “cloud” from IT leaders, I immediately think of Inigo Montoya from “The Princess Bride” when he said, “You keep using that word. I do not think it means what you think it means.”

    The National Institute of Standards and Technology has defined cloud computing to have five essential characteristics:

    1. On-demand self-service
    2. Broad network access
    3. Resource pooling
    4. Rapid elasticity or expansion
    5. Measured service

    Your DevOps tools should also have these characteristics. Specifically, if you are not allowing external teams to utilize your tools and require someone to make a request via ticket first, you are doing it wrong.

    Time to learn how to offer DevOps as on-demand self-service.

    — Robert Reeves

  • Low-Code Application Development: A Catalyst to Digital Transformation

    Low-Code Application Development: A Catalyst to Digital Transformation

    Low-code and no-code software development platforms have emerged as a focal point for CIOs, and it’s easy to see why. With an increasing emphasis on market disruption and continuous innovation across industries, tools such as these fit the bill in simplifying application development. Capabilities such as drag-and-drop integrations, out-of-the-box user interface (UI) templates and easy process flows allow anyone—including those with no coding background—to build and change applications. As a result, organizations can quickly deliver new applications and functionalities to keep up with, or disrupt, their markets. Traditional software development cannot match the enhanced collaboration, speed and productivity gains that come with low-code development.

    Laggards need to pay attention: Low-code is establishing itself as a key enabler for digital transformation and differentiator for organizations. Below are five reasons why every organization should embrace low-code adoption.

    Enterprises will struggle to find developers to keep up with global app development demands: Enterprise IT departments cannot keep up with market demand for application development. In fact, Gartner predicts that market demand for app development will grow at least five times faster than IT’s capacity to deliver through 2021. Low-code application development platforms help bridge an organization’s skilled developer shortage gap. Instead of relying only on short-staffed professional programmers, these platforms enable non-programmers to participate in and contribute to application development. Non-programmer citizen or business developers, such as business analysts, process specialists and departmental specialists, can use their experience with visual drag-and-drop tools to work collaboratively with IT to design and modify business applications.

    Low-code increases productivity: Organizational leaders today preach agile processes and methodology to build apps iteratively with constant feedback and collaboration. Bringing the business or citizen developers into application development enables organizations to deliver on the promise of agile. Low-code platforms make it much easier for business users to enter their requirements directly into the application development environment than the old way of creating huge requirements documents. This ensures business requirements are not lost in translation by IT. And just as importantly, the company’s skilled developers have more time to focus on higher-value work, rather than constantly chasing down business users for business requirements.

    Low-code development allows disparate teams to build apps collaboratively: How do IT, operations, business, marketing and sales collaborate to build apps that improve customer engagement and drive operational efficiencies? Instead of code, they need a common language that everyone understands, in the form of visual models. Adopting a low-code platform can empower every part of the organization to contribute to application development. CIOs and IT leaders can tap into the knowledge of their front-line workers to create apps that provide next-level customer experiences. And on the back end, organizations can leverage their internal subject matter experts from various departments to create better internal apps that drive operational excellence.

    Low-code empowers continuous innovation and scaling: Low-code platforms help organizations start small, evolve and then scale to drive digital transformation. Organizations can quickly build out minimum viable products (MVPs), deploy these apps on the fly, learn and optimize and scale these innovations to foster continuous innovation. Without writing complex code, businesses can easily extend their apps to more channels—mobile chatbots, self-service portals, etc. And cloud-based low-code platforms allow organizations to move between cloud platforms or use a hybrid cloud, enabling even more flexibility.

    Competitors are already using a low-code approach: Organizations are looking for ways to innovate, break down silos and reduce costs—and low-code helps them do all of those. A recent Pega-commissioned survey from Frost & Sullivan found that it’s not just hype; 81 percent of respondents already use a visual or low-code approach.

    The question isn’t whether to embrace low-code; it’s what to look for when implementing the technology. Some low-code platforms enable organizations to create only simple lightweight applications that fail to scale and offer limited reusability. Other low-code platforms provide disconnected app authoring environments that perpetuate a siloed approach to development for business and IT. With these types of platforms, organizations end up spending too much time stitching together pieces of apps created in these disparate environments.

    On the other end of the spectrum, next-generation, role-based authoring environments provide the right tools to anyone who touches enterprise applications. These include visual and intuitive authoring experiences for citizen developers, professional developers, system administrators and data scientists—where users can seamlessly toggle between different studios to quickly access what they need, where and when they need it, all in one unified platform. Users can quickly build and deliver MVP—or better yet, minimum lovable product (MLP)— while evolving and scaling the app to deliver enterprise-grade performance.

    The time has come to abandon slow and expensive code-heavy app development. True organizational collaboration and digital transformation depend on it.

    — Sid Misra