Category: DevOps in the Cloud

  • IBM Adds Fully Managed VMware Service to Cloud Portfolio

    IBM Adds Fully Managed VMware Service to Cloud Portfolio

    At the VMware Explore 2022 Europe conference, IBM this week announced an IBM Cloud for VMware-as-a-Service offering that integrates instances of VMware Cloud with the infrastructure-as-a-service (IaaS) platform managed by IBM in the cloud.

    Rohit Badlaney, vice president of product management and strategy for IBM Cloud, said now that VMware Cloud can be consumed as a subscription service, it’s now possible for IBM to integrate it with its cloud platform to create a fully managed service. Previously, IT organizations would have had to separately license VMware Cloud and deploy it on IBM Cloud themselves, he noted.

    In general, Badlaney said IBM is focused on working with organizations in highly regulated industries that need to run complex workloads in the cloud. IBM is not interested in competing against other cloud service providers to run workloads on commodity infrastructure, he added.

    The majority of applications that run in the cloud today consume a narrow range of memory and storage resources. The IBM cloud is clearly more focused on providing higher-margin services to complement the cloud infrastructure it makes available via its data centers. Less clear is to what degree monolithic applications running in on-premises IT environments are being lifted and shifted to the cloud. While there is clearly a segment of organizations that no longer want to operate their own data centers, the bulk of applications continue to run in on-premises IT environments. The reasons for this include everything from performance requirements and security concerns to regulatory compliance issues.

    However, since most on-premises applications run on VMware virtual machines, much of the focus on cloud migration has revolved around platforms that would not require IT teams to refactor applications to run on a different virtual machine platform. IBM is also betting that, given the current state of the global economy, more organizations will soon be opting to not manage their own data centers. Cloud platforms managed by a third party would enable those organizations to focus more of their own internal IT efforts on application development and deployment.

    Each organization will need to determine for itself whether to treat IT as an operating versus a capital expense, depending on which approach makes the most economic sense. Organizations that have embraced DevOps workflows would need to align the way they build and deploy applications to a managed service.

    In theory, of course, a managed cloud computing service makes IT teams more agile and efficient. Less IT infrastructure winds up being overprovisioned by developers that can programmatically spin up resources on demand. Of course, there are a lot of IT stacks other than VMware Cloud that can be deployed in the cloud. IBM, for example, makes available the Red Hat OpenShift platform to run cloud-native applications on Kubernetes clusters. IBM has not yet committed to offering the VMware Tanzu platform for running those types of applications.

    Not every application is going to wind up running in the cloud, but what is certain is that application environments are becoming more complex to manage in the next era of cloud computing.

  • Fastly Adds Observability Tools for Edge Computing Environments

    Fastly Adds Observability Tools for Edge Computing Environments

    Fastly, Inc. this week added a set of observability tools to its portfolio that are optimized for edge computing platforms connected to its content delivery network (CDN).

    Laura Thomson, senior vice president of engineering at Fastly, said the company is now providing a set of tools that enable DevOps teams to capture logging data and metrics in real-time via a single console.

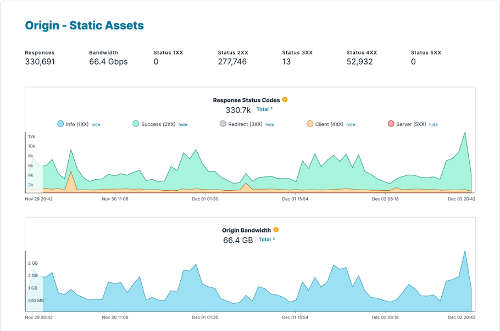
    The first two available tools are Origin Inspector—to observe network traffic flows including HTTPS response codes—and Domain Inspector—to access metrics based on both historical and real-time data. In total, Fastly is now providing access to more than 200 metrics spanning client, origin, cache, web application firewall (WAF), Compute@Edge, Image Optimization services and others that cover 100% of the data generated since the service was spun up.

    There is no sampling of data, and the company is also providing integrations with 33 storage and analysis services provided by either Fastly or a third party, noted Thomson. IT teams can now log any aspect of HTTP requests and responses through a large variety of logging formats, including the Common Log Format, JSON or as a key/value store. IT teams can also store their own logs to make sure they retain complete control over access.

    Over the next several months, Fastly will continue to expand this portfolio of observability tools, including an Edge Observer dashboard it is providing to customers that are deploying applications at the edge, added Thomson.

    In general, observability tools are being used to not only improve processes and overall customer experience but also identify and block suspicious activity. Fastly is making a case for observability tools that enable DevOps teams to achieve those goals without necessarily having to deploy a separate observability platform.

    Of course, most DevOps teams have been continuously tracking various pre-defined metrics for years. Observability tools, in contrast, are designed to make it feasible to interrogate logs, metrics and traces so that IT teams can discover issues before there is a disruption to services. The challenge, of course, is that not every IT team necessarily knows how to shape the queries required to discover the root cause of a potential issue.

    One way or another, DevOps teams will need to be able to remotely diagnose edge computing issues as the number of workloads deployed on these platforms expands. IT teams are not going to be able to travel to the physical location of every edge computing platform every time an issue arises. In many ways, the rise of edge computing will force a transition to observability tools that will enable IT teams to more proactively manage IT environments rather than respond after a metric has already exceeded its threshold.

    It’s not clear to what degree that approach will prevent IT issues from occurring, but the amount of time required to detect and remediate issues should dramatically decline as more visibility into IT environments, including edge computing platforms, is gained.

  • Rust Momentum Intensifies | Elon Says No WFH

    Rust Momentum Intensifies | Elon Says No WFH

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: People won’t shut up about Rustlang, and Musk mandates Twitter teams return to the office. (more…)

  • CloudBees Demos Orchestration Capabilities of ReleaseIQ Platform

    CloudBees Demos Orchestration Capabilities of ReleaseIQ Platform

    At the online DevOps World 2022 event today, CloudBees demonstrated for the first time the capabilities of the application release management platform it gained last month through the acquisition of ReleaseIQ.

    Shawn Ahmed, chief marketing officer and interim chief product officer at CloudBees, told conference attendees that the ReleaseIQ platform will provide application development teams with visibility into precisely how their code is making it into production environments.

    Armed with those insights, it then becomes possible to understand exactly how the way commits are made during a build process are, for example, creating a workflow bottleneck, he added.

    The ReleaseIQ platform is designed to enable DevOps teams to both create and maintain pipelines using a no-code tool. That enables greater transparency into workflows via dashboards that also provide optimization recommendations.

    CloudBees already provides a Flow orchestration engine within its continuous delivery platform. However, ReleaseIQ provides a similar capability across multiple continuous integration/continuous delivery (CI/CD) platforms using a SaaS platform that is more accessible. ReleaseIQ can also be integrated with multiple platforms including CloudBees CI, Jenkins, CircleCI, GitLab, Bamboo, ArgoCD and others.

    Naturally, the current level of DevOps maturity varies widely by organization. However, as more organizations realize how much they depend on software to drive digital business transformation processes, the need to further automate application development and delivery becomes more apparent. While CI is widely used today, the number of organizations that have consistently implemented CD to automate application release management is still fairly limited. The underlying infrastructure that software is deployed on typically has a unique set of application programming interfaces (APIs) that each CD platform needs to support. Platforms such as ReleaseIQ provide a higher level of abstraction that simplifies managing the pipelines that deliver software.

    CloudBees is essentially positioning ReleaseIQ as the orchestration engine for both unifying pipeline management and, ultimately, enabling value stream management across increasingly complex application development environments. It may take a while to fully realize that ambition, but with the acquisition of ReleaseIQ, the company is now pursuing a more cloud-centric approach toward enabling DevOps teams to, for example, more easily reuse pipelines.

    DevOps teams, of course, have created a lot of scripts over the years to provide orchestration capabilities. The issue is that those scripts tend to be brittle in the sense they don’t scale especially well over time. They also tend to be poorly documented and challenging to maintain if the script writer leaves the organization. It’s not uncommon for new members of a DevOps team to replace a script with one they wrote simply because they’re more familiar with how it’s constructed.

    More than a decade after the launch of the Jenkins CI/CD platform, there are still plenty of manual DevOps processes that should be more automated. A no-code orchestration platform may prove to be a significant step toward automating a wide range of tasks that consume more time than they should.

  • A DevOps Reset for a Multi-Cloud World

    A DevOps Reset for a Multi-Cloud World

    In the world of DevOps, only two things really matter: 

    • To release applications and updates as quickly as possible
    • To have access to resources (processing, storage, networks) able to run those apps, as cost-effectively as possible. 

    The measures used to achieve these twin goals should work together seamlessly–otherwise, you’re inefficient. But software development and IT operations have been on separate journeys, and it now takes layers of tools, specialized expertise and lots of precious time to distribute and manage applications where they need to run. Organizations tolerate all this complexity (and the delays and costs that come with it) since they see no alternative. But what if there was an easier way?  I’ll examine the two fundamental shifts driving software development and IT operations and see why current processes are so cumbersome.  

    Shift One: From Monolithic Applications to Microservices

    In the beginning, applications were monolithic, with all functions and code packaged together. That approach was manageable when apps were updated once or twice a year, but not when updates are expected multiple times each day. Finally someone realized that applications would be much easier to build, improve and maintain if they were divided into smaller units called microservices—independent, loosely coupled, individually deployable services, each one addressing a specific function. 

    To support microservices, a technology stack has emerged, similar to steps on a ladder:

    • To make them portable, microservices are packaged in containers—a lightweight, standard way for applications to move between environments and run independently. Everything needed to run the microservice such as settings, system tools, libraries and dependencies is packaged inside the container.
    • A single application could have hundreds of containers associated with it. How do you manage them? Along came Kubernetes (aka K8s), open source software for deploying and orchestrating containers within a cluster of virtual machines. (Note the word cluster—the significance will be discussed momentarily.)
    • Since microservices are updated constantly, how do you make sure the correct version is running? Along came GitOps to provide version control for all updates to all those microservices. Git repositories provide a single source of truth for the desired application state, as well as a record of every code change.

    Finally, we need to set up continuous integration/continuous delivery (CI/CD) for rolling out application improvements and new features. Along came ArgoCD, a GitOps continuous delivery tool for Kubernetes that continuously monitors running applications, compares the current, live state against the target state specified in a Git repository, and resolves discrepancies.

    Shift Two:  From On-Premises to Multi-Cloud 

    Not long ago, IT departments were having hot debates about this strange new concept called the public cloud and whether it could possibly play a role in their operations. But once they discovered how easy it was to spin up resources, the floodgates opened.

    The first tentative steps typically involved hybrid clouds combining an on-site private cloud with spillover into a public cloud for workload spikes. These initial forays mushroomed to dozens or hundreds of clouds, in different locations and with different providers. It’s a mind shift happening in enterprises globally—where they once had a small number of clouds, now their cloud operations are huge, growing and boundless. Companies are also discovering that the cloud is not just an easier, more cost-effective way to run their applications, it unlocks new opportunities.

    Now there are core clouds, edge clouds for hyper-local applications, regional clouds, clouds for high availability and resilience and more. Edge computing is another option, where low latency is required for operations at the customer-facing frontend cloud while backend processing happens in the primary cloud. But this is just the beginning.

    Continuous Delivery is Now Way Too Complicated

    Today, an application may have dozens of microservices distributed across different clouds that need to work together—perhaps some in cloud one, a few in cloud two, others in cloud 40, etc. The scale gets huge very quickly; for example, if 100 microservices are being delivered to 100 clouds, there are 10,000 mutations that have to be configured and managed. 

    This is the new normal, and DevOps needs to adapt to it. Processes should mesh transparently, but connecting microservices across multiple clouds and cloud instances requires inter-cluster communication, which Kubernetes (and GitOps/ArgoCD on top of it) does not natively support.

    To make all this work requires specialized skill sets, so organizations hire teams with expertise in continuous delivery, multi-cloud, networking, security and automation. The first step involves distributing K8s containers to clouds where the microservices are going to run. Some enterprises create their own distribution system, others choose to download, install, and manage third-party software such as open source ArgoCD.

    The second step is more complex: Securely connecting those microservices across different clouds and K8s clusters. This involves integrating complex service meshes, load balancers, API gateways and network/firewall automation tools, all feeding into a centralized console for configuration and monitoring.

    The result is inevitable: Lots of extra costs, inefficiency, potential security risk and delayed time to market with resulting risks to the business. Development teams update microservices daily but depend on CloudOps, NetOps, SecOps and other flavors of Ops to deliver them to the different clouds and clusters where they need to run. 

    Despite the best efforts of these different stakeholders, it can take days or weeks to update cloud networks and security for each change.

    Simplifying Multi-Cloud Operations With an Overlay Network

    When hundreds of microservices are being distributed across more and more clouds and updated constantly, you need an alternative—one that streamlines current operations without sacrificing security or application performance. Let’s set aside traditional methods and think about how it should be done.

    First, the solution should be easy to use, so DevOps people don’t have to be proficient with the underlying technology or be dependent on NetOps, SecOps and/or CloudOps people who are. Instead, just provide some basic information about the Git repository and the clouds where you want the microservices to run, and an overlay network handles the rest.

    It should be comprehensive—integrating ArgoCD, the service mesh, the K8s ingress gateway, zero-trust security, resilience/failover, load balancing and multi-cloud networking — all those elements that normally require assembling and configuring individual tools.

    It should make multi-cloud Kubernetes application operations easy to manage, with a single dashboard where you can securely deploy, connect and monitor microservices in all your clouds and clusters.

    Finally, the solution should be available as a service, rather than having to install an ArgoCD server and try to manage it yourself (or hire a team to support it). And if you have questions or need help, competent people should be available to give you a hand.

    Disruptive – In a Good Way

    Get ready for self-service multi-cloud Kubernetes decoupled from the underlying networking and security details. It’s an approach that’s about to upend how microservices are deployed and managed, so DevOps can get back to what really matters:  Delivering applications as fast as possible, on the resources where they need to run. The ability to deliver new features in a fraction of the previous times while significantly reducing costs and without compromising security will mean a competitive advantage and a stronger bottom line. 

  • VMware Extends Equinix Alliance to Drive Managed Hosting Service

    VMware Extends Equinix Alliance to Drive Managed Hosting Service

    VMware today announced it has extended its alliance with Equinix to launch a managed distributed cloud service that runs instances of its cloud computing platform in hosted IT environments.

    Announced at the VMware Explore 2022 Europe conference, the VMware Cloud on Equinix Metal service takes advantage of more than 240 Equinix data centers in 71 major metro areas around the world to deploy instances of the VMware Cloud platform running atop the company’s virtual machine software.

    Narayan Bharadwaj, vice president of cloud solutions at VMware, said this VMware service extends the scope and reach of the company’s multi-cloud computing strategy beyond the scope of the major hyperscalers and traditional on-premises IT environments.

    The goal is to provide a managed IT environment that provides an alternative for deploying latency-sensitive applications closer to the network edge where data can be processed and analyzed in near-real-time, he noted. In addition, Equinix’s hosted IT environment also makes it possible for IT teams to more easily comply with requirements in highly regulated industries.

    It’s not clear what percentage of applications today are running in managed hosted environments versus a public cloud or local data center. But as more organizations decide not to operate data centers themselves, many of them are discovering managed hosting services are preferable to the cloud for reasons spanning everything from application performance and cost and security to compliance.

    In some cases, organizations are determining that certain classes of longer-running applications initially deployed in the cloud are actually less expensive to run in an on-premises IT environment, noted Bharadwaj. A managed hosting option often provides the flexibility benefits of the cloud at a lower cost for those applications, he added.

    As cloud computing evolves, it’s become apparent that IT is becoming more distributed than ever. Many organizations are finding they now have a mix of applications running on public clouds, in co-location facilities and traditional on-premises IT environments. The challenge is that with each new platform employed to run applications, the total cost of managing IT increases. Regardless of any potential infrastructure cost savings, each platform typically requires a set of dedicated specialists to master the frameworks need to manage it. In fact, the single biggest IT expense remains the cost of labor. VMware is making a case for a familiar IT framework that can be deployed anywhere to rein in those costs.

    DevOps, of course, was created to provide a new approach to automating the management of IT at scale. However, DevOps continues to be employed unevenly, largely because there are not enough IT professionals with the programming skills required to successfully manage IT-as-code. Managed services are gaining traction because, in most cases, they shift the responsibility for managing DevOps workflows onto a vendor such as VMware.

    It remains to be seen just how automated the management of IT will become in the months and years ahead. However, it’s apparent that, in the era of the cloud, more organizations are opting to rely on third parties to manage infrastructure so they can devote more resources to building and deploying applications.

  • Snowflake Makes Case for Building and Deploying Apps on Platform

    Snowflake Makes Case for Building and Deploying Apps on Platform

    During a Snowday 2022 event, Snowflake this week moved to make it simpler to build applications on top of its cloud platform for managing data in addition to enhancing the overall security of the platform.

    The company has made generally available Snowpark, a framework for building Java, Scala, SQL or Python applications. Snowflake also committed to making generally available in early 2023 an open source Streamlit framework for building Python applications that Snowflake acquired earlier this year.

    Snowflake also revealed it is adding observability tools to the platform to make it easier to build, test, debug, deploy and monitor data pipelines, including alerting tools (private preview), logging capabilities (private preview), event tracing (private preview), task graphs and history (public preview).

    Torsten Grabs, director of product management for Snowflake, said those capabilities will make it easier to alert DevOps teams to issues that might arise with applications deployed on the Snowflake platform.

    At the same time, Snowflake is also making it simpler to build data pipelines by making a Serverless Tasks capability generally available. In addition, the company is previewing a Schema Inference engine that makes it simpler to ingest data and a Dynamic Tables capability to declaratively manage data pipelines.

    Other capabilities being added to the platform include a public preview of a Query Acceleration Service to make additional compute resources available on demand. Snowflake has also improved query efficiency with join elimination in addition to providing search optimizations.

    There are also now cost optimization tools that enable IT teams to run a cost-benefit analysis of Snowflake services in addition to tools that make it easier to replicate data across multiple cloud computing environments running the Snowflake platform.

    IT teams can now also replicate Streams and Tasks via a capability in public preview that enables data pipelines to seamlessly work on secondary Snowflake accounts and configure failovers using a graphical tool that is available in private beta.

    Finally, Snowflake has also enhanced its cross-cloud Snowgrid Capability to make it easier to share both public and private listings of data in addition to applying tags to and searching masked data.

    The latest editions to the Snowflake platform come at a time when more organizations are starting to adopt DataOps best practices to manage data. Snowflake is now making a case for building and deploying applications on top of a platform that automates the management of the data pipelines used by applications to access data.

    It’s not clear to what degree the Snowflake platform will be employed to host applications, but the company is clearly betting the volume of data residing in its cloud platform will attract a wide range of application developers that, in turn, will need to be supported by DevOps teams.

    Of course, Snowflake is not the only provider of a data warehouse or data lake that has similar ambitions. Regardless of platform, however, the one thing that is clear is that a convergence of DevOps and DataOps workflows is now underway as IT organizations look to streamline the management of the massive amounts of data that now reside in the cloud.

  • Cisco Adds Open Source Tool to Validate Serverless Functions

    Cisco Adds Open Source Tool to Validate Serverless Functions

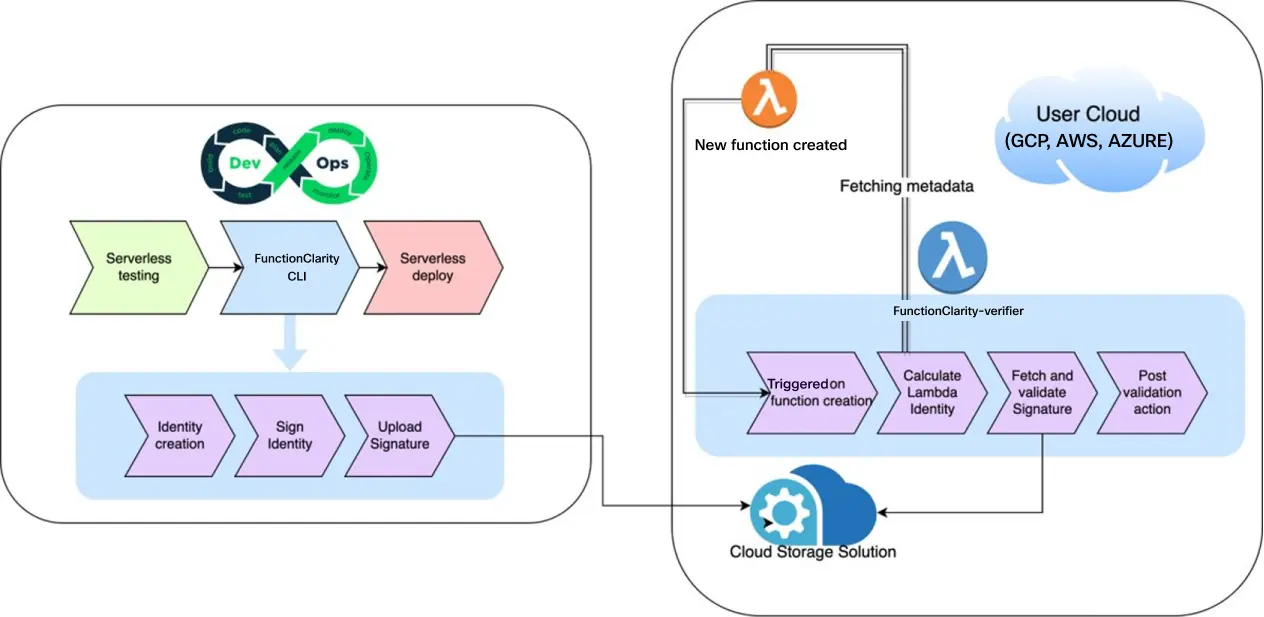
    Cisco has launched an open source project, dubbed FunctionClarity, that makes it possible to verify signatures before code is deployed in a serverless computing environment.

    Vijoy Pandey, vice president of emerging technologies and incubation at Cisco, said that one of the application security issues that has emerged in serverless computing environments is the lack of validation capability to verify code signatures prior to deployment. As more organizations employ serverless computing frameworks, the overall software supply chain becomes less secure, he noted.

    FunctionClarity includes a command line interface (CLI) tool to invoke a verification function that can be deployed on the Amazon Lambda serverless platform to address that issue; support for Microsoft Azure and Google Cloud serverless platforms is planned, he added.

    The FunctionClarity project aims to close that gap by employing either a keyless approach using open source sigstore tools or a traditional encryption key, noted Pandey.

    The FunctionClarity project is the latest extension of a Cisco OpenClarity initiative that includes an existing project for securing application programming interfaces (APIs) using a service mesh, dubbed APIClarity, and a tool for detecting and managing software bills of materials (SBOMs) and vulnerabilities in container images and filesystems dubbed KubeClarity. All three projects are part of an ongoing Cisco effort to contribute code to the open source community that, while essential, does not provide a lot of differentiated value for any one vendor, said Pandey.

    The FunctionClarity project arrives at a time when concerns over the security of software supply chains is on the rise. Many of the software security issues that organizations are encountering stem from the simple fact that developers can provision cloud infrastructure without any kind of meaningful cybersecurity review. Code signing, within the context of a larger set of DevSecOps workflows, is now starting to gain traction to better ensure secure software supply chains. The challenge is that as more code winds up running on serverless computing platforms, a need to extend the reach of whatever approach to code signing an organization adopts becomes more evident.

    In general, the open source community is collectively trying to respond to an executive order issued by the Biden administration that required federal agencies to implement a series of steps to better secure their software supply chains. One of those measures includes wider adoption of code signatures to ensure the authenticity of code being incorporated into applications. The challenge is that incorporating code signatures into DevOps workflows has historically not been a trivial process to implement. Most recently, a free sigstore cloud service launched that promised to make it easier to achieve that goal.

    It’s not clear how widely or even how rapidly code signing will be adopted, but enterprise IT organizations are paying close attention to how federal agencies are responding to the executive order. Many of the tools and processes defined by those agencies will inevitably be copied by enterprise IT organizations that have thus far made limited use of code signing to verify the authenticity of software components. The challenge now is finding a way to achieve that goal without slowing down the rate at which modern software is developed.

  • Introduction to SPIFFE/SPIRE

    Introduction to SPIFFE/SPIRE

    For a long time, people have been logging into the apps they use via passwords or password managers. And many open standards and identity providers on the market continue to evolve how users authenticate and authorize with websites and applications. The issue is that the same problem exists for software services—when applications talk to applications, how do we prove the credibility of service-to-service connections?

    Enter SPIFFE and SPIRE. SPIFFE is a specification for implementing identity for workloads, and SPIRE is the code that implements this specification in practice. Together, the projects create a standardized, secure way to identify software services and authenticate them. SPIFFE and SPIRE recently reached graduation status with the Cloud Native Computing Foundation (CNCF), solidifying the projects’ maturity as a top open-source standard mechanism to deliver cryptographic runtime identity for both cloud-native and legacy workloads.

    SPIFFE and SPIRE are already used across many major public deployments. Yet not all developers are familiar with their intricacies. Below, I’ll take a gander at both projects and how they operate to provide a bit more context. I also spoke with Evan Gilman, SPIFFE/SPIRE maintainer, to gather more insights on the history of the projects and their future goalposts.

    What is SPIFFE?

    The Secure Production Identity Framework For Everyone (SPIFFE) is a specification for workload identity. According to Gilman, the easiest way to think about SPIFFE is as a passport. Similar to how people are issued passports in a common shape with a barcode and standard information, SPIFFE dictates the standard methods to prove and validate the identity of a service. It’s like bringing the “Sign in with Google” experience to the software services themselves, he adds.

    There are three key components in SPIFFE. First, SPIFFE specifies that services shall identify themselves with what’s called a SPIFFE ID, which is defined as a URI in the format of spiffe://trust-domain-name/path. These IDs are then encoded into a SPIFFE Verifiable Identity Document or SVID. SVIDs aren’t so much a document type themselves — instead, they support either X.509 or JWT document types. Last but not least, SPIFFE specifies a workload API that issues and rotates these SVIDs, along with the keys needed to validate them.

    What is SPIRE?

    SPIRE is the code that implements the SPIFFE specification—you can think of it as a production-ready SPIFFE runtime environment. SPIRE, the “flagship SPIFFE implementation,” is a true end-to-end instantiation of SPIFFE that securely issues SVIDs, renews SVIDS and performs attestation, among other functions. If SPIFFE defines what a passport is, then SPIRE is the agency that issues the passports, said Gilman.

    The SPIRE agent runs on a node and exposes the workload API, which hooks into each workload. A workload, as defined by the SPIFFE documentation can be a web server, an instance of a MySQL database, a worker program or a web application composed of independently deployed systems. By communicating in this manner, SPIFFE/SPIRE can solve the issue of “secret zero,” which refers to the conundrum of proving the first credential to newfound systems.

    More Background on SPIFFE/SPIRE

    Joe Beda, a co-founder of Kubernetes, first proposed SPIFFE at GlueCon in 2016. At the time, Google was considering what internal technology it had that might prove helpful to the broader industry. It’s said that the technology that inspired SPIFFE/SPIRE can trace its roots to security and identity subsystems brought to Google from AT&T and Bell Labs.

    Nowadays, SPIFFE/SPIRE is actively maintained by many organizations, and we continue to see impressive production use cases. “SPIRE is deployed in some staggeringly large cases,” explained Gilman. SPIFFE/SPIRE adoption can be seen within GitHub, Netflix, Pinterest, Square, Transferwise, Uber and many other large technology companies. In terms of ownership, Gilman said that SPIRE is most used by platform engineers, infrastructure engineers or security engineers, depending on the organization’s roles.

    Future Outlook for SPIFFE and SPIRE

    SPIFFE/SPIRE appear to have the resources and backing to maintain a stable implementation, so the future looks bright for both projects. In terms of new features, in mid-2022, a first-class integration with SPIRE was merged into the Istio service mesh as a more flexible alternative to Istio’s built-in SPIFFE implementation. Another recent update is experimental support for SPIRE on Windows. Regarding future plans, SPIFFE/SPIRE maintainers will likely continue to iteratively improve the specification and implementation with frequent updates.

  • Cloud Disaster Recovery Best Practices

    Cloud Disaster Recovery Best Practices

    It’s increasingly common for companies in all sectors to use the cloud to store their data. The cloud provides scalability, security and flexibility that was often inaccessible to businesses only a few years ago. But just like any other technology, it has its limits.

    What happens if a severe thunderstorm knocks out power to a data center or if an employee accidentally deletes critical files? These are the types of scenarios that, however unlikely, can still happen and cause significant disruptions to a company if they’re not prepared.

    That’s where cloud disaster recovery comes in. In this article, we’ll discuss why cloud disaster recovery is critical for businesses and the different strategies you can implement to ensure your data is always safe and accessible.

    What Is Cloud Disaster Recovery?

    Cloud disaster recovery (CDR) is a strategy that helps businesses keep their data safe in the event of an unforeseen disaster. This can be anything from a natural disaster like a flood or earthquake to a man-made disaster like a power outage, fire or cyberattack.

    There are many different cloud disaster recovery strategies that businesses can implement, but the most important thing is to have a plan in place so that you know what to do if and when something goes wrong.

    One Company’s Story of Cloud Impact: OVHCloud

    Before providing strategies, we wanted to give you a real-life example of a cloud disaster that impacted multiple businesses, big and small.

    In 2021, OVHCloud, one of the world’s largest cloud service providers, suffered a catastrophic fire at one of its data centers in Strasbourg, France. The fire destroyed the facility, causing widespread damage and leaving many businesses without access to their critical data.

    In the aftermath of the fire, it quickly became apparent that OVHCloud did not have a solid cloud disaster recovery plan. As a result, many businesses were left scrambling to find alternative solutions for their data storage and backup needs.

    The moral of the story is that even the biggest and most well-known companies can be caught off guard by a disaster. This is why it’s so important for businesses of all sizes to have a cloud disaster recovery plan.

    Now that we’ve seen the importance of cloud disaster recovery, let’s look at strategies you can implement to keep your data safe.

    Cloud Disaster Recovery Strategies

    When discussing cloud disaster recovery strategies, many options are available, but not all of them will be right for every business. The key is to find the strategy or combination of strategies that work best for you and your company.

    Here are some of the most common cloud disaster recovery strategies:

    1. Know Your Infrastructure

    The first step in any cloud disaster recovery strategy is to understand your current infrastructure and what assets and data you have. Your assets can include everything from physical servers and hard drives to cloud-based applications and data. 

    Do the homework necessary to understand what you have and where it’s located. For example, take inventory of all of your assets and determine which ones are critical to your business operations. 

    Once you know what you have, you can start to develop a plan for how to protect it. Yes, this may take some time, but it’s an essential step in protecting your data.

    2. Conduct a Business Analysis

    Data breaches within the cloud can come in many different forms. From unexpected data loss to malicious cyberattacks, it’s important to understand the different ways your data could be compromised. This is where conducting a business impact analysis comes in.

    A business impact analysis (BIA) is a process that focuses on identifying and evaluating the potential risks to your business. Rather than focusing on the causes of the breakdown, a BIA focuses on the potential impact of the disruption. The impact can include things like loss of income, damage to reputation and compliance issues.

    By conducting a BIA, you can better understand the risks your business faces and what steps to take to protect against them. For example, using endpoint security vendors can help protect your data by preventing attacks on endpoints on or off the network.

    3. Draft a Disaster Recovery Plan Based on RPO and RTO

    Once you’ve conducted a BIA and clearly understand the risks your business faces, you can start to draft a disaster recovery plan, specifically around the recovery point objective (RPO) and recovery time objective (RTO).

    Your RPO measures how much data is lost during a disruption, while your RTO measures how long it takes to recover from it. By understanding these two factors, you can start putting together a plan that meets the specific needs of your business.

    It’s important to note that your RPO and RTO will likely differ based on the type of data you’re working with. For example, if you’re working with data that can be easily recreated, your RPO may be relatively low. However, if you’re working with mission-critical data that can’t be easily replaced, your RPO will be much higher. The same is true for RTO.

    Regardless, you want to ensure that your disaster recovery plan is based on your specific RPO and RTO so you can recover from a disruption promptly and with minimal data losses.

    4. Have a Strong Cloud Backup Solution

    No matter what cloud disaster recovery strategy you implement, it’s essential to have a strong backup solution in place. It will ensure that you can quickly pivot to a different strategy and dodge the hefty price tag that often comes with data loss and encrypted files when there’s no backup.

    There are several different backup solutions available, so you must find one that meets the specific needs of your business based on the type of data you have and how often it changes.

    5. Test Out Your Disaster Recovery Plan Regularly

    Once you have your disaster recovery plan in place, it’s important to test it out regularly. Testing will ensure that your plan works as intended and that you can recover from a disruption quickly. Things to test for include data backups, file restores and application availability.

    You should also involve your entire team in the testing process so everyone knows what to do in the event of a disruption. Look for collaboration software that comes with important tools such as chat, video conferencing and task management so your team can easily communicate and work together, even when they’re not in the same place.

    Final Thoughts

    There you have it! These five cloud disaster recovery strategies can protect your business from data loss and keep your operations running smoothly. We suggest starting this process as soon as possible so you can be well-prepared for whatever comes your way.