Category: DevOps in the Cloud

  • When the Cloud and the Edge Are the Same Thing

    When the Cloud and the Edge Are the Same Thing

    Edge computing remains a growing and exciting new architecture for enterprises across multiple industries. Distributing computing power across a decentralized network gives new opportunities for AI- and IoT-based applications. Demand is such that Gartner predicts by 2025, 75% of enterprise-generated data will be created and processed on the edge. 

    However, the cost and latency of sending all this data back to the cloud for processing are significant. To retain profitability, enterprises will need to keep as much data on the edge as possible while also moving processing to the edge. The benefits of these requirements are many, including:

    • Real-time processing, lower latency, faster answers
    • Resilience and availability, not relying on a stable connection to the cloud
    • More resource- and cost-efficient, less data shipping

    I believe organizations achieve these requirements and realize these benefits via a concept I call the cloud-to-edge data plane.

    A cloud-to-edge data plane unifies cloud and edge into a single solution that allows you to define your data and business logic once, package it up as a service and simply deploy it without having to worry if it should run in the cloud or out at the edge (which might change over time). This frees up the data plane automatically and adaptively to move services around, optimizing data access, coordination and replication, ensuring physical co-location of data, compute and user for the lowest possible latency with the highest throughput and availability.

    Choosing between cloud and edge is not a binary, black-and-white decision but has a lot of shades of gray in between. From an architectural perspective, the edge consists of many hierarchical layers between the cloud and the devices; each layer is further away from the cloud but closer to the end-users—a continuum. 

    Where you need your services to run in this continuum is very much use-case-dependent and might change over the lifetime of an application, depending on usage patterns or changes in features and business requirements. Critical parameters like latency, throughput, consistency, availability, scalability, compute resources, etc. change drastically as you move through this continuum. This results in both new opportunities and challenges:

    edge cloud

    One of the new services enabled by this architecture is mobile location transparent services. This new class of services is a thing of beauty. It means services are free to run anywhere and collaborate with other services without restrictions. It also allows the underlying platform to optimize overall system behavior by relocating services as needed, based on changes in usage, resources available, communication patterns, failure scenarios, and more. 

    If services are not location-transparent, then the system’s runtime topology needs to be part of the design and encoded into the services themselves. In practice, this means hardcoding decisions such as: 

    • If the communication between services is local or distributed—allowing for concurrency or distribution
    • If services are to be considered stationary or mobile—pinned to a specific physical address or free to be relocated
    • How the services can respond to failure—self-healing bulkheads that can be migrated to other nodes if needed or tied at the hip with the failed node

    Locking in decisions like this upfront will make the system harder to run efficiently, evolve, adapt and maintain over time. These should not be design or development decisions, not deployment decisions, but runtime decisions, not affecting the code. 

    It’s hard to predict the future. This includes knowing how an application will be used over time, how changes in usage and load patterns will evolve, and how future features or changes in business requirements will impact the initial design, assumptions, and runtime/operational characteristics. 

    Not having to take these decisions or worry about how they will be maintained efficiently but only focusing on API, data model, and business logic reduces time to market and overall risk substantially. 

    Here’s my vision for data…

    Data always exists wherever and whenever needed, but only for the time it is needed.

    • Having the latest and correct data always available to you right when you need it and wherever you happen to be located—in the central cloud or at the far edge—sounds like a developer’s dream.
    • On the other hand, it’s been said that “laziness is a virtue,” which is very much true of data management in a distributed system. Replicating data to locations where it will never be needed is a loss (unless needed for resilience/failover). The same is true for holding on to data longer than needed (holding resources hostage and forcing needless consistency mechanisms). 
    • Balancing this is very hard and should ideally be done by the platform adaptively at runtime at a global system level, rather than by the developer.

    Data is always co-located with processing and end-user—ensuring ultra-low latency, high throughput and resilience. 

    • If not, as in traditional three-tier stateless architecture, data is often somewhere other than where you need it to be and therefore has to be fetched before being used and pushed out to storage after modification. This increases latency, reduces throughput and puts the service at the mercy of the availability of the storage service.

    Data and compute move adaptively together with the end-user. 

    • Many use cases at the edge serve users on the move (e.g., cell phones, cars). To serve these users as efficiently as possible, their data and compute need to move geographically with them. 

    Data is injected into the services on an as-needed basis—automatically, timely, efficiently and intelligently. 

    • Data storage management is often very intrusive in application design and business logic: How to map domain objects to DB tables (OR-mapping), transaction management, storage API calls for fetching and updating the state, etc. 
    • Externalizing all of this to the platform and instead having the data injected into the service when new data is available (just as we are used to with events in a pub/sub system) makes the code easier to design, write, understand and maintain. 
    • Additionally, if the service is doing all data management itself, then it’s a black box to the platform. The platform has no idea what access patterns have been used, on what data, when data can be safely cached, replicated, sharded, prefetched, shared, etc. On the contrary, if the platform is doing all the data management, then it can look broadly across all services and safely optimize data management for the overall system holistically. 

    I believe RedMonk analyst Steve O’Grady’s concept of vertical integration fits well into this narrative. It all leads to what I feel is a distillation of a cloud-to-edge programming model (a continuum, as described previously). This model is about abstracting away everything that is not core business value, leaving the three things that can never be delegated: Data model, API and business logic. 

    As Timothy Keller said, “Freedom is not so much the absence of restrictions as finding the right ones, the liberating restrictions.”

    By using a serverless developer experience (DX), I believe the answer to extending real-time data and computing to the edge can be realized in a fully managed developer PaaS model. That model abstracts away all infrastructure into a single declarative programming model and effectively unifies cloud-native and edge-native development. This is “vertical integration” and the cloud-to-edge data plane vision.

    Conclusion

    Today, cloud computing and edge computing are typically treated as separate domains. However, rapidly evolving demands for intelligent low-latency processing of edge-generated data are creating requirements for a new approach combining cloud and edge into a single continuum. With cloud-native applications, architects and developers have already embraced the concepts required to build services that run in an essentially infinitely scalable (but logically centralized) cloud infrastructure. Extending this thinking to a fully decentralized infrastructure, including the edge, is a natural next step in enterprise application architecture. Programming models that enable a data-centric, location-transparent approach combined with intelligent runtimes that automatically enable data and processing to be co-located where and when needed will allow developers to take full advantage of such a wholly distributed edge-to-cloud environment.

  • Fire at Data Center Causes Chaos | 20% Costlier Cloud

    Fire at Data Center Causes Chaos | 20% Costlier Cloud

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: A South Korean conflagration leads to a ridiculously long outage, and the price of public cloud is skyrocketing. (more…)

  • Datadog Extends Reach of Integrated DevOps Platform

    Datadog Extends Reach of Integrated DevOps Platform

    At its Dash 2022 conference, Datadog announced today it is extending the reach of its namesake cloud-delivered monitoring and observability platform to address continuous testing, application security and cost management.

    In addition, Datadog has made available in beta a Data Streams Monitoring tool that makes it simpler to identify upstream issues that are likely to impact DevOps workflows. Also in beta is a Dynamic Instrumentation tool that makes it possible to employ Datadog agent software to collect data on the fly from specific source code to investigate performance issues. Datadog is also making available in beta a Resource Catalog to make it easier to navigate cloud resources that IT teams are employing and has added a Datadog Workflows tool to create blueprints to for automating repeatable processes.

    Datadog is also expanding the reach of its Watchdog telemetry analysis service infused with machine learning algorithms to add beta support for containers. There is also now a beta of an Event Management tool that DevOps teams can employ to more easily investigate a stream of related alerts using the Watchdog service.

    The Datadog Continuous Testing service, now generally available, provides DevOps teams with a workbench for generating and maintaining tests that can be integrated within continuous integration (CI) workflows. Datadog has also added an Intelligent Test Runner tool, in beta, to enable DevOps teams to only run tests that need to run when a change is made by analyzing code execution paths to increase developer productivity.

    Renaud Boutet, senior vice president of product at Datadog, said the goal is to make it possible for DevOps teams to create and run tests from within the Datadog user interface in parallel using a set of no-code tools without having to employ scripts. The capability will make it possible to automatically generate tests using data collected by the Datadog platform as part of an infinite DevOps workflow loop, he added.

    At the same time, Datadog is making generally available a cloud security management service that combines its existing cloud security posture management (CSPM) service and the cloud workload security (CWS) service to provide an integrated cloud-native application platform (CNAP) at no additional cost. In addition, Datadog is making it possible to block access to application components that are under attack or might be attacked in real-time based on the known vulnerabilities detected using tools that are currently in beta.

    That approach reduces the total cost of cybersecurity by providing IT teams with a single service through which they can manage application security using a platform Datadog gained last year with the acquisition of Sqreen.

    Finally, Datadog is making generally available a cloud cost management tool that leverages its monitoring capabilities to enable organizations to automatically attribute spend to applications, services and individual teams. Changes to spending patterns that impact costs are surfaced alongside the same tools IT teams are already using to monitor their cloud computing environment. That unified visibility increases awareness of costs in a way that encourages DevOps teams to optimize the utilization of multiple classes of cloud resources.

    The services being added are extensions of a Datadog platform that employs a single set of agents it provides. The Datadog platform also supports the open source OpenTelemetry agent to deliver a wide range of services. That approach eliminates the need for IT teams to deploy multiple agents each time they add an additional monitoring, security, testing or cost management tool.

    Datadog has been making a case for an integrated platform that reduces the level of integration effort DevOps teams would otherwise need to expend when deploying separate point products to address monitoring, observability, security and cost management issues. That approach makes it easier for DevOps teams to collaborate and reduces the total cost of DevOps. In contrast, each time a DevOps teams adds a point product to address a specific issue, they need to deploy and maintain a separate set of agents.

    In the longer term, it’s not clear how problematic that agent issue will be once open source OpenTelemetry agent software is more widely employed. However, it may still be years before open source software provides the same capabilities that are available today using proprietary agent software.

    It may take some time before every application is as fully instrumented as it should be, but as monitoring and observability platforms continue to evolve, it is possible to more proactively manage application environments.

  • More Choices, More Problems: The Double-Edged Sword of Multi-Cloud

    More Choices, More Problems: The Double-Edged Sword of Multi-Cloud

    Multi-cloud environments can be a double-edged sword. On the one hand, there are clear benefits to using whatever cloud or tool is best for your particular needs, regardless of vendor – in theory. In practice, however, the more choices you have, the more complex and expensive your environment becomes. In fact, Andreessen Horowitz postulates that multi-cloud architectures are oftentimes costing enterprises more than if they had stayed with on-premises systems.

    Enterprises need a multi-cloud environment to compete in such a rapidly expanding digital economy. For the majority of companies, completely repatriating to on-prem isn’t an option–the train has already left that station for most. But what do you do when the costs of staying competitive become more and more prohibitive, ironically making you less competitive?

    Hybrid Clouds Became Multi-Cloud

    When hybrid cloud–a mix of public cloud services and on-prem systems–became table stakes for enterprises, companies only needed one public cloud service provider. Most put all of their eggs in the AWS basket, splitting their workloads between AWS public cloud services and on-premises systems.

    This setup provided more agility and flexibility to enterprises and lowered costs by reducing dependence on expensive, cumbersome on-prem hardware. A lot of capex was replaced by opex; with cloud services, you only pay for what you use as you use it without the physical infrastructure and maintenance costs.

    Inevitably, the cost and efficiency benefits of the cloud drove companies to migrate more and larger workloads from their on-premises systems, increasing cloud costs over time. And the more workloads you had with a single vendor, the more beholden to that vendor you became. If AWS raised their prices, you had no alternative but to pay more.

    Soon, hybrid clouds grew into multi-clouds, with other public cloud providers such as Azure and GPC in the mix. Sometimes this was by choice–why be locked into one vendor and suite of tools when you could choose from multiple vendors that might offer better pricing or have some products that are better suited for your needs?

    More often, though, it was involuntary–developers spinning up their own clouds and resources for their own purposes without consulting IT, creating shadow IT. Or companies acquiring other organizations whose cloud choices varied. Either way, the enterprise is using multiple clouds whether they planned to or not.

    Regardless of how it happened, once more clouds were introduced, complexity multiplied.

    The Multi-Cloud Hydra

    Too many organizations underestimate the complexity they’re introducing with each additional cloud. Operating systems, networking, cost monitoring and tracking, workload methodologies and data aggregation are all different for each vendor. How many people in your organization know what all these differences are and how to navigate between them? How do you effectively manage, govern and monitor usage, costs and security and compliance issues when each public cloud does it differently? You have to manually collect data from each cloud and aggregate it in spreadsheets for analysis. How accurate can that be, how long does it take and at what cost in terms of people and time?

    Furthermore, how will you be able to accurately pinpoint waste and inefficiency? If you’re chasing down engineers to turn off resources or having to choose between one manual cost-efficiency action versus another, the waste will add up and your budget will be inaccurate.

    As if that’s not chaotic and complicated enough, development teams spread out across the enterprise adopt different tools and use them for their own purposes, without any alignment or coordination. The same tool is purchased multiple times. Best practices between teams aren’t shared. Everything needs to be custom-coded, creating layers of “spaghetti code” that blur visibility and are ripe for misconfigurations, which results in security vulnerabilities. And let’s not forget shadow IT, which IT departments don’t even know about, let alone monitor.

    You started your journey with a unified cloud strategy, but now you’re struggling with an ever-growing number of different clouds and strategies for different groups. Each group prefers different tools, clouds, methods and processes, and this has left you stuck with siloed teams, unending tool sprawl, infinite lines of custom code, worsening security risks and no clear visibility. And the meter keeps spinning, costing you millions.

    So, what do you do now?

    Taming the Chaos

    To survive and thrive in the new cloud order, enterprises can’t just write off exploding cloud costs as “the cost of innovation,” or otherwise justify their cloud chaos as par for the course. Too many are doing that now, and it won’t end well, as we’re likely headed into recession and growing uncertainty and turbulence in markets.

    First and foremost, taming cloud chaos and getting multi-cloud costs under control requires visibility and interoperability. You must be able to view, monitor, manage and analyze all clouds from one place; manually collecting that data with spreadsheets won’t do anymore.

    Development teams can no longer be siloed off from each other. There should be a single repository where all teams can access and utilize all tools, scripts, and previously coded integrations. When everything is viewable and available in a single place, no one has to buy the same tool twice or reinvent the wheel when using it. Once a tool has been integrated, any other team that wants to use that tool can simply re-use the integration, configuration, and policies that have already been created and vetted. If multiple groups are doing the same thing, an approved automation process can be created and shared.

    True cost optimization also requires organizational awareness and shared responsibility. If people don’t know they’re wasting resources, how will they be able to stop? Enterprises need a system that detects waste and cost overruns and notifies stakeholders accordingly.

    For example, a development environment may be up and running even though it’s no longer being used. An automatic alert could be sent to the appropriate team leader, reminding them to shut it down. A developer provisioning cloud resources might not choose the most cost-effective option, but the alert system would flag their activity and notify them of a cheaper alternative. Cloud resources that are left on overnight or on weekends would also be detected and shut down. Commitments would be conducted automatically every day and no longer require individuals to remember to do them manually.

    There’s just no going back to the traditional whack-a-mole style of cloud management and cost control. Enterprises that understand this and create a holistic framework for cloud management capabilities based on simplicity, visibility, unity and awareness will be in a much better position to navigate the choppy economic waters to come.

  • Oracle Enables Partners to Reuse Cloud Platform

    Oracle Enables Partners to Reuse Cloud Platform

    At its CloudWorld event, Oracle today announced it will enable IT teams to deploy the same platform it uses to independently deliver cloud services anywhere they see fit.

    Leo Leung, vice president of products and strategy for Oracle, said an Oracle Alloy offering will enable organizations to provide a full set of cloud services they can extend and brand as their own. All of the more than 100 infrastructure and platform services that the company makes available on Oracle Cloud can now be deployed anywhere, he said.

    In addition, Oracle unfurled a MySQL HeatWave service through which IT teams can access instances of the open source MySQL database running on the Amazon Web Services (AWS) cloud. A similar offering for the Microsoft Azure cloud is also planned.

    As part of an ongoing effort to gain share against rival cloud service providers, Oracle has been making a wide range of services available at a lower cost. Oracle Alloy now extends those efforts by making it possible for a wide range of organizations, including traditional enterprise IT organizations and internet service providers, to benefit from the company’s research and development efforts.

    Organizations that ally with Oracle can set their own pricing, rate cards, account types and discount schedules and define the support structure and service levels. A preconfigured instance of Oracle Fusion Financials to enable Oracle Alloy partners to manage customer invoicing and billing is also provided.

    It’s not clear to what degree these organizations might want to compete with cloud service providers such as Amazon Web Services (AWS), Microsoft and Google, but Oracle Alloy does provide an alternative approach to cloud computing that enables organizations to retain more control over the IT services they provide to others. The challenge, of course, is that acquiring the infrastructure is only one part of the equation. Organizations will also need to hire and retain IT specialists needed to manage cloud platforms on an ongoing basis.

    As the volume of applications being deployed in cloud computing environments steadily increases, Oracle clearly views Oracle Alloy as an opportunity to make up for lost ground in a market segment that it initially all but ignored when cloud computing first emerged more than a decade ago. Now, Oracle provides cloud services in 40 commercial and government regions across 22 countries. It has added 10 public cloud regions over the past year and has plans to add six additional commercial regions.

    Oracle is betting that, in some cases, partners will opt to deploy some cloud services themselves while relying on Oracle for others depending on the level of demand for specific classes of services. In effect, Oracle is enabling a set of federated cloud services to emerge that are no longer specifically tied to a single provider. It remains to be seen how receptive organizations will be to that approach, but it’s certain that the number of organizations that could afford to deliver cloud services could substantially increase. In theory, at least, increased competition should also lead to lower cloud costs for the organizations that consume those services.

  • DevOps Principles, Implementations and Culture

    DevOps Principles, Implementations and Culture

    When organizations begin using DevOps for application development, many only reference DevOps as part of their infrastructure and select a subset of DevOps before understanding the cultural and process changes needed for success. Instead, organizations must first determine which ‘Ops’ approach best promotes a DevOps mindset and integrate their workflows into their culture. In doing so, these organizations will better align their development and operations teams on common goals and protocols.

    There are many variations and subgenres of DevOps. However, it’s important organizations understand the ‘Ops’ choices available and choose the one that’s right for them.

    Principles Vs. Implementation Differences

    General DevOps and its subgenres can be split into two groups. The first and “purest” are the principles that these terms focus on unifying two or more industries with operations.

    The second type is those that focus on an implementation type.

    Principle Types

    DevOps: Improving Technical Processes and Culture

    DevOps is the overarching umbrella term for operations that combine Agile development concepts with IT operations and fast-tracks the development and deployment of applications in cloud environments. While there are different subgenres of DevOps, each subgenre is a different application of DevOps methodology, all geared toward making development more agile, stable and efficient. Because DevOps shortens the development life cycle by a significant margin, this streamlined approach to application development is quite popular.

    DevSecOps: Adding Security Checks

    DevSecOps bakes additional security measures into the workflow. Where DevOps typically has security checks at the end of a cycle, IT pros that leverage DevSecOps integrate security early and often in their DevOps journeys. With DevSecOps, collaboration between developers, security specialists and ops is crucial to maintaining agility and delivery speed, but the extra layers of security can slow processes down. DevSecOps leverages fast testing and robust pipelines to favor better code integrity. This method can be beneficial if an organization needs to elevate security during development.

    NoOps: Reducing In-House Teams for Operations

    NoOps is the lofty vision that DevOps is so automated it doesn’t require in-house expertise, meaning no manual intervention is required in processes. NoOps differs from DevOps because there is less focus on Agile and process management. This process assumes that developers do not need to know how to use the automated tools and uses continuous integration techniques to allow developers to focus only on application development.

    Though NoOps speeds up the deployment processes, if used by itself, NoOps lacks open communication and team management. Successful implementation of NoOps is only achievable if an organization does not have lofty technical goals or if its development team is small but strong and able to handle development and operations.

    GitOps: Using Git to Automate

    GitOps has been gaining traction in the development industry over the past two years because of its use of Git to automate continuous delivery pipelines. GitOps is a robust and manageable form of operations because it uses Git as the single source of truth for operations. In addition, due to developers’ familiarity with Git and pull requests, there is no complicated tool to learn, and changes to existing workflows are often unnecessary.

    The GitOps method can also boast that it is backed by some of the market’s most innovative cloud services, thus automating the process of building an update, testing for errors, reviewing code and pushing the update to production. Because Git is the only source of truth with GitOps, it is vital to effectively fortify the Git repository to avoid needless commits or pull requests.

    CloudOps: Implementing Cloud-Native Features

    CloudOps attempts to take more advantage of cloud-native features offered by modern service providers. Since CloudOps focuses on distributed development and deployment, there is no single point of failure, making the whole cloud environment more reliable. In addition, certain parts of the workflow in this type of operation can go stateless, making it cost-efficient as organizations only pay for the resources they actually use. Though CloudOps can be time and cost-efficient, organizations must get the configuration right for the approach to be beneficial, which could mean added complications to configuring CI/CD pipelines.

    CIOps: Requiring CI Operators for Configuration

    Continuous integration Ops (CIOps) is the latest iteration of DevOps, requiring CI operators to configure the infrastructure needed to support new code before deployment. The manual inputs necessary to ensure CI jobs’ correct configuration and deployment location bring advantages and disadvantages. Control over infrastructure allows two deployments to have different infrastructure configurations. The major disadvantages are the required manual intervention leaves room for error and the need to link an organization’s CI tool to its API can pose security risks.

    CIOps is better-suited for smaller development environments where automation is an inconvenience. While CIOps gives developers flexibility in configuring cloud infrastructures, the approach takes time and effort to run smoothly.

    ITOps: Automating IT Management Pipelines

    IT is loosely defined as the management of end user or employee systems. They are the systems that are required to run a core business. The fundamental difference is that there is little to no development. If your business doesn’t require a software engineering team and can function solely on prebuilt applications, then ITOps is for you.

    ITOps is in charge of delivering and maintaining services, applications and the underlying technologies necessary to run a business, covering jobs like system administrator and network administrator. ITOps focuses on updating laptops and office networks in addition to highly-tested commercial software and solutions for constructing the infrastructure, making updating infrastructure components more complicated. When using ITOps, an organization’s CIO will focus on managing the system via automation. 

    Choosing the Best Op for an Organization

    Choosing between the variations of DevOps is a matter of finding an approach that works best for the kind of apps the organization is developing and the cloud infrastructure they use. Though all of the above Ops strategies are based on unique ideas, they tend to focus on the technical side. Contrarily, DevOps stands out for its ability to comprehensively improve workflows and streamline technical processes while fostering a culture of innovation and collaboration in an organization.

  • Keeping the DevOps Pipeline Flowing as Attack Surfaces Grow

    Keeping the DevOps Pipeline Flowing as Attack Surfaces Grow

    The attack surfaces that today’s businesses and public entities must manage have never been more complex and difficult to protect. The introduction of cloud and SaaS offerings over the past decade has caused seemingly insurmountable IT sprawl, with a third of successful attacks now occurring via unmanaged or virtually unknown assets. And while shadow IT is an urgent threat confronting many organizations, the migration of the software development life cycle to the cloud—and the rise of machine identities—is compounding the attack surface in profound ways. Emerging out of the Agile and lean strategies for software development in the 2010s, DevOps predates the mainstreaming of cloud computing.

    But once the value of cloud-based IT resources came to be widely appreciated, development teams began moving their developer environments to the cloud in a big way—to the point where many people today think of DevOps and cloud as inseparable. Recent Gartner research showed that much of enterprise IT spending is now directed toward cloud projects. In fact, for IT categories like application software, infrastructure software, business process services and system infrastructure, more than 51% of IT spending will shift away from traditional solutions to the public cloud by 2025. Nearly two-thirds of spending on application software alone will be directed toward the cloud by 2025.

    The explosion in cloud DevOps has brought with it a huge uptick in the number of privileges, credentials, identities and access rights under management. We’re all familiar with how digital identity and access management (IAM) works in conventional settings through combinations of usernames and passwords. In the DevOps world, where cloud containers can run as distinct microservice processes interacting with other processes (machine-to-machine communication), identities and privileges are usually governed through SSL/TLS certificates. These machine identities have emerged as a critical security priority across multiple industries, not just because they’ve proliferated exponentially, but because of the lack of effective tools and strategies available to IT security teams.

    Machine Identities—Scope of the Issue

    A recent global survey of 1,000 CIOs found that the average organization has 250,000 machine identities under management coming into 2022, with that number expected to double by 2024. The study also found that 83% of organizations suffered a machine identity-related outage in the past year, with 57% of organizations experiencing at least one data breach or security incident related to compromised machine identities over the same time period.

    Because the perimeter defense solutions and strategies that formed the basis of IT security best practices for many years are of little use in cloud environments, security admins have had to rely on existing IAM and privileged access management (PAM) tools to secure data, accounts, and development pipelines. Not surprisingly, identities and access privileges have become the leading attack vector in the cloud, providing attackers with an exponentially higher number of vulnerabilities to target within the enterprise than were available even a few years ago. We’ve seen these points of weakness come into play in recent high-profile breaches and attacks such as SolarWinds, Codecov and PHP.

    Embracing Zero-Trust Principles to Secure the DevOps Pipeline

    Fortunately for today’s DevOps teams, cloud-oriented privilege management technologies have evolved rapidly in recent years, especially in the categories of cloud infrastructure entitlement management (CIEM) and time-based role access management or just-in-time privileging. CIEM solutions target the security weak points and process vulnerabilities that are unique to the cloud environments. These include the lack of deep visibility into user, group, and role privileges, which together make it difficult to conduct oversight and control over the activities of users within cloud infrastructure and applications. Where conventional approaches such as IAM and PAM are designed primarily to secure data, apps, and users within the organization, CIEM is designed to manage permissions risks to prevent cloud breaches and data theft.

    Emerging CIEM solutions are bringing to bear advanced capabilities in discovery, monitoring and auditing to significantly broaden visibility into DevOps processes for IT security professionals. With a CIEM solution, security teams can scan cloud applications for existing users, groups, roles and granted privileges down to the resource level. Each user, group, role, and privilege can be categorized to identify and verify that privileged users have the appropriate levels of access. Access reports can be generated to concisely outline users and groups with the most privilege and the highest risk.

    On the audit front, CIEM solutions provide the capability to track and report on levels of privilege as well as all activity associated with those privileges. In this way, it becomes possible to generate privileged access reports for consumption by internal and external auditors to ensure compliance with regulatory and other requirements such as SOX, GDPR, HIPAA, GLBA, PCI-DSS, ISO 27001, SOC 2, FedRAMP and more. Similarly, with the ability to monitor privileged access across all cloud applications, security teams can apply behavior analysis to identify privilege abuse and abnormal activities from users. As with conventional SIEM tools, CIEM solutions will generate alerts to administrators to suspect activities or behaviors—for instance, if a user attempts to circumvent policies preventing direct privileged access to cloud services.

    Just-In-Time Privileging and Zero Standing Privileges

    Importantly, CIEM solutions are also effectively eliminating standing privileges to cloud resources based on least-privilege access and zero-trust principles. The automated granting and expiring of permissions—just-in-time (JIT) privilege grants—is highly effective at minimizing attack surfaces. Because these JIT/zero standing privilege (ZSP) solutions work on a zero-trust model, no one and nothing is trusted with standing access to cloud accounts and data.

    With JIT permissioning, elevated privileges can extend either for the duration of a session or task, or for a set amount of time. Once the task is complete, those elevated privileges are automatically revoked–all without sys-admin involvement. Where a user previously had standing access privileges potentially extending around the clock for months at a time, converting to JIT granting would compress that attack surface to several hours per month. Further, JIT permissioning largely frees organizations from having to maintain and pay for both privileged and non-privileged accounts. Dynamic secrets generation – where a dynamic secret is generated on demand and is unique to a client, instead of a static secret being defined and shared ahead of time – also provides a better model for securing temporarily deployed services and features.

    DevOps and DevSecOps are still new and fast-evolving concepts within the wider computer science and cybersecurity universe. No doubt, DevOps has been wildly successful in accelerating automation and speeding time to market for innovative applications and business services. To date, however, security solutions providers have struggled with cloud access management. In other words, they have struggled to accelerate privileged access solutions that could secure the devices, data, and resources used by DevOps teams, especially in cross-cloud environments. Dynamic permissioning platforms using JIT privilege grants and employing ZSP principles show great promise in solving these problems.

  • Google Looks to Secure Software Supply Chains

    Google Looks to Secure Software Supply Chains

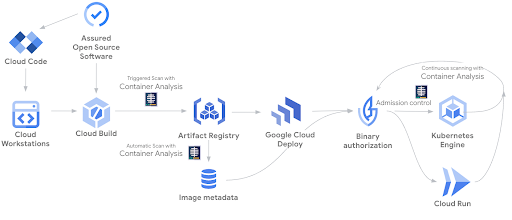
    At the Google Cloud Next ’22 conference, Google today launched a managed Software Delivery Shield (SDS) service to enable DevOps team to store, manage and secure the build artifacts in Artifact Registry. At its core, SDS is based on a trust-based policy engine to establish, maintain and verify a chain of trust across the software supply chain.

    In addition, Google has updated its container analysis tool to include vulnerability scanning for Maven and Go containers along with preview support for non-containerized Maven packages.

    The managed Software Delivery Shield service spans a range of Google runtimes environments, including Google Kubernetes Engine (GKE), Cloud Code, Cloud Build, Cloud Deploy, Artifact Registry and Binary Authorization. Cloud Build also now officially supports Supply chain Levels for Software Artifacts (SLSA) Level 3 best practices by default in addition to generating authenticated and non-falsifiable build provenance for both containerized applications and non-containerized Maven and Python packages.

    GKE, in preview now, provides detailed assessments, assigns severity ratings and surfaces the security posture of the clusters and workloads, including insights into operating system vulnerabilities, workload configurations and other actionable insights. Log data can now also be captured while security event information can be routed to, for example, a security information and event management (SIEM) platform.

    The Google Cloud Run serverless platform can also, in preview, display software supply chain security insights such as SLSA build-level compliance, build provenance and vulnerabilities found in running services.

    At the same time, Google is also making available in preview Cloud Workstations, which provide fully managed secure development environments on Google Cloud that can be accessed via a browser. Built-in security capabilities include virtual private cloud (VPC) controls, no local storage of source code, private ingress/egress, forced image updates and identity access management (IAM) policies.

    Finally, the Cloud Code plug-in for integrated development environments (IDEs) now includes a preview of Source Protect to give developers real-time security feedback in the form of vulnerability dependencies and license reporting as they write code.

    Collectively, Google claimed it now provides more than 250 curated packages across Java and Python with verified provenance. It also automatically generates a software bill of materials (SBOM) to create an inventory of all components and dependencies.

    Historically, cloud service providers have been advocating a shared responsibility approach to cloud security that required organizations to not only secure their applications but also the way cloud infrastructure is provisioned. The challenge is developers generally provision cloud infrastructure themselves even though they generally have limited cybersecurity expertise. Too many developers assume the underlying cloud infrastructure is more secure than it actually is.

    Now, cloud service providers are extending the security services they provide at a time when organizations are making security a bigger factor in determining where to build and deploy applications.

    Sunil Putti, vice president and general manager for Google Cloud Platform, said Google is attempting to make cybersecurity invisible to developers in the sense that guardrails will automatically be embedded within the platform.

    The issue is that cloud computing environments are becoming more complex as new classes of cloud-native applications are deployed alongside legacy monolithic applications. Complexity, as always, is the enemy of cybersecurity.

  • GitLab Allies With Google to Improve Developer Productivity

    GitLab Allies With Google to Improve Developer Productivity

    GitLab Inc., in collaboration with Google, today launched an open source Cloud Seed tool that makes it simpler for DevOps teams to consume Google Cloud Platform (GCP) resources.

    The Cloud Seed tool, announced at the virtual Google Cloud Next ’22 conference, is integrated within the GitLab web UI to make it simpler for developers to consume Google cloud resources—such as Cloud Run for building and deploying containerized applications—and the managed Cloud SQL database service.

    Nima Badiey, global vice president of alliances for GitLab, said the goal is to reduce friction that would otherwise be created by requiring developers to write code to consume these services using a set of lower-level application programming interfaces (APIs).

    That self-service approach not only improves productivity but provides the added benefit of reducing the odds those services might be misconfigured in a way that creates a cybersecurity vulnerability, he added.

    As it seeks to gain ground on Amazon Web Services (AWS) and Microsoft, Google has a vested interest in working with providers of DevOps platforms to make it simpler for developers to consume cloud resources. The challenge is that developers often make mistakes when they programmatically invoke cloud services. Those resulting misconfigurations are all too often not discovered and remediated until after there has been some type of cybersecurity incident.

    In the wake of a series of high-profile breaches of software supply chains, there is a lot more focus on security. The challenge, of course, is finding a way to ensure application development platforms are as secure as possible without slowing down the rate at which software is developed and deployed. Achieving that goal requires the right mix of policies, training and systems, said Badiey.

    Most organizations are trying to strike a balance between the need for greater security and their need to attract and retain developer talent. In theory, the rise of DevSecOps best practices is pushing more responsibility for security further left toward developers. However, most developers have little to no cybersecurity expertise, so it’s clear more guardrails need to be built into DevOps tools and platforms to prevent cybersecurity mistakes from being made.

    It’s not clear how much improved developer productivity and greater security will drive organizations toward one cloud platform versus another, but in an age where many more organizations now routinely employ two or more cloud platforms, it could make a significant difference. Developers don’t especially enjoy remediating applications after they are deployed in a production environment because they have generally already moved on to other projects. IT operations and cybersecurity professionals are also likely to nudge developers toward platforms that create the least amount of operational overhead for them.

    Regardless, one thing that is certain is compliance requirements are about to become stricter for all concerned as scrutiny of software supply chains intensifies in the months ahead. The issue now is how to proactively address those requirements before they become a much larger issue.

  • Low-Code/No-Code Options Key to Bringing Web3 Mainstream

    Low-Code/No-Code Options Key to Bringing Web3 Mainstream

    Driven by cryptocurrencies and NFTs, Web3 is one of the most talked about technology industry waves in the last several years. But even with all the money it’s generated and the media coverage received, Web3 hasn’t yet gained the mainstream acceptance that Web2 has achieved. One of the main reasons for this gap is that blockchain-based technology continues to be complex, requiring developers to learn new languages and development environments as well as gain expertise in concepts like cryptography, hashing, oracles, zero-knowledge proofs, proof of work, proof of stake and more. And even once users understand that they then need to figure out how these pieces all fit together. The required time and money investment has slowed adoption by developers—until now.  

    Web3 is finally coming into its own, thanks in part to the abstraction provided by SDKs and APIs. This technology is making it increasingly possible for all developers, not just Web3 developers, to participate and innovate on this new wave of technology disruption.

    If you look at many of the providers in Web3 like Infura (ConsenSys), NFT Port and OpenSea, for example, and their growth, there’s been a significant movement from these providers over the past couple of years from simply providing nodes for underlying blockchains to now offering higher-level APIs. This translates into developers and companies no longer having to set up their own nodes to provide SDKs and higher-level APIs that rely on data indexers and pre-audited smart contracts to simplify token minting and reading from blockchains. 

    With the evolution of APIs and SDKs, developers using these programs no longer have to learn the intricacies of creating contracts on different blockchains, multiple developer tools, syntax and languages nor must they possess a deep understanding of these different blockchains. Instead, developers can rely on APIs that abstract the underlying complexity, easing the burden for developers who need only pass parameters like chain for indexing, token or smart contract IDs and other general-purpose information. These APIs will evolve into providing more low-code/no-code offerings with larger graphical UI components that developers can simply drag-and-drop to extract value as well as create DApps that can also be retrofitted into their existing applications or app infrastructure. 

    This evolution will be similar to the way the cloud evolved; look at AWS’ and Azure’s infrastructure-as-a-service (IaaS) as a current example. Existing apps could be lifted and shifted onto the cloud. This led to platform-as-a-service (PaaS) offerings with APIs that were cloud-ready; with developers’ latency, security and scalability needs augmented by low-code or no-code offerings. This is also similar to Microsoft’s Power Platform which used drag-and-drop operations on many cloud components, allowing integration and extensibility of the Microsoft platform in a short amount of time. This spawned a new generation of ecosystem players as the bar to participate and innovate in the cloud lowered; now every type of developer, no matter what their area of expertise, can take advantage. This also meant that the new technology was accessible for all developers to solve business challenges more quickly while significantly decreasing time-to-market.  

    You can already see this parallel in the Web3 world. A lot of the key players building developer tools are starting to target the business and technical decision-makers. They are talking about how easy it would be for Web2 developers to leverage their high-level APIs and SDKs (something that Web2 developers understand extremely well) to use Web3 technology to solve new business challenges. And they can do so without setting up expensive innovation organizations and looking for scarce (and expensive) Web3 developers. The next step in this evolution would be to extend these APIs for NFTs, analytics, streaming, MEVs, estimating gas and more to have no-code, automatically generated components that finally allow more Web2 developers to transition to Web3 and, as a result, bring Web3 into the mainstream.