Category: DevOps in the Cloud

  • Three Strategies for Reducing MTTD and MTTR as Outage Costs Spiral

    Three Strategies for Reducing MTTD and MTTR as Outage Costs Spiral

    According to a New Relic survey of IT professionals, the median annual cost of IT outages has reached an astronomical $7.75 million. Over one-third of the 1,700 respondents said critical business application outages now cost more than $500,000 per hour. In a business environment where most interactions with customers, suppliers and business partners are conducted digitally, downtime has become a problem and an existential threat.

    Most IT organizations carefully monitor two key metrics — mean time to detection (MTTD) and mean time to resolution (MTTR) — to track their success in identifying and remediating critical systems issues. The figures represent, respectively, the average time it takes administrators to identify that a problem has occurred and to remediate the underlying issues. They serve as a benchmark for understanding the organization’s level of awareness of the status of its systems and the speed with which problems can be diagnosed and acted upon.

    There are many ways to improve performance against these metrics, but three stand out as the most effective, as evidenced by New Relic and the survey results.

    Monitor Everything

    The less you know about a problem, the longer it takes to diagnose and fix. The New Relic survey measured 17 different observability categories, such as network monitoring, alerts, log management, browser monitoring and distributed tracing. Across the board, about two-thirds of the companies that used even one of those monitoring tools reported reduced MTTR, with many saying resolution times had fallen by more than 25%.

    One-third of respondents whose organizations implemented full-stack observability—which is the ability to see everything in the tech stack that could affect the customer experience—reported the fewest outages, fastest MTTD and MTTR, lowest outage costs and highest median annual return on investment compared to all respondents. For example, those who have full-stack observability experience a median outage cost that is 37% less than those without.

    As the complexity of enterprise technology stacks increases, so does the difficulty of pinpointing the root cause of an outage. Any monitoring is better than no monitoring at all, and the more visibility you have into applications and infrastructure the faster you can identify and resolve incidents. Strive for full-stack observability around integrated observability data and a comprehensive dashboard.

    Have an Incident Management Action Plan

    The worst time to figure out how to resolve a problem is when you’re in the midst of a crisis. Organizations with mature observability practices also have extensive and documented response plans.

    Your incident plan will be unique to your organization. Small companies and startups tend to have ad hoc response strategies based on the skills within the organization. Large enterprises may use a more formal methodology like IT service management that defines strict procedures and protocols. Companies that have embraced modern DevOps and Lean principles often use a hybrid approach that depends heavily on teamwork and collaborative problem-solving. All of these approaches can work if the team fully understands the chosen strategy.

    Document your IT architecture, identifying known vulnerabilities and outlining procedures for responding to the most common types of incidents. Plans should cover obvious disruptions like fires and power outages, but you should also think about “unicorn” scenarios such as a rogue query that ties up a database server or a communication outage at a key supplier. Mature observability teams devote a portion of their resources to constantly testing new and unpredictable scenarios and use chaos engineering to randomly inject problems in a controlled manner to see if systems respond as expected.

    As you develop incident response procedures, document the processes in runbooks, which tell responders exactly what to do when a specific problem occurs. This not only creates a database of organizational knowledge about response strategies but also helps with onboarding new employees and covers for skills gaps that occur when team members are unavailable or leave the company.

    Fix for the Future

    Technical debt is a long-term obligation that is created when a short-term – and incomplete – solution is applied. You should aim to minimize it in your observability operation.

    When a problem occurs, the temptation is to fix it as quickly as possible. Human nature is to move on to the next task without taking the time to go back and understand why a problem occurred. “Quick and dirty” fixes are an invitation to larger problems in the future. Your observability plan should include a forensics stage that documents root causes and the fixes that were applied. Even if it isn’t convenient to implement a long-term solution immediately, the documentation serves as a guide for implementing a permanent fix down the road.

    Building a resilient IT architecture is a marathon, not a sprint. The more rigor you apply to identifying and resolving problems when they happen, the better prepared you will be to prevent their reoccurrence and the more informed your team will be about the resources they manage. Reducing your MTTD and MTTR will not only improve the bottom line of your business, it will ensure that your customers have an amazing digital experience.

  • Bitrise Tightens Mobile DevOps Integration With AWS Cloud Services

    Bitrise Tightens Mobile DevOps Integration With AWS Cloud Services

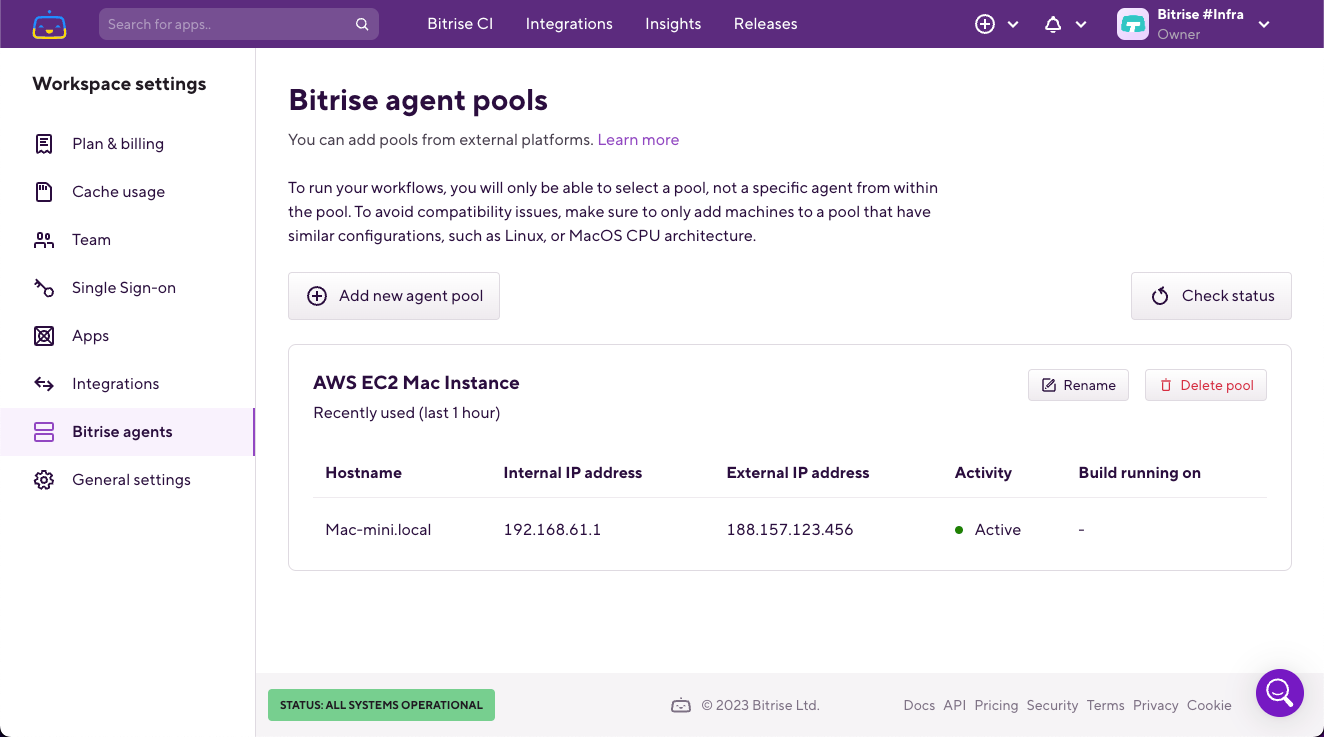
    Bitrise this week will tighten integration with its DevOps platform for building and deploying mobile applications and the application development services provided by Amazon Web Services (AWS) cloud.

    Announced at the AWS re:Invent 2023 conference, the goal is to provide easier access to automated building, testing and release management capabilities provided by AWS as part of an effort to increase overall efficiency.

    Bitrise CEO Barnabas Birmacher said those capabilities will streamline workflows for a Bitrise Mobile DevOps platform that has been specifically designed for building and deploying mobile applications that typically need to be updated frequently.

    Based on a continuous integration/continuous delivery (CI/CD) platform developed by Bitrise that can be deployed in an AWS cloud computing environment, the integrations will make it simpler to build and run mobile applications at scale, noted Birmacher.

    The goal is to reduce the total cost of building mobile applications while at the same time improving developer productivity for mobile applications that have to be thoroughly tested before being made accessible via an application store, he added.

    It’s not clear how many organizations will prefer to have a dedicated CI/CD platform for building and deploying mobile applications versus using the same CI/CD platform they might already be relying on to build and deploy other applications. Bitrise claims to have more than 6,000 customers, including Reddit, WISE, Equinox and Philips Hue.

    As the percentage of mobile applications that make up an organization’s portfolio continues to increase, the pace at which those applications need to be updated lends itself better to a CI/CD platform optimized for those types of applications, said Birmacher.
    In fact, a recent survey conducted by Bitrise found 62% of respondents have been adversely impacted by manual processes that slowed the rate at which mobile applications were deployed and updated. The survey also found (44%) of respondents reported their release approval process is mostly or entirely manual, with only 9% having fully automated application releases.

    The survey also found that nearly two-thirds of organizations (66%) have deployed applications that can’t be opened in two seconds or less, which is widely considered the accepted level of performance required for mobile applications. In addition, three-quarters of organizations (75%) required more than two days to address bug fixes.

    Many mobile apps have become increasingly mission-critical thanks to digital business transformation initiatives. Consequently, the amount of focus on them within most organizations is high; any issues that arise are likely to be noticed at the highest echelons of an organization. That level of attention can easily put pressure on DevOps teams, mainly because the general expectation among end users is that mobile applications will be regularly updated with new functionality. However, if release processes are largely manual, regularly improving the user experience can become problematic.

    Each IT organization will need to decide for itself how best to go about building and deploying mobile applications, but the one thing that is certain is adjustments to DevOps workflows will need to be made as a lot more of these applications are continuously built, deployed and updated.

  • Couchbase Adds Columnar Database to DBaaS Environment

    Couchbase Adds Columnar Database to DBaaS Environment

    At the AWS re:Invent 2023 conference today, Couchbase, Inc. announced it added a columnar database based on the JSON file format to its database-as-a-service (DBaaS) portfolio to enable organizations to build real-time analytics applications.

    Scott Anderson, senior vice president for product management and business operations at Couchbase, said the Capella columnar database is designed to be integrated with the company’s JSON-based document database via a database change protocol (DCP) that Couchbase has embedded within its DBaaS environment.

    Deployed on cloud services from Amazon Web Services (AWS), the overall goal is to reduce the level of friction that IT teams would otherwise encounter when integrating a document database with a columnar database optimized to process analytics using columns rather than the rows typically associated with a relational database.

    That approach gives IT teams the ability to use a schemaless database architecture that provides an alternative to employing disparate databases that would need to be deployed and then integrated using extract, transform and load (ETL) processes to move data from one database to the other, noted Anderson.

    Capella columnar also uses the same SQL++ language as the company’s document database to streamline queries in addition to supporting Capella iQ, a copilot based on generative artificial intelligence (AI) that enables queries to be crafted in natural language.

    In addition, Capella columnar provides connectors to move data from Amazon DynamoDB, Amazon DocumentDB, Amazon Relational Database Service (Amazon RDS) and other data sources deployed on the AWS cloud.

    In the longer term, Couchbase is also planning to add vector capabilities to its DBaaS environment to make it simpler to securely extend generative AI models, said Anderson.

    In general, document databases have been widely adopted because they provide developers with an alternative to legacy database platforms that they can download and deploy themselves. The Capella DBaaS platform further simplifies that process via a managed service through which Couchbase assumes operational responsibility for managing databases. The columnar database extends that capability using a columnar database that can drive analytics capabilities to deliver a more personalized application experience, noted Anderson.

    It’s not clear to what degree organizations will ultimately wind up relying on as-a-service platforms, but since the start of the COVID-19 pandemic, the shift to this approach to consuming IT resources has increased significantly. As a result, the way internal IT teams are organized is shifting as lower-level tasks are either automated or handled by an external IT team that works for a vendor.

    Regardless of how databases are managed, however, there remains a need to integrate the data operations (DataOps) processes used to manage them with the DevOps workflows used to build modern applications. Each organization will need to determine how much economic sense it makes for them to manage that data versus relying on an external services provider. The challenge when relying on an external service provider is, as always, integrating that service into an existing IT environment.

  • How DevOps Teams Can Unlock Cloud Savings and Improve DevEx

    How DevOps Teams Can Unlock Cloud Savings and Improve DevEx

    Can DevOps engineers unlock cloud cost savings for their organization that are incremental to what cost optimization tools offer (and improve the developer experience in the process)? Absolutely. Allow me to illustrate how.

    Reserve instance buying optimization and auto-stopping are proven tactics to reduce waste, but are those the only forms of waste that exist in your cloud budget? Of course not.

    Think about all the times environments have been brought up and then stayed up longer than required. Consider all of the times a commit changed the way data is stored, which spiked the cost to operate. Or how about the times when a commit changed how memory was used, which resulted in unexpected autoscaling?

    Collaborative Cost Management

    So the question becomes, what is the most efficient way to identify and root out additional savings while also balancing governance and agility? Bottom-up, collaborative cost management may offer a solution.

    A bottom-up approach to cost management involves pushing knowledge and functionality to the edge of the application and data engineering teams that own and operate code every day. This does not mean ceding centralized cost control to developers but rather arming them with timely, actionable insights inside their everyday workflow and, where appropriate, enabling action on a self-serve basis.

    How does this work in practice? It starts by enabling engineering teams to see the costs of the various services and environments they own on a timely basis. This helps teams understand when spikes occur and provides a path they can follow to understand why the spike occurred.

    That path can involve bringing different pieces of information together for engineering teams. They’ll want to see the costs of the individual resources that power their service or environment during the selected timeframe to see what spiked and maybe even drill down further to see the cost drivers of that individual resource. They’ll likely want to see deployments and commits, at a minimum, and maybe even explore observability data as well during this timeframe.

    Once they’ve identified a root cause, to the extent it involves needing to change a configuration setting of a resource, teams may want to understand a resource’s dependents, like other resources that are linked to it as well as any other environments and services that depend on it to size up the blast radius of a potential change. From there, they may wish to view config settings for the resource.

    Collaborative Discussion

    Finally, you want to give teams the ability to take certain actions on their own and, in other cases, foster a collaborative discussion between engineering and DevOps. You can accomplish the former via self-service actions, which are simple no-code workflows in which a developer can see if the DevOps team has allowed an action to be seen by a specific team for a resource via a role-based access control (RBAC) model. These workflows connect to your existing infrastructure-as-code (IaC) or CI/CD tools to orchestrate the desired change, leveraging golden paths defined by DevOps. This approach alleviates developers’ cognitive load and TicketOps for the DevOps team. For various changes that require coordination with DevOps, your engineering teams can have a collaborative discussion on a timely basis thanks to the fresh, actionable information you’ve made available to them.

    So what does it take to actually implement this vision? It’s easier than you might realize.

    Chances are, your existing cost optimization tool cannot provide cost visibility at the level of granularity and freshness developers need – daily cost insights at the service (or data pipeline, ETL job, etc.) level. That’s okay, though. Collaborative cost management is an incremental tactic that can still leverage some of the insights in these tools.

    The easiest way to facilitate this competency across your enterprise is via an internal developer portal. Internal developer portals are living sociotechnical knowledge maps that connect various data from your tools, clouds and teams to your services and the teams that own them. They are the perfect conduit to slice cloud cost data at the service level and put it in front of application and data engineers in their everyday workflow.

    Backstage, an open source framework to build a developer portal, offers a cloud cost plugin, though it involves a time commitment to set up, and the information it makes available to your developers may be limiting in the context of this scenario. For instance, your team may be unable to see per-resource costs, individual resource cost drivers, blast radius information and config settings. You must also expend effort wiring actions to support resource changes.

    You could also try building a BI dashboard for your team to accomplish this. This would require ingesting daily cost feeds from your cloud and then allocating the cost of each resource to each environment and to each service leveraging proprietary resource<->environment<->service mappings you would build and maintain as your system evolves. You would also need to build scripts and leverage IaC and CI/CD tooling and teach your engineers how to discover, configure and execute these actions.

    However you choose to get to this destination, collaborative cost management is a powerful emerging competency that can lead to meaningful savings and improve the developer experience by empowering your teams with the knowledge and functionality they need to manage costs on a proactive and, where appropriate, self-service basis.

  • Microsoft Previews Additional Copilot Tools for Azure

    Microsoft Previews Additional Copilot Tools for Azure

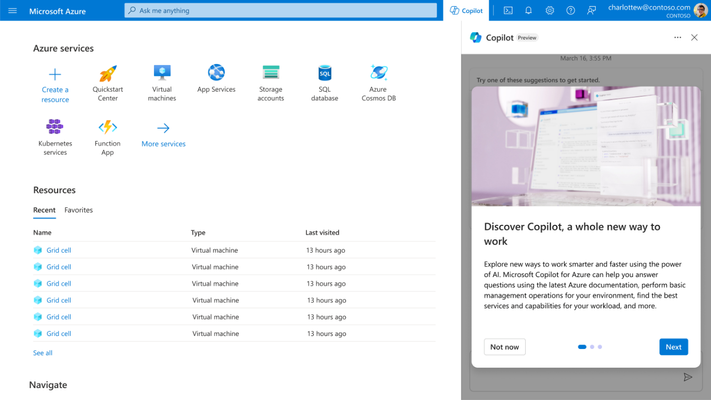
    At its Ignite 2023 conference, Microsoft this week previewed Copilot tools to simplify the management of the Azure cloud service along with a tool that streamlines the building and deploying of artificial intelligence (AI) applications on the Azure platform.

    In addition, Microsoft launched Microsoft Copilot Studio, a low-code tool that automates the process of creating data integration plugins and adding custom copilots within the Microsoft Copilot for Microsoft 365 tool that Microsoft previously launched.

    Microsoft Copilot for Azure leverages large language models (LLMs) to enable IT teams to use natural language to create, configure, discover and troubleshoot Azure services. It also enables IT teams to create complex commands, ask questions and optimize costs.

    Erin Chapple, corporate vice president for Azure Core at Microsoft, told Ignite attendees that Microsoft, along with a handful of customers, is already using Microsoft Copilot Azure to manage Azure infrastructure.

    In the long term, it’s clear that Microsoft is moving toward streamlining the building and deployment of AI applications using Azure AI Studio, a framework for invoking the AI models that Microsoft makes available on the Azure platform. The goal is to make it possible for organizations to create their own copilots based on AI models they have trained.

    It’s still early days in terms of organizations leveraging AI models to build applications, but it’s already apparent that DevOps and machine learning operations (MLOps), along with data engineering and cybersecurity best practices, will need to converge. Microsoft is making a case for Azure AI Studio as the framework that will enable IT organizations to achieve that goal.

    Of course, Microsoft is not the only provider of IT infrastructure resources with similar ambitions, but thanks to its investments in OpenAI and the acquisition of GitHub, it is furthest along in terms of defining a framework for building AI applications at scale. Last week, GitHub previewed an extension of the Copilot tools it already provides to help developers write code that leverages generative AI to automatically propose an editable plan for building an application based on natural language descriptions typed into the GitHub Issues project management software. Copilot Workspace will generate editable documents via a single click that can be used to create code that developers can then visually inspect. Any errors discovered by application developers or the Copilot Workspace platform can also be automatically fixed.

    At the same time, GitHub has extended the scope and reach of Copilot Chat to make it simpler for developers to use natural language to discover issues in their code base.

    Generative AI is already having a massive impact on the rate at which applications are developed, but that code still needs to be reviewed. Chat GPT is based on a general-purpose large language model (LLM) that is trained by pulling in code of varying quality from all across the web. As a result, code generated by the platform might contain vulnerabilities or be inefficient. In many cases, professional developers still prefer to write their own code.

    Of course, not every programming task requires the same level of coding expertise. In many instances, ChatGPT will generate, for example, a script that can be reused with confidence across a DevOps workflow. There is no shortage of mediocre developers who are now writing better code thanks to tools such as GitHub Copilot, and soon, domain-specific LLMs will make it possible to consistently write better code based on validated examples of code.

    The next challenge is going to be finding a way to manage increased volumes of code. There is no doubt that AI will be applied to the management of DevOps pipelines, but for the moment, at least, the pace at which AI is being applied to writing code is already exceeding the ability of DevOps teams to manage it.

  • Redgate Automates Pulling of Test Data From Production Databases

    Redgate Automates Pulling of Test Data From Production Databases

    Redgate today added a Redgate Test Data Management (TDM) tool that automates the pulling of masked test data from databases running in production environments.

    David Gummer, chief product officer for Redgate, said this capability eliminates manual tasks that previously inhibited testing or resulted in personally identifiable information (PPI) being inadvertently used to test applications.

    Redgate TDM automatically classifies and masks data residing in SQL Server, PostgreSQL, MySQL or Oracle database before it is used to test an application. It then produces a copy or clone of that data that is a fraction the size of the original, said Gummer.

    That approach creates a repeatable process for DevOps teams that can withstand a regulatory audit of application development processes, he added. In fact, with the increased focus on software supply chain issues, more auditors are specifically reviewing how data is secured during the application development process.

    Designed to be invoked via a command line interface (CLI), within an integrated development environment or via a graphical interface, Redgate TDM reduces the friction that currently occurs when DevOps teams request test data from database administrators (DBAs), said Gummer. Many DBAs are either too busy to fulfill those requests or reluctant to provide access to sensitive data that would result in the organization running afoul of a compliance mandate.

    Developers then often resort to using anonymous data that doesn’t actually reflect the environment in which their application will ultimately be deployed.

    The amount of data that developers need to build applications is only going to increase. In the absence of any way to effectively automate the process of accessing that data, it ultimately takes longer to build and deploy stable applications. In many cases, applications are simply not tested as thoroughly as they should be before being deployed in a production environment, resulting in rollbacks that might otherwise be avoidable.

    Advances in artificial intelligence (AI) are making it easier to create test scripts, but much of the testing setup process is still based on manual processes that increase the overall level of toil.

    At a time when more organizations than ever are trying to increase developer productivity, automating relatively mundane tasks such as pulling test data can have a big impact. Developers want to spend as much time as possible focused on writing code. Everything else is a task that gets in the way of achieving that goal. While there is a general desire to empower developers, that doesn’t necessarily mean they want the cognitive load associated with building applications to increase. In fact, one of the reasons platform engineering has emerged as a methodology for managing DevOps workflows at scale is to reduce the current level of cognitive load developers experience today.

    Of course, DevOps teams are, by their nature, ruthlessly committed to automating as many processes as possible. The challenge is bottlenecks in those processes conspire to slow down the overall rate at which applications can be built and deployed despite the best intentions of all involved.

  • What the Future Holds for FinOps and DevOps

    What the Future Holds for FinOps and DevOps

    FinOps, or financial operations, is a cultural practice that brings financial accountability to the variable spend model of the cloud. It’s a strategic approach combining systems, best practices and culture to increase an organization’s ability to understand cloud costs and make informed decisions.

    In essence, FinOps is a framework for managing cloud operating expenses (OpEx). It’s about bringing together technology, business and finance professionals to ensure that companies can get the most out of their cloud investments. The goal is to provide businesses with a better understanding of their cloud usage and costs, enabling them to make strategic decisions about resource allocation and cost management.

    FinOps bridges the gap between finance and operations. It’s not just about monitoring costs; it’s about understanding why those costs occur, how they relate to business value and what can be done to optimize them. It’s a comprehensive, cross-functional and continuous approach to managing cloud expenses, ensuring that businesses can maximize their return on investment (ROI) in the cloud.

    What Does FinOps Mean for DevOps Teams?

    Traditionally, DevOps has been focused on improving the speed, efficiency and quality of software delivery. But with the advent of cloud computing, cost has become a crucial factor. The dynamic nature of the cloud, with its pay-as-you-go model, means that costs can quickly spiral out of control if not properly managed. This is where FinOps comes in.

    Budget Responsibility

    As a DevOps team member, you’re likely used to thinking in terms of speed, performance, and quality. With FinOps, you need to add cost to that equation. You’re not just responsible for delivering high-quality software quickly; you’re also accountable for the cost of that delivery. This requires a shift in mindset, moving from a project-based budgeting approach to a product-based one.

    In a project-based approach, you have a fixed budget for a specific project. Once the project is finished, so is the budget. In a product-based approach, on the other hand, you’re responsible for the ongoing costs of a product throughout its life cycle. This means you need to consider not just the cost of development, but also the cost of maintenance, support, and continuous improvement.

    Resource Optimization

    In the context of FinOps, resource optimization is all about making sure you’re getting the most bang for your buck. You want to ensure that you’re using your cloud resources as efficiently as possible, minimizing waste and maximizing value.

    Resource optimization can involve a variety of strategies, from rightsizing instances to eliminating idle resources. But it’s not just about cutting costs; it’s also about aligning costs with value. You need to understand the value that each resource brings to your organization and allocate costs accordingly. This requires a deep understanding of your cloud usage and a commitment to continuous monitoring and improvement.

    Collaboration With Finance

    One of the key aspects of FinOps is the collaboration between DevOps and finance. You’re no longer working in silos; you’re part of a cross-functional team working towards a common goal. This requires open communication, mutual understanding, and shared responsibility.

    As a DevOps team member, you need to understand the financial implications of your decisions. You need to be able to articulate the value of your work in financial terms, demonstrating how your efforts contribute to the organization’s bottom line. At the same time, you need to be open to feedback and guidance from your finance colleagues, learning from their expertise and incorporating their insights into your decision-making process.

    Performance Metrics

    Performance metrics are crucial in the world of FinOps. They provide the data you need to understand your cloud usage, monitor your costs and make informed decisions. But these aren’t just any metrics; they’re metrics that align with your business goals and reflect the value of your cloud investments.

    These metrics might include cost per workload, cost per user or cost per unit of output. The key is to choose metrics that make sense for your organization, providing meaningful insights that can guide your resource allocation and cost management efforts. And remember, these metrics need to be regularly reviewed and updated to reflect changes in your cloud usage and business needs.

    Automation of Cost Controls

    Automation is a key tool in the FinOps toolkit. It can help you streamline your cost management processes, reduce manual effort and increase accuracy. From automated alerts to automated remediation, there are many ways automation can improve your FinOps efforts.

    With automated alerts, you can be notified when your cloud costs exceed a certain threshold. This allows you to respond quickly, addressing issues before they become major problems. With automated remediation, you can take this a step further, automatically adjusting your cloud resources in response to changes in demand or performance.

    Future FinOps Trends

    The year 2024 promises to be an important one for FinOps, with several trends poised to redefine the landscape:

    1. AI Algorithms for Cost Analysis and Prediction

    The use of AI algorithms for real-time cost analysis and predictions is predicted to be a major trend in 2024. AI enables the automation of complex financial calculations and projections, allowing for more accurate and timely decision-making. AI is already not just analyzing and predicting costs but also providing actionable insights to optimize these costs.

    The power of AI in FinOps lies in its ability to process massive amounts of data quickly and accurately. It can analyze past and current financial data, identify patterns, and predict future trends. This means that instead of reacting to financial changes after they happen, you can be proactive and make strategic decisions based on accurate predictions.

    The use of AI in FinOps will also enhance risk management. By predicting potential financial risks, AI can help organizations take preventive measures and mitigate the impact of these risks. The integration of AI in FinOps is a trend you cannot afford to ignore if you aim for financial operations excellence.

    2. Empowering Teams to Manage Their Own Cloud Costs

    Traditionally, financial operations and cost management have been centralized functions. However, the advent of cloud computing and the shift toward decentralized work models have resulted in a new trend—empowering individual teams to manage their own cloud costs. In 2024, we can expect this trend to gain further momentum.

    In a cloud environment, costs are often directly linked to usage. This means that the teams using the cloud resources are in the best position to control these costs. By empowering these teams to manage their own cloud costs, organizations can promote accountability, encourage resource optimization, and ultimately achieve cost efficiency.

    This approach requires a shift in mindset and the development of new skills. Teams need to understand the financial implications of their actions and make cost-effective decisions. They also need tools and processes to monitor their cloud usage and manage their costs effectively.

    3. Managing Costs Across Multi-Cloud and Hybrid Cloud Deployments

    The use of multiple cloud providers and the coexistence of cloud and on-premises data centers have added a new layer of complexity to financial operations. Managing costs across these diverse environments is a major challenge, and it’s another trend that is expected to shape FinOps in 2024.

    With multiple cloud providers, each with its own pricing model and billing system, cost management can be a daunting task. Add to this the costs of maintaining on-premises data centers, and the complexity multiplies. In 2024, organizations will need to adopt strategies and tools that enable them to manage these costs effectively.

    One of these strategies is the use of cost management platforms that provide a unified view of costs across multiple environments. These platforms can track and analyze costs, allocate them to the appropriate departments or projects, and provide insights for cost optimization. They can also automate cost reporting and forecasting, easing the workload of financial teams.

    4. Emphasizing the Security Aspects of FinOps

    As financial operations become more complex, the risk of abnormal spending patterns or unauthorized activities increases. Identifying and addressing these issues promptly is critical to prevent financial losses and maintain financial integrity. In 2024, the identification of abnormal spending patterns or unauthorized activities will be a key focus area in FinOps.

    Tools and technologies that enable real-time monitoring and anomaly detection will play a crucial role in this regard. These tools can analyze financial data, detect deviations from normal patterns, and alert you to potential issues. They can also help you trace these anomalies back to their source, facilitating investigation and resolution.

    Moreover, organizations will need to strengthen their internal controls and governance mechanisms. They will need to define clear responsibilities and accountabilities, establish robust approval processes and enforce strict access controls. Regular audits and reviews will also be essential to ensure compliance and detect any irregularities.

    5. Measuring and Optimizing for Environmental Impact

    The environmental impact of financial operations is a concern that cannot be overlooked. As organizations strive to be more sustainable, measuring and optimizing for environmental impact is becoming a key aspect of FinOps. This trend is expected to gain prominence in 2024.

    The environmental impact of financial operations is largely tied to energy consumption. In a cloud environment, for instance, the energy consumed by data centers contributes to carbon emissions. Therefore, optimizing cloud usage not only reduces costs but also reduces environmental impact.

    To measure and optimize for environmental impact, organizations will need to track their energy consumption, calculate their carbon footprint, and implement strategies to reduce it. These strategies can include using energy-efficient technologies, optimizing resource usage and sourcing renewable energy.

    Conclusion

    In conclusion, FinOps is a dynamic and evolving field. The trends and predictions outlined above provide a roadmap for achieving financial operations excellence in 2024. By harnessing the power of AI, empowering teams to manage their own cloud costs, managing costs across diverse environments, emphasizing security in FinOps and optimizing for environmental impact, you can take your FinOps program to the next level.

  • BMC Mainframe Survey Results Show a Platform on the Rise

    BMC Mainframe Survey Results Show a Platform on the Rise

    What if I told you that the oldest active computing platform is also one of the most innovative, seen as a platform for growth and new workloads, not just by seasoned professionals, but by a new generation of stewards, too? The 2023 BMC Mainframe Survey shows just that. In addition to an overwhelmingly positive perception and growth mindset regarding the mainframe, the survey reveals that the majority of those who are most enthusiastic about its future are relative newcomers to the platform.

    Now in its 18th edition, the annual BMC Mainframe Survey gauges the opinions of more than 800 executive and technical professionals on a range of topics, from overall perception of the platform to top priorities, common practices and greatest challenges.

    This year’s results show that 94% of respondents have a positive perception of the mainframe, with 62% citing it as a platform to grow and attract new workloads. This tracks the 62% who report adopting DevOps practices on the platform. It’s no surprise, then, that two of the top five priorities cited by respondents are efforts to enhance automation and modernize applications. Organizations around the world recognize that the mainframe can be a leader in innovation, powering their digital transformations.

    Modern Management Approaches

    This innovation goes beyond the software and services developed for the mainframe to include those used to manage the platform. It’s reported that 35% of respondents listed the implementation of cloud technologies as one of their top four priorities for the coming year, with 41% saying they are considering cloud-based storage and backup. With the growing volume of mainframe data and the emergence of new regulations and standards governing data security and recovery, organizations are turning to cloud-based data management to reduce costs and improve recovery options.

    Year over year, the number of survey respondents reporting the use of AIOps hasn’t changed considerably, but those reporting its cross-platform use on both mainframe and non-mainframe systems has jumped 7% from 2021.

    Organizations are recognizing the need to take advantage of the greatest business values of AIOps — cited in the survey as improved uptime and the ability to detect problems quickly, understand trends and respond proactively — as part of a holistic approach to enterprise IT operations management.

    With increased cross-platform use, significant benefits and a decrease in the number of respondents reporting implementation challenges like cost, complexity and the need for specialized skillsets, BMC sees AIOps as an area ripe for significant growth in the coming year.

    Investment Pays Dividends

    Improving the availability, quality and efficiency of the mainframe, of course, requires investment. In our report on the results of the 2023 BMC Mainframe Survey, we compare the responses of maximizers (those planning to increase investment in the platform) with those of minimizers (those planning to decrease investment levels). The results are eye-opening.

    Maximizers have invested in future-proofing their workforce in a variety of ways, and the data bears that out; 81% have ten or fewer years of experience on the platform. The new generation of stewards sees the mainframe not as a legacy platform, but one of continued growth and innovation, worthy of the investment required not just to keep it modern, but to place it at the forefront of digital transformation.

    Another key difference between maximizers and minimizers relates to security, which was cited as the top overall priority of survey respondents for the fourth consecutive year. Maximizers are more likely than minimizers to have a dedicated resource to investigate security events and to have dedicated ransomware recovery capabilities in place. It should come as no surprise, then, that maximizers were 20% more likely than minimizers to report that their mainframe security controls for ransomware are extremely effective.

    These results show that the differences between maximizers and minimizers go beyond outlook, producing tangible effects on outcomes. The maximizers increasing their investment in the mainframe report fewer challenges with staffing and skills shortages and a stronger stance against increasingly sophisticated cyberthreats. The minimizers decreasing their investment in the platform not only have greater difficulty in maintaining a skilled workforce, which increases the risk of falling behind competitively, but it also puts their organizations at serious risk of potentially catastrophic security breaches.

    A Bright Future

    In short, the results of the 2023 BMC Mainframe Survey reflect a positive outlook for the platform’s future. By investing in their workforces and the tools required to advance and protect the platform while adopting modern techniques and practices, organizations can reduce risk and promote innovation that delights their customers.