Category: Continuous Testing

Continuous testing is the process of executing automated tests as part of the software delivery pipeline to obtain immediate feedback on the business risks associated with a software release candidate.

  • How to Adopt an SRE Practice (When You’re not Google)

    How to Adopt an SRE Practice (When You’re not Google)

    Site reliability engineering (SRE) isn’t a new term or practice. The practice of applying software engineering skills and principles to operations problems and tasks happened even before site reliability engineer was a defined job title. But organizing a proactive approach to building and maintaining software drives long-term success in improving operational efficiency, data-driven roadmap planning and general uptime and reliability. All these advantages account for the widespread adoption of SRE. 

    In this article, I’ll dive into what it takes to get into site reliability engineering, how to adopt it within your own organization and some of the core principles and best practices you’ll need to keep in mind as you move forward in your SRE maturity journey.

    What is SRE?

    SRE, or site reliability engineering, is the practice of applying software engineering expertise to DevOps and operations problems. Often, this means proactively writing code and developing internal applications or services to combat reliability and performance concerns. SRE has been a practice for many years but has been more recently popularized by Google when they first published Site Reliability Engineering: How Google Runs Production Systems in March 2016.

    SRE is a complicated acronym because it both relates to a job title, site reliability engineer,  as well as a general practice adopted by development and IT teams, site reliability engineering. SRE teams are often organized differently depending on the organization and the services they support. Sometimes site reliability engineers (SREs) are sprinkled among development teams. This means they can vocalize concerns during roadmap planning and work closely with QA teams, collaborating on everything from shipping features to staging to managing production environments. 

    Another approach organizes an SRE team as a standalone group. The SRE team as a whole is focused on responsibilities including monitoring applications and infrastructure, establishing reliability metrics, tracking issues with new releases and handling on-call duties. No matter how they are organized, what remains the same for all these SREs is their initiative—reliability and performance.  

    DevOps Vs. SRE

    The rapid adoption of DevOps practices may have you wondering, “How is SRE different from DevOps?” Commonly, the two terms go hand-in-hand. SRE is a practice that doesn’t necessarily have to be part of DevOps culture and adoption but is often implemented by organizations that are further along in their DevOps journey. The further along on your DevOps maturity model, the more likely you are to have bought into SRE practices.

    The conversation isn’t ‘SRE versus DevOps; the conversation is about establishing a proactive SRE team and operating model to help strengthen your DevOps practice. Whether you choose an SRE framework integrated into your development and IT teams, or you want to make SRE a standalone business unit, you need to understand their general responsibilities.

    SRE Team Responsibilities

    Site reliability engineers are responsible for defining what performant and reliable really mean when you talk about your applications, services and infrastructure. The day-to-day tasks can range anywhere from instrumenting new monitoring solutions to building custom apps for technical support teams. They might ship new code to production to fix bugs or deliver new features, or they might respond to incidents in real-time and work closely with support teams to deliver positive customer experiences.

    At the end of the day, site reliability engineers are the key to understanding exactly how customers experience your product and how to track system performance and reliability through your customers’ eyes. SRE teams need to figure out exactly where service boundaries exist between what development teams ship and what customers experience. From there, they need to find ways to monitor reliability and performance concerns in a way that helps your internal teams proactively identify risks and deliver better software. 

    SRE teams spread knowledge across the product and development teams to consistently define reliability across the entire organization. With everyone on the same page, the engineering teams can make data-driven decisions when it comes to releasing new features or improving current experiences in production. 

    Site Reliability Engineering Principles and Practices

    At a very high level, Google defines the core of SRE principles and practices as an ability to ’embrace risk.’ Site reliability engineers balance the organizational need for constant innovation and delivery of new software with the reliability and performance of production environments. 

    The practice of SRE grows as the adoption of DevOps grows because they both help balance the sometimes opposing needs of the development and operations teams. Site reliability engineers inject processes into the CI/CD and software delivery workflows to improve performance and reliability but they will know when to sacrifice stability for speed. By working closely with DevOps teams to understand critical components of their applications and infrastructure, SREs can also learn the non-critical components.

    Creating transparency across all teams about the health of their applications and systems can help site reliability engineers determine a level of risk they can feel comfortable with. The level of desired service availability and acceptable performance issues that you can reasonably allow will depend on the type of service you support as well. SRE principles and practices embrace experimentation and require a dedication to proactively understanding the health of the services they support.

    An SRE Operating and Maturity Model

    You can perform a lot of the responsibilities asked of a site reliability engineer and still have a software engineer job title. So, how do you know how mature your site reliability engineering practice is? Luckily for you, we’ll lay out a quick way to build an effective SRE operating model and track your maturity against it. An SRE operating model typically includes three elements, which you might achieve in phases:

    1. A team (or at least one person) dedicated to the practice of SRE.
    2. Deep integration and influence across product, development and operations teams.
    3. Autonomy to automate workflows and write code for nearly any part of your application or system.

    Your SRE maturity depends on where your organization falls along these three elements of an SRE operating model. If you’ve taken the steps to make an SRE team or hire your first site reliability engineer, you’re at the beginning of your journey. If you have a team and they are a valued part of roadmap discussions, QA, deployment workflows, incident management processes, then you have a somewhat mature SRE practice. 

    An organization only reaches complete SRE maturity when the SRE business unit has the autonomy to automate workflows, build applications, own monitoring and alerting solutions, or interject themselves into nearly any conversation. Vocalizing performance and reliability concerns upfront and having a proactive discussion about those concerns is always better than simply ignoring them until it’s too late.

    Monitoring, CI/CD and Organizational Automation

    Site reliability engineers can and will automate just about anything and everything. If it can proactively detect, remediate or resolve an issue, it needs to be automated. From continuous integration and delivery practices to production environment monitoring, SREs should have some visibility into all of it. If they can identify ways to proactively uncover performance and reliability issues, then they need to have the authority to implement those changes.

    Today’s DevOps and IT capabilities around automation, monitoring, artificial intelligence and machine learning give SRE teams a huge advantage when identifying issues, responding to them and fixing them. Organizations with mature DevOps and SRE practices can catch problems in staging and they can also build automated incident management workflows and self-correcting systems. By determining critical components in your applications and infrastructure, SREs can narrow down the scope of things that can cause major problems.

    The Practice of Service Levels (SLIs, SLOs and SLAs)

    Service levels come into play to help SRE teams communicate the true health of digital products and services to all stakeholders. This is done by identifying and measuring critical components that are key to delivering positive customer experiences. In particular, they need to know when one or more components expose functionality to external customers. We call these intersection points system boundaries. System boundaries are the place where site reliability engineers need to apply service-level indicators and objectives to their metrics in order to tell the real story of system performance and reliability. 

    • Service-level indicators (SLIs) are the key measurements to determine the availability of a system.
    • Service-level objectives (SLOs) are goals you set for how much availability you expect out of a system.
    • Service-level agreements (SLAs) are the legal contracts that explain what happens if the system doesn’t meet its SLO.

    While SREs aren’t always responsible for managing service levels, it often falls within their purview. By tracking SLIs and tying them to SLOs, you can set goals around the performance of a system. Google’s SRE book defines the four golden signals of service levels as latency, traffic, errors and saturation. So, for example, you could look at an API call and track its number of successful/failed requests (the SLI) against a general percentage of requests that need to be successful for customers to have a good experience (the SLO).

    SRE teams will often set strict SLOs on critical components within their applications and services to better understand how strict of an SLA they can agree to with customers. From here, the team can apply error budgets as a way to understand how quickly they must resolve issues in order to stay compliant with their SLOs. Service levels allow teams to aggregate metrics and create a transparent view of uptime, performance, and reliability across the entire organization. At a glance, business leaders can use service levels to monitor compliance across multiple teams, applications, services, etc. to gain a comprehensive understanding of their system’s health.

    Adopting SRE Best Practices

    Adopting SRE best practices and principles won’t happen overnight. It takes time and effort to proactively monitor your teams and systems for performance and reliability concerns. But, in the end, your DevOps teams and especially your customers will thank you for deciding to take advantage of site reliability engineering.

  • CDEvents Aims To Standardize CI/CD Interoperability

    CDEvents Aims To Standardize CI/CD Interoperability

    Companies are under mounting pressure to continuously release new applications and features. And as software development life cycles become more iterative, continuous integration and continuous delivery (CI/CD) has become a necessary ingredient to enable more rapid deployments.

    Many development teams now embrace DevOps, but fully automating a CI/CD pipeline from source code to production deployment is no easy task. For one, the number of tools in use continues to balloon, meaning CI/CD poses an ongoing maintenance hurdle. Furthermore, CI/CD tools often adopt varying formats to describe their events. A CI/CD pipeline, a form of event-driven architecture, may require a lot of special “glue” to patch events together if the output from each tool is not in a standardized format.

    Interestingly, CDEvents, an emerging open source standard from the Continous Delivery Foundation (CDF), is working to standardize the root semantics of how CI/CD tools describe the payloads of their events with more granularity than CloudEvents. The project aims to establish schemas for how common CI/CD events are described, easing integration and providing more actionable data surrounding the CI/CD pipeline.

    I recently met with Andrea Frittoli, open source developer advocate at IBM, to understand why the CDEvents project exists, how it works and what they’re hoping to achieve. According to Frittoli, who is also co-creator of the CDEvents project and a member of the CDF Technical Oversight Committee, CDEvents has the potential to bring much-needed interoperability to the sprawling CI/CD tooling ecosystem. Below, we’ll investigate where the project is and consider where it’s heading.

    The Problem With CI/CD

    At its core, the problem CDEvents is trying to solve is a lack of interoperability in the CI/CD field, explained Frittoli. As it stands today, DevOps engineers must routinely make point-to-point integrations between CI/CD tools. “No single tool will take you entirely from managing source code to production,” he said. A single development team could be using up to 15 unique components in one pipeline, and tooling preferences can vary dramatically across teams, he adds, further complicating CI/CD interoperability.

    Although CloudEvents has made inroads as a specification to describe event data, nothing has yet existed specifically for describing CI/CD events. According to Frittoli, CloudEvents falls short here, as it’s agnostic about what is inserted into the payload.

    Understanding CDEvents

    CDEvents is “a common specification for Continuous Delivery events.” Frittoli describes it as a shared dictionary or shared semantics for common events. These events could be a change in source code, running a test, or a code execution or deploy. CDEvents uses JSON object schemas to describe the event types and can work alongside CloudEvents as an attribute. “CDEvents is a standard format for the payload as well, not only for the envelope,” said Frittoli.

    As Frittoli explains, the CDF special interest group is still drafting the CDEvent specification’s exact semantics and common names. Currently, CDEvent organizes these objects into four main buckets: Core events, source code version control, CD events and CI events.

    While the group is still finalizing the format of events as they work toward the initial release, the example below is an approximation of what the final format will look like:

    "meta": {
      "version" : "draft",
      "event_id" : "A234-1234-1234",
      "source" : "/staging/tekton/",
      "type" : "dev.cdevents.taskrun.started",
      "timestamp" : "2018-04-05T17:31:00Z"
    },
    "subject": {
      "id": "/namespace/taskrun-123",
      "type": "taskrun",
      "content": {
        "URL": ...
        "pipelinerun": ...
      }
    },
    "extensions": [{
      "name": ,
      "content": ...}
    ],
    "links": [{
    ...
    }]

    Benefits of CI/CD Event Standardization

    So, why is it necessary to define the format of CI/CD event data? What benefits does this bring to developers and the business as a whole? Well, Frittoli sees two potential primary use cases. First off, CDEvents could reduce the effort spent writing and maintaining glue code between common DevOps tools like Spinnaker, Argo or Flux. “This will allow a smoother integration between all the parts,” said Frittoli. Alleviating this could help scale CI/CD initiatives and increase overall agility.

    Another positive side effect is collecting more detailed information about workloads and their performances. If all these components generate similarly-formatted events, Frittoli explained, then you can begin to create a true end-to-end visualization of the entire CI/CD pipeline. Then, you can start to measure things such as deployment frequency, failure rate, time to change and other metrics.

    If events begin to use a common language, you could do many interesting things with that data, says Frittoli. Event data could help ascertain the root cause of incidents and aid debugging. One could even foresee some AIOps potential to further automate operations and increase observability around CI/CD.

    Final Thoughts and Ways to Participate

    CDEvents emerged at a time when iterative software development has become commonplace. A slew of helpful CI/CD tools is at our disposal to enable niche operations. Yet, the space still requires a standard way to operate between them. CDEvents is an exciting prospect, yet the project is still in its early stages. It has yet to reach a full release or any production use and proofs-of-concept are still being developed.

    Of course, encouraging a vendor-neutral specification requires the tooling community to get on board. “It’s vital for the different tools to implement CDEvents for it to be successful,” said Frittoli. He encourages the tooling community to join the working group to collaborate in building proofs-of-concept. The SIG plans to continue working on finalizing the first version of the specification. In the meantime, the group has produced a proof-of-concept using Tekton and keptn and the project has its future sights set on Knative and Jenkins.

    The CDEvents project is in incubating mode and maintained by the Events Special Interest Group (SIG) at the CDF. For more information, you can peruse the CDEvents documentation here or become involved with the community here. The Events SIG also holds biweekly meetings and a CDEvents Community Summit will be part of the upcoming CDcon.

  • AppSmith Adds Git Support to Low-Code App Dev Framework

    AppSmith Adds Git Support to Low-Code App Dev Framework

    AppSmith has added support for Git repositories to an open source framework for building custom applications using a low-code platform based on the JavaScript programming language.

    Rishabh Kaul, head of marketing for AppSmith, said the Git support will make it simpler for developers to manage version control as they iteratively build applications using a set of graphical widgets provided by AppSmith.

    AppSmith is used primarily by developers to build internal applications that automate a specific task or workflow. Support for Git makes it possible for multiple developers to more easily collaborate as they add work to a Git branch and make requests within the context of a continuous integration/continuous delivery (CI/CD) pipeline.

    That also makes it simpler to test applications and roll back to a previous version in the event something should go wrong, said Kaul.

    The Community Edition of AppSmith will make it possible to connect to unlimited public repositories and up to three private ones before requiring developers to upgrade.

    In recent years, use of low-code tools has increased dramatically as organizations embrace tools that enable them to build applications faster. Not every application requires developers to employ tools for working with procedural code. There are typically hundreds of use cases where an organization could build and deploy an application that would eliminate the need for an internal team to license yet another packaged application.

    In general, AppSmith and other open source tool and framework providers are betting that, as the economy continues to shrink, the adoption of these tools will increase as organizations continue to become more sensitive to costs. That approach will allow them to continue to provide applications tailored to automate specific tasks.

    The challenge, of course, is that as the number of applications being built and deployed steadily increases, the DevOps workflows that regularly update, secure and maintain those applications become much more challenging.

    It’s not clear what percentage of applications are now being built using some type of low-code tool. However, the overall size of organizations’ application portfolio is generally much higher than it was prior to the pandemic. Many of those applications are driving digital business processes intended to make the workforce more efficient at a time when many employees continue to work from home.

    Less clear, however, is how many new applications are being built by so-called citizen developers. One way or another, however, it’s becoming easier for end users that have some basic software understanding to build applications. Inevitably, those application development efforts will also need to be integrated within the context of a DevOps workflow.

    Regardless of how an individual DevOps team may view low-code tools, they have permanently altered the application development landscape. The issue is no longer whether low-code tools will be used by developers but rather to what extent. In the meantime, DevOps teams would be well advised to review just how extensible their existing pipelines need to become.

  • Why is Security Still in the Way? A Look at DevSecOps Right Now

    Why is Security Still in the Way? A Look at DevSecOps Right Now

    According to industry trend reports for 2022, DevSecOps is now considered to be one of the most effective approaches to building software quickly and securely. This effort, of course, means development, security and operations teams commit to addressing security as early as possible in the software development life cycle (SDLC). The goal of the shift into DevSecOps revolves around the need for more automation, streamlined CI/CD pipelines, less friction among teams and plenty of time for productive innovation. Incorporating DevSecOps practices into an organization unites security, compliance and development issues into a collaborative concern, one that allows DevOps to move fast without jeopardizing code quality. 

    As we approach the middle of 2022, it’s worth looking back and considering why security is still standing in the way of smooth software development. Security vulnerabilities have always been present in the process, and yet these pesky bugs continue to be the biggest threat to software performance. The question is, why?

    The Truth About Security

    Software has always been deployed and shipped with some existing bugs. But as software and services continue to dominate our everyday lives, the reality of this statement continues to plague both businesses and the end user. On some level, software development has yet to evolve into the next phase of security. Code is still rolled out regularly, only to discover security vulnerabilities in production. Some say the way software is developed today actually lends itself to defects, mostly because the pace of work required supersedes best practices around AppSec. 

    While the larger cybersecurity industry—and every DevSecOps team in the world—is striving to make software more secure, many organizations still prioritize speed and productivity over digital risk. This means the state of security (and, to some extent, the DevSecOps world) has become somewhat lopsided, with some enterprises making great efforts while others embrace a more lackadaisical approach. To make matters worse, many professionals today believe there has been a general under-investment in cybersecurity over the past several decades. 

    The Next Phase of DevSecOps

    The shift to remote and hybrid work models has led to mass adoption of cloud technologies and digital transformation, across all sectors and industries. As a result of this evolution, organizations today need to bear in mind that the more services they use, the more digital threats and overall risk they face. As this exposure to vulnerabilities increases, so does the need for new approaches to security. 

    The majority of modern enterprises do, in fact, have a security process in place, as well as other risk management solutions. But with the cybersecurity reckoning of 2021 and the stakes of cloud computing being higher than ever, businesses right now are feeling the pressure to think long and hard about why security still isn’t a guarantee. The trend of slowing down software development to address security more thoroughly, also known as the secret sauce of DevSecOps, is not free from roadblocks—but it is also far from optional. For many organizations, the implementation of DevSecOps practices feels less like security and more like speed bumps that just slow down the shipping of software. 

    Even so, the effort to improve security is happening now. Organizations do not need several solution platforms or tools to get started. They can begin right away; evolving their security tools and practices as they grow the business. With this growth comes one of security’s biggest challenges—scalability. Because toolchains across the cloud have become more and more complicated, setting policies and/or workflows in one tool is challenging. While these issues can be largely addressed by the adoption of an end-to-end security solution, organizations must continue to focus on strengthening supply chains, improving security oversight, and bolstering their approach to DevSecOps. Some ways to make this happen include:

    • Making sure CI/CD pipelines are integrated with DAST and SAST testing in development
    • Ensuring developers and DevOps teams complete vulnerability scanning before commit or merge, as they write code
    • Minimize manual security as much as possible with automated AI/ML tools to support more effective scanning and monitoring
    • Invest in management solutions that improve security in a multi-cloud environment

    Addressing the Supply Chain

    According to an industry survey, 60% of companies have decided securing the software supply chain should be a top priority for 2022. When we think about software supply chain attacks, we need to think about better controls to validate its integrity through all stages of the SDLC. Obviously, DevOps and automation have provided considerable help in this area; however, they cannot pull all the weight of security without proper governance and guardrails. 

    With a secure supply chain comes better security, as well as compliance, privacy and transparency. When a supply chain is secure, it can automatically enforce policy requirements for things like instrumentation, testing and architecture. As a result, software development and deployment become a repeatable process that is also reliable. Teams across the organization can rest assured that the products and services they are building comply with security expectations, such as validating code before production with static analysis and scanning tools. 

  • CDF Report Surfaces DevOps Workflow Gains

    CDF Report Surfaces DevOps Workflow Gains

    At its cdCon 2022 conference today, the Continuous Delivery Foundation shared a State of Continuous Delivery in 2022 report that found nearly half of developers (47%) use either continuous integration or continuous deployment platforms—but only about 20% report using both to automate all application build, testing and deployment.

    Overall, only a little less than a quarter (23%) of the 18,585 developers surveyed by SlashData on behalf of the CDF said they are not involved in any DevOps-related activities.

    Fatih Degirmenci, general manager for the CDF, said that the relatively low percentage suggested that DevOps workflows are now more widely employed than ever. Monitoring software and infrastructure performance and using continuous integration to automatically build and test code changes remain the most popular DevOps-related activities cited in the survey, at 36% each.

    The survey also found that, among large enterprises, the proportion of low performers when it comes to lead time for code changes has dropped from 34% to 24% in the last six months, while the proportion of top performers that need less than one day for code changes has also increased from 13% to 21%.

    Larger enterprises are also seeing an increase in developers that report they can restore a service in less than an hour (22%) versus those that still require one week (18%), according to the report.

    The survey also suggested there is a strong correlation between the adoption of modern backend technologies such as microservices, containers and Kubernetes and improved lead times for code changes and time to restore. Survey respondents using containers are twice as likely to have lead times of less than one day, while respondents that have adopted Kubernetes are one-third more likely to be top performers.

    However, the survey found no impact on deployment frequency. The percentage of top performers capable of deploying code multiple times per day is 11%, the report found. Developers who don’t use these technologies are, in fact, about twice as likely to deploy multiple times per day. Overall, only 53% of developers that work in backend development are using microservices.

    Degirmenci said it is clear there is still much work to be done in terms of simplifying DevOps workflows. The average number of technologies that DevOps practitioners use now stands at 4.6 in the first quarter of 2022. The CDF last month launched a CDEvents project to create a vendor-neutral specification for defining a format for sharing event data across multiple services, platforms and systems.

    In the meantime, the CDF survey also noted more than a quarter of respondents (26%) now rely on managed continuous integration/continuous delivery (CI/CD) services rather than building and maintaining a DevOps platform themselves.

    It’s too early to say how much complexity is driving organizations to rely on managed services, but as the pace at which applications are being developed continues to increase, more organizations are starting to focus on developer productivity. As a result, more than a few organizations are reviewing their existing approach to DevOps and whether it is actually a bottleneck rather than an accelerant for building and deploying applications faster.

  • Contrast Security Adds Free Code-Scanning Tool

    Contrast Security Adds Free Code-Scanning Tool

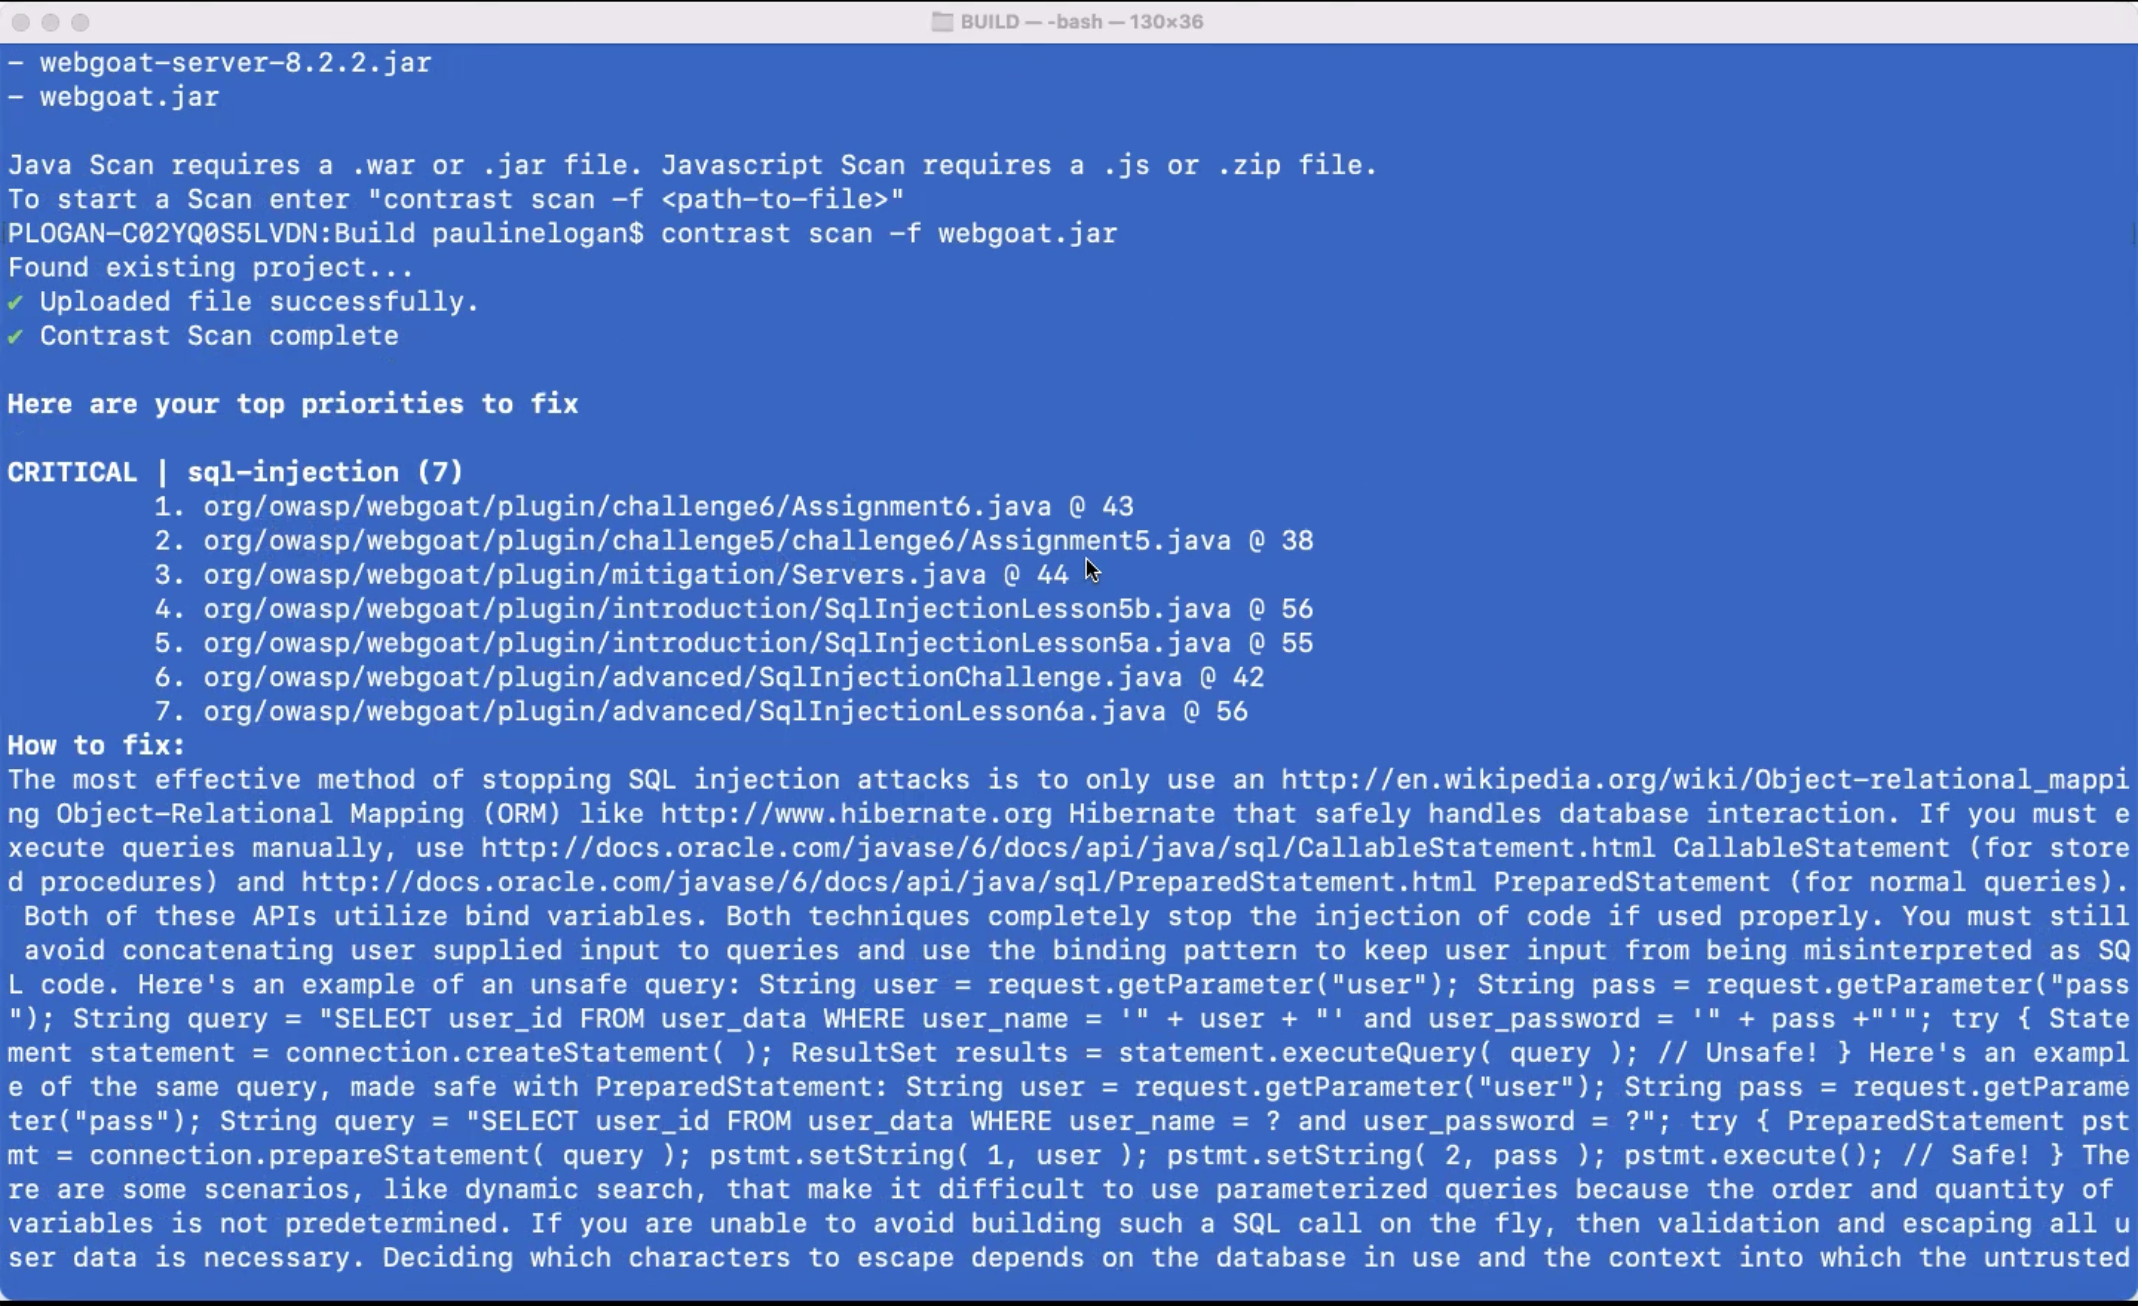
    Contrast Security this week made available a free security tool that enables developers to scan their code using the same core engine used by the cybersecurity team within their organization.

    Steven Phillips, vice president of product marketing for Contrast Security, said while there is no shortage of free tools for scanning code these days, the majority are not especially accurate. The scanning engine in CodeSec by Contrast Security is more than 10 times more accurate, Phillips said, because it is optimized to identify true positives versus generating a lot of false negatives, he claimed. He added that CodeSec is not just another freemium offering for developers that is a hobbled version of a commercial offering.

    CodeSec also differs from Contrast Security’s existing application security tool because it provides access to a command-line interface (CLI) that makes it easier to integrate within the context of a DevOps workflow. That approach makes it simpler for organizations to shift more responsibility for application security further left toward developers, noted Phillips.

    However, shifting responsibility left toward developers is not a panacea, Phillips said. The Contrast Security approach enables more collaboration between development and cybersecurity teams that are using the same scanning engine via a software-as-a-service (SaaS) platform to discover vulnerabilities, he noted.

    It’s difficult to determine just how far cybersecurity might shift left, but every vulnerability discovered by an application development team is one less for cybersecurity teams to ask developers to fix in a production environment. The challenge is making it as simple as possible for developers to discover those vulnerabilities.

    One way or another, the amount of time and effort being applied to application security has increased sharply in recent months following the disclosure of a series of high-profile breaches. Cybercriminals are now targeting software supply chains as part of an effort to compromise a wide range of downstream applications. Many of the modules that developers routinely reuse are being compromised by surreptitiously inserted malware. The fundamental challenge organizations are trying to address is how to build and deploy more secure applications without slowing down the rate at which they are built.

    Naturally, training developers to recognize security issues is a big part of the equation. However, no two developers are ever going to have the same level of cybersecurity expertise. Tools that identify vulnerabilities in ways that developers can act on are critical for advancing the adoption of DevSecOps best practices. Those tools require some level of acceptance among developers because they tend to prefer CLI tools.

    In the meantime, organizations will most likely have to scan a wide range of already-deployed applications for vulnerabilities. Applications running both inside and outside the cloud have been routinely deployed with a minimum level of scanning. The truth is that many developers have tended to view cybersecurity policies as an impediment to building and deploying applications. Unfortunately, cybercriminals now appreciate and take full advantage of the opportunity to wreak havoc.

  • 5 Testing Strategies For Deploying Microservices

    5 Testing Strategies For Deploying Microservices

    With rigorous development and pre-production testing, your microservices will perform as they should. However, microservices need to be continuously tested against actual end-user activity to adapt the application to changing preferences and requests. This article will cover five deployment strategies that will help developers and DevOps teams when releasing new features or making changes to microservices-based applications.

    Always Test in Production

    A staging environment is a necessary but insufficient step toward building a robust microservices infrastructure. Although indicative, it is not a substitute for evolving user traffic and behavior. When real users interact with the software during production, the services may not perform as efficiently.

    Users are unpredictable. They may make requests you have not accounted for when drawing up communication paths. Or your microservices architecture may not sustain the actual production traffic. When testing with real end-users, you are sure of your software’s performance and can improve it or add new functionality. 

    The disadvantage of working with real users is that they will be impacted by any errors. However, with specific deployment strategies, you can identify the issues and minimize their impact on those users. 

    Depending on your goals, you can implement the following testing strategies in the deployment stage. They can be performed individually or in various combinations, as each approach varies in its contribution to deployment.

    Blue-Green Deployment

    A blue-green deployment uses two distinct yet identical production environments. For example, you deploy an inactive version of your application in the blue environment. At the same time, the latest version available to end users runs in the green environment. Next, you push code to add new functionality to the blue environment. 

    At this stage, you test the services in the blue environment to ensure that they are running smoothly. You can automate this process by using basic smoke tests. When the microservices pass these tests, you can instruct the load balancer to gradually redirect user traffic to this new environment.

    If the new functionality poses no problems, the router moves all traffic from the green to blue environment, but can immediately revert traffic in case of any errors. 

    Due to the identical nature of both environments and their reliance on each other, there is little to no downtime. The end user’s experience is largely unaffected and the developers can move quickly to fix any bugs.

    The old environment serves as a backup, making it possible to execute a rollback without any downtime. After releasing the latest version, you can decide to kill the old instances, but only after you are confident that the new environment will continue running without errors. You can also clone both blue and green environments to repeat the process with other feature deployments in the future.

    Canary Deployment

    Canary deployment is similar to blue-green testing in that it protects against release-related risks.

    The phrase “canary deployment” originates from an old mining practice of placing caged birds in mine shafts to detect the presence of harmful gases. If present, the gases would kill the canary before affecting the miners, thus providing an early warning to vacate the mine immediately.

    A canary deployment works on a similar principle. Instead of creating two separate environments, a canary deployment operates within the same microservice or infrastructure. The developers roll out a new service or application version with changes only to a fraction of the end-users.

    You can quickly detect errors or vulnerabilities while using the new service. The impact is temporary and minimal as the experiment is only run on a subset of users with most remaining unaffected. Once they are working and have passed verification, you can scale up the changes. 

    The biggest challenge for those running canary deployments is the requirement to run multiple versions of the same microservices so that they can be deployed to a few users at a time. Implementing multiple versions also means you need to keep track of which users are on which versions to run accurate business metrics and analytics. Such monitoring can get increasingly complex with multiple canary deployments within the same application.

    Feature Flags

    A feature flag or feature toggle is a change or feature written inside conditional code. Developers can turn the feature on or off depending on their testing requirements while the application is running and in use.

    The code is already deployed and there are two code paths: One with the code that implements the feature and one without it. The developer only needs to choose one of the two paths. When the switch is toggled on, the code chunk is executed as part of the flow. When switched off, that code is skipped and the feature is not implemented. The rest of the source code continues to run as usual, independent of the feature flag’s condition, with no disturbances in the end user’s experience.

    Once integrated, a feature flag allows you to turn on a feature for a select group of users. Unlike a canary deployment where the selection is random, feature toggles are usually employed in specific cases. For example, developers do not create two separate applications to implement free and paid subscription tiers. Instead, operating a feature flag allows you to make a particular feature accessible only to subscription users.

    Feature flags are especially attractive during testing as developers can use them to run small experiments throughout the application without relinquishing control. Being able to flip the switch remotely also makes rollbacks easier. The risk is negligible as the application is self-sufficient in that it can continue to run without the feature. 

    Feature flags generate complex user-to-service paths by way of permutations and combinations. For a specific user, it is difficult to determine the exact route they took when using the services. Feature flags complicate this by allowing each user to have a different experience, ultimately making the application hard to debug. These toggles are easy to get started with minimal risks, but their maintenance can quickly become complex. It is best to use them only when needed and with other deployment strategies.

    Traffic Shadowing

    With traffic shadowing or mirroring, the router duplicates incoming traffic to an already-released service and gives the copy to another service. The request and response mechanism between the user and the existing service remains intact. On the other hand, the second service with a copy of the traffic contains new features that require testing. Consequently, it does not interfere with the existing process. Instead, the copy is used to test its functionality.

    Its most significant benefit is that it allows the new version to receive the same traffic that is currently being received by the service it seeks to replace. There is no need to create test data or worry about replicating scale. This accuracy comes with little risk, as there is no tangible impact on the existing services. Developers can run all relevant tests on this production environment, such as testing for errors and performance metrics. The new version’s responses, which are not sent to users, can also be compared to those of the production service. Both versions operate independently of each other with different end goals. This can happen in real-time or a copy can be saved and replayed for future testing.

    Traffic shadowing can be used with other deployment techniques like blue-green or canary deployments. After successfully shadowing a production environment, the changes can be rolled out gradually using a canary deployment to gain maximum confidence before a full release.

    Shadowing can have unintended consequences, though, so you should exercise caution when deploying this strategy with services that have third-party dependencies. 

    A/B Testing

    Unlike blue-green and canary deployments, A/B testing is focused on user perception and experience of new features. It measures if and how end users are interacting with these features, whether they are easy to notice and use and gauges the application’s overall functionality. It provides developer teams with business-level insight to improve their application as the features are ultimately implemented using code.

    A/B testing divides users into groups that access different features. Group A, for example, sees a different user interface than group B, although members in both groups are making the same requests to access the application. Traffic is routed to separate builds or different configurations on a common build. This is done by considering aspects like the users’ operating systems and user agents. It must be run on a sample that is representative of your end users. The test also needs to display statistically significant results to be valid.

    This test can be combined with blue-green or canary deployments as they handle the actual feature deployments that this strategy tests. After comparing the versions shown to the groups, the one that has performed better can be pushed to release for all users. 

    Building your Deployment Strategy

    Each strategy outlined can be used independently or together in a combination that best suits your goals, workflow and microservices requirements. They allow you to identify and reduce the impact of any vulnerabilities that may only surface at the final stage of your software’s release. Implementing them can be a somewhat complex process, especially with larger architectures and dependencies. But by implementing any of these strategies, your team will release the best possible version of your application. 

  • Catchpoint Enables Experimentation by Automating Web App Testing

    Catchpoint Enables Experimentation by Automating Web App Testing

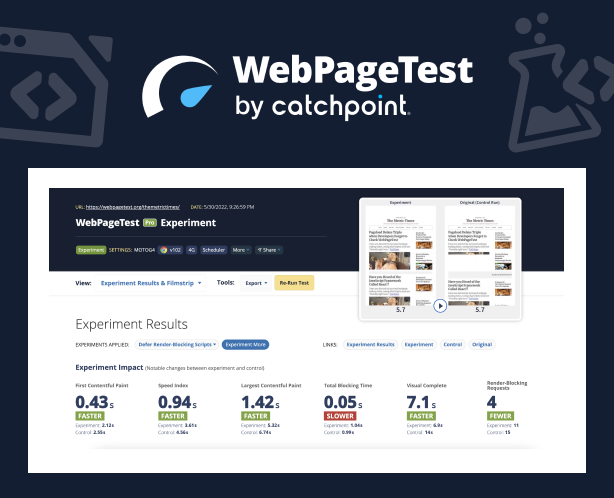
    Catchpoint this week expanded its open source WebPageTest performance testing suite of tools to enable IT teams to run instant tests that surface suggestions for improving overall web application and site performance.

    In addition, Catchpoint is now providing support for private tests, bulk tests and priority testing capabilities within the WebPageTest tool suite.

    Tim Kadlec, director of engineering for WebPageTest, said the goal is to make it easier for both developers and DevOps teams to experiment with how changes to applications and websites could improve performance using a capability that has now been added to the core suite.

    Identifying opportunities to improve performance typically requires tediously constructing manual tests over a period of weeks, noted Kadlec. Much of that effort is experimental in the sense that no one knows for sure if the tests being constructed will have a material impact on performance.

    The Opportunities and Experiments capability provides teams with a low-code tool for building tests based on a set of best practices that Catchpoint has defined. That approach makes it simpler to automatically generate and test tweaks that, for example, eliminate blocking scripts, optimize image rendering and minimize layout shifts. The result is optimization tests that show how their applications and websites could benefit from specific, actionable improvements without having to change any of the code that has already been deployed, said Kadlec.

    That’s a critical capability because it will encourage a level of experimentation that previously IT teams shied away from, simply because the amount of effort required to achieve an uncertain outcome was too high.

    It’s not precisely clear who is conducting these types of tests, as more responsibility for testing applications continues to shift left toward developers. The latest additions to WebPageTest make it easier for developers to conduct those tests without necessarily requiring help from a DevOps team, noted Kadlec.

    While there has always been a tremendous amount of focus on web application and site performance, the attention level has risen across organizations in the digital business transformation era. Many of the processes being implemented via web applications are extremely latency-sensitive. As more of those applications become routinely tested, the overall level of application performance should steadily improve.

    At the same time, the number of web applications and websites that most organizations are supporting also continues to expand. Most of those organizations are looking for ways to test applications without necessarily having to expand the size of the testing team or significantly increase the amount of time spent on testing.

    Regardless of the approach, it is apparent that testing is becoming more automated. The goal is not so much to eliminate the need for dedicated testing teams, but reduce the number of rote tasks that contribute to test avoidance in the interest of saving time. In theory, the more tests run—and the earlier they are run—the fewer issues that DevOps teams will need to deal with later.

  • Three Common Testing Mistakes – And Solutions

    Three Common Testing Mistakes – And Solutions

    A few weeks ago at SauceCon, DevOps.com talked to Matt Wyman, chief customer officer at SauceLabs. This year’s theme, Reimagine Test, emphasized the need to prioritize the user experience in testing. As Wyman put it, “We really focused on that customer experience, using the right type of test tool at the right moment.” After the conference, we caught up with him to talk more about a critical point—that many teams don’t know how to test for user experience because that hasn’t been in their wheelhouse.

    Wyman provided advice on three typical testing mistakes and how developers can improve the accuracy and breadth of their testing environment.

    1. Bloated Testing Suites

    Here’s a common scenario: Flaky tests get slipped into large test suites and developers ignore them instead of correcting or removing them. The suite gets increasingly bloated as people add more and more tests, which can obscure their results. “From the outside, it’s hard to tell which tests are the most critical when you’re making a change to pass,” Wyman said.

    He explained that if two people are working on the same part of the codebase and person A sets up a focused series of tests, person B can make a change and be sure it will work when those tests pass. But that’s no longer the case with a testing suite stuffed with irrelevant tests.

    “If instead, I create a two-hour suite with thousands of tests in it, you won’t know which one is most applicable to the change you’re making,” Wyman pointed out. “This is one of the more significant complications when people are less knowledgeable about building a good test suite or test practice.”

    2. Using a Single Tool Like a Hammer

    Wyman emphasized the need to use the right testing tools at the right time for the right purpose—something many developers don’t do. In this common mistake scenario, he said, the developer takes a functional user interface testing framework and uses it to validate their integrations, their APIs, their visual results and everything else.

    “It’s a classic case where you have a hammer and everything looks like a nail,” he said. “It makes your overall testing practice very heavy and very long. Typically, if you’re not using the right tool for the right purpose, it takes a lot of effort to maintain it.”

    3. User blind spots

    You don’t know what you don’t know—or, as Wyman put it, “the experience error is hard to find and even harder to discover.”

    Wyman discussed a hypothetical scenario in which engineers build and test a system that accepts only numeric inputs. Testing runs perfectly—because the engineers test only the entry of numbers. The fix here is fuzz testing: Thinking beyond simple use cases and introducing a “what if” quotient by testing random and unforeseen inputs, such as users who enter letters. Building this foresight into the programming language itself can involve developers in the quality assurance process much earlier and avoid mistakes down the line.

    He also stressed the need for observability in testing, with instrumentation that can help teams predict where users might run into limitations. “Developers have to look at the user analytics and usage analytics, not just system analytics,” he said. “Quite often the user analytics and observability the product manager is looking at, they see from the outside—and that’s useful data for the developer, so they can see those failure cases early.”

    Transcending Testing Limitations

    Is there such a thing as a flawless test environment? Probably not. But by sidestepping the three mistakes above, developers can transcend ingrained testing paradigms and elevate both quality and experience.

  • Opportunities and Challenges of Observability

    Opportunities and Challenges of Observability

    Observability platforms that unify metrics, logs and traces across applications and IT infrastructure are transforming how IT is managed. Most DevOps teams today are able to continuously monitor IT environments using tools that track a set of pre-defined metrics; observability platforms make it possible to aggregate data so that DevOps teams can launch queries that help them uncover the root cause of IT issues. DevOps teams leverage observability to allow them to understand what is happening within their applications more effectively and efficiently.

    Historically, applications were black boxes—meaning it was (and still is, in many cases) extremely difficult to know what is happening under the hood of the application.

    With the advent and subsequent growth of observability tools and techniques in the DevOps space, teams went from struggling to collect and understand the available data (which could vary from robust to almost non-existent) to easily aggregating data from numerous sources and being able to understand what that data means to being completely deluged with data—so much data it’s hard to keep up.

    Gather Data is No Longer Enough

    Josh Chessman, vice president of strategy and innovation at IT infrastructure monitoring specialist Netreo, explained that as applications become more and more complex, (e.g., running across multiple disparate environments with different technologies and in different locations) being able to collect data from these different environments is no longer enough.

    “Instead, DevOps engineers need to be able to collect the data and efficiently analyze it, too, to understand what is happening within the application,” he said. “Observability is the concept that drives this.”

    Chessman pointed out there are numerous observability issues DevOps teams face, but that they vary from organization to organization (and sometimes from team to team within an organization). 

    “Part of the problem is that many organizations simply lack tools to provide the data collection and analysis needed to move to an observability paradigm,” he said.

    This could be for numerous reasons, including budget (if you already have an existing tool, can you afford to acquire a new tool?), functionality (not all tools that claim to provide observability really do), implementation (this stuff is not easy and a poorly implemented tool could actually make things worse) and more.

    “One of the larger challenges I’ve seen is that organizations will go out and acquire an ‘observability’ tool and assume that is all they have to do,” Chessman said. “Unfortunately, that is not the case. Acquiring the tool gets you the technology, but the team must also be structured and ready to take advantage of the concepts and functionality provided by the tool.”

    GitLab’s senior director of product management Kenny Johnston explained that, on average, DevOps teams use five different observability tools which tend to inadequately connect developers to observability.

    In turn, developers struggle to respond to incidents swiftly while jumping across multiple tools and sources of truth and struggle to assign service level objectives (SLOs) and error budget definitions to the responsible product development teams.

    “To remedy this, we recommend adopting a unified software development solution that replaces the DIY ‘duct tape’ of products constraining developers and helps them deliver software more securely, at speed and scale,” he said. 

    Johnston said the most flexible and future-proof solutions today are open source tools like Prometheus and its ecosystem, as well as the OpenTelemetry toolset for more advanced use cases such as tracing.

    Prometheus has become very common in the developer space and, unlike other open source solutions or libraries, its format automatically emits metrics.

    “This allows for simple and future-proof interoperability, as one of the hardest things to change later down the line is code running,” he said. “Using open standards reduces the need for developers to rewrite and reintegrate the same type of code over and over again.”

    Observability Requires Understanding Your Goals

    From Chessman’s perspective, understanding what your goals are is critical for observability. 

    “Observability tools can do many things, but their primary function is to collect and analyze data,” he said. “While that is all well and good, if you do not define your KPIs from the beginning, all the collected and analyzed data is meaningless since you have no concept of what good and bad are.”

    Trying to define good and bad from the data collected is likely to result in failure because you are looking at where you are to figure out where you want to go.

    KPIs vary from application to application and, if you do not have them identified and well-defined before beginning down the observability path, it is that much harder, he said.

    Most tools (observability or otherwise) are capable of collecting hundreds if not thousands of metrics, but not all—not even most, in many circumstances—will be relevant to an organization. 

    “Instead of having to sift through the cruft to find the valuable data, it is better to start with identifying the valuable data and then figure out how to get there,” Chessman said. “If you don’t identify your KPIs in advance you could end up using the wrong KPIs for the wrong scenarios.”

    Johnston added that KPIs, like DevOps, are an iterative process and starting with KPIs helps developers create systems that can meet performance and availability expectations.

    “It’s important that DevOps teams continuously review their KPIs to allow for regular feedback on successes and failures,” he said.

    From his perspective, the best place to start for maintaining and improving observability is by storing observability definitions, instrumentation, SLOs, thresholds, incident response templates and dashboards as code.

    “This allows for rapid improvement via code changes by any team member, whether that’s a site reliability engineer (SRE), developer or platform team,” he said.