Category: Application Performance Management/Monitoring

  • Google Taps Nobl9 to Improve Services Reliability

    Google Taps Nobl9 to Improve Services Reliability

    Google announced this week it has added a capability for tracking reliability based on how service level objectives (SLOs) are being met that is based on a platform developed by Nobl9.

    Nobl9 launched a Nobl9 Reliability Center earlier this year that provides a single source of truth about the state of reliability in an application environment. Included in that platform is SLOgpt.ai, a generative artificial intelligence (AI) tool for programmatically creating SLOs and launching natural language queries to determine how well they are being adhered to across a distributed computing environment. The generative AI tool developed by Nobl9 is based on Vertex, a foundational large language model (LLM) provided by Google.

    Kit Merker, chief growth officer for Nobl9, said the generative AI tool also makes managing SLOs more accessible to a wider range of stakeholders.

    The expansion of the alliance with Google is the latest in a series that will make it simpler to manage SLOs across multiple ecosystems, including, most recently, partnerships that have been established with Microsoft and Cisco, noted Merker.

    The Nobl9 Reliability Center is already integrated with more than 50 DevOps, observability and incident management tools. It collects metrics, events, logs, traces and alerts to track incidents, releases, rollbacks, runbooks and other documentation. Those integrations will make it simpler for IT teams to create SLOs using historical data that would otherwise be challenging to define from scratch.

    In time, there is no doubt tools for managing SLOs will become more widely available, but given the dependencies that exist between applications and systems, DevOps teams will need an approach that can be employed across hybrid IT environments, said Merker.

    In general, as more microservices-based distributed applications are built and deployed, it’s becoming more challenging to maintain SLOs across them since they have many more dependencies than legacy monolithic applications. Each feature and application programming interface (API) added over time can adversely impact performance and reliability. The challenge is that it’s not so much that any given service will outright fail as much as it is determining where degradations are occurring that result in SLOs not being met.

    Each IT team needs to provide some sort of objective benchmark that assesses their overall effectiveness at delivering application services by making it simpler to track whether SLOs are achieved and maintained. Not every service needs to necessarily meet a stringent requirement, but IT teams do need to have confidence in the fact that, on average, certain levels of service are being consistently maintained.

    When it comes to SLOs, the challenge is first determining which dependencies might impact the level of reliability that can be maintained in the event of an outage and then, second, making sure whenever necessary workarounds—such as rerouting application programming interface (API) calls to other services—can be easily invoked.

    SLOs, of course, as a concept, have been around for decades, but with the rise of digital services that span multiple organizations, the level of reliability DevOps teams are expected to provide is now being written into business contracts. As a result, the overall level of stress related to managing SLOs is only going to increase in an era where businesses have never been more dependent on software.

  • BMC Adds More Tools to Modernize Mainframe Applications

    BMC Adds More Tools to Modernize Mainframe Applications

    BMC this week added a BMC AMI DevX Code Insights tool that makes use of machine learning algorithms to break apart monolithic COBOL mainframe applications into subprograms that are easier to update and refactor.

    In addition, BMC is now making available BMC AMI zAdviser Enterprise, a commercial instance of a previously announced free tool that uses machine learning algorithms to collect telemetry data from mainframe applications. The commercial version of the tool adds a dashboard built and maintained by BMC that makes it simpler to consume that data.

    John McKenny, senior vice president and general manager of Intelligent Z Optimization and Transformation at BMC, said BMC AMI DevX Code Insights visually maps a mainframe application to analyze data flow and debug applications made up of millions of lines of code in real-time that would otherwise be too complex to unravel. Armed with the insights gained, IT teams can then isolate business logic, refactor subprograms, add application programming interfaces (APIs) or remove dead code as they see fit, he added.

    BMC AMI DevX Code Insights also makes it simpler for organizations to onboard new developers to a project at a time when many of the original developers of COBOL applications are retiring, said McKenny.

    In the coming year, BMC is also committed to adding generative artificial intelligence (AI) tools to its portfolio for reengineering mainframe applications, added McKenny. Those tools, for example, will make it simpler to create documentation for legacy applications, he noted.

    It’s not clear how quickly organizations that have mainframes are looking to re-engineer applications, but as more of them adopt DevOps best practices, they are being updated more frequently. The less monolithic the application, the simpler that task becomes. The issue is that mainframes tend to run large applications that access large amounts of data, so many IT teams are naturally fearful of breaking them if they are reengineered, noted McKenny.

    While there is no doubt that the process of reengineering applications will become more automated in the years ahead, software engineers will still be needed to manage the overall process, said McKenny. The role of the software engineer will undoubtedly evolve, but it’s not likely software development and deployment will be wholly automated any time soon, he noted.

    In the meantime, IT organizations that manage mainframes continue to embrace DevOps best practices to varying degrees. There may be some applications that they continue to build and deploy using waterfall methodologies, but as mainframe applications become integrated into digital business workflows, the need to update them faster becomes more apparent.

    The challenge, as always, is not only providing IT teams with the tools to make that transition but also navigating the cultural issues that inevitably arise any time a change of this magnitude is made to the software development life cycle (SDLC). Regardless of the approach, the building and maintenance of mainframe applications are evolving. The only issue that remains to be resolved is finding ways to reduce the level of friction that transition creates as quickly as possible.

  • KubeCon 2023: Internal Developer Platforms and Developer Productivity


    Mitch Ashley: Hey there, everybody. Welcome back to Chicago to KubeCon 2023. We are on day two of our live-streaming on Techstrong TV across all of our sites, devopsy.kinsta.cloud, Security Boulevard, Techstrong.TV, and Cloud Native Now. So, we’ve got more great interviews. Alan’s just finished a couple and I’m teed up now with Amit Gorvin. Nice to meet you.

    Amit Eyal: Very nice to meet you.

    Mitch Ashley: And you are with, say the name.

    Amit Eyal: Kubiya AI.

    Mitch Ashley: Kubiya AI, okay. That’s a lot of syllables there, but okay. I’m just kidding you.

    Amit Eyal: We do this on purpose to confuse.

    Mitch Ashley: You know what? Once you hear it, it’s unique, right? You remember those [inaudible 00:00:45].

    Amit Eyal: Hundred percent.

    Mitch Ashley: Exactly. Okay, so I know you’ve talked with this before and you’ve talked about IDPs. It’s a really fast-growing area, right? Everybody’s focused on-

    Amit Eyal: Absolutely.

    Mitch Ashley: How do we help developers, platform engineers, the people all working together to make lives easier, self-service, that kind of thing, portals and all of that. I know you had some announcements recently. Talk about that, but maybe set it up of what you all do and why that’s a little different.

    Amit Eyal: Sure. I think maybe to take one step back, one of the things that I think a lot of companies in the industry, including ourselves are doing is, how do you create a better exchange between the developers and the DevOps, the operators on one side, developers on another hand where you have the golden path towards productivity. IDPs, internal developer platforms, have been known backstage being the primary leader in this space to unlock lab productivity.

    One of the things that we, at Kubiya, have discovered, and this is what we’ve tried to essentially address, is the self-service is only as good as the interaction between the users and the tools. And where often it does break down is on the fact that it’s a one directional exchange between the user and the tool. If you fail on authentication, fail on permission, don’t know the variables you need to pass or anything just doesn’t work as expected, you have a question, you have to go back and do a Jira ticket queue in order to go and to essentially get assistance from a human being.

    So, what has come to fruition in the last year, obviously ChatGPT doing the market education for this, is conversational AI, having a two directional exchange between machines and humans. We’ve married these two worlds together. We’ve created that exchange between your users, developers, and operators with the tools in a way where you can have a full-on conversation with it.

    You can go and spin up a Kubernetes deployment, it will ask you how many you replicated. You can scale it up, scale it down. You can have for your Jira ticket queue, for example, and ask it questions about who owns what, where they’re assigned creation, notating, anything that you would be able to do as a human, only in this case, you’re just having a conversation. Because imagine having on the other side, someone like Fred, John, Bob on the on-call channel having a conversation with you. We’re replacing that with the virtual assistant.

    Mitch Ashley: Interesting. So, replacing the virtual assistant model. It sounds like also you were maybe describing, if I got this right, that the developer technical staff can interface through ChatGPT to say… I mean the nice thing about ChatGPT is you can talk to it like a programming language just in conversational logic, right? I want you to create this for me with blah, blah, blah. Is that part of what you’re saying? You can give it instructions or requests?

    Amit Eyal: One minor information, we’re not using ChatGPT. It’s a ChatGPT-like experience.

    Mitch Ashley: I see.

    Amit Eyal: It’s probably the best way to anchor people to-

    Mitch Ashley: I jumped that.

    Amit Eyal: Which is fine. We’re using about eight different language models, both large and small. We’re actually using conversational AI piece with GPT-4 for Azure, just a FYI, but that’s separate. The experience is ChatGPT-like. Only here, it’s your tools, your programs, your scripts, essentially a personalized IDP, if you may, for each and every persona in organization, each and every individual in the organization.

    Mitch Ashley: Okay. So, are you using generative AI large language models underneath, or that’s just the experience that you’re delivering with whatever technology?

    Amit Eyal: Certainly. So, large language models are giving that natural exchange, essentially the benefits of large language models and the generative piece we’re using. But we’re also harnessing and scaffolding it with rule-based systems, with sound engineering practices. So, that’s how you get the benefit of an expected outcome on one hand. Our users would expect an expected outcome. Essentially, it has to be deterministic what they’d get on the other end.

    Mitch Ashley: I’m glad you said that because I was thinking down the ChatGPT line. It’s nice, but you don’t get the same response, same outcome. It’s not necessarily guaranteed to be consistent, to be accurate. So, it makes sense on the backend scaffolding part.

    Amit Eyal: And there’s permissioning and rule-based systems in place to harness the LLM to function the way you would expect it to.

    Mitch Ashley: Very nice. So, you talked about the developer experience, and I totally get the cognitive dissonance between I’m working in my IDE and doing my developer thing, and then I got to go to this ticketing system or go to some weird operating portal that wasn’t built for developers, but I still got to use it in a huge sense.

    Amit Eyal: Maybe it is, but it’s only as good as how it’s been upkept, maintained or what you’ve actually input into there. So, you still have to go in to program it to act the way you expect it to.

    Mitch Ashley: And it’s part of the flow too, right?

    Amit Eyal: Yeah.

    Mitch Ashley: I might not know answers to all 10 questions at the start of the interaction, but I need to get it started, and then finish it at some point in the process. But it’s about in the flow of the developer work, not I’m a form, fill me out. Right?

    Amit Eyal: A hundred percent.

    Mitch Ashley: Great. So, the announcement then, summarize again for us because I stepped on it with the GPT stuff.

    Amit Eyal: Sure, yeah. No, it’s fine. So, we came out last year actually with our initial platform, which was more resembling next generation of workflow automation because it was more so to get people connected to the world of conversational AI into the world of IDPs. Where we took it from there, and especially with the evolution of large language models, is an agent-based approach where we’re using different models and different agents trained on different models in order to map out effectively different functions within a transaction, almost like the human brain and the lobes interacting with each other.

    So, when you go and interact with the system, depending on how you approach it, it could be, show me how I do something. Say, set up a VPN. That may be in your docs. So, we’re using RAG techniques obviously to go into a train on your knowledge base. But if you’re going to go and run a query against a data source or a database, or maybe show me all my Jira tickets for current sprint for certain… That’s a different language model that’s interacting with you.

    And then if you’re going to go and create a Terraform, create a Kubernetes deployment, destroy Terraform, that’s an action base that’s also needing to go into verify permissions. We’re using open policy agent. We’re also using all the techniques to or data masking, and then we obviously have the orchestration there, a state machine that will go in to orchestrate all of those with the business logic of the organization. So, there’s a lot going on behind the scenes.

    Mitch Ashley: There is. Well, a lot of different kinds of users’ requests.

    Amit Eyal: To the user, it’s seamless. You have a brain emoji thinking and then reading back to you what it’s doing. So, it’s actually very fun interaction, human-like interaction, but then behind the scenes, there’s a lot that’s going on.

    Mitch Ashley: Very cool. Do you integrate at all with IDEs and go that far with it or is it a separate portal?

    Amit Eyal: Users can integrate with their IDEs. They can go and plug in. We have a SDK and it’s all open API based. So, essentially, you can connect to any tool.

    Mitch Ashley: I think it’s really nice and important because for one, it’s right there handy. And also, if you’re delivering any information that you can deliver in the way the code looks like or structured or auto-fill, you can mimic the behaviors of what you do in an IDE that… Very natural. So, I don’t have to go look up an API or what that call is; it’s right there. Or I don’t have to go look up what that thing’s called on my request; it’s right there.

    Amit Eyal: Agreed. So, I think maybe the one call-out I would love to make is people are thinking about the co-pilot approach or ChatGPT approach as a code completion tool. What we’re doing is, we’re doing an operations’ completion tool. Essentially, all of the next step, what would you do, how would you deploy the code, run your CI/CDs and maintain it for day two operations, so that’s where you can think about us filling that gap.

    Mitch Ashley: Okay, interesting. So, congratulations on the announcement.

    Amit Eyal: Thank you.

    Mitch Ashley: That’s fantastic. And every time you come, you’ve got new, in progress and things happening. I’m curious, maybe you’ve talked to Alan about this or Mike, your backstory, you’re CEO, founder of the company. How did you get going down this path? Was that, I was doing this at a big company and this is like a huge need, I’m going to go forward or?

    Amit Eyal: It’s a great question. So, the first time we came on it was myself and my co-founder, who he himself is an operator who built a self-service platform for his platform team in his previous company at Bluevine, and I came from AWS where I was managing partnerships for all the DevOps and DevSecOps-

    Mitch Ashley: Nice couple.

    Amit Eyal: Tier one players. So, I saw where they were possibly struggling with some of this self-service, and where I was in the middle of trying to assist them. And that’s where the thesis on the business side, which is this is a much larger problem and how we’ve actually solved this ourselves came together.

    Mitch Ashley: Interesting. Talk a little bit about your experience in the partnership side of it. Has that come to fruition as an important part of the business? I would imagine when you’re integrating with lots of things, just to look up the API, you can do it. You want to build relationships, partnerships with other companies.

    Amit Eyal: So, we have a very strong ecosystem of partners really looking to have the conversation. I experienced essentially that assistant experience on top of their platform. And right now, we’re letting into queue a few of the strategic ones that we feel that we can both have a strong alignment with, but also maintain. As we grow our team, we’re going to have a much larger ecosystem. We’re already at probably 10, 15 very strong players in the industry who want to have a partnership in place. So, I feel it’s only going to grow from that point.

    Mitch Ashley: Good, good. Amit, you already know this. I learned that lesson on one of the products I worked on where you didn’t design it with you were going to have a partner ecosystem in mind. You get to a point like, okay, we can’t do what we want to do. We got to go back and add that in. So, having that perspective upfront, if that’s a place you’re going to want to go at some point in the life cycle, it’s-

    Amit Eyal: That’s exactly it. Our ecosystem is built to be two-way conversation with all tools. So, if our customers are asking for it, there’s no reason why the vendor on the other side wouldn’t have a stronger alignment so we can have a better user experience for both sides.

    Mitch Ashley: I’m curious, do you sell to the engineering development community? Do you sell more to the platform engineering, operational DevOps tool folks? Where do you tend to focus?

    Amit Eyal: I would say usually that decision is made jointly. The platform teams typically have to have a handshake with the engineering managers. So, whether it’s an engineering manager taking us to the platform team, platform team taking us to the engineering manager, typically, we see both sides involved at least in validating this. But the easiest way to get started is really with the platform teams because they’re the power users typically of the system. They’re the ones creating and scaffolding the configurations of these systems, so it’s easiest for them to get started, test it internally on themselves. And very easily, we usually see that they roll it out to the rest of the engineering team.

    Mitch Ashley: They already have a good idea of what kind of requests come their way.

    Amit Eyal: Precisely.

    Mitch Ashley: And it would make that easier for people.

    Amit Eyal: Otherwise, the other way around would be, let me go and bring in a platform team. So, it’s a more direct approach [inaudible 00:13:09].

    Mitch Ashley: That makes sense and it’s nice. I could totally see. It’s starting, “Well, hey, something might make it easier to take a load off-

    Amit Eyal: Precisely.

    Mitch Ashley: The platform engineering team” or them saying, “Hey-

    Amit Eyal: We’re here to augment them.

    Mitch Ashley: … that’s an easier way to work with this.” Right?

    Amit Eyal: We’re here to augment them. Not everybody has a luxury of hiring three to five more headcounts for next year, but if you could do so with one or two headcounts and then Kubiya, now you can scale.

    Mitch Ashley: Great. If you look forward a little bit, maybe this next six months or maybe 12 months, six months or so, what things are happening in the industry, maybe where you’re heading, what are you thinking about next?

    Amit Eyal: The most recent announcements by OpenAI have been very interesting, because from our perspective, it’s giving us even more tools in order to get to our end goal, which is, in my opinion, a self-driving operator. A self-driving operator that will be able to take end-to-end tasks away from human beings and really free them up to do the highest and best use of their time. It’s still going to require human-in-the-loop interaction and we don’t expect it to be overnight. But I think a lot of the things that was announced recently is already in line with what we’ve been doing, but it’s only making it easier and again unlock more and more use cases.

    Mitch Ashley: Seems like OpenAI have done a pretty decent job of, don’t throw it all out there, incrementally add capability when you’re ready to handle it.

    Amit Eyal: Yes. Because we’ve been in this space a couple of years, we’ve been thinking about, we’ve already been architecting our platform to be conversational native. That’s allowing us to move very fast in this space.

    Mitch Ashley: Great. Well, tell folks where can they go check it out?

    Amit Eyal: Absolutely.

    Mitch Ashley: Can they get a demo online or what can we do to help?

    Amit Eyal: That’s a beautiful part. We open our platform up for self-service. So, you could actually sign up at Kubiya.ai, www.kubiya.ai. Sign up for a free trial. We also have a sandbox where you could, without needing to put in organizations credentials, anything. It’s a gated experience. Obviously, it’s a bit more limited, but you could go and have that nice exchange with Kubi, our DevOps assistant, and really enjoy the experience before committing to going into a trial.

    Mitch Ashley: Appreciate the sandbox. You don’t want to quite turn it loose on your infrastructure quite yet. Let’s kick the tires and then get there.

    Amit Eyal: Mostly read only. We have a few write actions in there, but typically, we want to make sure it’s rated PG for what people can do.

    Mitch Ashley: Exactly. Exactly. Great. And it’s spelled K-U-B-I-Y-A.ai.

    Amit Eyal: Y-A.ai.

    Mitch Ashley: Great.

    Amit Eyal: Thank you very much.

    Mitch Ashley: It was on the… I’m sure on your title but-

    Amit Eyal: Yes, it would be there.

    Mitch Ashley: Amit, pleasure talking with you and congrats on the new progress, new release and capabilities, where you’re headed next. Great market to be in.

    Amit Eyal: I appreciate it and I appreciate your time here today.

    Mitch Ashley: Of course. Great to have you on. For our folks, for the people in the audience, Amit’s representative of some of the great things that are happening not just at KubeCon but in our industry, and progress that’s happening overall. So, stay tuned. We’ve got more great interviews coming back up. Don’t go away. We’ll be right here in a few minutes. So, we’ll be back.

  • Three Strategies for Reducing MTTD and MTTR as Outage Costs Spiral

    Three Strategies for Reducing MTTD and MTTR as Outage Costs Spiral

    According to a New Relic survey of IT professionals, the median annual cost of IT outages has reached an astronomical $7.75 million. Over one-third of the 1,700 respondents said critical business application outages now cost more than $500,000 per hour. In a business environment where most interactions with customers, suppliers and business partners are conducted digitally, downtime has become a problem and an existential threat.

    Most IT organizations carefully monitor two key metrics — mean time to detection (MTTD) and mean time to resolution (MTTR) — to track their success in identifying and remediating critical systems issues. The figures represent, respectively, the average time it takes administrators to identify that a problem has occurred and to remediate the underlying issues. They serve as a benchmark for understanding the organization’s level of awareness of the status of its systems and the speed with which problems can be diagnosed and acted upon.

    There are many ways to improve performance against these metrics, but three stand out as the most effective, as evidenced by New Relic and the survey results.

    Monitor Everything

    The less you know about a problem, the longer it takes to diagnose and fix. The New Relic survey measured 17 different observability categories, such as network monitoring, alerts, log management, browser monitoring and distributed tracing. Across the board, about two-thirds of the companies that used even one of those monitoring tools reported reduced MTTR, with many saying resolution times had fallen by more than 25%.

    One-third of respondents whose organizations implemented full-stack observability—which is the ability to see everything in the tech stack that could affect the customer experience—reported the fewest outages, fastest MTTD and MTTR, lowest outage costs and highest median annual return on investment compared to all respondents. For example, those who have full-stack observability experience a median outage cost that is 37% less than those without.

    As the complexity of enterprise technology stacks increases, so does the difficulty of pinpointing the root cause of an outage. Any monitoring is better than no monitoring at all, and the more visibility you have into applications and infrastructure the faster you can identify and resolve incidents. Strive for full-stack observability around integrated observability data and a comprehensive dashboard.

    Have an Incident Management Action Plan

    The worst time to figure out how to resolve a problem is when you’re in the midst of a crisis. Organizations with mature observability practices also have extensive and documented response plans.

    Your incident plan will be unique to your organization. Small companies and startups tend to have ad hoc response strategies based on the skills within the organization. Large enterprises may use a more formal methodology like IT service management that defines strict procedures and protocols. Companies that have embraced modern DevOps and Lean principles often use a hybrid approach that depends heavily on teamwork and collaborative problem-solving. All of these approaches can work if the team fully understands the chosen strategy.

    Document your IT architecture, identifying known vulnerabilities and outlining procedures for responding to the most common types of incidents. Plans should cover obvious disruptions like fires and power outages, but you should also think about “unicorn” scenarios such as a rogue query that ties up a database server or a communication outage at a key supplier. Mature observability teams devote a portion of their resources to constantly testing new and unpredictable scenarios and use chaos engineering to randomly inject problems in a controlled manner to see if systems respond as expected.

    As you develop incident response procedures, document the processes in runbooks, which tell responders exactly what to do when a specific problem occurs. This not only creates a database of organizational knowledge about response strategies but also helps with onboarding new employees and covers for skills gaps that occur when team members are unavailable or leave the company.

    Fix for the Future

    Technical debt is a long-term obligation that is created when a short-term – and incomplete – solution is applied. You should aim to minimize it in your observability operation.

    When a problem occurs, the temptation is to fix it as quickly as possible. Human nature is to move on to the next task without taking the time to go back and understand why a problem occurred. “Quick and dirty” fixes are an invitation to larger problems in the future. Your observability plan should include a forensics stage that documents root causes and the fixes that were applied. Even if it isn’t convenient to implement a long-term solution immediately, the documentation serves as a guide for implementing a permanent fix down the road.

    Building a resilient IT architecture is a marathon, not a sprint. The more rigor you apply to identifying and resolving problems when they happen, the better prepared you will be to prevent their reoccurrence and the more informed your team will be about the resources they manage. Reducing your MTTD and MTTR will not only improve the bottom line of your business, it will ensure that your customers have an amazing digital experience.

  • Observability: The Central Watchtower Your All-Seeing IT Needs

    Observability: The Central Watchtower Your All-Seeing IT Needs

    If there’s something you need to keep secure, it’s natural to want to keep it sealed away under lock and key. However, even keeping something in a vault, far from prying eyes and ill intent, may not be enough to offer peace of mind. After all, how can you have the peace of mind of knowing it’s safe if you don’t regularly check to ensure it hasn’t bolted, been burgled or broken down?

    Now, multiply the volume and value of things being monitored tenfold — and you get a sense of the daily inefficiencies and anxieties IT professionals battle.

    Instead of jewels, these teams safeguard, manage and maintain something far more valuable: The data that underpins everything from business transactions to system performance to threat detection to service delivery and beyond. To make matters more complicated, today’s digital ecosystems are more complicated, distributed and disparate than ever before.

    Databases are critical to managing a successful IT department — and it’s time to discard the widespread industry’s perception of them as an unknowable black box. To be sure, databases represent the most difficult component of the IT ecosystems to observe, tune, manage and scale. But the database isn’t a Magic 8 ball in terms of its internal processes; We no longer have to shake the mystery toy and accept one of the six answers it’s designed to spit out.

    The fact of the matter is that database specialists and IT teams need a clear view of database performance telemetry if they want any hope of maintaining the health, stability and scalability of their services.

    Observability Tools

    This is where observability tools can play a transformative role. Taking its cues from the all-seeing panopticon watchtower, observability eliminates the dark corners of the database dungeon by providing a comprehensive view across the full cloud-native, on-premises and hybrid technology stacks.

    The word panopticon derives from the Greek word panoptes, or “all-seeing.” The panopticon model features a central, lighted guard tower at the center of a circular room — allowing 360-degree lines of sight that allow the guards to observe every surrounding cell from a single, centralized vantage point.

    English philosopher Jeremy Bentham had no way of foreseeing the challenges of today’s database professionals when he first conceived of the panopticon in the 1700s. The concept would lay the blueprint for a prison system designed around one core concept: Enabling the minimum number of guards to effectively monitor the maximum number of inmates. Bentham’s system also works as a strategy for ensuring the health and performance of your organization’s critical databases.

    The panopticon was designed so that every cell could be monitored from one central point — ensuring not only better and more straightforward security but preserving resources in saved time, manpower and effort expended. Think of your ITOps, database, DataOps and DevOps teams as the wardens of your IT performance. Traditional monitoring can be likened to patrolling a traditional prison: Rows of cells facing out into a hallway that is patrolled on a schedule or used to spot and address misbehavior as it’s noticed.

    How can they be sure they’re focusing their efforts in the right place? Or trust that Cell Block A won’t stage a breakout while they’re breaking up an argument in Cell Block B?

    In short: They can’t. Odds are, the team is either running from outage to outage in an everlasting firefighting mode or relying on random spot checks for something as vital as the health of our IT systems.

    Observability, as opposed to monitoring, puts teams into that central panopticon watchtower, allowing them to not just see everything, but to see it within the context of the bigger picture. This comprehensive visibility and always-on observation enable IT teams to identify critical issues as they occur, even those caused by complex dependencies between the database, operating system, storage subsystem and network.

    Database Performance Issues

    Furthermore, database performance issues are a starting gun for costly bottlenecks or serious outages that can handcuff your company’s ability to compete or grow. Without complete and precise database monitoring and observability, IT operations struggle to accurately determine an application’s root cause of performance issues. This increases the risk of downtime, data loss and poor customer experiences.

    Discovering the root cause of performance issues is quite literally a system-critical undertaking, whether you’re simply running your enterprise, scaling your operations or deploying new code. Observability also offers teams the rare opportunity to get ahead of performance issues since you can see performance anomalies in advance of a service disruption rather than relying on real-time remediation.

    With traditional methods, DevOps and IT teams must manually analyze the data presented to them, correlate it to the problem, and locate the error before they can finally begin addressing it. In contrast, observability collects data to provide information on what’s not performing as expected and why. This allows teams to take a proactive approach to solving downtime and bottlenecks and proactively preventing them.

    In the software world, that translates directly to more time spent where it matters: Developing new business value within your applications and infrastructures, fueling innovation and exceeding customer expectations.

    Given how complicated the modern database has — and continues to — become, arming your enterprise with the right observability solutions can provide a boost to efficiency and performance and pardon your teams from a sentence to time-consuming, mundane and error-prone work.

  • LaunchDarkly Previews Generative AI Testing Tool for Feature Management

    LaunchDarkly Previews Generative AI Testing Tool for Feature Management

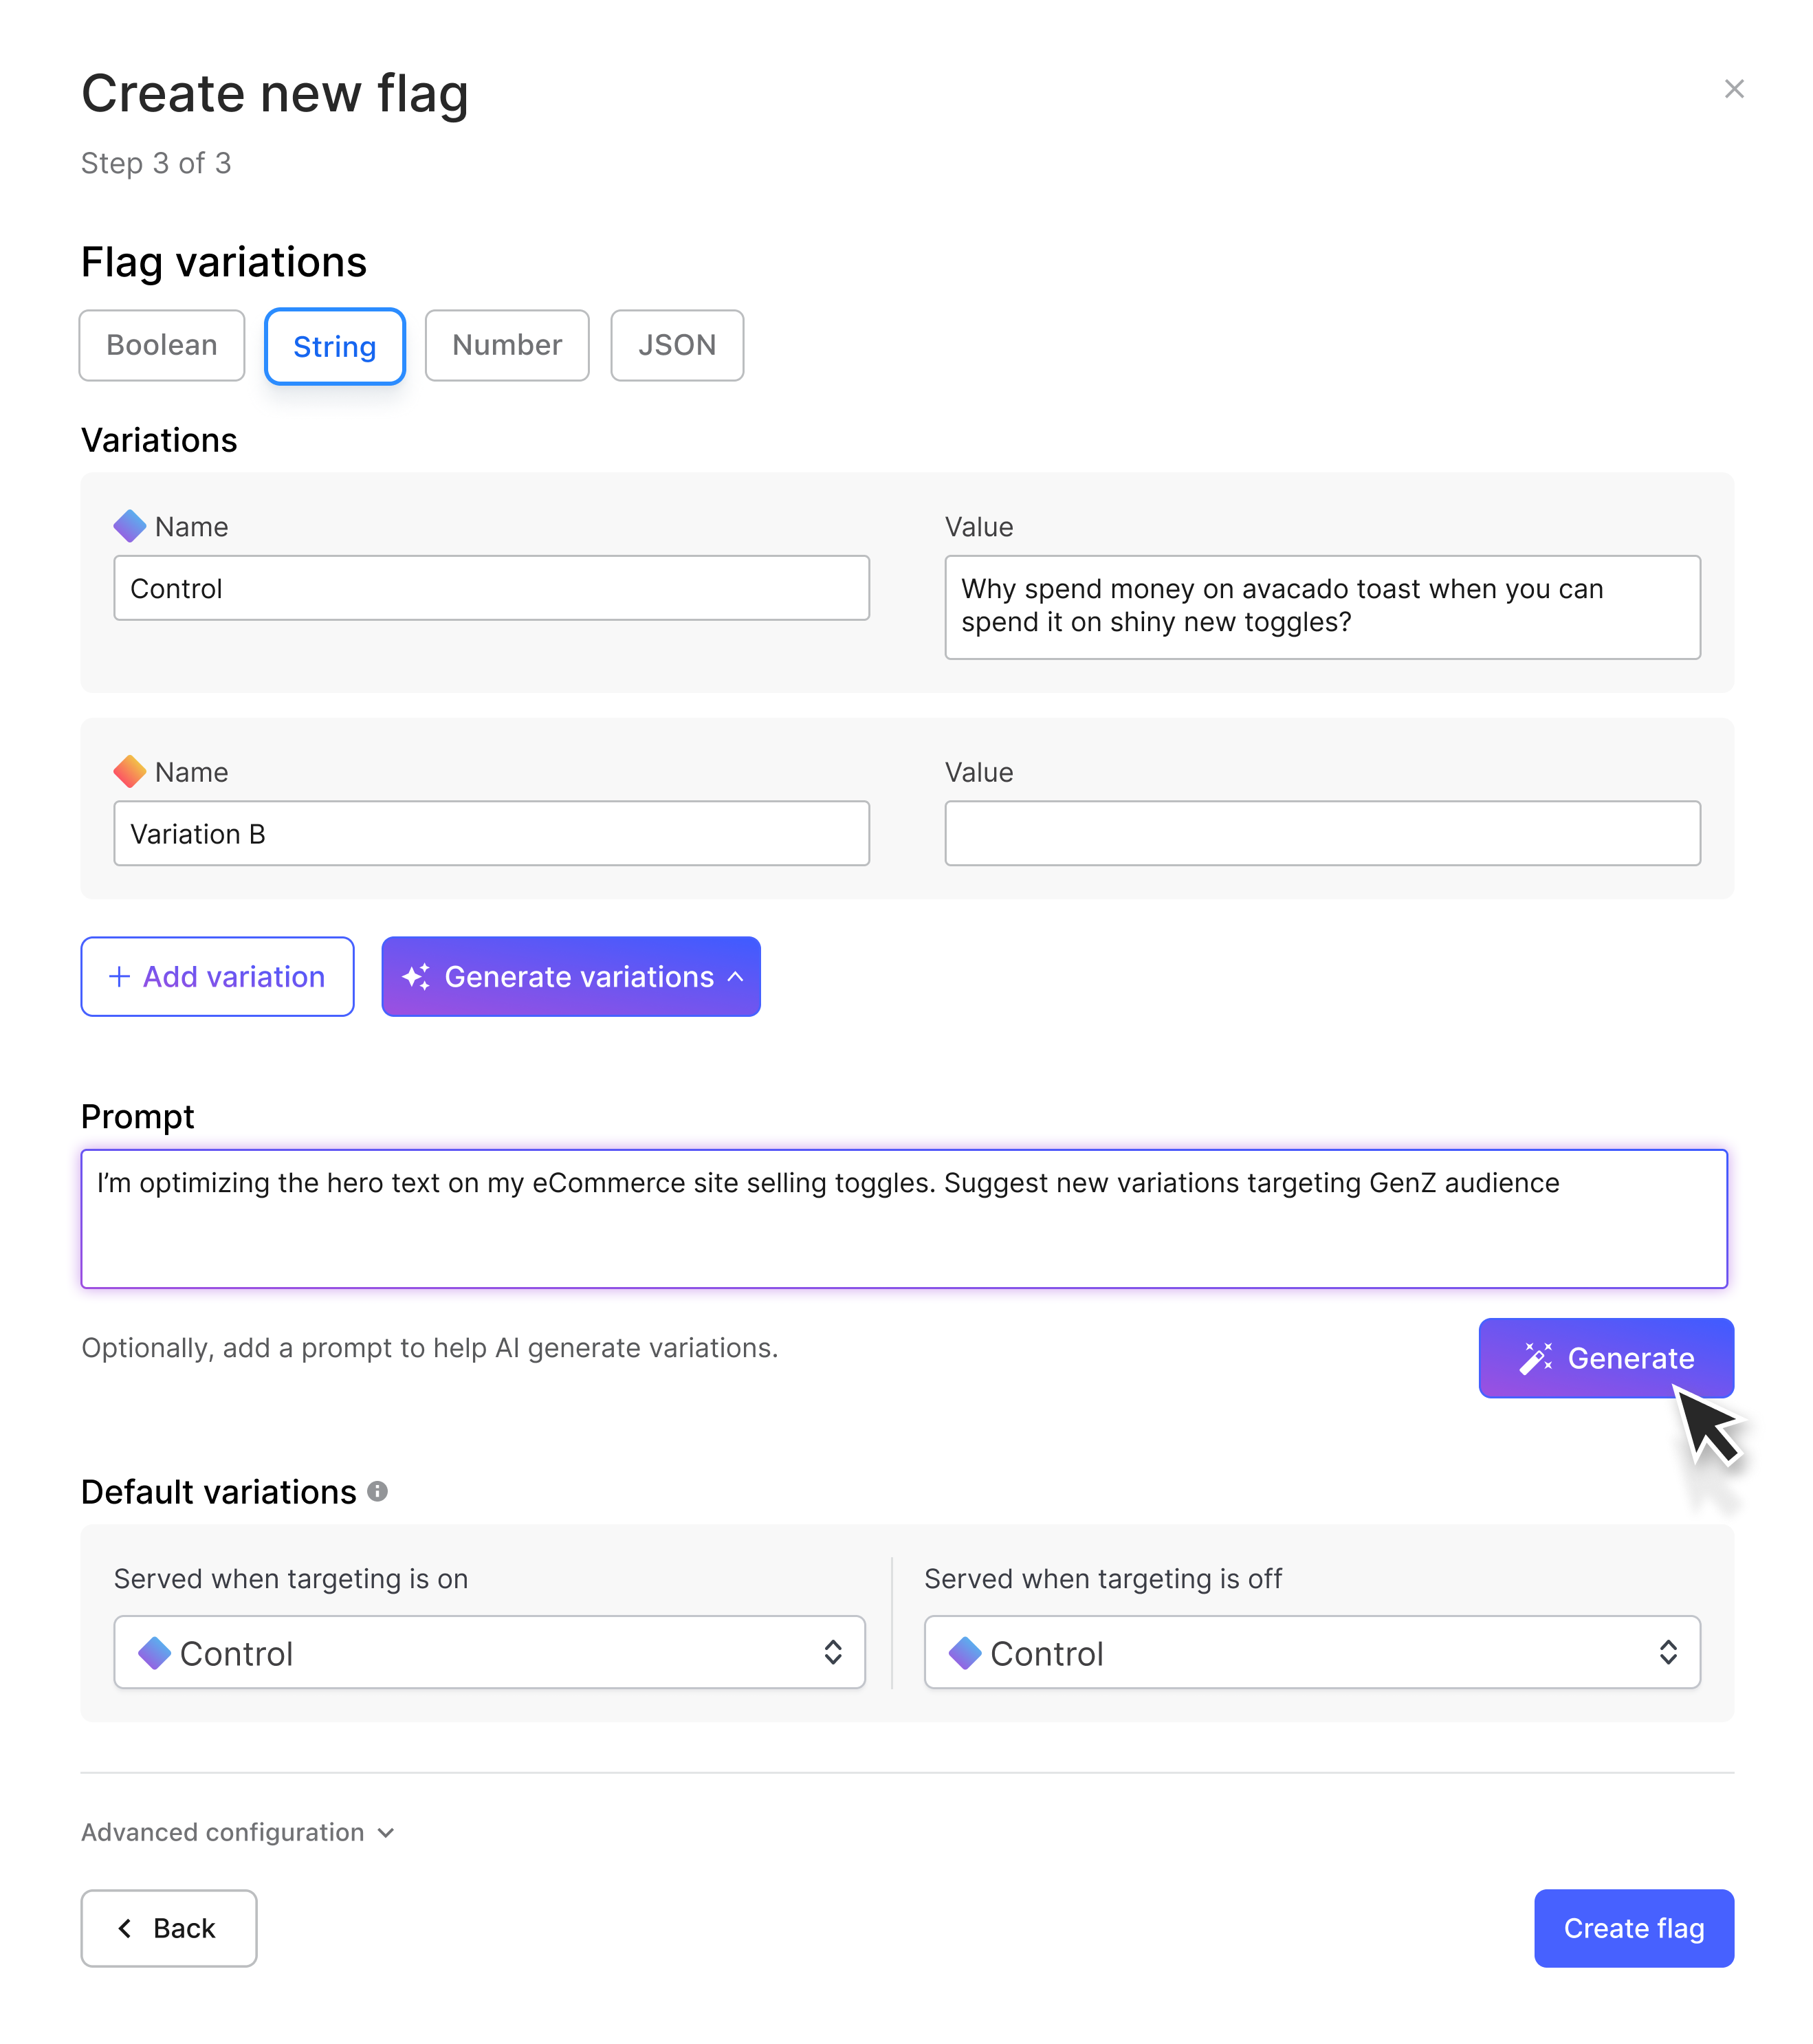
    At the AWS re:Invent 2023 conference, LaunchDarkly today previewed an ability to leverage generative artificial intelligence (AI) capabilities to create experiments for its feature management platform.

    Based on the Bedrock foundational large language models (LLMs) made available via AWS, this extension to the company’s Product Experimentation platform promises to make it simpler to use historical data to create a wider range of offerings that might be made available within an application.

    LaunchDarkly is making a case for a SaaS platform that can be used to centrally manage features across multiple workflows and platforms.

    Robert Neal, director of engineering for LaunchDarkly, said the company is now extending its testing capabilities using a managed Bedrock service provided by AWS that will enable leveraging generative AI to define a testing hypothesis more easily. That should also make it possible to involve more stakeholders in an iterative testing process within the context of a set of well-defined guardrails, he added.

    As more organizations start to deliver different tiers of digital services at varying price points, there is a clear need to be able to restrict access to those digital services. Application development teams have been employing feature management since the 1970s to isolate the development of various components into a branch that can be worked on and tested without impacting the primary build the application is based on.

    Feature management enables development teams to experiment with adding new capabilities in a way that doesn’t disrupt the application. When a project is completed, that branch is then usually merged into the primary build or can be deployed as a microservice that might be invoked via an application programming interface (API) by other modules with the application or another external application.

    At the core of that capability are what are known as feature flags, also known as feature toggles or feature switches, that make it possible to dynamically turn services on or off based on who is accessing them. Rather than being limited to the application development process, those feature flags are now being employed in production environments to enable the continuous delivery of multiple types of digital services to various classes of users of an application. A feature flag management platform enables an organization to keep track of all the flags being employed to keep the overall application environment consistent.

    It’s still early days in terms of understanding the extent to which generative AI can be applied to DevOps workflows, but it’s clear many of the manual processes that conspire to slow down the pace at which applications are built and deployed are going to be either reduced or outright eliminated. Each DevOps team will naturally need to determine for itself to what degree DevOps workflows can be automated using AI, but the overall pace at which applications can be built and deployed is going to clearly accelerate. The challenge now will be finding ways to keep pace with a rate of application development that is about to exponentially increase.

  • Lineaje Allies With Persistent Systems on Open Source Software Remediation Service

    Lineaje Allies With Persistent Systems on Open Source Software Remediation Service

    Lineaje this week revealed it has partnered with Persistent Systems to provide a managed service for remediating open source vulnerabilities that leverages artificial intelligence (AI) technologies.

    Persistent is extending an existing open source software maintenance service by incorporating a Lineaje platform that makes use of machine learning algorithms to analyze software bill of materials (SBOMs) to provide recommendations for fixing code and surface remediations such as updates that should be applied.

    Lineage CEO Javed Hasan said Persistent Systems is augmenting that capability with a dedicated team of specialists that IT organizations can contract to maintain open source code along with previous investments the managed service provider has made in large language models (LLMs) that add generative AI capabilities.

    Options for the services range from simply identifying issues that an internal IT team should address to a white glove offering through which Persistent Systems ensures all open source components are continuously updated.

    In the wake of an executive order issued by the Biden administration that requires federal agencies to better secure their software supply chains, more attention is being focused on the inherent cybersecurity risks associated with employing open source software to build applications. Many open source projects are led by a handful of maintainers that often lack the time and skills required to ensure the components they employ have not, for example, been compromised by malware that might find its way into downstream applications.

    Those maintainers are not being paid, so cybersecurity patches to open source software might not be readily made available, and even when they are, many organizations lack the skills and resources required to apply them in a timely manner. The majority of known vulnerabilities within application environments are still unpatched. Many IT teams are also reluctant to upgrade components for fear of breaking applications that have dependencies that are often difficult to track.

    It’s not known how much of the open source software that many developers routinely incorporate into their applications might contain vulnerabilities that could be exploited, but the level of technical debt that has accrued over the last several decades is considerable. While only a small percentage of those vulnerabilities have been exploited, cybercriminals are becoming more adept at discovering them.

    Hopefully, more contributions to open source projects will improve the overall state of application security, but in the meantime, it’s clear organizations will need to rely more on AI to drive DevSecOps workflows as ever-increasing amount of open source software continues to be relied on to build applications, said Hasan.

    The challenge, of course, is identifying which vulnerabilities, if exploited, will have the biggest impact on the organization. After all, at this point, it’s not possible to defend every application so the focus needs to be on prioritizing remediation efforts based on their actual severity rather than a general rating.

    In the meantime, DevSecOps teams would be well-advised to have incident response plans in place for remediating breaches involving both known and zero-day vulnerabilities that, in addition to being all but inevitable, can now be exploited within minutes of being discovered.