Author: Mike Vizard

  • Couchbase Adds Columnar Database to DBaaS Environment

    Couchbase Adds Columnar Database to DBaaS Environment

    At the AWS re:Invent 2023 conference today, Couchbase, Inc. announced it added a columnar database based on the JSON file format to its database-as-a-service (DBaaS) portfolio to enable organizations to build real-time analytics applications.

    Scott Anderson, senior vice president for product management and business operations at Couchbase, said the Capella columnar database is designed to be integrated with the company’s JSON-based document database via a database change protocol (DCP) that Couchbase has embedded within its DBaaS environment.

    Deployed on cloud services from Amazon Web Services (AWS), the overall goal is to reduce the level of friction that IT teams would otherwise encounter when integrating a document database with a columnar database optimized to process analytics using columns rather than the rows typically associated with a relational database.

    That approach gives IT teams the ability to use a schemaless database architecture that provides an alternative to employing disparate databases that would need to be deployed and then integrated using extract, transform and load (ETL) processes to move data from one database to the other, noted Anderson.

    Capella columnar also uses the same SQL++ language as the company’s document database to streamline queries in addition to supporting Capella iQ, a copilot based on generative artificial intelligence (AI) that enables queries to be crafted in natural language.

    In addition, Capella columnar provides connectors to move data from Amazon DynamoDB, Amazon DocumentDB, Amazon Relational Database Service (Amazon RDS) and other data sources deployed on the AWS cloud.

    In the longer term, Couchbase is also planning to add vector capabilities to its DBaaS environment to make it simpler to securely extend generative AI models, said Anderson.

    In general, document databases have been widely adopted because they provide developers with an alternative to legacy database platforms that they can download and deploy themselves. The Capella DBaaS platform further simplifies that process via a managed service through which Couchbase assumes operational responsibility for managing databases. The columnar database extends that capability using a columnar database that can drive analytics capabilities to deliver a more personalized application experience, noted Anderson.

    It’s not clear to what degree organizations will ultimately wind up relying on as-a-service platforms, but since the start of the COVID-19 pandemic, the shift to this approach to consuming IT resources has increased significantly. As a result, the way internal IT teams are organized is shifting as lower-level tasks are either automated or handled by an external IT team that works for a vendor.

    Regardless of how databases are managed, however, there remains a need to integrate the data operations (DataOps) processes used to manage them with the DevOps workflows used to build modern applications. Each organization will need to determine how much economic sense it makes for them to manage that data versus relying on an external services provider. The challenge when relying on an external service provider is, as always, integrating that service into an existing IT environment.

  • Lineaje Allies With Persistent Systems on Open Source Software Remediation Service

    Lineaje Allies With Persistent Systems on Open Source Software Remediation Service

    Lineaje this week revealed it has partnered with Persistent Systems to provide a managed service for remediating open source vulnerabilities that leverages artificial intelligence (AI) technologies.

    Persistent is extending an existing open source software maintenance service by incorporating a Lineaje platform that makes use of machine learning algorithms to analyze software bill of materials (SBOMs) to provide recommendations for fixing code and surface remediations such as updates that should be applied.

    Lineage CEO Javed Hasan said Persistent Systems is augmenting that capability with a dedicated team of specialists that IT organizations can contract to maintain open source code along with previous investments the managed service provider has made in large language models (LLMs) that add generative AI capabilities.

    Options for the services range from simply identifying issues that an internal IT team should address to a white glove offering through which Persistent Systems ensures all open source components are continuously updated.

    In the wake of an executive order issued by the Biden administration that requires federal agencies to better secure their software supply chains, more attention is being focused on the inherent cybersecurity risks associated with employing open source software to build applications. Many open source projects are led by a handful of maintainers that often lack the time and skills required to ensure the components they employ have not, for example, been compromised by malware that might find its way into downstream applications.

    Those maintainers are not being paid, so cybersecurity patches to open source software might not be readily made available, and even when they are, many organizations lack the skills and resources required to apply them in a timely manner. The majority of known vulnerabilities within application environments are still unpatched. Many IT teams are also reluctant to upgrade components for fear of breaking applications that have dependencies that are often difficult to track.

    It’s not known how much of the open source software that many developers routinely incorporate into their applications might contain vulnerabilities that could be exploited, but the level of technical debt that has accrued over the last several decades is considerable. While only a small percentage of those vulnerabilities have been exploited, cybercriminals are becoming more adept at discovering them.

    Hopefully, more contributions to open source projects will improve the overall state of application security, but in the meantime, it’s clear organizations will need to rely more on AI to drive DevSecOps workflows as ever-increasing amount of open source software continues to be relied on to build applications, said Hasan.

    The challenge, of course, is identifying which vulnerabilities, if exploited, will have the biggest impact on the organization. After all, at this point, it’s not possible to defend every application so the focus needs to be on prioritizing remediation efforts based on their actual severity rather than a general rating.

    In the meantime, DevSecOps teams would be well-advised to have incident response plans in place for remediating breaches involving both known and zero-day vulnerabilities that, in addition to being all but inevitable, can now be exploited within minutes of being discovered.

  • Microsoft Previews Additional Copilot Tools for Azure

    Microsoft Previews Additional Copilot Tools for Azure

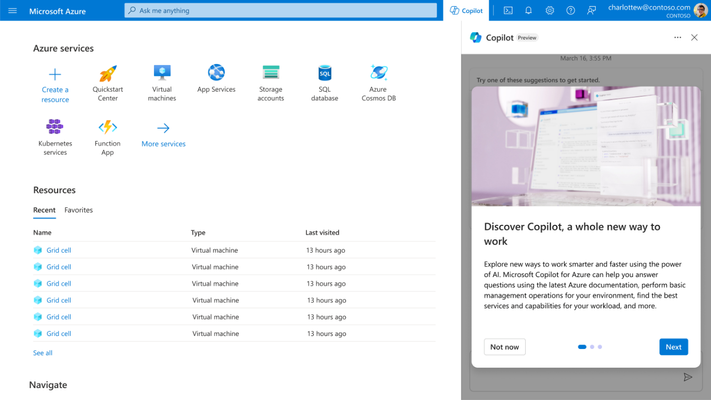
    At its Ignite 2023 conference, Microsoft this week previewed Copilot tools to simplify the management of the Azure cloud service along with a tool that streamlines the building and deploying of artificial intelligence (AI) applications on the Azure platform.

    In addition, Microsoft launched Microsoft Copilot Studio, a low-code tool that automates the process of creating data integration plugins and adding custom copilots within the Microsoft Copilot for Microsoft 365 tool that Microsoft previously launched.

    Microsoft Copilot for Azure leverages large language models (LLMs) to enable IT teams to use natural language to create, configure, discover and troubleshoot Azure services. It also enables IT teams to create complex commands, ask questions and optimize costs.

    Erin Chapple, corporate vice president for Azure Core at Microsoft, told Ignite attendees that Microsoft, along with a handful of customers, is already using Microsoft Copilot Azure to manage Azure infrastructure.

    In the long term, it’s clear that Microsoft is moving toward streamlining the building and deployment of AI applications using Azure AI Studio, a framework for invoking the AI models that Microsoft makes available on the Azure platform. The goal is to make it possible for organizations to create their own copilots based on AI models they have trained.

    It’s still early days in terms of organizations leveraging AI models to build applications, but it’s already apparent that DevOps and machine learning operations (MLOps), along with data engineering and cybersecurity best practices, will need to converge. Microsoft is making a case for Azure AI Studio as the framework that will enable IT organizations to achieve that goal.

    Of course, Microsoft is not the only provider of IT infrastructure resources with similar ambitions, but thanks to its investments in OpenAI and the acquisition of GitHub, it is furthest along in terms of defining a framework for building AI applications at scale. Last week, GitHub previewed an extension of the Copilot tools it already provides to help developers write code that leverages generative AI to automatically propose an editable plan for building an application based on natural language descriptions typed into the GitHub Issues project management software. Copilot Workspace will generate editable documents via a single click that can be used to create code that developers can then visually inspect. Any errors discovered by application developers or the Copilot Workspace platform can also be automatically fixed.

    At the same time, GitHub has extended the scope and reach of Copilot Chat to make it simpler for developers to use natural language to discover issues in their code base.

    Generative AI is already having a massive impact on the rate at which applications are developed, but that code still needs to be reviewed. Chat GPT is based on a general-purpose large language model (LLM) that is trained by pulling in code of varying quality from all across the web. As a result, code generated by the platform might contain vulnerabilities or be inefficient. In many cases, professional developers still prefer to write their own code.

    Of course, not every programming task requires the same level of coding expertise. In many instances, ChatGPT will generate, for example, a script that can be reused with confidence across a DevOps workflow. There is no shortage of mediocre developers who are now writing better code thanks to tools such as GitHub Copilot, and soon, domain-specific LLMs will make it possible to consistently write better code based on validated examples of code.

    The next challenge is going to be finding a way to manage increased volumes of code. There is no doubt that AI will be applied to the management of DevOps pipelines, but for the moment, at least, the pace at which AI is being applied to writing code is already exceeding the ability of DevOps teams to manage it.

  • Nobl9 Allies With Microsoft to Simplify SLO Creation

    Nobl9 Allies With Microsoft to Simplify SLO Creation

    Nobl9 this week revealed it has integrated its reliability center platform for managing service level objectives (SLOs) as code with the Microsoft Azure Monitor service to make it simpler to both create and track service levels.

    The Nobl9 Reliability Center provides access to dashboards for a single source of truth about the state of reliability in an application environment based on the metrics collected from the SLOs that have been defined.

    Nobl9 Chief Growth Officer Kit Merker said the integration with Microsoft Azure Monitor is the first in a series that will ultimately make it easier to define SLOs using historical data collected by third-party tools.

    The Nobl9 Reliability Center is already integrated with more than 50 DevOps, observability and incident management tools through which it collects metrics, events, logs, traces, alerts to track incidents, releases, rollbacks, runbooks and other documentation.

    Those integrations will ultimately make it simpler for IT teams to create SLOs using historical data that today are still challenging to define from scratch, noted Merker. In fact, the data tracked by Nobl9 can be used to automate remediations via those integrations, he noted.

    As more microservices-based applications are built and deployed, it’s becoming more challenging to maintain SLOs across applications that have many more dependencies than legacy monolithic applications. Each feature and application programming interface (API) added over time conspires to adversely impact performance. It‘s not so much that any given service will outright fail as much as it is determining where degradations are occurring that result in SLOs not being met.

    Ultimately, each IT team needs to provide some sort of objective benchmark that assesses their overall effectiveness at delivering application services by making it simpler to track whether SLOs are achieved and maintained. Not every service needs to necessarily meet a stringent requirement. Instead, IT teams need to have confidence in the fact that, on average, certain levels of performance are being consistently maintained.

    That’s crucial because as more organizations depend on software to deliver digital services, any disruption is likely to have a direct impact on profit and revenue. As such, the reliability of application environments has become a major concern in an era where IT teams are now trying to manage distinct services rather than individual applications.

    The challenge and the opportunity now is to find a way to proactively reduce that stress by programmatically managing SLOs as code rather than having to overprovision infrastructure resources to ensure maximum availability at the highest cost possible. At a time when more organizations are encountering economic headwinds, that’s no longer a luxury they can afford.

    Each organization will need to determine for themselves how aggressively they need to manage SLOs. Of course, SLOs as a concept have been around for decades, but with the rise of digital services that span multiple organizations, the level of reliability DevOps teams are expected to provide is now being written into business contracts. Not surprisingly, the overall level of associated stress DevOps teams are experiencing has correspondingly increased.

  • Redgate Automates Pulling of Test Data From Production Databases

    Redgate Automates Pulling of Test Data From Production Databases

    Redgate today added a Redgate Test Data Management (TDM) tool that automates the pulling of masked test data from databases running in production environments.

    David Gummer, chief product officer for Redgate, said this capability eliminates manual tasks that previously inhibited testing or resulted in personally identifiable information (PPI) being inadvertently used to test applications.

    Redgate TDM automatically classifies and masks data residing in SQL Server, PostgreSQL, MySQL or Oracle database before it is used to test an application. It then produces a copy or clone of that data that is a fraction the size of the original, said Gummer.

    That approach creates a repeatable process for DevOps teams that can withstand a regulatory audit of application development processes, he added. In fact, with the increased focus on software supply chain issues, more auditors are specifically reviewing how data is secured during the application development process.

    Designed to be invoked via a command line interface (CLI), within an integrated development environment or via a graphical interface, Redgate TDM reduces the friction that currently occurs when DevOps teams request test data from database administrators (DBAs), said Gummer. Many DBAs are either too busy to fulfill those requests or reluctant to provide access to sensitive data that would result in the organization running afoul of a compliance mandate.

    Developers then often resort to using anonymous data that doesn’t actually reflect the environment in which their application will ultimately be deployed.

    The amount of data that developers need to build applications is only going to increase. In the absence of any way to effectively automate the process of accessing that data, it ultimately takes longer to build and deploy stable applications. In many cases, applications are simply not tested as thoroughly as they should be before being deployed in a production environment, resulting in rollbacks that might otherwise be avoidable.

    Advances in artificial intelligence (AI) are making it easier to create test scripts, but much of the testing setup process is still based on manual processes that increase the overall level of toil.

    At a time when more organizations than ever are trying to increase developer productivity, automating relatively mundane tasks such as pulling test data can have a big impact. Developers want to spend as much time as possible focused on writing code. Everything else is a task that gets in the way of achieving that goal. While there is a general desire to empower developers, that doesn’t necessarily mean they want the cognitive load associated with building applications to increase. In fact, one of the reasons platform engineering has emerged as a methodology for managing DevOps workflows at scale is to reduce the current level of cognitive load developers experience today.

    Of course, DevOps teams are, by their nature, ruthlessly committed to automating as many processes as possible. The challenge is bottlenecks in those processes conspire to slow down the overall rate at which applications can be built and deployed despite the best intentions of all involved.