Author: Mike Vizard

  • CircleCI CEO Sees Growing Need for Developer Experience Engineers

    CircleCI CEO Sees Growing Need for Developer Experience Engineers

    There is no shortage of titles to go with all the tasks that make up a DevOps workflow, but given the critical role developers now play within any organization, it might be time for organizations to start creating a developer experience engineer (DXE) function within DevOps teams that is specifically tasked with increasing developer productivity.

    CircleCI CEO Jim Rose said it’s become apparent there is more friction than ever in the application development and deployment process, as more complex applications are constructed, thanks, in part, to the rise of microservices.

    A DXE, as outlined in a report published by CircleCI, would be responsible for implementing a common set of DevOps principles, maintaining the right tools and putting in place a cohesive set of standard processes that ensure developer success. Today, there are simply too many languages, frameworks, engineering styles and processes being employed within the same organization, and that conspires to reduce overall developer productivity, said Rose.

    While software engineers are, today, addressing subsets of these issues, Rose said the time has come to assign these tasks to an engineering team that views itself as an advocate for developers by making available more responsive infrastructure.

    As organizations of all sizes increasingly realize how dependent they are on software to drive digital business transformation initiatives, Rose noted that developer productivity is becoming a major corporate issue. Revenue forecasts and profit margins are now being directly impacted by the rate at which software is being delivered and updated.

    Software engineers today routinely build DevOps pipelines for developers, but not much time and effort is put into optimizing the developer experience, noted Rose. That’s become not only a major productivity issue, Rose said, it has a material impact on the ability of organizations to attract and retain developer talent. One of the reasons so many developers prefer to work for smaller startups than large enterprises is because their daily work experience is simply better. Large organizations need to reduce the amount of friction developers experience if they want to be able to compete for that same talent, said Rose.

    A DXE would also be more inclined to solicit input from developers on tool selection to best optimize productivity, noted Rose. Many software engineers today construct pipelines with little to no regard for how simple or hard it might be for a developer to employ tooling.

    Organization today are, of course, starting to become more obsessed with measuring application development velocity. However, in many cases, simply making someone responsible for achieving a goal is going to result in more gains at a lower cost. Analytics tools have a role to play, but obsessing over key performance indicators (KPIs) may not generate the same result as quickly as simply giving an engineer a specific mandate.

    As responsibility for application management continues to shift left toward developers, it should not come as a surprise that there is a lot more interest in automating the underlying infrastructure. The issue, at this point, is determining to what degree software engineers are going to achieve that goal versus forcing developers to seek out yet another platform that promises to do it on their behalf.

  • Dynatrace Applies AI to Surface App Vulnerabilities

    Dynatrace Applies AI to Surface App Vulnerabilities

    Dynatrace has enhanced the security module to its observability platform that leverages its Davis artificial intelligence (AI) engine to automatically identify the software libraries and open source packages that represent the greatest security risk.

    Ajay Gandhi, vice president of product marketing for Dynatrace, said the Davis Security Advisor, being added to the Dynatrace Application Security Module, makes it easier for IT teams to understand which vulnerabilities need to be remediated first.

    Davis Security Advisor aggregates vulnerability data in real-time and prioritizes remediation based on the number of vulnerabilities, severity, impact to sensitive data, public exposure, how widely known the vulnerability is, and whether the code impacted is facing the internet. That approach enables Davis Security Advisor to monitor all software libraries used in preproduction and production environments in a way that sharply reduces the number of false positives that would otherwise be generated, noted Gandhi.

    Dynatrace

    As application environments become more complex—in part due to increased adoption of microservices that have lots of dependencies—it’s become impossible for IT teams to implement DevSecOps best practices in workflows without some form of AI augmentation, added Gandhi.

    In fact, a recent Dynatrace survey found 89% of chief information security officers (CISOs) noted cloud-native architectures and container runtime environments, used primarily to construct microservices, have made it more difficult to detect and manage software vulnerabilities.

    In theory, application developers are taking more responsibility for remediating security vulnerabilities within their applications. The challenge is they often inadvertently use an older version of a library that has known vulnerabilities. Hopefully, that issue gets addressed before an application gets deployed. There are, however, plenty of cases where, for one reason or another, a library with known vulnerabilities gets deployed anyway.

    Making matters more challenging, many vulnerabilities are discovered after an application has been deployed. Developers don’t always have access to a software bill of materials that would make it easier to determine what libraries have been employed in what application or, for that matter, which libraries are dependent upon one another.

    Gandhi said the Davis Security Advisor resolves that issue via continuous topology mapping of dependencies to identify those potential security issues. Once identified, the updates that need to be made can then be slipstreamed into a DevOps workflow.

    Analyzing code for vulnerabilities is, of course, not a new idea. Training an AI model to perform that task on behalf of DevOps teams does promise to greatly accelerate the process at a time when organizations are under more pressure than ever to secure their software supply chains in the wake of a series of high-profile breaches.

    It’s just not clear yet who inside organizations might drive adoption for AI platforms capable of identifying vulnerabilities in a way that helps prioritize remediation efforts. In some cases, cybersecurity teams have a vested interest in reducing the number of potential security incidents.

    The one thing that is apparent is shipping insecure code faster only leads to more negative outcomes. There may not be such a thing as a ‘great’ application that happens to be insecure. Instead, the assumption will be that any applications with known vulnerabilities, no matter how great, are too flawed to be deployed given all the security risks most businesses currently face.

  • Hasura Extends Scope of GraphQL API Platform

    Hasura Extends Scope of GraphQL API Platform

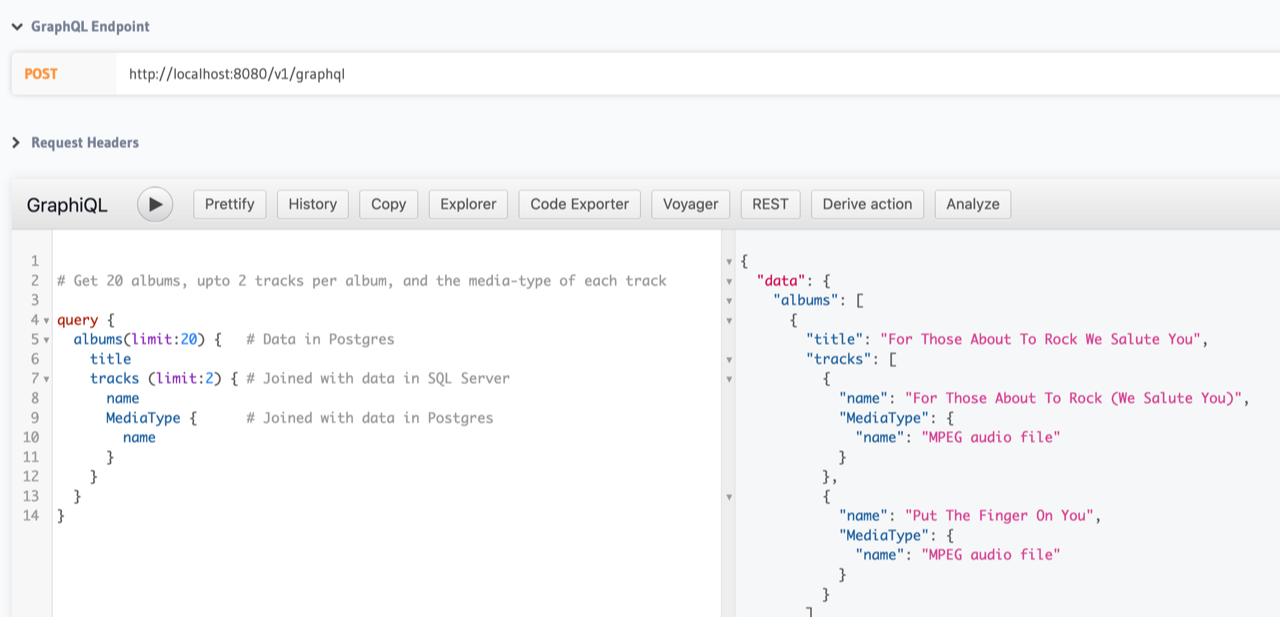
    During its online an HasuraCon ’21 conference, Hasura today announced that it has made it possible for developers to employ GraphQL application programming interface (APIs) to launch queries against data residing in multiple databases.

    At the same time, Hasura announced a preview of schema sharing capabilities along with support for workflows based on GitOps processes that it will make generally available later this year. The Hasura Cloud platform can now deploy local migrations from staging to production with a simple git push in addition to accessing previews of applications on every pull request to the git repository.

    The schema sharing capability added to the Hasura GraphQL Engine is intended to bridge the gap between beginner and power users by allowing them to share and install samples of permissions, relationships and metadata. In addition to improving collaboration, the goal is to make it easier to onboard software engineers as projects evolve and become more complex.

    Originally developed by Facebook, GraphQL has emerged as a popular alternative to REST APIs because it enables developers to retrieve data at a more granular level, which results in improved performance.

    Hasura is a provider of an instance of a GraphQL engine the company has developed around a project that is now hosted by the GraphQL Foundation, an arm of the Linux Foundation. The GraphQL Foundation counts among its members Airbnb, Amazon Web Services (AWS), Apollo, Coursera, Elementl, Facebook, GitHub, IBM, Intuit Hasura, Paypal, Prisma, Shopify and Twitter.

    GraphQL provides a complete description of the data made available via an API and is organized in terms of types and fields rather than traditional endpoints. In addition to clarifying what data is available via that API, developers can employ types to avoid writing manual parsing code.

    Since last summer, Hasura has been making available a pilot of a GraphQL implementation that is capable of supporting remote joins across disparate databases. That capability is critical because data sets that are related to a specific business process may wind up being stored in multiple databases.

    Hasura

    Tanmai Gopal, Hasura CEO, said the open source Hasura GraphQL Engine has already been downloaded more than 250 million times this year. Downloads in 2020 reached 100 million. The challenge is that while GraphQL offers a superior alternative to REST APIs, most of the API tooling that exists within organizations is still designed around REST APIs, noted Gopal.

    To accommodate that reality, Hasura has made a tool available that will convert a query designed using GraphQL into a set of calls that are compatible with REST APIs. Developers still gain the benefits of being able to launch more granular queries, noted Gopal.

    REST APIs, in general, are becoming more problematic as organizations embrace microservices-based applications. It often takes minutes to refresh a simple dashboard because of the amount of data that REST APIs are trying to pull from various data sources. As organizations embrace digital business transformation, they are also encountering application latency issues that can be traced back to the amount of data being called from multiple microservices.

    Hasura says in addition to providing a more efficient method to access data, Hasura is also working on adding caching capabilities to its core engine to further improve performance.

    It’s not clear at what rate GraphQL might replace REST APIs, but DevOps teams should assume organizations will wind up employing a mix of both for years to come. The challenge is going to be determining when to make the transition as organizations become more dependent on APIs.

  • Salesforce Pilots Series of DevOps Initiatives

    Salesforce Pilots Series of DevOps Initiatives

    At its online TrailheaDX 2021 conference, Salesforce today unveiled a DevOps Center pilot that provides a portal through which organizations can track and manage changes to Salesforce applications along with a unified command line interface (CLI) for all its applications.

    In addition, Salesforce plans to add Salesforce Functions to enable developers to deploy code in a serverless environment.

    The company has also promised to extend its low-code App Builder tool to include support for Dynamic Interactions, a capability that enables both professional and citizen developers to add reusable components to any application. The company has also added a Customer Identity Plus tool that enables developers to consolidate and manage customer identities.

    Finally, Salesforce is adding an Einstein Automate tool that employs machine learning algorithms to both integrate data and automate workflows that can invoke, for example, an existing MuleSoft Composer tool for integrating applications using a Flow Orchestrator that will be made available as a pilot project this summer. MuleSoft is a subsidiary of Salesforce. There is also now an Einstein Data Detect tool that ensures organizations adhere to data privacy laws by employing machine learning algorithms to discover when developers might have inadvertently exposed sensitive data.

    Dynamic Interactions, Salesforce Functions and CLI unification are expected to be generally available in the winter of next year, while the Einstein capabilities are expected to arrive this summer.

    Ryan Ellis, senior vice president of product management for platform at Salesforce, said the company is making a concerted effort to make it easier for both professional and citizen developers to build applications within the same environment by fostering collaboration via a DevOps Center portal that is expected to be generally available in the spring of 2022. Today the skills that any citizen developer can bring to bear are generally limited, largely because they don’t typically know how to build a well-designed, secure application that will truly scale in an enterprise IT environment.

    Salesforce

    However, as more artificial intelligence (AI) capabilities are added to low-code tools the amount of developer guidance being provided will increase over time. That additional guidance will enable citizen developers to build robust applications more reliably, noted Ellis.

    In the meantime, the primary beneficiaries of low-code tools continue to be professional developers that employ them to build applications faster than they could otherwise using procedural code.

    In general, Ellis said the relative DevOps maturity of organizations building and deploying custom applications on top of the software-as-a-service (SaaS) platform managed by Salesforce continues to increase steadily. In the wake of the COVID-19 pandemic, many organizations opted to extend existing SaaS applications provided by Salesforce to accelerate digital business transformation initiative using low-code tools rather than developing every application from scratch using procedural code.

    Of course, as the rate at which those applications are being built continues to accelerate, the next big challenge is managing the application life cycles after they are deployed.

    It’s not clear what the ultimate mix of applications built using low-code tools versus procedural code will be. Millions of lines of code are now being regularly deployed on Salesforce platforms, noted Ellis. It may be a little while before Salesforce is able to bring DevOps best practices to all that code, but, starting today, the journey has begun.

  • Plutora Dives Deeper into Value Stream Analytics Data

    Plutora Dives Deeper into Value Stream Analytics Data

    Plutora announced today it has extended the capabilities of its value stream management (VSM) platform to include a common object data model that more efficiently normalizes data collected from multiple DevOps tools and platforms.

    Jeff Keyes, vice president of product marketing and strategy for Plutora, said the goal is to expand the level of scale and depth at which the Plutora analytics engine embedded within the Plutora Platform can analyze flow metrics.

    VSM has emerged as a distinct DevOps discipline that provides a framework for enabling organizations to optimize workflow across DevOps environments in a way that allows them to accelerate application development. The core concept traces its lineage to lean manufacturing methods that continuously measure each step of a process to improve production.

    As organizations develop a deeper appreciation for their dependency on software, the level of interest in understanding how software is constructed has increased. Organizations, for example, want to better understand the impact of missed software development deadlines on revenue, which a business might not be able to generate as quickly as anticipated.

    Plutora is making a case for a dedicated analytics platform that pulls data from multiple platforms. Alternatively, more value stream analytics capabilities are now being embedded in everything from project management software to continuous integration. Plutora contends, however, that navigating multiple value stream dashboards surfaced by different tools that make up a DevOps workflow is not as simple or effective as relying on a single platform that collects data from every tool employed.

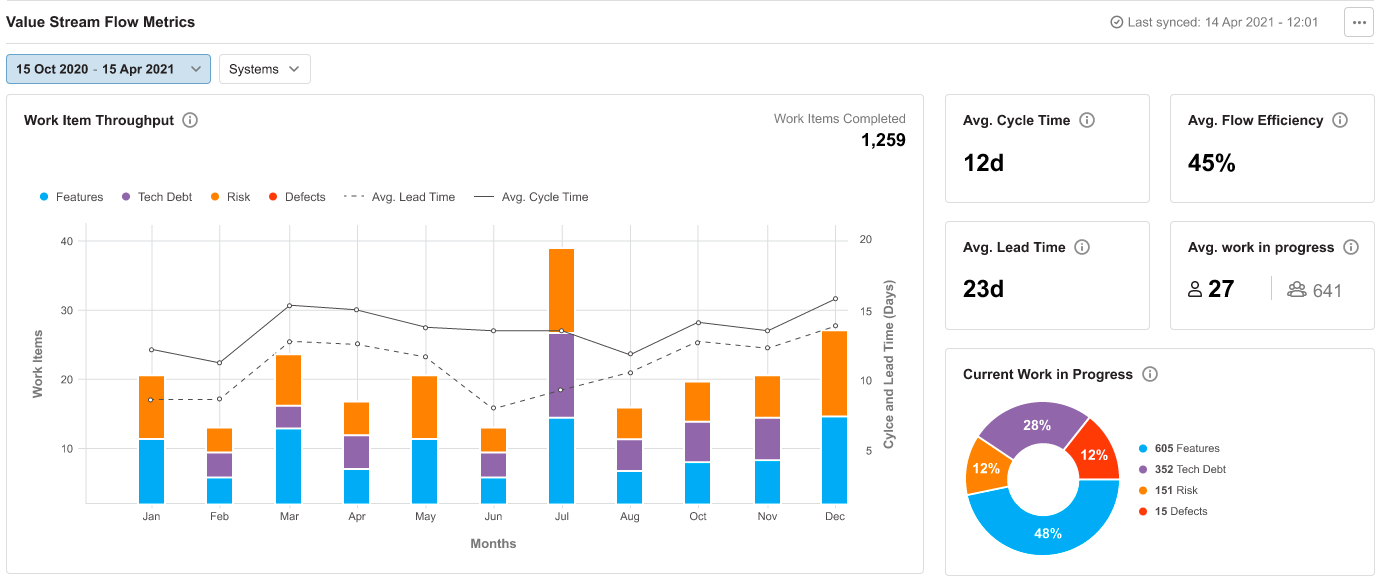
    Metrics that track lead and cycle times for projects as well as overall throughput become much easier to surface and comprehend, noted Keyes.

    One way or another, more transparency is coming to DevOps workflows. Historically, collecting this data has been challenging because it required DevOps teams to manually collect data from each tool being used. In effect, DevOps teams were wasting time copying and pasting data from one tool into an analytics application.

    As it becomes simpler to aggregate all that data, the data model provided by Plutora makes it simpler for multiple analytics tools to analyze the same data. A business user, for example, may prefer to analyze data using the Tableau analytics platform that is now owned by Salesforce.

    In general, analytics is being applied more widely across software development processes because organizations need to increase productivity while simultaneously reducing costs. It will be up to each organization to decide to what degree they may want to use that data to better train DevOps teams versus simply using it to remind those teams to stay focused on a specific set of key performance indicators (KPIs).

    In the meantime, the number of requests for reports being made to DevOps teams should decline as the process of collecting metrics becomes more automated. The challenge now will be making sure everyone reading those reports has the same firm understanding of what’s actually possible to achieve using not only the resources at hand, but also how any additional DevOps expertise might positively impact that equation.

  • GitLab Updates Approach to Integrating DevOps Workflows

    GitLab Updates Approach to Integrating DevOps Workflows

    GitLab today took the wraps off a major update to its continuous integration/continuous delivery (CI/CD) platform that embeds analytics tools in workflows to identify the root cause of inefficiencies, among other additional capabilities.

    David DeSanto, senior director for product management at GitLab, said that capability is part of an ongoing effort to include value stream analytics within the core GitLab 14 platform as an alternative to acquiring and deploying a separate platform. There are also additional charts and dashboards that enable DevOps teams to uncover bottlenecks over time.

    In addition, GitLab announced it is extending the security capabilities of the platform by adding integrations with open source Semgrep and Trivy vulnerability scanning tools as part of an effort to enable organizations to embrace DevSecOps best practices within workflows. GitLab has also added support for the fuzz testing tool it gained via the acquisitions of Fuzzit and Peach Tech to enable DevOps teams to test application security more thoroughly along with making available additional dashboards to track security metrics.

    As part of an effort to enable organizations to better secure their software supply chains, GitLab has also added support for immutable pipeline definitions that can’t be altered without specific levels of permissions being granted. That capability also enables DevOps teams to more easily achieve compliance with any number of regulatory frameworks, noted DeSanto.

    The company is also adding a pipeline editor that provides access to a visual tool for creating, managing and visualizing pipelines. That tool is designed to both make DevOps more accessible to novices and provide experienced DevOps teams with an alternative tool for managing pipelines in a way that doesn’t require them to write additional code.

    Finally, as part of its comprehensive approach to DevOps, GitLab is also making available agent software for Kubernetes clusters to eliminate the need for organizations to acquire a separate DevOps platform to build and deploy cloud-native applications based on microservices constructed using containers. The company now provides IT organizations with the option of crafting a GitOps workflow for Kubernetes using either an agentless or agent-based approach.

    Gitlab is betting that, as DevOps continues to evolve and mature, more organizations will prefer to replace the various tools they need to integrate themselves with a platform that lowers the total cost of DevOps. Gartner is forecasting that, by 2023, 40% of organizations will have switched from multiple point solutions to a DevOps value stream delivery platform to streamline application delivery, versus less than 10% using such a platform in 2020. Today, only 10% of organizations are employing such a platform, according to Gartner.

    There should also be many more organizations employing DevOps workflows to build applications. Organizations of all sizes now realize how dependent they are on software to drive a wide range of digital business transformation initiatives. The rate at which that software can now be securely developed and updated, in many cases, goes to the heart of their ability to compete. The issue is finding a way to achieve that goal without constructing a platform that ultimately takes time and resources away from building secure software.

  • Linux Foundation Makes Available Software Manifest Tool

    Linux Foundation Makes Available Software Manifest Tool

    The Linux Foundation is making available a set of free tools for building software bills of material (SBOMs) based on the software data package exchange (SPDX) file format it curates.

    Backed by more than 20 organizations, SPDX is an effort to standardize the way metadata describing the contents of a software package is described.

    The SPDX specification was submitted last fall to the International Organization for Standardization (ISO) by the Joint Development Foundation, an arm of the Linux Foundation.

    The Linux Foundation, as part of its efforts, is also making available a free, online training course to provide IT teams with the foundational knowledge required to create and maintain SBOMs.

    Kate Stewart, vice president of dependable embedded systems for the Linux Foundation, said SBOMs play a critical, often overlooked role in maintaining the security of a software supply chain. One of the major challenges organizations have today is that an SBOM isn’t often created, which makes it harder to discover what software components have been included in a package. That makes it difficult for organizations to determine if they are employing a version of a software component that now has a critical vulnerability that was just recently reported, noted Stewart.

    Even when there is a SBOM, its construction can vary from one team or organization to the next. The tools provided by the Linux Foundation are intended to standardize how the fields used to describe a SBOM are defined, added Stewart.

    The SBOM tools being advanced by the Linux Foundation are, in part, a response to President Biden’s executive order pertaining to the security of software supply chains, added Stewart. The National Telecommunications and Information Administration (NTIA), as a result, is now asking for wide-ranging feedback to define the minimum requirements for a SBOM.

    It may take time before there is an agreed upon SBOM standard, but as microservices based on containers become more prevalent, it’s also apparent the issue will become more pressing. More, smaller packages of software being deployed in the enterprise without manifests will only further exacerbate an application security crisis that has deepened in the wake of recent high-profile software supply chain breaches.

    Ultimately, a SBOM should automatically be self-generated as part of any DevOps workflow. The challenge is there is still a massive amount of software being created outside of any formal DevOps workflow. On top of that, the massive amount of poorly documented legacy application software already deployed in an enterprise IT environment makes it clear how big an issue the lack of a simple SBOM really is.

    It’s not precisely clear who inside an organization should be responsible for standardizing SBOMs. The challenge is that within many organizations it’s not the kind of issue for which developers are rewarded, much less motivated, to solve. Nevertheless, everything from application security issues to the massive amount of technical debt that stems from duplication of software development projects can all be traced back to the lack of a simple manifest.

    Of course, now that many organizations are starting to appreciate just how dependent they are on software, more questions are being asked about how it’s constructed. The thing that many of the business executives asking those questions are about to discover (with some incredulity) is how much of the software the organizations depend on is still being built using methods that have more to do with a medieval craft than they do a manufacturing line.

  • Google Proposes SLSA Framework to Secure Software Supply Chains

    Google Proposes SLSA Framework to Secure Software Supply Chains

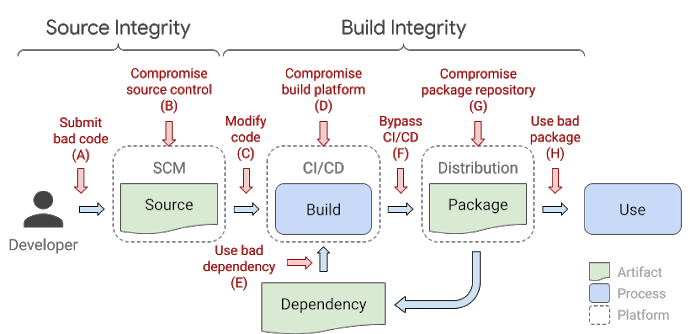
    Google is proposing organizations adopt a framework for securing the integrity of software artifacts across a software supply chain.

    Kim Lewandowski, a product manager for open source software security at Google, said the Supply Chain Levels for Software Artifacts (SLSA) is based on an internal framework, known as binary authorization for Borg, that the company has been employing now for more than eight years to secure its software. Borg is the name Google attached to the platform for building and deploying applications upon which Kubernetes is based.

    In its current form, SLSA is a set of guidelines that identifies how to attain four different levels of application security. The goal, however, is to create a framework that will automatically generate auditable metadata that can be fed into policy engines to create a SLSA certification.

    The lowest level of SLSA requires that the build process be fully scripted or automated and generates metadata that enables provenance to be created. At the highest level, SLSA requires a two-person review of all changes made during a hermetic, reproducible build process. At the highest SLSA security level, organizations should be able to assure others that their software supply chain has not been compromised, said Lewandowski.

    Google

    In the wake of a recent series of high-profile breaches of software supply chains, the level of scrutiny being applied to how software is constructed has increased significantly. In theory, at least, developers have assumed more responsibility for application security as part of an overall shift left that provided them with more programmatic control over IT environments. As a result, cybercriminals are now focused on compromising either the credentials of developers as part of an effort to insert malware into application as it is developed, or they are trying to exploit vulnerabilities that developers have inadvertently created by programmatically misconfiguring infrastructure.

    DevSecOps best practices are, of course, being adopted to teach developers how to better secure their application environments. The issue is that not enough developers are learning how to secure applications fast enough. The volume of attacks against the software supply chain continues to grow at a rate that is now much faster than organizations can thwart simply by educating developers. In some cases, organizations are once again empowering cybersecurity teams to make sure software supply chains are secure regardless of the potential impact on the rate at which applications are being developed.

    Google is trying to promote adoption of SLSA as a framework for securing both open source and proprietary application code, said Lewandowski. There’s no silver bullet for securing software, but a framework that ultimately automates as many of the security processes as possible within the context of a DevOps workflow would go a long way toward hardening the software supply chain, noted Lewandowski.

    SLSA is being put forward as a response to a cybersecurity executive order issued by President Biden that, among other things, tasks the National Institute for Standards and Technology (NIST), an arm of the U.S. Department of Commerce, to consult with federal agencies, the private sector, academia and other stakeholders in identifying standards, tools, best practices and other guidelines to enhance software supply chain security. Given the level of dependencies that exist across those software supply chains, that executive order, to varying degrees, now applies to almost any entity that builds software for an organization that, on some level, interacts with the Federal government.

  • Survey Reveals Slight Decline in Level of SRE Toil

    Survey Reveals Slight Decline in Level of SRE Toil

    The amount of routine toil that site reliability engineers (SREs) perform declined slightly in the last year even though IT environments in general are becoming more complex to manage.

    An annual survey of 300 SREs conducted by Catchpoint, a provider of an IT monitoring platform, in collaboration with VMware and the DevOps Institute suggests that the amount of toil—defined as low-level manual tasks—declined 15% in the last year.

    Only 22% of respondents claim to be scientifically measuring toil, so, to a degree, the survey results are apocryphal. Overall, the survey, published this week, finds SREs are, not surprisingly, spending the bulk of their time on responding to incidents and outages, followed by participating in postmortem analysis and on-call rotations. The primary sources of toil cited in the survey are too much technical debt, lack of alignment of priorities and goals, lack of appreciation of business value, lack of training and support and lack of collaboration.

    In terms of automation adoption, the most common use cases cited are release management, infrastructure management and application management. The tools most commonly employed by SREs are used to monitor infrastructure, networks and application performance. Adoption of artificial intelligence (AI) tools to manage IT operations (AIOps) remains low. The survey also finds respondents are roughly split evenly between centralized (42%) and decentralized (38%) approaches to managing IT. Another 20% said they have adopted a hybrid approach. Lack of visibility across the stack (53%) was the most cited cloud application monitoring challenge.

    The survey also finds only half of respondents continually refine their service level objectives (SLOs).

    Leo Vasiliou, director of product marketing for Catchpoint, said it’s clear that SREs are becoming more proactive in terms of preventing and containing the impact of IT incidents. The challenge they face is lack of visibility and context as those IT environments become more complex. Complexity is increasing, in part, because of the rise of cloud-native computing platforms running microservices-based applications that have lots of dependencies.

    Less clear right now is the percentage of IT environments managed by SREs today. In theory, a single SRE can do the same amount of work as multiple IT administrators by automating processes using various DevOps tools rather than relying on traditional graphical tools. However, SREs are hard to find and retain. It’s also not always apparent to what level of automation needs to be attained to qualify to be an SRE or, for that matter, what certifications may be required. Interest in becoming an SRE is rising, in part, because they typically command higher salaries.

    In the meantime, it’s clear organizations will need to find ways to automate the management of IT to a much greater extent. Most organizations cannot afford to hire a small army of IT professionals to manage IT environments that become more complex with each passing day. Everything from DevOps best practices and next-generation observability tools that promise to provide more context to AI platforms will all be part of the mix. The challenge is finding a way to implement those tools before IT management spins further out of control.

  • Grafana Labs Acquires k6 to Add Open Source Load Testing Tool

    Grafana Labs Acquires k6 to Add Open Source Load Testing Tool

    During its online GrafanaCONline 2021 conference today, Grafana Labs revealed it has acquired k6, a provider of an open source load testing tool.

    Raj Dutt, Grafana Labs CEO, said load testing will complement the observability platform Grafana Labs currently provides based on open source Prometheus software. Most of the output of any load testing processes are typically evaluated using a platform that analyzes metrics, he noted.

    The k6 platform has been gaining traction among developers that require access to a tool that makes it simpler to dynamically scale load testing up and down as required versus having to guess how much infrastructure might be required to test an application workload, said Dutt. That capability not only makes it simpler to integrate testing within a DevOps workflow, Dutt added, but also serves to reduce testing costs.

    In general, Dutt noted testing is shifting further left as developers assume more responsibility for quality assurance. The challenge is finding a way to enable developers to automatically incorporate testing within a continuous integration (CI) process that allows them to easily observe how synthetic tests are executing, added Dutt.

    There’s no doubt developers are running more tests before promoting workloads into a production environment as part of an effort to reduce the number of issues that might be encountered when an application is deployed in a production environment. In many cases, the support calls that arise now go directly to developers who now have a vested interest in reducing the volume of those calls.

    The issue that developers are contending with is as they embrace microservices, the dependencies that exist across multiple applications makes it more challenging to successfully deploy those applications. Grafana Labs has been making a case for a cloud platform that makes it simpler to centrally view data collected from instances of Prometheus distributed across multiple application development environments. Prometheus, now being advanced under the auspices of the Cloud Native Computing Foundation (CNCF) that oversees the development of Kubernetes, is now being deployed more widely by IT teams to observe legacy monolithic applications alongside emerging microservices-based applications.

    It’s not clear the degree to which organizations are also employing dedicated application testers. In many cases, those testers will surface issues that developers overlooked (or simply chose to ignore) in the face of tight application delivery deadlines.

    In the longer term, however, it’s also apparent artificial intelligence (AI) will be playing a larger role in application testing. Someone will still need to review those tests, but many more rote tasks will increasingly be automated.

    One way or another, the total cost of testing is declining, thanks in part to increased reliance on open source testing tools that, in many cases, developers are simply downloading themselves. Those tools are reducing much of the licensing friction and cost restrictions that developers might otherwise encounter.

    In fact, the easier it becomes to test applications, the better overall application quality will become in the months and years ahead. At at time when organizations have never been more dependent on software, that potential improvement to the overall state of application quality can’t arrive soon enough.