Author: Mike Vizard

  • GitLab Acquires UnReview to Further AI Ambitions

    GitLab Acquires UnReview to Further AI Ambitions

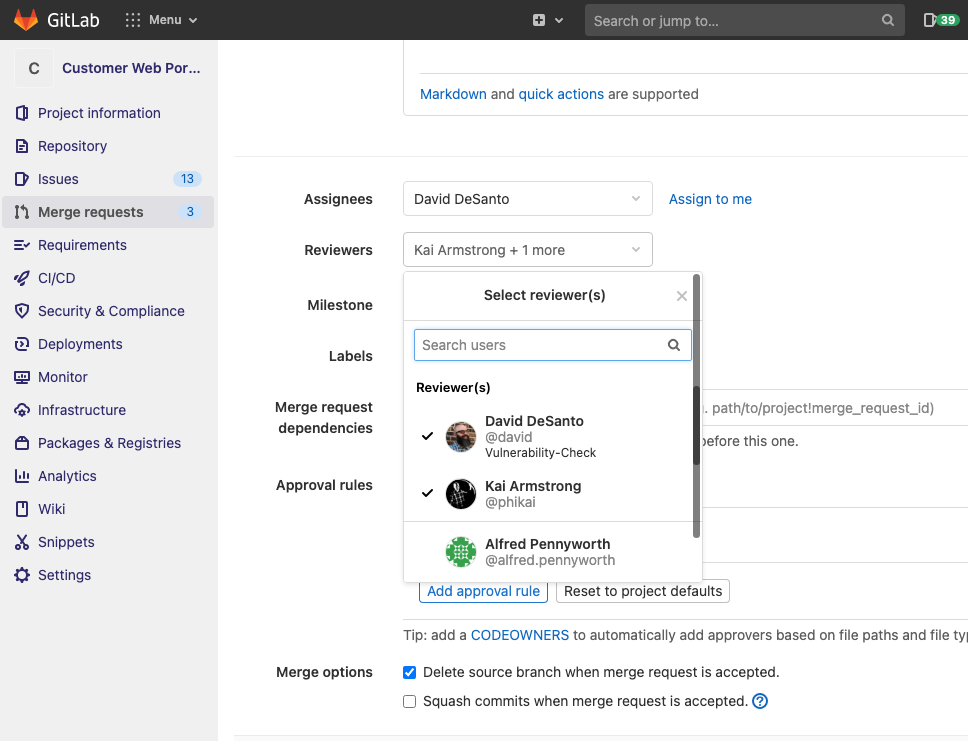
    GitLab announced this week it has acquired UnReview, a provider of a tool that employs machine learning algorithms to identify which expert code reviewers to assign to a project based on both the quality of their previous efforts and current workloads.

    David DeSanto, senior director for product management at GitLab, said the acquisition of UnReview is the latest step in an AI strategy that, in addition to optimizing DevOps processes, will eventually unify machine learning operations (MLOps) and DevOps workflows.

    Accessed via the Dev section of the GitLab platform, UnReview will also be employed to manage the overall code review process.
    GitLab

    DeSanto said GitLab is committed to employing AI technologies to automate workflows and compressing cycle times across all stages of the DevSecOps life cycle. The goal is to not eliminate the need for DevOps teams, but rather eliminate low-level tasks that conspire to hamper productivity while at the same time improving application security, noted DeSanto.

    Providers of DevOps platforms are now locked into an AI arms race on two separate fronts. Each of them clearly sees the opportunity to leverage machine learning algorithms and other forms of AI to automate a wide range of processes. At the same time, it’s apparent providers of MLOps platforms are borrowing heavily from DevOps best practices to manage the development of AI models. However, from the perspective of a DevOps team, an AI model is just another type of software artifact. Rather than deploying two distinct platforms, the goal should be to bring the data scientists that build AI models into the larger DevOps community, said DeSanto.

    The current challenge, of course, is the pace at which DevOps and data science teams work. It may take six months or more for a data science team to construct and validate an AI model that needs to be embedded within an application. Aligning the timetable for an AI model with the application development life cycle is difficult to accomplish if neither team has any meaningful visibility into each other’s workflows. As the rate at which AI models can be developed steadily improves, that alignment issue will only become all the more pressing.

    Going forward, it’s hard to envision any application that won’t have some sort of AI model embedded within it. The issue is that, just like any other software artifact, an AI model needs to be updated. As new data sources become available, an AI model is likely to drift beyond the parameters intended. A rapid change in business conditions may also require the replacement of an entire AI model. The same processes that DevOps teams apply to update any software artifact can also be applied to an AI model.

    It’s unclear how long it will take before some type of convergence of DevOps and MLOps inevitably occurs, as organizations look for more efficient ways to manage what will become thousands of AI models. The one certain thing is the longer it takes to make the effort, the more difficult it will become to overcome the organizational inertia that has been allowed to set in.

  • Cribl Automates Observability Efforts

    Cribl Automates Observability Efforts

    Cribl today announced it has updated the Cribl LogStream observability tool in addition to generally making available a software-as-a-service (SaaS) offering dubbed LogStream Cloud.

    Nick Heudecker, senior director for market strategy and competitive intelligence at Cribl, said Cribl LogStream provides the means to aggregate log data collected from multiple platforms and applications in a format any observability or monitoring tool can access.

    The challenge with observability platforms today is they leave it up to IT organization to copy and paste data into the platform. LogStream automates that process via a log router that collects and optimizes data streams from existing installed agent software and then shapes and routes that data on to analytics platform.

    Version 3.0 adds LogStream Packs, a framework for accelerating deployments of the log router. Alternatively, DevOps teams can employ LogStream Cloud to build and share LogStream configuration models.

    Heudecker said the goal is to reduce the cost of achieving observability by reducing the time and effort required to set up and manage data pipelines. No customization effort on the part of a DevOps team is required to collect and send data from hundreds of sources to any number of destinations, noted Heudecker.

    While observability is a core DevOps tenet, achieving it has been a major challenge. In addition to deploying and managing agent software to instrument IT environments, there’s a significant amount of time and data engineering effort needed to set up the pipelines employed to transfer data to a platform where it can be analyzed. Cribl is making a case for automating those data engineering tasks using a tier of software that abstracts data into a format that can be consumed by multiple observability and monitoring platforms.

    It’s not clear yet to what degree IT organizations perceive observability to be an evolution of monitoring, or simply the next logical evolution of monitoring. One way or another, IT teams need a lot more context than they have historically been able to attain using legacy monitoring tools. Each platform employed within an enterprise typically comes with its own monitoring tools that are used by the IT teams tasked with managing it. Whenever there is an issue, however, IT teams will spend hours correlating data from multiple tools to ascertain the root cause of a problem.

    Observability platforms promise to reduce that time and effort by applying analytics to data collected from multiple platforms. The challenge now is finding a way to efficiently collect all that data.

    It may be a while before IT organizations start to abandon all the monitoring tools they have in place in favor of observability platforms. However, as IT environments continue to become more complex (thanks, in part, to the rise of cloud-native computing platform based on microservices) the need for those platforms becomes more acute. The issue is enabling DevOps teams to achieve that goal without having to wait for an overworked data engineer to find the time to build a pipeline.

  • Atlassian Delivers on Forge App Dev Platform Promise

    Atlassian Delivers on Forge App Dev Platform Promise

    Atlassian this week made available a Forge platform for building applications that complements its existing portfolio.

    Mike Tria, head of platform engineering for Atlassian, said Forge is intended to provide an application development environment to both IT organizations and third-party partners. It provides developers with access to an integrated Atlassian DevOps toolchain to accelerate testing, deployment, debugging and to capture log data, added Tria. Forge also presents developers with a command line interface through which they can be onboarded to the Atlassian cloud where Forge runs to access documentation and application samples. It uses OAuth 2.0 to ensure applications deployed on the Atlassian cloud only access data they have permission to access.

    The overall goal is to provide developers with a more modern application development environment as an alternative to the application development platform the company previously made available.

    Once an application is built, developers can then publish their applications on the Atlassian Marketplace as free or commercial offerings. There are already more than 3,500 Forge apps that were created during a beta process that began late last year. Forge will soon be extended to the rest of the Atlassian portfolio, noted Tria.

    Forge is intended to complement an Open DevOps initiative launched earlier this month that tightens integration between the Jira project tracking and management tools provided by Atlassian and a wide range of other tools commonly employed by DevOps teams. The goal is to not only make it easier to correlate issues that are listed in Jira with artifacts found in various software platforms, but also to collect data from DevOps tools to automatically update Jira.

    That data will then be employed to inform key performance indicators (KPIs), based on graphs that Atlassian provides within Jira, to keep track of value streams. Rather than having to acquire a separate value stream management (VSM) platform to track software development progress, the insights needed to understand the impact of, for example, a delay to one project becomes a dividend of using Jira.

    Like most providers of software-as-a-service (SaaS) applications, Atlassian has been making available a platform for building applications on top of the same platform it employs to build its own applications. Atlassian claims there are more than 1,200 partners building applications in addition to internal IT that teams that have built custom extensions to its applications. Atlassian has already shown a proclivity for acquiring independent software vendors (ISVs) that build applications on its platform. As part of the overall Forge initiative, Tria said Atlassian will be working more closely to identify the white space that won’t be addressed by the Atlassian product roadmap at some future date.

    In the meantime, independent software vendors and internal IT teams will need to determine to what degree they will prefer to stand up their own application development environment versus opting to be dependent on Atlassian. In theory at least, applications built on Forge should be more tightly integrated with the rest of the Atlassian portfolio. The only potential downside is, of course, any potential conflict that might emerge with a provider of an application development platform that also happens to sell application software.

  • Digital.ai Deepens Value Stream Management Integration

    Digital.ai Deepens Value Stream Management Integration

    Digital.ai announced today it has expanded usage of machine learning algorithms within its namesake value stream management (VSM) platform to include modules to optimize flow and improve application quality in addition to enhancing its risk prediction and process optimization modules.

    In addition, Digital.ai has expanded the number of pre-built integrations it now provides for hundreds of DevOps tools and platforms.

    Derek Holt, general manager of agile and DevOps for Digital.ai, said the goal is to expand the bi-directional flow of data between the core Digital.ai platform and modules and tools provided by the company and its third-party DevOps partners.

    Digital.ai was formed from the merger of XebiaLabs and CollabNet VersionOne. The combined company has rolled up Numerify, a provider of analytics tools infused with artificial intelligence (AI), Experitest, a set of testing tools and Arxan, a provider of an application security platform. With the latest release, these capabilities have been integrated into the core Digital.ai platform in a way that goes well beyond merely providing access via a common user interface, said Holt.

    The goal is to provide organizations with a VSM platform through which better decisions can be made to optimize software development and delivery by first collecting data from all the DevOps tools employed and then using machine learning algorithms to surface optimization recommendations, noted Holt. As application development environments become more complex to manage, it’s already apparent that most IT teams will require AI capabilities embedded in a VSM platform to manage interdependent projects, noted Holt.

    Armed with those recommendations, it becomes simpler to reallocate resources in the event a critical project is going to be completed later than planned or shift resources to make sure that project is completed on time. A VSM platform also enables IT organizations to assess the impact those decisions will have on the rest of the business at a time when organizations have never been more financially dependent on the timely delivery of software. The late delivery of a single application module can wind up having a profound impact on revenue projections for organizations that increasingly rely on digital processes to engage customers.

    A recent survey conducted by Digital.ai found that many digital transformation initiatives are struggling, to some degree. Nearly half of respondents (49%) said they are not seeing the results they expected from their digital transformation efforts, and 54% admitted they were worried about their ability to compete. Over 90% need to see a better return on their digital transformation investments.

    Digital.ai claims it currently has more than 1,200 customers, including Allianz, Commerzbank, eBay, Janus Henderson and Levi’s that are using elements of the Digital.ai platform to better manage software development projects. Many of the users of those tools now include business executives and other application stakeholders that are employing a VSM platform to track the progress of application development projects. Digital.ai Analytics Lenses that are domain-specific make it simpler for different classes of end users to access pre-built dashboards and metrics, noted Holt.

    The market research firm Gartner has predicted that 70% of organizations will employ a value stream management platform by 2023 to improve flows across their DevOps pipelines. However, as DevOps platforms and project management applications continue to evolve, many are also adding many of the analytics capabilities found in a VSM platform. Each IT organization will need to decide which approach makes the most sense for them, but Digital.ai is clearly betting that as application development becomes more challenging, the need for an integrated VSM platform will become much more apparent.

  • JFrog Adds Private Distribution Network for App Binaries

    JFrog Adds Private Distribution Network for App Binaries

    At its online swampUP conference today, JFrog launched a Private Distribution Network (PDN) that makes it simpler and faster to distribute application binaries across an extended enterprise.

    Yoav Landman, JFrog CTO, said the PDN provides the equivalent of a content delivery network (CDN) designed specifically for distributing application binaries using a peer-to-peer network managed by JFrog. Each binary distributed is an immutable signed release that provides visibility and traceability to validate the source destination as well as the integrity of the binary, added Landman. That approach essentially applies concepts from a blockchain network to the distribution of application binaries, noted Landman.

    The PDN is based on patent-pending network optimization technology that employs caching, distribution nodes and lightweight accelerators that enable IT teams to distribute binaries through inbound-only firewalls or to environments that have limited connectivity, said Landman.

    Finally, the PDN also comes with tools to analyze binaries for open source security vulnerabilities and compliance with license policies in addition to role-based access controls (RBAC).

    Landman said the goal is to provide a way to distribute binaries via a single click all the way to edge computing platforms in a way that is tightly integrated with the continuous integration/continuous delivery (CI/CD) pipelines and software development life cycle (SDLC) processes a DevOps team already employs.

    Currently available via a private beta, PDN is scheduled to become available in the third quarter 2021 with pricing based on a per-use model that requires no upfront costs.

    JFrog

    For years now, JFrog has been making a case for applying DevOps best practices to the deployment of binaries rather than just managing source code. As enterprise IT environments become more distributed, the need to manage the deployment of binaries at scale becomes more acute. IT teams are not going to be able to dispatch software engineers to manually install binaries on every edge computing platform employed. The goal is to provide IT teams with complete transparency into software distribution in a way that makes it simple to address compliance requirements, said Landman.

    Most organizations already find deploying software to be a major challenge. CI processes are generally well understood as part of any application development process. CD has proven to be a more elusive goal, because each target platform on which software is destined to run tends to be unique, which makes automating the delivery process challenging. That issue is only going to be more difficult to address as organizations attempt to install software across hundreds, or even thousands, of edge computing platforms that might be based on a wide range of types of platforms. A PDN alleviates many of these issues by providing IT teams with a network to centrally manage the process, noted Landman.

    At this point it’s now only a matter of time before most organizations confront this next major DevOps challenge. As organizations look to process and analyze data at the edge to drive any number of digital processes in near real-time, the amount of software deployed outside of a cloud or traditional data center is about to explode. The challenge now, of course, is finding the most efficient way to secure delivery of all that code.

  • Oracle and Allies Launch ARM-Based Cloud Service

    Oracle and Allies Launch ARM-Based Cloud Service

    Oracle announced today it will make available for the first time ARM-based processors on the Oracle Cloud Infrastructure (OCI) that will also be supported as targets for deploying applications using GitHub, GitLab or Jenkins platforms. The latest Oracle service is based on processors from Ampere Computing.

    The company also revealed today it has joined the Continuous Delivery Foundation (CDF), an arm of the Linux Foundation that oversees the development of open source DevOps platforms and tools such as Jenkins and Spinnaker.

    Matt Leonard, vice president of compute for OCI, said the OCI Ampere A1 Compute provides an alternative to existing support for the x86-based processors that Oracle provides. That service will be offered at a cost of one cent per core hour with virtual machine sizes ranging from one to 80 OCPUs configured with one to 64 GB of memory per core or as a bare-metal service with 160 core and 1 TB of memory. Pricing per GB of RAM per hour is $0.0015. At that price point, Leonard said Oracle is now offering the lowest price per core of any cloud service provider.

    The growing availability of ARM-based processors is starting to have an impact on cloud economics at a time when organizations are significantly increasing the number of applications being built and deployed on public clouds. Many of those organizations, to reduce overall costs, are now actively evaluating ARM-based services, noted Leonard.

    To help jumpstart application development on the platform, Oracle is providing organizations with three classes of OCI Ampere A1 Compute services. An Oracle Cloud Free Tier gives developers $300 in free credits for 30 days. The Always Free ARM option gives developers four A1 cores and 24 GB memory, while an ARM Accelerator option provides open source developers, independent software vendors (ISV) partners, customers and universities with ARM-based development projects that need additional resources beyond what the Oracle Cloud Free Tier provides with credits for a 12-month period.

    Oracle Linux, Java, MySQL, GraalVM and the Oracle Container Engine for Kubernetes (OKE) service are also all available on the OCI Ampere A1 Compute along with integrations with DevOps platforms from GitHub, GitLab and/or Jenkins. Other vendors providing support for OCI Ampere A1 Compute include SUSE, Datadog, OnSpecta, NGINX and Genymobile.

    Oracle has also made available an Oracle Linux Cloud Developer image that enables DevOps teams to install, configure and launch a development environment via an OCI console that includes OCI client tools, utilities and common programming languages such as Java, GraalVM, Python, PHP, Node.js, Go and C/C++.

    Finally, each Ampere core is single threaded by design with its own 64 KB L1 I-cache, 64 KB L1 D-cache and a huge one MB L2 D-cache to eliminate any ‘noisy neighbor’ issues that IT organizations might otherwise encounter.

    Oracle is clearly betting that ARM-based processors will present the company with an opportunity to gain share at the expense of larger infrastructure-as-a-service (IaaS) rivals such as Amazon Web Services (AWS) and Microsoft Azure. It’s not clear to what degree IT teams might employ a different cloud service just to access ARM-based processors. However, in a world where IT teams now routinely employ multiple clouds, as far as Oracle is concerned, the playing field has never been more level.

  • Unqork Extends Automated No-Code SDLC Platform

    Unqork Extends Automated No-Code SDLC Platform

    Unqork today announced it has extended a no-code platform for managing the software development life cycle (SDLC) to include the ability to automatically document changes to application programming interfaces (APIs) and data models in addition to adding a point-in-time rollback capability.

    Ken Gavranovic, head of strategy and engineering for Unqork, said Unqork 2021.5 also adds a range of dashboards for monitoring application dependencies, service logs, revisions, logs and metrics.

    Finally, Unqork is adding tools to analyze, test and debug configurations along with enabling workflows to subscribe to events and adding a search capability for release candidates.

    Unqork is designed to present IT teams with a set of visual tools through which they can manage SDLC processes without having to build and maintain a platform made up of disparate offerings that they need to then integrate, said Gavranovic. The goal is to reduce the overall size of the team required to maintain an application development environment to enable organizations to allocate more time and resources to building applications, he added.

    The auto documentation for APIs is being added at a time when IT organizations are starting to employ a larger number of APIs as they transition toward building and deploying microservices-based applications. In addition to making it easier to reuse APIs, Unqork also now makes sure documentation for those APIs is always current, said Gavranovic.

    At the same time, Unqork is now providing a means to automatically document changes to data models based on a data store that is integrated in the platform, noted Gavranovic. That capability enables organizations to implicitly add governance capabilities to workflows with a minimal amount of friction.

    As organizations look to accelerate the rate at which applications are being developed to enable multiple digital business transformation initiatives, Gavranovic said more of them are starting to realize their existing processes are too complex and cumbersome to achieve that goal. Unqork is based on a data store that is shared by all the modules that make up the platform, which, in addition to enabling reusability, makes Unqork easier to deploy and manage, added Gavranovic.

    In addition, Gavranovic also noted that, over time, complex processes only increase the overall burnout rate of the development team. It’s hard enough to hire and retain developers today without requiring them to navigate a complex application development environment, he added. Eventually, the best talent will migrate to organizations that make it as easy for them to write code as possible, said Gavranovic.

    It’s not clear to what degree IT organizations will be revisiting the way they build software in the months ahead but as more of them realize how dependent the business now is on the timely delivery of software it’s only a matter of time before pressure to automate as much of the software development process as possible starts to mount. The cost of replacing an application development environment is, of course, not insubstantial. However, continuing to do the same thing with the expectation of producing a different result is, by definition, insanity.

  • Netlify Acquires FeaturePeek to Streamline App Feedback Process

    Netlify Acquires FeaturePeek to Streamline App Feedback Process

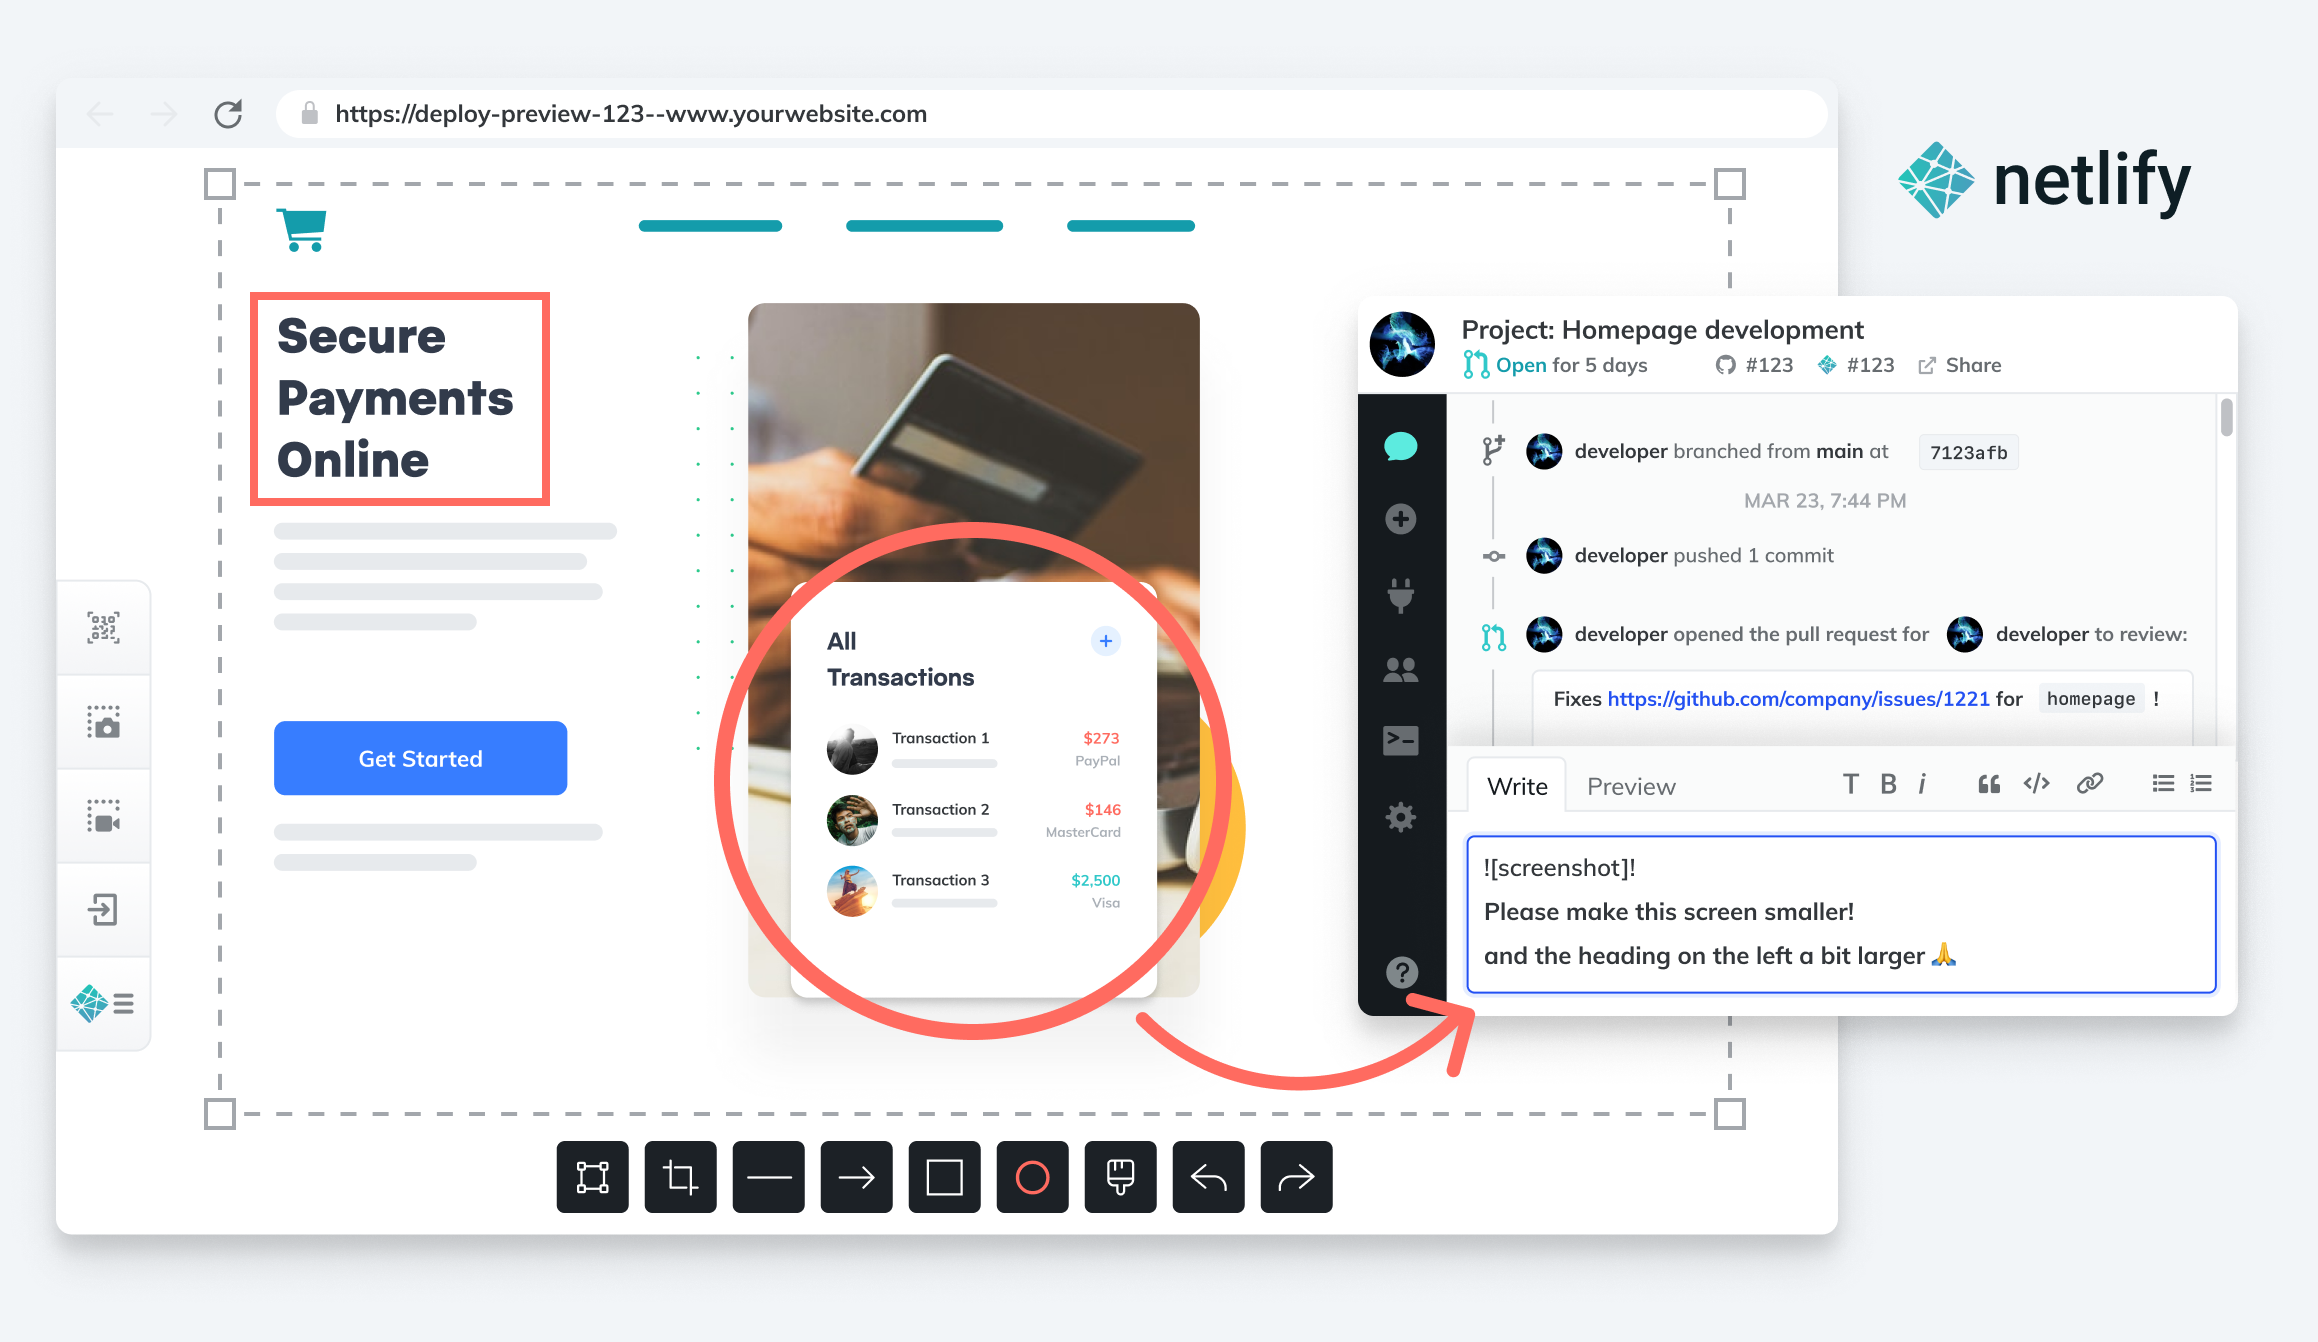
    Netlify announced today it has acquired FeaturePeek as part of an effort to make it simpler for DevOps teams to create a portal through which application stakeholders can both inspect a web application developed using JavaScript and leave comments for developers.

    Matt Biilmann, CEO of Netlify, said Netlify will embed that collaboration capability in the next iteration of its Netlify Deploy Previews. That tool makes it currently possible for a front end pull request from a Git repository to automatically generate a live preview of the site with a unique shareable URL.

    The current version simply shares URLs with application stakeholders, versus enabling DevOps teams to create a portal through which the review process can be centrally managed to make feedback more consistent, said Biilmann. Each piece of feedback from an application owner or stakeholder made via the portal will become a comment on the Git pull request, or can be shared via any collaboration tool a development team employs alongside a Netlify workflow, noted Biilmann.

    In the meantime, Netlify is also making available a free user role license for reviewers that want to make use of Netlify Deploy Previews to view recent updates to applications.

    Netlify has been driving adoption of a serverless computing framework based on a JAMstack architecture for building JavaScript applications faster. An application based on a JAMstack architecture isolates the front end and back end end of an application to make it possible to prebuild front ends that are highly optimized around static pages to make web applications faster. The name JAMstack is a mashup of JavaScript, application programming interface (API) and markup language.

    The need for more collaboration between developers and stakeholders has become more pronounced, in part, because organizations have significantly accelerated the rate at which they are investing in digital business transformation initiatives, noted Biilmann. With organization more dependent on software than ever, it’s critical for them to streamline the feedback cycle as the number of application stakeholders within organizations steadily increases, added Biilmann.

    As the relationship between DevOps teams and the rest of organization continues to evolve, the amount of feedback any team is likely to receive will continue to increase. Everyone from sales teams to the board of directors now realizes how dependent the business is on software. DevOps teams will need to way to organize and prioritize that feedback. They should also expect application owners and stakeholders to follow the progress of software development projects more closely than ever because, in many cases, financial projections are now based on assumptions being made about software delivery timetables.

    Many DevOps teams have been making the case to have a more central role in business planning for years. Now that many of them are getting a seat at the proverbial business planning table, however, they may soon realize they don’t really have the processes in place to absorb the overabundance of enthusiasm and anxiety that application stakeholders are likely to generate in equal measure.

  • ZenHub Brings More Science to Sprint Planning

    ZenHub Brings More Science to Sprint Planning

    ZenHub today revealed it has added a Planning Poker capability to its platform for managing software development projects that is designed to make it possible to prioritize sprints based on feedback collected from members of the application development team.

    That capability extends a sprint planning capability the company added this year to a project management application designed specifically for software development teams that employ the GitHub software repository. That sprint planning tool also automates routine tasks, such as automatically carrying over unfinished work to the next sprint.

    Aaron Upright, head of strategic accounts for ZenHub, said collectively, those capabilities will make it possible for development teams to prioritize their efforts in a way that is less biased using points that weight the opinions of team members based on how accurately they have made previous forecasts. For example, Planning Poker will assign a different weight to a developer that is consistently either overly optimistic or pessimistic about the length of time required to complete previous projects.

    Planning Poker is built right into GitHub, which Upright noted allows developers to make estimates without having to exit an environment where they already spend a good portion of their day.

    Thanks mainly to both an increase in and acceleration of the digital business transformation initiatives organizations have launched, DevOps teams are under increased time constraints.

    Many organizations’ entire business strategies now revolve around the rate at which software development projects can be completed. Many elements of those projects can’t go forward until a specific component upon which it depends is completed. Investors are holding business leaders more accountable for software delivery timetables that have direct implications on revenue generation.

    Not surprisingly, the type of end users that are now accessing project management applications to keep tabs on development progress has increased. Everyone from the sales team to the board of directors now wants more visibility into the rate at which software development projects are being completed. The challenge DevOps teams face is software development is an inexact science. Developers, based on individual personalities, exacting standards and willingness to work extra hours, are going to have widely divergent opinions on how long it may take to complete any given sprint.

    Nevertheless, Planning Poker presents organizations with an opportunity to rely on a more scientific approach than traditional guesswork, said Upright. The simple fact of the matter is that all estimates are wrong. The goal is to narrow the margin of error, he added.

    Regardless of how application development projects are managed, the relationship between DevOps teams and the rest of the organization has fundamentally changed. The entirety of some organizations is wholly dependent on the speed at which high-quality software is developed. In many cases, expectations are not realistically aligned with available development resources. A project management application that is widely employed across an organization should make that apparent to all interested stakeholders, which, in theory, at least, should result in either the hiring of additional developers or reassessment of the business strategy before the existing development team simply decides to abandon ship altogether.

  • Nobl9 Makes SLO Specification Open Source

    Nobl9 Makes SLO Specification Open Source

    During an online SLOconf event today, Nobl9 revealed that the platform it created to enable IT teams to achieve service level objectives (SLOs) is now available under an open source Apache license.

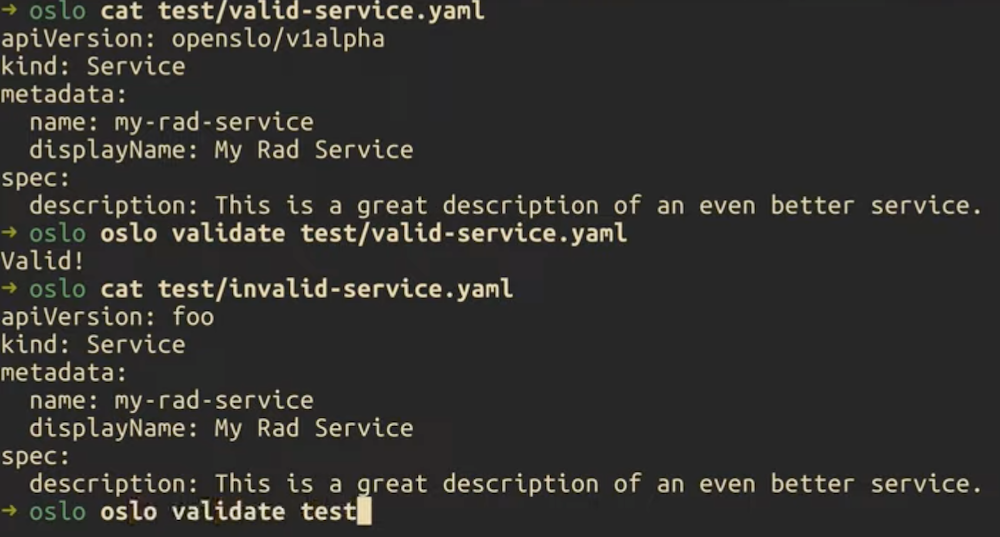
    Brian Singer, chief product officer for Nobl9, said the goal is to make a YAML specification format for defining SLOs that includes a parser and basic validation and testing capabilities more accessible via an OpenSLO project. Achieving that goal is critical at a time when organizations are deploying microservices-based applications that have dependencies that often adversely impact performance and availability.

    While the concept of an SLO and/or a service level agreement (SLA) has been around for a long time, IT teams that have embraced DevOps best practices by hiring site reliability engineers (SREs) are programmatically attempting to assure that SLOs are attained and, just as importantly, maintained, said Singer. Most SLAs have, historically, not been well-enforced. OpenSLO makes it possible to achieve that goal by embedding SLO objectives within a YAML file that become part of a Git-based workflow, he noted.

    SLOs

    Niall Richard Murphy, author of the book, Site Reliability Engineering, has signed on to be a core OpenSLO contributor working alongside committers from GitLab, Dynatrace and Nobl9. The ultimate goal is to make it simpler to share and migrate portable SLO specifications across multiple application development projects by constructing them using an object model, said Singer.

    Nobl9, meanwhile, will continue to operate a software-as-a-service (SaaS) platform for managing SLOs based on OpenSLO. Singer noted there will be an increased need for OpenSLO as it becomes more widely employed. The Nobl9 SLO platform is compatible with monitoring platforms such as Datadog, New Relic and Prometheus, and uses data collected from monitoring and observability platforms to calculate acceptable rates of error per service. It can be configured to trigger alerts and even workflows in anticipation of outages.

    Accessible via a CLI/GUI/API, the platform also enables DevOps teams to create business rules and define “facets” of users based on the application experiences required. DevOps teams can identify users who are being serviced poorly in addition to tracking groups of users. They also can associate contractual obligations to an SLO for a critical business period.

    The platform also makes it easier to determine how to make systems more reliable or lower reliability goals to reduce costs when possible. IT organizations will also spend much less time determining the root cause of any issue using a combination of real-time and historical data that is more accessible. Today, it’s not uncommon for IT teams to spend weeks looking for the source of an application degradation issue, only to discover the problem can be fixed in a matter of minutes.

    It’s still early days as far as adoption of SLO-as-code is concerned, but the days when SLAs or SLOs were, at best, aspirational statements of intent are coming to an end. The expectation is SLOs will soon be maintained via YAML files embedded within application code and distributed across a rapidly expanding enterprise with more interdependencies than any IT team can manually track.