Tag: testing

  • Tips for Creating Unit Tests for Mobile Apps

    Tips for Creating Unit Tests for Mobile Apps

    Mobile app testing ensures your application is working perfectly without any freezes, bugs or crashes. There are unit, auto, system and acceptance tests, and in this article we will talk about unit testing for mobile apps.

    First, let’s discuss what unit tests are in general. Unit testing checks whether certain parts of the code work correctly. In other words, it helps us produce more robust and maintainable code. Each one small test is dedicated to a small feature. All of them are connected, however, so you get a kind of chain. If any part of this chain fail, the whole chain will fail as well.

    As a part of mobile application testing unit tests may be written at any phase of development or even before development (test-driven development, or TDD, is one of the iOS unit testing best practices). With this kind of development, you let your tests drive the development process. They indicate what you do, what you should do next and what the result should be. Testing controls the design.

    Thus, unit testing is the first step to perfectly working code. But it also is the primary means for your software quality assurance. In this article we’ll explain how to do mobile apps unit testing on an iOS example and give you a small iOS unit testing tutorial.

    Do I Need to Conduct Unit Testing?

    Does everyone need to do unit testing? The short answer is no. The long answer is that it  is a very good tool, though it isn’t necessary in all situations.

    You don’t need unit testing if:

    1. your app is very small and simple. If your app is small, it will be faster to check everything manually because there’s not that much logic to be checked.
    2. you don’t plan your app to work in the long term and you need it only for a demonstration.
    3. you’re a super-human who writes perfect code without any mistakes.

    If you don’t fall into any of these categories, then unit testing is what you need. At first, this kind of testing may seem too time-consuming. Lack of time is mentioned as one of the most serious problems related to testing, but actually performing unit testing can save a lot of time and improve development speed. In addition, it can serve as a kind of documentation for your library. We at Mobindustry spend up to 30 percent of our development time on testing.

    Unit tests have two main purposes:

    1. Reduce the number of bugs by making sure that our class/module/component is working as expected with all possible inputs.
    2. Reduce the number of regressions by making sure that our new functionality, bug fixes or refactoring hasn’t broken any existing functionality.

    How Do Unit Tests Work?

    How to create iOS unit testing? Xcode has built-in support for unit tests and works as an iOS unit test framework. You can use Xcode by pressing cmd+U or via the menu by selecting Product -> Test. xCode will run all active tests and generate a report with results (passed/failed). All failed assertions are indicated. Code coverage data is also generated in this framework, which allows you to get to any class and check which lines of code were called and how many times they were called.

    Types of Unit Tests

    Unit test for iOS can either check the UI or the logic of the application. Logic ones have a few subtypes:

    • Regular ones are used to check straightforward functionality.

    func testExample() {

    let account = Account()

    account.amount = 100.0


    account.withdraw(20.0)


    XCTAssert(account.amount == 80.0, "Account should have current amount of 80.0 but has

    (account.amount)")

    }

    This is used to simply check if the withdraw() method is working correctly.

    • Asynchronous tests use XCTestExpectation to check for expected outcomes.

    func testExample() {

    let url = URL(string: "http://www.google.com")

    let expectation = XCTestExpectation(description: "expectation_description")


    let task = URLSession.shared.dataTask(with: url) { (data, response, error) in

    if let error = error {

    XCTFail("Error: (error.localizedDescription)")

    return

    } else if let statusCode = (response as? HTTPURLResponse)?.statusCode {

    if statusCode == 200 {

    expectation.fulfill()

    } else {


    XCTFail("Request failed with status code (statusCode)")

    expectation.fulfill()

    }

    }

    }

    task.resume()


    waitForExpectations(timeout: 10) { (error) in

    XCTFail("Expectation (expectation.description) has failed")

    }

    }


    This one will check if Google’s website is available (i.e. if it returns status code 200).

    XCTestExpactation is used to wait for the async task to finish. An Expectation will either finish successfully by calling the fulfill() method or will fail if the timeout time has passed but fulfill() hasn’t been called.

    • Measure ones check heavy logic:


    func testExample() {

    self.measure {

    let lotOfObjects = []

    for obj in lotOfObjects {

    obj.makeCalculations()

    }

    }

    }


    You can create this test to measure how much time and how many resources are spent on particular calculations inside the measure() block.

    Tips on Unit Testing for Mobile Apps

    • Remember the structure

    The common AAA approach to structuring is the most common and convenient way to write tests. AAA stands for:

    1. Arrange – the part that allocates all necessary objects and sets up initial parameters
    2. Act – the part that executes the logic
    3. Assert – the part that checks if the obtained results match the expected results

    Сode written this way is easy to read and use, which means it’s easier to maintain.

    • Cover only necessary things with tests

    Some people think it’s necessary to cover every single part of your code with a unit test. This approach is actually time-consuming, complex and completely useless.

    There are four types of code you may have in your project. Let’s look at them starting with the most extreme options:

    1. Simple code without any dependencies: Probably everything is already clear with this kind of code and there’s no point in assessing it.
    2. Complex code with lots of dependencies: If you have this kind of code, it’s a good idea to refactor. There’s no need to cover this code because we’ll rewrite it, which means new classes will appear and method signatures will change. Why write something that won’t be used? Of course, such code also needs quality assessment, only on a higher level.
    3. Complex code without dependencies: This code contains algorithms or business logic. This is the perfect kind of code for testing because these are very important parts of the system.
    4. Moderately complex code with dependencies: Such code links different components together. Tests are very important here; they tell how exactly components must interact.

    Usually, they cover the following areas of code:

    • Common functionality, core models, classes and their interaction
    • Main UI workflows
    • Crucial logic
    • Bug fixes

    Unit tests may be applied not only for these areas. They can actually be used for testing almost any functionality.

    Don’t cover trivial functions and system functions.

    • Test only one thing at a time

    The idea is to divide your application into different independent modules that are able to work by themselves without interacting with other parts of the application. This allows you to work on each module separately and simplify the code. If you check several things at the same time, sooner or later your code will become overloaded and too complex. It will become difficult to support it and use.

    • Name your tests logically

    It’s very important to name your tests properly and assign them to the correct parts of your project. Many projects have tests that no one is running because of inconvenient placement and naming. Here are some tips for logical structure:

    1. Choose a logical location in your version control system: They have to be part of your version control. Depending on your needs they can be organized differently, but here’s a common recommendation—if your app is monolithic, put all of them in a Tests folder; if it has many components, store relevant tests in each component’s folder.
    1. Choose a convention for naming: One of the best ways to do this is to add a test project to each project you build.
    1. Use the same convention for naming test classes that you use for naming project classes: If you have a class ProblemResolver, it’s a good idea to add a class called ProblemResolverTests. Each class should work only on one thing; otherwise, your tests will be very hard to manage.
    • Work with mocking objects

    You can use different fake objects to make the testing process easier. There’s no need to allocate and manage a huge class or component just to use a single method from it. Such fake objects can be divided into two groups:

    • Stubs
    • Mocks

    Stubs are fake methods for returning a predetermined response. The main use for stubs is when interacting with an API. The idea is not to wait for the actual connection to finish but to return predefined data or a predefined error instantly.

    Let’s assume we have an app where you can add a friend connection. There’s a FriendListViewController that displays a list of all your friends. This friend list can be downloaded from the backend, so there’s an ApiManager class with a method like this:

    ApiManager.shared.getListOfFriends(withCompletion: { (friends) in

    let friendsListVC = FriendListViewController.init(friends: friends)


    //Present friendsListVC

    }) { (error) in

    //Display error


    }

    This method has a completion handler, and we need to wait till it finishes.

    But we actually don’t need to wait because we don’t need any APIs or even an internet connection. We need to make sure FriendListViewController is working correctly, and all we need for that is some list of friends; it doesn’t matter where they come from. So we’ll introduce an ApiManagerStubs class that will duplicate methods from the actual ApiManager but will not perform any actual API requests.

    For this particular test, we’ll write a method for getting a list of friends:

    func getListOfFriends() -> [Friend] {

    let friend1 = Friend.init(name: "Bob", surname: "Barker", age:34);

    let friend2 = Friend.init(name: "John", surname: "Doe", age:30);


    return [friend1, friend2];

    }

    After that we can easily allocate and test FriendListViewController.

    func testExample() {

    let friends = ApiManagerStubs.shared..getListOfFriends()


    let friendsListVC = FriendListViewController.init(friends: friends)


    //Testing friendsListVC.tableView

    }

    Mocks are fake objects that partially duplicate real objects, allowing you to check if a method was called or a property was set after certain events.

    In the example above, when a friend is deleted we need to clear the chat history for this friend. We have some class like ChatManager for this functionality. But again, for this, we don’t need to actually delete any data or call any APIs; we just need to check if the corresponding callbacks are triggered. So we’ll introduce the mock object ChatManagerMock, which behaves like ChatManager, only instead of deleting data it just remembers which callbacks were triggered.

    class ChatsManagerMock {

    var deleteFriendWasCalled = false


    func clearChatHistoryForFriend(_ friend: Friend) {

    deleteFriendWasCalled = true

    }

    }

    Now we can implement our test as follows:

    func testExample() {

    let friends = ApiManagerStubs.shared.getListOfFriends()


    let friendsListVC = FriendListViewController.init(friends: friends)


    let mock = ChatsManagerMock()

    friendsListVC.chatsManager = mock


    //Trigger Delete action for first friend in the list

    friendsListVC.deleteFriendButtonAction(nil, index: 0)


    XCTAssert(mock.deleteFriendWasCalled, "deleteFriendWasCalled should have been called")

    }

    Conclusion

    Unit tests are a very powerful tool to help developers avoid bugs and spot them quickly when they do appear. They help you maintain your code, but at the same time they need maintenance as well. The big problem of many projects is tests that no one uses, and to avoid it you need to stick to some rules. Your tests must:

    • be reliable;
    • not depend on the environment they’re run in;
    • be easy to maintain;
    • be easy to read and understand (even a beginner QA has to be able to understand what’s going on);
    • have a standard naming convention; and
    • be launched regularly and be automated.

    Following these basic rules will help you get a working system. Each test will check only one thing. Your tests will be specifications for class method; it will tell all about what input they expect and what other system components expect as the output. There are very few systems like this. Such systems have an actual specification, and there’s usually not very much text in it—only basic features, server schemes and a “getting started” guideline. The life of such projects no longer depends on people; developers may come and go while the system is reliably tested and tells all about itself with the help of its own tests.

    About the Author / Svetlana Cherednichenko

    Svetlana Cherednichenko is a content writer. Currently she is a part of Mobindustry marketing team. She is an active member of the debate movement and she is a winner of two regional tournaments. Now she is in the process of improving her skills in graphic design and learning new frameworks. She graduated from the Dnipropetrovsk National University. Svetlana likes to travel, read about tech news and play video games. Connect with her on LinkedIn.
  • Testing’s Role in Delivering Digital Transformation

    Testing’s Role in Delivering Digital Transformation

    “We have a quality philosophy now…but it took the rise of the middle child to make it happen.”

    • Ann Lewis, ExxonMobil

    Ann Lewis’ metaphor of testers being the “middle child” between software development and IT operations was present throughout Accelerate 2017, Tricentis’ annual user conference. Nearly every head in the room nodded as Lewis described how testers, like middle children, tend to get less attention than their professional or familial siblings, but she insisted that there’s never been a better opportunity for testers to receive the respect they deserve. Digital transformation, no matter how you define it, requires new commitments to quality, and it’s up to testers to claim be the change agents in the transformations that CIOs are tasked with delivering.

    Tricentis CEO Sandeep Johri and other CxOs who spoke at Accelerate echoed this sentiment. Johri pointed out that speed continues to be a primary focus of maintaining or gaining competitive advantage, and manual testing processes that prevent agility or DevOps success at the enterprise level must be automated going forward.

    What was also made clear is that scaling investments in automation is not the single key to success. The pressure CIOs are under today, especially around digital transformation, requires new investments in a number of different areas, many of which are only just being realized. While CIOs may understand the necessity of quality, it’s up to testers to get the buy-in required for the continuous testing required to deliver it at scale.

    Testers with an oft-ignored middle child mindset may find the concept of being recognized as a “champion” by their CIO or CEO unlikely. But, Todd Pierce’s impassioned session on “What CxOs really think about testing” was designed to inspire testers to change the way testing was viewed too often in the past.

    As a current Rock Health and Dignity Health board member, and former Bill & Melinda Gates Foundation chief digital officer, Pierce shared his peers’ all-too-common beliefs that testing takes too long, costs too much and constrains developer productivity. And, while it may hurt to admit, with manual testing that should be automated and insufficient testing time that results in bugs making it to production, it’s not surprising that CIOs would feel this way.

    Pierce explained that testers who adopt innovative, scriptless “high-precision testing,” are able to shorten their test cycle, reduce defects that make it to production and eliminate costly rework for themselves and developers alike. When high-precision testing is performed continuously throughout the software development life cycle (SDLC), those beliefs that testing takes too long, costs too much and impedes innovation lose all validity. “Everyone in this room should be the drivers of agility in the enterprise,” remarked Pierce.

    Emmet Keeffe at Insight Venture Partners hosted a CIO roundtable later in the day where four CIOs detailed their personal experiences with taking enterprises through digital transformations. Each CIO admitted that in the past they had underestimated the the time being spent on testing, and one somewhat bravely stated that he’d always found testing somewhat “boring.” One might expect a room of testers to storm the stage with charges of heresy, but, given that many testers have suspected that management felt this way for years, I got the feeling that many were simply impressed that someone who felt that way had admitted it.

    But the panel, Pierce, Lewis and countless other speakers at Accelerate also made sure that the attendees of their sessions understood one thing: As more organizations undergo digital transformation—and no matter what stage of digital transformation they’re in—testing has never been in a better position to drive positive changes that will have monumental impacts on the business.

    Whether CIOs have been tasked with delivering greater agility, DevOps shifts, increased security, enhanced user experience, reliability and performance or legacy app modernization, testing may not be the first organization that CIOs turn to for help. But, as Keeffe explained, testing leaders who truly understand the incredible opportunity they have to make those CIOs heroes will make themselves heroes in the process.

    About the Author / Noel Wurst

    Noel Wurst leads influencer relations for Tricentis, and collects stories around cultural shifts and evolving technology’s impact on the software testing industry. By attending global conferences, interviewing passionate software professionals, and working closely with product, engineering and customer success teams, Noel looks for stories that matter and innovative ways to share them with audiences that lead to business growth. You can follow Noel on Twitter and LinkedIn.

  • Keep Developers Happy and Velocity High

    Keep Developers Happy and Velocity High

    In today’s economy, the companies that prevail are those that can accelerate software delivery and increase developer productivity. Yet, as applications become more complex and codebases grow, companies are forced to implement more comprehensive quality safeguards, which slow the rate at which they can deliver new software. Delivering more incremental builds in shorter intervals can address this conundrum: Customer needs are serviced quicker, overhead for engineers is reduced, and risk is mitigated because changes released into production are smaller.

    That’s why high-velocity engineering teams are applying not only continuous delivery processes but also lessons in experimentation from established leaders including Amazon, Netflix and Facebook. These companies have made experimentation a foundation for their release processes, trying out major feature releases and redesigns within smaller groups before making them broadly available. By using new techniques such as feature flagging, rollouts and traffic splitting, experimentation is no longer just the future for marketing teams; it’s quickly becoming an essential practice for high-performing development teams as well.

    Today, discussions around velocity focus on key practices that developers can use to maximize the effectiveness of continuous delivery, software development and experimentation programs. Here are some key ideas to consider.

    Reducing Your Dependency on a QA Team Actually Makes You Faster (Shifting Left)

    Many organizations eschew the conventional wisdom and deprioritize the heavy lifting of writing comprehensive test suites, opting instead to throw them over the fence to a Quality Assurance team. This approach is almost always less effective and causes organizations to lose momentum instead of conserving it.

    Higher-performing teams actually “shift left” and empower developers to own many parts of the QA process. A solid foundation of tests creates less overhead later on and empowers engineers to release quality code into production faster. Companies can address customer and product needs efficiently, quickly and with more confidence than if they wait for full QA cycles to finish.

    But what if you don’t have the ability (or luxury) to rewrite tens of thousands of tests? The good news is that even without expansive test coverage, you can still take advantage of this approach using code coverage tools. These work by evaluating how much of your codebase gets executed during test runs. If the overall coverage decreases, it means a feature was potentially rushed and is untested and should not be merged into the codebase until the ratio is balanced out. This code-to-test measurement can even “block” code merges unless it meets or exceed the previous threshold.

    Prioritize the Build and Test Frameworks Themselves

    Teams that that prioritize the development of build-and-test frameworks—as opposed to individual tests—are rewarded with faster, more reliable builds. But it’s a struggle to build out reliable processes that can handle tens of thousands of tests in a performant way for each developer.

    Particularly with more complicated test suites, there’s a tendency for these tests to become brittle or prone to occasional failure because of all the moving pieces. Optimizely built a “test gatekeeper” that automatically disables tests that fail in this way, without the need for human intervention, and assigns them to an owner to be fixed. Remember: unreliable tests are sometimes worse than no test at all.

    Achieve Faster Release Cycles Through Experimentation

    Companies that want additional, real-time insights and fine-tuning for their application stack are shifting to feature flagging and feature rollouts to expand their capabilities.

    Feature flags are simple control-flow boolean values that allow developers to use a new, experimental process on their application by gating it behind a virtual on/off switch, and have the option to disable it if a problem is found, all without another code deployment cycle. An example could be a “down for maintenance” notice, or something more advanced like a new product homepage that doesn’t require a code rollout to update the content.

    Feature rollouts take this concept a step closer to real experimentation by placing users into two or more experimentation groups, allowing every new feature to be beta-tested before a full general release. Each new feature becomes an opportunity to run an experiment and collect immediate feedback on your development hypothesis.

    Finally, there’s traffic splitting, a concept similar to feature rollouts that transparently routes a small number of users to a new experimental version to identify any bugs before they reach a broader audience. The primary difference between feature rollouts and traffic splitting is the “all-in” nature of traffic splitting an entire application vs. a single feature.

    Worried that the automated and manual testing of your large product release didn’t catch everything? Send a small percentage of your traffic to the new application as a “canary build” and see what happens. Optimizely experiments with traffic splitting between different production environments (stable versus release candidate, for example) to a small number of users. Facebook, and others have utilized this process for years.

    Shift Left, and Enter a High-Velocity Future

    Thorough testing helps companies catch many issues before they reach customers, but it’s extraordinarily difficult to anticipate every possible usage or scenario for your product. Investing in these release strategies will help companies mitigate the risks of unintended bugs creeping into code or, worse, unwittingly turning their customers into the QA team.

    Our advice? Don’t let feature development take priority over the necessary steps to keep your organization from working lean.  Empower your developers to participate in the process early by shifting left, and watch developer productivity and velocity soar.

    About the Author / Brian Lucas

    Brian Lucas is Senior Software Engineer at Optimizely, responsible for the Build, Test and Release Engineering. Previously, he was CTO at Credible and Hoopla, and lead architect at Sling (Slingbox). He holds four patents. Connect with him on LinkedIn and Twitter.


  • SMEs Can Benefit from DevOps, Too

    SMEs Can Benefit from DevOps, Too

    The DevOps approach has several clear-cut benefits with the value centered in several key business areas: improved market agility, increased quality and revised culture of cooperation and effectiveness in staff operations. By promoting and implementing a DevOps culture in your SME’s business, Dev and Ops teams align much closer together and can better share in-between knowledge. This lets you create products more fluidly and increase deployment rates. The time for evaluating the business idea, development, testing and moving the finished product into the operations department is reduced dramatically. Quality margins improve, and this feeds back into the ability of your teams to continually fine-tune the products you offer.

    Businesses see a point in adopting DevOps only if it is directly contributing to the company’s increased effectiveness, productivity and, of course, profitability. The only way that it is possible for small and medium enterprises (SMEs) is when their IT and DevOps teams are working in sync and streamlining the provision of tech solutions that solve the business needs. And only a successful and timely DevOps adoption inside your organization will help your company beat competitors and stay afloat as the development across the industry speeds up.

    In the last years, we’ve seen a tremendous application delivery shift in businesses. We’ve moved away from the old ways of having large-scale system implementations based on one single project and its continued maintenance. SMEs now perceive application delivery as a continuous evolution. DevOps plays a leading role, as this software engineering trend ensures that such a major shift is possible. It brings all of the different parts of the enterprise together: business, development and operations teams collaborate on a different, more in-depth level with a goal of automating processes. This helps eliminate the usual constraints and takes the time-to-market issues off the table.

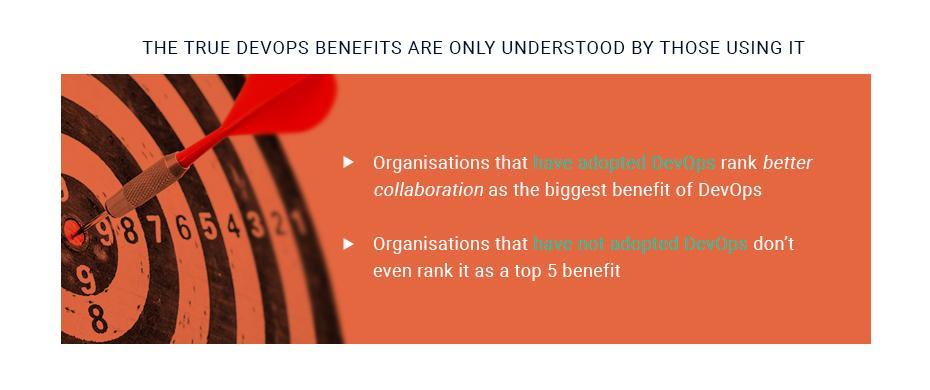
    In the latest ECS-Digital research on adopting DevOps in businesses, 57 percent of SMEs have partially implemented DevOps practices in their daily routine. The key benefit of DevOps for them is improved inter-departmental collaboration. But for the 43 percent that haven’t yet adopted DevOps, the collaboration issues are among the last priorities on the list.

    Step-by-Step Guide to a High-Level DevOps Life Cycle

    According to IBM Cloud Director, the end goal of a relevant DevOps practice is to cut the development time and improve enterprise’s efficiency. A growing business has to start from the “business needs” of the company and go down the road to make it come to life. The goal of adopting DevOps in your company is to push your business needs into production at a quicker pace more reliably. The goal in any DevOps practice is to cut the time and increase the efficiency of processes. You need to move from the “business need” to the “it’s live!” stage.

    Business Needs are a DevOps Priority

    But does your business have to get involved? Of course, your SME leadership focuses on the “business needs” of your company. But when we look at organizations that have implemented proper DevOps practices, the internal structure of the company shifts to focus on delivering great business results across the whole life cycle of your product/services offering.

    DevOps also ensures that employees have the ability to correct their work direction during the whole lifetime of a project. Things and goals tend to change, competitors may roll out some features that may make some of your project’s parts trivial, and all of this makes the need to adjust your project accordingly. This is easily done when your business need is close to both the Development and Operations teams that are able to steer and drive this alignment of goals.

    Have a look at the infographic below that clearly shows how a DevOps delivery cycle looks like:

    The Clash Inside Organizations

    Measuring the impact of DevOps on the things that matter to business is vital. Most SMEs are experimenting with DevOps, and there are some within the company who want to prevent DevOps adoption. The culture within enterprises is shifting too drastically and dramatically, although the effects are mostly positive.

    Such a shift is impacting all operations, with software development impacted the most. SMEs have it easier to change and adapt compared to larger businesses, and this lets them move the workplace culture a step ahead of their larger counterparts.

    If we look at business, operations and developer teams from a historical point of view, it was never a goal to establish inter-connection between them. The teams started cooperating only when it was absolutely necessary to get the other team’s input. SMEs are still faced with such a separation, as most responsibilities are set in stone for each team and the individual employee. All business units are used to working in their closed-in niche, and there is a lack of will to leave the comfort zone and act outside the predefined roles. Such actions in the past could have been viewed negatively.

    While most businesses that want to implement DevOps have employees who want the business to prosper, it can be difficult to force people to act outside their duties. However, to reach the end goals of any business—namely, ensuring fast and quality product delivery—and solve issues on the go, people must interconnect their duties and reach outside their business unit. With proper DevOps application, such collaboration can be smooth and result in the improvement of cross-functions.

    DevOps Represents Change in Internal Business Structures

    Many SMEs are faced with internal structural issues that limit the company’s prospects: Engineers are not willing to be on-call, the Ops team has a negative attitude toward those who write code and executives are slow to embrace automation. Organizations must overcome the culture war to be able to approach the agility and productivity gained by a DevOps model. The faster they can get there, the faster these organizations can take the competitive edge away from traditional enterprises.

    DevOps culture looks very different from organization to organization. However, regardless of the business implementing a DevOps approach, the potential benefits are the same. From faster deployments to increased efficiency and cultural changes toward experimentation and away from rigid planning, a DevOps culture has the ability to transform an organization completely. Wholeheartedly adopting a DevOps culture has real implications on how well a business is positioned to take on the market. With many industries facing uncertainty and a host of upstarts disrupting the status quo, shifting to a DevOps culture can be an important weapon in repositioning your business.

    Empathy is the Core of DevOps Adoption

    One of the foundational ideas behind DevOps is mutual empathy. Having empathy from operations toward developers and vice versa, as well as empathy in other business-related and non-technical company units, remains vital. It’s not about patting your colleague on a shoulder. We are talking about the moral mandate of a developer who just creates their part of the software and doesn’t care about how it can be deployed in production. The goal is to push employees to think outside of their small task, and to take into account the outcome of their work: Is the developed app secure? How hard is it to deploy it? Is it easy to keep it running? etc. If those questions are not accounted for, the developer’s colleagues on the Ops side will pay the price if something goes wrong past the release.

    By ensuring that the SME has empathy for each other at its core, businesses will deliver better products/services. And doing just that is what DevOps aims to bring to companies. Until this idea is ingrained, DevOps will face a cultural war of sorts.

    Your Most Valuable DevOps Resource

    By considering to adopt the DevOps approach to running your SME, you can better rethink the ways your organization operates—how it deploys its teams across the enterprise and how often it addresses structural problems that appear over time. Now you can lay out a new foundation for your SME based on the culture of cooperation and experimentation. With proper guidance in the application of DevOps culture, you can address the waste of time, human resources and money in your business.

    Becoming a DevOps organization is no easy task and taking up on such a challenge requires faith that changing the existing processes will bring its benefits. Reworking and optimizing organizations is the new norm, regardless of their size, industry, and goals. The faith in DevOps culture is driven by the firm and quantifiable statistics, but the intangible benefits to corporate culture are just as compelling. Many businesses are looking at implementing DevOps, and even more, SMEs are in the active process of its application. When your company is delivering quality ahead of time, there is a strong chance your competitors will be left behind as you are getting the bigger piece of the pie.

    Key Takeaways

    • To stay current, businesses need to adapt to an ever-changing environment, respond to competitors and stay on top of the innovation cycle, increasing customer value via responsiveness to change.
    • Increased service quality depends on both the availability of the service and being able to restore the service to an error-free state. Thanks to fast feedback loops and high release velocity, service breakdowns can be removed much more quickly than in the past.
    • DevOps are built on the sound principle of waste reduction such wait times and process overhead due to continuous improvement. This helps to improve agility and has a positive impact on costs.
    • Fostering continuous learning and improving culture through efficient principles is what DevOps is all about. In a fast-paced, unpredictable environment, non-stop improvement is paramount for sustaining your competitive advantage. It is also important for attracting exceptional talent and keeping employee satisfaction at a high level.

    About the Author / Stephan Pushkarev

    Stepan Pushkarev is the Head of DevOps Practice at Squadex.com and CTO at Hydrosphere.io. Co-founded and managed engineering teams for eCommerce, IoT and Ad-tech companies. He is responsible for the full products stack: math models, infrastructure & operations, enterprise applications as well as recruiting, establishing engineering culture and delivery processes. Stepan combines strong technical and managerial skills, and entrepreneurial spirit. Connect with him on LinkedIn.

  • QA/Testing and DevOps: Partners, Not Adversaries

    QA/Testing and DevOps: Partners, Not Adversaries

    Software testing and QA is sometimes given low priority during development. The idea of treating software testers as adversaries by the developers seems old-fashioned and is short-sighted. It’s hard to believe that such an attitude can still exist, and yet it still persists, even in a modern DevOps team. But a DevOps-focused software team benefits when it considers QA/testing as an integral part of developing high-quality applications.

    In a business setting, the hidden costs of buggy or unsecure software are lost productivity, revenue and extra work by the development team (and even extra work by users, if the software isn’t running right). QA/testing helps test for system flaws, vulnerabilities and security issues, so why wouldn’t a DevOps team be supportive?

    QA/testing can help an enterprise avoid big mistakes. In fact, the DevOps Institute notes, “With the advent of DevOps and the movement to break down silos between developers and operations, it becomes critically important that all members of an IT team—regardless of what tools they use, or role they play—understand the essentials of testing.” And, according to Puppet, a standard for automating the delivery and operation of software, high-performing enterprises build quality testing into each stage of their software development process.

    Make QA/Testing a Priority

    Whether your DevOps-focused developers are handling the QA/testing themselves or passing it along to QA/testing specialists, it’s something that must be done. Ideally, developers themselves would handle QA/testing in an integrated DevOps environment, and that’s why some developers see it as an unwelcome chore. It’s not something they’re usually trained in, and they might struggle with it or see it as a burden. That could be the reason why some DevOps teams hit a “software testing bottleneck.” As data from a Vanson Bourne survey commissioned by Appvance shows, 73 percent of 200 enterprise IT decision makers in the United States have adopted DevOps processes, but 57 percent of those adoptees experienced a bottleneck during software testing that impacts how quickly new and updated software can be released.

    On the flip side, the developer’s company may have QA/testing professionals in-house, so the developers are hands-off in that area. Needless to say, the relationship between developer and the QA/testing pro could get a little rocky. Just think about it: The role of the QA/testing specialist is to find problems and point out issues with the developer’s code. Or, perhaps the developer or engineering staff is lagging behind schedule, so the team inevitably needs QA/testing to rush its processes, further creating a tense or adversarial relationship between the two groups.

    At one of my startups a while back, we worked for months on our first software release of a web application for an online marketplace. Late on a Wednesday night, we let the CEO of our company try it out—and the app immediately crashed. “Gee,” I said, “It was working on my computer.” Of course, it really wasn’t. We had synchronization problems, which are common in multi-threaded applications that access the same information for multiple users. And we made the mistake of letting the CEO be the first simultaneous user to try it out (creating a bad impression), instead of making organized QA/testing a priority at our company.

    QA/testing in a DevOps environment can help your team avoid mistakes, so passion for app functionality doesn’t supersede quality and robust bug-free software. In the end, what you need from your team is passion for both functionality and quality/testing. Otherwise, you’ll deliver a faulty product and lose customers or users—unnecessarily—because of a bad first impression by your software.

    Two Approaches for Integrating QA/Testing with DevOps

    When you’re integrating QA/testing into your DevOps environment, there are two different approaches or procedures to ponder. First is the more traditional test of the full system, sometimes called integration testing. The second is test driven development (TDD), which is popular in Agile and Scrum methodologies. The main difference between the two is in how software code is tested. During integration testing, developers review and test the code. Then, for critical facets of the software, a peer review of code is completed. Afterward, testers create scripts and deploy an array of integration and system tests. These could include scalability testing, load testing, stress testing and very importantly, security testing. Code vulnerability, SQL injections and malicious code would be things to think about.

    Under TDD, the order in which testing appears in the cycle is reversed. Each developer first writes “unit tests” and then writes the code. This is done iteratively in such a way that every discrete section of code is automatically tested. When new code is sent to the integration server, the tests go with it. The server itself runs unit tests for all the code that developers deposit in the server. On top of this, testers design system and integration tests to run automatically by the integration server. Finally, testers perform any manual tests that are impossible to automate. In this way, the integrity and quality of the code is constantly guaranteed.

    Academic studies and field experience suggest that TDD increases development time by approximately 15 percent … but hold on. Experience also shows that total cost of ownership of TDD-developed software is lower than software using integration testing only. It’s worth noting that by using TDD and integration testing, a company can deploy software of world-class quality that exhibits less than 0.3 errors per 1,000 lines of code during 18 months of use.

    QA/Testing: A Partner in Your Software’s Success

    If you’re hesitant about integrating QA/testing into your DevOps team and instead tempted to outsource it, you may want to push pause. It’s actually quite challenging if you do development in-house and expect to simply outsource what you think is independent QA with cheap testers. Outsourcing QA/testing and assuming that piece is done is not really outsourcing—it’s staff augmentation at a distance and it usually doesn’t work. You don’t want a “siloed team” to handle a critical component such as QA/testing. Instead, outsource QA/testing and bring your in-house and outsourced teams together around a common DevOps culture and mindset.

    DevOps experts Bob Aiello and Leslie Sachs, in an IBM report, say quality software “… requires not only a shift in behavior, but a dramatic shift in the organizational culture as well.” So whether you outsource or have an in-house squad, your developers and the entire team should take ownership of QA/testing, and remain open to new ways to test code efficiently.

    Ultimately, QA/testing should not be viewed as a time-consuming, disruptive chore by anyone on your team or in your enterprise. Think of it as a partner in your software’s success—not an adversary.

    About the Author / Steve Mezak

    Steve Mezak is founder and CEO of Accelerance, a leader in global software development outsourcing, as well as the author of “Software Without Borders,” co-author of, “Outsource or Else: How a VP of Software Saved His Company,” and a CIO columnist.
     

  • Keys to Improving Enterprise DevOps Practices

    Keys to Improving Enterprise DevOps Practices

    As enterprises move to adopt DevOps practices, there is a desire to measure where teams are on their journey. This sometimes leads to the development of maturity models used to assess teams’ levels and progress. While I am not going to pass judgment on what might be useful for certain organizations, I believe that the real key is to drive positive DevOps practices, which include continuous improvement through data such as lead time, frequency of deployments and mean time to resolution (MTTR) (i.e. the key metrics from the State of DevOps Reports).

    Any static maturity model will become outdated. What’s more important is that teams are taught concepts that can help them continuously evaluate what is stopping them from delivering more quickly so that they identify areas for improvement. Key to this is the lean concept of value stream analysis. If you walk up to a team and ask them why they can’t go faster, they will typically say they are waiting for something. They could be waiting for more work to flow into their backlog. They could be waiting for infrastructure needed for development or testing. Or, they could be waiting for another team to develop a service they need to consume.

    Many teams don’t spend time in retrospectives talking about how to overcome these types of blockers or wait states and developing countermeasures as continuous improvement initiatives. One reason for this is the lack of objective data that can be analyzed to provide insights on this. This is where the lead time metric comes into play. Historically, lead time has been defined as (last) code commit to deploy into production. While this is important, it only tells part of story because accelerated delivery and feedback really starts with a customer concept and measuring how long this takes until it is delivered into production so feedback can be provided.

    One challenge to providing this kind of end-to-end metric, which spans the entire delivery value stream, is the lack of an integrated delivery pipeline from which data can be automatically collected. A customer concept starts in the portfolio space, which might result in data being entered in some type of PPM (portfolio management) system. Once approved, this results in features being created which eventually should flow into a product backlog. Stories are then created that can be pulled by the agile line supporting that product into an iteration. This information is typically in some agile management system (e.g. Jira or IBM Rational Team Concert). Then the team develops and builds the stories, tests them and deploys them into production via a deployment tool like UrbanCode. So, this flow of work goes through various tooling and generally is not visible or easily traceable across the value stream.

    Our initial goal in measuring lead time was to shift left and measure the time from story card backlog until the story was released into production. This would then give us four discrete measures that would provide more insight into the time spent in different parts of the value stream.

    1. Time spent in the backlog
    2. Time spent developing the story
    3. Time spent testing the story
    4. Time spent once the story was completed (marked “done”) until it was deployed

    We mapped the first and last categories into wait times and the second and third into process times to provide a baseline of this metric. While we have just started providing this information to teams, we are finding that scrum masters believe this type of data can be used in retrospectives to better understand why some lead times are high. They also believe that this will help the team better understand when blockers are encountered during development and testing and what contributed to them. We also plan to make that visible as part of our metrics (time spent in a blocked state). Tooling like TaskTop Integration Hub can help integrate your pipeline tooling to provide visibility and insight.

    Once teams gain more insight into what is slowing them down, they can identify countermeasures that can be applied. Categories of wait-states include:

    • Waiting for a dependent area to provide functionality necessary to complete a feature
    • SLAs associated with a service that is provided by a centralized organization (e.g. performance testing or security testing)
    • SLAs associated with infrastructure needed for an environment
    • Contention for a shared test environment

    Countermeasures associated with these types of wait-states are:

    • Architecture decoupling
    • Dark Launching / Feature Toggling
    • Expanding cross-functional teams to enable them to do self-service performance and security testing (at least some portion of it)
    • Automated Provisioning Capability for environment to avoid wait-states and contention

    The “State of DevOps Report 2017” contains information on the importance of architecture and how decoupling dependencies (using APIs and microservices) can mitigate certain types of wait states. DevOps Case Studies provides more information on applying DevOps practices such as dark launching.

    But again, at the heart of this is getting teams to think more about what their value stream actually looks like, how long it takes to deliver business value that can generate feedback and what is getting in their way of going faster. This is not a technology play. This is not something that somebody can sell or educate you on. This is something the team itself needs to take on.

    A good starting place for a team is to educate themselves on some of these concepts for DevOps practices using a book club. A great place to start is to study the “Phoenix Project.” This novel approach combines aspects of both DevOps and Lean to drive home some key points in the journey to discover types of work, manage work in progress and ultimately make visible and gain control over the work being done for the business. Once a team has an understanding of their value stream and blockers, they can then study the “DevOps Handbook” that provides practical guidance for improving their delivery capability and speed.

    About the Author / Carmen DeArdo

    Carmen-DeArdo-sqCarmen DeArdo is the director of Build Technologies at Nationwide Insurance. He is responsible for helping drive accelerated delivery utilizing Lean and DevOps techniques across the end-to-end delivery value stream.  One current focus area is the creation of an integrated delivery pipeline capability.
  • 10 Rules for Writing Automated Tests

    10 Rules for Writing Automated Tests

    Over the recent months many of our customers asked for our guidance and building their test suites properly. Performance, ease of management and scalability were key priorities for them. We decided to share our suggestions with the broader audience.

    We came up with the list while building our own test suite. Since we strongly believe in dogfooding, Testim is tested using Testim. We also learned a lot working with a variety of companies from small startups to large enterprises.

    Rule 1: Prioritize

    Most apps include thousands of scenarios. Testing the functionality and correctness is merely one step of the way to shipping high-quality software and meeting users expectations. There’s performance testing (speed and responsiveness in a normal state or under load/stress), visual testing (checking that 1+1 = 2 is one thing, but many visual bugs can make it a very bad experience), and so on.

    Start by listing the most important user flows, for example login, add to cart, checkout, etc. Order the list by those more vital for user conversion.

    Try to sort by first adding those that must succeed e.g. create account, checkout and payment. You can use your analytics tools (e.g. Google Analytics, Mixpanel, Kissmetrics, Woopra) to find which are the common scenarios. We also found Segment.io to be useful.

    Rule 2: Reduce, Recycle, Reuse

    The next step is to break the user’s scenarios down to simple, single purpose, almost atomic flows. e.g. “Create user,” “Login,”  “Send email,” etc. Create a test for each of these flows. When completed, compare this to the the user stories.

    Naming convention – Defining a good naming convention is an important part. For example, including the component name in the flow name, which can result in flow structure (e.g  “Account.login“ and “Account.logout”).

    Reuse components. Don’t Copy/paste – for non-experienced developers/testers, a copy/paste seems like a reuse. However, the challenge is to update those steps when the flow changes. Even a single step/line that repeats in hundreds of tests is a huge hassle.

    Rule 3: Create Structured, Single-Purpose Tests

    Single purpose tests verify one thing only!

    Single purpose tests are easier to create and maintain, they will also run faster compared to longer and complex ones. Ideally, they should only fail if the feature they test is broken or one of its dependencies (which we’ll try to minimize). If you test several features and the first one fails, you know nothing about the other features, since you haven’t reached them.

    A test should consist of three parts:

    1. Setup – e.g. login
      Those steps gets the AUT (application under test) to the state required for testing. This could vary by the test: sometimes you only require a login. you require a complex structure to pre-exist.
      Note: Premature optimization is not a good practice. Implementing the login flow (user/pass fields) is an easy way to start, and if you reuse the same login in all your tests, it wouldn’t be difficult to change the implementation later on to a quick implementation (e.g. by using cookies), so there’s no need to start with the speed optimization if you know it’s easily fixed.
    2. Actions – the flow you want to test.
      Continuing with our aforementioned “login” example above, unlike the setup steps, which require the login to be completed successfully (don’t care in which way), testing the “login” itself is a different task, and should not be reused.
    3. Validations – validate UI state, validate DB – the result you expect.
      There are different validations.his depends greatly on whether you’re testing data which is being updated from production on a weekly basis, or whether it’s the same Test Data.
      In UI testing, the basic validations are done on elements in the UI.

      • Validate an element is visible.
      • Validate an element comprises some text.
      • Validate an element is in a specific state.
      • Visual Validation – validate the is comprising the expected text, image and has the correct styling (e.g. font, layout).

    Using a predefined dataset has the advantage of making the validations easier, as when we know the exact setup state, you also know the precise expected state after the stimuli steps were completed.

    If the dataset is updated, you get different scenarios which you didn’t expect (as different user use your application differently), making it harder to debug failures (as the scenario might not be reproducible).

    Example: A test for a login could look like:

    • Set initial state:
      • Open AUT
      • Navigate to the signup page
    • Actions:
      • Choose a random username and it to a variable named username
        g. “user” + Date.now() + “@mailinator.com”.
      • Sign up for new account by using username.
        • Set username to username
        • Set random password
        • Click submit
      • Validations:
        • Open mailinator.com
        • Navigate to “inbox”
        • Look for email to username
        • Check that there is one email with the expected link.
        • Click on the link
        • Login with username and pass
        • Validate login was successful

    Note: One of the biggest differences between unit tests and end-to-end tests is the overhead. Opening a browser and logging-in to the AUT used to be extremely slow, pushing testers to perform many tests after reaching the Setup state, saving valuable time. Today, with docker, it’s much faster to boot a browser up, the speed of the browser help developers to write applications that load quickly, minimizing the  overhead of writing end-to-end tests.

    Rule 4: Tests’ Initial State Should Always be Consistent

    Since automated tests always repeat the same set of steps, they should always start from the same initial state. The most common maintenance issues when running automated tests are ensuring the integrity of the initial state. Since automated tests depend on that state, if it is not consistent test results won’t be, either. The initial state is usually derived from user previous actions.

    For example:

    1. Adding an item to a list that already contains it (from previous test run).
    2. Views that behave differently for new users and returning users.
    3. Application redirect automatically if user already logged in.

    Possible solutions:

    • Create new user for each test run
    • Use a dedicated app environment for test automation, as opposed to using your production one.
    • Seed your application with initial data before each suite run, also known as fixtures.
    • Use conditions on steps/group to handle dual cases in test which are hard to set.
    • Eliminate dependencies between tests. The AUT’s state after “Test_1” shouldn’t affect the flow of “Test_2”.

    Rule 5: Compose Complex Tests from Simple Steps

    Complex tests should emulate real user scenarios, you should prefer composing those test from simple tests parts (shared steps) instead of recording the entire scenario directly. Since you already tested all the simple actions in the simple tests, the complex tests should only fail on integration issues (this is where Rule No. 2 comes in handy).

    Make sure to order your suite to run the simple tests first. It will give you indication when something is wrong in the complex tests when running the whole suite.

    Rule 6: Add Validations in Turnover Points

    Validations are usually used at the end of the test to signal the test is in a passed/failed state. It is also best to add them at points of major changes as a checkpoint to stop the test if an action failed. Since validation will run until its timeout reached, like all steps, it is also a mechanism to wait for a long async operations in your app (e.g. fetching data from server, continuous view rendering, etc.) before running the next steps.

    Examples:

    1. On action completion – navigation, form submission, modal display, etc.
    2. After major DOM changes add validations to ensure you are in the new state before trying to play next steps.
    3. Following a client-server communication which change app state – e.g. data submitted successfully message, etc.

    Rule 7: No Sleep to Improve Stability

    Sleep with random duration (what I call magic numbers) is one of the main sources of flaky tests. Although all apps are asynchronous in nature, there are rare cases where a human doesn’t know when the page is ready and perform the next action. The same should be true for automated tests.

    The reason to avoid static sleep is you rarely know the load of machine upon you run the test on. Only in performance testing do you have the machine to yourself (knowing for sure all CPU and memory are for you). Since you probably use virtual machines or Docker you will get timeouts if you set the sleep too slow, or slow tests if you set it too high.

    In most cases you add a wait-for-condition step, which waits just like a human would, or sometimes waits for some internal state (e.g. javascript value).

    At Testim we provide all kinds of built-in wait-fors, ranging from wait for element to be visible to wait for a specific text (you use also variables and regex), wait for some visual change (e.g. color change) or code-based changes.

    Rule 8: Use a Minimum Two Levels of Abstractions

    If your test is composed mostly of user interactions, such as clicks and set-text actions, then you’re probably doing something wrong. If you used low-level frameworks (e.g. Selenium), you might have heard of the PageObject Design Pattern, which recommends to separate the business logic (e.g. login) from the low-level implementation (e.g. set username, set password and click login button). This is true for Testim as well. Having layers contribute to reuse reduces the maintenance and allows other members of the organization to quickly understand what happen, as sometimes the testers write the tests but the developers run them (before merging new code). The developers in this case need to understand quickly what the test does, and what is the bug.

    Rule 9: Reduce the Occurrences of Conditions

    A test should have as few as possible conditions (if-statements). Those that have many are usually unpredictable (don’t know the exact state you’re in) or complex (you might even see loops, too). Try to simplify your tests by:

    • Start your test at a predefined state;
    • Disable random popups; and
    • Disable random A/B testing, and choose a specific flow.

    Rule 10: Write Independent and Isolated Tests

    An important methodology of test authoring is creating self contained, independent flows. This allows to run tests in high parallelism, which is crucial for scaling the test suites. If, for example, you have 1,000 tests that run for a minute each, running them one by one will take more than 16 hours. Minutes, at full concurrency, can cut this testing time to 1 minute.

    Having a fast build reduces the feedback time between the moment that developers commit their code and the moment they knows their feature is production ready and can lead to true agile development cycle.

    In Summary

    Proper planning of your tests can make a big difference in your development process. The ability to get fast feedback, adapt tests to new user flows quickly and quickly analyze the results, identify bugs and get enough information to quickly fix them. Proper planning can also save a lot of time and expenses. Suites that are not properly planned require high maintenance and keep the R&D team away from building new functionality and increasing coverage. Finally proper planning can help expand the responsibility for quality beyond the Q&A organization and let others contribute.

    About the Author / Oren Rubin

    Oren RubinOren Rubin is CEO of testim.io. He has over 20 years of experience in the software industry, building mostly test-related products for developers at IBM, Wix, Cadence, Applitools, and Testim.io. In addition to being a busy entrepreneur, Oren is a community activist and and the co-organizer of the Selenium-Israel meetup and the Israeli Google Developer Group meetup. He has taught at Technion University, and mentored at the Google Launchpad Accelerator. Connect with him on LinkedIn and Twitter.

  • Using Application Deltas in Deployments

    Using Application Deltas in Deployments

    Developers have been versioning their source files since the early days of Unix. Anyone else remember SCCS? Back in those days, storage was at a premium: Disks were small and very expensive and it was too inefficient to store a complete copy of each version of the source file. So version control tools would simply store deltas—the changes made from one version of the file to another. This was more efficient; if you only changed one line in a 3,000-line file, the system would simply store the new line and some metadata about where it fit in the file and who made the change.

    Some tools would save the latest version of the file and use reverse deltas to record the changes if you wanted to revert to an earlier version. This was usually more efficient, since generally developers want the latest version of a file. As such, it was more efficient to apply deltas to get earlier versions than it was to start with a 3-year-old file and roll forward through 472 changes to get the file you wanted.

    These days, disk storage is literally 3 million percent cheaper than it was in 1981. (The storage in my phone would have cost $38 million in 1981!) Because of this, storing deltas is not the panacea it used to be. In addition, CPUs now can crunch numbers faster than they used to, so it’s possible now to use math to compress and store a complete copy of the new version of the file. That’s what modern revision control tools such as Git do.

    Now that’s all very interesting, but the title of this post is, “Using Application Deltas in Deployments.” So why am I rattling on about source code versioning?

    Well, here’s the rub: While deltas may no longer have much of a part to play in tracking changes to source files, they most certainly do when it comes to deploying applications, and for similar reasons that plagued us (or our parents!) 30 years ago.

    Applications are Made of Components

    Let’s be frank: An application that consists of a single binary on a single server is not going to need deltas. That would be akin to a change to a single-line source file. All you need to do is to replace the old binary with the new and you’ve deployed. But applications are getting more complex:

    • The application may be split across multiple servers. An n-Tier application may have different tiers running on different servers (and even different operating systems).
    • The application could be wholly or partially containerized. You can have multiple containers each running different microservices.
    • There could be database changes associated with an application change. Indeed, the application change could consist solely of a database change. Database updates are pretty much always deployed as deltas; alter scripts are used to add and remove columns, tables and indexes.

    In the same way a single binary can be built from lots of different source files (each of which is under its own version control), an application can be made up of lots of different binary components. Clearly, if the application consists of lots of different components and those components are resident on different servers or containers, then deploying every component every time a new application version is deployed would be wasteful, time-consuming and error-prone.

    An application version “delta,” therefore, would track which components have changed between the version of the application being deployed and the versions of the components on the target environment. This allows the deployment tool to only deploy the components that have changed. So what do we need to track to make this work?

    • Component Versions. Obviously, we need to version each individual component so we know which version of which component is included in any particular application version.
    • Which component version is present on any particular endpoint within a target environment. That way, if the application we’re about to deploy has version 5 of a component (a DLL or a WAR file, say) and version 5 is already present in the target environment, then we don’t deploy that particular component.

    This approach has a number of advantages. You can deploy to an existing environment and only deploy the components that have changed, minimizing the downtime and reducing the risk of failure. You can deploy to a newly provisioned environment and deploy all the components within the application. Then, if you need to fire up a new virtual machine (or a container), the deployment pushes everything. But the next time you deploy to that environment, only the components that have changed are deployed.

    Database Deltas

    We may need to consider special cases when it comes to database components. Remember we mentioned that database changes are nearly always delivered as deltas, SQL “alter” scripts that make changes to the previous version of the database schema? Well, if all you’re doing is deploying the next version of the application, then that works fine. However, what if you’re deploying a version that’s several releases ahead of what’s in the environment? This can easily happen if the test and production environments are “pulling” deployments into their environment (as opposed to having them “pushed” via a continuous delivery process). Now, just applying the alter script that is associated with this application version won’t work in any environment that doesn’t contain the previous version of the application.

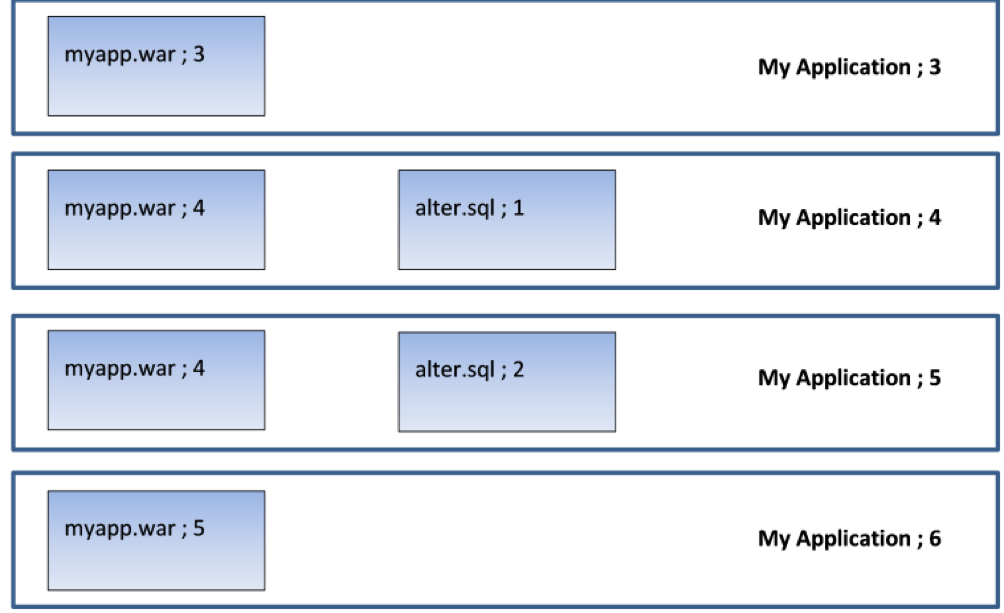
    Picture an application (“My Application”) that is up to version 6. It has two components: a WAR file and a database component that contains alter scripts that roll the database schema forward. Here is what the last four versions look like:

    So version 3 has a new version of the WAR file; version 4 has a new version of the WAR file and a database alter script that adds a column to a table. Version 5 only changes the database (it amends a stored procedure which uses this new column). Version 6 applies a new change to the WAR file.

    Now, in a continuous delivery process, the test rig being targeted will receive each new version. So when version 4 is deployed, the rig will receive version 4 of the WAR file and the alter script will be executed to add the column to the table. Then, when version 5 is deployed, only the DB alter script will run (alter.sql;2) to amend the stored procedure. The WAR file is not deployed, since the server already contains version 4 of the WAR file. When version 6 is deployed, only version 5 of the WAR file is deployed. This is exactly what we want.

    But now what happens when we move to user acceptance testing (UAT)? By this stage, we’ve done as much automated testing as we can get away with; in UAT, real users need to log on to our test system to make sure they’re happy with everything. So we’re not going to do a “push.” In UAT, the test lead does a “pull” when they’re ready to accept the new version of the application for testing. So they pull “My Application Version 6” into their test environment and get their testers lined up with coffee and pizza.

    But what happens if the test environment is currently on version 3? Well, for the WAR file, there’s no problem—there’s a difference in the component version for the WAR file so the new version is deployed. But what happens to the database? There are no alter scripts associated with version 6 of the application, but without applying alter.sql;1 and alter.sql;2, the database schema is not going to be valid for use with myapp.war;5. The testing will fail, not so much “falling at the first hurdle” as “falling in the paddock.”

    Deltas allow us to cure this issue. What we need to do is identify the components that represent the database changes and get them to be applied in sequence for each interim version. In that way, successive database “deltas” are applied to roll the database forward to the correct schema version before the required version of the application is deployed.

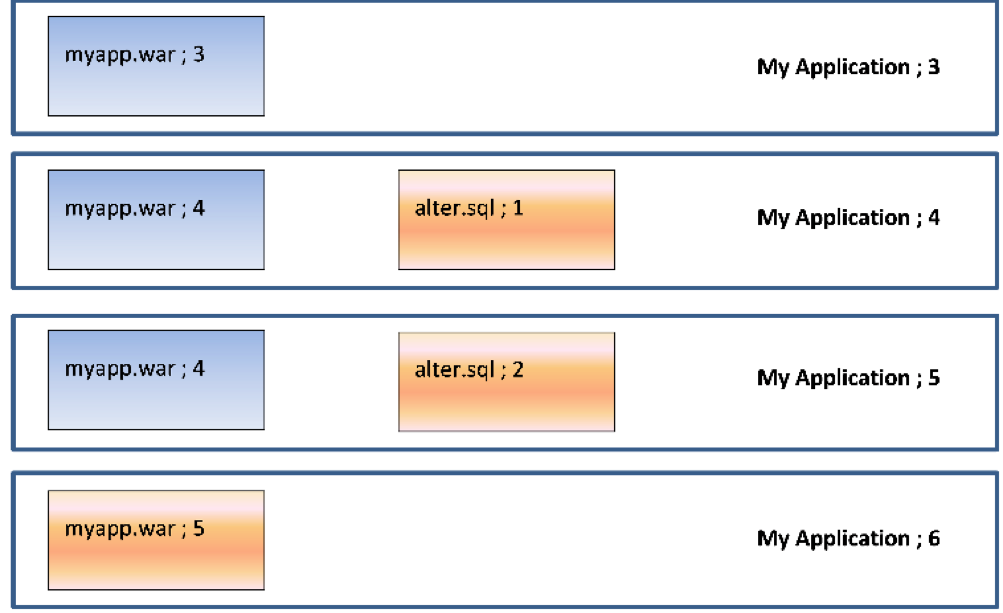
    So, in our case, going from version 3 to version 6 would deploy the following components:

    So we will deploy (and run) alter.sql;1 to add the new column, then alter.sql;2 to amend the stored procedure and, finally, deploy myapp.war;5. Deltas mean we do the minimum required to get the application version to the desired state.

    Conclusion

    Versioning the components that make up an application means it is easy to determine the deltas (changes) between one application version and another. Recording what version(s) of the components are on the endpoints in a target environment makes it easy to only deploy the components that have changed, minimizing downtime and making the deployment quicker and less error-prone. Identifying the deltas for a database gives us the ability to roll databases forward and jump between releases, which is invaluable when transitioning from an agile “push” to a waterfall-centric “pull” deployment model.

    — Phil Gibbs

  • Move the Needle in DevOps with Continuous Testing

    Move the Needle in DevOps with Continuous Testing

    Shift-left testing, risk based testing, early testing and technical debt reduction are all predicted to be some of the most sought-after trends in product development life cycle. All of these can be achieved with continuous testing through DevOps, as it emphasizes quicker transitioning of quality products to production environment at a reduced business risk.

    Software Engineer in Test (SEiT) or Software Developer in Test (SDiT) was long-spoken earlier and now implemented as part of DevOps culture. As the software side of the organization moves to continuous testing practices, so, too must the product side of the organization. External market forces including competition, innovation quotient, faster time to market, scalability and lean process initiatives definitely play a role in driving the continuous testing trend.

    From a technical standpoint, test environment creation, full test coverage, regression testing and integration testing of multiple endpoints are key parameters to ensure a faultless production environment when a new feature is added.

    Adopting Testing Tools for DevOps Implementation

    Continuous testing implementation not only includes adoption of right tools and test automation, but also a cultural change to incorporate testing at each stage of the agile development life cycle. It will involve changes right from test planning, test scenarios creation, automation feasibility analysis to test execution.

    Teams need to be restructured in an agile setup to align testers closer to developers and operations teams, and have common goals for product/software delivery. This involves changing the culture and organization structure, which generally takes a longer gestation time. Test management tools such as JIRA and TestNG can help expedite this structuring, as both parties would be aware of the product features that need to be delivered and can view the progress at all times. There also are various open-source tools, including Selenium, Appium, Python robot framework/pytest and JMeter, that aptly meet the needs of agile testing.

    Regression testing generally takes up the bulk of the time, as new features need to be tested every time they are added to avoid critical failures. Hence, automating regression tests have become an imperative as part of continuous testing. JUnit, which is a unit testing framework, promotes test-driven development and early code quality improvement. Bamboo can run tests in parallel batches and support hundreds of build agents providing an early feedback to developers. Automation scripts for test data cleanup, load and execution saves the testing effort of the operations team. Selenium test automation framework for web applications is one of the most famous tools for continuous testing, as it works with a host of programming languages including Java, C#, Groovy, Perl, PHP, Python and Ruby. Appium is another tool used frequently for cross platform mobile application testing.

    Ensuring an Effective Product Release

    Testing UI components and functionality of a product through API-based test automation is another important phase in continuous testing. API test scenario creation also generally needs involvement from the ops team. Considering virtualization of devices, along with applications or services, will accelerate test setup environments. Device virtualization using Raspberry pi helps in testing end–to-end use cases in IoT scenarios. Network virtualization for performance testing ultimately helps improve uptime and reduce outages.

    The orientation of continuous testing with continuous integration and continuous delivery pipeline within an enterprise will determine the long-term success and standing of the final product in the market, from a quality perspective.

    About the Author / Urvashi Babaria

    Urvashi Babaria is a Product manager at eInfochips working in new age areas like IoT, DevOps and CloudOps. She is a techno commercial marketer with nine years of experience in product and project management, business analysis and transformation. She has keen interest in areas of data science including visualization, analytics and modeling. Connect with her on LinkedIn.


  • The Role of QA in the DevOps World

    The Role of QA in the DevOps World

    The need for faster time to market and superior quality is getting intense in the software development process. Software trends for 2017 suggest that DevOps will grow as a trend and become more widely accepted across enterprises. Organizations are reaping the benefits of DevOps approach and are incorporating the rules within every aspect of software testing. A case in point: DevSecOps—security testing integrated with DevOps—is an emerging concept and is being considered by enterprises to execute application security testing.

    The underlying objectives of adopting DevOps are to make the testing and development process more collaborative, ensure software quality and to help launch the product faster to the market. This makes quality assurance (QA) a key component in the DevOps methodology. New-age applications need real-time changes and updates to meet the growing demands of the consumer. This requires continuous testing, continuous development and continuous delivery/deployment. DevOps enables teams to constantly upgrade and deliver.

    In 2016 a number of enterprises adopted DevOps. According to industry experts, 2017 will see more defining moments for DevOps. The idea of accepting DevOps is to consider a cultural shift and not just a technical shift. As digital transformation expert Jeff Sussna says about DevOps, “The key to following the continuous delivery path is to continually question your own assumptions about what’s possible.” Currently, DevOps is on the route of being questioned and defined at every level. It will result in bringing more value to the methodology.

    Every enterprise and its style of working differs. The way they would adopt DevOps will differ, too. But digital transformation and the need to be available for customers all the time with new updates is transforming the way enterprises adopt new practices and methodologies. Every enterprise has to evolve in a sustainable manner, so quality is at the core of every practice, including DevOps.

    Why is QA Integral to DevOps?

    In the DevOps scenario, QA integrates into the testing and development process and takes the collaborative approach. Quality is ensured throughout the testing and delivery cycle and both the testing and development teams are responsible for it. In the traditional pattern, quality creeps in toward the end, but with DevOps it comes in at every level.

    In terms of code development, the QA team pushes the new development code into production and DevOps facilitates to ensure a seamless deployment of infrastructure and tools. Thus, it helps in releasing a code on a consistent basis and the responsibility to ensure quality is not just limited to killing the bug; it is built in the overall application release.

    In the current scenario, hourly releases are required to meet the demands of the consumers and deal with competition. Web/mobile applications such as an ecommerce or financial services application need to be updated frequently. It is a key business requirement. DevOps helps to make this possible, but with QA involved, the quality of the release is ensured. Moreover, with DevOps, the reality check can happen in real time rather than taking the code offline and testing it.

    On the whole, the popularity of DevOps over the years has intertwined quality into every engineer’s responsibility, which is a positive sign. This helps in addressing the needs of the market and ensure that customers do not suffer. QA further enables and directs teams to check the application for performance and quality before it is delivered.

    The role of QA in the current software development process is changing, where the customer comes into focus and the needs of the customer are brought into perspective while delivering the application. Releasing new and functional builds at any point through the application’s life cycle can become a disaster if quality is not ensured constantly. Automation of tests plays a critical role to guarantee quality and bring speed.

    Building a QA strategy with the necessary best practices is essential for organizations that are embracing the DevOps movement. This will help in delivering effective software development and operations to achieve user experience. DevOps practices are adopted to improve the regularity of the releases and reduce the defects. It is a methodology that boosts rapid, short, iterative development and deployment of applications.

    So, the idea of incorporating QA is to ensure continuous improvement in the delivery process. DevOps helps digital enterprises to meet the needs of the competition and enable overall business growth. As a result, enterprises are able to streamline and pace up the delivery of applications with changes and innovation.

    Best Practices for Incorporating QA in DevOps

    The key aspect to consider while merging QA with DevOps is that the QA and testing teams must team up with the technical teams. In this way QA becomes an enabler for ensuring quality in the software development cycle. In addition, it is important to define tangible aspects of the quality that are expected from the project/application. This helps in achieving results within stipulated time frames.

    Putting down the quality metrics is absolutely critical in DevOps, which helps teams to identify bugs early in the development cycle. Defining the metrics also enables teams to integrate them within the organizational culture at various levels. In this way, quality is ensured at every level and development teams also get enabled.

    The idea of DevOps is to make the developer think in line with testers and constantly check the code for potential errors. On the other hand, a tester who holds the responsibility to test the application/software with various testing tools and methodologies also needs to fix the code. In this way, enterprises with an inadequate QA or testing strategy cannot ensure continuous testing and continuous delivery.

    In Conclusion

    The application scenario is changing and it is getting very complex. DevOps can speed up the development, but what can you expect without a robust QA strategy? QA is absolutely integral to the DevOps process. Continuous development and delivery is impossible without a comprehensive QA/testing strategy.

    This blog has been drafted in collaboration with Cigniti Technologies, an independent software testing company. Click here to read more blogs on DevOps.

    About the Author / Komal Lopez

    Komal Lopez works with Cigniti Technologies and is instrumental in helping enterprises take better decisions related to Quality Assurance products, tools and services by leveraging research and content. She specializes in writing about technology trends, testing trends and has been in the Marketing and Communications industry for over a decade. Connect with her at komal.lopez@cigniti.com