Tag: telemetry

  • How to Migrate an Observability Platform to Open Source

    How to Migrate an Observability Platform to Open Source

    Achieving full observability across enterprise applications is challenging. While third-party services like New Relic or Datadog make end-to-end observability easier, as your application grows in complexity, so does the telemetry data, leading to increased costs. Migrating to an open source stack gives you control over telemetry data and reduces observability costs, despite challenges with existing service provider commitments.

    Migrating to open source solutions is straightforward with simple architecture and tech stacks. However, transitioning the entire observability stack to open source demands meticulous planning, tools/frameworks assessments, testing, risk analysis, and cross-team communication, especially given the number of microservices, heavy cloud reliance, and diverse languages and frameworks to take into account.

    A cloud observability platform usually absorbs 20%-30% of overall infrastructure spending, but in some cases, it can reach 50%-60%. If your observability expenses exceed 50%, then transitioning to open source solutions would be a sensible option to mitigate tech infrastructure costs.

    For the past two years, I have been working on migrating the observability platform from a proprietary solution provider to an open source stack. Let’s dive into the key steps necessary for such a migration.

    Finalize the key telemetry data and systems

    Managed observability platforms offer comprehensive insights into system health, necessitating a significant volume of high-quality telemetry data. By default, the agents tasked with capturing and transmitting telemetry data are configured to gather as much information as possible, facilitating the creation of extensive dashboards and reports. However, this extensive data collection contributes to the overall cost.

    Select which systems you actually need to monitor. A typical enterprise application includes databases, caching databases, container orchestrators, and numerous cloud services. Engineers often monitor more services than necessary, which leads to unnecessary complexities and costs. It’s often sufficient to streamline the monitoring scope to essential systems.

    In my experience, the quantity of telemetry data required is significantly lower than what third-party services typically retrieve. You can easily divide those data collections into two buckets: must-have and nice-to-have. The “must-have” data aligns with the well-established four golden signals:

    • Latency: the amount of time it takes to serve a request
    • Traffic: the volume of requests that a system is currently handling
    • The error rate: the number of requests that fail or return unexpected responses
    • Resource saturation: the percentage of available resources being consumed

    These fundamental signals serve as the foundation for key dashboards and alerts. Observability platforms built on these signals cover 80% of typical use cases.

    Understanding each signal’s metadata requirements is crucial. The extent of metadata captured directly impacts the observability platform’s complexity and cost. For example, when monitoring service-to-service latency, consider the necessity for service IP addresses, instance IDs, or header information.

    Select the relevant stack

    Managed observability platforms such as New Relic and Datadog provide comprehensive monitoring for various enterprise components. However, when you migrate to an open source stack, you must assess and integrate the tool stacks to meet diverse monitoring requirements.

    One important aspect to consider is scaling: how to manage the huge amount of data generated every minute across all those systems. Focus on two fronts: selecting the stack for storing and processing telemetry data (logs, metrics and traces) and devising methods for capturing and pushing telemetry data from diverse systems.

    Telemetry signal stack selections
    Telemetry signal stack selections

    Stack for logs

    You require a stack that can efficiently and economically process and store the substantial volume of logs generated by the system. In the past, I used the ELK stack for storing and searching logs, but it is a generic solution and not tailored specifically for logs.

    I recommend Grafana’s Loki for its effective management of large log volumes and LogQL, a language akin to PromQL. If you are familiar with PromQL, navigating through extensive log data with LogQL is easy and intuitive.

    Stack for Metrics

    Prometheus is a popular database for storing time-series metrics data. However, it has scaling-related limitations; it cannot scale horizontally. Alternatives like Thanos, Grafana’s Mimir, and VictoriaMetrics offer better out-of-the-box solutions for horizontal scaling.

    I conducted some research and ultimately chose Grafana’s Mimir to store metrics in a similar migration project. This decision was based on Mimir’s remote storage capability, as well as its scalable and highly available architecture.

    Stack of Tracing

    Distributed tracing is a must in a microservices architecture, for easily identifying bottlenecks in latency and for resolving performance-related bugs. Grafana’s Tempo could be a good option for several reasons:

    • It can seamlessly integrate as a backend for Grafana’s dashboard. Consolidating dashboards in Grafana helps avoid navigating between multiple applications. Switching platforms just for tracing while using Grafana for other aspects of observability would not be practical.
    • Tempo provides a similar experience to TraceQL when interacting with the database, streamlining the learning process and significantly reducing the learning curve.
    • Tempo is compatible with popular open source tracing protocols such as Zipkin and Jaeger. If any team already uses these protocols, transitioning to Grafana’s Tempo would be smoother.
    Capturing and pushing telemetry data
    Capturing and pushing telemetry data

    You have to install an agent on the system to capture and push the telemetry data. Those steps vary based on the system being monitored. Typical enterprise application setups involve monitoring cloud integrations, process monitoring, infrastructure hosts, Kubernetes clusters and application monitoring. Among the possibilities:

    • Cloud integrations: This includes monitoring for cloud services such as SQS, SNS, EMR and EC2.
    • Process monitoring: This involves monitoring processes running on bare-metal machines. With the advent of dockerization and Kubernetes, there is now a standardized way of starting the application. In the past, there was no fixed mechanism. For example, to run a Java application, you could use a Java application, the ‘java -jar’ command, Tomcat, or OS systemctl. In the case of node, it could be npm or PM2. Each team or service may have had its own way of starting the process.
    • Infrastructure host: This entails monitoring the machine itself for metrics such as CPU usage, memory, disk I/O and Network IO or checking if the machine is offline.
    • Kubernetes monitoring: You regularly need to monitor a Kubernetes cluster, such as instances where Kubernetes is unable to schedule a pod due to insufficient resources.
    • Application monitoring: This monitoring focuses on overseeing the services the team created. Each service may differ in its development approach and choice of tech stack; but from an observability perspective, they usually are treated the same.
    • Browser and mobile monitoring: These metrics ensure optimal performance and user experience across different platforms. Browser monitoring includes tracking page load times, rendering performance, JavaScript errors and resource usage. For mobile, it includes monitoring app crashes, latency, battery usage, network requests and device-specific metrics.

    Before the advent of OpenTelemetry, there was no standardized method for monitoring applications. OpenTelemetry emerged from the merger of two earlier projects, OpenTracing and OpenCensus. It stands as a vendor- and tool-agnostic framework to instrument applications or systems irrespective of language, infrastructure or runtime environment. OpenTelemetry represents a significant community effort, and its popularity and stability are steadily growing.

    Validate observability stack on application architecture

    Applications vary in architecture and development stages. To address this diversity, you need multiple proofs-of-concept (POCs) across different systems, such as infrastructure, cloud service and backend and frontend applications.

    Migrating an observability platform from one tech stack to another is simple when the application architecture is a monolith. However, when the underlying architecture is microservices, it becomes difficult.

    While the microservices architecture offers flexibility in choosing different tech stacks for building services, devising a standard solution for capturing telemetry data becomes challenging due to the diverse range of tech stacks involved.

    Conducting POCs for various tech combinations is necessary to build a self-service tool that individual teams can follow to migrate their services easily. For instance, if your service uses Java 11, Spring Boot 3.x.x and PostgreSQL, these POCs can provide standardized steps to enable application monitoring.

    Migrate core components

    Setting up the observability platform involves configuring the stack for metrics, logs and traces, as well as installing the necessary agents. One advantage of migrating the observability platform is that there’s no need to transfer old telemetry data. During the testing phase, you will have an overlapping period to accumulate enough useful data to create specific dashboards and alerts.

    Migrating alerts and dashboards to the new system is essential, even when data migration is not necessary. This is because changes in the underlying techniques for capturing metrics may modify the names of the metrics and subsequently change all query expressions used in alerts and dashboards. Some metrics may not be available in certain scenarios, especially derived metrics that can be recreated from underlying metrics.

    While migrating query expressions manually is an option, a manual process is error-prone and time-consuming for a large number of alerts. I had experienced a similar situation with alert numbers ranging from 100 to 400.

    To streamline the migration, we developed a Node.js script that programmatically converted New Relic’s query expressions to Prometheus expressions. The script performed the following high-level steps:

    • Connected to the New Relic API server and fetched all the alerts configured for cloud integration
    • Converted New Relic alert expressions into PromQL alert expressions
    • Wrote all the Prometheus alert expressions into the YAML file

    Implementing this technique allowed us to successfully migrate all alerts and dashboards in four or five days, a process that would normally demand a month’s manual labor. Additionally, scripting significantly minimized the risk of human error.

    Test the migration

    Verify each alert and dashboard. Run both old and new platforms during testing. Parallel operation permits thorough testing of the metrics.

    However, running both systems concurrently may lead to a performance hit due to services sending telemetry data to two locations. Additionally, there may be a slight increase in costs until the complete transition.

    Running both systems in parallel provides an ideal setup to ensure the migrated dashboards and alerts are functioning correctly.

    Testing alerts that trigger during this process is straightforward, but evaluating those that have not yet triggered poses a challenge. In one project, I reduced the threshold value of each alert and tested its functionalities. Approximately 90% of the alerts generated through custom scripts worked seamlessly, with only 10% requiring some manual tweaking.

    Migrate other related components

    Other systems depend on the data generated by the observability platform. For example:

    • Notification systems like email, Slack channel, etc., that alert in case of an incident
    • Incident management tools like PagerDuty provide a streamlined way to handle incidents.

    These systems rely on the alert’s payload to work properly. Their assets should be updated, as a change in the observability platform leads to a change in the alert payload. Update the templates of notification systems to ensure they seamlessly integrate with the new alert payload.

    Similarly, incident management tools like PagerDuty require modifications to routing rules, escalation policies, and scheduling. Fortunately, readymade open-source migration tools are available to facilitate easy migration from PagerDuty to Grafana’s OnCall. However, in other solutions, you may not have access to out-of-the-box migration tools. In such cases, manual migration or script writing may be required.

    Timeframe for the Migration

    Planning a migration involves finalizing key telemetry data and systems, selecting relevant stacks. and validating the observability stack on the application architecture. It typically takes around three weeks.

    The project duration depends on factors such as the number of teams involved and the quantity of active services. For instance, a migration to open source with 100 microservices and involvement from 10 different teams may take four months to complete.

    Migration Complete!

    Transitioning your observability platform to an open-source stack offers a promising avenue for cost reduction and increased control over telemetry data. However, accomplishing this migration demands meticulous planning and execution, encompassing essential steps like feature prioritization, stack selection, POCs, core component migration, testing, and the migration of related systems. Despite the challenges posed by diverse architectures and technologies, a systematic approach, comprehensive assessment, and collaboration among teams can facilitate a smooth migration process and guarantee its success.

  • KubeCon 2023: Telemetry and Data Management

    KubeCon 2023: Telemetry and Data Management

    Speaker 1: This is Techstrong TV.

    Alan Shimel: Hey everyone. We’re back here at KubeCon and it’s bustling, man. It’s a crazy big floor with a lot of people walking around, so we hope you like this. This is a little different than we usually do. Usually people can’t see the background because the cameras face this way, but we usually have sort of the typical background that you see at some of these other booths. But we wanted to give people kind of a flavor that we’re alive here.

    Tucker Callaway: We’re in the middle of it.

    Alan Shimel: We’re in the middle of it. So kind of like if you ever watch Sunday night football, they always have that. So that’s what we were shooting for. But anyway, let me introduce you to Tucker Callaway. Tucker is the CEO of a company called Mezmo. Now, some of you may have heard of, I think it was Log DNA.

    Tucker Callaway: Before. Yep.

    Alan Shimel: And they pivoted. Was it about four years ago?

    Tucker Callaway: About two years ago now.

    Alan Shimel: Two years ago.

    Tucker Callaway: I’ve been here for four, but big change was two years ago, renamed.

    Alan Shimel: Renamed to be Mezmo and a slightly different mission, let’s call it. And then I had a chance to catch up with Tucker at RSA last, I guess it was last April.

    Tucker Callaway: April. Yeah.

    Alan Shimel: This year it’s May. So I think it was around then last year. And for those of you who want to catch that interview, it’s actually available on Techstrong TV. If you look up RSA 2023, it’s there. But so Tucker, before we get into that, let’s back up. Mezmo. Not everyone out here. Look, not everyone out here knew Log DNA either, so don’t worry about it.

    Tucker Callaway: Fair enough. Yeah.

    Alan Shimel: Let’s start there. Let’s talk about the mission.

    Tucker Callaway: Yeah, so the mission of Mezmo is essentially to help people with their telemetry data. So we’ve found that there’s really kind of three main problems in the telemetry data space. There’s too much of telemetry data. It’s not in the right format. It’s not in the right location. So that was kind of one of our founding kind of principles of solving.

    Alan Shimel: Yeah, I think that.

    Tucker Callaway: Solving the problem.

    Alan Shimel: Those were three rock solid.

    Tucker Callaway: Hard to debate.

    Alan Shimel: Hard to debate. That’s the good way of putting that. And also, quite frankly, all three problems are like they compound each other.

    Tucker Callaway: They do.

    Alan Shimel: So it’s like you have too much data. That’s a big problem, but we have too much data that we don’t know how to categorize, so that exponentially makes that problem worse. So these are-

    Tucker Callaway: Compounding problems. No question about it.

    Alan Shimel: No doubt about it. So when we were at RSA, you felt like you were kind of on the cusp of a realization, right? You were going to help customers. Why don’t you? Well, you tell the story better than me.

    Tucker Callaway: So as we were talking about earlier, we had just launched this new product capability, the telemetry pipeline at RSA. We’ve got a lot of great customers and great experience since then. When we think about the core value of what it provides, it helps people with cost, it helps people get better insights and helps people enforce compliance. What we were surprised by though in the last couple months, is how little people actually understand of their data.

    In fact, we’ve put a lot of time and effort as an industry into getting control of our applications and getting control of our infrastructure, but we haven’t really gotten control of our telemetry data yet, and that’s like the big opportunity that we see. But with that, in order to get that value I described, people didn’t need to understand their data better. And so that was a big revelation for us.

    And we just launched our data profiling capability that helps people categorize and understand baseline, to do the schema management for their data, which is a really strong foundation for data ops principles applied to telemetry data. Then the next thing we found after we solved that problem was now that people understood their data and they were able to optimize it because they understood it. They also realized that the context and telemetry data changes rapidly. So for example, you don’t want to store all this data because you don’t need it until you need it, and then you really need it.

    Alan Shimel: I’ll take a little, they do want to store the data because people are data hoarders.

    Tucker Callaway: The data hoarder. Yeah.

    Alan Shimel: It’s when they get hit with the bill for storing all that data, they say, “Wait a second, I don’t need all this data. Not at that price.”

    Tucker Callaway: Something has to give somewhere.

    Alan Shimel: Exactly.

    Tucker Callaway: And so what we realized though was if you take the bookend of this value, we think of as understand, optimize and respond, we talked about understand and optimize the response stage was a really important one for us. So when new context comes in, the pipeline can change its behavior and change its optimizations to account for the current flow of data and the current needs. So if you’re sampling down to 20% and you see an event, you see performance, you can rehydrate, reprocess, dynamically change the responsiveness of the pipeline and get all the data to the right location for the right people, which helps address the cost problem, but also gives you the full visibility that you need.

    Alan Shimel: If one was going to do a business school case study on this, someone who’s not from this industry would say, “Hey, just the fact that you discovered that most of these organizations don’t even know how much data or what data they have would be enough to build a company around.”

    Tucker Callaway: Yeah, I’d like to think so.

    Alan Shimel: No, it’s logical. It makes sense, but it’s not, it’s the threshold. Because I think you’d hit the nail on the head here, Tucker, which is once they recognize that, now there’s a whole new vista of realization for them of, “Holy mackerel, I got all this data, now I want to start understanding it. Wow. I’m seeing stuff I never thought I’d see. Maybe I intuitively thought I had, but I got the goods now.”

    Tucker Callaway: We like to think of that as being mesmerizing, right?

    Alan Shimel: Okay, I love it. Mesmerized by Mezmo.

    Tucker Callaway: I couldn’t not take the shot, but that was just-

    Alan Shimel: Yeah, that was your shot.

    Tucker Callaway: That’s the derivative of the name.

    Alan Shimel: I feel used. I feel used.

    Tucker Callaway: I got back into it a little bit.

    Alan Shimel: So now you’re mesmerized and now like, “Oh my God, what can I do with this?” And that really becomes the business. And I guess that’s now where you are.

    Tucker Callaway: The next step for us is clearly that. Yeah, and I think there’s two plays on that, too. There’s a, “What do I do with it? Help me, tell me what to do. Give me the best practices that from all of your customers, what should I do?” And so we’ll be coming out probably later in the spring with something that actually allows you to simulate how that data might look when optimization’s applied to it so you can start to make those decisions more effectively.

    But then the second phase of that, too, is that also won’t be sufficient for certain organizations that want to look at their data as a strategic advantage. And they’re going to be looking for ways to take actions and drive more insights out of that data. And so the way we see that, we see that through recipes. We’ll give you the standard offerings, but then you have the ability to go in and edit as code and go do the things you need to do to go drive more value out of that data. If you’re ready for advanced yoga moves in the data space.

    Alan Shimel: Got it, got it, got it. My background is security.

    Tucker Callaway: Yep.

    Alan Shimel: Started a security company in 2001, and it was right when we were moving from IDS to IPS. So intrusion detection to intrusion prevention. Same thing with vulnerability management. We were moving from just finding vulnerabilities to patching, remediating, not always patching, remediating. Seemed like who wouldn’t want that? No brainer, right? Just don’t tell me I’m getting attacked. Block the thing. By the time you tell me, the attack went through. Don’t just tell me you found a vulnerability, make sure I’m not getting exploited. But a funny thing that I learned in that was a lot of people say, “Go slow here. I can’t afford, because sometimes the vulnerability or the attack or the data that you want me to act on can affect something that I consider more valuable.”

    Tucker Callaway: Yeah, fair enough.

    Alan Shimel: And I like to go slow when it comes to letting a program or an application or a product, just do things. Just give me my menu and I’ll decide what I want to do. Now, of course, that was before the world of AI and ML and a lot of the automations. And quite frankly, the speed of business was probably a little slower then. Do you see a way station where people are going to want that? Just give me best practices and I’ll decide when, how, and where I want to implement it. Or do we move right to, “Hey man, make it happen for me.”

    Tucker Callaway: I think there’s a way station, when we think about the data management, telemetry, data management in general, the word that’s the most important to us is trust, right? So it is one thing to optimize the data, but you have to trust that data is constantly being optimized and handled in the right way for all those varying needs you described.

    So I do see that the first step is a suggestion with a human in the loop. You want to hit that button still to say “go”, and then as you build trust in that data and you know that the algorithms are working, then you’ll let that go. Probably with some backstops on the side, I’m going to let it go, but I’m [inaudible 00:09:52] just in case. And then you’ll start to optimize it more and more. And I think naturally, almost like a realtime data platform, operating system will start to evolve.

    Alan Shimel: So really the key there is trust.

    Tucker Callaway: Key is trust.

    Alan Shimel: To build trust in the next. So as the CEO, how do you build that trust?

    Tucker Callaway: Well, trust is always a tough.

    Alan Shimel: I’m interested, you tell me.

    Tucker Callaway: Yeah. I think like anything else in life, you deliver trust through consistent delivery. And so that’s where I think that human in the loop step is important. It has to be sustaining. It can’t be a moment in time, it can’t be the very first implementation. It’s something that you earn over time where people can count on you or could count on the data or count on the ways that you treat data to get you to the outcome that you want to go through. So it’s really only through the delivery of outcomes to the customer that they will trust the systems and all those things.

    Alan Shimel: Makes sense?

    Tucker Callaway: Yeah.

    Alan Shimel: All right. Got to do a little housekeeping.

    Tucker Callaway: Okay, let’s do it.

    Alan Shimel: People who want to know more about Mezmo.

    Tucker Callaway: Come to the website. We’ve got an offer out there to profile anyone’s data for free right now.

    Alan Shimel: Do you really?

    Tucker Callaway: Yeah. Come to mezmo.com or stop by our booth.

    Alan Shimel: M-E-Z-M-O.com.

    Tucker Callaway: M-E-Z-M-O.com

    Alan Shimel: Out there in TV land or if you hear a coupon.

    Tucker Callaway: Come by the booth. I forget the number, but it’s over there.

    Alan Shimel: You know what, if you look on the, I don’t have it. If you look on the back of your ID thing, you could actually look stuff up like that.

    Tucker Callaway: Yeah, it’s back there. If you connected to the wifi here at KubeCon, it’s Mezmo Data.

    Alan Shimel: I’ve noticed that.

    Tucker Callaway: Is the wifi.

    Alan Shimel: I was like, “Wow, what a cool thing.” Yeah.

    Tucker Callaway: You have see us. Come see us. Profile your data will give you insight and understanding into that and talk to you about the next steps.

    Alan Shimel: All right, check it out at Mezmo. Tucker, thanks.

    Tucker Callaway: Thanks for having me.

    Alan Shimel: Actually, we’ll see you. Are you going to be at AWS?

    Tucker Callaway: Yeah, we’ll be there. Yeah, I’ll be there. Yeah.

    Alan Shimel: We’ll be doing videos, not on the show floor. It’ll be a little quieter in a private suite. And then of course you’ll be at RSA.

    Tucker Callaway: We’ll be at RSA.

    Alan Shimel: We’ll be there as well.

    Tucker Callaway: We might not be on the show floor at AWS just because of-

    Alan Shimel: It’s a little crazy there isn’t it? A little pricey.

    Tucker Callaway: Yeah.

    Alan Shimel: Yeah, I hear you. That’s why we’ll be at the wind in the studio.

    Tucker Callaway: I’ll see you there.

    Alan Shimel: Come on up. I’ll have coffee.

    Tucker Callaway: Sounds good.

    Alan Shimel: But RSA will be at broadcast alley and we’ll be doing our DevSecOps thing on Monday. And the usual kind of RSA craziness.

    Tucker Callaway: Looking forward to it.

    Alan Shimel: Absolutely.

    Tucker Callaway: Okay.

    Alan Shimel: Check out Mezmo.com.

    Tucker Callaway: Thanks everybody.

    Alan Shimel: Tucker Callaway here on Tech Drunk TV. We’re going to take a break. I guess it’s almost lunchtime here, but it’s still busy.

    Tucker Callaway: Near enough.

    Alan Shimel: Stay tuned. We’re here all day. We’ll be back. Bye-Bye.

  • Observability: The Central Watchtower Your All-Seeing IT Needs

    Observability: The Central Watchtower Your All-Seeing IT Needs

    If there’s something you need to keep secure, it’s natural to want to keep it sealed away under lock and key. However, even keeping something in a vault, far from prying eyes and ill intent, may not be enough to offer peace of mind. After all, how can you have the peace of mind of knowing it’s safe if you don’t regularly check to ensure it hasn’t bolted, been burgled or broken down?

    Now, multiply the volume and value of things being monitored tenfold — and you get a sense of the daily inefficiencies and anxieties IT professionals battle.

    Instead of jewels, these teams safeguard, manage and maintain something far more valuable: The data that underpins everything from business transactions to system performance to threat detection to service delivery and beyond. To make matters more complicated, today’s digital ecosystems are more complicated, distributed and disparate than ever before.

    Databases are critical to managing a successful IT department — and it’s time to discard the widespread industry’s perception of them as an unknowable black box. To be sure, databases represent the most difficult component of the IT ecosystems to observe, tune, manage and scale. But the database isn’t a Magic 8 ball in terms of its internal processes; We no longer have to shake the mystery toy and accept one of the six answers it’s designed to spit out.

    The fact of the matter is that database specialists and IT teams need a clear view of database performance telemetry if they want any hope of maintaining the health, stability and scalability of their services.

    Observability Tools

    This is where observability tools can play a transformative role. Taking its cues from the all-seeing panopticon watchtower, observability eliminates the dark corners of the database dungeon by providing a comprehensive view across the full cloud-native, on-premises and hybrid technology stacks.

    The word panopticon derives from the Greek word panoptes, or “all-seeing.” The panopticon model features a central, lighted guard tower at the center of a circular room — allowing 360-degree lines of sight that allow the guards to observe every surrounding cell from a single, centralized vantage point.

    English philosopher Jeremy Bentham had no way of foreseeing the challenges of today’s database professionals when he first conceived of the panopticon in the 1700s. The concept would lay the blueprint for a prison system designed around one core concept: Enabling the minimum number of guards to effectively monitor the maximum number of inmates. Bentham’s system also works as a strategy for ensuring the health and performance of your organization’s critical databases.

    The panopticon was designed so that every cell could be monitored from one central point — ensuring not only better and more straightforward security but preserving resources in saved time, manpower and effort expended. Think of your ITOps, database, DataOps and DevOps teams as the wardens of your IT performance. Traditional monitoring can be likened to patrolling a traditional prison: Rows of cells facing out into a hallway that is patrolled on a schedule or used to spot and address misbehavior as it’s noticed.

    How can they be sure they’re focusing their efforts in the right place? Or trust that Cell Block A won’t stage a breakout while they’re breaking up an argument in Cell Block B?

    In short: They can’t. Odds are, the team is either running from outage to outage in an everlasting firefighting mode or relying on random spot checks for something as vital as the health of our IT systems.

    Observability, as opposed to monitoring, puts teams into that central panopticon watchtower, allowing them to not just see everything, but to see it within the context of the bigger picture. This comprehensive visibility and always-on observation enable IT teams to identify critical issues as they occur, even those caused by complex dependencies between the database, operating system, storage subsystem and network.

    Database Performance Issues

    Furthermore, database performance issues are a starting gun for costly bottlenecks or serious outages that can handcuff your company’s ability to compete or grow. Without complete and precise database monitoring and observability, IT operations struggle to accurately determine an application’s root cause of performance issues. This increases the risk of downtime, data loss and poor customer experiences.

    Discovering the root cause of performance issues is quite literally a system-critical undertaking, whether you’re simply running your enterprise, scaling your operations or deploying new code. Observability also offers teams the rare opportunity to get ahead of performance issues since you can see performance anomalies in advance of a service disruption rather than relying on real-time remediation.

    With traditional methods, DevOps and IT teams must manually analyze the data presented to them, correlate it to the problem, and locate the error before they can finally begin addressing it. In contrast, observability collects data to provide information on what’s not performing as expected and why. This allows teams to take a proactive approach to solving downtime and bottlenecks and proactively preventing them.

    In the software world, that translates directly to more time spent where it matters: Developing new business value within your applications and infrastructures, fueling innovation and exceeding customer expectations.

    Given how complicated the modern database has — and continues to — become, arming your enterprise with the right observability solutions can provide a boost to efficiency and performance and pardon your teams from a sentence to time-consuming, mundane and error-prone work.

  • Observability Leaders: The Mighty Minority Holding Their Own Against Outages

    Observability Leaders: The Mighty Minority Holding Their Own Against Outages

    The job of IT teams has become much harder thanks to the new realities of hybrid IT, with workflows occurring across on-premises and cloud-based networks and applications. Yet so much rests on your ability to respond to these challenges, all while managing the expectations of your customers and the health of your bottom line. With the growing complexity of ecosystems comes the need for better visibility, both into specific systems and across your entire stack.

    Observability solutions address this by providing visibility across your network, infrastructure, systems, application, database, digital experience and log monitoring.

    In other words, observability enhances your ability to observe your digital ecosystem with more transparency, more effective detection and more intelligent insights. Take, for example, the very timely and pressing issue of outages. On average, the typical business experiences nine brownouts or outages every month, lasting roughly twelve hours each and averaging $13.7M annually, according to new research we conducted at SolarWinds.

    Over the course of the year, that can add up to nearly 1,300 hours, with outages chipping away at your organization’s productivity, reputation and competitive edge.

    It’s not enough to monitor for these outages and address them once they take down your systems. Repeated or prolonged outages signify a gap in the enterprise’s ability to comprehensively monitor and understand its network’s internal state and performance. A robust observability strategy can preemptively detect anomalies and potential issues—before they become full-blown outages.

    According to new data from the 2023 IT Trends Survey released this month by SolarWinds, companies who’ve embraced observability tend to not only lead in detecting, remediating and preventing outages—they’re experiencing better business and IT outcomes, too.

    The technology professionals surveyed shared how observability is helping them achieve better performance, compliance and resilience in digital environments—and how you can follow their lead.

    Observability Drives Better Business Outcomes

    The observability leaders surveyed were 300% more likely to say their organization is doing extremely well with growing revenue and 250% more likely to say the same about their organization’s speed of innovation. Interestingly, they also reported a better employee experience: They were 388% more likely to rate their organization as doing “extremely well” with employee experience and also reported fewer and smaller skill gaps on their teams.

    So, how does embracing observability actually translate into better business outcomes? According to the data, observability leaders are…

    • Investing in top priorities: Data shows organizations using observability solutions to support the priorities most critical to their growth and success: Improve their customer experience (96%), enable faster innovation (71%), reduce time spent solving (71%) and detecting (60%) issues and increase operational efficiency (55%).
    • More automated and integrated: Observability leaders embracing automation and investing in tools that provide enhanced efficiency are 214% more likely to say they are doing extremely well with operational efficiency, 750% more likely to say they are doing extremely well with auto-remediation of complex alerts and 300% better at automatically collecting background diagnostic data for IT support staff.
    • Ahead on IT: The data found that those ahead of the curve on observability are also leading by huge margins when it comes to monitoring, detecting and resolving issues that could otherwise bring the business to a screeching halt. When it comes to IT, they are 233% better at auto-escalation of tickets, 213% better at auto-remediation of simple alerts and 36% better at settling alert levels based on historical behavior.

    How to Reap Observability Benefits in Your Organization

    All told, observability adoption is still in its early days. Only 1% of enterprises are already up and running using observability tools on a regular basis, while another third are undergoing the implementation process.

    That’s good news for other businesses who are ready to reap the rewards—it’s not too late to be an observability pioneer.

    If you’re interested in bringing observability to your own organization, start by addressing a few important factors that can help you sidestep challenges—such as the accelerating pace of change in technology (72%) or insufficient budget (58%)—that might otherwise obfuscate your observability opportunities:

    • Make sure your observability solutions are appropriate for multi-cloud environments: Multi-cloud environments have become standard for many companies because of the many upsides, but they can be challenging for IT teams to manage. Strategically accelerate your organization’s cloud migration with an observability solution designed for complex hybrid and multi-cloud environments​ to save a lot of headaches down the road.
    • Give your teams autonomy—and build toward autonomous operations: Observability brings your enterprise a step closer to autonomous operations. Autonomous operations, where IT systems can govern themselves, providing a proactive approach to addressing issues, rather than reactive, won’t replace your human teams but rather free up their time and brainpower to support the business and drive innovation.
    • Don’t ignore the database: Databases represent the most difficult ecosystems to observe, tune, manage and scale. They require significant computing power, tend to be memory-intensive and likely make up the bulk of your organization’s cloud spending. Tasks crucial to the health and functionality of your business—including troubleshooting, root cause analysis and remediation—simply cannot happen without full, transparent observability across the numerous resources a database needs to engage to do its job.

    Observability helps balance competing priorities and demystify application requirements while increasing your overall DevOps agility, efficiency and speed to market. Observability not only fosters transparency and collaboration but also encourages a system of ongoing review, which benefits the organization, IT teams and—crucially—your customers.

  • Survey Surfaces Major Observability Challenges

    Survey Surfaces Major Observability Challenges

    A recent survey found the biggest obstacles to observability were the pace of technology change, IT blind spots and the complexity of modern applications. The survey polled 300 IT professionals to identify the biggest challenges they faced in achieving observability. The accelerating pace of technology change (72%) topped the list, followed by IT blind spots and the growing complexity of modern applications (58% each), and lack of funding (52%).

    The survey, conducted by SolarWinds, also found the typical enterprise suffered nine brownouts or outages every month, each of which lasted around twelve hours. The full cost of outages and brownouts averaged $13.7M annually for these enterprises, according to the SolarWinds report.

    Jeff Stewart, field CTO and vice president, global solutions engineering at SolarWinds, said the survey makes it clear that a lack of observability is having a material impact on businesses. Organizations are now moving beyond monitoring predefined metrics to embrace observability platforms that make it simpler to investigate the root cause of issues that adversely impact businesses; these businesses are more dependent on IT than ever, he added.

    In fact, the primary reason organizations are investing in observability is to improve their customer experience (96%), enable faster innovation (71%), reduce time spent solving (71%) and detecting (60%) issues and improve operational efficiency (55%), the survey found.

    While it’s still early days as far as achieving observability is concerned, a lot of progress is starting to be made as organizations realize that complex IT environments require a different management approach. IT teams can no longer afford to navigate multiple monitoring tools in what often turns out to be a vain effort to prevent brownouts and downtime, noted Stewart.

    In addition, many IT teams are becoming increasingly aware that the telemetry data collected via an observability platform provides the foundation for infusing IT operations with artificial intelligence (AI) capabilities, he added. The ultimate Holy Grail is to one day achieve autonomous operations, noted Stewart.

    There is, of course, no shortage of observability platforms, but Stewart contends that providers of monitoring tools such as SolarWinds are in the best position to help IT teams make the observability transition. Rather than ripping and replacing a monitoring platform, a more seamless transition that results in less disruption is preferable, he noted.

    Regardless of approach, observability platforms that enable IT teams to launch queries across complex distributed computing environments are becoming a necessity. Distributed computing environments often have more dependencies than IT teams can manually track. It’s only a matter of time before the most talented DevOps professionals start to migrate to organizations that provide them with the management tools and platforms required to succeed. Otherwise, the stress of managing a complex IT environment will only result in higher rates of burnout among DevOps professionals.

    It may be a while before observability platforms are pervasively employed across IT environments, but as it becomes clear that brownouts and downtimes result in a decline in revenue, business leaders will understand what’s required to maximize profits. In many cases, the answer will be an observability platform that surfaces the insights needed to proactively manage modern IT environments.

  • New Relic Taps Generative AI to Simplify Observability

    New Relic Taps Generative AI to Simplify Observability

    New Relic has added a tool that takes advantage of generative artificial intelligence (AI) to make it simpler to query the telemetry data collected by its observability platform via a natural language interface (NLI).

    Jemiah Sius, director of developer relations for New Relic, said New Relic Grok will make the New Relic One platform more accessible to a wider range of IT professionals, especially those that haven’t mastered New Relic’s proprietary programming language that enables DevOps teams to identify the root cause of an issue.

    New Relic Grok automatically pinpoints code-level errors in integrated development environments (IDEs) in addition to analyzing code, stack traces and production telemetry to suggest fixes. New Relic is providing this capability via integration with the large language models (LLMs) created by OpenAI, which is providing the foundation for a broad range of generative AI capabilities through Microsoft. New Relic has a long-standing alliance with Microsoft, added Sius.

    Using plain language, anyone can generate a system or app health report complete with anomalies, issues and recent deployments in a way anyone can understand without having to create and filter dashboards, he noted.

    New Relic Grok also makes it simpler to identify instrumentation gaps that can then be addressed using the instructions it provides. It can also set up missing alerts and automate alerts using the open source Terraform infrastructure-as-code (IaC) tool.

    Finally, IT teams can also use New Relic Grok to manage accounts, users and user access, data retention rules, usage, billing and other administrative tasks.

    New Relic previously invested in machine learning algorithms to automate observability tasks. These AI extensions to the New Relic platform are part of a larger effort to extend the reach of the New Relic One observability platform further left toward developers and IT administrators rather than just site reliability engineers (SREs), said Sius.

    However, New Relic doesn’t anticipate that generative AI will eliminate the need for SREs to use its programming tool to solve more complex problems, he added.

    The overall goal is to provide development teams with frictionless access to observability data at every stage of the software development life cycle to reduce mean-time-to-detection (MTTD) and mean-time-to-resolution (MTTR) of issues.

    In general, most organizations are still in the early stages of achieving full-stack observability. A recent New Relic survey found only 27% of respondents have achieved full-stack observability and only 5% claimed they have a mature observability practice in place. A third (33%) of respondents also said they still primarily detect outages manually or based on complaints, the survey found. On the plus side, the survey also found nearly three-quarters of respondents said C-suite executives in their organization are advocates of observability, and more than three-quarters of respondents (78%) saw observability as a key enabler for achieving core business goals. However, more than half (52%) of respondents said they experienced high-business-impact outages once per week or more and 29% said they take more than an hour to resolve those outages.

    AI, of course, promises to improve reliability. At the very least, it could make it easier to identify issues long before a major disruption occurs.

  • Mezmo Adds Free Community Plan for Managing Observability Data

    Mezmo Adds Free Community Plan for Managing Observability Data

    Mezmo this week added a free trial and a community plan for the Mezmo Telemetry Pipeline service to make it simpler for DevOps teams to store and manage the large amounts of telemetry data they are collecting.

    Mezmo CEO Tucker Callaway said as more DevOps teams embrace observability to minimize disruptions to application environments, they are struggling to manage the explosion of data being created. The Mezmo platform makes it possible to apply data engineering best practices to manage that data using a set of drag-and-drop visual tools, he added. A set of data transformation tools also makes it simpler to extract metrics embedded in the logs, summarize events and metrics and then forward those metrics to downstream platforms for analysis.

    The free edition of the platform makes it possible for organizations to begin to apply those capabilities without any upfront costs required, noted Callaway.

    It’s not clear to what degree DevOps teams may need to add data engineering to manage all the telemetry data being collected. It’s already apparent that the cost of storing and managing all that data is becoming a significant issue as more applications are instrumented. In fact, it’s nearly impossible to manage cloud-native applications without being able to observe interactions between the microservices used to construct them.

    Log management has always been a challenge, but with the addition of traces, the amount of telemetry data being collected to surface metrics has increased. The Mezmo platform makes it possible to set a daily or monthly hard limit on the volume of logs stored or, alternatively, set soft daily or monthly quotas that can apply throttling logic to ensure mission-critical log data will continue to flow.

    DevOps teams can also make use of soft limits to reallocate storage resources from one team to another based on how much log data might be generated for a specific amount of time.

    Reducing storage costs has naturally become a higher priority during challenging economic times, so there’s a lot more pressure for DevOps teams to be more efficient. Finance teams are reducing costs by, for example, applying quotas to the amount of storage resources being made available to individual DevOps teams. The days when cloud storage resources were made available indiscriminately are over.

    It’s not clear how quickly DevOps teams are embracing observability, but it is certain that relying on predefined metrics to monitor IT environments is no longer sufficient. DevOps teams need to be able to query telemetry data to, for example, identify bottlenecks that are often created by dependencies between microservices. The issue is striking a balance between the amount of data being collected and the cost of storing it all.

    Regardless of approach, observability is rapidly becoming a requirement for DevOps teams to succeed. In fact, there is already no shortage of observability platforms to choose from. The issue is that not every observability platform provider is equally concerned about the cost of storing all the data being collected.

  • New Relic Adds Module to Surface Code Metrics

    New Relic Adds Module to Surface Code Metrics

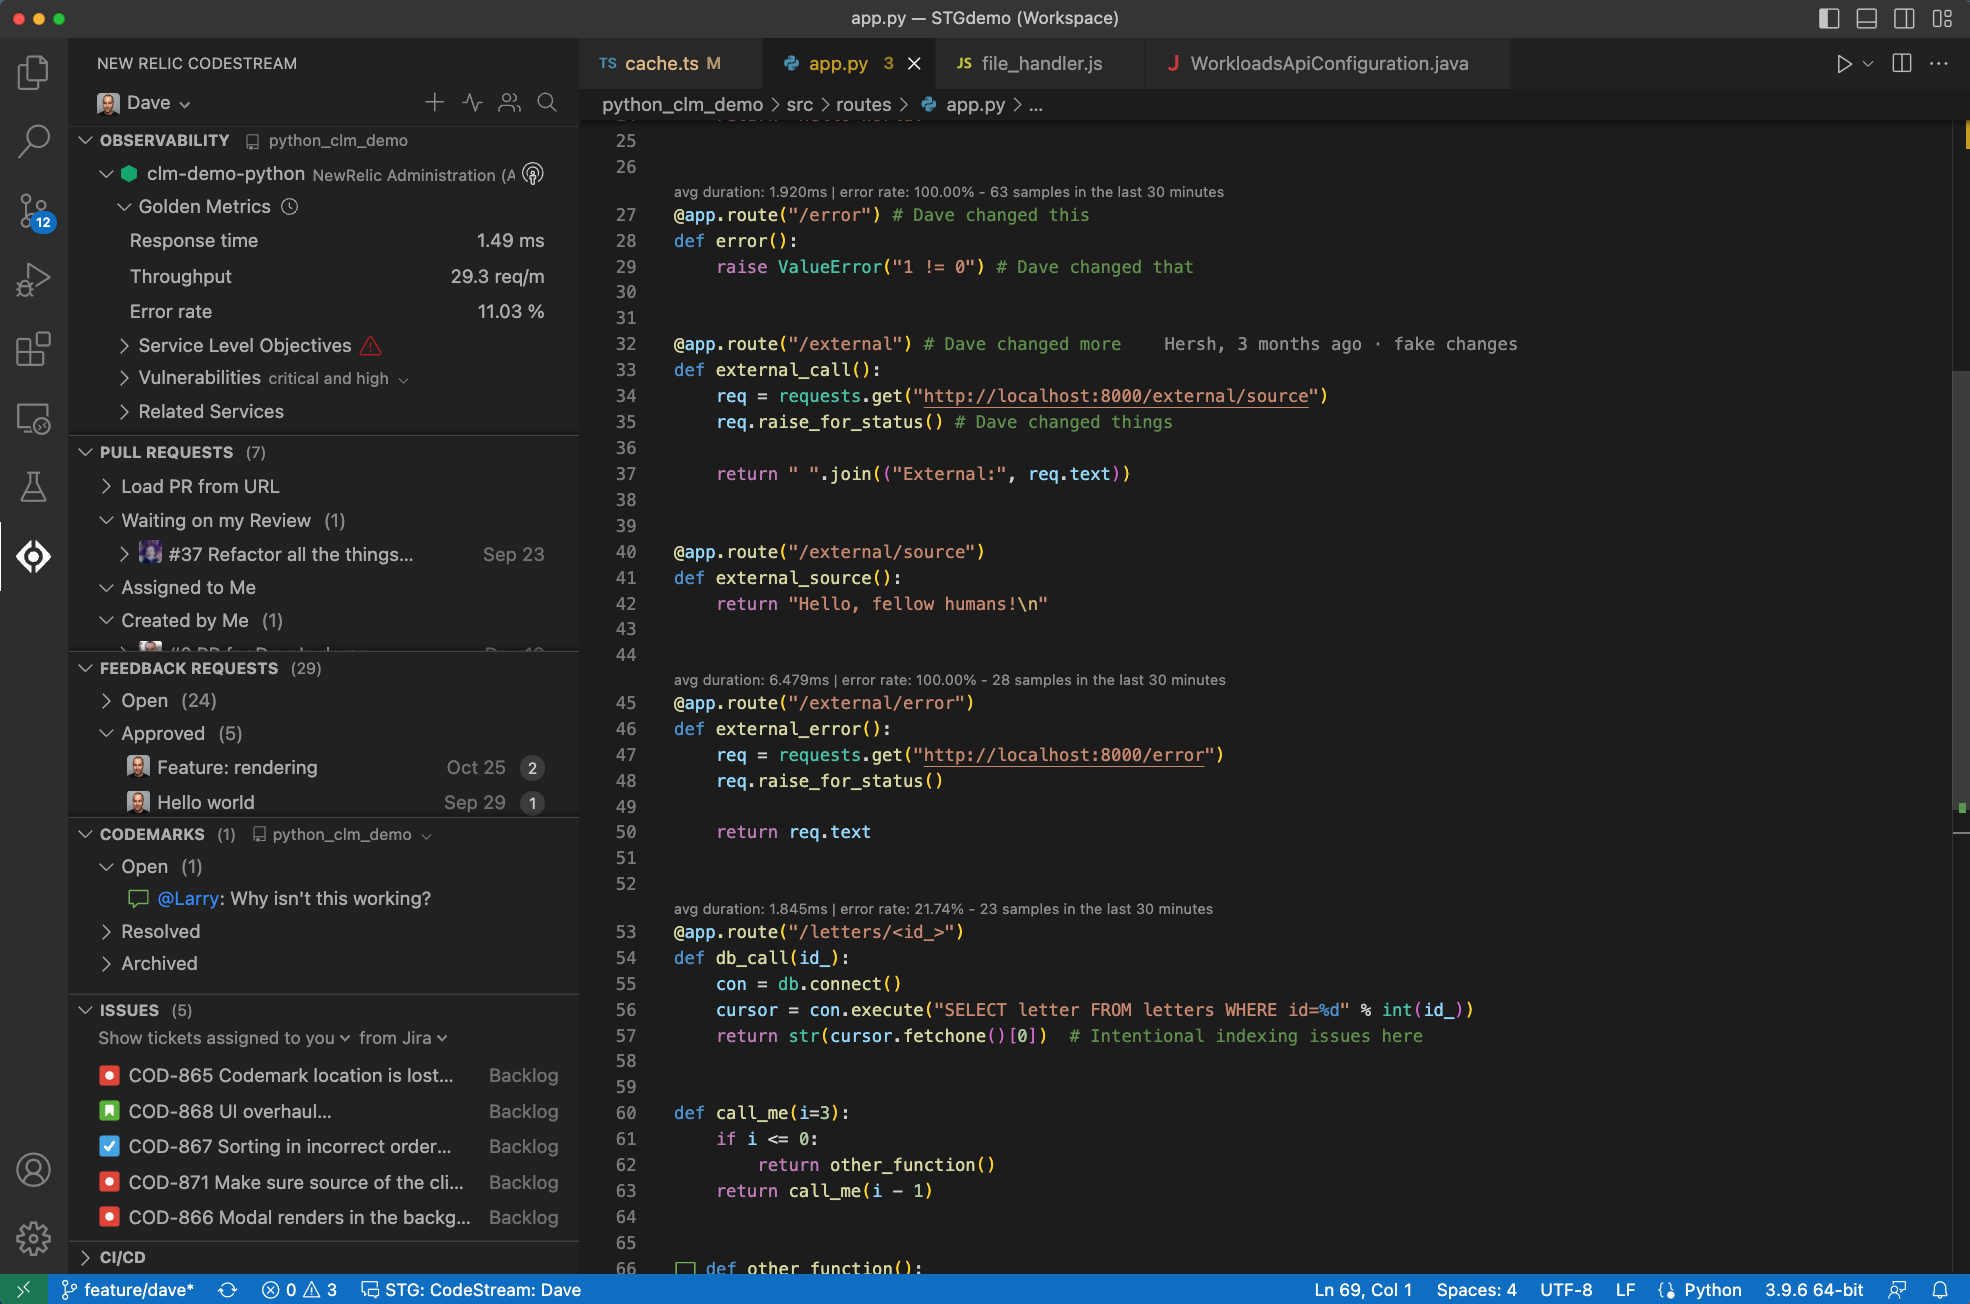
    New Relic today added a free CodeStream module to its observability platform to give developers access to metrics and telemetry data that will enable them to write higher-quality code faster.

    Peter Pezaris, group vice president and general manager of strategy and experience for New Relic, said this capability is part of an effort to shift observability left toward developers to optimize code as it is written and after it is deployed.

    CodeStream surfaces metrics and telemetry data within the integrated development environment (IDE) developers use to write software. Telemetry metrics are displayed as a line of text above the code or in the debugging tool used to troubleshoot an application. Alternatively, developers can view metrics via an observability panel at the service level. They can also view performance metrics such as error rates and response times for related services.

    That approach eliminates the need to wait for IT operations teams to surface issues that usually don’t manifest until long after the code in question was originally developed, noted Pezaris.

    The overall goal is to provide development teams with frictionless access to observability data at every stage of the software development life cycle, he added. That analysis capability will result in faster mean-time-to-detection (MTTD), mean-time-to-resolution (MTTR) and, ultimately, shorter development cycles, said Pezaris.

    Organizations should also be able to reduce technical debt faster by making it easier to identify issues that, for example, adversely impact application performance, he noted. That activity can be especially challenging because developers often inherit code written by someone else that often lacks clear documentation. CodeStream makes it simpler to onboard a developer to any application modernization initiative that has been launched to reduce technical debt, said Pezaris.

    A recent New Relic survey found only 27% of respondents have achieved full-stack observability, and only 5% claimed they have a mature observability practice in place. A third (33%) of respondents also said they still primarily detect outages manually or based on complaints, the survey found.

    On the plus side, the survey also found nearly three-quarters of respondents said C-suite executives in their organization are advocates of observability, and more than three-quarters of respondents (78%) saw observability as a key enabler for achieving core business goals. However, more than half (52%) of respondents said they experienced high-business-impact outages once per week or more, and 29% said they take more than an hour to resolve those outages.

    A full 82% of respondents said they use four or more tools to monitor the health of their systems. Only 7% said their telemetry data is entirely unified and only 13% said the visualization or dashboarding of that data is entirely unified. Nearly half of the respondents (47%) said they would prefer to have a single, consolidated observability platform, but only 2% said they currently used one tool for observability.

    Regardless of the approach to observability, it is clear that development and IT operations teams need to be looking at the same metrics and telemetry data at the same time to collaborate effectively.

  • Cribl Simplifies Telemetry Data Analytics

    Cribl Simplifies Telemetry Data Analytics

    Cribl today announced general availability of a search capability that makes it simpler to query observability data where it resides without having to first collect and centrally store it.

    Nick Heudecker, senior director for market strategy for Cribl, said Cribl Search makes it possible to analyze telemetry data at its point of origin or when it is stored in a low-cost object storage platform to minimize costs.

    As the volume of telemetry data being collected continues to grow, DevOps teams are struggling with ingesting it all. Cribl takes advantage of a platform it created to stream and normalize the collection of telemetry data. Cribl Search adds the ability to also query that data at the endpoint where it resides, said Heudecker.

    While observability has always been a core tenet of DevOps, achieving it has been a major challenge. In addition to deploying and managing agent software to instrument IT environments, there’s a significant amount of time and effort required to set up the pipelines necessary to transfer data to a platform for storage and analysis. The more data is collected, the greater storage costs become. Cribl is making a case for automating those tasks using a tier of software that abstracts data into a format that can be more easily collected and analyzed.

    In general, observability is emerging as the next logical evolution of continuous monitoring. Existing monitoring tools enable DevOps teams to track specific pre-defined metrics. Observability platforms are intended to make it easier to query telemetry data to discover the root cause of an issue that is not being tracked by a set of pre-defined metrics.

    It’s not clear yet whether IT organizations perceive observability to be an evolution of monitoring or a distinctly separate but complementary capability, but it’s apparent IT teams need a lot more context than they have historically been able to attain using legacy monitoring tools. Each platform used within an enterprise typically comes with its own monitoring tools that are used by the IT teams tasked with managing it. Whenever there is an issue, it’s not uncommon for DevOps teams to spend hours correlating data from multiple tools to ascertain the root cause of a problem. Observability platforms promise to reduce that time and effort by applying analytics to data collected from multiple platforms. The challenge is finding a way to efficiently collect all that data, which in the past has often required a data engineer to build a pipeline spanning multiple sources of telemetry data.

    One way or another, observability platforms should make it easier for DevOps teams to manage IT issues more proactively. The goal, as always, is to identify issues before they cause a major disruption. In that sense, it may be difficult to prove the ROI of deploying an observability platform. However, the best IT incident is always going to be the one that never happened or, at the very least, never escalated to a level of noticeable disruption.