For a long time, monitoring just meant staring at dashboards and waiting for something to flash red. Engineers tracked things like CPU usage, memory, response times, error rates, and uptime. If a number crossed a certain line, you’d get an alert. Then, someone dived in to figure out what was wrong.
That basic approach isn’t useless, but it’s just not enough anymore. Today’s systems are way more complicated. Apps run across containers, Kubernetes clusters, cloud services, databases, APIs, queues, and all sorts of third-party services. A single user’s request might hop through dozens of different pieces just to finish. Simply knowing “something broke” isn’t helpful. You need to find out why it happened and what’s actually affected.
This is where observability steps in.
Monitoring Just Says Something’s Wrong
Traditional monitoring works fine when you already know where things can break. You set a threshold, collect some numbers, and get pinged when something’s outside the expected range.
Take CPU usage as an example. Say you trigger an alert when it’s over 80% for a few minutes. Okay, you know something needs attention, but what does that really tell you? Not much about why the CPU is so busy. Maybe you just shipped some inefficient code. Maybe you got hit with more traffic. Or another service is hammering this one. Or the database got slow and requests are piling up.
Monitoring gives you a starting point, but someone still needs to play detective.
Observability goes further. Instead of just measuring obvious problems, it helps you dig into unfamiliar and weird issues. It’s about piecing together what’s really happening based on the clues the system gives off. OpenTelemetry describes it as making systems understandable through their outputs and letting you figure out why something’s happening, not just that it is.
That difference starts to matter when everything’s spread out over dozens of services.
Logs, Metrics and Traces Are Only the Start
Everyone talks about the “three pillars” of observability: logs, metrics and traces.
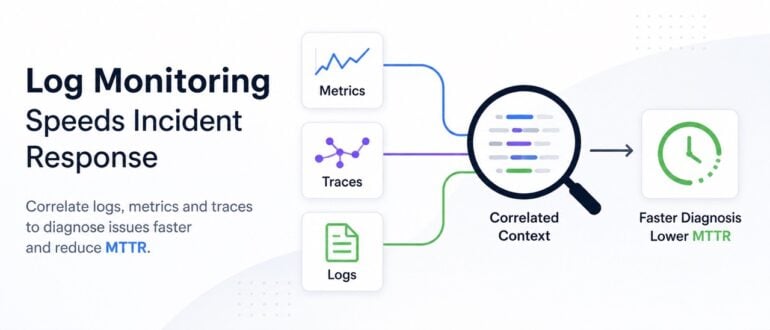
Metrics are numbers that sum up how the system’s behaving. Logs record the blow-by-blow of what happened. Traces follow a request as it weaves through different services.
These are all pieces of the story.
A metric might tell you latency just shot up. A trace shows most of the delay is in a database call. The logs spell out that a certain query keeps timing out.
The real value? Connecting these dots, instead of just staring at them in isolation.
That’s one reason OpenTelemetry is getting so much attention. It lets you collect and connect telemetry across systems, without being locked into one monitoring tool.
Collecting data isn’t the point. Making it useful is.
Drowning in Alerts
More telemetry sounds great until your phone blows up with thousands of alerts.
This is a classic pain point with traditional monitoring setups. You can be fantastic at catching odd behavior and still be useless at showing people what actually matters.
Imagine ten different services rely on the same database. The database slows down, and suddenly every single service starts yelling for help at once.
One root problem snowballs into ten fake crises.
That’s alert fatigue. Engineers just tune out because half the noise is symptoms, not causes.
Modern observability should do more than just fire off alerts. It should help untangle what’s connected: events, services, deployments, dependencies and infrastructure changes, all woven together.
Instead of just saying “ten services have errors,” you want to know: Are these problems related? That’s the real question.
Moving Past Dashboards
Dashboards aren’t going away. Engineers still need a visual to spot patterns and get an overview.
But there’s a shift happening behind the dashboards. Modern observability ties together telemetry from everywhere, so you can see not just what’s failing, but the broader context. Say latency goes up. You see not only which service is affected, but also the build that was deployed a few minutes before, the downstream dependency and the trace showing exactly where time is being eaten up.
So instead of wasting half an hour gathering info from five tools, an engineer starts with a clearer picture. You cut straight to what changed and where to look first.
Observability is shifting. Less watching, more understanding.
AI Changes the Game
Artificial intelligence is speeding up this change.
There’s simply too much telemetry for humans to comb through line by line. AI helps sift the mountains of logs, traces, and metrics, surfacing connections or oddities that would take hours to spot otherwise.
Picture a production service dragging its feet. AI-powered systems can instantly scan recent deployments, traces, infra tweaks, database health, error waves, you name it. Instead of just saying “latency increased,” the system points to likely causes, with evidence in hand.
Engineers still make the final call, but they start the hunt in the right place.
And this isn’t just a nice-to-have for AI apps. It’s required. Projects like OpenTelemetry are adding new hooks to track things inside LLM-powered apps—model calls, token usage, tool calls, and so on—so you’re not left guessing what went wrong inside the “black box.”
AI Apps Need Their Own Observability
Classic apps are sort of predictable. A database error? There’s a log. A crash? There’s a stack trace.
AI apps don’t play by those rules. An AI agent can ping multiple models, grab info from a database, call a bunch of tools, try again if it’s not happy, and finally spit out an answer. All without any “normal” errors. Sometimes the result stinks, but you have no obvious clues.
So observability gets even more important. You need to see which model was used, how long each call took, how many tokens flowed through, which external tools were called, and where the delays happened. OpenTelemetry’s work here isn’t just for show. It’s exactly the kind of telemetry teams need to debug these new problems.
For DevOps, observability is breaking past infrastructure and app code. You now have to track how the AI itself behaves.
Don’t Forget CI/CD
Observability isn’t just about production.
CI/CD pipelines are systems, too, with their own headaches. One pipeline can touch source control, build servers, security scans, artifact repositories, containers, deploy tools, cloud infrastructure, and test suites.
If your pipeline slows down, just knowing a build “took longer” doesn’t help. You need to know which stage stalled, whether a dependency changed, if a test is acting flaky, or if some external service dragged its feet.
OpenTelemetry is also moving into CI/CD, aiming to standardize pipeline telemetry so teams can get a handle on delivery changes, not just production issues.
That means DevOps teams can gain visibility further left in their delivery pipeline, not just after code hits production.
Observability Is a DevOps Practice
You can’t just bolt observability onto an app after it’s built.
It needs to be part of development from the beginning.
Developers should pay attention to what telemetry their code creates. Teams should agree on which metrics matter, how to trace requests, and how to give enough context so you can follow a user journey, even if it jumps across five services. Key events should tie back easily to deployments and infrastructure tweaks.
The earlier you build this in, the easier it is to troubleshoot when things go sideways in production.
Good observability isn’t about drowning in data. It’s about collecting the right pieces to help engineers solve real problems, fast.
Let’s Talk Costs
Here’s one thing you can’t ignore. Telemetry isn’t free.
As systems grow, logs, traces, and metrics pile up quickly. Storing everything forever is a non-starter.
Teams have to decide what to collect, how much detail is really needed, how long to keep it, and what info actually matters when you’re trying to solve a problem.
Observability needs discipline. If you keep everything “just in case,” you don’t solve operational problems. You just end up with an expensive data mess.
The smart move? Focus on valuable signals, set sensible retention policies, sample where you must, and make it clear who owns what telemetry.
The Human Engineer Still Matters
It’s tempting to imagine that fancy AI-powered observability will make engineers obsolete.
Not going to happen.
Production systems are messy because business is messy. Automation might spot a technical link, but engineers still have to judge the bigger impact and the safest way to respond.
A traffic spike could be a meltdown. Or just the result of a killer marketing campaign.
That “bad” database query? Fixing it in the middle of the busiest hour could cause more harm than good.
Context is everything.
AI can speed up investigations, but you still need human experience and judgment.
The Future: Observability 2.0
Observability isn’t just about prettier dashboards.
The real leap is creating a connected, living view of your whole system. Infra, applications, databases, networks, pipelines, cloud, and even AI workloads all linked together.
That’s why standards like OpenTelemetry are a big deal. They make it easier for every part of your stack to work together, without getting married to a single vendor.
The direction is clear. We’re going from passively watching for fires to actively understanding what makes the system tick.
What’s the Real Goal?
It’s not about creating endless dashboards or blasting out more alerts.
It’s about cutting down the time engineers waste asking, “What happened?”
A solid observability setup helps you see what changed, where it changed, why, what’s affected, and what to look at next.
That’s a big leap beyond old-school monitoring.
As software grows more complex and AI becomes part of production, actually understanding your system’s behavior matters just as much as keeping it running.
The teams that master this won’t just know when something broke. They’ll have the insight to respond fast, make smart decisions, and, most importantly, learn from it.
That’s the direction observability is heading.
Less watching, more true understanding.