Tag: observability

  • Observe Inc. Brings Generative AI to Observability

    Observe Inc. Brings Generative AI to Observability

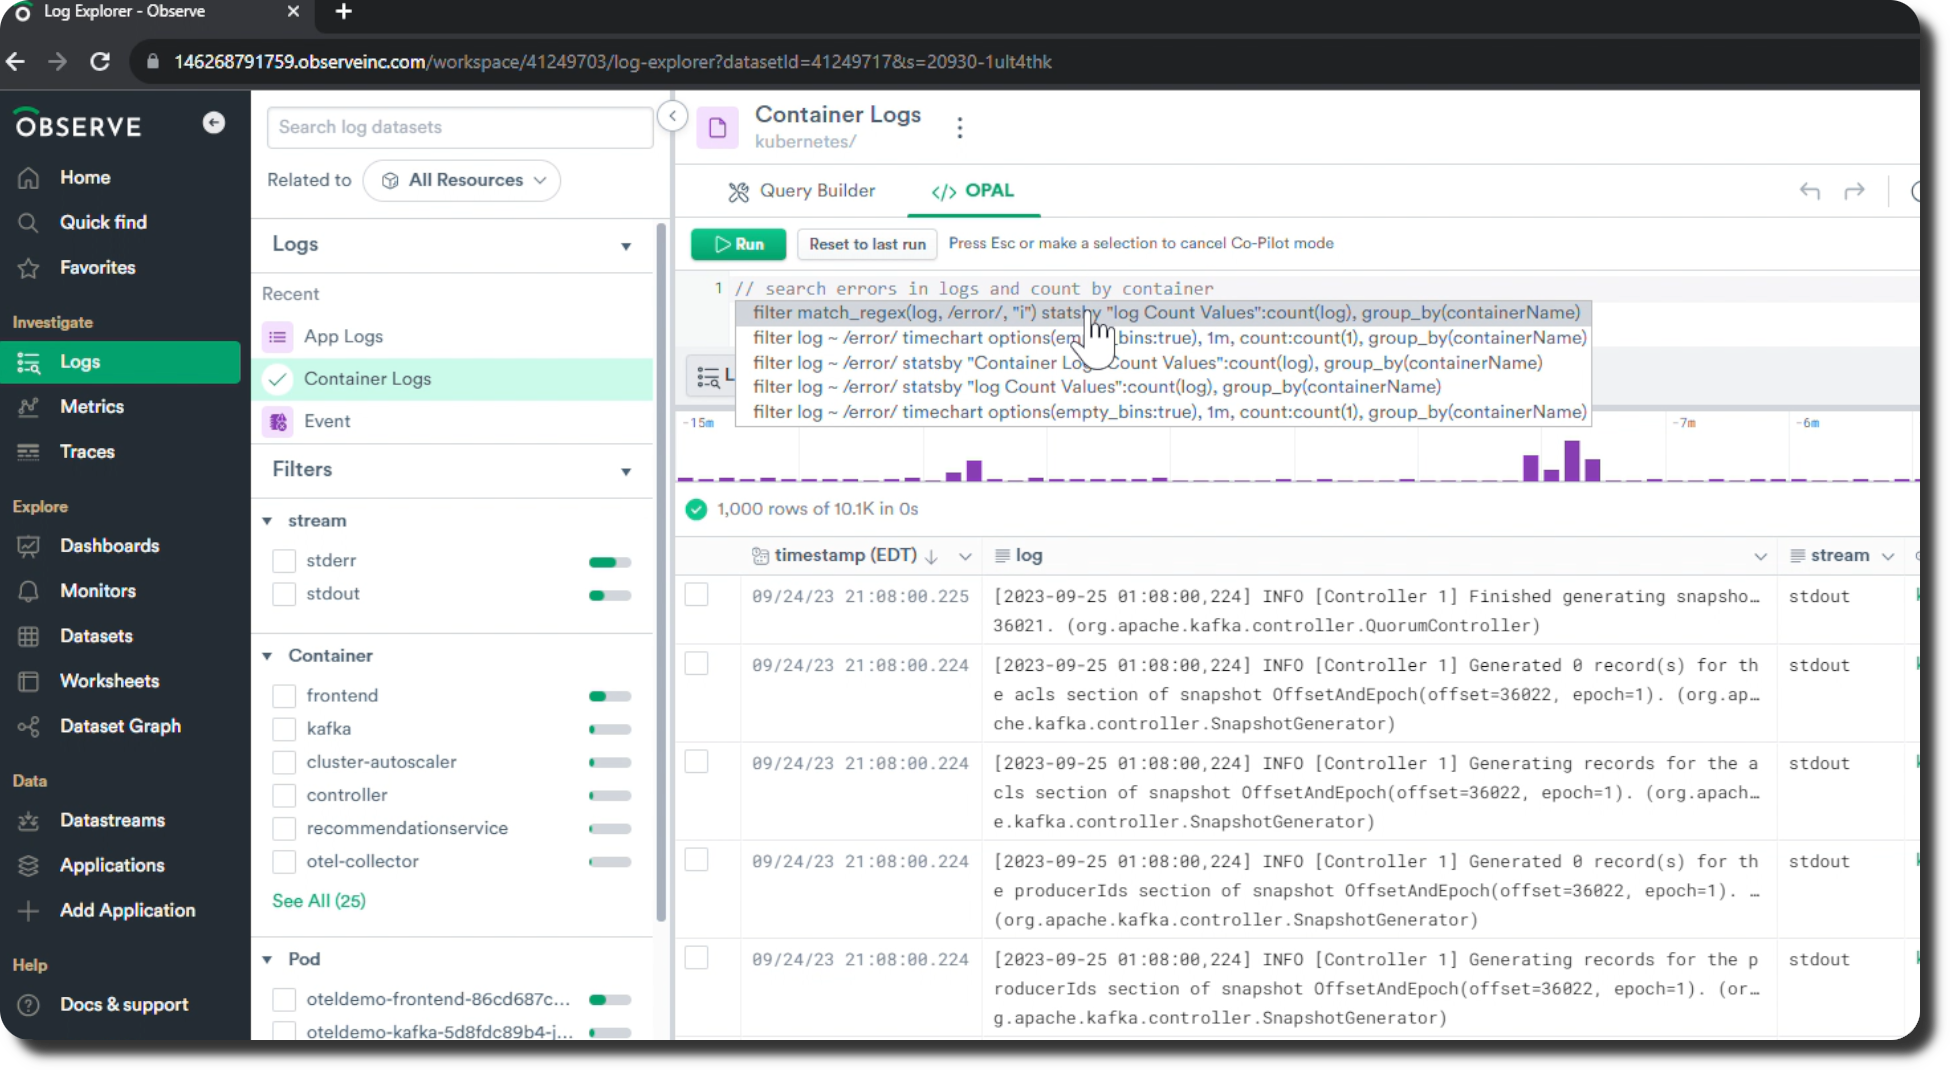
    Observe, Inc. today revamped the Hubble user interface to its observability platform that has been infused with generative artificial intelligence (AI).

    Fresh from raising an additional $50 million in funding, Observe CEO Jeremy Burton said as the company’s software-as-a-service (SaaS) platform continues to be infused with AI using multiple large language models (LLMs), it’s becoming apparent that observability is rapidly becoming democratized.

    Most IT organizations still rely primarily on legacy monitoring tools to track a set of predefined metrics. Observability platforms have arisen to aggregate metrics, logs and traces to enable DevOps teams to launch queries and surface the root cause of performance issues or IT incidents. The challenge is that most observability platforms have required IT teams to master a proprietary query language such as Observe’s RegEx.

    However, with the rise of generative AI tools, it is now possible for IT professionals of all skill levels to employ a natural language chatbot to generate a RedEx query, noted Burton. A RegEx generation tool also parses data to add structure to logs on-the-fly, and there is also an OPAL Co-Pilot that generates OPAL code in response to natural language inputs.

    Observe

    The Hubble interface furthers those capabilities by simplifying the onboarding experience anytime there is a new member added to an IT team, he added. Hubble also expands the range of data access options available, including a public application programming interface (API), a command line interface (CLI), export to CSV and data sharing to the Snowflake cloud platform.

    IT teams are also coping with an explosion of telemetry data generated by modern distributed applications based on microservices architectures. Legacy observability and monitoring tools were not designed for these data volumes, so when there is an incident, the mean-time-to-resolution (MTTR) is increasingly extended. In contrast, the Observe platform now features a ‘Live’ mode that enables data to be queried in 20 seconds or less from when it was created.

    Other capabilities include an assistant embedded in Slack to help users troubleshoot issues and summarize threads for incident response.

    While it’s still early days as far as the adoption of observability platforms are concerned, there is already no shortage of options. The pending acquisition of Splunk by Cisco next year will cause more organizations to reevaluate their IT management options, so the pace at which organizations are transitioning to cloud-hosted observability platforms should increase, noted Burton. Even after the merger is completed, it might be several more months before Cisco integrates its AppDynamics platform with the observability platforms that Splunk added to its IT operational analytics platform, he added.

    In the meantime, IT environments are only going to become more complex. It won’t be feasible for most IT teams to manage highly distributed computing environments without some help from AI. The challenge, as always, will be finding the budget dollars needed to deploy an observability platform before the number of increased IT incidents makes the need for one painfully obvious.

  • Digma Leverages ML to Bring Observability Insights to IDEs

    Digma Leverages ML to Bring Observability Insights to IDEs

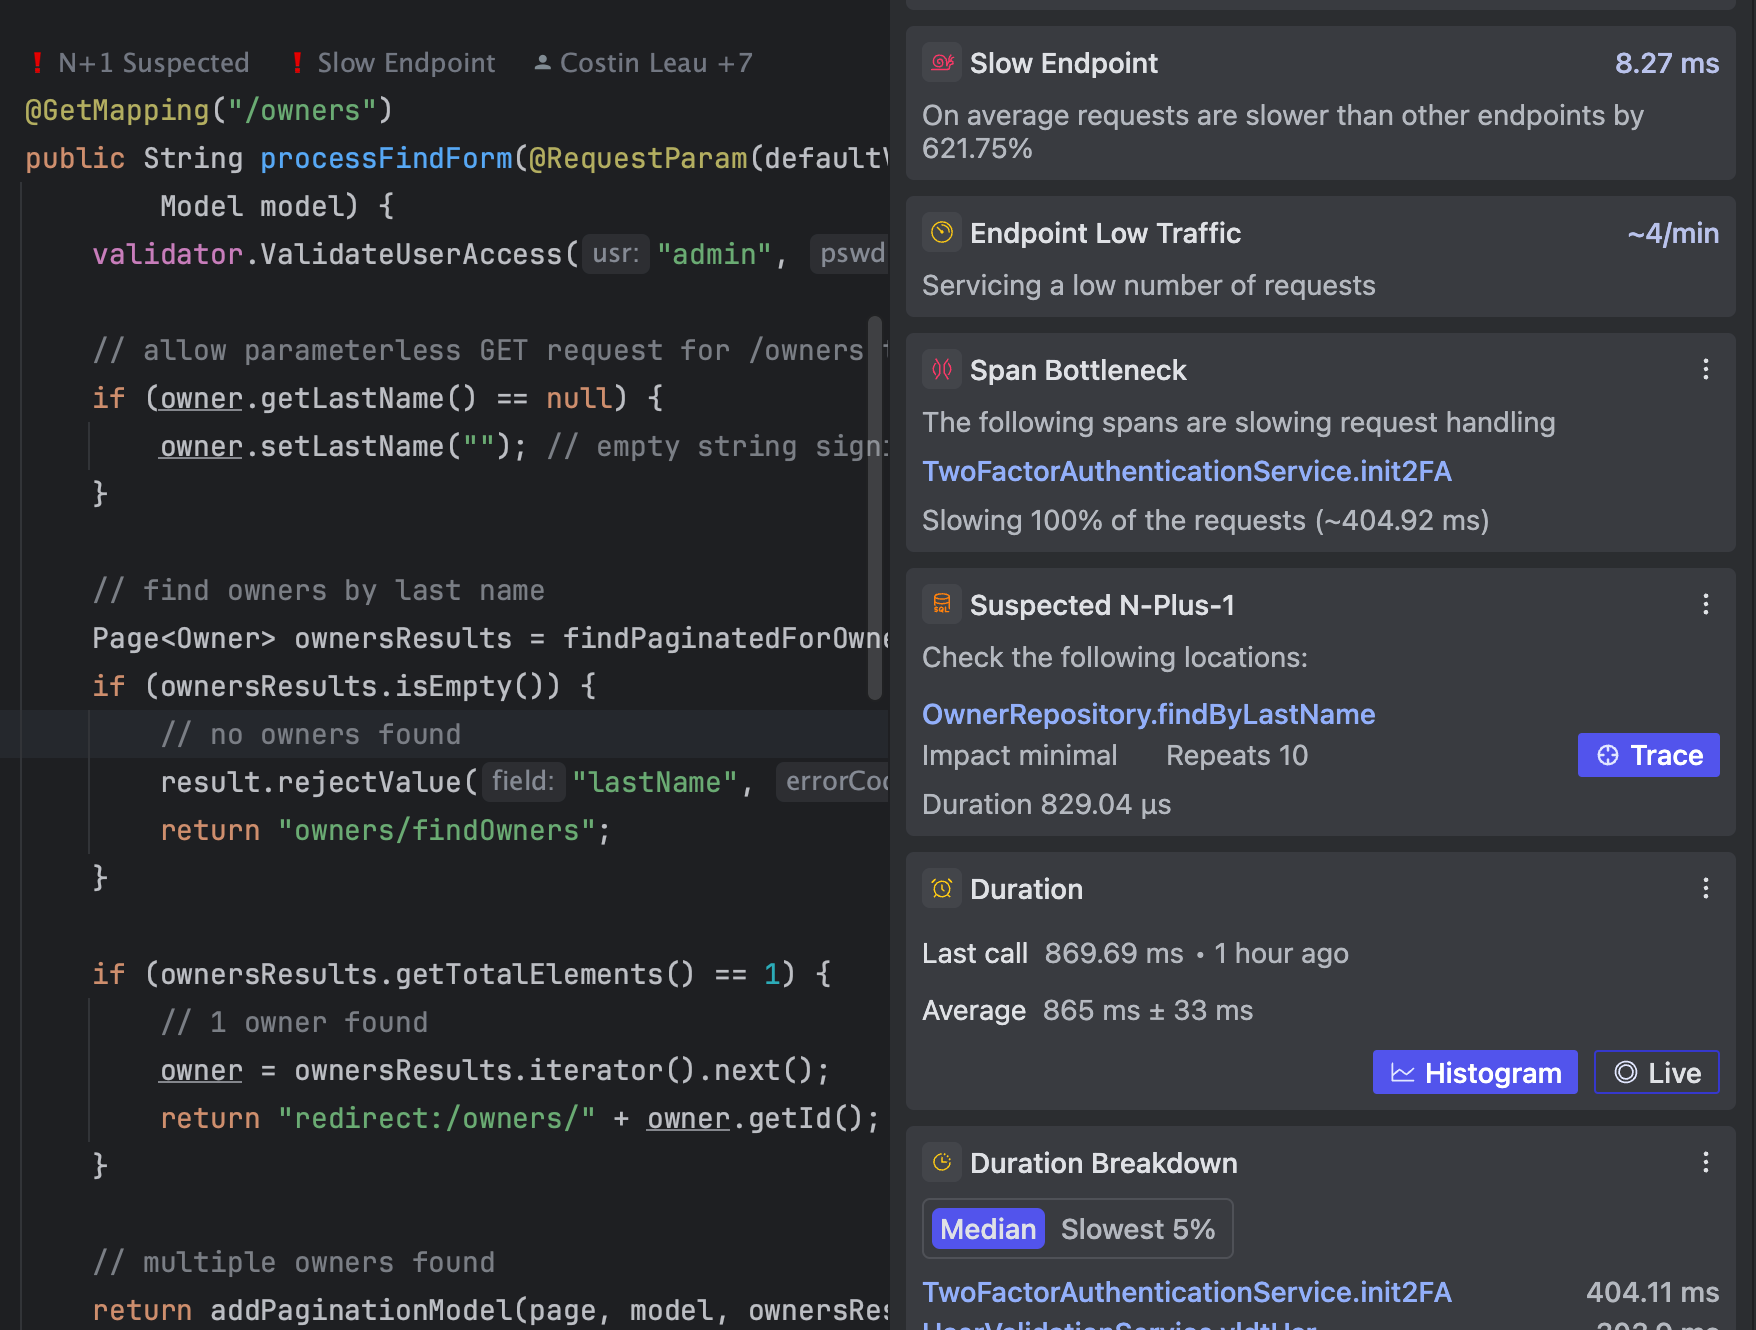
    Digma has launched a namesake platform the provides developers with continuous feedback from observability data that surfaces directly within their integrated development environment (IDE).

    Digma CTO Roni Dover said the Digma Continuous Feedback platform leverages machine learning algorithms to enable developers to easily analyze their code at runtime to identify issues, anomalies and regressions. Digma Continuous Feedback removes the need to consult a separate dashboard that requires developers to log into an observability platform.

    In fact, the reason developers often don’t make use of the data that observability platforms provide to write better code is that it’s not readily accessible at the time they are writing code, noted Dover.

    In general, it’s become much easier to collect logs, metrics and traces by using open source OpenTelemetry agents that can be embedded within software libraries. The Digma Continuous Feedback platform applies machine learning algorithms to that data to provide developers with insights on improving code in real-time, said Dover.

    The ultimate goal is to make it simpler for IT teams to distinguish when, for example, a software component actually needs more memory or is simply inefficient, he added. Those insights can be applied to code written by developers or code generated by an AI platform.

    Whether code is written by a human or generated by a machine, quality is often in question. Developers with varying levels of experience will naturally write code that can differ substantially in quality and efficiency. At the same time, developers may be asked to fix code someone else wrote; the original author no longer works for the organization, noted Dover. In either use case, the Digma Continuous Feedback platform immediately surfaces issues that will enable organizations to set higher baselines for code quality, he added.

    That baseline is especially critical as more code starts to be generated by generative AI platforms based on general-purpose large language models (LLMs) trained using code samples of varying quality collected from across the web. Developers will be able to immediately determine any issues that may arise should they choose to incorporate that code within an application.

    Developers, of course, don’t deliberately set out to write bad code, but the tools that enable them to identify issues are not easily accessible. In fact, too many developers tend to view observability platforms designed for IT operations teams as being overly complex, noted Dover. The Digma Continuous Feedback platform takes that issue off the table by identifying issues without increasing the level of cognitive load developers are expected to carry, he added.

    Eventually, thanks to the rise of machine learning algorithms and generative AI platforms designed specifically to write high-quality code, the overall state of software engineering will improve. The issue is determining the best way to get the benefits these technologies provide directly to the developers who write code—an issue that is at the heart of so many DevOps challenges.

  • SolarWinds Adds Service Management Platform to Portfolio

    SolarWinds Adds Service Management Platform to Portfolio

    SolarWinds has added a service management capability to its portfolio as part of an effort to make it simpler for IT teams to align support services with specific functions.

    At the same time, SolarWinds has updated its SQL Sentry observability tool for databases and DataOps workflows to add query-level wait statistics along with a revamped web portal and dashboard for tracking the overall health of a database environment.

    SolarWinds Enterprise Service Management (ESM) makes it possible for IT teams to manage IT services based on the ticketing systems, knowledge bases, service portals and request catalogs available for specific departments such as marketing or human resources.

    Kevin Kline, senior staff technical marketing manager for SolarWinds, said that as IT management continues to evolve, there is a greater need to streamline and optimize workflows based on the insight from observability platforms. As a result, there is now a need to apply observability more broadly to include database platforms alongside DevOps and other IT workflows, he noted.

    The overall goal is to eliminate the blame game that results when IT platforms are managed in a more siloed fashion, added Kline.

    Most IT teams are still relying on monitoring tools to track a set of predefined metrics in the hope that an alert will enable them to proactively address an issue before it leads to a major disruption. However, as IT environments become more complex, there is a growing need for observability platforms so IT teams can launch queries and surface issues that predefined metrics aren’t likely to identify. Initially, observability platforms were embraced by DevOps teams, but it’s rapidly becoming apparent that this capability needs to be applied to every IT process. In effect, organizations are on the cusp of democratizing observability, noted Kline.

    Achieving that goal will also become simpler thanks to the rise of machine learning algorithms capable of predicting issues and generative artificial intelligence (AI) tools that will make it simpler to craft queries.

    In the meantime, there is already no shortage of observability platforms, but the SolarWinds approach is different in that, in addition to DevOps workflows, the company has integrated its platform with multiple database platforms to provide a more comprehensive approach, said Kline.

    It’s not clear just yet how observability platforms might impact the way IT teams are structured, but the need for specialists such as database administrators (DBAs) isn’t likely to go away anytime soon, noted Kline. Instead, the level of collaboration across various IT teams should substantially improve.

    In the meantime, IT teams might be well-advised to define an observability strategy today before multiple teams start implementing approaches that might be optimized for a relatively narrow range of use cases. After all, trying to reconcile insights generated by multiple observability platforms may very well defeat the purpose of investing in observability in the first place.

  • Why Data Silos Are Killing Your Developer Productivity

    Why Data Silos Are Killing Your Developer Productivity

    Every company is at risk of fostering data silos. In fact, a study conducted by Forrester Consulting for Airtable across employees in the U.S. and the UK revealed that, on average, knowledge workers spend 30% of their week looking for the information they require to do their job and the difficulty in finding and accessing data is the top reason why they feel disengaged from work. What causes essential data to be inaccessible in the workplace? We will explore the root of modern data silos, why they drain developers’ productivity and how to break away from these silos with better observability in your organization.

    What are Data Silos?

    A data silo is a collection of data held by a group that is not easily or fully accessible by other groups in the same organization.

    Data silos can be a byproduct of organizational structure. When different departments or business units in an organization operate independently, they develop their own way of collecting, storing and managing their data. The processes to access that data from other business units can be cumbersome or even nonexistent. Sometimes, the individuals responsible for the data will even be against sharing it for fear that it would be misused or misunderstood outside of their particular unit. The difficulty in accessing information then leads to independent data collection from other business units and ultimately creates other data silos and multiple sources of truth.

    Data silos can also happen during times of growth for an organization. New tools are necessary to support the growing needs of the business and are added to the list of tools already in use. Over time, this list grows, and systems that were designed to operate in isolation can create data silos by limiting the ability to integrate with other systems. A recent survey of marketing organizations by Emarsys showed that the surveyed organizations are using an average of 91 marketing cloud services. These 91 tools undoubtedly create data silos unless they are fully integrated together or into a central system.

    Why are Data Silos Killing Your Developer Productivity?

    Data silos aren’t only slowing your developers down by limiting their access to the data needed for development. They also put a lot of extra work on their plates. And it goes without saying that this additional time spent on data management reduces the time available for improving your product.

    Management of Redundant Data
    Multiple teams in the organization storing their data separately means increased workloads for developers, who need to update and maintain separate copies of the same data.

    Inconsistent Data Quality
    Data gaps or quality issues happen more frequently since different parts of the organization have their own standards for collecting, cleaning and validating data. This can lead to development delays or errors in the product.

    Time-Consuming Integrations
    Developers have to code a lot of integrations to connect all the different tools your organization uses and keep the data flowing between them.

    Inefficient Collaboration
    When different teams work in silos, the chances of misunderstanding are greater, leading to development delays and misaligned priorities.

    Difficulty in Data Governance
    Maintaining high standards of data privacy, security and compliance is time-consuming when the data is spread out in different silos and can create costly regulatory risks.

    Steps Leaders Can Take to Break Down Data Silos

    Fortunately, there are steps that you can take to break down the data silos in your organization, relieving your developers at the same time. Each step may have its own set of advantages and challenges, so the solutions you choose ultimately depend on your organization’s needs and objectives.

    Create a Unified Data Strategy
    Set clear goals and standards for data collection, storage, management and analysis at the company level. You should also implement data governance and security policies.

    Adjust the Culture
    Foster a culture of collaboration and data sharing across the company by encouraging teams to share data, insights, and best practices across different departments. You can achieve this through regular communication, training and incentives for cross-functional collaboration.

    Establish Cross-Functional Teams
    Bringing together members of different departments to collaborate on data-related projects can prove invaluable. These teams should have a shared understanding of the organization’s data strategy and should be empowered to make decisions about data collection, analysis and sharing.

    Invest in Data Integration and Interoperability
    Invest in tools and technologies that promote data integration and interoperability across different systems and departments. Adopt standard data formats, implement APIs and data connectors or use data integration platforms to make observability collaborative. Make sure that the tools you choose to add to your company have various native integration capabilities to avoid custom integrations as much as possible.

    Congrats, you now know all about data silos and how to break them down! The next step for you is to identify the data silos in your company and put a plan in place to get rid of them. Your employees and coworkers will thank you!

  • There’s No Value in Observability Bloat. Let’s Focus on the Essentials

    There’s No Value in Observability Bloat. Let’s Focus on the Essentials

    The observability market paired with cloud security has been predicted to reach $70B by 2026, but that market prediction is a myth, and I’ll tell you why.

    If observability was a grand buffet and every company needed a feast of features and capabilities of this proportion, maybe this prediction would be valid. But most companies don’t need an over-the-top feast. Legacy APM and observability solutions are serving up an all-you-can-eat buffet when the reality is that most companies only need the essential ingredients to satisfy their observability strategy. And the cost for that can be much more modest. The $70B observability market prediction is, therefore, suspect, considering the true needs of most organizations.

    Complex cloud ecosystems, the rise of applications built on microservices and Kubernetes, and the overall scale and complexity of applications have led to exponentially more data being created in the pursuit of observability. Storing and processing all that data is expensive, and as the volume of data balloons, so does the cost.

    And while the complexity of business-critical systems and the volume of data have scaled, so have the overall cost of those legacy tools—in direct proportion. Partially, this is driven by the features and instrumentation added that only contribute to the bloat and valueless telemetry.

    Customers aren’t seeing value in any of this bloat, and for the most part, all that’s been accomplished is increased complexity in deploying and operating the system, with a commensurate lengthening of time to value. Plus, pricing models haven’t significantly changed despite the advancements in the market. The fact is, organizations can’t really say that they have gotten more insight into the overall performance of their mission-critical systems. What they are saying, however, is that these tools are becoming overwhelming to manage and overwhelmingly expensive, and developer productivity is not increasing.

    What organizations need and want are real-time insights into the health and performance of their cloud infrastructure and applications–specifically the confluence of logs, metrics and traces within the context of modern observability. There is little tolerance for software bugs, slow web experiences, crashed apps and other service interruptions, and the responsibility lies on developers, engineers and ITOps teams to quickly resolve production issues before they impact customer experience.

    There is a call for observability, but rather than an explosion of features and noise, what’s being called for is a narrowing of focus.

    Observability Has an Efficiency Problem

    Telemetry data gathered from the distributed components of modern cloud architectures needs to be centralized and correlated for engineers to gain a complete picture of their environments.

    Engineers need a solution with critical capabilities such as dashboarding, querying and alerting, and AI-based analysis and response, and they need the operation and management of the solution to be streamlined.

    What’s important for them to know is that it’s not necessary to spend more to ensure peak performance and visibility as their environmental complexity grows.

    Legacy players experiencing some maturity in the market may have conditioned them to believe this is true—they have set a standard for higher costs correlating with incremental amounts of data, no matter the quality of that data. Companies are being fed the lie that all this data may be relevant and they’ll be doing themselves a disservice by neglecting even one byte of it.

    Data Does Not Inherently Equal Insights

    No doubt, more data is being generated, but most of it is not relevant or valuable to an organization. Observability can be optimized to bring greater value to customers, and that’s where the market is headed.

    Call it “essential observability.” It’s a disruptive vision to propose a re-architected approach to observability, but what engineers need is a new approach making it easier to surface insights from their telemetry data while deprioritizing low-value data. Costs can be reduced by consuming only the data that enables teams to maintain performance and drive smart business decisions.

    Essential observability is cutting out the fluff and only focusing on—and paying for—the impactful data. It’s about arming engineers with meaningful insights so they can quickly resolve production issues and business disruptions. Organizational performance increases without inflating data complexity and resource consumption.

    The Essential Observability Revolution

    Observability tools have evolved beyond the model of linear price increases as complexity and data scales. For companies (especially growth-stage organizations) that want a partner to help them make more informed decisions and keep their costs more reasonable (i.e., stop recklessly spending for useless data), they need to focus on tools offering them the essentials.

    Solutions are available, offering targeted features and automated capabilities out of the box, delivering the insights needed to understand and fine-tune data. These solutions provide continuous support, reduce complexity and accelerate time to value.

    The next revolution in observability isn’t features and functionality but providing insights to make data-driven decisions that keep essential observability cost-effective while not compromising the value derived.

  • Observability Leaders: The Mighty Minority Holding Their Own Against Outages

    Observability Leaders: The Mighty Minority Holding Their Own Against Outages

    The job of IT teams has become much harder thanks to the new realities of hybrid IT, with workflows occurring across on-premises and cloud-based networks and applications. Yet so much rests on your ability to respond to these challenges, all while managing the expectations of your customers and the health of your bottom line. With the growing complexity of ecosystems comes the need for better visibility, both into specific systems and across your entire stack.

    Observability solutions address this by providing visibility across your network, infrastructure, systems, application, database, digital experience and log monitoring.

    In other words, observability enhances your ability to observe your digital ecosystem with more transparency, more effective detection and more intelligent insights. Take, for example, the very timely and pressing issue of outages. On average, the typical business experiences nine brownouts or outages every month, lasting roughly twelve hours each and averaging $13.7M annually, according to new research we conducted at SolarWinds.

    Over the course of the year, that can add up to nearly 1,300 hours, with outages chipping away at your organization’s productivity, reputation and competitive edge.

    It’s not enough to monitor for these outages and address them once they take down your systems. Repeated or prolonged outages signify a gap in the enterprise’s ability to comprehensively monitor and understand its network’s internal state and performance. A robust observability strategy can preemptively detect anomalies and potential issues—before they become full-blown outages.

    According to new data from the 2023 IT Trends Survey released this month by SolarWinds, companies who’ve embraced observability tend to not only lead in detecting, remediating and preventing outages—they’re experiencing better business and IT outcomes, too.

    The technology professionals surveyed shared how observability is helping them achieve better performance, compliance and resilience in digital environments—and how you can follow their lead.

    Observability Drives Better Business Outcomes

    The observability leaders surveyed were 300% more likely to say their organization is doing extremely well with growing revenue and 250% more likely to say the same about their organization’s speed of innovation. Interestingly, they also reported a better employee experience: They were 388% more likely to rate their organization as doing “extremely well” with employee experience and also reported fewer and smaller skill gaps on their teams.

    So, how does embracing observability actually translate into better business outcomes? According to the data, observability leaders are…

    • Investing in top priorities: Data shows organizations using observability solutions to support the priorities most critical to their growth and success: Improve their customer experience (96%), enable faster innovation (71%), reduce time spent solving (71%) and detecting (60%) issues and increase operational efficiency (55%).
    • More automated and integrated: Observability leaders embracing automation and investing in tools that provide enhanced efficiency are 214% more likely to say they are doing extremely well with operational efficiency, 750% more likely to say they are doing extremely well with auto-remediation of complex alerts and 300% better at automatically collecting background diagnostic data for IT support staff.
    • Ahead on IT: The data found that those ahead of the curve on observability are also leading by huge margins when it comes to monitoring, detecting and resolving issues that could otherwise bring the business to a screeching halt. When it comes to IT, they are 233% better at auto-escalation of tickets, 213% better at auto-remediation of simple alerts and 36% better at settling alert levels based on historical behavior.

    How to Reap Observability Benefits in Your Organization

    All told, observability adoption is still in its early days. Only 1% of enterprises are already up and running using observability tools on a regular basis, while another third are undergoing the implementation process.

    That’s good news for other businesses who are ready to reap the rewards—it’s not too late to be an observability pioneer.

    If you’re interested in bringing observability to your own organization, start by addressing a few important factors that can help you sidestep challenges—such as the accelerating pace of change in technology (72%) or insufficient budget (58%)—that might otherwise obfuscate your observability opportunities:

    • Make sure your observability solutions are appropriate for multi-cloud environments: Multi-cloud environments have become standard for many companies because of the many upsides, but they can be challenging for IT teams to manage. Strategically accelerate your organization’s cloud migration with an observability solution designed for complex hybrid and multi-cloud environments​ to save a lot of headaches down the road.
    • Give your teams autonomy—and build toward autonomous operations: Observability brings your enterprise a step closer to autonomous operations. Autonomous operations, where IT systems can govern themselves, providing a proactive approach to addressing issues, rather than reactive, won’t replace your human teams but rather free up their time and brainpower to support the business and drive innovation.
    • Don’t ignore the database: Databases represent the most difficult ecosystems to observe, tune, manage and scale. They require significant computing power, tend to be memory-intensive and likely make up the bulk of your organization’s cloud spending. Tasks crucial to the health and functionality of your business—including troubleshooting, root cause analysis and remediation—simply cannot happen without full, transparent observability across the numerous resources a database needs to engage to do its job.

    Observability helps balance competing priorities and demystify application requirements while increasing your overall DevOps agility, efficiency and speed to market. Observability not only fosters transparency and collaboration but also encourages a system of ongoing review, which benefits the organization, IT teams and—crucially—your customers.

  • Cisco Acquires Splunk to Create Observability Powerhouse

    Cisco Acquires Splunk to Create Observability Powerhouse

    Cisco today revealed it has signed a definitive agreement to acquire Splunk for $28 billion in cash. The deal will add Splunk, one of the most widely-used platforms for managing IT operations, to Cisco’s portfolio, joining the AppDynamics observability platform in addition to a wide range of IT infrastructure equipment.

    Chuck Robbins, CEO of Cisco, told industry analysts the combined entity will be one of the largest software companies in the world. The Splunk and AppDynamics platform creates a comprehensive observability platform spanning applications, networks and hybrid cloud computing environments, Robbins added.

    By combining AppDynamics with the data collected by the Splunk platform, the combined company will be able to provide greater insights into IT operations than any other company, added Robbins.

    Splunk CEO Gary Steele said the acquisition represents the next natural, logical step for Splunk and furthers its long-term partnership with Cisco to keep IT environments secure and resilient. The two companies will also be able to apply artificial intelligence (AI) more effectively to IT operations, he added.

    In its most recent quarter, Splunk reported revenues of $911 million, with cloud revenue accounting for $445 million, or 29%, of the total. Total Splunk revenues are forecasted to be between $3.925 billion and $3.95 billion for fiscal 2024.

    Splunk previously acquired SignalFX, a provider of an observability platform, in 2019. It’s not yet clear how the platform might be integrated into the AppDynamics platform, but Robbins said there is little overlap between the observability platforms the two companies currently provide.

    The Splunk acquisition comes at a time when it’s becoming more apparent that the need for observability extends well beyond DevOps workflows as organizations become more dependent on software.

    Each IT organization will need to determine how long it will wait for the Splunk acquisition to close before investing further in observability. Historically, acquisitions of this scale have been accompanied by price hikes to help fund the merger once the deal is concluded.

    In the meantime, IT and DevOps leaders will likely revisit the way IT is managed in the months ahead. Splunk came to prominence at a time when most workloads were running in on-premises IT environments. While the bulk of workloads continue to run in those environments, many workloads deployed in the cloud are being managed using platforms designed specifically for those environments. Splunk has been making a case for a hybrid cloud computing approach that assumes the management of on-premises and cloud computing environments will become more unified.

    In theory, economic headwinds are driving more organizations in that direction to reduce the total cost of managing IT. But it’s just as feasible to extend cloud tools to on-premises IT environments as it is to extend legacy tools to the cloud. Despite the inevitable outcome, Splunk rivals will spend the better part of the next year coming up with offers to switch platforms both before and after the deal eventually closes.

  • Survey Surfaces Major Observability Challenges

    Survey Surfaces Major Observability Challenges

    A recent survey found the biggest obstacles to observability were the pace of technology change, IT blind spots and the complexity of modern applications. The survey polled 300 IT professionals to identify the biggest challenges they faced in achieving observability. The accelerating pace of technology change (72%) topped the list, followed by IT blind spots and the growing complexity of modern applications (58% each), and lack of funding (52%).

    The survey, conducted by SolarWinds, also found the typical enterprise suffered nine brownouts or outages every month, each of which lasted around twelve hours. The full cost of outages and brownouts averaged $13.7M annually for these enterprises, according to the SolarWinds report.

    Jeff Stewart, field CTO and vice president, global solutions engineering at SolarWinds, said the survey makes it clear that a lack of observability is having a material impact on businesses. Organizations are now moving beyond monitoring predefined metrics to embrace observability platforms that make it simpler to investigate the root cause of issues that adversely impact businesses; these businesses are more dependent on IT than ever, he added.

    In fact, the primary reason organizations are investing in observability is to improve their customer experience (96%), enable faster innovation (71%), reduce time spent solving (71%) and detecting (60%) issues and improve operational efficiency (55%), the survey found.

    While it’s still early days as far as achieving observability is concerned, a lot of progress is starting to be made as organizations realize that complex IT environments require a different management approach. IT teams can no longer afford to navigate multiple monitoring tools in what often turns out to be a vain effort to prevent brownouts and downtime, noted Stewart.

    In addition, many IT teams are becoming increasingly aware that the telemetry data collected via an observability platform provides the foundation for infusing IT operations with artificial intelligence (AI) capabilities, he added. The ultimate Holy Grail is to one day achieve autonomous operations, noted Stewart.

    There is, of course, no shortage of observability platforms, but Stewart contends that providers of monitoring tools such as SolarWinds are in the best position to help IT teams make the observability transition. Rather than ripping and replacing a monitoring platform, a more seamless transition that results in less disruption is preferable, he noted.

    Regardless of approach, observability platforms that enable IT teams to launch queries across complex distributed computing environments are becoming a necessity. Distributed computing environments often have more dependencies than IT teams can manually track. It’s only a matter of time before the most talented DevOps professionals start to migrate to organizations that provide them with the management tools and platforms required to succeed. Otherwise, the stress of managing a complex IT environment will only result in higher rates of burnout among DevOps professionals.

    It may be a while before observability platforms are pervasively employed across IT environments, but as it becomes clear that brownouts and downtimes result in a decline in revenue, business leaders will understand what’s required to maximize profits. In many cases, the answer will be an observability platform that surfaces the insights needed to proactively manage modern IT environments.

  • Operational Intelligence: AI-Powered SRE Measurements and Observability

    Operational Intelligence: AI-Powered SRE Measurements and Observability

    In my recent blog, Revolutionizing the Nine Pillars of SRE with AI-Engineered Tools, I indicated AI can help analyze vast amounts of data from monitoring and observability systems, identifying patterns and correlations that may be difficult for humans to detect. In this blog, I explain, in more detail, how AI-engineered tools can be used to improve the site reliability engineering (SRE) measurements and observability pillar of practice.

    AI Use Cases for SRE Measurements and Observability

    Making Applications Observable: AI tools like Dynatrace can provide real-time observability of applications, identifying trends and anomalies that might not be evident from raw data. Challenges here include the potential for overwhelming amounts of data, which can be mitigated by AI’s capacity to analyze and prioritize this data effectively.

    Making Infrastructure Observable: Tools like New Relic and Datadog use AI to provide insights into the health and performance of infrastructure. The challenge here can be the complexity of modern, cloud-based infrastructures, but AI tools can model these systems and analyze their behavior to provide actionable insights.

    Monitoring Applications in Production: AI can be used to monitor applications in real-time, identifying potential issues before they impact users. Tools like Splunk use AI to monitor application logs, detect anomalies and automatically alert relevant teams. The key challenge here is filtering the signal from the noise, which AI can help by learning which anomalies are significant.

    Monitoring Production Infrastructure: AI can monitor infrastructure health and performance, predict maintenance needs and identify potential bottlenecks. Tools like Zenoss use machine learning to predict infrastructure failures before they occur. One of the main challenges here is the diversity of infrastructure components, but AI can handle multiple data sources and types and integrate this data into a comprehensive overview.

    Tracing and Logging: AI can help manage the vast amounts of data generated by modern logging and tracing systems, identifying patterns and correlations that might be difficult for humans to detect. Tools like Logz.io use AI to analyze log data, detect anomalies and provide actionable insights. One challenge can be the sheer volume of log data, but AI can handle this by focusing on patterns and anomalies and learning over time which issues are significant.

    Production Dashboard Design: AI can help design more effective dashboards by identifying which metrics are most relevant and should be highlighted. Tools like Grafana use machine learning to optimize dashboard layouts based on usage data. The challenge here is determining what information is most relevant, but AI can learn this from usage patterns and user feedback.

    Performance Forecasting: AI can help with predicting system performance based on current and historical data, helping to prevent performance issues before they arise. Tools like Virtana use AI to provide accurate forecasts of system performance, helping teams to plan for future capacity needs. The challenge here is the variability of performance data, but AI can handle this by identifying patterns and trends in the data.

    Automated Root Cause Analysis: AI can be instrumental in quickly identifying the root cause of issues in complex, distributed systems. Tools like RunWhen and Moogsoft use AI to correlate events across different systems and tools, significantly reducing the time to identify the root cause. The challenge here is the complexity of modern systems, but AI can handle this by analyzing data from multiple sources and identifying correlations that might not be evident to humans.

    RoadMap for SREs to Transform Measurements and Observability With AI

    Here is a practical roadmap that organizations can use to transition to AI tools for SRE measurements and observability.

    Understand the Current State: First, an organization needs to fully comprehend its existing monitoring and observability practices. This includes understanding what tools are currently in use, what metrics are being monitored and where the gaps in visibility exist.

    Define Goals and Objectives: The next step is to define what the organization hopes to achieve by implementing AI in its monitoring and observability practices. This could include goals like improving system performance, reducing downtime or predicting system failures before they occur.

    Identify the Right Tools: Evaluate different AI tools to help achieve these goals. This includes looking at AI-powered monitoring tools like Dynatrace, New Relic and Datadog, log analysis tools like Logz.io and Splunk and AI-driven observability platforms like Moogsoft and Zenoss.

    Test and Iterate: Implement the chosen tools on a small scale initially, using a test environment if possible. Monitor the results and adjust your approach as necessary. This step might involve tweaking the AI models, adjusting the data inputs or even trying a different tool if the initial choice doesn’t provide the expected results.

    Training and Upskilling: Ensure your teams are well-versed in using the chosen AI tools. This could include formal training sessions, workshops, or even bringing in external experts to provide guidance. This will help your team to effectively use these tools and get the maximum benefit from them.

    Full-Scale Deployment: Once testing has been successful and the team is comfortable with the tools, deploy them across your production environment. Continue to monitor their performance and make adjustments as necessary.

    Continual Evaluation and Adjustment: AI tools learn and improve over time. It’s important to regularly evaluate their performance and make adjustments as needed. This could involve feeding them new data types, adjusting their models or retraining them based on the latest performance data.

    Summary

    Harnessing the power of AI to revolutionize your SRE practices can propel your organization to new heights. AI tools can significantly enhance the measurements and observability pillar of SRE, providing unparalleled insights into application and infrastructure performance, enabling more efficient monitoring practices and ultimately driving improved system reliability and performance. These tools, such as Dynatrace, New Relic, Datadog, Logz.io and Moogsoft, can transform how your organization perceives and interacts with its technological environment, providing crucial visibility and actionable intelligence.

    Imagine a world where your monitoring systems not only alert you about a problem but also predict potential system failures before they occur and even recommend preventive actions. With the implementation of AI in your SRE practices, this can become a reality. By following a well-defined roadmap that begins with understanding your current state, defining your objectives, selecting the right AI tools, iteratively testing and upskilling your teams, you can pave the way for a future where improved system performance and reduced downtime are the norms. AI-powered SRE practices today can unlock a new era of operational efficiency and system reliability.