Tag: IT operations

  • Focusing on the Real Value of AI for IT Ops

    Focusing on the Real Value of AI for IT Ops

    In all the hype over AI, let’s concentrate on the real value it can provide, especially for busy IT Ops teams.

    2018 is already shaping up to be the year when AI and machine learning (ML) go mainstream—at least in terms of public awareness, if not yet of actual usable products. As I write this, the annual CES event—the show that is, Prince-style, “formerly known as “The International Consumer Electronics Show—is in full swing. The usual suspects are out in force, with Amazon’s Alexa getting embedded in more and more products and Google also showcasing its own consumer AI capabilities.

    More unexpected AI adopters included Ferrari, but there were also some notable failed demos, with an AI-enabled suitcase repeatedly running away from its owner or AI refusing to answer questions during an on-stage demo. All of this led the BBC to question, “When will AI deliver for humans?”

    What Happens in Vegas, Stays in Vegas

    Of course, much of what comes out of CES is frivolous, but there are all sorts of other applications of AI and ML. The problem is that whenever there is this much hype, disappointment and disillusionment are not far behind. Gartner’s famous Hype Cycle model can help here.
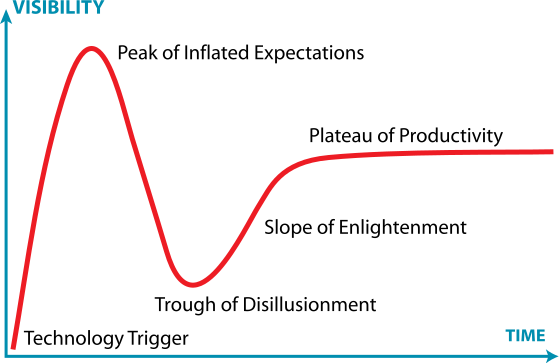
    Gartner Hype Cycle - from Technology Trigger, via Peak of Inflated Expectations, through Trough of Disillusionment, up Slope of Enlightenment, to Plateau of Productivity.
    By Jeremykemp at Wikipedia, CC BY-SA 3.0

    The conventional concern is that overly optimistic projects initiated at the Peak of Inflated Expectations risk failing, leading to excessive caution and fewer projects starting during the Trough of Disillusionment, before a more realistic understanding sets in and the technology achieves true mainstream adoption. Due to the nature of AI and ML, though, there is a second failure mode that is far more insidious.

    AI and ML generally operates as a black box. Results are provided, very quickly and without the need to develop deterministic rules, but it is generally not possible to determine why a specific result was generated or troubleshoot failures in detail. As these techniques are used in the real world, potential problems that might not have been obvious in the lab begin to appear. If your smart fridge misreads the expiry date on that chicken (and you don’t think to check yourself), you might be in for an uncomfortable few hours. If your smart thermostat decides for some reason that your house should be as hot as physically possible, you’re still on the hook for the heating bill.

    Those are the “nice” failure modes. If a facial recognition algorithm was trained on a data set that didn’t have the right racial balance, you might wind up with some of your employees not being able to get in the door, or some of your customers not being able to unlock your device, or whatever.

    It gets worse. Law enforcement has an obvious interest in facial recognition—but what if a faulty system places you at the scene of a riot? https://www.liberty-human-rights.org.uk/news/blog/misidentification-and-improvised-rules-we-lift-lid-mets-notting-hill-facial-recognition Even if you can prove your innocence, you might still have to deal with some difficult conversations with your family and your employer, and your neighbours may never forget the time you were hauled off in handcuffs.

    Don’t Throw The AI Baby Out With The Hype Bathwater

    So should we just forget about this AI nonsense? Far from it. In fact, I am personally convinced that AI is very much a key part of our future. It just needs to be used in the right way.

    I mentioned training data above, and that is the key. AI systems need a lot of good data, and they need to be trained to make good assessments. Out there in the real world, both sides of that problem are actually very hard. Gathering enough data, making sure that the data gathered are actually representative of the problem space, dealing with privacy issues around personally-identifiable information, and formatting the data correctly for ingestion by your machine learning system are already not trivial issues. However, even assuming that you have successfully dealt with that hurdle, the initial results will not be very good or reliable. Intelligent assessment by humans who understand the domain that you are training for is key if your deep learning model is not to go off the rails.


    Come Up to the IT Ops Lab

    Seen in these terms, IT Ops is an ideal domain to which to apply these techniques. First of all, IT infrastructure already generates huge amounts of event data – Big Data, if you insist – and all of those events are already, by definition, formatted to be easily machine-readable. Sure, there are many different formats out there, from SNMP, via various proprietary product-specific formats, to modern REST APIs, but it turns out that computers are pretty good at translating information from one representation to another.

    Once the event data are in the AI system, it can apply whatever algorithms to try to make sense of them: which events are even significant, which ones are related to each other, what other relationships might exist, and so on. When it comes to evaluating the results, again, IT Ops already has people, tools and processes working on precisely that question: is this a real issue, and if so, what to do about it — or if not, why not. This evaluation can be fed back to the learning system to improve its results for next time, iterating over time to provide ever more valuable and reliable results.

    This learning can even be applied to the evaluation process itself, watching what users find most interesting and valuable, and extrapolating from that to present the most significant data first, or looking for patterns in human interaction to assemble the most effective teams to work on particular types of incident.

    This is what AIOps is all about. Don’t assume that the sort of consumer-grade AI that you see at CES is all that is going on in this field. AI has huge potential to help streamline enterprise IT Ops, by presenting human specialists with actionable events, helping them collaborate more effectively, and learning and improving over time.

    Once the CES hype has died down, take a good look at AIOps and start to think how it can fit into your plans for 2018.
    — Dominic Wellington

  • The State of Alerting in the IT Ops world

    The State of Alerting in the IT Ops world

    OnPage Corp. just finished a survey of more than 100 ITOps professionals from across the United States. Our goal was to acquire a greater understanding of how well engineers in the industry are performing when it comes to critical alerting and alert management of their IT teams.

    We wanted to understand the antecedents of alert fatigue for ITOps that appear earlier in the food chain. We also wanted to see how many alerts teams receive per day as well as who gets alerted. We wanted to understand how alerts are managed. And, we wanted to see how well teams analyze their actions and take those lessons forward.

    In many ways, the survey was successful. We received a large number of responses from a number of industries and acquired a strong sense of how ITOps is performing across the country. Unfortunately, we also saw that for all the Chaos Monkeys and strides toward improved response to alerting, there is still a significant lack of progress.

    What’s All the Buzz About?

    Automated alerting is an essential component of monitoring. Automated alerts are what allow teams to receive automatically generated alerts from multiple points along their IT stack and software. In theory, this multitude of alerts is what enables teams to more quickly identify the causes of a problem and minimize the severity. The hope is, that with early recognition of the issue, engineers will be able to minimize service degradation and disruption.

    But alerts aren’t always as effective as they could be or need to be. Real problems often are lost in a sea of noisy alarms. As our survey showed, this is because teams are inundated with alerts coming in via multiple formats. Moreover, the barrage of alerts leaves teams inundated and practically unable to cope.

    The Law of Above Average

    Our survey showed that more than 80 percent of IT teams are alerted to critical incidents via email. General best practices would dictate that email is fine for daily communication inside a business. However, for critical incidents, email is less than ideal, as it allows critical incidents to get buried under a pile of other emails. There is no way for critical issues to rise to the top of the pile.

    Since our questions were multiple choice, respondents could provide multiple answers with regard to how they received notice of critical incidents. So, while email was the most prevalent form of communication, individuals indicated that they are also simultaneously receiving alerts by SMS or phone call.  Our survey showed that 58.9 percent and 51.4 percent of respondents received alerts via these methods.

    Already from this nugget of information, we see the opportunity for both information overload and an opportunity for missed alerts. By simultaneously receiving alerts through multiple formats, the level of irritation and overload inevitably rises. At the same time, if emails are the only form in which IT professionals receive alerts then there is a high opportunity to miss alerts all together.

    How Many Alerts Was That?

    The survey results also indicated that just over 41 percent of ITOps receive 11 alerts or more per day. Additionally, just over 20 percent of this group received 40 alerts or more per day. While 40 alerts is clearly more than a team can reasonably manage or should manage, this figure also goes a long way toward explaining why some alerts just get missed. If more than 40 alerts are sent to you and your team every day, it becomes very difficult to prioritize alerts and determine which should be handled first.

    Perhaps to better manage this large number of alerts, many teams use escalation procedures. Our survey showed that 76.6 percent of respondents have some sort of escalation procedure in place. At the same time, the most frequent ways to escalate critical responses was through email or SMS.

    The conclusions one can draw from these numbers are that, despite the large number of papers written on improving alert management, many ITOps have not been able to achieve this end. While our survey did show that just shy of 59 percent receive a manageable number of alerts, 41 percent are inundated.

    Not Just Intelligence, Business Intelligence

    Perhaps analysts of the industry could be more optimistic if they saw that teams were using analytics to track how well they are performing. If teams employed analytics, they would be better able to review their progress, see where they are failing to meet the grade and then embark on routines to improve. Unfortunately, this is not the case.

    When asked whether their team has employed any type of business intelligence to review and analyze their team’s performance, more than 70 percent reported that they did not subscribe to any BI platform. The problem with this result is more than just a missed opportunity; it is also the loss of opportunity to fundamentally improve the business at many levels.

    One of the most important reasons why you need to invest in an effective BI system is because such a system can improve efficiency within your organization and, as a result, increase productivity. Effective business intelligence can also improve the decision-making processes at all levels of management and improve your tactical strategic management.

    Yet by forgoing investments in these BI tools, teams are failing to investigate their processes and methods that would improve their team and minimize alert fatigue.

    A Call for Smart Alerting

    The lesson can be drawn from this is that companies don’t necessarily need more alerting. What they do need is to shift toward more smart alerting.

    Smart alerting means that not every bump on the monitoring screen gets tied to an alert. Instead, monitoring output is calibrated so that possibilities are aligned with probabilities and impacts. Alerts also get sent to the teams or individuals that are best able to manage the issue. Additionally, alerts are actionable and come with instructions regarding what the problem might be.

    Smart alerting also means that teams use business intelligence tools such as reports and graphs and charts to determine which of their practices have been effective or not effective. Without this insight, teams are often unaware of the subtle points that could really impact their team and provide them with a way to improve their output.

    Conclusion

    There are a number of insights that can be garnered from our survey. I encourage you to take a moment and download a copy of the study and see what you can learn that will help your team.

    — Orlee Berlove

  • Making Software Maintenance Cool Again with DevOps

    Making Software Maintenance Cool Again with DevOps

    What makes DevOps so important? Part of the answer lies in how DevOps encourages more appreciation for and investment in software maintenance.

    Traditionally, the IT industry has been like the construction industry. People who design new things (architects or software developers) are at the top of the value hierarchy, whereas the folks who build and maintain them (construction workers and IT Ops admins) are not held in such high esteem.

    This isn’t to say people hate admins, of course (or construction workers, for that matter). What I mean is that the work of building and maintaining tends to be seen as less creative and exciting—and ultimately less important—than the work of designing new things.

    This is why software developers in the pre-DevOps world got most of the glory. They created new code that did exciting things.

    Meanwhile, admins on the IT Ops team were stuck deploying and maintaining that code—and occasionally cleaning up messes created by developers who wrote bad code. Admins were also the first folks to take the blame when something went wrong.

    This isn’t to say that developers cause all the problems, of course. Some mistakes can be attributed to admins. Others are the result simply of poor communication between developers and admins.

    Still, in general development work—which involves creating new features and innovations—was what was celebrated. Maintenance work performed by IT Ops was less glorious.

    DevOps and Software Maintenance

    One of the most important—yet also most underappreciated—results of the DevOps movement is that it has made software maintenance cool again.

    In addition, DevOps provides more organizational support for maintaining software, while also facilitating the type of communication between developers and admins that leads to better maintenance.

    DevOps does this through principles such as the “you build it, you own it” mantra, which stipulates that whoever writes code is also responsible for deploying and maintaining it.

    Even if your organization doesn’t adopt that particular DevOps practice, it probably still seeks greater collaboration between developers and IT Ops. As a result, when something breaks in production or needs to be upgraded to maintain reliability, developers are involved, too.

    Celebrating Software Maintenance in DevOps

    Despite the emphasis that DevOps has brought to software maintenance in practice, you still don’t hear a lot of talk about maintenance work in the DevOps world.

    In essence, coding is still seen by many people as the coolest type or work that is done in the DevOps world. What DevOps has done is break down the silos separating those who code from those who maintain. It hasn’t necessarily made maintenance itself the object of more excitement.

    It may be time for that to change. Forward-thinking organizations should recognize that software maintenance—which includes tasks such as applying updates, monitoring applications and scaling host infrastructure—is just as crucial for a seamless application experience as the applications themselves. This should become an explicit part of the DevOps conversation.

    — Chris Tozzi

  • What Developers Want, and How to Give It to Them

    What Developers Want, and How to Give It to Them

    Software is at the core of every modern business, and software-driven companies are disrupting most traditional industries. As the demand for rapid delivery in digital services grows, companies are looking for ways to release products and upgrades in weeks instead of months, or in days instead of weeks. Many DevOps groups are adopting the continuous integration/continuous delivery/continuous deployment cycle of Agile software development to address the high velocity of releases and faster time-to-market requirements. In the CI/CD/CD cycle, developers and testers continuously integrate and test new code, deliver applications and upgrades to production, and from there, deploy them to customers through cloud- or web-based venues.

    But in most companies, dev/test teams are dependent on IT and operations (IT Ops) teams to provide the physical and software stacks they need, and IT Ops teams can’t provide developers and testers with infrastructure and applications fast enough to meet the ongoing and relentless pace of the CI/CD/CD cycle.

    DevOps Challenges

    The most common IT Ops obstacles are long procurement and provisioning cycles, lack of automation and organizational silos.

    Long Procurement and Provisioning Cycles: In many software companies, the IT Ops team has a lengthy procurement and provisioning cycle, and developers may have to wait anywhere from several days to a few weeks for IT Ops to handle each request.

    Lack of Automation: Developers may be using an outdated IT ticketing system to request infrastructure and software. Each time a developer issues a ticket request, an IT Ops person must follow a certain workflow to fulfill that request, and must complete each step before sending the ticket on to the next IT Ops person in the chain. These workflows often consist of time-consuming manual steps. For example, an IT admin may spend hours manually copying database software from a file server over to the hardware using command line interface (CLI) scripting. The admin must then install and configure the database software and connect it to the network.

    Organizational Silos: In large enterprises, individuals or sub-teams fulfill certain tasks for a dev/test request separately from the others. These silos turn IT Ops procurement into a long series of handoffs, where each team member must complete their assigned tasks before handing the job off to another team member.

    What’s a company to do? The answer is to implement a self-service, automated private or hybrid cloud. Here are some of the reasons for this approach.

    On-Demand, Self-Service Provisioning

    Every developer is different, and each should have the power to create their own workspace. A self-service cloud automates the provisioning process by letting developers and testers manage their own initial deployments and configurations. The cloud platform should offer a set of automated provisioning tools to allow developers and testers to create their own dev/test environments. The cloud solution should include both a self-service user interface and an API-driven infrastructure-as-code that lets developers create VMs and databases, access storage, set up network connections, etc., using RESTful API coding.

    An Intelligent, Well-Organized User Interface

    A self-service cloud should have an intelligent user interface (UI) that gives developers access to a set of common infrastructure tools and applications. Ideally, a self-service UI should allow IT Ops administrators to assign resources in an organized manner. Admins should be able to designate business units (BUs) on the UI (i.e. “AppDevTeam1,” “WebDevTeam1”) based on units within the company, assign team members to BUs, and designate current projects (i.e. “AppDevProject1”) on the UI according to BU. They should also be able to assign quotas to each BU (i.e. AppDevTeam1 gets 100 VMs, 25 vCPU cores, 100GB memory and 400GB storage), and to each individual project (i.e. AppDevProject1 gets 10 VMs, 5 vCPU cores, 8GB memory and 40GB storage).

    An Application Store

    A self-service private cloud should have an online “application store” that provides single-click access to common tools and services for CI/CD, workload management, middleware and storage back-ends.

    Seamless, Two-Way Hybrid Cloud Migration

    A self-service hybrid could should have seamless, two-way migration to allow developers and testers who have public cloud access to easily move applications and workloads back and forth between public and private clouds.

    Administrative Dashboards

    A self-service cloud should have a set of administrative dashboards that allow the IT Ops team to control access to resources on the UI. These dashboards should deliver complete visibility into which teams and team members are using which resources, and allow the IT Ops team to perform admin tasks such as:

    • Creating user accounts and passwords on the UI
    • Creating BUs, and projects for each BU, on the UI
    • Assigning developers and testers as “members” of a certain BU or project
    • Assigning self-service infrastructure tools (compute, storage, network) on the UI, and set quotas for those tools according to BU or project
    • Importing new applications to the application store or the UI.

    A Software-as-a-Service Platform

    A software-as-a-service (SaaS) platform with portal-based access is the best venue for a self-service cloud solution. A SaaS platform offers the flexibility to do upgrades and customization to the various features of the UI, application store and administrative dashboards. The flexibility of the SaaS private-cloud solution gives it the potential to become the de facto standardized platform for CI/CD/CD in Agile software development.

    In short, DevOps teams need to keep up the CI/CD/CD pace in a modern enterprise, and self-service cloud platforms offer the self-provisioning and customized workspaces that keep developers productive and happy.

    About the Author / Kamesh Pemmaraju

    Kamesh Pemmaraju leads product management, product marketing, and technology partnerships at ZeroStack. Kamesh is a seasoned product management/marketing leader with a strong engineering and consulting background. In his most recent product roles at Mirantis and Dell, he focused on delivering private and hybrid cloud solutions to enterprises. He holds a Master of Science in Computer Science from Indian Institute of Science. Connect with him on LinkedIn and Twitter.
  • Now is the Time for Full-Stack Operations

    Now is the Time for Full-Stack Operations

    The idea of “full-stack developers” is becoming a fairly common one, although it is still widely contested. But what about full-stack operations?

    There are cycles in the IT industry, and if you wait long enough, you can see the same ideas swing in and out of favor. Business applications used to be fairly monolithic, and so it was expected that their programmers would have a good understanding not just of the application’s code and business logic itself, but of its underpinnings as well.
    Stacked stones

    Over time, different parts of those underpinnings were separated, breaking out data silos in a process of modularization. With the increasing complexity of architectures, the expectation became that specialists would be in charge of each module and simply ensure that standard interfaces were available to teams whose modules needed to interact with each other.

    While modularization at the architecture level is here to stay, there is now some push back against it being extended too aggressively to the hum

    an developers in charge of building the system. This takes the form of a quest for “full-stack developers,” who are able to understand all the nuances of the entire application stack.

    There is a similar need on the IT operations side of the house. Different specialized support teams used to be able to focus on one particular area (server, network, database, middleware and so on) and use their own specific tools to analyze and understand the performance of one particular module of a complex enterprise architecture. The assumption was that if each module was up, then ipso facto, the entire stack was up, and therefore the application as a whole was also up.

    As it turns out, it’s not that simple.

    Let’s Do Some Root-Cause Analysis

    These days, failures of business services rarely are caused by a catastrophic outage of one particular component. Hardware is cheap, resiliency is built in and experience from web-scale environments has trickled down to become common best practices. What actually causes problems—such as getting you embarrassing news coverage or angry customers demanding refunds—is the unexpected: many seemingly minor and isolated issues that suddenly add up to a big problem.

    When this sort of cascading failure occurs, modular operations teams and processes are not able to cope. Multiple tickets are opened for each affected module and routed to that module’s support queue. Each of those tickets contains only partial information, by definition, and may even describe only a symptom of a failure in another module. Because of this, precious time is wasted diagnosing, reassigning and escalating those tickets, until eventually a complete picture of the actual problem is laboriously assembled.

    At this point, representatives of all of the various affected support teams assemble, either in person or on a conference call, and try to determine what to do to restore service as quickly as possible. All too often, these efforts are further delayed by unproductive blamestorming and finger-pointing, but eventually, the issue does get resolved.

    Given the complexity of modern-day enterprise architectures, it is impractical for any single IT operations specialist to understand the entire stack in depth, including all the interactions between different modular components. Even if it were possible to do so for a snapshot in time, these days most environments are self-modifying to a greater or lesser degree, provisioning or decommissioning capacity in response to demand, balancing load across available resources and performing routine maintenance tasks. This sort of dynamism is impossible for humans to model accurately in real time.

    How Is It Possible To Do Full-Stack Ops?

    No single person can be a full-stack ops specialist, but that does not mean that the whole team cannot work to deliver full-stack support. The key is to break down the walls between the different siloed teams supporting each module, and make it easier to build an overall picture of, yes, the full stack that is supporting a particular business service.

    This bringing-together must happen in real time, because that is the pace of business today. An outage that has a technical duration measured in a handful of minutes may cause hours-long business repercussions. Ops teams need tools that can relate signals from different modules into a comprehensive picture of what’s going on in the IT environment, proactively inform the right people, and give them the support they need to pool knowledge and work together effectively to resolve the outage and restore service to affected users.

    These tools cannot be simple incremental improvements in the monitoring of one particular module, important as that is. The responsiveness that the organization as a whole expects from its IT operations requires that silos be broken down and information and expertise be pooled. Real-time collaboration between specialists in different domains is the only way to deliver truly full-stack operations.

    The rapidly maturing discipline of AIOps aims to do just that. The beauty of this approach is that, unlike rip-and-replace approaches in the past where moving to the new thing meant ripping out the old thing, AIOps takes advantage of what was done in the past, simply joining together what were previously disconnected islands of knowledge and making information available when it is needed.

    Gartner Market Guide for AIOps PlatformsTake a look at some of the players building out these capabilities in the AIOps Market Survey from Gartner. Normally these documents cost $1,295, but you can get it for free courtesy of Moogsoft at this link.

    — Dominic Wellington

  • Nutanix Extends DevOps Ambitions

    Nutanix Extends DevOps Ambitions

    Nutanix at its .NEXT Europe conference has signalled its ambitions now extend into the realm of DevOps. The company announced it will make available an Acropolis Compute Cloud (AC2) and an Acropolis Object Storage Service on top of its Enterprise Cloud OS software that creates an instance of a hyperconverged infrastructure (HCI) platform that can be deployed on-premises or in a public cloud.

    In addition, Nutanix is embedding an App Marketplace in its Nutanix Calm orchestration software through which applications developed on top of Enterprise Cloud OS can be accessed.

    Finally, Nutanix has added Veritas Technologies to the list of providers of data protection software that can be employed to provide backup and recovery software for applications running on top of its core AHV hypervisor.

    Greg Smith, vice president of product marketing for Nutanix, says his company is now moving well beyond simply trying to combine compute and storage in a locally deployed appliance. It envisions organizations employing Enterprise Cloud OS to drive hybrid cloud computing applications across a consistent set of automated orchestration services based on a common platform optimized around an HCI architecture.

    HCI architectures were pioneered by cloud service providers, and Nutanix applied those concepts to local data centers in the form of an appliance. The company then took the software it developed for the appliance to create a portable cloud operating system environment it is now extending with, for example, an object service that is compatible with the S3 interface defined by Amazon Web Services (AWS).

    Smith says Nutanix is making the compute and storage services available on top of Enterprise Cloud OS as an alternative to more expensive compute services based on platforms such as VMware. Nutanix is essentially in a race against other providers of HCI software to extend the reach of its platform. VMware, for example, has made its software stack available on the IBM Cloud and similarly is working to make its software available on AWS. Smith says the Nutanix approach gives IT organizations more control over where they want to deploy HCI software on any platform, including server platforms from Cisco Systems, Dell EMC, Lenovo and Hewlett-Packard Enterprise (HPE) if they so desire. All three of those vendors also provide access to rival HCI software platforms.

    Nutanix developed its own hypervisor on which Enterprise Cloud OS is built to enable its software to be deployed on multiple platforms. But just to make things more interesting from an IT operations perspective, Nutanix also has HCI software that can be deployed on a VMware hypervisor.

    Against that backdrop, IT organizations are trying to determine the rate at which they want to replace traditional rack-based systems with HCI platforms, which combine compute and storage to reduce the total cost of operating an IT environment. Most legacy applications still expect to access external storage. But as new applications are developed, the expectation is that most of them will run on some form of an HCI platform that can scale out to support a much broader range of applications.

    It’s not likely legacy applications running on rack systems will go away anytime soon. But it is apparent that IT operations teams will be managing a mix of rack and HCI systems for years to come.

    — Mike Vizard

  • Building a Services and IoT Platform with DevOps, Part 3

    Building a Services and IoT Platform with DevOps, Part 3

    Business needs and IoT demands are taking new dimensions in connecting millions of devices, people, process, tools and systems. With endless possibilities of creating new IoT solutions, DevOps teams are the key players who handle the challenges in successfully rolling out a IoT solution while handling the business, development, operations and infrastructure demands in the background. This article focuses on some of the DevOps best practices to adopt during IoT development, enabling faster time to market.

    DevOps practices to adopt during IoT development

    1. Adopt Security by design – Teams need to be educated and made aware of security threats. Use threat models mitigation techniques such as using authentication; storing secrets separately and protecting those secrets; using tamper-resistant protocols, digital signatures, timestamps, audit trails, encryption, authorization policies, filtering; and running services with least privileges during security design and development.
    2. Shift left security analysis and security testing – Integrate security analysis tools, customize security compliance rules and run security testing as part of continuous integration pipeline, generate security threat reports on vulnerabilities and act on these threat reports to fix issues early in the development phase and minimize the security risks.
    3. Follow security standards during development such as security development life cycle (SDL), which has guidelines and measures for building the software for devices and application components of IoT platform.
    4. Perform code reviews for device software, application software, PaaS rules and configurations, as quality assurance can become a huge risk given the complexity of the infrastructure, millions of devices connecting and dynamic environment configurations. Code review tools need to be integrated to the CI pipeline with pull request code review.
    5. Use the right branching policies in a version control repository, including precommit/preflight builds, pull requests for merging the code changes and access control for maintaining branches and using the right branching strategies, as there will be multiple fragmented development and deployment pipelines for devices and application developments to reduce the overhead. Use distributed repository/central repository with traceability and auditability based on the requirements.
    6. Automate deployments and create deployment pipelines for device development, application development, infra-automation scripts development with build and deployment pipelines targeting for different target endpoints.
    7. Customize the builds and release pipelines to pull the packages from multiple build and deployment pipelines to integrate and deploy as units of deployment.
    8. Plan for frequent release cadences—say, monthly—for application rollouts. Release cadences for firmware update rollouts can be planned for three to six months, as device updates cannot be pushed so often.
    9. Continuously monitor deployments – Use a release management tool for orchestrating the releases and release coordination activities, with gated checks and approvals with a view of what is getting deployed to each environment, as well as traceability and audit.
    10. Enable feedback loops and automated alerts if firmware deployments or application updates fail.
    11. DevOps teams can define key tenets, criteria to be met and standards to be followed for the devices; infrastructure to be provisioned; device protocols usage and standards in connecting to existing/new devices and services. This can reduce the complexity in development and deploying to multiple varied devices by following the same protocols for connectivity and communication.
    12. Train the team of developers, QA and hardware developers on how to do continuous integration for IoT development, follow agile and lean practices and ensure security criteria for all layers of the application and in process.
    13. Adopt user-centric test automation and end-to-end testing approaches and build robust test cases in perspective of testing a complete flow, with devices/services that may not be in your scope but will be part of your overall IoT platform ecosystem.
    14. Create/utilize container based test environments and device simulators coupled with service virtualization for functional testing.
    15. Automated infrastructure provisioning – Use the right configuration management tools to automate the infrastructure along with dependencies to create environments through code instead of provisioning basic VMs.
    16. Use container and cluster management tools such as Docker Swarm or Kubernetes for service discovery, auto-scaling, self-healing and scheduling.
    17. Use RBAC, service accounts and security access controls in the infrastructure templates/scripts that are created instead of individual user credentials to limit the risk of unauthorized users provisioning the environments using scripts. Build security in devices, cloud security, application security and infrastructure automation templates. Use secrets, key vaults, encryption methods and certificates to secure the credentials and access control.
    18. Configure individual build and deployment pipeline jobs for application development and infra-automation development, as there will be a huge development effort involved in automating the infrastructure.
    19. Create infrastructure verification tests with scripting tools such as Python or use testing frameworks such as Pester or any other open-source tools and integrate the infrastructure tests with the CI/CD pipeline. Ensure to run these tests every time the infrastructure is provisioned.
    20. Version-control the infrastructure templates, scripts, user profiles, environment configurations and device configurations apart from source code.
    21. Set up a centralized dashboard of monitoring tools to monitor the clusters, nodes, firewall rules, VMs, applications, devices and services. Feedback should flow back to developers/QA/DevOps teams.
    22. Configure applications to provide logging about exceptions, memory leakages and response times and push the logs to the monitoring tools or the dashboards in monitoring tools.
    23. Use the telemetry from the applications and devices to derive the analytics graphs/trends and set up KPIs/metrics to measure application performance/availability, as well from derive business metrics to set SLAs for DevOps and operations, to improve productivity.
    24. Ensure DevOps teams have close coordination with dev/QA teams of both software and hardware teams, as managing IoT platforms need more skill and expertise in hardware and software in the IoT domain.
    25. Manage legacy and cloud infrastructure with multicloud management platforms, and monitor and optimize the infrastructure usage.
    26. Create a DevOps governance plan/guide, with clearly defined access control policies, access rights for devices, control limits on infrastructure provisioning in different clouds, limits on PaaS/IaaS services to be used, etc., and standardize the process to be followed in DevOps/development/testing/operations, tools, etc.

    Following DevOps practices for application development has become quite streamlined in recent years. However, in IoT, where traditional methodologies and practices are followed in industrial enterprises, adapting to agile methodologies and following DevOps practices coupled with right DevOps-skilled team, tools and expertise can streamline and simplify IoT developments.

    About the Author / Lavanya Subbarayalu

    Lavanya Subbarayalu is Senior Architect working with Technology Office in HCL Technologies. She has expertise in IOT, Azure, DevOps consulting & Microsoft technologies. She is associated with DevOps COE, working on design and Development of DevOps solutions and consulting tools. Connect with her on LinkedIn.
  • Measure What’s Important: DevFinOps

    Measure What’s Important: DevFinOps

    Lately there seem to have been quite a few DevSomethingOps terms being coined. However, I do think we need one more: DevFinOps.

    Dev-What-Ops?

    One of the biggest problems in IT is working out the cost of IT. Left unchecked, IT will expand to fill whatever budget it is given. This may mean evermore involved business continuity and redundancy, reinventing evermore elaborate wheels, irrational versus buy decisions and so on.

    In fact, the whole idea of cost estimates for IT projects has become something of a joke. Most IT projects are reputed to exceed their budgets.

    There is an entire #NoEstimates movement that rejects the idea that it is even possible to deliver a sensible estimate for a software development project. As is often the case, the basic idea is reasonable:

    it is possible to do small chunks of work incrementally, leading as rapidly as possible to a desired shippable product, and that when you do that there is no need to do much of anything in the way of estimating stories or the project.

    However, the simplistic interpretation that is all over Twitter is that because there is no estimate of the  overall project, there is no estimate at all. That is not the idea! It is simply to break down the overall estimate (which is probably wrong) and instead budget for much smaller chunks of work, which can presumably be estimated more precisely and accurately.

    So What Can We Do?

    Maybe what is required is integration of financial concerns directly into the fabric of IT development operation. We might call this DevFinOps, in line with other extensions of DevOps such as DevSecOps or DevNetOps.

    This is not such a leap; after all, we already integrate costs in areas such as SLA calculation, estimating the TCO of a tool or the ROI of a proposed purchase. However, these are generally calculations that are made after the fact, and may even be retconned to fit external assumptions.

    What I am proposing, though, is to build this information right into the IT metadata and processes to enable us to make better decisions.

    This is not IT Asset Management, although it would build on those data and extend their reach. A particular device or piece of hardware has its purchase price and current amortised value documented in the ITAM database, but the actual value it has at any given time might vary depending on which business function it is currently supporting. This calculation should change over time to reflect the real current value it is delivering to the organization at any given time.

    An idle server has no particular value beyond the intrinsic value of the hardware, back-end support (floor space, network, cooling, etc.), and perhaps any associated licensed software. However, the same server will take on a much higher value to the organization when it is provisioned as part of the infrastructure supporting a major business-critical application.

    Performing actions on these systems would therefore have different potential impacts, and should be treated as costs deducted from a limited budget. Live-patching a business-critical server is an expensive operation, not to be treated lightly. The cost of doing so should be deducted from an operational budget.

    This calculation has the benefit of making it easier to communicate the different impacts of various proposed courses of action outside the IT department. Deciding between cloud and on-premises deployment options, or between different flavors of cloud, can be a fraught process. Technical options and pricing models are rarely easily comparable, and then there are other costs such as compliance (yes, and GDPR) or vendor risk. Quantifying and normalizing these disparate factors would make it that much easier to compare options up front and calculate benefits after the fact.

    Is This Even Possible?

    Google already does something like this in its Site Reliability Engineering (SRE) program, with the notion of an error budget:

    The business or the product must establish what the availability target is for the system. Once you’ve done that, one minus the availability target is what we call the error budget; if it’s 99.99% available, that means that it’s 0.01% unavailable. Now we are allowed to have .01% unavailability and this is a budget. We can spend it on anything we want, as long as we don’t overspend it.

    There is a long and sordid history of attempts to make programming projects comparable and their estimates more reliable. Often this devolves to simply counting lines of code, according to the age-old management syllogism: “We need to measure something; this measurement is easy to gather; let’s measure this!” and of course the Mythical Man-Month.

    Fortunately, there is a way to calculate the complexity, and therefore the potential cost impact, of a piece of code: the Halstead volume. This is a measurement of the complexity of code, described in terms of the number of distinct operators, the number of distinct operands and the total number of operators and operands. While it is not guaranteed to be perfectly accurate in every case, it is at least accurate enough to be comparable, and therefore can be used to estimate the risk of a change, in terms of the relative Halstead volumes of the code to be changed and the patch to be applied.

    But What About the Squishy Meatbags?

    Connecting the human costs would also enable other metrics to be gathered. It has been historically difficult to differentiate between what is urgent and what is important, and how to prioritize each. If we connect salary data (including overtime) to changes, it becomes much easier to make the call on when enough time has been wasted on a problem and the cost-effective solution is to start from scratch.

    It sounds like a lot of work to gather all of this information, but these data already exist; they’re just not connected up in one place. When the business wants to launch a new service, there are (usually) pretty rigorous calculations behind that decision. The expectation is to acquire or retain a certain number of customers who have a certain average lifetime value and break-even points and other criteria are all mapped out ahead of time. For whatever reason, though, these islands of information are rarely if ever connected up.

    This, incidentally, is just one reason why it can be worthwhile to work with reputable and experienced vendors. I have written before about what this process looks like. The good vendor sales teams will help to unearth this sort of information—but even in the most positive sales processes, the kimono is rarely fully open. There is far more information inside the organization that could be enormously useful if only it were available in the right place and at the right time.

    Longer term, this would mean that business cases and ROI calculations would finally be concrete and factual, rather than extended performance pieces in the medium of spreadsheets. On that note, there is a wonderful little book, titled “How to Lie with Statistics,” which is even available as a free PDF. It’s one of those books that is fun to read because you start spotting the things it was talking about simply everywhere.

    If you wanted to be maximally Zeitgeist-compliant, you could probably verify all of this with blockchain, although I worry that the transaction costs (including thermal costs!) would be prohibitive. The good news, though, is that you could use this DevFinOps methodology to work that out too …

    All That Effort, for What?

    Bottom line, the goal is to be able to calculate (at least within reasonable limits) how much IT is costing today, and what the impact of any proposed changes would be—and crucially, to do so in real time.

    The goal is agile cost estimates. There is a reason I chose the DevFinOps coinage. The way we do cost estimates today is very “waterfall“: large teams have extended arguments over spreadsheets, and the process is so painful and expensive (in person-hours and disruption) that it is only undertaken for the largest changes.

    Agile’s faster release cycles do not align at all well to this process, which is where #NoEstimates is coming from. However, if we start gathering and processing all the cost data in real time, and make it available via a simple API call, it becomes possible to calculate both ends of the cost of a proposed change: the complexity of the code itself, and therefore the probability that it contains bugs, and the infrastructure impact that the deployment will have. This cost can then be compared to the team’s current SRE error budget to determine whether the change can be made automatically or whether it requires signoff as an exception.

    The result looks a lot like ITIL’s notion of a “standard change”, but without the inherent conflict between ITIL’s centralization and SRE’s decentralization. The key is a common accepted measurement of what a standard change actually is, which would otherwise require the ITIL Change Manager to make the determination ahead of time.

    What Does This Look Like in Ops?

    Let’s not forget Ops, either. Proper cost estimates like the ones described above would enable Ops to prioritize alerts correctly and estimate impacts accurately. Two outages with equal technical severity may have very different business impacts. Today, that reconciliation relies on tribal knowledge and systems that are often inaccurate or out of date. Given a central shared repository of data that describes the value of deployed systems, it becomes possible to calculate those impacts much more accurately.

    While we work to get to full DevFinOps, you might want to consider AIOps, which helps gather a contextual view of what is actually going on in IT. Gartner just released a Market Survey for this emerging space. Normally these documents cost $1,295, but you can get a free copy here, courtesy of Moogsoft.

    Dominic Wellington is Chief Evangelist at Moogsoft. He has been involved in IT operations for a number of years, working in fields as diverse as SecOps, cloud computing, and data center automation.

    — Dominic Wellington

  • Operations Management Puts the ‘Ops’ in DevOps

    Operations Management Puts the ‘Ops’ in DevOps

    Awareness and anticipation of operational management, best practices can improve your app at every stage of its life cycle

    How important or interesting you find the “operations management” aspects of DevOps methodologies likely depends on your background, experience and how many operational horror stories you have lived through. If you have been on the hot seat when services are impacted, woken up in the middle of the night when major outages occur or dragged into blame-battle war room calls while you and your team scramble to restore service, then the importance you place on operations management may be very high.

    However, if you have avoided such experiences, it would surprise no one if the operations management aspects of DevOps are not top of mind. When everything is smooth sailing, then it is understandable that you might be reluctant to make any significant changes to your daily routine. However, in agile, fast-moving environments, things can go wrong very fast, even if your organization separates duties intentionally to create an “operational firewall” to keep ill-advised code or configuration changes to a minimum. Using effective ways to lend your app expertise to assist during impactful situations can make your life much easier and limit disruption to conducting your other duties.

    You may work in an organization which is new to owning and managing operations management tools. It is becoming more common for organizations outside of a central IT operations team to do so as scopes of responsibility expand. Several analyst firms have published recent studies that nearly half of purchase and usage of operations tools is already done outside of IT operations teams. This trend is predicted to grow to the majority in a few years.

    Configuration and automation tools are also becoming more commonly owned outside the data center. Such shifts in responsibility make efforts of operational skill-building, incident readiness and resolution more challenging. As the number of different groups deploying these tools expands, the likelihood of overload of notifications, alerts, events and general operational noise starts to rise dramatically. Note: I will be presenting a webinar on how new operations management tools can help you carry out the best practices, join me in this conversation Thursday, Oct 26.

    Organizations deploying new apps and management tools in the cloud naturally look to manage those workloads from the cloud as well. Other organizations with legacy applications often are managing digital transformation leading to transformative projects for operations management. Whether your organization is already leveraging cloud-based tools or you are part of an organization undergoing transformation, you may have the challenge of a hybrid set of workload deployments, both cloud-based and on-premises. For your organization, this could mean finding a pragmatic complementary approach to deploy and manage the new, cloud-based applications and their associated management tools. Such an approach may not need to be isolated from your current tools and methods. Sufficient tool interoperability could support a federated, phased path.

    In this blog series, we will explore the common operational challenges many DevOps teams are facing today, how traditional IT operations best practices could be leveraged for use in a DevOps methodology and how new operations management tools can help you carry out those best practices to meet your goals on an on-going basis.

    Here’s a preview of the forthcoming blog topics:

    Let the Noise Wail Without Going Deaf

    Unless your applications and services exist in a vacuum sealed chamber of silence, agile development, continuous rollouts and updates and infrastructure system changes create a plethora of events that range in severity of impact, validity and meaningfulness. Those events tend to come from multiple monitoring and configuration tools or reflect many different parts of your applications and underlying services. This mixture of events and alerts leads to what is commonly known as operational “noise.”

    Smart Ops Action: Taking the Right Action for Ops Traction

    Empowering anyone in your organization who contributes to restoring service when incidents occur can ensure their time is well spent, with the intended results. All too often, operations teams effectively identify and triage incidents, yet fall short of empowering first responders to actually resolve problems. Bolstering your team’s efforts to take the actions necessary to resolve the situation at hand and restore service promptly is achievable—if done right.

    Boring is Best! How Can You Thrill Your DevOps Stakeholders with Boredom?

    Strive for stability and structure in production without stifling development agility. Don’t try to thwart the innovation and chaos that results from agile development and constant rollouts—get structure and stability where you have control so you can focus your talented team members to be supportive, valuable contributors to innovation and agility.

    Fuel innovation and make your stakeholders smile with boredom by effectively turning chaos into stable operations.

    If you’re a veteran IT operations practitioner with years of experience helping your company’s applications, services and underlying infrastructure run efficiently, these tips may be obvious. Hopefully you’ve been successful advocating these best practices to your development and line of business colleagues.

    If you are new to operations—and especially if you are amongst the growing population of DevOps professionals who are understandably reluctant to conduct triage, investigation, diagnosis or resolution of operational incidents—rest assured there is relief. Tried-and-true best practices carried out with new, easy-to-use tools can empower your team to conduct these unwanted tasks like a seasoned veteran, regardless of operational experience. Learn more.

    About the Author / James Moore

    James Moore is Principal Offering Manager, IBM, responsible for offering management and strategy for IBM HybridCloud Operations Insight solutions including IBM Cloud Event Management, Runbook Automation and Alert Notification. James joined IBM from the Candle acquisition in 2004, where he was product manager for Candle’s Application Response Time product lines. James has over 15 years’ experience in event management, application performance management, and business service management. Connect with him on LinkedIn and Twitter.
  • With a Multicloud Infrastructure, Control is Key

    With a Multicloud Infrastructure, Control is Key

    Ask any developer or DevOps manager about their first experiences with the public cloud and it’s likely they’ll happily share some memories of quickly provisioning some compute instances for a small project or new app. For (seemingly) a few pennies, you could take full advantage of the full suite of public cloud services—as well as the scalability, elasticity, security and pay-as-you-go pricing model. All of this made it easy for teams to get started with the cloud, saving on both the IT budgets and infrastructure setup time. Public cloud providers AWS, Azure, Google Cloud, Rackspace and others made it easy to innovate.

    Fast forward several years and the early promise of the cloud is still relevant: Services have expanded, costs have (in some cases) been reduced and DevOps teams have adapted to the needs of their team by spinning up compute instances whenever they’re needed. But for many companies, the realities of their hybrid-IT infrastructure necessitates support for more than one public cloud provider. To make this work, IT Ops needs a control layer that sits on top of their infrastructure, and can deliver applications to customers over any architecture, including multicloud. This is true, no matter what the reason teams need to support multi-cloud environments.

    Prepare for the Worst

    As any IT Ops manager, or anyone who has lost access to their web app knows, outages and cloud service degradation happen. Modern Ops teams need a plan in place for when they do. Many companies choose to utilize multiple public cloud providers to ensure their application is always available to worldwide customers, even during an outage. The process of manually re-routing traffic to a second public cloud in the event of an outage is cumbersome, to say the least. Adding an app delivery control plan on top of your infrastructure allows companies to seamlessly and automatically deliver applications over multiple clouds, factoring in real-time availability and performance.

    Support Cloud-driven Innovation

    Ops teams often support many different agile development teams, often in multiple countries or from new acquisitions. When this is the case, it’s likely that the various teams are using many architectures on more than one public cloud. Asking some dev teams to switch cloud vendors is not very DevOps-y. A better option is to control app delivery automation with a cloud-agnostic control plane that sits on top of any cloud, data center or CDN architectures. This allows dev teams to work in their preferred cloud environment, without worrying about delivery.

    Avoid Cloud Vendor Lock-in

    Public cloud vendors such as Amazon Web Services or Microsoft Azure aren’t just infrastructure-as-a-service (IaaS) vendors, they sell (or resell) products and services that could very well compete with your company’s offering. In the beginning, using a few cloud instances didn’t seem like such a big deal. But now that you’re in full production and depend on one of these cloud providers for your mission-critical app, this no longer feels like a great strategy. Adding a second public cloud to your infrastructure lessens your dependence on a single cloud vendor who you may be in “coopetition” with.

    Multiple-vendor sourcing is a proven business strategy in many other areas of IT, giving you more options during price and SLA negotiations. The same is true for IaaS. Cloud services change often, as new services are added or removed, and price structures change. Taking control over these changes in public cloud service offerings, pricing models and SLAs is another powerful motivator for Ops teams to move to a multi-cloud architecture. An application delivery automation platform that can ingest and act on cloud service pricing data is essential.

    Apps (and How They’re Delivered) Have Changed

    Monolithic apps are out. Modern, distributed apps that are powered by microservices are in. Similarly, older application delivery controllers (ADCs) were built for a static infrastructure world, before the cloud (and SaaS) were commonly used by businesses. Using an ADC for application delivery requires a significant upfront capital expense, limits your ability to rapidly scale and hinders the flexibility to support dynamic (i.e. cloud) infrastructure. Using ADCs for multiple cloud environments compounds these issues exponentially. A software-defined application delivery control layer eliminates the need for older ADC technology and scales directly with your business and infrastructure.

    Regain Control

    Full support for multicloud in product may sound daunting. After all, Ops teams already have plenty to worry about daily. Adding a second cloud vendor requires a significant ramp-up period to get ready for production-level delivery, and the new protocols, alerts, competencies and other things you need to think about. You can’t be knee-deep in the details of each cloud and still manage infrastructure. Adding in the complexity of application delivery over multiple clouds can be a challenge, but much less so if you use a SaaS-based application delivery platform. With multicloud infrastructure, control is key.

    About the Author / Andrew Marshall

    Andrew Marshall is the Director of Product Marketing for Cedexis, and has driven product marketing efforts at New Relic, Amazon Web Services and Microsoft. Connect with him on LinkedIn.