Tag: devsecops

  • DevOps and Security: Focus on Importance

    DevOps and Security: Focus on Importance

    Why have I written “DevOps and Security” and not DevSecOps or one of the other names that floats around? Because this post is aimed to apply to everyone—not just those far enough along to have melded some of their security practices into DevOps.

    Note: After I wrote this article but before I posted it, Bill Doerrfeld wrote this excellent example/solution post. It’s worth a read.

    From the beginning, DevOps has struggled with a couple of touch points that don’t give themselves easily to the “frenetic movement” of DevOps. Security is one of those items. If your organization does manual vulnerability assessments, it is unlikely that this testing slips well into the DevOps process chain.

    Most organizations that are dead set on making DevOps their primary dev/test/deliver platform have simply put limitations on security—limiting what long-running processes can be part of DevOps or dropping unaccommodating processes altogether. Some spectacular failures have occurred because of this type of thinking—and more will come—but for many the benefits of DevOps outweigh the risks. Will I get flamed for this paragraph? No doubt. That doesn’t make it untrue.

    Given that IT has almost never given security the full leeway/authority that they want—and in shops where IT did, business often stepped in to say no—this really is not a massive change from how we have always done business. Just in the modern development environment, where a ton of libraries come from outside and configuration is software or data, there is a greater risk from running roughshod over the security team.

    So what can security do to minimize the risk? Start looking more at enterprisewide and architectural risk. Accept that app or app portfolio team X is not going to give you time/resources to thoroughly vet their product and focus on things such as configuration files and malicious code embedded in that external library “Bob’s Really Good GIF Drawer™” that the team insists on using. Focus on the database configuration being in GIT or a shared (public/private) repository and what mischief might come about should attackers get at that repository. Run some of the increasingly sophisticated checkers against external libraries and review the results. As has been the growing case for years now, use automation to at least minimally check apps for things such as SQL Injection, but focus actual man-hours in places that might impact more of the organization. It might be worth the fight to get a full-on security review for applications or an application portfolio that touches the customer database, but perhaps not so much for the app used to schedule a conference room, even if customers are using it (unless it touches the customer database, of course; then see the first part of that statement).

    Worry about network configuration as code, database configuration as code and the whole slew of unique security issues that come from public cloud. They’re manageable, and there are tools to help. Just make sure you have it down, because architecture is going to be the new target. A hacker doesn’t have to hack your DC if you left a public cloud storage bucket misconfigured and the data they want is in that bucket.

    In too many organizations, the CISO is increasingly treated as chief compliance officer (assuming compliance does not interfere with DevOps cycles) with less to do with security and more to do with legal protection should security fail. Don’t be that organization. Security doesn’t have to be perfect; it just has to make you a hard enough target that only someone who really has it in for your company will keep trying.

    As for Devs doing Agile and Ops doing DevOps, as has been true from the beginning, some of the security burden needs to fall to you. Security doesn’t have its hands in what you do every day, so ask them for guidance, learn from them; make it so they need to be active in every step, then include them in every step, because the security environment changes faster than almost anything else in IT. And when you are implementing monitoring, include security monitoring. In most DevOps shops, the question isn’t, “What can we monitor?” but rather, “In this wealth of data, what do we want to monitor?” Well, the answer should include, “What security thinks will help protect us and our customers’ data.”

    As automation continues to increase, this tension will continue to ease, and focus can increasingly shift to locking down the really important bits such as database configurations and repositories. Until then, keep fighting the good fight and protect your customers’ ass(ets).

    — Don Macvittie

  • 3 Tips to Build A DevSecOps Organization

    3 Tips to Build A DevSecOps Organization

    For organizations undergoing digital transformation today, modernizing the existing environment can present serious challenges when it comes to security. Whether you’re dealing with a transition from legacy to cloud or hybrid models, or shifting from ITIL and waterfall methodologies to DevOps, the increasing number of technologies and complexity mean you need to rethink your security posture. The traditional approach to security—that is, a static strategy that largely involves patching on piecemeal measures at the 11th hour—is simply not a winning formula anymore, especially when dealing with requirements such as privacy compliance or contractual agreements.

    DevSecOps represents a fundamental shift in which real business needs drive a dynamic, living/breathing approach to security based on continuously changing requirements. To evolve from DevOps to DevSecOps, an organization must focus on integrating security into the very fabric of the software development cycle, and work to increase intelligence, situational awareness, and collaboration.

    Here are three critical ways to consider to ensure your DevSecOps strategy is up to snuff.

    Create a Single Source of Truth

    When you have multiple teams trying to work at breakneck speed, having one absolute source of data is essential. Gone are the days when we could rely on static spreadsheets that lived locally on this or that person’s computer, and even communication mechanisms such as email are too manual and out of sync to be trusted. What’s more, it’s impossible to draw meaningful correlations and map trends if your data is sitting in silos across your organization.

    Creating a single source of truth will ensure the greatest accuracy of information for everyone. You need to pinpoint where your data is coming from, how it should be collected and how it should be shared. You’ll want to integrate your full tool stack and workflow, and harness automation to streamline hand-offs between collaboration tools, system updates, chatbots and more.

    Shift Left: Secure By Design

    Relying on firewalls and antivirus as your primary security measures is a bad, bad habit. The key is instead to shift left of these elements and work to embed privacy from the start. This is the new age of security, using a risk-based approach instead of a reactive one—that is, identifying what needs protection, why it must be protected and how you will do so. It’s also understanding that security should not be just an external threat perspective, but also having visibility into what’s happening internally.

    The key drivers of your secure-by-design approach for DevSecOps should be privacy compliance, contractual obligations and threat models, both known and emerging. The goal here is to be proactive and avoid spending valuable resources to address threats or vulnerabilities that could have been prevented. And in case you didn’t already know, properly written, patched and documented code accounts for about 80 percent of security!

    Understand Your Environment

    If your organization has embraced DevOps, then you’re likely aware of necessities such as process, collaboration and automation. However, these can sometimes come at the expense of other important things, including privacy and security. A lot of this is due to lack of oversight and poor visibility into change management.

    As organizations accelerate their adoption of cloud services, threat vectors are ever-expanding. As such, you need to have complete situational awareness of your organization. You need to know what to monitor for and when, and this cannot be limited to the events directly related to security. Instead, focus on extending your perimeter of knowledge beyond your DevOps pipeline and ensure you’re monitoring everything from operating system logs and directory systems to DNS and servers. Without all of this context, there’s simply no way to correlate security incidents with other data from your IT environment. This is the information you need to document processes, workflows and playbooks, and ensure your teams can communicate and collaborate rapidly to address issues before the business is impacted.

    Remember, when it comes to the ultimate big-picture goal of DevSecOps, it’s always about minimizing the financial impact to your organization. Whether we’re talking about your reputation or lost time and resources, the bottom line is dollars down the drain. And the data is compelling so far—in its “State of DevOps 2017 Report,” Puppet found that high-performing DevOps teams experience a 96X faster MTTR from downtime and a 5X lower change failure rate compared to lower-performing teams.

    This article was co-written by Domnick Eger.

    — Robert Hawk

  • Are Developers Your First Line of Security Risk or Defense?

    Are Developers Your First Line of Security Risk or Defense?

    Every organization on the planet, whether public or commercial, is facing an ongoing challenge: to exist in an increasingly digital space. Past products must transform to meet the digital expectations of their customers, and new products must be built with “digital-first” frameworks in mind. After all, if they fail to meet these expectations, there’s almost certainly a competitor ready to swoop on the opportunity.

    So, what does that mean for all these businesses, old and new? It means they are employing teams of developers to create line after line of the code that forms their digital product or service.

    In this fast-moving, high-pressure environment, CIOs have become the new innovators, and are in positions of immense influence. However, they face a strong demand to meet rapid speed-to-market goals, enhance product quality with each update and increase flexibility. This has led to complex, often fragmented development teams whose primary focus is on rapid development of features and functions, without consideration of the vulnerabilities they could be creating in the code they are so quickly churning out.

    If our data is to remain safe, we must implement a new way of working. Just look at the catastrophic damage Equifax faced following its recent breach: a disaster that occurred as a direct result of insecure coding practices.

    CIOs and CISOs need to consider carefully whether their development teams are in fact the first line of data breach risk in the organization or the security champions, their company’s true “first line of defense” against cyberattacks. If they’re not the latter, they certainly could be.

    Secure Coding Checklist

    Where does your own dev team fit? I have created this Secure Coding Checklist to help CIOs and CISOs identify whether their development teams are truly equipped to be secure coding champions, helping to innovate with faster, better and safer code (or, indeed, whether you’re in need of a more robust security program):

    1. Is there acknowledgment at your executive C-level that traditional network security is no longer enough?

    These days, securing the network layer using traditional security measures is simply not good enough (and, let’s face it, is rarely successful anyway) even against semi-professional hackers. Among many consistent reports, Verizon’s “2017 Data Breach Investigations Report” cites that 35 percent of data breaches today are caused by web application vulnerabilities.

    Web application security is equally as important as network security; ignoring fundamental, protective AppSec measures could leave you well and truly open to a breach.

    2. Are you considering security from the start?

    The current approach to application security utilizes tools that focus on moving from right to left in the software development life cycle (SDLC). This, by design, supports a detection and reaction outcome. This means that security teams search for and detect vulnerabilities code that is already written, then react to fix them. According to the National Institute of Standards and Technology (NIST), it is 30 times more expensive to detect and fix vulnerabilities in committed code than it is to prevent them as they are written in the IDE. This doesn’t even take into consideration the production delays, double-handling and time spent in remedying any issues. Secure code champions start at the extreme left of the SDLC, with a focus on continually training their developers in secure coding, so they can be the first line of defense in their organization, preventing common vulnerabilities from occurring in the first place.

    3. Do you actually make the effort to build security skills, or are you just feeding knowledge?

    The vast majority of security training solutions (online and in-classroom) focus on building knowledge instead of building practical skills. For developers to thrive and engage in writing secure code, they need regular access to hands-on learning that actively encourages them to learn and build their skills in a real environment. They need to learn about recently identified vulnerabilities, in real code, and be able to work in their own languages/frameworks. This learning experience should help them understand how to locate, identify and fix known vulnerabilities in the code they are actively working on in the course of their jobs.

    4. Are you measuring your secure coding skills with real-time metrics?

    A vital step in ensuring a security-first mindset is being built within a development team is to collect and review evidence. Metrics seek to prove to the developer and their organization that their hard work is paying off, and secure coding skills are improving. You can’t improve what you cannot measure. There should be relevant assessments, and these should help identify the progress of your development teams in real-time as well as benchmarking their secure coding strengths and weaknesses for continuous improvement.

    5. How sure are you that any outsourced vendors are actively using secure coding techniques?

    Many organizations decide to contract out development work to other development houses. Whether they exist on- or offshore, their general secure coding abilities and practices are a relative mystery. In the best case, the only form of assurance an organization will receive relating to security is a statement in the contract requiring the deliverable to be “secure.” Few companies actually take the step to verify the skills of these development houses upfront, thus winding up with software that has been built without following sound secure coding practices. Worse yet, if the company is not aware of them, it risks going live with a vulnerable application.

    The most common scenario is that any vulnerabilities get picked up by dedicated security specialists (that come at a high cost) and you are faced with a delay of your go-live date, and possible contractual discussions on who needs to pay for fixing these security weaknesses. However, if you’re smart upfront and assess the application security skills of the developers who are going to build your next application, you save a lot of potential delay, frustration and cash.

    6. Are your developers aware of the most common security weaknesses?

    More than 85 percent of exploited web application vulnerabilities are attributed to just 10 known vulnerabilities—the OWASP Top 10. At a bare minimum, your application security training must cover these, in addition to many more vulnerability types. The training challenges your developers contend with must be actively revised and updated on a regular basis, with new challenges for either new coding frameworks or new vulnerability types.

    7. Do you have in-house security champions?

    Every developer-heavy organization should invest in a security champion—someone who is going to take responsibility for a security standard within the dev team. Their purpose is to be a support point of contact for anyone with questions around security, as well as become the chief advocate for following security best practice.

    8. Have you invested in tools for your developers to make secure coding easier?

    If your organization is one in which agile development is practiced, or indeed you are faced with frequent updates to company-built applications, automating parts of your security is one of the only ways to keep up with the frantic pace and volume of work.

    There are tools available at each stage of the SDLC that will serve as advisers, quality gatekeepers or detection tools. Ideally, you should have IDE plugins that focus on certain types of security bugs and act almost like a “spell-checker” while developers are writing their code. There are others that integrate with the build process, detecting certain types of weaknesses as the code is being submitted to a code repository.

    In addition, some tools run automated tests over the code, simulating attempted hacking once the software is in production. All have their own set of benefits and challenges, and none can provide a catchall, 100 percent guarantee that no security threats exist within the application. The No. 1 preventative measure you can employ is that the earlier you can capture the weakness, the faster and cheaper it is to remediate it with the least impact on your business.

    CISOs and CIOs are essentially forced to quickly and aggressively build their enterprise agile capabilities. As such, secure coding skills will be a weapon—not a hindrance to—innovation, and foregoing them could spell the absolute destruction of company reputation and data. Think twice before you skip this critical capability.

    So, how did your organization fare against this checklist?

    — Pieter Danhieux

  • How DevSecOps Can Help Avoid Catastrophic Breaches

    How DevSecOps Can Help Avoid Catastrophic Breaches

    Earlier this year, Tesla’s Cloud was hijacked and used to mine cryptocurrency, exploiting a vulnerability in the company’s Kubernetes cluster. A mountain of FedEx data was recently exposed, affecting 119,000 individuals. The Equifax breach garnered international attention after an estimated 145.5 million Americans were jeopardized. In other news, we’ve reported on how the Vine Docker registry fiasco was hacked, leaving an embarrassing PR trail in its wake.

    What is common across all these scenarios? They arguably could have been avoided with basic safeguards underpinned by a healthy dose of DecSecOps. In hindsight, let’s see what specific strategies developers can adopt to avoid such horrendous leaks.

    Basic DevSecOps Can Prevent Vulnerabilities

    DevSecOps is described as placing security at the forefront of every action. Within the world of cloud tooling, this means instilling protection at every point of the build life cycle. You would think this equates to advanced container and orchestration security, powerful access management and establishing hardened oversight for internal applications, right? Actually, many modern exploits simply involve a lack of basic password protection.

    Case Study No. 1: Tesla Cloud Cryptojacking

    In mid–2018, Tesla’s Amazon servers were hijacked by malware and used to mine cryptocurrency for rogue agents. Similar cryptojacking has transpired at Gemalto, Aviva and others. According to RedLock’s report, the hackers infiltrated the Kubernetes console, which was not password-protected. In one pod, they found access credentials to Tesla’s AWS environment. The breach exposed sensitive telemetry data, though was limited to “internally used engineering test cars only,” according to Tesla.

    How to Prevent

    Password protection for Kubernetes administrative consoles is a readily apparent lesson here. All cloud accounts, even if used internally, must be better-equipped and access credentials sequestered. Surely, instilling a “security by design” mentality can help limit the number of such consoles left accessible.

    Case Study No. 2: Vine Registry Breach

    In 2016 a white hacker by the alias avicoder was able to infiltrate Vine, the video-sharing social network. The hacker used tools to discover subdomains and behind one—https://docker.vineapp.com—found an open Docker private registry that housed the Vine source code. Such a vulnerability could have been used to collect user details or inject malware for malicious purposes. Thankfully, no users were compromised, and the Twitter Bug bounty program awarded avicoder a handsome sum for the discovery.

    How to Prevent

    In this particular incident, there was nothing at fault with Docker or Docker containers. The service (which was meant to be private) was simply left public and devoid of access controls. The lesson is that URLs on the world wide web are just that—publicly exposed to the world. It does not matter if no documentation links to them; such subdomains are easy to discover with crawlers and will be exploited if found.

    Case Study No. 3: Equifax Exploits

    In the Equifax breach, millions of customer records were stolen. The Equifax report notes that hackers exploited a “website application vulnerability.” Further reports detailed that the 2017 breach utilized flaws in Apache Struts, likely through a zero-day exploit, according to the Apache Struts Project Management Committee.

    How to Prevent

    Some note that the deserialization of untrusted data inherent in Apache Struts applications leaves some major vulnerabilities and potentially malicious code execution.

    Containers, due to their short lifespan, are not persistent, therefore making consistent hacking harder. They can also isolate functionalities so as to decrease attack vector. Regarding the Equifax breach, Aquasec speculates that container usage could have lessened the impact:

    “… it’s likely that such a breach would have been more difficult with containers, and that if successful, it would have been less persistent, not as widespread, and mitigated sooner.”

    Some view containers as a formidable force if armed with behavioral analysis and firewalls for network connections. Still, others note flaws in assuming containers are safer.

    Regardless of architecture, In DevSecOps, security for customer data isn’t drafted into the background; rather, it is imbued into the entire tooling process and holds equal footing within each build.

    Instilling a DevSecOps Culture

    Instead of a build-now, secure-later attitude, DevSecOps seeks to elevate security into every decision. With each build, security is melded with greater forethought regarding the repercussions for how data is treated.

    Admin consoles for Kubernetes clusters must be armed and password-protected, and the same goes for private GitHub repositories or Docker registries. Any traversal of data through cloud SaaS services must have authorization in place. A most obvious lesson is to password protect those “hidden” registries with discoverable URLs.

    Bounty programs for white hackers continue to lead to successful bug detection. At least for these institutions, there is less evidence of compromised user data and remediation is quickened.

    Much of this can be distilled by due diligence and through breeding a culture of security. While that’s a little fluffy for some, it apparently still requires repeating for institutions that continually de-privilege these basic safeguards.

    — Bill Doerrfeld

  • Alcide Report Finds 75% Will Increase the Number of Cloud Security Tools They Rely On Over the Next 12 Months

    As Hybrid Cloud and Serverless Continue to Gain Ground, Organizations Rush to Keep Up; Fewer than Half Have Dedicated Cloud Security Teams

    Tel Aviv – November 6, 2018 – Alcide, provider of the most comprehensive full-stack cloud-native security platform, today released the findings of a new industry report: 2018 Report: The State of Securing Cloud Workload based on responses from close to 350 security, DevOps and IT leaders. The report reveals that as more organizations embrace hybrid cloud – with more than 50 percent claiming a hybrid cloud setup – and serverless, now used by close to third of organizations, they lack the tools and specialization to keep up. 75 percent of respondents expect to see an increase in the number of security tools they rely on in the next year, while over half share they still manually configure security policies. The resulting complexity has the potential to slow critical business functions in the absence of an integrated security approach to distributed cloud environments.

    According to a recent report from 451 Research:

    The pace of innovation on cloud-native environments places significant burden on traditional security practices. Not only is there a need to support new technology options – quickly moving from traditional virtual machines to containers, serverless, and newer constructs such as service mesh – but there is also a difference in how security and DevOps teams consider their needs and workflows.

    Alcide’s report, conducted in August 2018 in conjunction with Informa Engage, reinforces the idea that new practices and technologies are disrupting traditional security practices, with findings including:

    Cloud complexity increasing, with hybrid cloud as the new infrastructure normal:

    • While virtual machines (VMs) remain the most common cloud computing environment (83%), containers (37%), serverless (28%), and service mesh (21%) are gaining traction.
    • Hybrid and multi-cloud approaches now make up more than three-quarters of all configurations (77%).

    Serverless running in production; most bullish about its security

    • Despite some security concerns, the majority (57%) of serverless users are currently running it in both production and development.
    • The majority currently using serverless have a high degree of confidence in its security, while one third (32%) express a lack of confidence in the security of their environments.

    As cloud infrastructure complexity grows, security becomes a shared responsibility with DevOps

    • Fewer than half of organizations (45%) now have a dedicated security team responsible for the cloud, with 35% of all organizations now using either a DevOps team or dedicated DevSecOps team for security.

    Hybrid cloud complexity pushes Dev, Sec and Ops teams to look for more tools to secure their distributed environments

    • Over two-thirds (75%) expect to increase the number of tools in use over the next twelve months – with no one expecting to retire any tools in use
    • One-third of organizations reporting using more than five tools for cloud security

    Proliferation of cloud security tools leave the enterprise vulnerable, point to need for intelligent policy automation

    • More than half (60%) of organizations rely on manual configurations of security policies for their apps, while almost all organizations (90%) rely on multiple individuals to configure and set policy rules.

    “Our report validates what we’ve seen with our own customers – modern organizations are striving for a consolidated security approach that will support business velocity and tackle the challenges associated with the overhead of multiple tools in use,” said Karine Regev, VP Marketing of Alcide. “Modern teams can’t assume that emerging technologies like serverless are secure, and need a practical and uniform enforcement and management of security policies to control disparate and cloud-native services, infrastructure and environments.”

    Access the full report here for additional insight.

    About Alcide:

    Alcide’s Cloud Native Security Platform protects any combination of container, serverless, VM and bare metal. Offering real-time, aerial visibility, threat protection and security policies enforcement, Alcide secures the cloud infrastructure, workloads and service mesh against cyber-attacks, including malicious internal activity, lateral movement and data exfiltration. For more information, please visit www.alcide.io

  • Building Great Cloud Security Guardrails

    Building Great Cloud Security Guardrails

    Security guardrails are an incredible way to keep our cloud deployments safer without slowing things down. Taking this structured approach will minimize friction while increasing protection.

    When I first started working hands-on in cloud (AWS) around nine years ago, I quickly realized both the power and risks of just how darn fast and agile cloud could be. Being, on occasion, an optimist, I decided this capability was a significant upgrade to our security capabilities. Sure, I could accidentally spin up internet-exposed servers, but in exchange I gained levels of central control and visibility unheard of in traditional infrastructure.

    One of the most powerful new capabilities is the ability to leverage cloud APIs and automation to build automated security guardrails without having to spend a gazillion dollars for a big box that actually delivers as promised, but also adds tremendous friction and slows things down. Guardrails are automations that constantly watch your deployments, find deviations from desired baselines and can even automatically remediate issues. Yet, even cloud-native guardrails can become problematic if they aren’t designed properly. Having both built a fair few myself and worked with many organizations as they built out their cloud security programs, here are some of the lessons I’ve learned along the way and some code to show you how it works.

    Building Awesome Guardrails

    My first guardrails were a bit of a hodgepodge in terms of structure and capabilities. And practically speaking, there are a lot of ways to attack the problems. Even today I’ll take different approaches depending on the particular challenge in front of me, but most of my guardrails (including operational ones) tend to follow a consistent pattern:

    • Define the problem: I like to start by defining the business outcome we want, and then move onto the technical problem. I used to start with a narrow technical problem to solve but found that didn’t always lead me to the right outcome. For example, is the problem that we want to stop all internet-facing port 22 access, or is the real outcome we don’t want to expose internet-facing admin servers to the open internet and we want to use a guardrail to restrict to our known corporate IPs instead? This helps prevent a guardrail from becoming a blocker.
    • Set the scope: Multiple cloud accounts (or subscriptions/projects for you Azure/GCP people) are now the standard. The first step is to determine how broad a guardrail you want, which will also define some of the technical specifications. For example, if you want it to apply to multiple accounts in Amazon Web Services, that affects where you run it from and how you manage the required IAM privileges.
    • Build or pick the deployment model: There are a lot of technical specifics regarding where and how to run your guardrail. Today’s example will run in AWS within a single account, but if you manage a larger, enterprise-class deployment you will need to look at how and when to balance centralized and localized guardrails. More often than not, I prefer a serverless approach (FaaS with other supporting PaaS), but I’ve also found longer-running guardrails often need containers as well. Thanks to API gateways, it isn’t bad to build deployments that can support both.
    • Define filters: It’s awesome that you can automatically close all internet-facing security groups with 20 to 40 lines of code—right until you break a production application. Filters allow you to tune your guardrail for a particular environment or project’s needs. Basic filters might work on a simple resource tag, while more complex filters might evaluate a combination of include and exclude rules for greater flexibility. This can, for example, treat development and production environments differently from the same guardrail.
    • Determine triggers: We have a rich range of trigger options on the major cloud platforms today. The main categories are time-based assessments and event-based triggers. I tend to use both, with event-based for more deterministic events (an S3 bucket policy was changed) and time-based sweeps to catch conditions I might miss purely on an event trigger.
    • Perform the analysis: This is the meat of our guardrail. Based on the trigger, collect the information we need and, in combination with our scope and filters, make a decision. For example, if we find port 22 open to the internet, if it is a Dev environment we might decide to update the security group to restrict to known corporate IP addresses. If it is in Prod we might delete the rule completely unless it was implemented through a CloudFormation template that went through an approval process.
    • Send notifications: Even when you have a completely automated guardrail, you likely want a parallel notification. These can go straight to email/text/Slack or drive into a ticketing system. For security guardrails, I also recommend sending them to your SIEM or other security alert/management system. If you’re fancy, you can turn these into the first step of a chatOps process.
    • Take actions: Actions are what separates guardrails from all the annoying alerts of the past. Based on the analysis and filters, actions can be fully automated remediations or request human intervention. Actions also can follow different paths based on the conditions to provide the best options for that situation. The key is that even if a human is called to make a decision, the decision should be a simple click to run the action, saving the person from having to fix things manually. Unfortunately, we still sometimes need human beings to make a decision. Then again, the alternative is bowing down to our robotic overlords. It’s a trade-off, I suppose.
    • Validate and log: Don’t assume the action actually did anything. Rechecking is vital, as is logging and sending the results as a second notification to the ticketing system/SIEM/etc. I fully recommend sending both incident open and close notifications to the destination system, even if the guardrail fixed everything within seconds. This keeps a consistent record and also allows you to do nifty things such as measure your mean resolution time and compare automated versus manual.

    Running a Demonstration Guardrail

    One of my favorite guardrails to demonstrate is automatically reversing security group changes in AWS. Here’s how to set it up for yourself and run my demonstration code to see what it looks like:

    • The first step is to make sure you don’t start running this in production or anyplace else where you might break things before you actually tune the filters. If you do, it isn’t my fault. The desired outcome in this case is ensuring we don’t have network exposures due to unapproved security group changes on designated resources.
    • The scope of this guardrail is a single local account, with a corresponding deployment model. We will use CloudTrail, CloudWatch Rules, Lambda and SNS.
    • There are three prep steps to configure your account before building the guardrail:
      • Log into the AWS console and set up a destination for notifications. If you haven’t done this before, you want to use SNS (Simple Notification Service). Create a topic for security alerts and a subscription to wherever you want to send the alerts. I recommend starting with a simple email subscription.
      • Make sure you have CloudTrail turned on and streaming to CloudWatch. For you newbies, CloudTrail records (almost) all the API calls on your account and we need this for our trigger. Sending the logs to CloudWatch allows us to build near real-time triggers in CloudWatch based on events such as the API call we will look for.
      • Create an IAM Role for Lambda to use. It will need the rights to AuthorizeSecurityGroupIngress, DescribeSecurityGroups and RevokeSecurityGroupIngress. To save logs, it also needs PutLogEvents, CreateLogStream and CreateLogGroup. These are also in a JSON template in the project repository for cut and paste.
    • With that in place, create a new Lambda function (Python 2.7) and load in our code located at https://github.com/disruptops/RevertSecurityGroups.
    • Now go to CloudWatch Rules and create a new rule. For the trigger, use the following:
      • Service Name: CloudTrail
      • Event Type: AWS API Call via CloudTrail
      • Specific Operations: AuthorizeSecurityGroupIngress
    • Then set two targets: your Lambda Function and your SNS topic for security alerts. This will revet the changes and simultaneously send you a notification.
    Screenshot of configuring the trigger in CloudWatch

    This should now revert any new ingress rules added to a security group. If you play with the code you can also use this for egress rules. This is just demo code and there are edge cases it will miss.

    The code also includes a number of filter options, including:

    • Restricting to a region or VPC.
    • Restricting based on a tag or a specific security group ID.
    • Allowing the change if it comes from a designated IAM user, and reversing if it was originated by anyone else.

    It takes the action automatically; if you want to manually review first you would modify the code to send a notification instead. We have some alternative examples posted at https://github.com/disruptops/demos-tools. These includes some samples that protect S3 and also show how to embed notifications in the Lambda itself for more-flexibility.

    Hopefully this gives you some ideas to refine your own guardrails to dramatically improve security while still moving blazingly fast.

    — Rich Mogull

  • DevOps Chat: disrupt:Ops Brings Security Closer to DevOps

    DevOps Chat: disrupt:Ops Brings Security Closer to DevOps

    Shifting security left during the software development process can be tough for companies because of the sheer number of operational things that go along with implementing security that must occur somehow in the realm of DevOps. It can be easy to lose control over their security processes without some sort of guardrails in place to help.

    A brand new company is helping do just that. I’m excited to introduce disrupt:Ops, which bills itself as a guardrails platform to help companies include and enforce best practices across security and operations, bringing security into the DevOps process at the beginning. My friend Mike Rothman, disrupt:Ops co-founder and president, joins me in this DevOps Chat to discuss the vision of his company and how it hopes to help make security truly a part of DevOps.

    You can read more about disrupt:Ops and their guardrail approach to cloud security and devsecops from another co-founder of the company, my friend Rich Mogull at https://devopsy.kinsta.cloud/building-great-cloud-security-guardrails

    As usual, the streaming audio is immediately below, followed by the transcript of our conversation.

    Audio

    Transcript

    Alan Shimel: Hey everyone, it’s Alan Shimel, devopsy.kinsta.cloud, and you’re listening to another DevOps Chat. Breaking some big news today on DevOps Chat, the launch of a labor of love of some friends of mine. I’m happy to be joined by Mike Rothman, cofounder and president of disrupt:Ops. Mike, welcome.

    Mike Rothman: Alan, it’s great to be here, thanks. It’s always fun to catch up with old friends.

    Shimel: Yep, and old friends it is, Mike. We should let our audience know – maybe we shouldn’t let them know. But we are old friends. We go back a long time now, back to the beginning of blogging and security –

    Rothman: That’s right.

    Shimel: It’s got to be 2004, 2003 or something like that.

    Rothman: Yeah, that’s right, that’s right. When I had dark hair. Actually I didn’t have dark hair back then, but you know, it’s –

    Shimel: I had hair.

    Rothman: You had hair. That’s right.

    Shimel: I had hair. But you know what, Mike? I said it was a labor of love and everything else. Just in the way of background, why don’t you share with our audience your personal sort of journey in tech and, you know, work history.

    Rothman: Well sure. I started out, God, in what feels like 100 years ago, as a mainframe programmer. Ended up doing some local area networking stuff. Kind of found my way to network security. Went into research for quite a while. Did a couple of companies and then went back to research and for the last 10 or 11 years at this point I’ve been partnered up with Rich Mogull and Adrian Lane at Securosis, doing a bunch of kind of information, security-centric research. And actually about a year and a half ago we spun out some technology that we had prototyped within Securosis in cloud management and cloud automation into our new company disrupt:Ops, and have been just making a lot of progress over the last year with that. And that’s what we’re announcing this week.

    Shimel: Yep. So Mike, you’re being humble. When you say you did research, you were an analyst at Giga, were you not?

    Rothman: META Group, yes. META Group, exactly.

    Shimel: META Group. And then you were also – you had executive positions in several cyber – we didn’t call it cyber – infosec companies back then. 

    Rothman: It was. Yeah, you bet. So companies like TrueSecure and CypherTrust, you know, back early in the e-mail security days. I did a network monitoring company called EIQ. So yeah, I’ve been there, done that. Have the road rash and kind of the screw-ups under my belt to prove it. But you know, it’s interesting in terms of just how long and how small an industry security is for being actually a really big thing nowadays. 

    Shimel: Being so big, yeah. It really is. And Mike, again, for many people in our audience who come from DevOps or even from security – but they’re worldwide and they not be familiar with Securosis. You know, Rich Mogull comes over from Gartner. Adrian’s been CTO at major companies. You know, you guys are probably the leading, let’s call it independent security analyst research firm – you said 10 years-plus. Certainly in my time you guys laid the fundamental kind of – a lot of the fundamental backbone of what Cloud Security Alliance teaches and so forth. 

    Rothman: Yeah, that’s exactly right. So it was interesting. So I guess it was probably eight and a half years ago we partnered up with the Cloud Security Alliance and helped them build their curriculum for their CCSK certification. And that got us to be much deeper than your typical analyst in terms of having to play around with cloud, having to understand automation, having to build a number of the kind of scripts and – I’ll call it the inherent messiness of building out a stack in the cloud and really making it operational, because we were eating our own dog food. Our website, a lot of the stuff that we had prototyped was really demonstrative of the challenges that organizations face as they move a bunch of their stuff into the cloud, and really as they embrace a DevOps mindset of trying to be agile, trying to be innovative, trying to move towards more of a continuous type of deployment model. We really came across a number of the challenges these organizations have in terms of just really maintaining control, right? Once you have multiple DevOps teams doing things in multiple kind of accounts, you start to run into challenges relative to how you enforce best practices.

    And that’s really one of the challenges that security people have with this whole DevOps revolution, which is, “Hey, this sounds great, but we’ve got a playbook, a set of practices and policies that we really require all of our environments to adhere to in order to protect that data.” And obviously the faster you move, the more agile and continuous you try to operate, the harder it is to enforce those best practices.

    Shimel: More about that in a second. You touched on two things there that we’re going to dig into. Let me just finish laying my groundwork. Mike, besides you, Rich and Adrian, the Securosis gang, there are at least two other key people on the founding team of disrupt:Ops who also happen to be friends of ours for years –

    Rothman: Yeah, that’s right.

    Shimel: Give them their due. Why don’t you give them a shout out?

    Rothman: You bet. So back when we spun the technology out of Securosis, we brought on two guys, very experienced guys in the security space. Our CEO is Jody Brazil. So Jody was a cofounder and long-time CEO of a company called FireMon, which I know you’ve done work with for a long time –

    Shimel: Sure.

    Rothman: So Jody kind of is really the driving force behind a lot of what we’re doing at disrupt:Ops. And our CTO is a guy named Brandy Peterson, another longtime security professional. He was actually the CTO of FishNet Security for 15 or 16 years.

    Shimel: As was Jody before Brandy, right?

    Rothman: Yeah. I met both of them around the same time.

    Shimel: Yes, when I first met Jody, he was CTO and FishNet, and he said, “Who is this Jewish guy with the New York accent?” I went out to visit him in Kansas City to tell him why you shouldn’t use Qualys, and he should use StillSecure, and he made fun of my accent. [Laughs]. Good times. Anyway. But Mike, let’s turn back to a couple of things you were saying about kind of the genesis driving disrupt:Ops. You touched on one thing; you said, “multiple DevOps teams.” So this is something we see, and I call it almost second-generation DevOps. You know, when a company or an organization is first embarking on their DevOps journey and they do sort of a trail balloon, and they pick a project and they have a DevOps team – you know, and they may not call it DevOps. They  have a team that’s practicing DevOps sort of principles on this one particular project. And oftentimes, wow, great success, because you are – you know, it’s an isolated environment, right? In some ways you’re not in the quote/unquote real world.

    And then you say, “This is great. Let’s take it out. Let’s expand that beachhead. Let’s expand the bubble.” And all of a sudden – you know, larger organizations; small teams or smaller organizations not so much, but larger organizations – now you start having two, three, four, six different projects that are being run with a DevOps mindset and you have multiple instances of Jenkins and you have three different – this team’s using Puppet; that one’s using Chef. And serverless. And all of the complexities that we see in today’s modern software factory. And it’s chaos, right? And then at some point the CIO or VP or director of IT says, “Oh my God, this DevOps thing isn’t working so good. It’s all over the place.” Let alone the security guy’s screaming, you know, right out of the Phoenix Project, “No, no, no!”

    Rothman: That’s right.

    Shimel: And that’s a problem that we see with a lot of second-gen, if you will, DevOps installs, where it goes beyond the initial team to several teams.

    Rothman: That’s right.

    Shimel: That’s what you guys see.

    Rothman: We do. And it’s interesting, because what you have are really kind of two paths at that point, in terms of how these teams start to behave when starting to be put under scrutiny in terms of, kind of again, their ability to enforce operational and security best practices. You know, one group kind of buries their head in the sand and continues to move forward and really don’t do much, right? They’re like, “Oh, it’s okay,” and you know, they’ll maybe run a vulnerability scan to kind of prove that they’re sort of within policy, but they really don’t have an operational environment that is built to work in concert with the rest of their factory. I love that term, right? That really does encompass a lot of how software is being built today. And then the other part ends up being folks starting to build their own scripts, right? They take maybe an open source-looking thing, they start to build a bunch of their own scripts and code around it, and then what they find is they’ve got a suitcase full of these scripts that they end up having to maintain, upgrade. They don’t have any means of reporting or any scheduling for how they enforce and run a lot of these scripts.

    It’s really – you know, we call it automation, but it’s manual automation, which I get is a total oxymoron. But that’s really how it is. You know, you have a bunch of folks, they’re building these scripts out, they’re executing them manually or through very simple triggers, without any means of maintaining, upgrading or scheduling or reporting on what these really key aspects of their operational environment are doing. And it becomes, again, a big problem, where you have – it’s unwieldy because of just the sheer number of things that are happening in a modern DevOps environment with multiple teams. Then you compound it with a number of very tactical scripts that are built to surround the environment, if you’re doing anything. And then at some point somebody says, “Hold on a sec, folks. This is just not where we want to be. We really need to think about it more from an operational excellence perspective and make sure we’ve got an environment that we can enforce our best practices for security and operations.”

    And that’s kind of when they get the sense that, “Well, I’m either going to have to make a significant investment in this and become like” – Rich calls them the unicorns of cloud land, right? You know, the Netflix and the Capital One and, you know, the folks who have whole teams of environments that are building tools to do this. Or they have to start looking for some kind of commercial option, because there really is no option, but you’ve got to do something. You can build it yourself or you can look to buy it. And candidly, until the last handful of months, there really wasn’t a realistic commercial offering to start implementing some of these capabilities.

    Shimel: No, no. I think the bigger – you know, a lot of what you’re saying certainly obviously rings true. The other fundamental piece of this is, even if you are using one of these homegrown, cockamamie, you know Rube Goldberg kind of things –

    Rothman: Yeah.

    Shimel: – is it the security guys who are? You know what? Shame on me. It’s not the guys. Is it the security team who’s doing this, people? Is it the DevOps cross-functional team? Is it a little bit of both?

    Rothman: Yeah, yeah.

    Shimel: You know, how many of – look, here’s my basic, fundamental belief. You are not going to find a developer who raises his hand who says, “I want to write shitty code. I can’t wait to put something insecure out there.” No one says that. No one says that, right? They’ll tell you they’ve got time pressure, there’s pressure to release, pressure to release, they wish they could do more on security. And some of them, the enlightened ones, as you said, they’ll even try. They’ll run a vulnerability scan, because there are certainly open source kind of tools out there for them to mess with.

    The problem is, they go to a lot of the security guys, and as you alluded to before, security guys say, “Well we have our rules and procedures here. This is a no.” Right? And they don’t want to hear no. They’ve got to go.

    Rothman: You know, what’s interesting, Alan – I want to hit on a couple things that you alluded to there, because they’re important, right? The first is kind of where you start to see the agitation for better operational and security practices. And it’s not that it’s not the security folks. Obviously they’re always going to push for that. But it really is – you mentioned it, right? The DevOps teams that we’ve worked with, they’re very cognizant, they’re very serious stewards of kind of the corporate data, and they want to do the right thing. But in a lot of cases they don’t know what to do, right? So you have a whole bunch of folks who don’t know what they don’t know and they don’t want to go to the internal security team because of a lot of those things you were just alluding to. They’d say, “No, we can’t do that. We have all of these rules.” And in a lot of cases the security team has not updated their set of conditions, their set of policies – 

    Shimel: Exactly.

    Rothman: – to work in a DevOps type of environment, so these folks really struggle. They talk to – again, on the consulting side of our house at disrupt:Ops, we do a lot of work with those teams in terms of helping them understand what cloud native architecture looks like and how to integrate cloud security into their environment, and really just to help them build a program in order to do that. So then you do that with one DevOps team, then you end up talking to another DevOps team and maybe the third DevOps team, and finally IT, at some point, they’re like, “Um, what are you telling our folks? They seem to like what you’re doing and they seem to be doing things in a more secure way. So can you help us?” And then IT starts to get religion. The security team starts to get a little bit of religion about what they have to evolve to. And it really is kind of that interesting transition where it has started kind of out in the DevOps community with, again, those enlightened ones going, “I don’t know what I don’t know. Let me get some help,” and then it kind of back-ending into security. That’s not always the case, but probably three quarters of the time, that tends to be the transition that we see.

    And the other thing I want to hit is just about velocity, right? JA very forward-thinking DevOps leader that we’re working with, he said it the best. And he’s just like, “I’ve got 20 DevOps teams. I cannot slow these people down. They are doing stuff; they are making progress. The last thing I can do is put a bunch of onerous security requirements on what it is that they’re doing. They’ll ignore me, they’ll go around me and that’s counterproductive. I can’t do that. What I really need is to be able to build and enforce a set of guardrails around their environment.” Right? That term, “guardrails?” It just really kind of opened up and was a light bulb in our head when we were having this conversation. It’s not about stopping them from doing things. If anything, it’s about allowing them to go faster, yet making sure they don’t drive the car off the road, right?

    And that’s really the metaphor that resonates relative to what we’re doing at D:Ops, and really just kind of where the environment is going, in that we have to be able to move faster. Slowing things down is not an option, yet you want to make sure that you are not putting corporate data at risk. You are not opening up significant new attack services just – because people are moving so quickly. Sometimes they make mistakes. Sometimes automation isn’t done in the perfect way. Sometimes humans get involved and certainly are fallible from that standpoint. But with a lot of the inherent, underlying automation orchestration that’s possible within the cloud and DevOps and continuous, you have options to enforce these best practices in a way that we couldn’t do in our traditional data center with our traditional waterfall types of development and operational motions.

    Shimel: Absolutely. And you know, Mike – I mean, I’ve spoken about this a lot at various conferences and stuff. A lot of that has to do – you know, we use this term “shift left” in security and all that. A lot of it does have to do with getting to security earlier, faster. Yeah, we’re going to have to automate it. Yes, we can’t be the roadblock. But we can be the appendix after – when I say, “we,” I mean security. We can be the appendix after the delivery or after the deployment.

    Rothman: I’ll raise you. I see your point and I’ll raise you one, right? I’m of the opinion that security isn’t a thing. Right? Security should be within everything.

    Shimel: Yeah.

    Rothman: And that’s really the mentality that we’ve been trying to push on the industry for a long time.

    Shimel: Amen.

    Rothman: And it’s one of these things where we really can’t afford to wait and be in a position where we’re trying to retrofit poorly architected systems that are moving faster than we’ve ever seen before and then say, “Oh hey, we’ve got to change it because of security,” or because of any other operational gap that we see there. Right? What we have to do is be building in a way that allows us to use architecture as security control, right? Isolation, segregation, multi-factor authentical, identity management – all of these things that are fundamental building-blocks of what we do in the cloud and DevOps can be utilized to build in a much more secure fashion. And it’s really about those kinds of practices that are going to make the biggest difference relative to what it is that we see and what it is that we deploy over the next couple of years.

    Again, like I said, I don’t think security is a thing five to seven years from now. Because if it’s not embedded within everything that we deploy, we screwed up.

    Shimel: Yep. You know, I heard – because I never come up with original ideas. I just listen. But I heard something awhile back – “Security needs to become synonymous with quality.” And we’ve had QA as a concept in software technology forever or for a long time. Security needs to be just built in, like as part of the quality control. Right? The same way shit or stuff gets tested, whether it be hardware or software or whatever. Security needs to be part of that quality. 

    Rothman: You bet. To use a software term? Right? Why is a functionality defect different than a security defect?

    Shimel: Exactly.

    Rothman: Right? And they should all be within the same thing. And again, that’s a lot of when you start talking about immutable, when you start talking about kind of building security testing into your pipeline, which again, is stuff I know that you guys at devopsy.kinsta.cloud write about quite a bit. Again, it’s really not any different than you managing and making sure that you hit your functionality kind of specs from the standpoint of just building code, right? Part of that factory. So yeah, the code has to work, but it also can and should be secure, and there really aren’t different operational motions to make that happen. And that’s what’s so exciting. For a guy who spent 25 years trying to retrofit and get people to think about security as part of their core structure and to treat it as really a business function, it’s really enlightening to be in a situation where you actually can implement a lot of those functions within the core processes that you use to develop the technology.

    And again, are we there yet? Of course not. Is there a lot of education to be done? Without a doubt. But we at least have the option now, right? That’s the aspirational goal to what it is that we all do every day, which is to make sure that we’re pushing for the right types of decisions to be made as early in the process as we can, because we all know how much it costs to fix it later.

    Shimel: Absolutely. Mike, I’ve got to tell you, listening to this conversation, I’m thrown back to, “NAC: is it a feature or stand-alone?”

    Rothman: You’re dating both of us, man. Stop that out. Cut that out.

    Shimel: It’s such a pleasure to talk a little theory here with you. But let’s turn for a second to real stuff. Not that what we’re talking about isn’t real. But I wanted to give our audience a little bit of a taste – so disrupt:Ops – great people, great big problem to tackle out there. Give us some specifics. What are you guys doing?

    Rothman: Yeah, so what we’re doing is we’re basically building a cloud management platform to implement a lot of these ideas that we’ve been talking about for the last couple of minutes, Alan. Initially it’s a guardrails platform. So what we have is the ability to, in an AWS environment, enforce a set of best practices across security, operational and also cost management. So one of those things we don’t talk about too much is that developers don’t really like to shut their stuff down because, “No, it’s going to mess with something. I don’t have to. The CFO bitches but we don’t really care.” What we can do is also implement best practices in order for folks to clean up their room, right? We try to do that with our kids all of the time, too. You know, so we try to do that with our developers as well.

    So really implementing a platform for security, operational and cost management guardrails, to again, immediately not just find the issues – there are a lot of tools, as you said. A lot of vulnerability scanners can kind of look at your cloud environment and tell you you have problems. The issue with that is that most operations people are overwhelmed with the number of other things they have to fix every day. Adding more stuff to their list doesn’t really help them. So disrupt:Ops is really focused not just on finding the issues, but also fixing them and enforcing those best practices. Let me give you an example of that. So let’s just say some person decides they want to open up a server to the internet because it’s just easier for them to do that. Well obviously that would be a pretty significant security problem. So as opposed to just taking that server offline, what you can do is you can basically change the security group to make sure that it’s only accessible via a known, good IP address range within your corporation. That’s a good example of a guardrail. Or making sure that you’ve got MFA turned on for every account that gets spun up by your magical Terraform environment that may not build that out as a core security requirement.

    So again, there are 50 to 60 of these guardrails, in effect, that you can implement in your environment, to again, make sure that you are not just alerting when you get out of policy, but actually fixing the issues, in a lot of cases before you even know they’re issues, so that you’re not sitting there trying to pick up the pieces after half of your data is in Chechnya.

    Shimel: Exactly. Or Romania.

    Rothman: Or Romania. It’s somewhere.

    Shimel: Mike, how is the offering packaged? Is it a SaaS kind of offering? 

    Rothman: Yeah, it is. What we found is since – you know, remember the days where people were like, “Oh, I don’t know about this cloud thing or SaaS. I’m not sure I’m comfortable with that”? Now it’s like, “Wait, you want me to install software in my environment? What? What’s wrong with you?”

    Shimel: That would be kind of oxymoronic for a DevOps tool, but –

    Rothman: That’s right. That’s right. So we deliver as a SaaS service. It’s actually a very cool kind of one-click provisioning process where, when you’re logged into your AWS account, you run basically a cloud formation script that really kind of gives us cross-account privileges to your environment. And again, we’re security guys, right? So at the end of the day, we are basically not even just assuming but enforcing least privilege. So we only have read-only access. When we need to make changes, we grant the privilege as we need it, then we revoke it. Because again, what we’re trying to do is make sure we enforce operational best practices; not add more attack service. So again, we’ve built the environment to be secure by design. We use all of our own dog food, to make sure that we are adhering to kind of common best practices. And again, we’re all 25-plus years security folks, so we do take that pretty seriously.

    Shimel: Excellent. Mike, for people who maybe want to download – not download, excuse me – sign up for it or check it out more, where can they get more information?

    Rothman: Yeah, disruptops.com. So by the time you hear this little interview, the site will be live. There’s a place you can sign up. You know, first we start with a demo and show you what it’s about and then you can sign up for early access. And again, we’re kind of expanding towards the end of this month, in October. We’re going to add a bunch more folks to the system with the goal of kind of being ready to actually sell the product by the end of the year.

    Shimel: Fantastic, man. Well, I don’t have to tell you, Mike. I wish you, Rich, Adrian, Jody, Brandy and the rest of the team nothing but success. We’ll be checking in, I have a feeling, pretty often here, whether it be through Security Boulevard, devopsy.kinsta.cloud, Container Journal or what have you. And you know, fantastic. It’s good to have you back in the game.

    Rothman: Yeah, no, I’m excited. Again, really it’s not just a big promise and not just a huge opportunity. You know, and what Rich, Adrian and I, and now Jody and Brandy have always done is – you know, we’re trying to do the right thing to evolve the practice. Right? And that’s what it’s about. It’s a big world and there’s a lot of opportunity. There’ll be a lot of folks talking about guardrails over the next year. And that’s great, right? Because what we want to do is get to a position where we can move faster but move more securely, and I a lot of cases, in the world that we grew up in, those were counter indicators. Right? You couldn’t move fast and be secure. You couldn’t do operational excellence and make sure that you’ve got a lot of these things enforced. And now you can, and that’s what’s really exciting to us. Again, we’re just excited to partner with you, as always, and again, just go out and solve some bring problems for a lot of organizations.

    Shimel: Fantastic. All right. Mike Rothman, president and co-founder of disrupt:Ops, a hot new entrant in the DevSecOps space, with a great pedigree and a real reason for being our guest today on DevOps Chat. I hope you’ve enjoyed this. This is Alan Shimel for devopsy.kinsta.cloud. Until next time, everyone, have a great day. Bye-bye.

    — Alan Shimel
  • DevSecOps and Development: Making the World Safer One Application at a Time

    DevSecOps and Development: Making the World Safer One Application at a Time

    If you have been around software development much at all in the past five or 10 years, then you’ve certainly heard of DevOps and know it’s here to stay. And it is very likely that you have also heard the term “DevSecOps” even more recently. With today’s extensive proliferation of application capabilities being delivered through services—and all the inherent complexity that comes with the delivery systems for them—it’s no wonder that cybersecurity has moved to the forefront for many companies. In fact, according to research from Stratistics MRC, the current global application security market is growing at a CAGR of 23.4 percent and is expected to reach more than $10 billon by 2023.

    But it is one thing for there to be an interest in cybersecurity; it’s another thing entirely to implement it well—and that is where the conversation gets more interesting. Today, the name of the game in application security is all about bringing the role of the developer into the fold and equipping developers to code, fix and maintain security as part of the software development process. In an article on DevSecOpsDays.com, DevOps thought leader and author Jon Willis offers the following comments:

    Fast forward to February 2017. I was speaking at the RSA Conference in San Francisco and I started seeing for the first time people talk about security as an interesting new way of integrating it into DevOps. They were unapologetically calling it DevSecOps. They were talking about this in a way that included security as a systems (end to end) approach to the traditional DevOps pipeline.

    This was not the first time I had heard people talk about security and DevOps.

    The thing that most caught my eye was that this approach was clearly putting the ownership of security on the developer. I immediately thought back to Werner Vogels’, the CTO of Amazon, statement of “You Build It, You Run It”, back in 2006. However, what I was hearing this time was “You Build It, You Secure It”. This thing they were calling DevSecOps was describing a holistic and systems approach to security as part of the software delivery pipeline.

    This notion of developer empowerment being a critical aspect to success was something I heard again and again at the recent 2018 Black Hat USA Conference. You can read more about my experience at Black Hat in this DZone article. But how do you effectively bring developers into the security fold? That is what we will explore in this multi-part series.

    In this first article, we will focus on what I (and many others) believe is the single most important factor for long-term success: the organizational culture. And by culture I am talking about the day-to-day environment of the organization the developer is a part of, and how they are (or are not) allowed to do their work. A successful DevOps culture is one that promotes collaboration to foster innovation and speed delivery, and the following two sections of this article depict perhaps the two most critical components for a strong DevOps culture: leadership and trust.

    It All Rises and Falls with Leadership

    Many would easily agree with the notion that long-term success for DevSecOps in an organization needs executive support and buy-in—and they would be correct—but real success needs much more than just budget approval and a shifting of resources. It needs ownership. It needs visibility. It needs truth-telling and that is where leadership comes in. According to the PuppetLabs “2018 State of DevOps Report,” 64 percent of C-Suite respondents firmly believed that security teams are involved in technology design and deployment, but only 39 percent of actual team members agreed. Bridging that kind of a gap requires breaking down traditional silos and evolving for better communication and transparency. The same survey also found that high-performing organizations were 24 percent more likely to use automated security policy configurations—a clear indication of tighter cooperation between security teams and the operations teams maintaining production environments.

    So, what are some of the key ingredients of successful leadership in this space? Glad you asked. Here are some things to look for:

    • Balance: Is the organization able to balance lowering technical debt with new work?
    • Shared ownership: Does everyone see how they contribute to business success and how their role impacts it? Is security included in that?
    • Shared learning: As projects progress and complete, is information moving across teams and projects? Are there best practices, lessons learned, etc., that are communicated both internally and externally?
      • Another way to think of this one: Is the level of “tribal knowledge” in your organization getting reduced?
    • Shared Vision Goals: Does everyone see and understand what matters most? Do they know the core metrics and KPIs, and how what they do impact them? Can they see their own success and bottlenecks?

    To have great success, you need leadership that defines the key standards, actively facilitates learning and collaboration and then provides the freedom necessary for innovation to occur. And there is another reason why you need it: Great leadership builds trust. Let’s explore that next.

    Your Speed of Delivery is Directly Proportional to Your Level of Trust

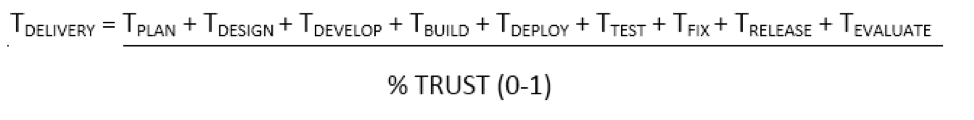
    The best depiction I have seen that correlates the speed of delivery with trust is this simple equation shared with me by DevOps Technical Evangelist Al Wagner from our mutual friend and Senior IT Specialist Lee Reid. It can also be found here. It simply states:

    Where “T” simply stands for time. In this simple equation, you can see that the HIGHER the percentage of trust is in the organization, the LOWER the overall value of the Time to Delivery will be, which is what we are all after. What that tells us is that today, businesses cannot tolerate a trade-off between speed and quality—you need both simultaneously.

    But how to you calculate trust?  In this model we are not talking so much about the work habits of the individuals as much as we are considering the outcome of each part of the process.  We  have to consider how often each of these areas “gets it right” versus how much we have to go back and rework.  Lee provides this example based on a client scenario:

    On a given project team the plan has about a 50/50 chance of being right, and the design is about 85 percent right, and the developers will get about 90 percent of the implementation right, and the testers have about 90 percent of the test cases right, and the release team has about 95 percent reliability of having the right stuff together to release, then your trust factor is something like

    .5 x .85 x .9 x .9 x .95 = 32 percent Trust

    Putting that back into the simple equation above, this level of trust means that your delivery time is three times longer than it could be.

    When my children were in elementary school and doing homework, I used to tell them that sometimes the best way to go fast is to go slow. The point was that if you wanted to solve problems you first had to understand them. Rushing to a formula or just trying combinations of numbers doesn’t work well and it ends up taking you twice as long to get done. This notion of trust and DevSecOps is similar and when you make the initial investment to build trust it can make a real impact.

    While it is true that adding application security to the Tplan and Tdeisgn parts of the process will initially increase those values, having application security as part of the software delivery process from the start—instead of at the end of a release cycle—will naturally cause the values for TDevelop, Tfix, and TEvaluate to shrink. This is largely because you are NOT having to go back to rework security into those areas midstream. It could also actually shrink Tplan and Tdesign over the life of the project for the same reason. In addition, the overall level of trust goes up because the risk that is associated with the delivered items decreases. We are more confident that artifacts are secure if vulnerabilities were identified early and fixed then.

    If you would like to learn more about how you can build trust, lower risk and make real business impact with application security, or to learn more about the potential impact of cognitive capabilities and artificial intelligence on your development efforts, download this complimentary Ponemon Institute study.

    — Rob Cuddy

  • DevOps Chat: The New Security Breed with Veracode’s Mark Curphey

    DevOps Chat: The New Security Breed with Veracode’s Mark Curphey

    DevSecOps has changed the way developers approach security in their application development cycle. But it’s also been the source of confusion, as some developers grapple with understanding how DevSecOps is different from application security. Mark Curphey, VP of strategy at CA Veracode, is clued in to the differences, which he discusses in this DevOps Chat.

    As usual, the streaming audio is immediately below, followed by the transcript of our conversation.

    Alan Shimel: Hey, everyone. It’s Alan Shimel, devopsy.kinsta.cloud, Security Boulevard, and you’re here for another DevOps Chat. Today’s DevOps Chat is all about DevSecOps, AppSec, what’s happening on the front lines. I’m joined by an old friend of mine, Mark Curphey. Mark is currently VP of strategy at CA Veracode. Hey, Mark, welcome to DevOps Chat.

    Mark Curphey: Thanks, Alan. Great to talk to you again.

    Shimel: All right. So Mark, let’s start off with this. I know you’ve fairly recently joined Veracode. Give our audience a little bit of your background and how you came to be where you are.

    Curphey: Yeah, sure. So misspent youth, went back to university late, did a master’s degree in information security, and wound up working for a bunch of banks in the city of London. Moved here to the states in 2000, then ran software security for Charles Schwab. So Microsoft were creating the SDLs. You know, sort of Gates had sent out the famous memo and I was doing the same for an online service basically at Charles Schwab. So that’s where I started. Then at OWASP, which some people sort of associate my name with, which is the Open Web Application Security Project.

    And since then I’ve worked at Microsoft around the security tools team and then I think with MSDN, the Microsoft Developer Network. I more recently created a startup called SourceClear which was focused on helping developers use open source code safely in the modern DevOps world. We were acquired by Veracode about five months ago. So I’m now the VP of strategy at Veracode helping the Veracode platform and how we really sort of work with DevOps and the new way of doing things.

    Shimel: Fair. Okay, so Mark, let’s start off with this though, and I think there’s some confusion out there with both security people as well as non-security people in terms of what’s the difference between AppSec and DevSecOps? Is one really just synonymous with the other? Is DevSecOps another name for AppSec? I don’t think it is. What do you think and how do you define the differences between them?

    Curphey: Well, certainly every vendor’s got a DevSecOps product these days, right? So it’s easy why people are getting confused. I mean I think the reality is the way you have to do AppSec in a DevOps world is fundamentally different to the way we’ve done it before. It used to be about educating developers, writing policies that people had to read, human processes to do final check off, things like threat modeling, you know, all of these sort of things. They kind of worked okay in a waterfall world were kind of modified a bit to work in an agile world. But, you know, DevOps is changing the game completely. So we’re in a world of automation, and, you know, the modern ways that we have to secure it are fundamentally different. So for me DevSecOps is about how do you apply security in this modern, you know, DevOps world and that’s predominantly focused around, you know, automation. What can you automate and, you know, how can we put automation in those pipelines that are happening so that security happens inline as code is created and it’s moved through the pipelines?

    Shimel: Fair enough. We talked pipelines. We talk left to right, Mark. You know, and Veracode is probably one of the leaders in this space when we talk about DevSecOps and shifting left and working. But I think what people want to know is really how does the security person or the security team work with the development team? It’s easy to say, but what does it really –

    Curphey: Sure.

    Shimel: What does it really mean?

    Curphey: Yeah. I mean, look, I think there’s a new breed of security people which is exciting to see. Like the old world that used to be the development team and then there were the security team. There were kind of the two separate teams. The security team needed to sort of bless things before they went into production, but we get appointed a data center and whatever. These days what you see is it’s all about velocity.

    So, you know, there are security people that are embedded into the security teams and they’re kind of acting like consultants and helping the dev team do security as and when it’s needed and make the right decisions without slowing things down. So instead of it sort of being this procedural thing where they were required to go through whatever a control grate, they’re just tired of the flow. That’s exciting to see because I think we’re seeing a paradigm shift of how that happens.

    Shimel: Yep, I think we are seeing a paradigm shift in this. So here’s going to be a question you’re going to say, “Alan, you’re crazy,” but Mark, does it make a difference? Is it definitively improving our security here?

    Curphey: Yeah. First, Alan, I’m never gonna call you crazy, but that’s good to know, I think.

    Shimel: I figured you would.

    Curphey: No, but look, I mean like, for sure, like think about like we all know what happened with Equifax, right? Like biggest data breach in history, result of open source that was insecure and hadn’t been updated. That problem is solvable and it’s solvable at scale in a pipeline. So what we were doing at SourceClear – I don’t want to turn into a product pitch in any sense, but we were basically trying to close the loop of this library is out of date, issue the pull request, figure out if it’s going to break things, and if so, update it. And the developers loved that, not because they’re fixing security but they’re fixing the dependency hell problem.

    So we’ve not been able to do that before because, you know, we hadn’t been injected directly in the pipelines. So these are opportunities that really make a difference and companies that implement these tools like us and there are others around, totally can avoid the whole Equifax thing. It’s not a case of like no one got notified or no one knew. Like it happens automatically in the pipeline. So there are great opportunities to do things like that.

    And I think moving forward we can also look at things like are people using dangerous APIs? Are they calling, you know, external services that we don’t want them to call? Like to a large extent the pipeline has become the new firewall and it’s a place where we can put controls, inspect the traffic, and decide what we want to allow and what we don’t want to allow which is a great place to be.

    Shimel: I agree. I agree there. So Mark, I guess where I wanted to go next with this is a lot – again, I’m a man who lives with a foot in each world, right? I spend a lot of time with my security friends and colleagues that I’ve known for years and years and years, but as part of devopsy.kinsta.cloud I’m out speaking to developers an awful lot, right?

    Curphey: Mm-hmm.

    Shimel: And some of the questions that I hear from both sides is, okay, you can’t serve two masters, there can’t be two people in charge. How does the day-to-day of this flow? You know what I’m saying?

    Curphey: Yeah, no, for sure. I mean look, the reality is in all organizations the digital transformation and everything else happens that it’s all about value creation and the value is created by developers. So they’ve been empowered to choose their tools. They’ve been empowered to figure out which process allows them to innovate faster and all those things. With that we’ve seen the rise of the cloud and everything else. So it can’t be an us or them scenario. It’s how do you support those developers on their mission to change things and create this digital transformation? So the old ways, you still see it but you still see the old school of security people saying no and stopping people; but those battles are not going to be won. It’s about how do we help people move forward at the right rate.

    I mean I kind of equate it like someone was saying the other day, like similar to autonomous cars, like you’re not going to stop them. Like figure out how to make them work properly, safely, and securely. But if you don’t like it, you’re not going to stop that, have that technology happening and being created so you’ve got to embrace it. That I think is the philosophy that is going to win out the day.

    Shimel: Fair enough. I don’t disagree with you there, Mark. Let’s talk a little bit about what you see near term and maybe a little bit longer term in developments here that, you know, our listeners, you know, could fundamentally change their day to day. Where do you think we’re heading?

    Curphey: Yeah, sure. So, you know, I think machine learning and artificial intelligence and big data were sort of touted and, you know, the hype cycle kick off and, yeah, people didn’t always deliver on that. But there are exciting things happening in that which allow us at scale and at speed to do things that we couldn’t do before. So a good example of that is in the security world most of the vulnerabilities no longer exist in the CV system open source code. They just can’t keep up with the scale. We’re releasing thousands of libraries. In the DevOps world, developers find things, fix them, push them out. They don’t go back to monitor and publish these vulnerabilities, etc.

    But the great news is, you know, there are big data systems, machine learning that can process that data and we can identify those things at scale. Those same kind of techniques have been applied by Google and the Android App Stores and things like that. So that application of like that modern tech I think has great opportunities for us to do things which we’ve not been able to do before, and you’ve certainly seen some of the big vulnerabilities that have been released have been a result of that stuff coming out.

    Shimel: Got it. Got it. I just had my phone ringing there. I apologize. Mark, let’s, if I can and if you’re not too shy about it, I doubt you will be, let’s talk specifically a little bit about Veracode.

    Curphey: Yes.

    Shimel: You know, you’ve been there five months. What do you see? What gets you excited there in the morning?

    Curphey: Yeah. We had loads of places to sort of land. We came to the conclusion that people wanted to have less tools than more. So they wanted to buy a suite. When you look around, what the Veracode guys had done is built sort of best-in-class SAST and it started working on software composition analysis. We had best-in-class software composition analysis. So it made sense from that perspective.

    Also as you know, the heritage of the company, you know, it isn’t a fly-by-night company. It’s Chris Wysopal and Christien Rioux, right? These guys were in the loft, right? So that legendary around the place. So the company has this real DNA about it around security. So for me it’s kind of this exciting security DNA in the company embracing the way we build modern software. So that’s what attracted us to join forces. We’ve been extremely excited since. A lot of exciting things happening that for sure will start to come out of it at the other side no doubt.

    Shimel: I agree with you. I actually have Chris on a panel we’re doing on DevSecOps next week. I’m really excited to have Chris as well as Dave Duncan from CA, I think is on the panel with us.

    Curphey: Right. Right.

    Shimel: So Mark, you know, running out of time here, but I wanted to talk a little bit more about, you know, you came into Veracode, as you said, about five months ago via the acquisition. There’s a lot of people out there seeing a lot of buying and selling, M&A kind of stuff going on in especially around DevSecOps and DevOps related companies. I mean obviously a rising tide lifts all boats and there’s consolidation going on, but is there anything else at play that you’re seeing that’s kind of driving this stuff?

    Curphey: Well, I mean, you know, in the place that you look on the horizon is actually where the dev tools are going. So you know, if we look at companies like AWS, it’s not really just a hosting platform. It’s a full tool suite, right, of everything from machine learning libraries in the cloud to real-time databases and things. Google and Azure are building the same. As we start to think about like what is a next generation of developer look like, they’re likely to use an IDE and a browser. It’s not going to run on a desktop anymore. And you know, co-changes happen and everything happens up in the cloud. So I think there are a lot of exciting things happening there and how do you integrate security into that world for sure. So that’s a lot of the stuff that I’m focused on. Then you can get scaled I think.

    Shimel: Got it. Got it. Mark, you know, I appreciate you talking to us today. I think we’re about out of time. But for people who want to get more information on what’s going on, veracode.com obviously, correct?

    Curphey: Yeah, veracode.com is an excellent, well-trafficked blog with Wysopal and various other people and myself contributing to it which is great and we’re out speaking at conferences and talking about some of the both current work and sort of some of the futuristic stuff as well. So love to engage with the community and the industry for sure.

    Shimel: Perfect. All right. Hey, Mark Curphey, VP of Strategy, CA Veracode. Thanks for being our guest in this episode of DevOps Chat and we look forward to having you on again soon.

    Curphey: Yeah, great, Alan, thanks a lot. Great to reconnect and look forward to doing so the next time.

    Shimel: Okay.

    Curphey: Take care.

    Shimel: This is Alan Shimel for devopsy.kinsta.cloud. You’ve just listened to another DevOps Chat.

    — Alan Shimel

  • DevSecOps: Helping Contain the Security Problems Containers Introduce

    DevSecOps: Helping Contain the Security Problems Containers Introduce

    The idea of building security into applications as they are developed versus bolting it on at the end always made sense but proved difficult to pull off in legacy environments. Monolithic software was too complex and the teams were disparate. But the arrival of containers 1) demands the need to attack the problem earlier because the attack surface changes so rapidly, and 2), thankfully, vastly simplifies the security process when DevSecOps principles are employed.

    The DevSecOps movement, which builds on DevOps by stirring in security, has been steadily building momentum as containers shoulder increasingly critical roles in larger organizations. Heck, DevSecOps even has its own manifesto.

    Although not all organizations adhere to the approach spelled out in the manifesto by DevSecOps.org (which says it was founded by “security practitioners dedicated to the science of how to incorporate security within agile and DevOps practices”), the core elements are the same: The goal is to shift left, as some people say, meaning start the process of securing applications earlier in the development process, improve communications, and repeatedly test along the way.

    Adding the Sec into DevOps

    Obviously, DevSecOps builds on DevOps, which is all about development and operations teams working more closely together to focus on the full life cycle of applications rather than one team focusing on the beginning of the cycle and the other on the end. DevOps is about breaking down boundaries of responsibility and modifying processes so the output is more resilient and code can iterate faster.

    DevSecOps is all that plus security. “DevSecOps requires changing mindsets, processes and technology,” Gartner says. “Security and risk management leaders must adhere to the collaborative, agile nature of DevOps to be seamless and transparent in the development process, making the Sec in DevSecOps silent.”

    The need to embrace the new approach is necessary because containers upend so many conventions.

    For example, in the DevOps world security tends to be viewed as a tech thing. “Are we encrypted?” “Yes.” “Great. We have secure connections. That’s all we need to do.”

    As containers become used for more mission-critical things, that approach is too limited because there are so many more moving parts.

    Before you might have had to worry about securing a few physical servers and a few dozen VMs supporting an application, and now that application requires you to secure 200 to 400 containers, spread across a couple dozen virtual machines in both AWS and Google Cloud. The amount of work has multiplied by 10. The older security methodologies just don’t scale.

    What’s more, there are more layers to worry about—your container runtime (Docker, RKT), your orchestrator (Kubernetes, OpenShift) and your build environment (Jenkins).

    And with containers we release things faster. It isn’t once per quarter or even every month. With containers and microservices architectures and continuous integration/continuous development, we are pushing new versions of software into production on a daily or weekly basis. Existing security practices can’t keep up.

    How Do You Do It?

    There are a number of ways to realize DevSecOps, but typically organizations aren’t going to fully integrate security personnel into DevOps groups, or require developers to become security experts or security experts to become developers. That’s what Gartner was getting at with keeping the Sec in DevSecOps silent.

    The movement is all about building processes and inter-team communications and workflows, which is also how DevOps started before it become more of a delineated role/persona. Yes, developers will have to learn more about security. Yes, security team members will have to learn some particulars about containers. And, yes, workflows will need to morph.

    But the good news is that once experts from the various disciplines agree on what is important, many of the DevSecOps processes can be automated.

    When to Test

    Job one is figuring out where in the container development process code should be tested for security. The goal is to set up a series of gates developers have to go through to make the resultant code more secure. Typically—and most critically—it starts with scanning source code repositories.

    So, before an app is even built, the code the developers are writing is being checked. Are they referencing a package with known vulnerabilities, or pulling in a library that has a vulnerability or is open source and against company policy? This a workflow change that starts the security process much sooner than traditional approaches.

    The next check in the cycle typically comes when the container image is being built, say in Jenkins, the popular open source build environment. When the image is being pulled together, packaging the code up into a container and defining dependencies, a scan is done to ensure it is free of vulnerabilities and is configured to meet the best practices and policies defined by the organization.

    And finally, when the image is pushed to the registry, the image is scanned yet again before it can be put into production.

    All these checks are tied to your CI/CD pipeline and just become part of the developer’s build process. The scans themselves are automated.

    “The goal of CI is to provide rapid feedback on disparate code changes, allowing developers to correct errors as soon as possible by identifying functional defects introduced into the larger code base,” according to eSecurity Planet. “In this environment, integrated security testing is needed to provide developers a real-time threat assessment of all changes they’ve made, regardless of their operational success in the larger code base.  Without integrated security testing, there’s a risk of re-engineering solutions multiple times to address security threats detected long after functional solutions are accepted.  That wastes valuable time, money, energy and effort.”

    Gates = Slow?

    Developers traditionally have viewed security as a necessary evil. They would build something, get it in staging, test it and then right before it hits production, some security review would identify 10 things that need to be changed.

    Testing more often, earlier and using automated scans vastly reduces the chance there will be significant problems with the resulting application. So, while the idea of introducing testing gates into the development process might seem like something that would put off developers, the end result will more than make up for any inconvenience along the way. Instead of huge changes at the end, there are incremental fixes at different phases of development.

    Companies are adopting many of the DevSecOps practices today even if they aren’t calling it that. DevSecOps is, after all, more of a process and a way of working rather than a specific role. Those practices enable organizations to move faster and improve the quality of the services they deliver from a risk, security and compliance perspective.

    Of course, there is no such thing as 100 percent security, and vulnerabilities will still crop up and be exploited. But even here a DevSecOps culture can be a huge step forward for container environments.

    In legacy enterprise environments, when a vulnerability is found in something that is running live, the organization would identify it as critical and have a service level agreement that called for it to be patched in two weeks. The patch needs to be developed and the deployment planned, and probably includes some amount of infrastructure management and updating.

    With DevSecOps and container environments, you can make the change in development and push it out within a day.

    So, even as containers change the security calculus by introducing more and new things to worry about, with the adoption of DevSecOps best practices organizations should come out being more secure and fleet of foot.

    — Loris Degioanni