Tag: devsecops

  • Reflections: A DevOps Christmas Carol

    Reflections: A DevOps Christmas Carol

    “Marley was dead, to begin with.” So begins my DevOps Christmas Carol. In this reflection, I am visited by the ghosts of DevOps past, present and future. I hope that, after hearing my story, you will have a better understanding of where DevOps is going based upon where it came from and where it is now.

    The Ghost of DevOps Past

    The ghost of DevOps past took me back to Las Vegas, 2012. I shared a bottle (or two) of wine with Gene Kim, Gene was talking about a manuscript for a book he was working on based on The Goal by Eliyahu Goldratt. It was a digital story of resource constraints and the way forward based on something called DevOps. I was fascinated by this new way of thinking about development and operations while musing about what a great thing that could be for security, which was my thing then. A whole new world opened up to me as I met and learned about the work of people like Patrick Dubois, John Willis, Jez Humble, Damon Edwards and more.

    I was taken to Boulder, Colorado where Foundry Group and Techstars were putting on a symposium to make sure their portfolio companies were smart about DevOps. The CTO of Rally software did a presentation on Agile and DevOps and, again, it was like looking at the IT world from a whole new vantage point. It was after speaking to some of my friends, Rajat Bhargava and Brad Feld, that the idea for what became devopsy.kinsta.cloud was born.

    What a golden time that was. DevOps was an elusive thing. No manifesto, no official definition. Some people said it was mythical and not real. Others said it was just for startups born in the cloud. Still others said it was just for large enterprises. DevOps, it seemed, could be everywhere and nowhere, all at once.

    Looking back, it was an exhilarating time, with philosophical arguments vigorously debated. And over the weeks, months and years that followed, the idea of DevOps became a real thing, the benefits it provided revealed themselves and a set of best practices emerged. My partners at the DevOps Institute and I tried to capture these emerging best practices and build courseware and certifications around them. Oh, my—what a sh*tstorm that created. The idea of being certified in DevOps was scoffed at, derided, spit on and ridiculed. But that, too, eventually passed. Looking back at this part of my trip, I realized that while it all seemed idealistic and exciting and despite the ups and downs and bumpy road, we were always moving forward.

    The Ghost of DevOps Present

    Next, the ghost of DevOps present visited me. In this dream, DevOps had begun to blend into the woodwork. For the most part, it was an accepted way of developing and operating software. Many principles such as CI/CD, continuous testing, SRE and DevSecOps were mainstream. While not 100% fully adopted, the majority of organizations used some DevOps patterns in their business.

    It had become so mundane, in fact, that people began to ask, “Has DevOps hit the wall?” “Has DevOps passed its peak?” and “What’s next for DevOps?” While this may sound ominous, it is actually par for the course in the adoption cycles of new technologies. As certain as the Gartner hype cycle, technology that has settled into the stack seems to be the way of things. So as much as the ghost of DevOps present tried to frighten me, I was unafraid. Adoption was proceeding just as expected. It was firmly entrenched as part of digital transformation initiatives. Cloud-native and DevSecOps also were becoming more and more accepted.

    The Ghost of DevOps Future

    Next, I was visited by the ghost of DevOps future. She showed me a glimpse of what the future held. In this future version, SREs worked side-by-side with DevOps teams. There was a smooth handoff at the time of deployment ensuring that apps behaved the way they were intended. Automated feedback loops allowed developers to incorporate lessons learned into future versions. 

    Low-code/no-code solutions designed for developers allowed for even faster, automated deployments. AI-enabled applications let testing keep pace with development, more automation enabled even faster deployments. 

    AI also made observability more than just a spectator sport. Actionable intelligence that was wisely acted upon was the norm in this future. Of course, security was still an issue. There were even more regulations and compliance requirements. The bad guys were as notorious as ever. It seems even a DevOps future where security was everyone’s responsibility could not fully solve our security issues. But, overall, progress had been made.

    DevOps teams were deploying directly from Git onto cloud-native stacks that started with Kubernetes but didn’t end there. There were service meshes and APIs connecting everything. Serverless platforms were offered by most vendors. Overall, no one wanted to be locked into one cloud provider and picked the right cloud for each project. Indeed, DevOps in the future seemed on the verge of recognizing and achieving many of its aspirations.

    I awoke and felt good about everything that was happening with DevOps. In the words of Tiny Tim from that other Christmas carol, “God bless us, every one!”

  • DevSecOps for Databases: Data Masking, Cloud Backup, WAF and More

    DevSecOps for Databases: Data Masking, Cloud Backup, WAF and More

    DevSecOps is everywhere. More and more organizations realize that the traditional separation between DevOps and security is wasteful and dangerous. As a result, they are rushing to integrate security into all their software development processes. 

    Adding security to containerized applications, cloud resources and other parts of modern DevOps infrastructure is already well understood. But what about databases? Databases were always—and remain—a critical system component and a prime target for attackers. Here, I’ll review the basics of modern database security and show you how to create a continuous security process for databases in a DevSecOps organization.

    What is DevSecOps?

    DevSecOps incorporates security practices into the DevOps methodology. DevSecOps promotes a ‘security-as-code’ approach via the partnership between release engineers and security teams. Similar to DevOps, the DevSecOps approach focuses on creating innovative solutions for complex software development processes. Teams complete this within the framework of an agile approach.  

    DevSecOps aims to close the gap between security and IT teams while ensuring the speedy and safe delivery of code. Organizations replace the siloed development method with a new approach that promotes the shared responsibility of security tasks during the delivery process. 

    In DevSecOps, two supposedly opposite aims—delivery speed and secure code—are united into one effective process. 

    Database Security Basics

    The term “database security” is an umbrella term used to describe all of the tools created to develop and preserve database availability, integrity and confidentiality. A key responsibility for any DBA is to ensure that the information stored in databases is always secure.

    The goal of database security is to protect:

    • Database management systems
    • Applications that access database information
    • Datastores within databases
    • Hardware servers
    • Virtual database servers, such as cloud-based servers
    • Network access points

    It is critical to strike a balance between security and usability. While you must prioritize data security, information needs to be accessible to offer value to the organization. The more access you provide to the information retained in a database, the more vulnerable the information is. However, an overly secure database is neither practical nor functional.   

    A good way to achieve a balance between accessibility and security is to create meaningful security protocols, create tiered levels of information access and invest in a robust database security and activity monitoring tooling. 

    Common Threats and Challenges

    Here are some of the most common types of database attacks:

    • Insider threats—These involve privileged users misusing their access credentials. An insider could be a negligent employee who unwittingly exposes the database to attack, a malicious insider who abuses the database on purpose or an outside infiltrator who steals credentials to breach the database. The risk of a breach increases as more employees hold privileged access credentials.
    • Injection attacks—These involve inserting arbitrary attack strings into the database queries that HTTP headers or web applications serve. These attacks can be SQL or NoSQL. Secure coding practices and regular vulnerability tests should help protect you against injection attacks.
    • Database software vulnerability exploits—Database software providers regularly release security patches for vulnerabilities in their software. However, if you don’t apply the patches quickly, you prolong your exposure and run the risk that hackers will exploit vulnerabilities in your database. 
    • Backup attacks—If you don’t protect your backup data with sufficient controls, you expose your database to an attack on your backups. 

    The following challenges can exacerbate these threats:

    • Large volumes of data—Organizations must adequately manage increasingly large volumes of data using scalable tools and practices.
    • Sprawling infrastructure sprawl—Organizations are increasingly shifting to hybrid and multi-cloud environments, making their networks more complex and security harder to manage. 
    • Evolving regulations—With the global regulatory landscape changing and growing more complex, it is increasingly challenging to maintain compliance.
    • Skill shortage—The demand for cybersecurity personnel far outstrips supply, and this shortage is only likely to increase in the future. 

    4 Techniques for Continuous Database Security With DevSecOps

    A DevSecOps approach calls for continuous database security during all stages of database development and usage. Let’s explore a few techniques for achieving continuous security.

    Data Masking

    Data masking technology lets you create a structurally similar, anonymized version of an organization’s data. You can use this data for user training or software testing. The aim is to safeguard the real data while using a functional substitute for use cases in which the actual data is not needed.  

    In data masking, you keep the format of the data the same. You only change the values of the data. You can alter the data in various ways including character shuffling, encryption and word or character substitution. Whichever method you choose, you have to modify the value in some way that makes reverse engineering or detection impossible. 

    Use data masking when presenting data to users (whether inside or outside the organization) who don’t need to access the data as part of their role. You should apply data masking to all sensitive information before displaying it in public forums. 

    Use Web Application and Database Firewalls

    Protect your database server from security threats using a firewall that stops access to traffic as a default. The only traffic permitted should come from particular web servers or applications that require access to the information. The firewall must also prevent your database from establishing outbound connections unless they are specifically needed. 

    Protecting the database using a firewall is not enough. You should also deploy a web application firewall (WAF). That’s because SQL injection attacks, which target web applications, can be employed to delete or exfiltrate data from the database. A database firewall may not stop this from occurring if attacks are initiated from an application that is a permitted source of traffic. However, a web application firewall likely will stop attacks of this nature because it can analyze traffic at the application layer and identify malicious query patterns.

    Cloud Backup

    Database backup solutions help organizations safeguard their data with backup database copies in the event of user error, physical hardware failure, data corruption or ransomware attacks. Organizations can ensure their information is always accessible by using database backup tools, even if their central database fails or is compromised. 

    Cloud backup services allow you to send a database copy to an off-site, secondary location for safekeeping if there is a disaster or failure. A third-party service provider typically hosts the secondary data storage systems and servers. This provider bills the backup customer based on capacity used or storage space, number of users, data transmission bandwidth, number of times the information is accessed or the number of servers. 

    Using cloud data backup can help you improve data protection without overwhelming IT staff. This labor-saving advantage could be significant and may even offset some of the added costs connected with cloud backup, including data transmission costs. 

    Secure Database User Access

    You must strive to limit the number of individuals with access to the database to the extreme minimum. Administrators should only have minimal privileges—those they require to carry out their job and only when they require access. 

    For small organizations, this might be difficult to achieve because employees have multiple roles, and there may be only one or two database administrators. However, you should at least manage permissions using roles or groups rather than granting access directly.  

    If you have a large organization, you must think about automating access management via access management software. Access management software can give authorized users a provisional password with the privileges they require every time they want access to the database. This software also logs the activities conducted during that time and stops administrators from sharing their passwords. 

    It is critical to lock down any form of password sharing—this is a common practice by administrators and database users, but it makes accountability and effective database security nearly impossible. 

    In addition, you should follow standard account security procedures: 

    • Enforce the use of strong passwords
    • Store, encrypt and salt password hashes
    • Lock accounts after three or four login retries
    • Deactivate accounts when employees leave or switch to different roles

    DevSecOps and Database Security

    In this article, I explained the basics of DevSecOps and database security, covered the primary threats facing database systems in a modern IT environment and provided four ways you can implement continuous security for databases:

    • Data masking—All modern RDBMS systems offer data masking mechanisms that can reduce the impact of compromised accounts.
    • Using WAFs and database firewalls—Firewalls provide excellent runtime protection and visibility for application-layer attacks.
    • Cloud backup—Backing up databases in the cloud is a continuous process that can enhance availability and reduce the impact of ransomware attacks.
    • Secure database user access—Using least-privilege principles can dramatically reduce the threat surface of a database.

    I hope this will be useful as you extend your DevSecOps practices to critical database systems in your environment.

  • API Sprawl a Looming Threat to Digital Economy

    API Sprawl a Looming Threat to Digital Economy

    New estimates say the total number of public and private APIs in use is approaching a whopping 200 million. APIs are becoming increasingly crucial to the global digital economy. They are the backbone of many digital platforms and drive the composable enterprise model. But this ubiquity presents sprawl issues.

    F5 recently released a study that examines the conditions of the API economy at large. Authored by Rajesh Narayanan and Mike Wiley of F5, the paper, Continual API Sprawl: Challenges and Opportunities in an API Driven Economy, articulates the state of API sprawl and the conditions behind its arrival.

    According to Narayanan and Wiley, “If data is the new oil, then APIs will become the new plastic.” This looming reality will require a continuous approach to API management to avoid further polluting the digital ecosystem.

    Below, I’ll review the report’s main takeaways to see what has given rise to API sprawl and consider how IT leaders should respond.

    State of API Growth

    APIs have evolved as a standard mechanism for businesses and services to connect and share value. And, as more companies begin to rely on them, the API economy is becoming big business—83% of organizations today consider API integration a critical part of their business strategy, according to the 2020 Cloud Elements State of API Integration Report.

    There is a proliferation of API styles. Thousands of public productized APIs exist, but more private and partner APIs are in use. Technically speaking, APIs come in many different forms—they may be web-based, browser-based or embedded into devices. The report also identifies single-purpose APIs and those that aggregate multiple data providers.

    API use cases are pervasive, from hotel bookings to weather, stock tickers, transportation, IoT, DevOps workflows and many other areas. “API-powered apps have permeated every aspect of our lives,” said the report. Yet, typical market estimates are usually quite conservative when sizing up this market, said F5. According to F5’s aggressive calculations, we will be approaching 1.7 billion active APIs by 2030.

    APIs present a high value from startup use cases to enterprise applications. However, a downside is that this growth is leading to sprawl, said Narayanan and Wiley.

    API sprawl is the term used to describe both the exponentially large number of APIs being created and the physical spread of the distributed infrastructure locations where the APIs are deployed.

    Factors Driving API Sprawl

    Sheer growth. Sources predict the number of developers will grow to 45 million by 2030. SlashData also estimates that 30% of developers already use APIs. As the number of APIs on the market moves into the millions, managing growth poses a significant challenge, especially without proper governance and best practices.

    Lack of standards. “The lack of a common shared model contributes to API sprawl,” the report said. API design standards do exist, yet guidelines often leave room for nuances between services. Standards have also emerged around specific industries, like financial data exchange (FDX). While helpful for a single sector, this doesn’t advance multiple industries simultaneously. A lack of standardization leads to differing versioning approaches and integration challenges.

    New development approaches. Integration requirements are forcing many new APIs to unite disparate business apps. The microservices architecture trend is also adding to sprawl, as “APIs are both northbound to interfaces via microservices and horizontally between microservices.”

    Continuous software development. Continuous development, paired with the need to connect business units with bespoke requirements, could produce multiple versions of the same API. This quickly leads to maintenance difficulties, out-of-date documentation and broken clients. The report also cites rising data creation and “everything-as-a-service” trends as harbingers of an API sprawl.

    Various computing evolutions. New computing trends are also prompting a sprawl, says the report. Business units may be operating on different on-premises or cloud environments. When this hybrid situation occurs, APIs could get dispersed over many locations and become difficult to track. Specific connections may be created to cater to new environments like edge computing and IoT devices, further increasing sprawl.

    Problems With API Sprawl

    A digital economy reliant on APIs also relies on the underlying stability and availability of these services. Yet, “APIs have a shelf life and become unsupported if ignored by the developers,” the paper acknowledged. It could be hard to maintain service reliability for APIs sprawled across a distributed cloud. In addition to reliability issues, there are many other possible repercussions of an API sprawl.

    For one, management and operation at scale become difficult. Not all APIs are based on a specification, like OpenAPI. This means that API documentation may not be as streamlined and accessible, thus hurting discoverability and onboarding. “A simple means to connect these APIs may not be possible with conventional or legacy networking approaches,” the report added.

    As developers are top consumers of APIs, a sprawl could negatively impact their integration experience. Maintaining a swelling library of API dependencies can be cumbersome. Plus, APIs are prone to evolve and version over time and when endpoints are altered without advance notice, it leads to broken clients. Even small changes in API functionality can have a huge impact since all observable API behaviors will become relied upon, whether documented or not. (This is known as Hyrum’s Law).

    But the security ramifications of API sprawl are perhaps the most troubling. A whopping 91% of enterprises experienced an API security incident in 2020. Malicious API traffic also rose by a staggering 300% in mid-2021, Salt Labs found. Increased API use will undoubtedly cause more frequent attacks.

    “Unmanaged API sprawl is a security breach waiting to happen,” said the report. APIs typically adopt API keys for authentication and authorization, but this method is prone to misuse. Credentials are often exposed or misconfigured. Bad actors can use APIs to steal loads of data and computing power. As a result, sprawl is undermining trust in API connections and responses.

    Mitigating The Sprawl

    With the growth of the API economy slated to reach the billion mark in the next ten years, figuring out secure, stable inter-cluster communication will become more critical. According to F5, existing solutions (gateways, ingress controllers, service mesh and forward and reverse proxies) are not an adequate response.

    “We believe the solution should hence involve an intermediary (proxy) device focused on solving inter-cluster connectivity, security and integration challenges.” The writers call this solution API Gateway 2.0, which they describe as a bi-directional application-level proxy. The technology exists to implement such middleware and perhaps it could help companies address sprawl issues.

    Outside of Narayanan’s and Wiley’s recommendations, there are plenty of actions API owners can take to avoid adding to the sprawl. Here are a few:

    • Treat the API as a product
    • Improve developer experience
    • Use spec-driven development
    • Ensure up-to-date documentation and code libraries
    • Use consistent endpoint naming
    • Set clear guidelines for versioning and deprecation
    • Go beyond API keys with OAuth and OpenID Connect

    For more context, check out Continual API Sprawl: Challenges and Opportunities in an API Driven Economy for free without an email gate here.

  • A Pro Football Approach to Agile Vs. DevOps

    A Pro Football Approach to Agile Vs. DevOps

    Enterprises and professional football teams have a lot in common. The pressures of being more agile, more resilient while ensuring performance is felt both on and off the field. For CIOs, surviving and thriving requires a serious focus on operations tied to business mandates and growth.

    I am frequently asked questions around infrastructure and operations (I&O) with organizations looking to solve ITOps, DevOps and DevSecOps challenges.

    • How do we shift from legacy ITOps models to transformative digital operations?
    • How do we align process, people and tools for closer integration, consolidation and correlation?
    • How are we structured as teams across functions—ITOps, DevOps, SecOps?
    • How do we transform to analytics-driven operations at speed and efficiency?

    Historically, Agile and DevOps teams face off on the IT playing field as adversaries; both sides want to advance their plans, execute plays and reach the end zone. Disconnects happen when teams are not aligned, goals are not defined and resources are constrained.

    To effectively deliver digital services, teams must focus on the essentials of clear communication, unified culture and measures to ensure resiliency, performance and availability if they are to be effective.

    Traditional I&O teams often operate independently, and knowledge is not shared nor available to cross-functional teams. Attempts to respond and resolve critical incidents can take longer. With DevOps or even DevSecOps, the ideal is for groups to align across functions by breaking down silos of tooling and responsibility.

    In a hybrid ops environment, a lack of integration and coordination between DevOps roles can easily misalign efforts and priorities. Whether it’s hybrid in terms of IT environment or hybrid in support model, there are unique challenges that must be addressed. Not being able to huddle around the same data sets while troubleshooting incidents poses a huge challenge when implementing proper analytics comes into play. Legacy IT operations management (ITOM) tools simply cannot support DevOps’ use of cloud-native services nor support remote IT teams working globally.

    For successful DevOps and traditional Agile teams to coexist and be successful, IT leaders need to change existing mindsets and implement new practices in order to scale.

    • DevOps and ITOps groups have to feel supported by the entire IT organization.

    Often DevOps starts as an experiment with a small group of people working on one application. Everyone in IT, from the leaders to IT workers, needs to understand what the end goals are for integrating new methodologies. Deep realization sets in when DevOps finishes a project and pushes to production which is still supported in traditional ITOps models. It becomes obvious that operations needs to adapt to frequent change.

    • Plan and implement DevOps practices to avoid disruptions.

    With legacy systems still in practice for delivering digital services, DevOps teams cannot disrupt critical day-to-day operations by driving new support models without taking into account migration considerations. Instead, teams will need to work in a hybrid model using application development delivery methods.

    • Collaboration and planning tools are essential.

    The use of collaboration and planning tools alongside automation capabilities is essential in hybrid organizations. Start by automating alerts to generate tickets for the appropriate team(s) to handle versus having Level 1 support process all alerts independently.

    • Build or buy scalable data analysis systems.

    These systems will aggregate and correlate data across infrastructure and digital/cloud-native technologies to deliver contextual insights to problems and provide corrective steps to resolve them.

    Scaling and modernizing operations and creating agile practices is an ongoing process that needs constant planning, testing and adapting. Streamlining DevOps and ITOps processes using automation starts the process as teams begin to work together versus working in traditional silos.

    For winning football franchises, dynasties weren’t built in a single season; the same is true for your digital ops transformation. It takes challenging the status quo—taking a hard look at the deeply embedded ways ITOps has always been done—and reimagining the whole process focused on data-driven digital operations.

  • DevOps Teams Struggling to Keep Secrets

    DevOps Teams Struggling to Keep Secrets

    A growing number of organizations are suffering security incidents related to exposed secrets in DevOps CI/CD pipelines, according to a recent ThycoticCentrify report.

    The study paints a troubling picture: Only 5% of survey respondents said most of their development teams use the same secrets management processes and tools.

    The incidents run the gamut, from secrets published in the clear in public cloud code repositories to insecure third-party code to vulnerabilities in the organization’s own code or configurations.

    The problem is often made worse by security teams not knowing what to protect because development teams have their own cloud infrastructure or the ability to create internet-facing applications directly without security teams’ knowledge.

    “The reason why we see so many security incidents related to exposed secrets in DevOps is that using hardcoded passwords and keys is the easy path to getting things to work,” said Joseph Carson, chief security scientist and Advisory CISO at ThycoticCentrify. “We need to make it just as easy for DevOps to use secrets vaults so even when secrets get compromised they are no longer usable, valid or expired.”

    Carson said moving away from persistent privileges to just-in-time, on-demand privileges will reduce these types of misconfigurations and attacks.

    “Unfortunately, many developers continue to use hardcoded passwords or static keys that, when compromised, allow an attacker to gain control of the application resulting in either data exposure, ability to change the application configuration or move laterally around the network,” he added.

    John Bambenek, principal threat hunter at Netenrich, said the fundamental problem is that when organizations go to agile and DevOps, they remove all friction to moving code quickly—and that almost always includes removing security.

    “That means security is inherently reactive instead of being embedded into engineering, and that’s assuming security even knows what to protect in the first place,” he said. “It’s the natural consequence of removing security from the equation and expecting that it’ll just work on the backend. That approach hasn’t worked for decades; a JIRA board isn’t going to suddenly fix that problem.”

    From Carson’s perspective, secrets management is the ability to move away from hardcoded passwords or static keys to just-in-time privileges or one-time-use passwords so even when comprised they cannot be used.

    “Many privileged access management solutions that protected privileged access for years have extended functionality to developers to help move the value into DevOps so they can manage credentials for applications, databases, CI/CD tools and services without causing friction in the development process,” he said.

    Approaches like privileged access security helps enable API-as-a-service and provides instant availability of secrets, SSH keys, certificates, API keys and tokens.

    Secrets Management

    Bambenek added the problem isn’t choosing a secrets management process or tool, but rather that they aren’t in place at all.

    “Pick something that will keep keys and secrets out of public cloud repositories that developers will use that allows for quick and easy rotation of keys as the need arises,” he said. “The most important thing is that it’s the same tool everywhere that operates in a near-invisible process for developers. Four decades of software vulnerabilities have taught me that if you rely on the developers to do the secure thing, you’ll consistently be disappointed.”

    One Wrong Step

    Davis McCarthy, principal security researcher at Valtix, pointed out developers are not security practitioners by trade.
    “Developers are building new ideas, and no good idea comes without experimentation,” he said. “Experimenting with a new technology stack may lead to misconfigurations that unintentionally expose data.”

    McCarthy said shared SSH keys between users create a larger attack surface, and users will store secrets differently creating multiple attack vectors.

    If one user’s endpoint becomes compromised and their SSH keys are exfiltrated, it’s difficult to know what the first mitigation steps are. Between insider threats and malware, the wrong step could lead to a breach.

    “Whereas a software engineer may hold great knowledge of secure coding methodologies, web application attacks and encryption, they are still focused on executing their craft,” he said. “Organizations that do not build security into the development life cycle create a systemic risk that leads to failures in best practices.”

    McCarthy added organizations can centralize and embed secrets management into the tools already in use in CI/CD pipelines by creating an inventory, auditing it and frequently rotating secrets to sensitive environments.

    Bambenek said the short answer is to make sure the infrastructure of CI/CD pipelines is centrally managed and controlled without the ability of engineering teams to ‘roll their own.’

    “No security control will remain intact if someone can pick their own tools without any real governance,” he said. “CI/CD processes don’t require engineering teams to manage the backend of the deployment pipeline which means someone can ensure those functions are in place to begin with.”

  • Top 10 DevOps Things to Be Thankful for in 2021

    Top 10 DevOps Things to Be Thankful for in 2021

    Thanksgiving has been observed in the U.S. since 1861 and was officially designated as an official holiday in 1863 by president Lincoln. Of course, the tradition itself traces its lineage to the early days of the Pilgrims.

    This past year, of course, has been one of recovery from a pandemic that caused the deaths of millions of people around the world. Vaccines have saved the lives of countless more, so there is much to be thankful for despite all our recent trials and tribulations. In that spirit, there are more than a few things for DevOps professionals, in particular, to be thankful for this year starting with:

    Digital business transformation: Organizations of all sizes have had to adjust their business models because of both major changes in buyer behavior and an ongoing supply chain crisis. DevOps teams are at the core of any major digital business transformation initiative, so the demand for DevOps expertise continues to outstrip the available supply. Going forward, it’s been predicted we’ll see more digital transformation in the next 10 years than in all the last 40 years combined. The vast majority of those initiatives would never see the light of day if it were not for the expertise of developers and engineers working hand-in-hand to build and deploy applications faster than ever.

    Low-code platforms: As the demand for applications to drive digital workflows spiked in the wake of the pandemic, professional developers relied more on low-code platforms to decrease the time required to build an application. While many complex applications will still be built using procedural code, it’s clear not nearly as many applications could have been deployed without relying on low-code platforms to build them. It remains to be seen how many of the next generations of low-code applications will be built by so-called citizen developers that may soon be flooding DevOps pipelines with application code.

    Microservices: As an architecture for building applications the core concept of employing loosely coupled services together to construct an application goes all the way back to when service-oriented applications (SOA) were expected to be the next big thing in the 1990s. Microservices have, of course, been around for several years themselves. However, with the rise of containers as a software artifact for building microservices, it’s only now becoming apparent that building an application constructed using microservices not only takes less time but is easier to maintain and also more resilient.

    Observability: As a concept, observability traces its lineage to linear dynamic systems. Observability in its most basic form measures how well the internal states of a system can be inferred based on knowledge of its external outputs. In the past year, a wide range of IT vendors introduced various types of observability platforms. These make it easier for DevOps teams to query machine data in a way that enables them to proactively discover the root cause of issues before they cause further disruption. That’s a major advance over monitoring platforms that typically only provide predefined metrics to identify when a specific platform or application is performing within expectations.

    Biden’s executive order: In the wake of a pernicious attack against IT service management software from SolarWinds, the Biden administration published a sweeping executive order that requires federal agencies to implement a wide range of security best practices. Foremost among them is guidance concerning the security of software supply chains; which resulted in many organizations reviewing their entire software supply chain to make sure similar breaches will not occur.

    DevSecOps: As an extension of any DevOps best practice, DevSecOps generally describes an overall shift left in terms of making developers more responsible for application security. While still in its relative infancy, DevSecOps is starting to gain traction as DevOps and cybersecurity teams look to bridge a cultural divide that is as wide as any in IT. The ultimate goal is to deliver more secure applications without reducing the speed at which they are being built and deployed.

    GitOps: At its core, GitOps is an operational framework that takes DevOps best practices used to automate application development and extends them to infrastructure. The basic idea is that the configuration software created to manage infrastructure-as-code is just another software artifact to be stored in a Git repository. The approach provides a means for IT teams to achieve a continuous delivery goal that, more than a decade after DevOps best practices were defined, remains elusive. It’s still early days as far as GitOps best practices are concerned, but this has been the year when GitOps become part of the mainstream DevOps conversation.

    Kubernetes: Simultaneously one the most powerful and most complex IT platforms ever to come down the proverbial enterprise IT pike, Kubernetes has emerged as a de facto standard for building and deploying container applications that can more efficiently scale up and down as required to consume IT infrastructure. The challenge (and the opportunity) now is to make Kubernetes much more accessible to mere mortal IT administrators that typically don’t have the programming skills of a site reliability engineer (SRE) and which are both hard to find and retain.

    GraphQL: Employed as a query language for application programming interfaces (APIs), GraphQL provides a more efficient means of accessing data than the REST APIs that have been employed by developers in the past. Originally developed by Facebook, GraphQL adoption is still in its infancy but it’s clear APIs based on GrapQL will one day be as plentiful as REST APIs. That’s especially critical for microservices-based applications that rely on APIs to access data across a highly distributed computing environment that requires a more efficient means for transferring data.

    Venture and Wall Street capital investments: Investment firms are helping fuel DevOps advances as they continue to make capital available for companies vying for their share of a market that is expected to see compound annual growth rates of 24.7% through 2026. There will, of course, eventually be a wave of consolidation as merger and acquisition activity inevitably ensues. In the meantime, however, there is a wide range of DevOps technologies that might not otherwise be as broadly adopted if it were not for all the cash being poured into DevOps companies.

    The most important thing, of course, is that so many DevOps professionals are still here to build and deploy applications. It’s been a trying year for all concerned; however, as the pandemic crisis continues to recede, we can all be thankful for the opportunities that lie ahead.

  • Stopping Mobile Fraud With Automation and DevSecOps

    Stopping Mobile Fraud With Automation and DevSecOps

    Mobile fraud is a multibillion-dollar problem that’s only getting worse. One study showed that mobile click fraud alone rose 64% during the first few months of the COVID-19 pandemic. In fact, during the pandemic, about one in five mobile ad clicks were fraudulent. And that’s just one form of mobile fraud.

    Weaponized botnets, mobile malware, mobile Trojans and mobile cheat engines and dynamic instrumentation tool abuse—the methods that fraudsters use to defraud companies and consumers via mobile devices—are constantly expanding in number and scale. 

    Historically, organizations have fought against fraud through monitoring and data analysis. As transactions and data come in, analytics and AI work to discern legitimate events from fraudulent ones. These systems require training and a lot of data to become proficient at identifying fraud, and they can become very accurate. But fraudsters are always changing their tactics to evade these systems, and, as many of us have experienced, false positives are still a big problem. If you’ve travelled enough overseas, likely you’ve had your bank account or credit card frozen until you could call your financial institution to let them know that your purchases were genuine. 

    Another challenge with existing mobile fraud prevention solutions is that they are designed to protect networks and network resources first. As a result, while fraud is occurring and fraud prevention systems are learning, mobile end users are still being affected. Also, when a bad act is identified and a system enforces protections against fraud, these enforcement points typically block network traffic. That protects the network, but the consumer and their mobile app remain at risk. Once a fraudster compromises a mobile app, they may be able to attack through other vectors, even if one network is shut down. For instance, if a consumer unwittingly downloads and launches EventBot to their mobile device thinking it was a legitimate app, it may compromise multiple banking apps. If one bank shuts down its network after detecting fraud, EventBot may have other opportunities on the device.

    DevSecOps

    As this chart shows, once fraud takes place, damage to a brand, customers and the bottom line begins immediately. Even if it is detected and halted, the harm it has already caused can’t be undone. Mobile app publishers and developers need to stop mobile fraud where it starts, and that means implementing mobile fraud prevention inside the app within a DevSecOps framework. By blocking the technical methods used to carry out fraud via mobile apps, organizations can make massive inroads toward stopping fraud before it ever gets to the network level, preventing both customers and organizations from getting scammed.

    Why Traditional Security Approaches Don’t Work in Mobile Apps

    To achieve a multi-layered defense against fraud, a mobile app should include app shielding, anti-tampering, code obfuscation, data encryption (including strings, resources, preferences), jailbreak/rooting prevention and man-in-the-middle prevention (such as certificate pinning or certificate validation). Certainly, there are commercial SDKs and third-party libraries that can provide these functions, with some limitations. But these approaches typically still require extensive development work and introduce additional frameworks or programming language dependencies and incompatibilities. 

    They don’t solve the fundamental problem of implementing fraud prevention inside a mobile app—it’s too expensive and time-consuming.  The root of the problem rests in the way mobile apps are developed, released and updated in a modern agile organization. DevOps depends on processes that are dynamic, automated, agile, integrated, iterative and continuous. Mobile app security has traditionally been very different: Static with manual, line-by-line coding. This way of implementing manual security will never work in an agile delivery model.

    The promise of DevSecOps is built-in security, delivered as a fundamental part of a release process where security is designed into the process at each and every phase of the life cycle. The security model can be delivered and evolved atomically, iteratively and dynamically so that it adapts to fit the app.

    The future of fraud prevention lies in the mobile app, but to make this possible, the industry needs to apply AI and ML to automate fraud prevention and security implementation into mobile apps on time within an agile, fast-moving and iterative app life cycle and release process.

  • Google Makes Fuzz Testing Integration Tool Available

    Google Makes Fuzz Testing Integration Tool Available

    Google today made available a ClusterFuzzLite tool that makes it simpler to incorporate fuzz testing into a DevOps workflow.

    Fuzz testing refers to an automated software testing technique that involves providing invalid, unexpected or random data as inputs to an application to discover issues such as potential memory leaks.

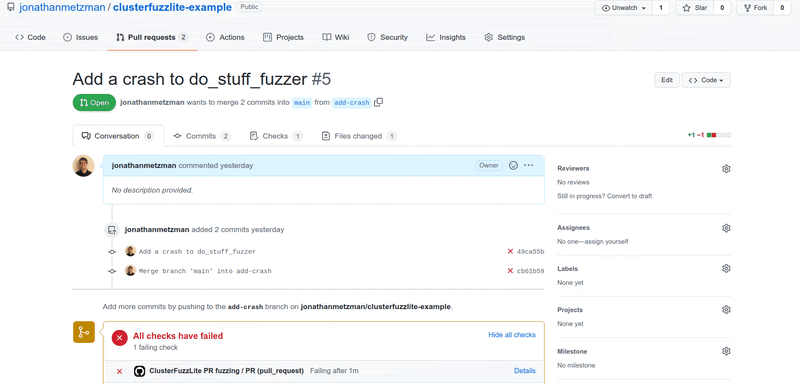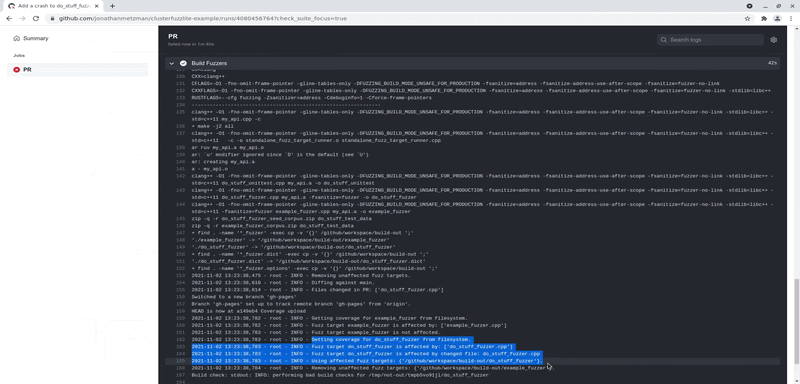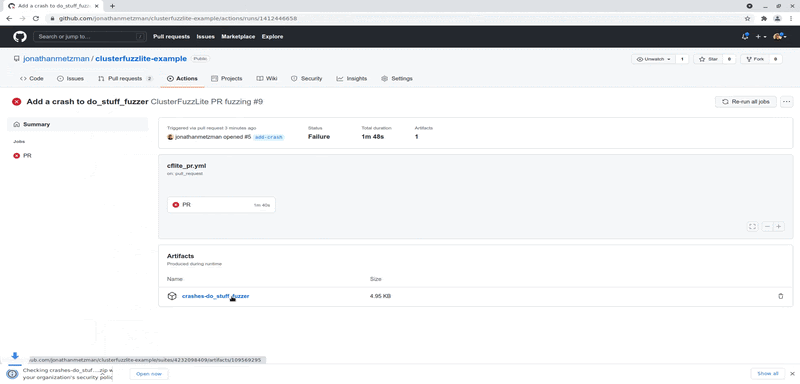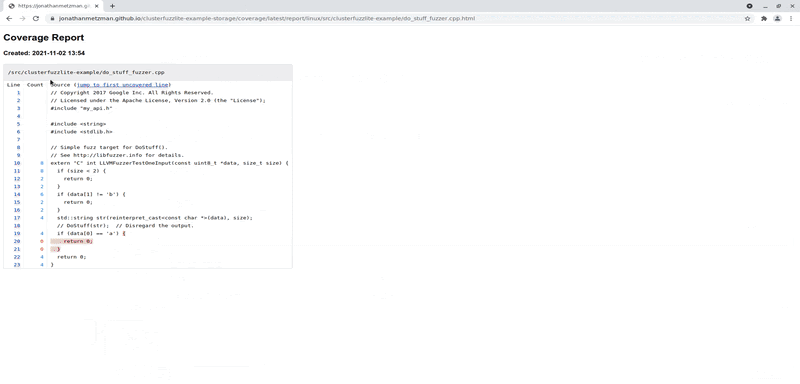
    Jonathan Metzman, a senior software engineer for Google, said ClusterFuzzLite is a lighter-weight version of a tool that Google makes available to its internal development teams. It is not a fuzz testing tool itself, but rather a tool that makes it easier to surface the results of a fuzz test within a DevOps workflow. Once those results are surfaced, it then becomes easier for developers to address issues before an application is deployed in a production environment.

    Core capabilities enabled by ClusterFuzzLite include continuous fuzzing, sanitizer support, corpus management and report generation tools. The goal is to make fuzz testing more accessible to a broader range of developers as part of an overall effort to embrace DevSecOps best practices, noted Metzman.

    ClusterFuzzLite currently supports GitHub Actions and Google Cloud Build, but Metzman said it is easily extensible to other DevOps platforms. It is designed to run as part of a DevOps workflow by adding a few lines of code to a continuous integration/continuous delivery (CI/CD) workflow.

    Google has already made ClusterFuzzLite available to open source projects, but is now providing additional access for commercial developers. Since its release in 2016, over 500 critical open source projects have integrated into the Google fuzz testing program for open source software, resulting in over 6,500 vulnerabilities and 21,000 functional bugs being fixed.

    In the wake of recent guidelines issued by the U.S. National Institute of Standards and Technology (NIST) that were themselves in response to an executive order issued by president Biden, the number of organizations using fuzz testing is expected to increase now that NIST has determined that fuzz testing is a minimum standard requirement for code verification.

    For several years, Google has been making a concerted effort to improve the security of open source software. The challenge for all developers is finding a way to build more secure applications without slowing down the rate at which they are deployed. Fuzz testing makes it possible to identify issues much earlier in the application development life cycle versus just before an application is deployed.

    Less clear, of course, is whether developers are starting to use these tools on their own or if the increased adoption is because of a concerted effort by their organization to embrace DevSecOps best practices. Regardless of the motivation, however, the overall state of application security should continue to improve as it becomes simpler for developers to invoke more advanced testing tools.

    In the meantime, organizations of all sizes are reviewing how they construct software in the wake of a series of high-profile security breaches. In theory, at least, increased focus on software supply chains should prevent issues from arising after deployment when they become much more costly to remediate.

  • Data Theorem Adds Runtime Protection Enabled by Observability

    Data Theorem Adds Runtime Protection Enabled by Observability

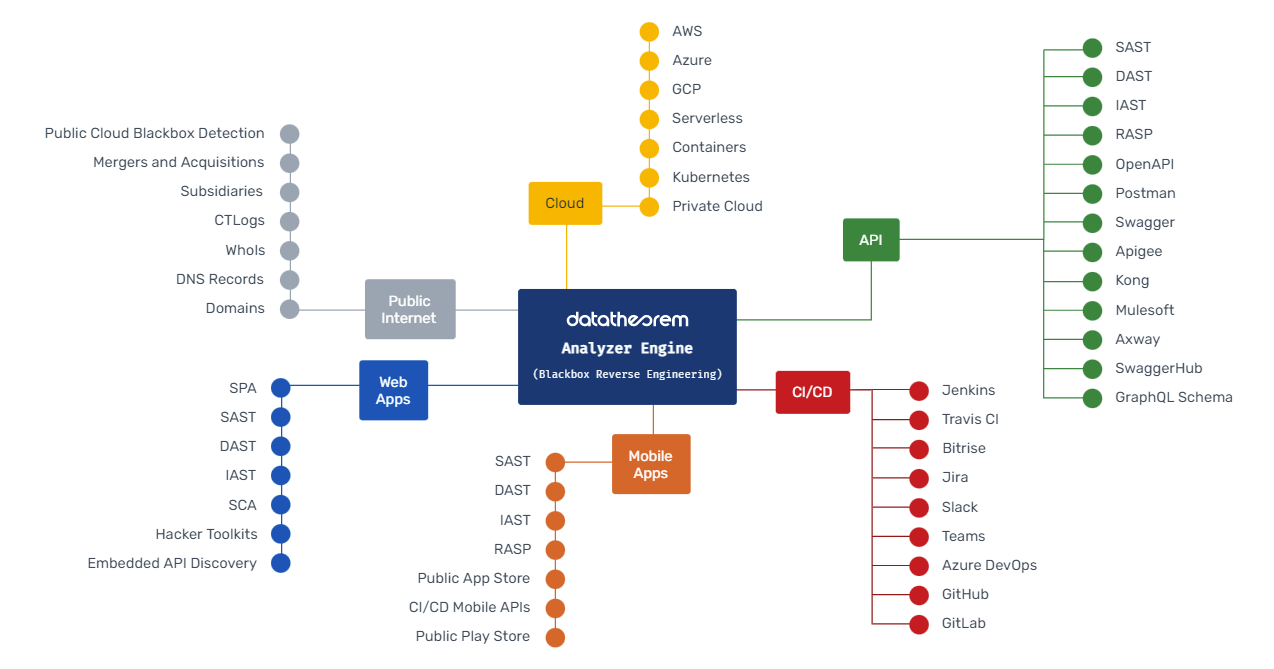
    Data Theorem, Inc. this week added an Active Protection offering to its portfolio of application security services that makes it possible for DevOps teams to embed observability and runtime defenses in their applications via a software development kit (SDK).

    The Data Theorem cloud services are based on Trustkit, an open source framework the company created to make it easier to employ secure socket layer (SSL) to encrypt connections and Analyzer Engine, its runtime analytics engine.

    The company is now extending its services to make it possible to embed observability capabilities by collecting logs and traces. Those logs and traces are then used to enforce runtime security policies that protect applications from known attacks from malicious sources and other common attack vectors as defined by the Open Web Application Security Project (OWASP) Foundation. It also prevents violations of encryption levels, authentication types and authorization rules along with a variety of custom rule checks, including preventing broken object-level authorization (BOLA) attacks.

    Doug Dooley, Data Theorem COO, said Active Protection can be applied across any application stack, including microservices applications based on cloud-native frameworks. In contrast, existing approaches to securing application runtimes based on web application firewalls (WAFs), runtime application self-protection (RASPs) or endpoint detection and response (EDR) agents cannot be applied to cloud-native applications based on containers and serverless computing frameworks.

    Active Protection solves that issue because it is designed to be applied via the Data Theorem software development kit (SDK) or using application extensions made available via a serverless computing framework or as a container sidecar.

    Dooley noted that the Active Protection service is also designed to be fully integrated with DevSecOps workflows that are increasingly being driven via continuous integration/continuous delivery (CI/CD) platforms to enable continuous, automated security inspection and remediation. The company claims to have detected more than one billion application incidents and is currently used by more than 8,000 applications.

    Developers don’t generally set out to build and deploy insecure applications. The issue is most developers don’t have a lot of security expertise, so it’s easy for mistakes to be made. Organizations looking to embrace DevSecOps best practices need to find a way to achieve that goal in a way that developers can easily embrace. The more automated the checks for security issues become during the application development process, the more likely it is developers will make additional efforts to remediate vulnerabilities long before an application is ever deployed in a production environment. In effect, DevSecOps is easier to achieve when addressed from the bottom up rather than via an edict from above without any real implementation plan in place.

    It’s still early days as far as DevSecOps is concerned, but as best practices for DevOps continue to evolve, there may come a day when security is just another gate that needs to be passed within the context of a larger DevOps workflow. In the meantime, DevOps teams and cybersecurity teams should put aside their differences and work together as the number of attacks launched against applications increases.

  • Dynatrace Adds Security Gates to Advance DevSecOps Adoption

    Dynatrace Adds Security Gates to Advance DevSecOps Adoption

    Dynatrace today added a security gates capability to its observability platform to make it easier to automatically embrace DevSecOps best practices within an application delivery pipeline.

    Steve Tack, senior vice president for product management at Dynatrace, said the security gates function much the same as the quality gates that Dynatrace previously added to that platform in that each release is now also automatically assessed to ensure only secure code is being deployed.

    The Dynatrace platform now uses a Davis artificial intelligence (AI) engine to scan for vulnerabilities in application workloads in real-time and then prioritizes them based on the risk they pose, noted Tack. The goal is to make it simpler for organizations to incorporate security reviews in application development processes in a way that doesn’t necessarily require developers to become security experts, he added.

    Instead, the core DevOps platforms should be capable of identifying issues that can be remediated before an application is ever deployed in a production environment, said Tack.

    Dynatrace earlier added an ability to automatically identify the software libraries and open source packages that present the greatest security risk. The security gates capability now extends the scope of that effort to include applications as they are constructed using custom code.

    In general, most organizations are looking for ways to embrace DevSecOps best practices. The challenge is achieving that goal without unduly slowing down the rate at which applications are developed. In fact, a recent survey commissioned by Dynatrace found, on average, organizations expect to increase the frequency of their software releases by 58% over the next two years. However, nearly a quarter (22%) of respondents admit they’re often under so much pressure to meet the demand for application deployments that they must sacrifice code quality, which broadly includes security issues.

    It’s not clear to what degree security reviews will automatically be included within a quality assurance process, but Tack said the goal should be to limit human involvement in the application deployment process as much as possible. The issue many development teams encounter today is that applications are being rejected by cybersecurity teams that are reviewing applications just before they are deployed, noted Tack. As a result, developers are racing to build applications faster only to see them rejected and returned to them at the last possible moment, he added.

    In the wake of a series of high-profile software supply chain breaches, the focus on DevSecOps has increased substantially within most organizations. It’s often not precisely clear who is responsible for application security, but as DevOps platforms continue to evolve, there may come a day when security issues are routinely addressed within every DevOps workflow.

    In the meantime, there needs to be a lot more focus on bridging the divide between DevOps and security teams. Given the chronic shortage of security professionals, there’s no doubt DevOps teams need to assume more responsibility for application security. The challenge and the opportunity is finding a way to achieve that goal with the least amount of friction possible.