Tag: devops

  • Building a Services and IoT Platform with DevOps, Part 2

    Building a Services and IoT Platform with DevOps, Part 2

    BCG’s latest IoT market research finds that predictive maintenance, automated inventory and self-optimizing production are some of the top use cases driving the need to build internet of things (IoT) platforms by 2020.

    As we think of building IoT solutions, it’s important to have a deep understanding of the business-level considerations and architectural design-level considerations before selecting the right IoT platform. This article talks about some of the important factors to consider in selecting an IoT platform.

    Considerations for Selecting the Right IoT Platform

    Following are some of the considerations in selecting a right IoT platform or IoT solution provider.

    Business Need and Requirements: Identify the business needs, estimate the ROI, identify what specific business and architectural use cases needs to be addressed.

    Examine the core differences in different IoT solution providers and analyze their evaluate out-of-the-box features against the defined business/technical limitations for the use cases you have identified before deciding to build custom or off-the shelf solution.

    Global Presence and Business Stability: Identify whether the existing IoT solution providers have a global footprint with datacenters across the geos, which will enable you to scale in that business region as your business grows.

    Device Management: Check if the platform and the hardware is supported by the IoT provider and supports remote monitoring of the devices and maintain over-the-air updates to the devices.

    Data Analytics: Look for options on how data will be stored, the data storage options to store large volumes of data, with segregation and storage of device and telemetry data, in addition to the extraction and reporting tools and dashboards.

    IoT Data Collection: Identify how data can be collected from the devices and how your devices can communicate to the respective platform (cloud or local). Each vendor has different means of collecting the data from the remote devices, For example, Azure IoT uses Azure IoT Hub while AWS uses Rules Engin, to connect and communicate to the devices and collect the data.

    Edge Computing: Identify the network latency, how to filter the data selectively from different devices and relay it to the cloud, the connectivity of devices that are not exposed to internet through a field gateway, the customization of the gateway and protocols and how to achieve quicker response times with different IoT platforms.

    IoT Protocols and Standards: Examine whether the device list supported by the vendor is developed as per the standards defined by IoT consortiums and whether the vendor supports standard protocols or uses any proprietary technologies.

    Compatibility and Extensibility: Examine for the compatibility of the devices to the vendor platforms, support for additional new devices to the platform and support for customization/extensibility of WRT gateway protocols and device rules.

    Storage: Identify platforms/IoT vendors that provide big data storage, data security, compliance and data recovery options.

    Security:  Think security at all levels from ground up—device-level security, device-to-cloud security, cloud security, data security and privacy, user-level security, application security and end-to-end security.

    Pricing and Hosting Models: Finally, compare hosting models and pricing models offered and any hidden costs. Pricing varies from per device to per million message-basis, per message volumes/day, cloud usage and other factors.

    IoT Architectural Considerations

    Hardware and Software Heterogeneity: The platform should support for various hardware and software devices from a wide range of device manufacturers, multiple devices, device operating systems and support multiple protocols including MQTT, web sockets and AMQP. It also should support device management and monitoring of connected/non-connected devices and seamlessly connect with multiple network providers.

    Enhance Security: The system should have security and privacy for device, users, device and user identity, authentication and authorization with policies, data protection (encryption/decryption) for data at rest and in motion, data attestation, SAS-based token per unique publisher, certificates, TLS authentication support and adhering security standards to enable developers to follow security standards during device development and security testing.

    Hot/Cold Data Path Analysis: Determine the network latency, support for high-scale data ingestion, support for high-scale data processing and high data retention options, support for segregating device metadata from telemetry data storage and the ability to perform analytics on the data with customizable dashboards.

    Scale Efficiently: The system should support for hyperscale deployments of individual data processing units such as event hubs, stream analytics and AWS Kinesis and also support millions of device and scale between small to hyperscaled dimensions of devices and telemetry.

    Flexibility: The platform should be extensible to use third-party solutions for individual conceptual components in IoT solutions and should support integration with business applications/workflows and REST APIs/CLIs for communicating to the systems from external systems.

    DevOps Automation: There should be support for the adoption of build, test and deployment automation for device and other solution components in an IoT solution with the right set of tools for DevOps. Testing and monitoring are key in DevOps automation with user-centric end-to-testing and automated releases of firmware updates to the remote devices. The platform you choose or building should be driven with DevOps capability.

    QoS, Cost: Other key factors to consider include maintaining data and devices, monitoring devices, scalability, reliability of systems, backup and disaster recovery of data and devices, performance of the devices, the network and pricing models (based on messages sent/received, per devices, cloud transactions, message size, throttling limitations of cloud based components, cost of ingress/egress/compute/storage/services/business apps/devices/security, etc.).

    Lower Barrier to Entry: The platform should support the ability to evaluate, prototype, deploy and scale quickly; lower the barriers to trying IoT out-of-the-box/preconfigured solutions; and support new development and experimentation with the data to refine and derive useful business metrics from telemetry.

    Building an IoT platform may be challenging, but making critical decisions on business factors and design considerations such as device management, security, storage, analytics and pricing before selecting a platform can help achieve ROI and lead to building a mature IoT platform.

    About the Author / Lavanya Subbarayalu

    Lavanya Subbarayalu is Senior Architect working with Technology Office in HCL Technologies. She has expertise in IOT, Azure, DevOps consulting & Microsoft technologies. She is associated with DevOps COE, working on design and Development of DevOps solutions and consulting tools. Connect with her on LinkedIn.
  • Testing’s Role in Delivering Digital Transformation

    Testing’s Role in Delivering Digital Transformation

    “We have a quality philosophy now…but it took the rise of the middle child to make it happen.”

    • Ann Lewis, ExxonMobil

    Ann Lewis’ metaphor of testers being the “middle child” between software development and IT operations was present throughout Accelerate 2017, Tricentis’ annual user conference. Nearly every head in the room nodded as Lewis described how testers, like middle children, tend to get less attention than their professional or familial siblings, but she insisted that there’s never been a better opportunity for testers to receive the respect they deserve. Digital transformation, no matter how you define it, requires new commitments to quality, and it’s up to testers to claim be the change agents in the transformations that CIOs are tasked with delivering.

    Tricentis CEO Sandeep Johri and other CxOs who spoke at Accelerate echoed this sentiment. Johri pointed out that speed continues to be a primary focus of maintaining or gaining competitive advantage, and manual testing processes that prevent agility or DevOps success at the enterprise level must be automated going forward.

    What was also made clear is that scaling investments in automation is not the single key to success. The pressure CIOs are under today, especially around digital transformation, requires new investments in a number of different areas, many of which are only just being realized. While CIOs may understand the necessity of quality, it’s up to testers to get the buy-in required for the continuous testing required to deliver it at scale.

    Testers with an oft-ignored middle child mindset may find the concept of being recognized as a “champion” by their CIO or CEO unlikely. But, Todd Pierce’s impassioned session on “What CxOs really think about testing” was designed to inspire testers to change the way testing was viewed too often in the past.

    As a current Rock Health and Dignity Health board member, and former Bill & Melinda Gates Foundation chief digital officer, Pierce shared his peers’ all-too-common beliefs that testing takes too long, costs too much and constrains developer productivity. And, while it may hurt to admit, with manual testing that should be automated and insufficient testing time that results in bugs making it to production, it’s not surprising that CIOs would feel this way.

    Pierce explained that testers who adopt innovative, scriptless “high-precision testing,” are able to shorten their test cycle, reduce defects that make it to production and eliminate costly rework for themselves and developers alike. When high-precision testing is performed continuously throughout the software development life cycle (SDLC), those beliefs that testing takes too long, costs too much and impedes innovation lose all validity. “Everyone in this room should be the drivers of agility in the enterprise,” remarked Pierce.

    Emmet Keeffe at Insight Venture Partners hosted a CIO roundtable later in the day where four CIOs detailed their personal experiences with taking enterprises through digital transformations. Each CIO admitted that in the past they had underestimated the the time being spent on testing, and one somewhat bravely stated that he’d always found testing somewhat “boring.” One might expect a room of testers to storm the stage with charges of heresy, but, given that many testers have suspected that management felt this way for years, I got the feeling that many were simply impressed that someone who felt that way had admitted it.

    But the panel, Pierce, Lewis and countless other speakers at Accelerate also made sure that the attendees of their sessions understood one thing: As more organizations undergo digital transformation—and no matter what stage of digital transformation they’re in—testing has never been in a better position to drive positive changes that will have monumental impacts on the business.

    Whether CIOs have been tasked with delivering greater agility, DevOps shifts, increased security, enhanced user experience, reliability and performance or legacy app modernization, testing may not be the first organization that CIOs turn to for help. But, as Keeffe explained, testing leaders who truly understand the incredible opportunity they have to make those CIOs heroes will make themselves heroes in the process.

    About the Author / Noel Wurst

    Noel Wurst leads influencer relations for Tricentis, and collects stories around cultural shifts and evolving technology’s impact on the software testing industry. By attending global conferences, interviewing passionate software professionals, and working closely with product, engineering and customer success teams, Noel looks for stories that matter and innovative ways to share them with audiences that lead to business growth. You can follow Noel on Twitter and LinkedIn.

  • The Need for Speed Demands New-Era APM

    The Need for Speed Demands New-Era APM

    Applications have become the primary conduit by which customers experience a brand, making the application experience critical to business success. As such, continuous delivery and highly available systems that deliver optimal end user experiences at lightning speed have become top priorities for organizations. Modern IT is all about speed, efficiency and customer experience. Simply put, companies that develop new applications and services the fastest will win.

    That’s where containers and microservices come in. Containerized microservice applications enable organizations of all sizes to approach the ultimate goal of continuous integration and continuous delivery. This accelerates everything within the application life cycle, from initial development to component updates and new functionality.

    To match the development speed that microservices and containers enable, Ops teams need tools that can also operate hyper-fast, providing an immediate understanding of the impact of changes made, real-time analysis of vast amounts of data across applications and technologies, visibility across a range of languages and infrastructures, and knowledge of how the application is performing for end users.

    In fact, we are at a critical inflection point in application performance management (APM), where a generational shift is needed to keep pace with the new hyper-dynamic application architectures consisting of microservices, containers and hybrid cloud environments. To fully understand the impact of this shift, we can examine the genealogy of APM.

    APM Evolution

    The first generation of APM, established at the end of the last century, collected statistics and metrics out of system and application components, providing a first generation of user-defined transaction profiling by using instrumentation technology. APM 1.0 required a lot of effort to implement and maintain, but helped to monitor and analyze the performance of newly developed 3-tier applications.

    The second generation of APM was driven by more distributed, service-oriented architectures (SOA) and the rise of more elastic, virtualized or cloud-based infrastructure. APM 2.0 added application topology discovery and could analyze distributed applications. User experience monitoring of web and mobile apps quickly became part of APM 2.0 as more businesses depended on the service quality of their applications. With a primary focus on application monitoring, not management, APM 2.0 required an even broader set of subject matter experts to configure and interpret monitoring data from dashboards and reports. Similar to APM 1.0, the second generation still required way too much human analysis and setup to fully understand application problems and derive actions.

    The continuous change in today’s modern dynamic applications makes it difficult, if not impossible, for those older tools to keep up. Throw in additional architectural challenges such as hybrid clouds, containers and orchestration (such as Kubernetes and Mesosphere) and the picture gets murkier, all in the name of high-speed delivery. Meanwhile, the microservice architecture and development strategy spawns wide technology diversity—each engineer can choose the programing language, middleware and databases best suited to code their individual microservice. Scale, complexity and constant change is the new reality for today’s dynamic applications.

    Wanted: A New Breed of APM

    In this environment, traditional IT monitoring tools won’t work. These new applications use a vastly larger set of technologies, must scale dynamically and are in a constant state of flux.

    In this effort to engineer for speed and efficiency, complexity and scalability have increased exponentially, requiring continuous monitoring and more visibility than ever before. As organizations embrace agile methodologies for development and containerized microservices for deployment, developers have shifted their thinking in technology choices. Developers now continually select the most optimal technology for their individual goals regardless of DevOps’s ability to configure, deploy and manage the specific technology.

    With several teams across the enterprise constantly publishing new software releases, understanding the impact of these new releases and changes to the overall environment has become a significant challenge. Today there is no single source of truth assisting communication between various organizations, resulting in what seems a wild west–like environment for IT. With so many groups and technologies in play, everybody seems to be speaking a different language, especially when it comes to delivering high-quality applications. In this environment, a new breed of APM  is needed that can provide a “Truth Machine”—complete with deep visibility across all application components in the technology stack.

    This new breed of APM must be automatic and dynamic to deal with the ever-changing world of applications running in containerized microservices. To deliver these critical capabilities, the tool must provide real-time visibility into dynamic, containerized, microservice applications, regardless of language or infrastructure. New thinking is required to meet the challenges of these complex, large and dynamic application environments; a new monitoring and management approach that can handle dynamism by:

    • Delivering real-time analysis of vast amounts of data across all applications and technologies.
    • Conducting continuous discovery and automatically mapping every component, host and container, (hosted on-prem, private cloud, public cloud), to the exact architecture of complete technology stack.
    • Visualizing the application architecture and delivering actionable suggestions that assure the operational health of systems and applications.
    • Providing real-time accuracy to visualize, structure and identify problems immediately.
    • Monitoring the complete set of diverse technologies that run in microservice environments.
    • Operating in a heterogeneous environment and automating deployment across nearly all programming languages.

    Artificial Intelligence for Next-Generation APM

    DevOps and IT organizations are struggling to match the speed of agile development, and this is creating exponentially more challenges around new application architectures. The only constant in these modern application environments is change. Whether change is due to microservice architectures, container orchestration or simply more agile delivery execution to effectively manage microservice applications, DevOps needs up-to-date visibility, a precise picture of the application’s structure and an immediate understanding of its health. To accomplish that, DevOps must be able to apply artificial intelligence to the act of monitoring modern dynamic applications.

    Rather than spending time configuring and reconfiguring monitoring tools, organizations must automate management steps with as little human setup and configuration as possible. To have complete control and visibility of their environments, regardless of language and infrastructure, organizations must use a modern application management solution that is automatic and AI-powered to deal with the ever-changing world of dynamic containerized microservice applications.

    About the Author / Pete Abrams

    Pete Abrams is a co-founder and the chief operating officer at Instana, the leader in application performance management for containerized microservices applications. Formerly vice president of customer centric innovation at AppDynamics, Pete has spent more than two decades in the technology industry focused on introducing new products to market and ensuring customer feedback and desired capabilities are incorporated into future product innovation. Connect with him on LinkedIn.


  • Event Management: Let the Noise Wail Without Going Deaf

    Event Management: Let the Noise Wail Without Going Deaf

    In part 1 of the blog series “Putting the Ops in DevOps,” by James Moore, we discussed the awareness and anticipation of operational management and the best practices that can improve the app at every stage of its life cycle. In this blog, I would like to cover one of the event management discipline maturity and share some best practices.

    If you are an operations professional on a team that’s beginning to embrace DevOps methodologies, you probably are facing some significant challenges.

    You know the business is applying pressure to get to continuous integrations/delivery, where release cycles can be measured by value delivered in days or even hours rather than weeks or months. Your Dev teams have embraced agile development, and are producing (what should be) production-ready code in short iterations. Your combined orgs are working toward implementing an integrated delivery toolchain that can build, test and deploy a new release version at the touch of a button. Your Dev teams are leveraging cloud technologies and architectural patterns that enhance their agility, auto-scaling microservice architectures of unprecedented scale and modularity. They are producing, as a matter of best practice, highly instrumented code that provides a dense trail of data relating to the state of the applications deployed on runtimes that constantly report their own state. You may be responsible for physical and virtual compute, network and storage infrastructure that itself is monitored with tools that spew a continuous stream of state information.

    In other words, you find yourself faced with continuous change (both automatic and human driven) and a barrage of potential noise. If you are a seasoned operations professional, bitter experience may have lead you to see change as the enemy—as change tends to zero, then so does operational risk. Now, you may to have to deal with continuous change as an inevitable force for advancing your company’s business goals. How will you separate the signal of service status from the noise of service state? Doing this successfully will be the difference between knowing quickly that there is a problem with an application or service before your users notice and being told about it by your users. It may also be the difference between getting a good night sleep and unnecessarily responding to a page indicating a benign application state.

    Enter event and incident management. The discipline of event management has matured, and has continued to mature, over decades as a mechanism for determining the status of elements of a managed environment from the state. Best practice in event management consists of:

    • Filtering out events that are not likely to be service affecting. A trace message from an app log is not worth your attention, unless you need to view it as a part of a diagnostic procedure. A synthetic user transaction timeout may require immediate investigation.
    • Correlating events that are likely to be related, so you get one notification per true incident rather than, say, 20.
    • Enriching events with context, so if a single service instance fails in a redundant array of five instances, route the event to the operations console but don’t wake anyone up unless the service is affected.
    • Implementing X-in-Y policies. In a large and complex system, a single microservice-to-microservice HTTP timeout may not be a huge problem. But you may want to investigate if you start getting 20 per second.
    • Implementing runbooks for common failures. Collaborate with development on the definition of those runbooks. Tie those runbooks to incidents as they occur so that the first responder has a process they can reinstate a service or prevent an outage in the first place.
    • If possible, automating those runbooks. If the problem is a failed process, then restart it. A disk is full? Free up some space.
    • Leveraging analytics and machine learning to gain insights from the reams of data your tool collects. Can you learn from event history to suggest correlations or areas for improvement to ops efficiency?

    With rapid delivery of new features and capabilities, the Dev team should already be mindful of the operability of the software they produce. Shift awareness of the event management tools and logic to the left. Have development use the same management tools that Ops use in production, but in pre-production. And then learn from what they see in pre-prod to improve. This should be done in combination with systems failure testing. Perform the test and see how the operations tools responds. Ask yourself, “Would I have been able to fix this if it had happened in production? Would I even have known what to do?”

    As is obvious by now, successfully operating an application or service in a modern business requires unprecedented co-operation between development and operations teams. Event management as a discipline and the tools that support that discipline are as critical now as they have ever been, if not more so.

    Listen to my recent podcast where I spoke about the common operational challenges many DevOps teams are facing today and how the traditional IT Operations best practices could be leveraged for use in a DevOps methodology.

    Also, download this white paper, which includes best practices for DevOps transformation and improving event or incident management.


    About the Author / Dr. Kristian J. Stewart

    Kristian Stewart is Architect – Hybrid Cloud Event Management and Analytics at IBM. He currently leads architecture for IBM’s Netcool Event Management offering, and is part of the team providing as-a-service capabilities to IBM’s clients with Cloud Event Management. He has worked in Systems and Service Management for 18 years. He lives in England with his wife and two daughters, two cats, and five Raspberry Pis.
  • The Future of Continuous Testing: Fail Faster

    The Future of Continuous Testing: Fail Faster

    In the early days of Agile and Lean development practices, a very noticeable gap appeared between dev teams and ops and QA. Development was accelerating at a lightning-fast pace, but testing processes could not keep up, slowing down the entire life cycle and preventing organizations from achieving continuous delivery. Traditional testing methods, which rely heavily on manual processes and frequently updated GUI tests, proved too cumbersome and inadequate for our new lifecycle timelines.

    The era of testing as an afterthought is dying out, and continuous testing has emerged as the new standard. The idea behind continuous testing is pretty straightforward: Implement a systematic approach towards improvement that incorporates not only automation, but also all of the other tools and processes that will help reduce risk before software progresses to release and production. Organizations embracing this are rethinking testing as a continuous process that starts from the sandbox, rather than a precursor to release.

    Continuous Testing: Achieving ‘Fail Faster’

    At xMatters, we strive to a testing strategy that supports our goal of committing to production multiple times per day—one that we’ve been diligently moving closer to, having progressed from releases every quarter to every month to every week to now, twice per week. Our approach is to conduct unit tests at the team level, code quality, sonar and static analysis, and then deploy to production at limited percentages that we bump up in stages. Our overarching mantra is “fail fast,” because the faster and sooner you fail, the faster and sooner you can fix what’s broken, and the less resources and time you will spend troubleshooting and resolving issues. This, of course, translates to real cost savings.

    Correlating failure to actual events is the biggest hindrance to the continuous testing dream, as pinpointing root causes is an incredibly time-consuming process. This is where automation will take us to the next level, if implemented in a smart way. The future of continuous testing will be adaptive so as to determine the causes of failures faster. We need to automate as much as possible the process of predicting where code quality issues are and identifying the precise data correlations that will enable us to fix issues rapidly.

    Part of this adaptive testing approach will include automating intelligent regression testing. We don’t need to run a black box test in every instance, for example, which can take hours every time. We’ll save incredible amounts of time, money and developer resources if we design tests that can detect new changes and only test those. Smarter regression testing will result in precious time saved that ultimately impacts—and can even make or break—the speed of innovation.

    Another critical consideration to smarter testing is making sure to account for a comprehensive understanding of risk. We need to incorporate real business considerations into our understanding of risk and bake those into our tests as well. We should hold our software to not only standards of code quality and integration success, but also to meet real business expectations for areas such as security, compliance and reliability. Testing from the bottom up must be done in tandem with top-down analysis to account for the full spectrum of potential risks that have the potential to impact the bottom line. Machine learning systems can also be extended to learn new business applications as new functionalities are added and assist in creating test cases that serve to enhance the quality of the application.

    Developing these intelligent automation tools remains our biggest barrier to achieving the continuous testing dream, and while many organizations are gunning for it, most are still mired by manual processes. A global study conducted earlier this year by CA Technologies, for instance, demonstrated that while 75 percent of organizations identify continuous testing as important, just 20 percent report a high quality of test automation coverage.

    It’s worth noting that not every aspect of testing can be successfully automated. The vast majority of functional tests will almost certainly not be manual processes—but what about user experience testing? We have yet to conceive of an approach to this that can truly be automated. Because nothing beats a real human’s assessment of experiential quality, this will be one of the areas of testing that will likely remain manual. Thus, while our goal is to automate 100 percent, realistically this won’t be the case.

    The end goal here is not only to achieve the dream of continuous delivery, but also to eliminate distractions as much as possible. The more repeatable processes you can automate, the fewer distractions your team will encounter, and the more they can focus on creativity, strategy and building new features and capabilities instead of fixing old ones. This is what will ultimately determine your ability to innovate, as you’ll no longer have to sacrifice either time, scope or quality.

    About the Author / Deepa Guna

    Deepa Guna is Senior QA Architect for xMatters. She has been working in technology since 2003. Connect with her on LinkedIn.

  • The 7C Holistic Approach to DevOps

    The 7C Holistic Approach to DevOps

    The DevOps methodology was first adopted in 2007 with a bigger purpose of improving organizational efficiency by bridging the gap between software release and IT operations teams. This started as the core practice of continuous integration (CI) and continuous delivery (CD) with a prime focus on better quality of releases and more frequent releases. Now, DevOps is becoming the norm of the industry and is being embraced by multiple organizations as a digital transformation with a shared goal, involving all stakeholders, to serve the customers better with higher quality product release and more frequent releases.

    DevOps has evolved beyond release and deploy and now involves product owners, project managers and all aspects of software development life cycle. This is the key reason it has evolved as a holistic approach starting from the service team interacting with the customers to product release and production monitoring. In this blog, we will explain how the 7C approach of DevOps is a natural evolution of DevOps and how it helps different organizations to perform better.

    DevOps now spans across the entire organization involving customer service, marketing, product owners, project managers, program managers, and different levels of developers, QA, release or build teams and infrastructure team. As the main focus of DevOps is to serve the customer better and faster, it is important that all the stakeholders have better end-to-end visibility of operations, planning, integration, testing, monitoring, delivery and feedback. This is the 7C approach of DevOps, as illustrated in Fig 1. This requires an efficient integration of processes and tools to automate the seamless information exchange and execution. This approach also empowers all the stakeholders to better contribute in product’s success and efficient execution.

    Fig. 1: 7Cs of DevOps

    The 7C holistic approach to DevOps also requires efficient collaboration between all stakeholders, empowering them to contribute more. The 7C approach removes all silos of information and execution.

    Startups were fast to adopt DevOps as many of them were setting up things from scratch. But the latest industry trends show large enterprises embracing DevOps primarily with the focus on efficiency and better, more frequent releases.

    The DevOps domain includes lots of tools and many of them are open source. This has provided a toolset for engineers to tinker with or experiment. This tends to have problem of its own, as too many toolsets in the flow create silos of information and execution, which creates confusion and inefficiency. This is becoming a problem and that’s why solutions are required which provide better integration and execution across multiple tools. The right solution for this will be a platform with deep integration capabilities.

    A deep integration platform for DevOps will enable seamless integration and execution across different tools, even home-grown proprietary tools, to provide a holistic solution starting from customer initiation to production deployment and feedback. This approach is significantly important for large enterprises, as this enables them to have the flexibility of preserving their existing investments on tools and processes while also allowing them to selectively introduce new tools. Rather than trying everything new, large enterprises can manage changes while primarily focusing on efficiency, automation, collaboration, better quality of releases and more frequent releases.

    This 7C approach gives same visibility to all stakeholders and everyone knows what feature is being released when. This approach also helps to move information/execution in both left and right direction with powerful traceability features, analytics and dashboards. Deep integration of information and execution also reduces dependency on other teams and promotes self-service.

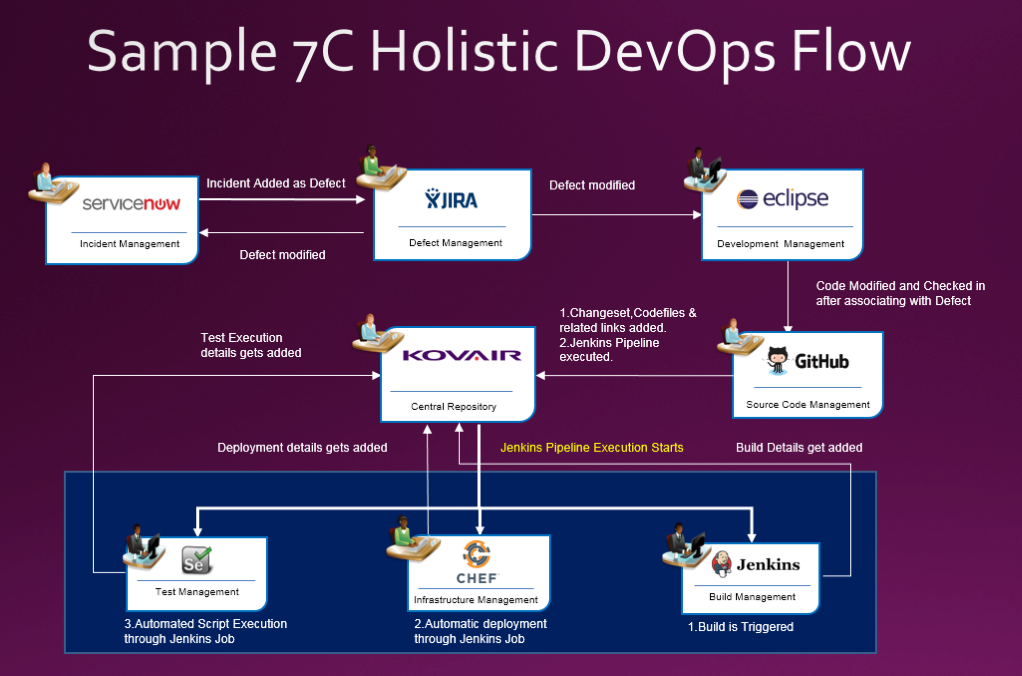
    Fig. 2 illustrates a sample DevOps flow where service team uses ServiceNow; software, product and project managers are using Jira for Agile management, developers are using Eclipse as their integrated development environment, GitHub is used for source code repository, QA team uses a test management tool for test and defect management, and finally the release team uses Chef and Jenkins to orchestrate build, release and deployment. In real-world examples, teams add more tools for code analysis, security and production monitoring. All such complex flows are supported within DevOps 7C holistic approach by utilizing the deep integration platform. The 7C approach is more productive as it allows faster detection, analysis and resolution of problems.

    Fig 2. Sample DevOps Flow with Deep Integration

    The 7C approach works well with both traditional waterfall software management as well as Agile software management—mainly because of better end-to-end visibility, efficiency and collaboration.

    To conclude, 7C approach of DevOps is the natural evolution of DevOps, empowering the team to achieve better efficiency and execute better. This empowers all the stakeholders in the organization by providing better end-to-end visibility and powerful means of collaboration. Involving all stakeholders also creates a better environment of trust and collaboration. With this 7C approach, DevOps is not limited to build and release but it has spanned across the entire spectrum of software development lifecycle. This is especially highly beneficial for large enterprises as it enables them to preserve their prior investments and enhance their existing flows. This gives them leverage to selectively try new tools and technology while preserving what is working well. This is a great approach to expedite the enterprise level digital transformation.

    About the Author / Devendra Joshi

    Devendra Joshi is Sr. Director, Customer Solutions and Products at Kovair. He is a software professional with over 20 years of experience in enterprise software, social media, healthcare, SaaS companies, and EDA. He has worked with startups and large enterprises in engineering management, and product and solutions management roles.

  • SMEs Can Benefit from DevOps, Too

    SMEs Can Benefit from DevOps, Too

    The DevOps approach has several clear-cut benefits with the value centered in several key business areas: improved market agility, increased quality and revised culture of cooperation and effectiveness in staff operations. By promoting and implementing a DevOps culture in your SME’s business, Dev and Ops teams align much closer together and can better share in-between knowledge. This lets you create products more fluidly and increase deployment rates. The time for evaluating the business idea, development, testing and moving the finished product into the operations department is reduced dramatically. Quality margins improve, and this feeds back into the ability of your teams to continually fine-tune the products you offer.

    Businesses see a point in adopting DevOps only if it is directly contributing to the company’s increased effectiveness, productivity and, of course, profitability. The only way that it is possible for small and medium enterprises (SMEs) is when their IT and DevOps teams are working in sync and streamlining the provision of tech solutions that solve the business needs. And only a successful and timely DevOps adoption inside your organization will help your company beat competitors and stay afloat as the development across the industry speeds up.

    In the last years, we’ve seen a tremendous application delivery shift in businesses. We’ve moved away from the old ways of having large-scale system implementations based on one single project and its continued maintenance. SMEs now perceive application delivery as a continuous evolution. DevOps plays a leading role, as this software engineering trend ensures that such a major shift is possible. It brings all of the different parts of the enterprise together: business, development and operations teams collaborate on a different, more in-depth level with a goal of automating processes. This helps eliminate the usual constraints and takes the time-to-market issues off the table.

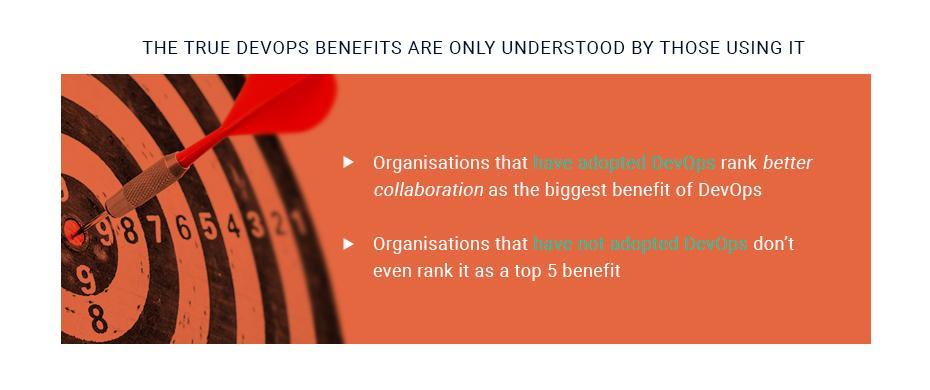
    In the latest ECS-Digital research on adopting DevOps in businesses, 57 percent of SMEs have partially implemented DevOps practices in their daily routine. The key benefit of DevOps for them is improved inter-departmental collaboration. But for the 43 percent that haven’t yet adopted DevOps, the collaboration issues are among the last priorities on the list.

    Step-by-Step Guide to a High-Level DevOps Life Cycle

    According to IBM Cloud Director, the end goal of a relevant DevOps practice is to cut the development time and improve enterprise’s efficiency. A growing business has to start from the “business needs” of the company and go down the road to make it come to life. The goal of adopting DevOps in your company is to push your business needs into production at a quicker pace more reliably. The goal in any DevOps practice is to cut the time and increase the efficiency of processes. You need to move from the “business need” to the “it’s live!” stage.

    Business Needs are a DevOps Priority

    But does your business have to get involved? Of course, your SME leadership focuses on the “business needs” of your company. But when we look at organizations that have implemented proper DevOps practices, the internal structure of the company shifts to focus on delivering great business results across the whole life cycle of your product/services offering.

    DevOps also ensures that employees have the ability to correct their work direction during the whole lifetime of a project. Things and goals tend to change, competitors may roll out some features that may make some of your project’s parts trivial, and all of this makes the need to adjust your project accordingly. This is easily done when your business need is close to both the Development and Operations teams that are able to steer and drive this alignment of goals.

    Have a look at the infographic below that clearly shows how a DevOps delivery cycle looks like:

    The Clash Inside Organizations

    Measuring the impact of DevOps on the things that matter to business is vital. Most SMEs are experimenting with DevOps, and there are some within the company who want to prevent DevOps adoption. The culture within enterprises is shifting too drastically and dramatically, although the effects are mostly positive.

    Such a shift is impacting all operations, with software development impacted the most. SMEs have it easier to change and adapt compared to larger businesses, and this lets them move the workplace culture a step ahead of their larger counterparts.

    If we look at business, operations and developer teams from a historical point of view, it was never a goal to establish inter-connection between them. The teams started cooperating only when it was absolutely necessary to get the other team’s input. SMEs are still faced with such a separation, as most responsibilities are set in stone for each team and the individual employee. All business units are used to working in their closed-in niche, and there is a lack of will to leave the comfort zone and act outside the predefined roles. Such actions in the past could have been viewed negatively.

    While most businesses that want to implement DevOps have employees who want the business to prosper, it can be difficult to force people to act outside their duties. However, to reach the end goals of any business—namely, ensuring fast and quality product delivery—and solve issues on the go, people must interconnect their duties and reach outside their business unit. With proper DevOps application, such collaboration can be smooth and result in the improvement of cross-functions.

    DevOps Represents Change in Internal Business Structures

    Many SMEs are faced with internal structural issues that limit the company’s prospects: Engineers are not willing to be on-call, the Ops team has a negative attitude toward those who write code and executives are slow to embrace automation. Organizations must overcome the culture war to be able to approach the agility and productivity gained by a DevOps model. The faster they can get there, the faster these organizations can take the competitive edge away from traditional enterprises.

    DevOps culture looks very different from organization to organization. However, regardless of the business implementing a DevOps approach, the potential benefits are the same. From faster deployments to increased efficiency and cultural changes toward experimentation and away from rigid planning, a DevOps culture has the ability to transform an organization completely. Wholeheartedly adopting a DevOps culture has real implications on how well a business is positioned to take on the market. With many industries facing uncertainty and a host of upstarts disrupting the status quo, shifting to a DevOps culture can be an important weapon in repositioning your business.

    Empathy is the Core of DevOps Adoption

    One of the foundational ideas behind DevOps is mutual empathy. Having empathy from operations toward developers and vice versa, as well as empathy in other business-related and non-technical company units, remains vital. It’s not about patting your colleague on a shoulder. We are talking about the moral mandate of a developer who just creates their part of the software and doesn’t care about how it can be deployed in production. The goal is to push employees to think outside of their small task, and to take into account the outcome of their work: Is the developed app secure? How hard is it to deploy it? Is it easy to keep it running? etc. If those questions are not accounted for, the developer’s colleagues on the Ops side will pay the price if something goes wrong past the release.

    By ensuring that the SME has empathy for each other at its core, businesses will deliver better products/services. And doing just that is what DevOps aims to bring to companies. Until this idea is ingrained, DevOps will face a cultural war of sorts.

    Your Most Valuable DevOps Resource

    By considering to adopt the DevOps approach to running your SME, you can better rethink the ways your organization operates—how it deploys its teams across the enterprise and how often it addresses structural problems that appear over time. Now you can lay out a new foundation for your SME based on the culture of cooperation and experimentation. With proper guidance in the application of DevOps culture, you can address the waste of time, human resources and money in your business.

    Becoming a DevOps organization is no easy task and taking up on such a challenge requires faith that changing the existing processes will bring its benefits. Reworking and optimizing organizations is the new norm, regardless of their size, industry, and goals. The faith in DevOps culture is driven by the firm and quantifiable statistics, but the intangible benefits to corporate culture are just as compelling. Many businesses are looking at implementing DevOps, and even more, SMEs are in the active process of its application. When your company is delivering quality ahead of time, there is a strong chance your competitors will be left behind as you are getting the bigger piece of the pie.

    Key Takeaways

    • To stay current, businesses need to adapt to an ever-changing environment, respond to competitors and stay on top of the innovation cycle, increasing customer value via responsiveness to change.
    • Increased service quality depends on both the availability of the service and being able to restore the service to an error-free state. Thanks to fast feedback loops and high release velocity, service breakdowns can be removed much more quickly than in the past.
    • DevOps are built on the sound principle of waste reduction such wait times and process overhead due to continuous improvement. This helps to improve agility and has a positive impact on costs.
    • Fostering continuous learning and improving culture through efficient principles is what DevOps is all about. In a fast-paced, unpredictable environment, non-stop improvement is paramount for sustaining your competitive advantage. It is also important for attracting exceptional talent and keeping employee satisfaction at a high level.

    About the Author / Stephan Pushkarev

    Stepan Pushkarev is the Head of DevOps Practice at Squadex.com and CTO at Hydrosphere.io. Co-founded and managed engineering teams for eCommerce, IoT and Ad-tech companies. He is responsible for the full products stack: math models, infrastructure & operations, enterprise applications as well as recruiting, establishing engineering culture and delivery processes. Stepan combines strong technical and managerial skills, and entrepreneurial spirit. Connect with him on LinkedIn.

  • Automation: Addressing Bot Security with BotChain

    Automation: Addressing Bot Security with BotChain

    Bot technology is all the rage these days, and with good reason. Bots help you shop and provide customer service. In fact, one bot keeps contacting me on Facebook, telling me how I can optimize my marketing spend. They’re everywhere and they’re getting smarter all the time. Any one bot can access the entire intelligence of the internet to answer your most arcane questions or give you insightful suggests tailored to the details based on your online profile.

    Still, the full potential of bot technology has yet to be realized. Right now, most bot interactions take place between a bot and a human. But, what would it be like if bots could bring their powers of recognition, recommendation and bargaining to bear interacting with other bots? Such a time is not that far away. The implications will be profound, particularly for those in DevOps.

    The Emergence of Bot-to-Bot Communication

    Machine-to-machine communication is nothing new. Unassisted stock trading has been going on for years. A machine monitors stock exchanges throughout the world looking to buy or sell stock according to its programmed logic. Once an opportunity is identified, a trade takes place without any human intervention. While it is true that each machine is acting with some degree of autonomy, the scope of interaction is limited. A machine designed to buy and sell stock is not going to go awry and buy a car. Also, the details of the interaction are well-known. When a trade takes place, the details of the transaction are recorded and an audit trail is created on both ends of the transaction. However, when it comes to bot technology, things start to look different.

    Bots can act autonomously. For example, imagine a bot that is on a mission to find the best price for red sneakers in size 9. Instead of using a predefined list of sneaker vendors, the bot can use an internet search service such as Google to find online merchants that sell sneakers. The bot will use the result of the search to continue forward, looking for the best sneaker price. (See Figure 1.)  As you can see, there is a good deal of machine autonomy in play already.

    Figure 1: Bots use the internet and can act autonomously

    Once the best price for red sneakers in size 9 is identified, typically, the bot will defer back to a human to make a purchase decision. However, deferring to a human is not mandatory. As we saw with the stock trading scenario, a machine-to-machine purchase transaction is entirely possible. Thus, given the proper programming, there is nothing to prevent a “buyer bot” from interacting with a “seller bot.” Furthermore, it also is entirely possible for the “buyer bot” to interact with a variety of “bank bots” to determine the best credit card to use to make the sneaker purchase. Who knows? Credit card “A” might be offering better air miles than Credit card “B” on that purchase date.

    The important thing to understand is that, in the past, machine-to-machine interaction was pretty much a two-party interaction that is well-known. Today, modern bot technology makes it possible for a bot to engage in any number of transactions with any number of other bots with a high degree of autonomy. Along with such autonomy comes a good deal of risk: Any one of those bots could be an impersonator or could be using fraudulent information.

    The Perils of Bot Impersonation

    Any transaction is subject to fraud—a person writes a check without the backing funds, another makes a purchase using a stolen credit card, somebody else submits an invoice to a company by impersonating a vendor. These types of misdeeds happen all the time within the scope of human activity. So, too, will such crimes happen with bots. Just as a cybercriminal can impersonate a bank website to lure unsuspecting customers into giving away money and sensitive information, bots will be able to fool other bots into fraudulent transactions.

    As bots become increasingly autonomous, the degree of harm that one bot can perpetrate upon another will grow, too. So, what’s to be done?

    Ensuring Bot-to-Bot Interaction Using Blockchain

    If you want to know that bots are playing by the rules, you have to be able to observe their behavior. For those in DevOps, the usual way to observe the behavior of the systems within an enterprise is by analyzing logs.

    Logging is a way of life in DevOps. We put logging statements into the software we write to report the details of the commands executed; we put entry dates in the records we write to our databases; we log the requests being made to websites, and administrators use logs to provide the audit trail necessary to determine the integrity of the transaction being made in systems and between systems. Coupling logging with comprehensive system security and data encryption practices makes it so that IT operations knows who is in the systems and what those entities are doing.

    However, given the autonomy that bots can have and the wide scope of interactions that they can engage in, the usual mechanisms used to determine transactional integrity degrade. Going back to our red sneaker example described above, imagine the “buyer bot” contacts an unknown number of “seller bots” to negotiate the best price for a sneaker. Part of the negotiation process is in a bidding war among all the “seller bots.” Then imagine that once the sneakers have been identified, the “buyer bot” negotiates with two “bank bots” to determine the best credit card to use. That’s a lot of transactional activity, all of which is dynamic and most of which is unknown. How do we know that each of those “seller bots” is authentic? What do we know about the details of the negotiations done by all the bots in the bidding war for the sneakers? How do we know that the credit card used to make the purchase is not stolen? The fact is, without a common source of truth that describes all the transactions in the sneaker scenario, we don’t.

    While it is true that each bot might keep records of its part in a given conversation or transaction, there is no common ledger that records all interactions made by all the bots in the given scenario. Without a common ledger by which to audit the activity, the security, integrity and quality of bot behavior is compromised.

    This is not a new problem. Those who work with cryptocurrencies have had this problem for a long time—making sure that the information provided in a transaction is authentic, true and auditable. The way that cryptocurrency systems solve this problem is to use blockchain technology. Given that cryptocurrencies and bots share many of the same security issues, blockchain technology can be applied to bots. In fact, there is an emerging technology that applies the principles of the blockchain to bots. It’s called botchain.

    Botchain makes it so that all activities conducted among bots are reported in a common, secure ledger. The botchain ledger is a distributed resource on the internet. Botchain provides the mechanisms and audit trail required to ensure that bot-based transactions on the internet are conducted by authentic bots, acting within the scope of their rights.

    Botchain technology is projected to be an important part of the modern internet, particularly as IoT technology grows. As bots become more a part of general DevOps landscape—particularly in the e-commerce-enabled IoT space (think: refrigerators that can buy their own inventory)—systems and engineering staff will need to become more adept at using botchain technology to protect the enterprise.

    Bots will bring added benefit to the enterprise, no doubt, but they will also create new types of threat vectors. Agent impersonation is but one one of many security risks that are sure to emerge. The wise DevOps organization will do well to prepare. At the least, having a working knowledge of botchain will be a good insurance policy to battle the threats on the horizon. As those of us in IT have learned, the best insurance you can buy is the insurance you never use.

    Mastering the details of botchain technology is an excellent way for DevOps to address the security issues that will arise with the increased use of bots in the modern internet. There is little downside in preparing for a future that is sure to come.

    — Bob Reselman

  • Continuous Testing: Crushing the Testing Bottleneck

    Continuous Testing: Crushing the Testing Bottleneck

    The practice of continuous delivery has been with us for many years, but it has started to see real adoption in the last couple of years. Continuous delivery is about automating and simplifying the process of delivering new features to the market at any given time, accelerating delivery and helping bring Dev and Ops together to make them jointly accountable for the release process.

    As continuous delivery is helping to break down barriers, culture and bottlenecks in the delivery pipeline, a new practice has evolved to help teams solve this most daunting challenge of the delivery pipeline: Quality.

    The practice is called continuous testing, which can be defined as:

    • Testing your change in an efficient way (so your tests are completing faster),
    • In an optimized way (so that you find issues as early as possible in the cycle),
    • Based on risk and priority (so you test what is important to your users and the business).

    Some may think of this as equivalent to test automation, but that premise would be wrong.

    Automated testing tools can execute tests repeatedly, provide reports on testing outcomes and show comparisons with previous test runs. This is a critical foundation for a continuous testing practice, but just a starting point.

    In a continuous testing practice, testing is not done just in the “testing” phase and not only by test teams. Testing is performed at the level of the build (for example, Unit Test and Security Test) and does not stop after the change has been deployed into the production, where testing can ensure great customer experiences. Here are some other key aspects of continuous testing.

    Continuous Testing Automates Test Environments

    Let me clarify what I mean by environment. Basically, you want to replicate the real-world situation much as possible for testing. A test environment contains the test cases to be run, the right test data and services available, and the right application version deployed in the right environment. The juxtaposition of these elements of an environment must come together automatically to ensure a continuous testing practice.

    Continuous Testing Amps Up Throughput

    A key premise of continuous testing is that you are continually maximizing efficiency. This is a must to keep up with the velocity and frequency of today’s modern software factory.

    You are doing testing earlier in the testing cycle (shift left) where problems are easier to fix and less expensive. You are doing more testing in parallel. You are automating the promotion and feedback during testing stages. And you are ideally able to prioritize the testing order based on the risk profile of the code so that you are testing higher risk areas first. All of this enables you to find issues quickly and roll forward if possible or roll back seamlessly.

    Continuous Testing Applies Intelligence

    Finally, continuous testing means you have the knowledge at your fingertips about the risk profile of a release so you can make more informed decisions. You should be able to see what was changed in the code and the implications. For example, was there a small change in the UI or a complex backend change that affected integrations and could break the APIs for the interface?

    You also need a detailed view of the quality level of the release, including which tests have failed, which tests have not been executed, whether you have tested the new or the risky areas. All this intelligence will help you to understand the quality profile of a release and make faster decisions about whether additional tests are needed or if a release is ready to go to production.

    Steps Toward Continuous Testing

    There is no perfectly prescribed way to put a continuous testing practice in place for your organization. For example, you may find that your biggest bottleneck of the moment is managing test data, so you should tackle that first. But here are five steps critical in your adoption of continuous testing:

    Step 1: Implement best-of-breed test automation tools—Functional, GUI, Performance, Security, etc.

    Step 2: Automate test environments with the right test data and virtual services to ensure real-world, always available testing.

    Step 3: Automate test requirements (you’ll find manual methods can no longer keep up).

    Step 4: Automate the automation—Connect your testing toolchain and stages. Automate promotion from one stage to the next. Automate feedback loops end to end.

    Step 5: Get smarter—Automatically align the right tests to the right app version. Automate testing sequence by risk profile of the code. Build release health profiles.

    About the Author / Uri Scheiner

    Uri Scheiner is a senior director of product management in the Continuous Delivery Business Unit of CA Technologies. He was previously a key architect and responsible for the product road map and vision at a leading release automation company Nolio, which was acquired by CA in 2012. Uri started his career as a software engineer at Mercury Interactive (acquired by HP in 2006) where he was responsible for developing several products for the DevOps and APM markets.
  • CA Technologies Positions Automic at the DevOps Core

    CA Technologies Positions Automic at the DevOps Core

    After acquiring Automic earlier this year, CA Technologies suddenly found itself with an embarrassment of IT automation riches. Now the company is moving forward by further integrating the Automic IT automation platform with the rest of the portfolio of tools and services that it says are required to construct a software factory.

    Ron Gidron, technology evangelist for Automic, says the latest version of Automic increases the number of integrations with the rest of the CA Technologies portfolio to include support for CA Test Data Management, Service Virtualization, Privileged Access Governance, Application Performance Management and Veracode application security software, among others.

    CA Technologies has made it clear it intends to make the release automation software originally developed by Automic the foundation of its overall DevOps strategy. Most of that effort is now focused on integrating the various elements of the CA Technologies portfolio. Longer term, CA Technologies will eventually move to rationalize any duplication in functionality.

    Version 12.1 of Automic also brings forward orchestration tools and self-service capabilities to enable developers to provision resources within guidelines defined by IT. Gidron says that while there will always be a need for IT operations specialists, CA Technologies is making a concerted effort to “shift left” to provide developers with more programmatic control over the IT environment. To facilitate that process, Automic and the rest of CA Technologies have been investing in creating a standard set of external-facing REST APIs, which also will be used to make it easier for products and services created by the company to consume a wide variety of external data and metrics.

    Via acquisitions and internally developed software, CA Technologies is clearly trying to unify application, infrastructure and security management with the context of a single DevOps framework. The company doesn’t plan to force organization to consume that entire stack of software. But it will try to make acquiring as much of its portfolio as financially attractive and frictionless as possible to drive what the company describes as intelligent automation across a modern software factory. Driving that need is the realization that just about every company in every industry is now dependent on some form of custom software to drive one digital process or another.

    The rate at which CA Technologies has been expanding its DevOps portfolio via acquisition is a major contributor to what appears to be a wave of consolidation starting to occur across the DevOps category. Regardless of how advanced any organization might become in terms of building a software factory, major IT vendors realize that it’s only a matter of time before IT organizations start to pressure them to bundle more DevOps-related functionality together. In fact, the line between what’s DevOps today and tomorrow versus what was considered traditional IT management appears to be getting more blurred with each passing day.

    — Mike Vizard