Tag: developers

  • Is DevOps Ready for a ‘Steam’ Moment?

    Is DevOps Ready for a ‘Steam’ Moment?

    It’s hard to believe we live in a world where a game such as “Goat Simulator” can manage to find an audience in an industry brimming with AAA titles including “Destiny 2,” “Overwatch” and “Call of Duty,” but we do. “Goat Simulator” was a massive success, but none of that would been possible in a pre-Steam world.

    Before Valve launched Steam Greenlight, and subsequently Steam Direct, the indie game community was a shell of what it is today. The path to market for independent game developers was very limited up until that point, allowing the likes of Electronic Arts, Square Enix and Nintendo to dictate the future of the industry as a whole. While only apparent in hindsight, the state of the market wasn’t only impacting game developers, it was limiting the choices of the gamers themselves.

    The state of cloud services today is almost identical to what we saw among indie game developers prior to the launch of Steam Greenlight. Amazon, Microsoft and Google have established a cloud monopoly, but they don’t have a monopoly on innovation. This has forced developers to play by the monoclouds’ rules and live within their walled gardens, sacrificing quality and performance for cost and convenience.


    Related Content:

    Operations Management Puts the ‘Ops’ in DevOps

    Resource Availability: The Missing Piece of the Cloud DevOps Puzzle


    This ultimately undermines the prime directive of DevOps, by limiting an organization’s ability to map software investments and architecturing to its business objectives. The phrase “one size fits all” has no place in the world of DevOps, but if Amazon and the other cloud titans have their way, Dev and Ops teams will have no choice but to do their best with an increasingly ubiquitous set of solutions.

    Sure, there are breakout success stories among developer service startups including Twilio, MongoDB, New Relic and SendGrid, but for every developer service that manages to get off the ground, there are at least 10 that die on the vine. Why should the future of the cloud, which is arguably the biggest technological advancement since the internet, be shaped by companies known for retail, search and hardware? It shouldn’t.

    Developers need their own Steam moment, and it wouldn’t just benefit DevOps teams, it would benefit businesses and make the market more competitive overall. The developer equivalent of “Goat Simulator” is out there, waiting to go viral, except instead of letting you control a four-hooved wrecking ball, it lets you hunt down expensive N+1 queries or configure RabbitMQ clusters.

    Get Ready for the Steam Moment

    So what does developer’s Steam moment look like? It all starts with discovery.

    Developer startups will never be able to compete with the economy of scale that a company such as Amazon possesses. The resources behind AWS allow the company to pump out comparable solutions to emerging developer favorites before they have a chance to reach a mainstream audience, which results in the death of far too many promising startups. Even with superior technology, they simply can’t keep up with Amazon’s spend on sales and marketing, which allow them to manufacture user bases overnight. If we applied this state of affairs to gaming, and Steam hadn’t existed in 2014, games such as “Goat Simulator,” “PLAYERUNKNOWN’S BATTLEGROUNDS” or “Stardew Valley” would have easily been co-opted by a major game studio right when they were on the verge of taking off.

    To correct course, cloud service startups need a platform for connecting them with their audience, whether they offer a solution that will be useful to 100 or 100,000 developers around the world. However, to make this possible, developers and operations teams need to gain a voice during the procurement process before their executives make their way to AWS re:Invent to be wooed by flashy sales pitches and $50 steaks.

    But, that is only step one. DevOps teams need to do their research and point management toward solutions that reside outside of the monocloud hierarchy. Even if the developer equivalent of Steam exists, that doesn’t guarantee non-technical executives will find it, which is why developers not only must vocalize the solutions they need, but also where to find them. Contrary to popular belief, even if you build it, they don’t always come, and if the developer community remains quiet, we can forget about having our own Steam moment.

    I’m glad we don’t live in the timeline where a goat simulation can turn into a viable business, and hopeful our cloud future won’t be dictated by the likes of Amazon and Microsoft. Our Steam moment hasn’t happened yet, but if developer and operations teams join forces to demand a better alternative to the one-size-fits-all approach, it could be just around the corner.

    — Peter Cho

  • HashiCorp Adds Terraform Workflow Tools for IT Ops

    HashiCorp Adds Terraform Workflow Tools for IT Ops

    HashiCorp this week moved to templatize automating IT operations by making it easier to share Terraform configuration files which make it simpler to programmatically invoke infrastructure that exposes application programming interfaces (APIs) without knowing how to code.

    Available in an on-premises edition or as a software-as-a-service (SaaS) application, HashiCorp Terraform Enterprise is intended for use by IT operations teams. A HashiCorp Terraform Enterprise Module Registry function has been added to enable IT operations teams to implement a publish-and-subscribe mechanism for Terraform configuration files.

    Company CTO Armon Dadgar said HashiCorp Terraform Enterprise is designed to enable IT operations teams to respond faster to requests from developers for infrastructure resources without requiring them to develop programming skills. It’s unlikely developers working for traditional enterprise IT organizations will be taking over control of IT infrastructure anytime soon, he said, and Hashicorp Terraform Enterprise allows IT organizations to inject a level of agility into their workflow processes without requiring IT operations teams to completely re-engineer existing processes.

    The HashiCorp Terraform Enterprise Module Registry extends that capability further by making it easier for IT operations professionals who have developed expertise employing declarative Terraform configuration files to share those files with other members of the team, Dadgar said.


    Related Content:

    HashiCorp Terraform Enterprise Empowers IT Administrators

    Operations Management Puts the ‘Ops’ in DevOps


    At the same time, IT operations teams that want to build workflow applications on HashiCorp Terraform Enterprise can use a set of application programming interfaces (APIs) that HashiCorp has exposed. In addition, the company has revamped the user interface for Terraform—workspaces now can be created by combining Terraform files into modular components that can be assigned to specific IT teams. Permissions to access are provided via support for the secure access markup language (SAML) as well as the Sentinel policy management software developed by HashiCorp.

    The HashiCorp approach to automating IT operations strikes at the core of the DevOps debate in the enterprise. While web-scale companies typically can afford to hire IT professionals with programming skills to manage IT infrastructure, the average enterprise IT organization still relies on administrators to manage servers, storage and networking. Not only are IT administrators in short supply, most of them would not be in IT operations if they knew how to program—they’d be writing and testing applications instead.

    Rival approaches to automating the management of IT infrastructure, despite being around for years, have yet to gain mainstream acceptance, mainly because they require programming skills. Declarative approaches allow IT infrastructure to be managed as code still, with less resistance from IT operations teams that tend to be more comfortable employing declarative tools. In fact, there’s long been a chicken-and-egg debate over the degree to which the transition to modern DevOps practices requires organizations to acquire new tools first or vice versa. The HashiCorp approach strikes a middle ground by providing tools that enable IT operations teams to first become more efficient, which ultimately should enable them to implement new processes that often is much less disruptive to the existing IT culture.

    — Mike Vizard

  • We’re All Load Testers Now (Maybe)­

    We’re All Load Testers Now (Maybe)­

    More than 94 percent of organizations already have Agile or DevOps initiatives or plan to adopt them within the immediate future, according to a survey by VersionOne. As part of the process transformation required to adopt these more iterative and rapid methods of delivering software, organizations are reassessing all practices associated with software development and test, including load testing.

    Traditionally, load testing has been deferred until the late phases of waterfall release cycles. Specialized performance testers applied legacy load testing tools to validate application performance prior to release. Why is this no longer sufficient?

    1. With teams moving to more componentized applications (including cloud-native apps, microservices, etc.), an application involves many highly distributed components—and a performance issue in any of them could have a ripple effect across the entire application.
    2. Now that new functionality is being released weekly, daily or hourly, each team needs instant insight into whether their incremental changes negatively impact performance.
    3. The later you start load testing, the more difficult, time-consuming and costly it is to expose, debug and resolve performance problems.

    In-depth load testing by performance-testing specialists remains critical, but it doesn’t provide the level of fast, on-demand load testing that’s critical for Agile and DevOps. Developers and testers need a way to expose critical performance issues before new functionality progresses through the delivery pipeline. To achieve this, DevTest team members must be able to easily:

    1. Create load tests that provide fast feedback on the functionality they’re evolving; and
    2. Execute and scale those load tests as needed—without the exorbitant costs and efforts traditionally required to establish, configure and maintain a performance test lab.

    Traditional Load Testing Isn’t for Everyone

    However, load testing has long been the domain of performance testing specialists for a reason: it’s difficult. Today’s developers and testers don’t have the time (or desire) to wrestle with all the technical details required to get load tests working correctly and to keep brittle load tests in sync with the rapidly evolving application.

    The traditional way of approaching load test scripting is at the protocol level (e.g., HTTP). This includes load testing with open source tools such as JMeter and Gatling, as well as legacy tools including LoadRunner. Although simulating load at the protocol level has the advantage of being able to generate large concurrent load from a single resource, that power comes at a cost. The learning curve is steep and the complexity is easily underestimated.

    The main culprit for this complexity is JavaScript. In 2011, there was usually less than 100 KB of JavaScript per page, which spurred around 50 or fewer HTTP requests. Now, that’s doubled: We see on average  200 KB of JavaScript per page, and this gives us more than 100 requests per page.

    Just running a search on a simple search page involves things such as XML HTTP requests processed asynchronously after page load. You also find things such as dynamic parsing and execution of JavaScript, the browser cache being seeded with static assets and calls to content delivery networks.
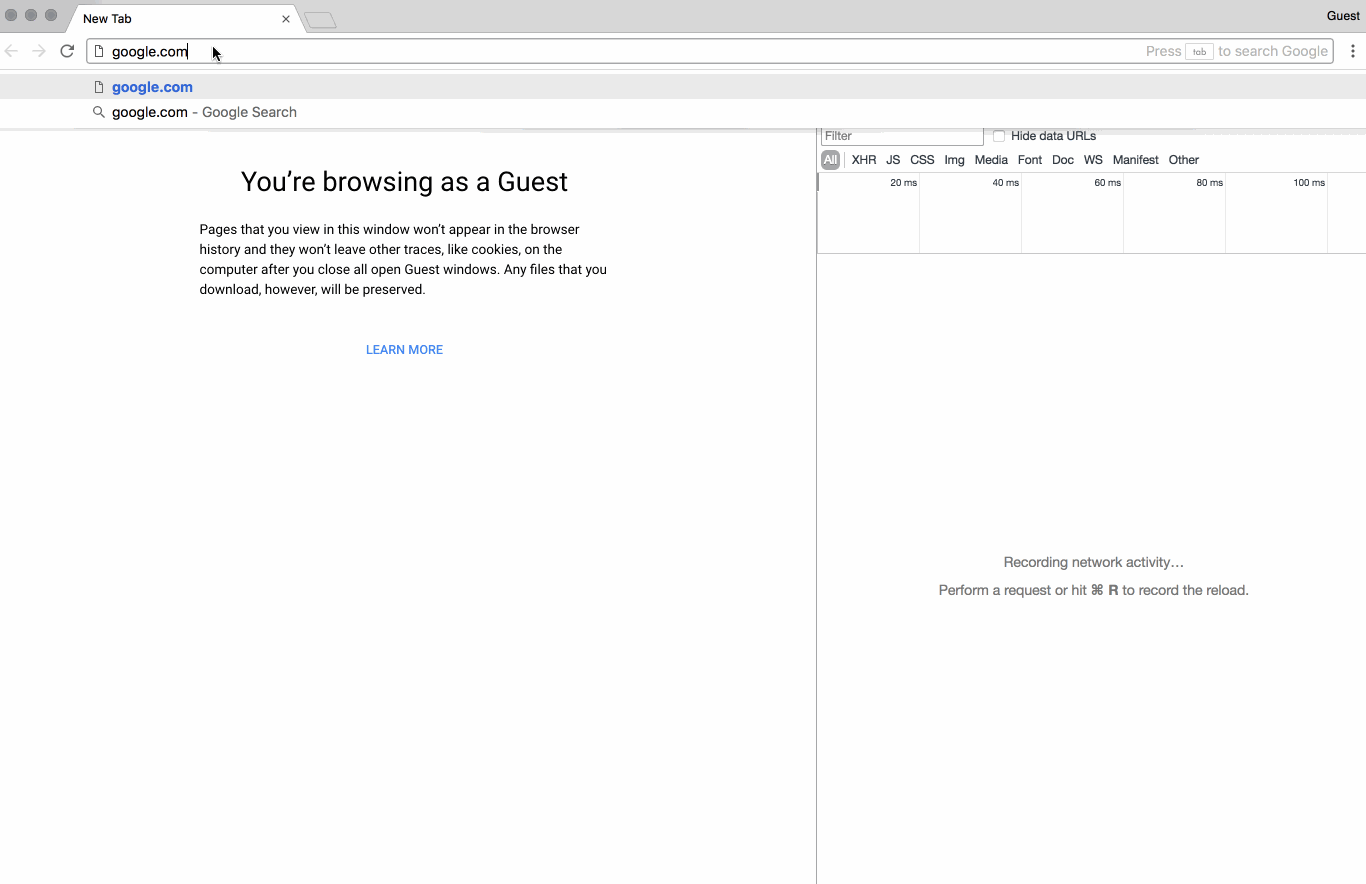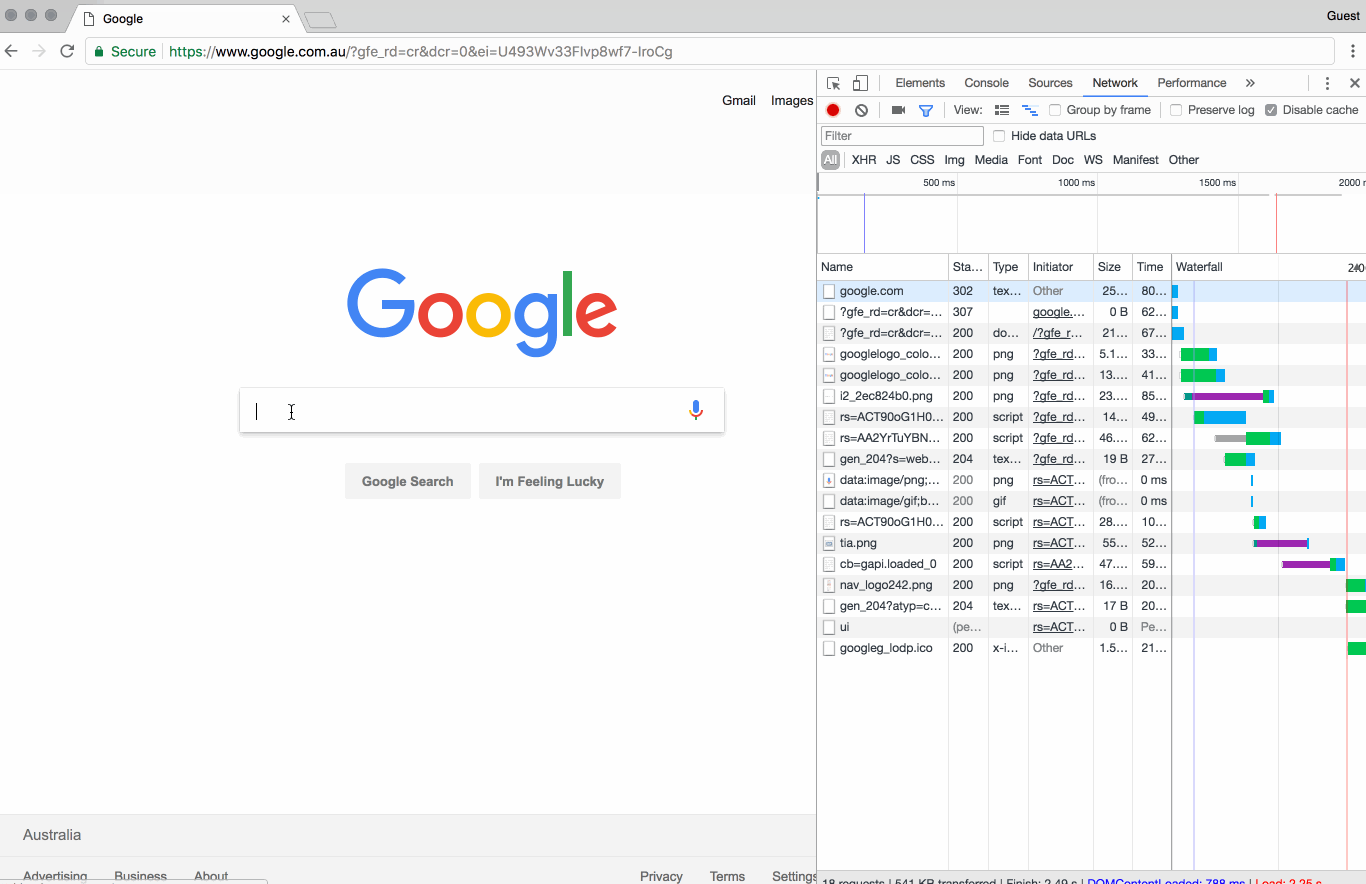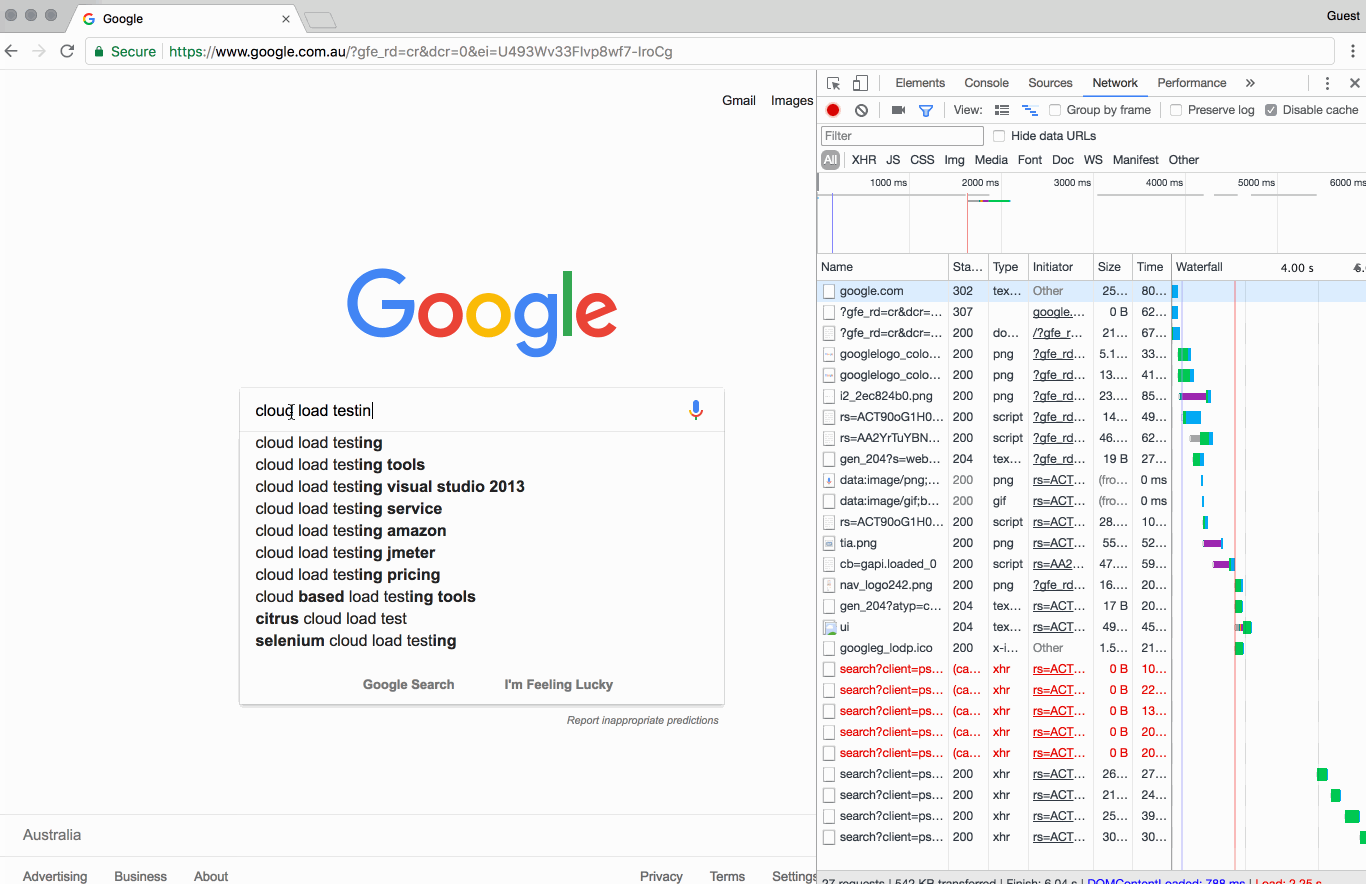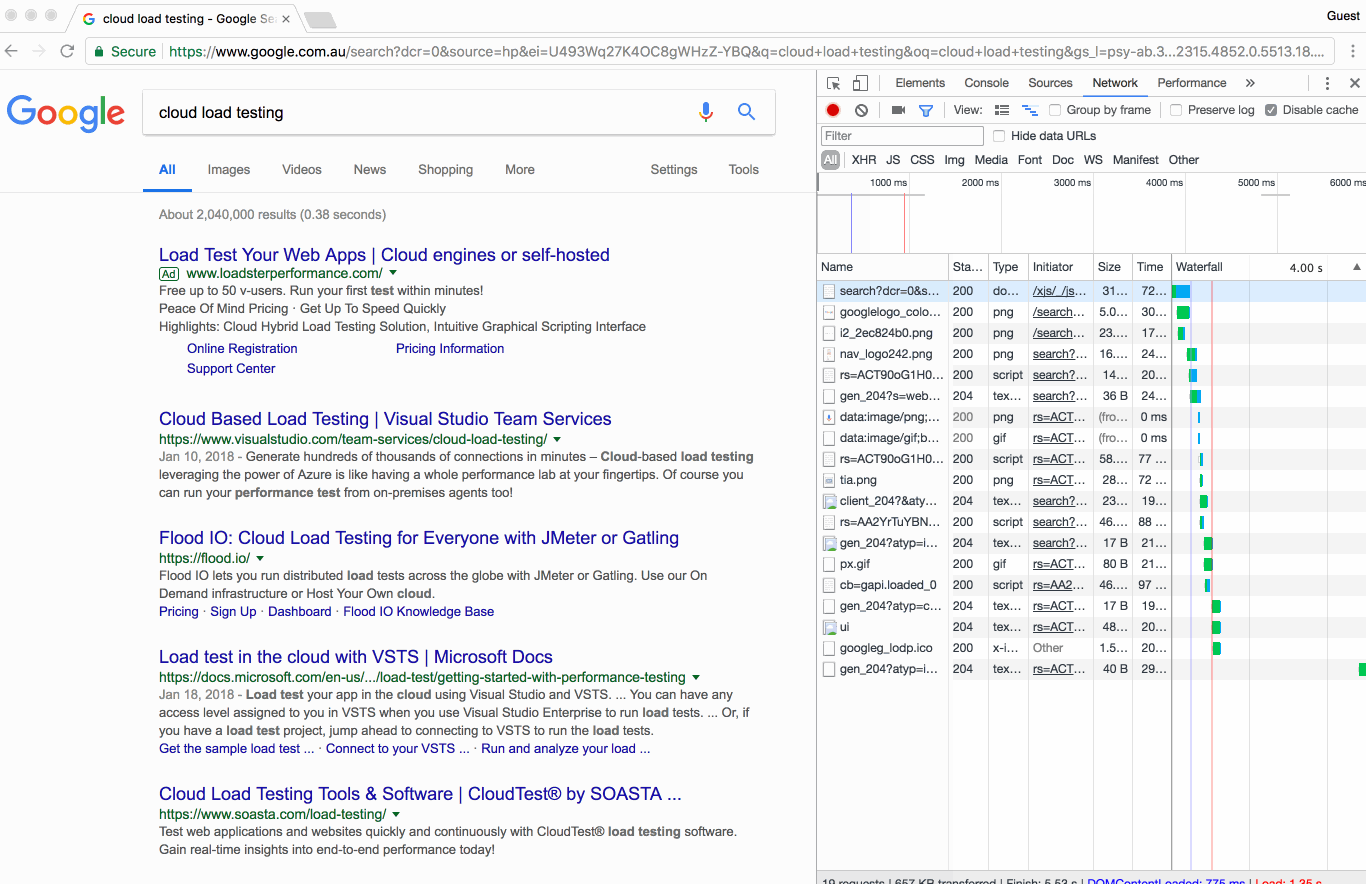
    For a more business-focused example, consider the SAP Fiori demo app. Assume we want to load test two simple actions: navigating to a page and then clicking on the “My Inbox” icon. This actually generates more than 120 HTTP requests at the protocol level.

    When you start building your load test simulation model, this will quickly translate into thousands of protocol-level requests that you need to faithfully record and then manipulate into a working script. You must review the request and response data, perform some cleanup and extract relevant information to realistically simulate user interactions at a business level. You can’t just think like a user; you also must think like the browser.

    You need to consider all the other functions that the browser is automatically handling for you, and figure out how you’re going to compensate for that in your load test script. Session handling, cookie header management, authentication, caching, dynamic script parsing and execution, taking information from a response and using it in future requests … all of this needs to be handled by your workload model and script if you want to successfully generate realistic load. Basically, you become responsible for doing whatever is needed to fill the gap between the technical and business level. This requires both time and technical specialization.

    You might be thinking, “Okay, we’ll use ‘record and playback’ tools, then.” Theoretically, you could just place a proxy between your browser and the server, record all the traffic going through and be set. Unfortunately, it’s not quite that simple. Even though you’re interacting at the UI level, the testing is still based on the protocol level. Assume we were looking at the traffic associated with one user performing the simple “click the inbox” action described above. When we record the same action for the same user two different times, there are tens if not hundreds of differences  in the request payload that we’d need to account for.

    Of course, you can resolve those differences with some effort. Unfortunately, when the application changes again, you’re back to square one. The more frequently your application changes, the more painful and frustrating this becomes.

    Taking a Browser-Based Approach

    To sum up the challenge here: modern web applications are increasingly difficult to simulate at the protocol level. This raises the question: Why not shift from the protocol level to the browser level—especially if the user’s experience via the browser is what you ultimately want to measure and improve?

    When you’re working at the browser level, one business action translates to maybe two automation commands in a browser as compared to tens, if not hundreds, of requests at the protocol level. Browser-level functions such as cache, cookie and authentication/session management work without intervention. There are a number of ways to simulate traffic at the browser-level: Selenium is clearly the most popular, but there are a number of cross-browser tools available—some of which let you test without getting into scripting.

    However, historically, it just wasn’t feasible to run these tools at the scale needed for load testing. In 2011, if you wanted to launch 50,000 browsers with Selenium, you would have needed something on the order of 25,000 servers to provide the infrastructure. Moreover, it would have been prohibitively expensive and time-consuming to provision the necessary infrastructure.

    Today, with the prominent availability of cloud-based technology, the concept of browser-based load testing is feasible. At the same time, projects Google Chrome and other projects are offering fast automation and better memory profiles with headless or UI-less variants of the browser. In fact, tests with headless Chrome show that it’s possible to go far beyond the industry standard benchmark of two to five browsers per machine and achieve around 50 browsers per machine.

    Suddenly, generating a load of 50,0000 browsers is a lot more achievable—especially when the cloud can now give you access to thousands of load generators that can be launched from any web browser and can be up and running in minutes. Instead of having to wait for expensive performance test labs to get approved and set up, you can get going instantly at an infrastructure cost of just cents per hour. Fast feedback on performance is no longer just a pipe dream.

    At Flood IO, we’ve captured our browser-level user (BLU) research and development in Flood Chrome: a browser-based load generation approach that builds upon APIs from Google for headless Chrome automation. This approach reduces the complexity of writing and maintaining tests while maintaining a viable level of concurrency and performance per machine. It creates scripts at a higher level of abstraction—the user level—then distributes those tests via the cloud for better economies of scale.

    Why consider this new approach to load testing?

    1. Simple scripting—or no scripting at all
    2. Reduced test complexity
    3. Test entire stack in one shot from the user perspective
    4. Capable of testing any user behavior
    5. Record network and user interaction times for front-end optimization
    6. Easier to test earlier and often
    7. Easier to maintain
    8. 10X faster than other Selenium load testing

    Or, in just one line: because it’s purpose-built for DevOps.

    There’s Still a Time and a Place for Protocol-Level Load Testing

    Of course, no single load testing approach is not going to solve everyone’s load testing needs all the time. For example, if you’re trying to test an application that’s not accessible from a browser, the BLU approach isn’t going to work for you.

    Moreover, there are still some situations where you’d be remiss to overlook protocol-level testing with tools like JMeter, Gatling, or API-based test cases. For example, if you want to simulate load against APIs, I’d still recommend running tests that exercise them directly at the protocol level.

    Ultimately, though, it’s important to remember that protocol-level tests can be higher maintenance and use them accordingly. If you have a single click that makes 20 background requests, would you rather wrestle with all the technicalities of scripting that at the protocol level, or have one line of a BLU script that achieves the same business functionality?

    Final Thoughts

    By reducing the complexity traditionally associated with load testing, BLU load testing gives developers and testers a fast, feasible way to get immediate feedback on how code changes impact performance. It’s geared to help people who are not professional performance testers quickly get started with load testing and create load tests that can be run continuously within a CI/CD process—with minimal maintenance. With this new “lean” approach to load testing, any developer or tester can get started with load testing.

    — Tim Koopmans
  • The Developer Playbook: 5 Ways We’re Just Like Football Players

    The Developer Playbook: 5 Ways We’re Just Like Football Players

    — Jeff Veis

  • Should You Migrate to Git? Part 1

    Should You Migrate to Git? Part 1

    There are many factors to consider when making the decision whether to migrate your source code. Is it appropriate for the project? Will it work? How might it impact the quality and performance of the finished product?

    Git can help make the decision easier. Git is an open source version control system for tracking changes in computer files and coordinating work on those files among multiple people (Wikipedia’s definition, not mine).

    Git is gaining in popularity and many industries are now moving to it for a number of reasons. For one, Git’s design and performance are remarkably good among all distributed version control system (DVCS) tools. Also, Git can move work quickly between servers without losing history.

    Git has a wide variety of plug-ins for IDEs, and it also comes equipped with a wide variety of tools to help users navigate the history system. Each occurrence of the source contains the complete history tree, which can be useful when developing without an internet connection.

    Plus, Git was created by Linus Torvalds, who also created Linux, which gives it a certain caché.


    Related Content:

    5 Open Source SIEM Tools Worth Checking Out

    Configuration Files and DevOps


    Git’s popularity has been bolstered by killer apps and services such as GitHub, and some very popular projects used it, which further increased its visibility.

    Git nowadays is very popular, but it is recommended companies don’t migrate tools so frequently. Also, there are challenges in  pre-migration and post migration worth considering.

    Distributed revision control uses a peer-to-peer model rather than using a centralized server to store code updates. While a peer-to-peer model would work better for global, open source projects, it may not be ideal in other situations. The downside to a dedicated server approach is that when the server is down, no clients are able to access the code.

    Pros:

    • Great for those who hate centralized version control system (CVCS)
    • Dramatic increase in operation speed
    • Full history tree available offline
    • Distributed, peer-to-peer model
    • Cheap branch operations
    • Attracting lot to non-technical due its open source features (Git is GPLv2)

    Cons:

    • Learning curve for those used to SVN
    • Not optimal for single developers

    Companies That Have Migrated

    Many of today’s new enterprise technologies are centered around free, “open source” technology. As a result, many big companies, from financial giants to retailers to services firms, prefer open source platforms. With the introduction of GitHub many companies have migrated their code base to Git.

    The most popular open source project serves as a “version-control system” for tracking changes and coordinating work between software developers.

    Some very well-known names use Git, including:

      • AWS
      • Reddit
      • Twitter
      • PayPal
      • LinkedIn
      • Gnome
      • Adobe
      • HubSpot
      • Mozilla
      • DropBox

    Terminology

    Git has it own terminology that users, or those considering using it, should become familiar with. Here are some terms worth knowing:

    • Master – the repository’s main branch. Depending on the workflow, it is the one people work on or the one where the integration happens.
    • Clone – copies an existing Git repository, normally from some remote location to your local environment.
    • Commit – posting files to the repository (the local one); in other VCSes it is often referred to as “check-in.”
    • Fetch or pull – Also known as “update” or “get latest” in other VCSes. The variance between fetch and pull is that pull combines both fetching the latest code from a remote repo and performing the merging.
    • Push –  submitting the code to a remote repository.
    • Remote – these are “remote” locations of your repository, normally on some central server.
    • SHA – every commit or node in the Git tree is known by a unique SHA key. You can use them in various commands to manipulate a specific node.
    • head – a reference to the node to which our working space of the repository currently points.
    • branch – similar to other VCSes; however, a branch in Git is actually nothing more special than a particular label on a given node. It is not a physical copy of the files as in other popular VCSes.

    — Amit Anan

  • Resource Availability: The Missing Piece of the Cloud DevOps Puzzle

    Resource Availability: The Missing Piece of the Cloud DevOps Puzzle

    Any successful software is effort of five groups: developers, the operations/infrastructure team, QAs or testers, product managers and owners, and the support team. There may be other titles involved, but the majority of work is done by these five groups.

    https://www.ibm.com/developerworks/rational/library/edge/08/mar08/pampino-pierce/image003.jpg

    AWS describes DevOps as:

    … the combination of cultural philosophies, practices, and tools that increases an organization’s ability to deliver applications and services at high velocity, evolving and improving products at a faster pace than organizations using traditional software development and infrastructure management processes.

    Under a DevOps model, development and operations teams are no longer “siloed.” Sometimes, these two teams are merged into a single team where the engineers work across the entire application lifecycle, from development and test to deployment to operations, and develop a range of skills not limited to a single function. Quality assurance and security teams may also become more tightly integrated with development and operations and throughout the application lifecycle.

    The majority of DevOps leaders included in this 2015 devopsy.kinsta.cloud agreed:

    • DevOps exists to help the business win.
    • The scope is broad, but centered on IT.
    • The foundations are found in Agile and Lean.
    • Culture is very important.
    • Feedback is fuel for innovation.
    • Automation helps.

    Looking at both of these references, from a technical perspective we can summarize that DevOps puts together development and operations, and speed of delivery can be achieved with tools and automation.

    This all might sound perfect for on-premises deployments because your Dev, QA, Test and Pre-production boxes will be up and running 24 hours and those who are part of the software success—QA managers, product owners etc.—can access them anytime they want.

    In cloud DevOps, however, that may not be the case. Any cost-conscious organization may instruct developers to take infrastructure offline when it’s not needed (most of us know how developers manage infrastructure, so I am not going discuss much about it). But what about other stakeholders of the project? What if the QA team wants to manually test or validate something or product owners want to review something?

    Currently, teams have three options:

    1. Stakeholders call and request the infrastructure team to bring up the servers they need.
    2. Stakeholders are provided with a script to bring up the servers themselves.
    3. Stakeholders must wait until the scheduler brings up the servers.

    Each of these has big drawbacks. The first two options waste a lot of manpower. In era where companies are trying to capitalize human power as much as possible by automating trivial things, it doesn’t make sense to use yesterday’s solutions for today’s problems. And, asking these teams to run scripts to bring up the servers introduces the possibility for errors, as these teams are not that hands-on with infrastructure or scripts.

    The third option is a perfect example of using old solutions for current problems. In the cloud world especially I see at least two problems with this solution:

    1. In cloud environments, where you pay for resources by the second, bringing up servers at whatever scheduled time wastes money. Let’s be frank: Who sits down in front of a computer at 8 a.m. and doesn’t move until 7 p.m.? There will be times during the day when the servers simply won’t be used due to other obligations such as staff meetings, lunches, etc.
    2. In Agile environments, where people work at their own pace and time schedule, it doesn’t make sense to limit them to a certain scheduled time period.

    Cloud DevOps demands a model that can keep all stakeholders working at peak efficiency without running into resource scheduling issues. It’s a difficult proposition that needs an effective solution.

    How is your organization handling resource availability in the cloud?

    — Krishna T

  • NodeSource Increases Metrics in Node.js Development Platform

    NodeSource Increases Metrics in Node.js Development Platform

    As reliance on Node.js to build applications in the enterprise has skyrocketed in recent years, the challenges with managing these applications have been manifold, because most existing tools don’t provide much visibility into Node.js applications. To help address that issue, NodeSource has revamped a development framework based on Node.js to make it easier to manage deployments of Node.js applications at scale.

    NodeSource CEO Joe McCann says N|Solid 3.0 includes a revamped user interface and enhanced dashboard through which thousands of processes can be monitored. DevOps teams now can choose from more than 50 metrics to explore relationships between application data. In addition, all of the snapshot and profile assets can be downloaded, sorted, deleted or marked as favorite. Previously, the dashboard could only monitor up to 250 processes.

    The latest edition of NodeSource also provides support for alerts that can be used to trigger notifications in the event certain thresholds are exceeded.

    Fresh off raising an additional $17.5 million in funding, NodeSource has been making the case for an enterprise-class implementation of Node.js for several years. It counts Citadel, Comcast, Condé Nast, Delta Airlines, Goldman Sachs, Mastercard and PayPal among the organizations using its platform.

    NodeSource captures application metrics using agent software written in C++. The idea is to replace an open source implementation of Node.js with the version developed by NodeSource that is integrated with that agent software.

    As a variant of JavaScript, Node.js is essentially delivering on one of the original core promises of Java by making it easier for developers to build applications that can run on both clients and servers. Variants of JavaScript may not be as robust a framework for building applications as Java, but as programming environments go, JavaScript variants are much more accessible. According to the Node.js Foundation, the arm of the Linux Foundation that oversees the Node.js framework, there are more than 15 million downloads of Node.js per month.

    Most of the Node.js use is driven by developers who don’t always appreciate operational management issues. Many IT organizations have been hesitant to more broadly employ Node.js because they lack the tools needed to manage Node.js applications at scale. NodeSource is now trying to address that issue by embedding management tools in its core platform.

    By embedding many of the management tools needed to manage Node.js at scale, NodeSource is hoping senior-level IT managers will adopt its platform as a corporate standard instead of continuing to allow developers to pick whatever flavor of Node.js they find. Naturally, increased usage of Node.js is drawing interest across a broad spectrum to DevOps tool providers, so the issue many IT organizations must evaluate is the degree to which they can rely on existing DevOps tools to manage Node.js applications. NodeSource recently integrated its platform with the application performance management tools provided by AppDynamics. Because developers are now being held more accountable for the performance of their applications, NodeSource is betting that the metrics it provides will also appeal to enterprise developers.

    The degree to which Node.js will become a de facto enterprise standard remains to be seen. Contention between various programming language camps is fierce. But at the very least it’s already apparent that Node.js applications in the enterprise are here to stay.

    — Mike Vizard

  • Dissecting the Role of QA Engineers and Developers in Functional Testing

    Dissecting the Role of QA Engineers and Developers in Functional Testing

    Until a few years ago, quality assurance was generally considered low-level R&D. As a result, quality assurance (QA) teams were characterized by a low budget, lack of attention and, more often than not, poor attitudes. Moreover, QA engineers were considered the enemies of developers and the product.

    However, today, this is no longer the case, and QA is part of the entire software life cycle. Today, organizations understand how a product’s quality affects the brand’s reputation and customer retention. In the Agile ecosystem, QA engineers are no longer solely focused on testing; they also fill an important role in the planning and delivery domains. The shift left approach—where testing is performed earlier in the life cycle—requires QA engineers to have higher technical abilities and involvement in the whole CI/CD process. Nevertheless, QA managers, who usually encourage assimilation in the scrum team, as well as rapid feedback for user stories and automation, must not forget the main objective of quality engineers: to ensure a high-quality product and a seamless user experience for customers.

    High quality demands testing and verifications. There are different types of testing that can be conducted to meet quality goals. In one of its blog posts, Testing Excellence describes almost 60 types of testing that can be performed on a product. We’re going to look at one that is quite clearly one of the most important types of testing: functional testing.

    Different than other forms of testing, functional testing is considered one of the most sophisticated test type, and the most comprehensive one.

    Same Team, Different Responsibilities

    One important fact every QA engineer must remember is that developers develop and QA engineers test. Even though QA and developers are part of the same scrum team, their work, methodologies and state of mind are completely different. In cases in which the significant contribution of QA isn’t visible to the whole team, testing might be considered an easy and clear task. Quite the contrary; testing an application is much more complicated and entangled than developing it. When planning tests and executing them, QA engineers must take into account several aspects developers likely never consider.

    Understanding How the User Thinks

    The primary distinction between dev and QA is state of mind. While developers write pieces of code that later become features in the application, QA is expected to understand how real users think, engage customers to learn business scenarios, and confirm that the application satisfies customer needs.

    Let’s look at eBay, for example. Every veteran R&D member will agree that eBay isn’t just a simple shopping application, but a comprehensive system that includes a whole set of capabilities on both web and mobile that requires attention and deeper understanding to determine whether they really function correctly. In such a rich and mature online platform, we can identify several types of users and many cases in which the application may be utilized. A seller performs different steps than a buyer and requires different functionality, while a support agent needs an entirely different version of the application. When planning tests, all these personas must be taken into consideration with a particular test plan for each. In other words, testing functionality is not just simulating user operations.

    In addition, eBay is not a standalone application—its web application lives inside the browser and subsequently depends on that browser’s rules and behaviors. This is true for eBay’s mobile apps, as well, which must meet the OS constraints to function correctly, whether it’s navigating to the seller’s store or making a purchase. This makes compatibility testing an integral part of functional testing. Most developers don’t think about the project availability matrix when they code, so QA is required to contemplate all the ways the customer will engage with the application and verify functionality for each.

    Viewing the Application as a Whole

    Dev and QA differ in their point of view—an obvious but important distinction. While developers focus on developing user stories, QA engineers test the user story, the feature it is part of and the application behavior with the new code. Integration testing is a crucial part of the application verification effort and requires a broader view of the application and how the new functionality is part of it. End-to-end testing is the fulfillment of the above two aspects, validating that real user scenarios in the context of multiple regions in the application behave as expected. End-to-end tests increase test coverage and reduce the risk of making the new code part of the application.

    Paying Attention to User Experience

    As noted, testing the application functionality is merely one step in functional testing. Testing the operations available in the application encompasses another type of testing—the user experience. If a new feature is developed, but users do not have easy access to it or cannot understand how to use it, it is as if the feature doesn’t exist. QA engineers must incorporate user experience as a main metric of features so users will not have room for error, which can lead to misuse and frustration.

    For instance, eBay’s “all categories” page previously displayed all the categories by default, even though some of the categories had no items. While this was the correct behavior from a functionality standpoint, it caused user confusion and mistrust. Consequently, the “all categories” view was changed to show only categories with items.

    Looking at the narrow current task, developers might implement features as they are told without questioning or contemplating the specifications. In the same way, testers who test features without realizing how customers perceive them are missing an important benefit of the test.

    The above three aspects—thinking like customers, testing the application as a whole and paying attention to user experience—revolve around the way developers and QA engineers relate to new features. While developers tend to follow the specification guidelines, QA engineers must “think outside the box” when it comes to user consumption of the feature.

    There are two other ways in which QA work is more complicated and yet invaluable—test maintenance and test automation.

    Maintaining High Quality Throughout an Efficient Release

    In general, developers split their time between developing new features and fixing defects. QA work is much more diverse. A substantial portion of the release is spent on testing functionality that already has been released and used. While the main effort of designing and writing test plans for this functionality was invested in past releases, every new feature developed requires a test plan and a maintenance effort on existing tests. One of the main goals for QA managers is reducing this effort to a minimum. Teams that succeed in creating clear and reusable tests simplify the maintenance struggle and optimize the test registration time.

    Eliminating Risk Through Automation

    However, for QA, the most cost-effective solution is test automation. At release end—the time when QA is at its most stressed and every commit might introduce a new risk—automation testing can eliminate risk and supplies early feedback on every change. Agile teams strive for the highest automation coverage percentage so the development team can have confidence in committing changes late in the release. That said, developers often aren’t interested in investing their time in automation. They support the QA automation effort, but they don’t want to “dirty their hands” by doing testing. Whether it’s UI automation—during which achieving element uniqueness is essential yet tricky and requires developers’ intervention—or API testing for APIs without proper documentation, QA faces intricate challenges that require sophisticated solutions, which developers are, in most teams, not part of. While the dev team focuses on the status of the new feature, QA attends to the application as a whole with extra attention to identify regressions created by a change.

    Join Forces for Higher Rate of Success

    Testing an application requires a completely different mindset than developing it. One of the main challenges in the Agile methodology is to create developer awareness of quality, involving other stakeholders in the quality assurance activities and making the QA process visible to everyone. QA managers must understand how day-to-day QA work is different than the work of other team members so they may truly represent the complexity, efforts and eventual success. R&D groups that join forces and understand that QA extends far beyond the actual tasks of the QA team have a much higher chance of improvement and set high standards for their product’s quality. Implementing the appropriate methodologies and utilizing the right tools lead to an increase in customer satisfaction and retention rate.

    About the Author / Ronit Eliav

    Ronit Eliav is the Director of Product Marketing at Panaya. With a deep interest in digital transformation and the latest IT trends, she enjoys creating thought leadership around such topics as agile and continuous delivery, DevOps, quality assurance and IT modernization projects. Connect with her on LinkedIn.

  • Making Software Maintenance Cool Again with DevOps

    Making Software Maintenance Cool Again with DevOps

    What makes DevOps so important? Part of the answer lies in how DevOps encourages more appreciation for and investment in software maintenance.

    Traditionally, the IT industry has been like the construction industry. People who design new things (architects or software developers) are at the top of the value hierarchy, whereas the folks who build and maintain them (construction workers and IT Ops admins) are not held in such high esteem.

    This isn’t to say people hate admins, of course (or construction workers, for that matter). What I mean is that the work of building and maintaining tends to be seen as less creative and exciting—and ultimately less important—than the work of designing new things.

    This is why software developers in the pre-DevOps world got most of the glory. They created new code that did exciting things.

    Meanwhile, admins on the IT Ops team were stuck deploying and maintaining that code—and occasionally cleaning up messes created by developers who wrote bad code. Admins were also the first folks to take the blame when something went wrong.

    This isn’t to say that developers cause all the problems, of course. Some mistakes can be attributed to admins. Others are the result simply of poor communication between developers and admins.

    Still, in general development work—which involves creating new features and innovations—was what was celebrated. Maintenance work performed by IT Ops was less glorious.

    DevOps and Software Maintenance

    One of the most important—yet also most underappreciated—results of the DevOps movement is that it has made software maintenance cool again.

    In addition, DevOps provides more organizational support for maintaining software, while also facilitating the type of communication between developers and admins that leads to better maintenance.

    DevOps does this through principles such as the “you build it, you own it” mantra, which stipulates that whoever writes code is also responsible for deploying and maintaining it.

    Even if your organization doesn’t adopt that particular DevOps practice, it probably still seeks greater collaboration between developers and IT Ops. As a result, when something breaks in production or needs to be upgraded to maintain reliability, developers are involved, too.

    Celebrating Software Maintenance in DevOps

    Despite the emphasis that DevOps has brought to software maintenance in practice, you still don’t hear a lot of talk about maintenance work in the DevOps world.

    In essence, coding is still seen by many people as the coolest type or work that is done in the DevOps world. What DevOps has done is break down the silos separating those who code from those who maintain. It hasn’t necessarily made maintenance itself the object of more excitement.

    It may be time for that to change. Forward-thinking organizations should recognize that software maintenance—which includes tasks such as applying updates, monitoring applications and scaling host infrastructure—is just as crucial for a seamless application experience as the applications themselves. This should become an explicit part of the DevOps conversation.

    — Chris Tozzi

  • HashiCorp Terraform Enterprise Empowers IT Administrators

    HashiCorp Terraform Enterprise Empowers IT Administrators

    Most of what passes for management of IT infrastructure often amounts to little more than a Word document describing how a system is configured. HashiCorp developed Terraform to enable IT organizations to programmatically manage IT infrastructure. Now the company is taking that concept a step further with the release of Terraform Enterprise, a collaboration application that can be employed to programmatically manage IT infrastructure without requiring IT administrators to know how to program.

    HashiCorp co-CTO Armon Dadgar says Terraform provides an application that makes its Sentinel policy management framework more accessible. Previously, use of Terraform and Sentinel were limited largely to developers looking for a common way to manage infrastructure as code. But Dadgar says customer requests made it clear there was also demand for a collaboration application that did not require any programming skills to employ.

    Terraform Enterprise includes Workspaces, a set of modules that that can be delegated to separate teams. Dadgar says Workspaces are roughly equivalent to Git repositories that have access controls for each IT team, using a secure access markup language (SAML) that comes with built-in encryption.

    In addition, Terraform Enterprise exposes an application programming interface (API) that can be invoked for integration with existing tooling or application delivery pipelines. Dadgar says with the rise of multiple clouds in an organization, it’s now only a matter of time before existing approaches to managing IT infrastructure simple become obsolete. Pressure from developers to increase the amount of time it takes to provision and update IT infrastructure is only going to increase, says Dadgar.

    HashiCorp is effectively trying to smooth over one of the more contentious aspects of DevOps. In theory, developers want more control over IT infrastructure largely because they often view internal IT teams as being too slow. To enable IT organizations to be more responsive, various APIs have been exposed that can be invoked using IT automation framework. Many of those frameworks, however, require programming skills that most IT administrators don’t possess. Many organizations also don’t want developers to be managing IT infrastructure when they could be devoting that time to writing and test applications. Dadgar says Terraform Enterprise provides a graphical user interface (GUI) through which all the benefits of managing infrastructure as code can be attained without having to teach administrators how to program, or allowing programmers to invoke IT infrastructure resources without any adult supervision.

    HashiCorp is not the only provider of IT management frameworks trying to solve this issue. There are rival declarative frameworks for automating IT and many providers of the latest generation of software-defined infrastructure are embedding modern IT management frameworks within pre-integrated systems. But HashiCorp is one of the few vendors providing organizations with a dual approach using the same core underlying set of APIs. Rather than continuing to be at odds with one another, developers and IT administrators now could find it easier to collaborate using whatever approach to infrastructure as a code they best see fit.

    — Mike Vizard