Tag: database

  • Enterprise Cassandra Deployments

    Enterprise Cassandra Deployments

    Successful Cassandra deployment in the cloud takes a certain amount of skill and knowledge. In this blog I will share best practices for a successful Cassandra deployment in the cloud such as Amazon Web Services (AWS) and Google Cloud Platform (GCP). I will also discuss how you can protect and recover the data in your Cassandra cluster when deployed in the public cloud.

    Cassandra Deployments in the Public Cloud

    There are two main ways to have successful enterprise Cassandra deployments in AWS:

    • Use a ‘managed’ Cassandra deployment. This is a reasonable approach; the only downside is the inability to customize data placement beyond what is typically provided by the vendor.
    • Manage the cluster yourself, if you want to have full control over your Cassandra deployment and customize it to scale and perform according your business needs.

    Please refer documentation from Datastax or Apache Cassandra for detailed best practices for Cassandra deployments. The following best practices are reiterated here to simplify deployment of a scalable Cassandra cluster in AWS.

    Storage

    Both AWS and GCP offer two types of local storage options for their compute instances. For AWS, the options are Elastic Block Storage (EBS) and Ephemeral Storage. In GCP, the options are Persistent Disks and Local SSD. Both options have their own trade-offs. Pick the one that best suits your deployment.

    Persistent Storage

    EBS volumes have performance characteristics similar to network storage such as a NAS or SAN. Because storage from EBS volumes is multitenant in nature, it is not suitable for distributed, log structured databases such as Cassandra. If you want to ensure reliable performance through EBS volumes, use “EBS optimized instances” with “provisioned IOPS.” Since the IO traffic to EBS volumes goes over the instance network, EBS optimized will provide reliable performance, but does not guarantee any increased performance. To get the most performance out of EBS volumes, use instances with multiple disks and separate the volumes used for “Data” and “Commitlog.”

    If you have to use EBS Volumes, go with “EBS Optimized Instances,” with “Provisioned IOPS” and split data and Commit Log on different volumes.

    Ephemeral Storage

    Ephemeral storage is a great option to use for downstream Cassandra environments such as test/dev and staging. Since ephemeral volumes are typically SSDs, there is no need to separate the data and commitlog into separate drives. To optimize performance, choose EC2 instances with multiple ephemeral storage drives and stripe them together into one logical volume. Send data and commitlog to the logical volume. Remember that when you stop the EC2 instance, the data in Ephemeral storage will be deleted.

    Stripe all Ephemeral drives into a single volume to get maximum performance.

    Data Distribution

    Cassandra uses Snitch to determine the topology of the cluster. The Snitch is also used to determine the data center and rack for each node in the cluster. Replication strategy is used to determine the placement of data across the different nodes in the cluster.

    AWS

    1. EC2Snitch works well for single region deployments.
    1. Ec2MultiRegionSnitch works well for cluster distributed across multiple AWS regions. Please note, Multi-DC, Active-Active configuration makes your cluster resilient to region failures and for multi-dc cluster, use “local quorum” to improve performance.

    Google Cloud Platform (GCP)

    1. Use GoogleCloudSnitch for Cassandra deployments in GCP.
    1. GoogleCloudSnitch treats regions as Cassandra data centers and availability zones as racks.

    Other Features

    Both AWS and GCP offer a series of operational capabilities that seem to make it easier to maintain high uptime on Apache Cassandra cluster. These capabilities have to be chosen carefully depending your deployment needs.

    1. Load Balancing: Network-level load balancing service is offered by both AWS (Elastic Load Balancer) and GCP. It is not recommended to put a load balancer in front of Cassandra. It is better to use a client connector that can handle this, consider open source utilities such Presto and Astyanax
    1. Autoscaling: Both AWS and GCP offer Autoscaling facility for compute instances. However, although this functionality looks very enticing, putting all C* nodes in an autoscaling group will not produce the desired result. Instead, create a separate autoscaling group of ‘1 node’ for every node in your cluster. This will ensure that anytime a node goes down, it is automatically brought back up. This will ensure the cluster data placement is not disturbed when nodes go down and nodes coming up do not cause excessive data movement.

    Scalable Backups and Reliable Point-in-Time Recovery

    Backing up your data is a must-have for enterprise organizations. The impact of data loss is so high that no enterprise wants to risk relying alone on replication. Protecting data in a public cloud environment may seem daunting, but there are several options available that can make this easier compared to an on-premise deployment. A simple option may look like one of the native snapshots:

    Storage Snapshots

    I have seen few customers use snapshots of EBS volumes as a way to protect the data in their cluster against logical and/or operational errors. This solution will work but with some severe limitations. On top of the overhead of maintaining the scripts to take snapshots, there is a large overhead in storage costs. Taking a snapshot of volumes does not allow for incremental backups of your data. This causes an exponential bloat in the amount of data stored in snapshots, leading to high cost of the backup solution.

    Amazon S3 or Google Cloud Storage

    Using an S3 bucket as the secondary storage enables enterprises to use low-cost, highthroughput storage, while reducing overall operating costs for storing backup data. Here are a few recommendations when using S3:

    1. S3 Region: Amazon S3 buckets are region-specific. A bucket created in one region will provide better performance characteristics to other infrastructure in the same region. Subsequently, it is important to ensure the S3 bucket used as the secondary storage is in the same region as the production database being protected and the Datos IO cluster.
    1. Storage Class and Lifecycle Policy: Amazon S3 allows users to create lifecycle policies on buckets. These policies dictate the performance and response time characteristics of objects in the bucket. STANDARD_1A is more suitable for longer lived and less frequently access data, and is not suitable as secondary storage. Additionally, do not turn on any lifecycle policies on the buckets used for the secondary storage. All buckets should be in the standard storage class.

    Conclusion

    As enterprises leverage the agility provided by public cloud environments, it’s important to understand the various facets of Cassandra deployments to ensure the efficient use of your money and time.

  • DBmaestro Raises $3M in Series A Funding to Expand DevOps for Database

    Financing came after DBmaestro tripled subscription revenue in 2015 

     Houston, Texas, February 24, 2016 – DBmaestro (http://www.dbmaestro.com/), the pioneer and leading provider of DevOps for Database solutions, announced today it raised $3 million in Series A funding from a number of venture capital firms including StageOne Ventures, lool Ventures and iAngels. The financing will be used to grow DBmaestro’s global sales and marketing and to seal its place as the leading database automation solution.

    The funding round came after a banner year for the company. In 2015, DBmaestro tripled their subscription revenue and signed many high-profile brands, including Barclays, Bank of the West, Allianz, and VISA. These achievements were driven by the success of their flagship product, TeamWork, which enables agile development, Continuous Integration, and Delivery for the Database.

    DBmaestro’s DevOps for Database solution offers a comprehensive approach to the database development life cycle, providing enterprises need to deliver changes faster. DBmaestro has been at the forefront of Continuous Delivery for the database, with a solution which brings innovative methods for safe database automation and ultimately reduces costs in development and deployment. Subsequently, it was named to the 2015 SD Times 100 for its Innovation in the Database and was also recognized as a prominent vendor of the DevOps tools market in Technavio’s Global DevOps Tools Market 2015-2019 report published in August 2015.

    The company’s growth led to the hiring of Danny Neuberger as Senior VP of Sales EMEA & APAC and Roy Lauzon as VP of R&D. Neuberger brings over 20 years of executive experience at Microsoft and EMC, while Lauzon has led software development teams at Celebros for almost 10 years. Said Lauzon: “Having worked for a decade on the software development side, I can attest to the critical need to adopt the best practices we’ve been implementing for software to the database as well.”

    “I believe that the success we have seen underscores the need in the community for our solution,” said Yariv Tabac, CEO and co-founder of DBmaestro. “Our customers are in highly competitive markets and the ability to implement continuous delivery and integration for the database is crucial. We are proud of our achievements and excited to bring on a number of experienced executives to continue to support each of our growing number of clients as they navigate the journey towards complete database automation.”

    About DBmaestro

    DBmaestro is a pioneer and leading DevOps for database solution provider. Its flagship product, DBmaestro TeamWork, enables agile development, Continuous Integration and Delivery for the Database.

    TeamWork supports streamlining of development process management and enforcing change policy practices. The solution empowers Agile team collaboration while fostering regulatory compliance and governance. With DBmaestro, organizations can facilitate DevOps for database by executing deployment automation, enhancing and reinforcing security as well as mitigating risk.

    DBmaestro’s solutions are deployed at many major international companies, including Visa, Isracard (MasterCard), Barclays, Bank of the West, Allianz, Frost Bank, Thomson Holidays, Bank Leumi, and others.

  • Avoiding Database Migration Pitfalls with Continuous Software Delivery

    Avoiding Database Migration Pitfalls with Continuous Software Delivery

    When people talk about continuous software delivery, they often focus on the delivery mechanism itself, such as automation tooling or branching strategies. What is frequently overlooked is the simple truth that continuous software delivery is worthless without continuous service availability. In other words, if you’re going to frequently update your service, your customers shouldn’t frequently experience disruptions.

    Despite all good intentions, the cause of many unintentionally-disruptive deployments are database migrations. This makes sense, as all other components of a service infrastructure are fairly easy to swap out or to roll back. Software directory symlinks can be easily changed, EC2 instances can be easily started, DNS entries can be easily updated, but performing a breaking change on a multi-million row table in a database that’s under heavy load? Not so easy.

    Successful Migrations

    There are three necessary requirements for a database migration to be considered a success:

    1. The delivery of the service was not disrupted or degraded
    2. The database migration must be repeatable (re-entrant)
    3. The software version can be rolled back to the previous release if needed

    The first seems obvious, but can be surprisingly difficult to achieve. The chief reason for this lies in the vagaries of how different database technologies, and even versions of the same technology, handle things like table locking during an ALTER statement. The other reason is a hidden complexity within your application code. For example, a JOIN statement that causes a frequent query to be blocked by a seemingly unrelated table change.

    The second criteria means that if a migration fails for some reason, it cannot leave the data in such a state that the migration cannot be run again – essentially, running the same migration twice should not result in a negative outcome.

    The third criteria absolutely precludes ever doing a “one way” release where rollback is made impossible due to data destruction. It’s okay to have a release that rules out rolling back several releases; without that, the database would become a giant pile of discarded data. That said, it’s never a good idea to paint yourself into a corner with a release that you cannot possibly revert.

    Avoiding Service Disruption

    The simplest way to avoid service disruptions is to never perform a database migration. But, that just isn’t feasible, so how do we avoid stepping on a landmine during a migration?

    First and foremost, implement a policy of strict database migration reviews. This doesn’t need to be burdensome or time consuming. It just means that someone who is best equipped to understand the impact to the database technology actually gets eyes-on the migration before it is run. This is a role often served by your database administrator, chief architect or most senior developer.

    Another good idea is to set up a hook in your code versioning repository, or a test that’s part of your build process, that examines database migrations and looks for certain keywords – and the lack of other keywords. For example, it might “fail the build” if it finds an ALTER TABLE statement that is not accompanied by the word CONCURRENT.

    If you’re dealing with a lot of legacy code, or a monolithic application with significant complexity, then there are two very important safeguards you can put in place: load testing and SQL statement logging.

    Load testing means having a development environment setup where you can apply a database migration to a database that is under load, i.e., experiencing a level of usage that roughly approximates your production database load and which contains an amount of data similar to production. Then, while your database migration is running, you can run an application smoke test or similar to see if production-like load combined with the migration results in any unexpected slowness or errors.

    Remember, all database migrations are fast when they are the only thing running on your database, and faster yet when the testing database is a tiny fraction of the size of the real thing. Going into production feeling confident that a migration took only ten milliseconds to complete on a half-empty database with zero active connections is a fool’s errand.

    When you have a poorly-understood or monolithic application, it can be a very enlightening experience to enable SQL statement logging on your production database server. Remember that MyISAM table that never seems to change and against which it should be safe to run a giant blocking migration? SQL statement logging might reveal that every single page load executes a long-forgotten JOIN statement that scans that entire MyISAM table. Or that the user login process looks in that table for reasons nobody can remember. This is also an area where using a solid application performance tool like New Relic can make a very big difference.

    Repeatable Database Migrations

    This one sounds simple but can actually be a bit tricky to implement. Consider the following scenario, you have a table that contains three columns: id (integer), username (string) and password (string).

    As it currently stands, the passwords are stored in plaintext in the database, and your application does a simple string comparison between what the user enters and the results of a SELECT statement. The next version of your application is going to hash the password entered by the user, and compare the hash against a hash returned from the database by SELECT.

    There are two possible ways of getting from where you are now, to where you want to be – one is dangerous, and the other is safe.

    The dangerous way would be to create a database migration that iterates through the password column and replaces each plaintext value with a hash of that value. Basically a SELECT; md5(); UPDATE; loop. This is dangerous for a number of reasons:

    If the migration stops before completing, the database will be left in an unusable state where neither the old nor new code can make use of the entire table.

    1. If the migration fails to complete for any reason, it cannot be run again without corrupting all the previously-migrated values.
    2. If the new code has to be reverted to the old code for any reason, the table is now in a state that cannot be used by the old code.

    The safe, and repeatable way of performing this migration actually involves three releases:

    Version 2.0 migration adds a new column (pass_hash) and migrates password to it, and new application code must INSERT and UPDATE to both

    1. Version 2.1 application code must now use only the pass_hash column, and ignore the password column.
    2. Version 2.2 migration removes the password column, and new application code continues to use only the pass_hash column.

    You can rollback from the first release (2.0), as all the original, unencrypted password data still exists in the database, and the previous code release won’t care about the new column (pass_hash) being present. You can also run that first migration multiple times – just have it remove the pass_hash column if it exists prior to creating it.

    Next, you deploy code (2.1) that makes use of the new column only. You might be tempted to bundle the database cleanup migration with it, but don’t – if you need to rollback for any reason, you won’t be able to if you’ve removed the password column. It’s always a good idea to delay breaking changes, like a column deletion or dropping a table, by at least one release.

    And finally, run a migration (2.2) that drops the password column, if it exists. That latter condition is so you can run the overall migration more than once if needed. If the password column exists, remove it; otherwise, merrily continue with the rest of the release. Note that at this point in time, the live application code is ignoring the password column entirely. This is important, since the current application code will be using the database while your migration is running. In other words, any migration must be safe to run under both the current and the about-to-be-deployed code version.

    In case you hadn’t already guessed, this approach to migrations does take a bit more conscious thought and effort than the old, dangerous way. You’ll need to keep track of “deprecated” bits of your database for future removal. And you’ll need to occasionally write code to intelligently update two columns or tables in lockstep, and then remember to remove that code in the future. That said, it’s definitely worth it in the long run when you’re able to release frequently with zero downtime.

    Release Rollback

    Nothing produces longer outages and greater negative customer impact than being unable to rollback or revert a release. If you’ve accidentally deployed a major bug into production, you want to quickly revert to the previous version that didn’t have that bug, and then reproduce and fix the bug at your leisure in your development environment. Being unable to reproduce the bug in your development environment is not a valid reason to fail to rollback a release, and it’s an entirely separate discussion apart from migrations.

    The essence of rolling back is speed. It must be a fast and reliable process. The number one way to ensure it is anything but fast and reliable is to have a breaking or one-way database migration in the release you wish to roll back. Thus, anytime you are creating a new database migration, ask yourself two simple questions:

    1. What would happen if I ran this migration with the current application version?
    2. What would happen if I ran this migration twice?

    If it would change the database in a way that would cause the current application version to explode, then it needs fixing. And if it would change the database in such a way that it can’t be run again, then it needs fixing.

    The End Results?

    In a nutshell, this approach to migrations means that each migration will be very small and very simple. Expect to get from state A in your database to state B via many safe steps, instead of one giant, dangerous step. Your customers, and your application uptime, will thank you!

    About the Author/Nate Lindstrom, VP solutions engineering

    highres_250316251Nate Lindstrom is the VP of solutions engineering for NS1, an intelligent DNS and traffic management platform with data driven architecture and a unique Filter Chain routing engine. NS1 is purpose-built for the most demanding, mission-critical applications on the Internet. NS1’s comprehensive platform technology leverages infrastructure, application, and network data to make intelligent routing decisions in real time, ensuring optimal application performance and reliability.


  • Building an agile data tier improves devops efficiences

    Building an agile data tier improves devops efficiences

    Meet the modern day agile data tier – improving DevOp efficiencies
    DevOps teams are constantly in the high-pressure environment of reacting to real-time market and industry changes and launching new features and functionality to maintain competitive positioning. Accelerating development is simply not possible if scalability is an issue. Scaling databases has proven to be especially challenging. Software rollout cycles can easily get delayed because of the complexity of coding for database scale out. At the same time, a lack of understanding and visibility of app behavior can also result in slow apps getting launched. Without intense technical development, databases can be the function hindering your apps – but they don’t have to be.

    DevOps: Resist the urge to do-it-yourself
    As pressures mount to deliver more and more applications, DevOps teams can benefit from creating an agile data tier that seamlessly addresses the most technical, yet burdensome, administrative functions of databases and lets software do the hard work instead. It is now possible for DevOps teams to offload database scalability and failover without increasing app complexity and enable a zero downtime experience along the way.

    Database load balancing software enables this agile data tier. It acts as an abstraction layer between apps and databases, getting developers out of the business of programming for the database and letting them instead spend their time on more strategic projects. Having an agile data tier profoundly reduces development time, taking dev cycles from months to weeks.

    The last thing any developer wants is for an app to become more complex and burdensome – both are big risks when dealing with databases. But there is more to database load balancing then other kinds of load balancing. Replication-aware load balancing, read/write split and caching functionality are all crucial for database scale out. But designing those functions directly into the app is time consuming and repetitive. Designing for high availability just adds to the complications.

    With database load balancing the idea is to take this burden off of the app – and therefore off the developer – resulting in faster rollout, better scalability, and the ability to refocus time and attention to features and functionality that contribute to the business. What developer woke up this morning craving to spend a good chunk of their time on programming for database scale out?

    Making applications fundamentally less complex and improving their availability, database abstraction solutions that provide database load balancing such as ScaleArc, the company I founded deliver on the promise of scale and always-on app availability. Such software makes application design far simpler, leaving more time to develop and build applications that drive business advantage.

    About the Author/Varun Singh

    Varun-SinghAs Founder and Chief Technology Officer, Varun Singh leads ScaleArc’s product development and technology strategy. He also served as ScaleArc’s CEO from March 2009 to September 2013 and was responsible for impressive company growth and customer acquisition of top brands including Tesla Motors and Zuililly with limited if non existant marketing or sales budgets. Varun is a technologist with broad experience in several fiends, from running Linux-based BBS sytems in the pre-Internet days to writing about technology and open source software at PC Quest, CHIP, Digit and Network Computing. He was responsible for creating India’s top online technology brands and his team kept CNN India running as the only uninterrupted news network during the Mumbai terrorist attacks.

  • Why DevOps for the database must include three way analysis

    Why DevOps for the database must include three way analysis

    Deployment automation is critical to practicing effective DevOps. Without deployment automation, releases still require a lot of manual steps and processes. Processes and steps that aren’t reliably repeatable, are prone to human errors, and can’t be handled consistently with high frequency.

    However, the software best practices can’t simply be grafted onto database deployments. Unlike software code, a database isn’t just a collection of files. You can’t simply copy a database among your different development, testing, and production environments. Deploying a database also presents a greater business risk since it holds your most valued asset – your data.

    In order to capitalize on DevOp automation advantages for databases and to promote database changes safely and quickly, all the particular components of a database; its tables, functions, and content, need to be protected.

    Any successful DevOps database automation solution must be capable of intelligently dealing with conflicts and merges of code and cross updates from other teams. The solution must be able to ignore wrong code overrides and give the user ultimate control over which changes and merges are pushed out.

    unnamed (5)

    In order to achieve these goals a DevOps for the database solution must be able to conduct a three-way analysis on the source (that is, the object after the development work is done), the original (or “baseline”) state, and the target (or “Production”) environment, identifying the differences among these three states. Team members, gaining full knowledge of the complete scope of the project from the analysis, can review the results and options the solution presents to resolve any discrepancies. The user selects what action, if any, should be taken on the database. The solution then automatically generates the scripts to execute the chosen actions.

    In this way, the solution uses automated three-way analysis and automatic script generation to eliminate both the potential for human error in manual script writing, and the potential for technological error in automated object overrides.

    Reaping the Rewards
    Implementing a solution that encompasses all these automation features to meet the particular challenges of database deployments, would enable a company to practice a DevOps approach to effective database automation and realize the following benefits:

    · Reduced deployment costs through streamlining of development process management

    · Minimizing deployment risks by enforcing change policy and best practices, and configuration management and consistency

    · Improving responsiveness to customers and market needs with speedier roll-outs of task-based development updates

    · Enhancing cross-team communication with clear audit trails and transparency regarding work done on objects and the state of different environments

    Can you afford to be without it?

    About The Author ⁄ Yaniv Yehuda, CTO, DBmaestro
    unnamed (4)

    Yaniv is the Co-Founder and CTO of DBmaestro, the leading provider of DevOps for Database solutions which enable control of database development and deployment. Yaniv is also the Co-Founder and the head of development for the Extreme group, a leading IT services solutions provider group.

  • Bringing the Database into the DevOps Fold

    Bringing the Database into the DevOps Fold

    In my last post on devopsy.kinsta.cloud I asked the question, “Where is the DBA in the DevOps Conversation?” I have wonderful news. I’ve found them! Having not been offered a seat at the table with everyone else, the DBAs have decided to have their own party in the form of a survey and corresponding report by Unisphere Research for the Independent Oracle Users’ Group.

    Until now so much of the research, literature, and web content on the topic of DevOps has been completely devoid of talk about the database and DBAs. The oversight was significant and troubling given the immense strategic business value of any organization’s ever growing store of data. The IOUG report does an excellent job of framing the case for DevOps in terms of the special considerations required when trying to adapt to the lightning fast pace of change in modern IT.

    For me, the biggest take away from the report is that DBAs and their managers are feeling the pain of increased release velocity acutely.
    Interestingly, while the age of automation and cloud may be upon us, an increasing number of database managers and professionals report that they are being mired in manual processes. More than one-third cited this as a challenge, up a dramatic 162% from four years ago.
    There’s no question that companies large and small understand that releasing quality services and features based on market demand at a faster rate than your competition keeps your organization on top. It’s also apparent that product development and most of IT operations have made the necessary investments in process modification and the automation necessary to truly achieve faster delivery. Unfortunately the report confirms what the good folks at my company, Datical, have been saying all along. The lack of safe, intelligent deployment automation options for the database is starting to limit the potential gains of DevOps implementation…and the data team knows it. But it’s not the actual script execution that takes so much time. It’s all the time spent before that maintenance window making sure that security isn’t being compromised, that the change is compliant with external regulations and corporate standards, and that it won’t negatively affect your data.

    Today’s manual database operations, processes, and approval time are among the causes of delays holding up the real-time enterprise, many database managers and professionals admit. Frantic development cycles and the accelerated pace of business innovation requires that data and insights be available at a moment’s notice. Close to 41% of respondents report that it takes a week or more to approve change requests, as well as to configure new databases for key purposes, even for testing.

    To safely reduce these cycle times a DevOps solution for database deployments has to harness the expertise and experience of an organization’s DBAs to fuel intelligent, environment-aware automated validation of these change requests. The automation can’t simply parse the SQL script looking for patterns that may be problematic. It must be able to evaluate all 5 W’s associated with the change and make the correct determination as to whether it is acceptable or needs further review. By focusing the valuable finite resource that is your organization’s DBAs on only those changes that need their special attention, you’ll reap even greater rewards from your DevOps investments.

    I’ve just scratched the surface of what’s available in this report and I highly recommend you read and share it with the DBAs at your company. The survey covers responses from folks in every size company and at every level of the database team. It is full of facts and observations that will be readily familiar to any DevOps enthusiast or practitioner. DBAs, IT, Developers, and the business are now all speaking the same language when it comes to DevOps. Do what you can in your organization to make sure they are speaking that language to each other.

    About the Author/Pete Pickerill

    Pete Pickerill is Vice President of Products and Co-founder of Datical. Pete is a software industry veteran who has built his career in Austin’s technology sector. Prior to co-founding Datical, he was employee number one at Phurnace Software and helped lead the company to a high profile acquisition by BMC Software, Inc. His ability to understand product demands from a customer’s perspective and translate those demands into actionable product and development plans has led to expanded duties at every company for which he’s worked.

  • Where is the DBA in the DevOps conversation?

    Where is the DBA in the DevOps conversation?

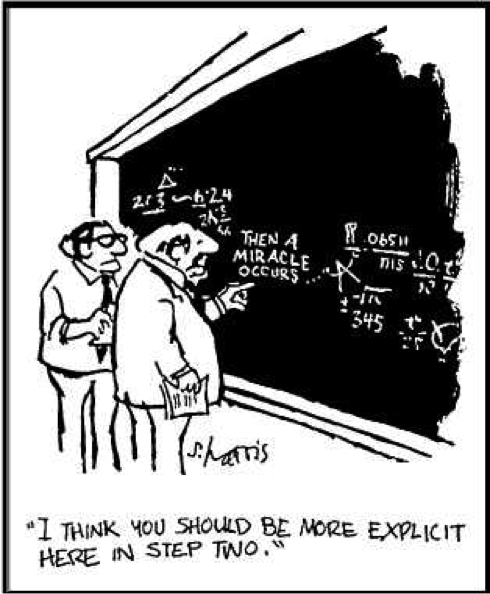
    dbapicIn reading case studies, surveys, and research articles on DevOps I am reminded of a cartoon I saw taped to my high school physics teacher’s file cabinet. Two scientists stand in front of a complex proof scrawled on a chalkboard. Separating steps 1 and 3 of the proof is the statement, “Then a Miracle Occurs.” One of the scientists points to the statement and says, “I think you should be more explicit here in step 2.”

    This is an apt metaphor for the DevOps zeitgeist’s avoidance of the database. ISVs and analysts spend a lot of time talking about how to streamline, accelerate, and automate application development and testing (Step 1) and how to monitor and automate the deployment of those applications (Step 3). But when it comes to managing the database change necessary to support the application and its release processes, it seems that everyone is waiting for that miracle to occur.

    This oversight is unfortunate. DBAs have a lot to offer when it comes to correlating the development of technology with the management of the environment in which it’s hosted. In a sense, DBAs have been DevOps all along.

    On the ‘Dev’ side, DBAs carefully evaluate each change request to ensure that it is well thought out, is compliant with organizational best practices and won’t have unintended consequences on database performance or the validity of dependent objects. They have developed and tested all of the SQL that has materially changed the database and crafted it into what it is today.

    On the ‘Ops’ side, DBAs have designed and provisioned the data platform. They are in charge of monitoring their databases and keeping them available and high-performing. They manage access to and the overall security of the platform. They perform release activities in support of the application and troubleshoot any errors that happen during that process or during day to day operation.

    So why isn’t the larger DevOps community including the data platform in the conversation? Why aren’t DBAs a crucial part of every DevOps team? Why are we relying on a miracle like the scientist in the cartoon?

    Every decision a DBA makes, every process or standard they put in place is influenced by the dual nature of their role. They are used to thinking about the impact of any task, requirement, or problem from both sides. It is deeply ingrained in them. They are deliberate and meticulous in their approach to change management because they understand that what they do has impact beyond what’s directly in front of them. They rely heavily on their expertise and their deep understanding of their organization’s data strategy to ensure they are making safe, future proof decisions to the best of their ability.

    This also explains why we haven’t seen the same proliferation of automation and orchestration solutions for the database that we have seen for other domains in the SDLC. True database automation has to be more than “run this script after that one” or “make this object look like that object over there.” To have a meaningful impact on your release throughput and staff productivity your database automation has to make use of your team’s intelligence. Any solution you implement has to harness the collective experience and knowledge of your DBAs and apply that knowledge to the evaluation of changes as they’re introduced in development. It has to be…miraculous.

    This is the whole reason we started Datical. When it comes to completing your DevOps vision, we wanted Datical to provide a real answer to Step 2 from that comic that has stuck with me all these years. Our flagship product Datical DB was designed and implemented to address the unique challenges associated with automating database changes in support of application releases. It automates and accelerates the propagation of database changes without sacrificing safety. We provide a highly customizable automation framework that is fueled by your experts. It allows you to define standards specific to your organization that are incorporated in our pre-deployment analysis. This greatly reduces the time spent manually reviewing SQL and checking the logic of your SQL scripts for errors that will cause application failures and downtime.

    About the Author/ Pete Pickerill

    High-Res-Peter-Pickerill-6571-150x150Pete Pickerill is Vice President of Products and Co-founder of Datical. Pete is a software industry veteran who has built his career in Austin’s technology sector. Prior to co-founding Datical, he was employee number one at Phurnace Software and helped lead the company to a high profile acquisition by BMC Software, Inc. His ability to understand product demands from a customer’s perspective and translate those demands into actionable product and development plans has led to expanded duties at every company for which he’s worked. In his time at Symantec, Pete worked directly with large financial services companies and online retailers to implement and improve online fraud prevention solutions that were used daily by millions of people worldwide. In addition to managing a development team and product schedule at BMC, Pete worked directly with large financial services institutions to provide the features they needed to achieve greater efficiency and cost savings in their application deployment processes.

  • Financial Sector Leading the Way with CD for the database

    Financial Sector Leading the Way with CD for the database

    The financial industry, especially banks, are still using a programming language that is over 50 years old. However, this doesn’t necessarily mean they are out of date, rather these giant institutions have found in some cases that their ancient systems just work. They are stable and secure software programs. But databases are not like static source code; they are always moving and changing. With the most important client information sitting in the database, it’s no surprise that banks and other financial institutions lead all other industries in adoption of Continuous Delivery methodologies for the database.

    A recent survey we conducted revealed that the banking and finance industry DBAs far outpace non-financial companies in terms of database Continuous Delivery adoption. Of the 55% of respondents not in the finance space practicing Continuous Delivery, only 49% said they practiced CD on their databases. When we asked banking and finance DBAs and managers, we found that over 70% utilize database automation for software and 64% of those also practiced CD for the database.

    These institutions are required to be agile in their database methodologies due to having such a large number of applications to deal with on a daily basis. Moreover, database errors that cause downtime are incredibly costly and financial institutions cannot afford to have any. Aside from the peace of mind that your database can run itself and adapt on the fly, proper database automation and version control can save financial institutions 80%-95% of time it would normally take to manually process changes and there is clear ROI when implementing Continuous Delivery.

    The economic effects of unplanned outages are prohibitive. According to a report by Gartner research, unplanned outages, on average, cost $42K per hour. When it comes to financial services companies, research shows the cost are much higher at about $110K per hour, the bigger the footprint that a company has, the more money it will lose when it fails.

    These statistics are one of the main reasons that we’re starting to see mainstream adoption of Agile and DevOps practices in finance companies. DevOps favors automating as many processes as possible and automation removes the potential for human error. By automating our processes, we allow machines to handle the redundant tasks freeing up the time and resources of skilled database professionals for more valuable and cost effective responsibilities.

    DevOps for Database, automation, control and enforced change management, provide confidence in the integrity and quality of the database code and virtually eliminates the potential that harmful database changes will find their way into production.

    About the Author/ Yaniv Yehuda

    Yaniv Yehuda, CTO, DBmaestro (http://www.dbmaestro.com/)

    Yaniv is the Co-Founder and CTO of DBmaestro, the leading provider of DevOps for Database solutions which enable control of database development and deployment. Yaniv is also the Co-Founder and the head of development for the Extreme group, a leading IT services solutions provider group.


  • SQL vs. NoSQL – Unsettled Debate & DevOps Pitfalls

    SQL vs. NoSQL – Unsettled Debate & DevOps Pitfalls

    Big Data, a relatively new phenomenon driving the industry hype-cycle is a mainstay in the database business. IT companies are convinced over the endless value proposition of the operational insight that comes with leveraging Big Data ( or Big Small Data ), so much so that it’s easy to overlook its impact on traditional database technologies and practices.

    (more…)

  • Walgreens reminds us to keep our database healthy

    Walgreens reminds us to keep our database healthy

    It’s clear that the super app you developed with your team, is really something, and it has high chance to be the “Bread and butter 3.0”, but are you prepared for the worst? There is a good chance that some combination of data, events and circumstances out of your control will eventually collude against you, to cause a failure or a software defect. You can try to anticipate and reason about all of the things that can go wrong with your application to prepare, but in a complex system it’s impossible to predict everything.

    (more…)