Tag: container

  • I Can’t Go to That DevOps Conference

    I Can’t Go to That DevOps Conference

    Last year, I was able to attend 18 DevOps conferences. I saw some awesome presentations, met incredible people and expanded my knowledge of the latest practices at each conference. While my role as the DevOps Advocate for Sonatype enables me to get out to all of these conferences, not everyone has the time, the budget, or the approval to get to even one event a year.

    DevOps for the Masses

    This is what led me and my colleague, Mark Miller, to found the All Day DevOps conference last year. Our dream was to build a DevOps conference for the masses. We decided to offer 57 online sessions over 15 hours and 15 times zones, and registration would be free. Our initial goal was to see if we could find 1,000 people to attend (because that sounded like a big number at the time), but the idea of a free online event caught a viral wind and we ended up having over 13,500 people register to attend.

    Every session delivered during the conference was shared by a DevOps practitioner. We had a simple rule for the conference and that was: no vendor pitches.

    Team Time

    People also told us that they valued having the chance to talk to other attendees they met at DevOps conferences, so we set up a free Slack channel for All Day DevOps. By the time conference was over, we recorded more than 10,000 conversations between the speakers, attendees and organizers.One of the things that fascinated us most about the conference was that organizations such as Accenture, Capital One, Ericsson, Oracle, Target, Telstra and many others had more than 20 employees attending the event. A few of these had hundreds. None of them needed to approve expenses for travel, hotels or conference fees. They just watched and joined in the conversations from their homes or offices.

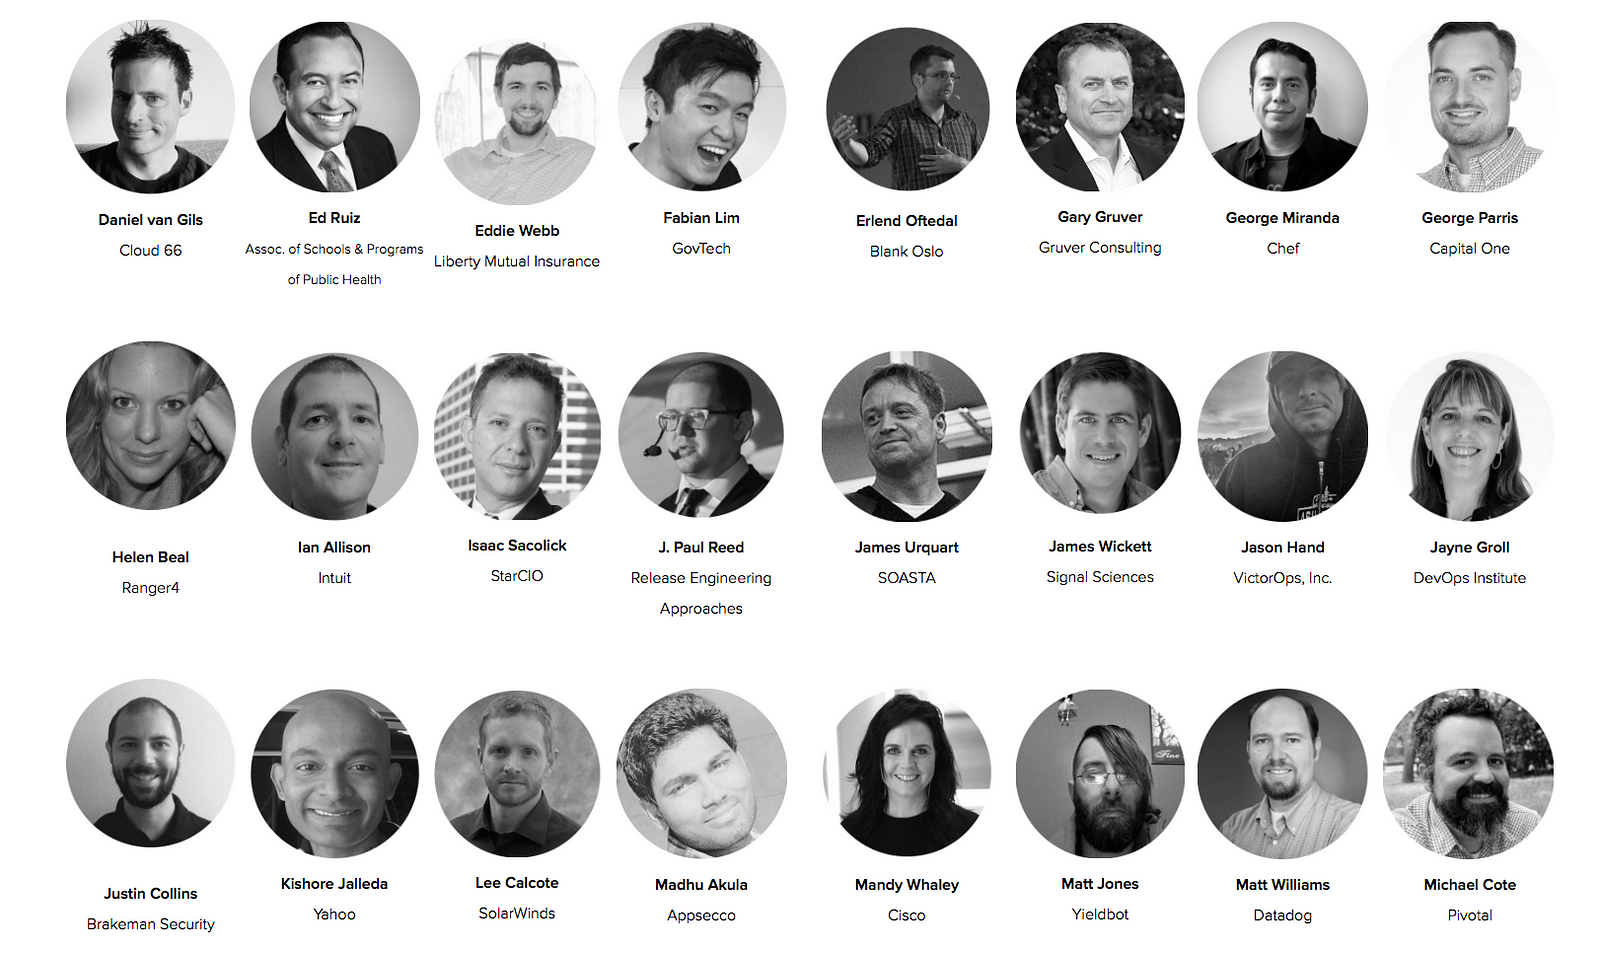
    Here are some of the folks who spoke at last year’s event across our CI/CD, Modern Infrastructure and Automated Security tracks. This year, we have also added a DevOps in Government track to the agenda.

    The event was so successful, we set it on the schedule again. All Day DevOps 2017 will take place Oct. 24. It’s online, it’s free and this year’s event will run for 24 hours. Therefore, no matter where you live, if you have an internet connection, you will be able to tune in to join us.

    A Few Things to Know

    1. You can register for free at www.AllDaydevopsy.kinsta.cloud. Invite your entire DevOps team to join. Everyone registering will have free access to all 57 recorded sessions from 2016.

    2. The CFP is open through May 31. If you have a story to share, we want to hear from you. Remember, no vendor pitches are permitted.

    3. All Day DevOps is a community event. Last year more than 40 DevOps meetups and software companies helped us spread the word. For those that helped, we added their logo to the site. Same applies to this year. Apply to be a supporter here.

    Please join us for this year’s event!

    Finally, a big thank you goes out to devopsy.kinsta.cloud, which helped us promote last year’s event to all of their readers. We are excited to have them helping us to promote the 2017 conference as well!

    — Derek E. Weeks

  • Native Docker for Windows Arrives: Are Containers Finally Serverless?

    Native Docker for Windows Arrives: Are Containers Finally Serverless?

    Is Docker finally ready for the age of serverless computing? That’s the message from the announcement this week of native Docker container support for Windows Server 2016.

    If you’ve been following Docker for a while, you know that Docker containers originally supported only Linux operating systems. Then, Docker made its platform available for Windows users, too—but with the major caveat that Docker Engine ran inside a Linux-based virtual machine image on top. So, you could run Docker from Windows, but Linux was still the middleman.

    Real Docker Containers

    This week, that all changed. On Sept. 26, Docker announced the general availability of native Docker container support on Windows Server 2016. By “native,” Docker means that the containers run using new primitives—the equivalent of namespaces in Linux—that are built into the Windows kernel itself. There’s no more virtualization.

    But that’s not all. The complete Docker tool set also now runs natively on Windows. The Docker CLI, Swarm orchestration, data volumes and all the other building blocks of a Dockerized infrastructure are officially compatible, as well as Docker containers themselves.

    The support is the result of more than two years of collaboration between Docker and Microsoft, which is now a Top Five contributor to the Docker open-source project.

    Caveats

    Native support for Docker is a big accomplishment. But there are still some limitations, including:

    • Docker containers can only run natively on Windows Server 2016 and Windows 10. Other versions won’t work with Docker because they lack the kernel enhancements necessary to support Docker containers, Scott Johnston, Docker COO, explained in an interview.
    • Some advanced networking configuration features for Docker are not yet supported because the “plumbing” required to make those features work is not complete inside the kernel, Johnston said, adding Microsoft is working to change that.
    • Most notably, Docker containers on Windows can only run Windows apps inside the containers. In other words, you can’t run an app compiled for Linux inside a Docker container running on Windows. You would need a Windows host to do that. (And the opposite holds true: You can’t run Windows apps inside Docker containers on a Linux host.) This is not something that will change, according to Johnston.

    Docker Becomes Serverless

    Docker the company is celebrating the support as an opportunity to expand the Docker ecosystem immensely. Support for Windows “doubles the potential market opportunity” for Docker partners, the company said in a presentation about the announcement. (By the way, Docker has good reason to want to keep its partners happy by giving them a larger ecosystem to work with. The integration of Swarm into Docker earlier this year undercut the value of some of Docker’s partners’ products. But I digress.)

    The most interesting aspect of this news from a DevOps perspective, however, is that it means Docker is now much more serverless. A large part of the value of Docker containers is their ability to simplify application delivery. As long as you can package your app as a Docker container, you can deploy it on any server that has Docker running.

    You don’t have to think about the underlying server hardware or configuration. In other words, Docker allows you to become serverless, because you no longer have to think very much about the server you are deploying to.

    Previously, however, this flexibility was limited by the fact that you did have to think about the server OS. Now, with native Docker support for Windows, that’s no longer the case. It doesn’t matter whether your infrastructure is composed of Windows servers, Linux servers or both. As long as you install Docker on them, you can deploy to any server.

    Of course, there is still the issue of having to make sure your app is compiled for the right operating system. But that is easy enough to manage in most cases during the build process.

    — Chris Tozzi

  • Industry Leader HyperGrid Debuts HyperForm For Microsoft Windows Server Containers

    London, UK. – September 26, 2016, HyperGrid, the pioneer in creating and delivering the world’s first and only container based, application aware HyperConverged Infrastructure-as-a-Service (HCIaaS) solution today announced that HyperForm, their platform that provides next-generation IT services built on Docker containers, can now support the automated deployment and life-cycle management of applications running on Microsoft Windows Server Containers.

    With support for Microsoft Windows Server Containers, the HyperForm platform now provides the following features:

    • Automated provisioning of Windows Server 2016 virtual machines (with pre- installed Docker & HyperForm Agent) on any cloud (including Microsoft Hyper-V and Microsoft Azure). Once the machines are provisioned, users can get access to a wide range of day-2 operations including:
      • Stopping or restarting the VM
      • Accessing an in-browser terminal through a secure message queue for command line access,
      • Performing historical monitoring analysis based on metrics like CPU, Memory, and Disk Utilisation,
      • Executing custom plug-ins using PowerShell scripts to make configuration updates or apply patches, and
      • Receiving alerts whenever the performance exceeds a pre-defined threshold or is stopped.
    • Automated building of Windows Container images for running Windows applications
    • On-the-fly Containerisation that allow users to deploy existing .NET applications on official base images like Microsoft/Windows Server Core and Microsoft/Nano Server while taking care of the complex application dependencies, service discovery, application storage automation and the post-provision updates
    • 
Life-Cycle Management of applications running on Windows Containers with access to monitoring, alerts and notifications, continuous delivery using Jenkins, application backups, scale in/out, in-browser terminal to access the containers, log viewing, and container updates using custom plug-ins written in PowerShell.

    “Containers have been the driving force behind efforts to accelerate software development and enable DevOps. With the General Availability of Windows Containers, .NET developers can finally reap the benefits of agility and application portability to speed up application development and deployment,” said Amjad Afanah, Vice President of Products, HyperGrid. “We’re excited to be delivering on-the-fly containerisation and deployment automation for applications on Windows Containers to turbo charge DevOps and accelerate the journey of .NET applications to containers.”


    About HyperGrid
    HyperGrid delivers IT at the flip of a switch:
    A revolutionary new concept HyperConverged Infrastructure, HCI-as-a-Service (“HCIaaS”) is the industry’s first and only container-based application aware offering that brings the simplicity and ease-of-use of HCI together with a pay-as-you-consume pricing model that scales elastically. HCIaaS delivers “one-click” automated application deployment and management seamlessly across any cloud or container infrastructure. Enterprises can now enjoy all the benefits of the public cloud at better rates without fear of vendor lock-in. HCIaaS solves the key challenges of DevOps for Enterprises – allowing for both traditional and cloud-native applications to be containerised, managed and deployed with a single tool, dramatically simplifying IT and bridging the needs of both developers and IT operators. HyperGrid solutions unleash innovation for the Digital Enterprise. HyperGrid is headquartered in Mountain View, CA. and its products and services are available through a global network of value-added resellers and partners.

    — Jules Louis

  • Test-First Development: Processes and Tools for Success

    Test-First Development: Processes and Tools for Success

    A lot of software development teams are talking about “test-first” methodologies. The practice involves moving testing up into the very earliest stages of development so automated tests can be written before code. Making this seemingly minor shift can result in much higher quality software and greater efficiencies. Integrating development and testing avoids needless late-stage bugs and complicated redevelopment efforts. It can help software development organizations focus on usability and features and achieve faster time to market. And because of test-first’s reliance on automated tests, organizations gain reusable tests, saving time and increasing standardization for testing and quality assurance overall.

    It’s no surprise, then, that 51 percent of organizations have begun using test-first methodologies, including 37 percent in the past year, according to a recent global survey of 200 software testers conducted by our company. But, despite the enthusiasm for this practice, there are concerns: 44 percent of survey respondents said their biggest fear about moving to this approach was forcing developers to contribute tests prior to completing code, while 19 percent said they worried about removing traditional testing checkpoints on the way to production. Other barriers include the lack of standard practices or tools. That said, test-driven development promises to bring ample benefits to software development teams, the business and, importantly, customers.

    Test-first development is recognized across three broad terms today: behavior-driven development (BDD), test-driven development (TDD) and acceptance test-driven development (ATDD). TDD is an umbrella term for the practice, although it has traditionally focused more on technical, unit testing. BDD and ATDD incorporate user requirements and business benefits along with technical testing. BDD differentiates through its adoption of specific automation frameworks and language for writing and running tests.

    Key Changes for Successful Test-First Development

    Getting started requires change across a few critical areas for most teams. First, evaluate your team for hiring and skills training needs. On the one hand, developers will need to learn basic testing skills, so they can write good tests and run tests before they develop code. Meanwhile, testers must become more proficient in automated testing tools, which usually entails acquiring a fundamental knowledge of programming. Many companies will need to hire key contributors from outside; in which case, leaders should look for well-rounded individuals with past experience using test-first methodologies successfully. An individual who is an expert at one skill, or who is too independent and can’t collaborate well, won’t be an ideal member of a team experimenting with test-first approaches. Leaders also may need to adjust by balancing the ranks more closely between developers and testers so that one group doesn’t rule over the other. Hiring additional experienced testers frequently will be necessary.

    Training of existing staff is paramount, best achieved through a combination of methods including internal training, mentoring, online courses and paired development, where developers and testers can sit side by side and collaborate. More than half of the survey respondents said developers and testers would be jointly responsible for automation test creation within their organizations.

    Beyond cross-training, the cultural challenge of moving to test-first methodologies can be overwhelming. It requires the development of incentives for creating quality products, not just delivering new features at speed. It requires an appreciation and respect for the practice of testing. Unfortunately, testing too often is viewed as a necessary cost of doing business, rather than bringing a clear benefit to the organization and its customers. That mind shift is not only inaccurate, but it doesn’t fly with progressive, Agile thinking. It will take strong leaders to help traditional teams understand the need to change and modernize practices. A leader may forego the buy-in process and instead decide to lay down the law to staff: Staff must move to TDD or BDD, or else. But the results won’t be ideal. Smart developers will find loopholes, such as writing tests that aren’t comprehensive or fully aligned with project goals, so the code will pass more quickly.

    On the process front, organizations that have moved or are moving from Waterfall to Agile and DevOps will have an easier time adopting test-first methodologies. In fact, it’s pretty difficult to implement test-first processes and tools in a Waterfall environment because of the siloed nature of functions and the long release cycles. The survey results support this premise: 55 percent of respondents said their testing process was Scrum/Kanban-driven before transitioning to test-first, while 21 percent said their approach was iterative-requirements driven and 18 percent was Waterfall-requirements driven.

    Along with that shift, test-first teams will need to adopt new metrics that align with this new way of doing business. Instead of looking solely at velocity, development leads should measure how long it takes the team to move a product from feature approval to code release. With a focus on quality and testing, companies also should measure and improve upon bugs, such as number of severe defects post-production. Those types of business and customer-oriented metrics align with the new set of Agile metrics that that many teams are working for today.

    Test-first teams will need to adopt DevOps toolsets, which are designed to push code out to the pipeline faster. Specific technologies that go hand in hand with test-first development include:

    • Continuous integration (CI) platforms such as Jenkins and Team City, to assist in running the automated tests immediately for quick build feedback.
    • Container technology for rapid deployment of test and pre-production environments, to capitalize on having features production-ready soon after coding.
    • Test management platforms including qTest Scenario or Cucumber Pro.
    • Test automation frameworks including Cucumber, SpecFlow , and other open source tools which enable easier support for customization and collaboration.

    There’s a lot to think about when moving toward test-first development. While it may seem overwhelming at first, all of this is achievable in a reasonable time frame if you have the right dedicated resources to see it through. One-third of survey respondents said it took them less than three months to complete the transition to a test-first approach, while 30 percent said it took less than one year. The payoff for software teams, in terms of improving quality, customer experience and reducing costs of innovation, can deliver higher customer loyalty and even faster growth in the marketplace.

    About the Author / Kevin Dunne

    Kevin Dunne picKevin Dunne is vice president of Business Development & Strategy at QASymphony.


  • Do You Continuously Deliver Your CD Pipeline?

    Do You Continuously Deliver Your CD Pipeline?

    If your job is to build and maintain the continuous delivery (CD) pipeline for your organization, do you feel you can’t keep up with your development counterparts in innovation? Everyone is raving about the new cool features in your company’s product. Who deserves the credit? People who wrote the code, right? It’s not that simple. Churning out new features requires a sound process and solid infrastructure. A well-designed CD pipeline is crucial to the developers’ success. It mitigates the inherent risks in a fast-paced, frequent iteration regime now prevalent in agile software shops. On the flip side, as software gets more and more complex and the appetite for a faster time to market grows, opportunities for innovation are in abundance for DevOps teams.

    Multi-speed IT

    So you’ve got two tactical teams with significantly different risk-reward equations, working at a different pace due to distinct objectives but marching toward the same strategic goal. You’re finding yourself in a multispeed IT environment. Development is focused on innovation and quick frequent iteration cycles. DevOps’ primary focus is to ensure the stability of the CD pipeline and keep a precise track record of what takes place inside the pipeline every step of the way. How do you make sure to stay ahead of the technological curve while minimizing risk?

    Based on my experience on both sides of the DevOps isle, I recommend the following four steps to successfully build and maintain a continuous delivery pipeline:

    1. Automate, Automate, Automate!

    My personal motivations for rolling up my sleeves and scripting a task are:

    • It became an annoying, mindless routine;
    • It’s no longer a one-time thing and isn’t going away;
    • My time can be spent on more important things; or
    • I make mistakes and then waste time fixing them.

    As with any type of code, organize the scripts into a sound logical structure easy to navigate and version-control it. You can always revise the code or completely rewrite it as the needs evolve.

    2. Treat Automation Code as a First-Class Citizen

    That’s right! As a practitioner, I learned the hard way that automation starts innocently small and simple. Then the requirements for more automated functionality begin to pile up rather quickly and things quickly become really messy. So write high-quality code from the get-go and reassess the design and implementation every step of the way. Remember that the visibility of your code is very high.

    Apply the same standards to your code as your peer development teams do to theirs. Write tests—unit, integration, functional, end-to-end—as appropriate. Use the same CD pipeline to automatically build, package, deploy and test your automation code. This will give your pipeline another round of validation, your code will be of a much better quality, and your team’s credibility and reputation will soar.

    3. Containerize the CD Pipeline Components

    In the past, because the CD pipeline components such as build servers were manually provisioned, they often became the single points of failure, which made it hard to plan and roll out the modifications to homegrown, open source and commercial tools. It wasn’t unusual for some components to fall behind the latest release by a full year or more. In the meantime, a year’s worth of updates and patches could address a litany of issues, but the need for a maintenance window, usually on a weekend, and the uncertainty of the outcome often would outweigh the sought-after benefits. Containerizing the CD pipeline component can be the solution. Running a build server in a container, for example, will make it a lot easier to create an exact copy of the production version in a test environment and iron out the upgrade process more thoroughly ahead of the upgrade.

    4. Test Commercial Tools

    Commercial and open source projects test their software, of course. However, it could make a whole lot of sense for your organization to create your own integration, end-to-end and performance tests for the software you don’t write—especially if the software has a plug-in architecture like Jenkins or UrbanCode Deploy and you use community or homegrown plugins. Commercial tools typically don’t provide any guarantees that those plugins will work after the upgrade. Running your own automated tests that exercise the functionality of the tool in your environment and on your specific data gives the opportunity to validate updates as they become available and identify any regressions proactively.

    The objectives of DevOps are not only to identify and eliminate the existing bottleneck in the organization’s continuous delivery process, but also to look out for any future potential bottlenecks and proactively address them before they become real issues.

    So your team is DevOps. Your product is a CD pipeline. How do you continuously improve the CD pipeline for your product?

    If want to learn more about how to effectively build and maintain your continuous delivery pipeline, please check out the newly released 2nd edition of the “Application Deployment and Release for Dummies” eBook.

    About the author / Alex Seriy

    Alex Seriy

    Alex is an accomplished technologist and DevOps evangelist with over 25 years of experience under the belt. He is an automation enthusiast and usability guru, passionate about uncovering new use cases and innovating applications for platforms, frameworks and tools. At IBM, Alex is a subject matter expert in Continuous Integration, Delivery and Testing. He currently focuses on integration testing in the API Economy through service virtualization. Prior to joining IBM, Alex served as the Senior DevOps Architect at TIAA-CREF for 4 years. Before that, he was a consultant specializing in SCM, Release Engineering, QA and DevOps for over 10 years.

    Connect with Alex on LinkedIn / Twitter

  • Sysdig raises $15 million in Series B funding to expand container monitoring for enterprises

    Sysdig raises $15 million in Series B funding to expand container monitoring for enterprises

    The container­native monitoring company surpasses 100 enterprise customers

    San Francisco, CA ­ DATE ­ Sysdig, the container­native monitoring company today announced a $15 million Series B funding round by existing investors Accel and Bain Capital Ventures. Sysdig will use the funds to accelerate growth, to continue building out its core technology for container and microservice environments, and to scale its operations and world­class support infrastructure to meet growing demand.

    “Containers are the building block for microservices, and represent the next great platform shift for software developers in enterprises of all sizes,” said Loris Degioanni, CEO and founder of Sysdig. “While containers deliver efficiency and agility for developers, they introduce additional complexity for monitoring, troubleshooting, and operating production environments. Sysdig was born to address these specific needs for containers and the microservices built on top of them.”

    According to a recent survey, 81 percent of respondents expect their companies to increase the investment in container­based technology. Respondents ranged from industry verticals including retail, banking/finance, manufacturing, and Internet infrastructure.

    Accel Partners and Bain Capital Ventures co­led this round of funding. “Containers will address the majority of use cases that heavier virtual machines do today, plus more that virtual machines cannot,” said Salil Deshpande, Managing Director at Bain Capital Ventures, who joins the board of Sysdig. “What’s needed now is software that natively understands containers, applications running within them, and services built on top of them. Sysdig has all of these capabilities and more.”

    Sysdig Cloud is based on sysdig, the open source troubleshooting tool that has been downloaded by hundreds of thousands of developers, devops, and sysadmins around the world. Its patent‐pending ContainerVisionTM technology provides deep, request‐level visibility inside containers without invasive instrumentation. This approach succeeds for container monitoring where legacy monitoring fails, and at the same time makes monitoring applications and microservices simpler and more robust.

    Company sails past 100 enterprise customers

    “The service and support I’ve received from the Sysdig team was really impressive. I encourage anyone looking to run containers in a production environment to talk to them first.”
    ­ Branden Makana, Senior Software Engineer, CDK Global

    “From exploration down to deep system captures, Sysdig has a complete approach to monitoring containerized environments.”
    ­ Zachary Smith, CEO of Packet

    In less than 8 months since general availability, Sysdig has passed 100 enterprise customers. More than a third of those have signed up in this year alone. These customers represent a broad range of industries and company sizes. For example:

    • ●  Industries such as finance, healthcare, media, telecommunications, technology, and consulting are using Sysdig Cloud
    • ●  Multiple Fortune 500 companies
    • ●  Companies from North America, Europe, and Asia­Pacific are adopting thesolutionCustomers are adopting Sysdig cloud for the ability to monitor production environments that require deep visibility into not only containers but also the microservices built on top of them. Chris Crane, VP of Product at Sysdig noted, “Our strategy combines container­native monitoring with native integration across ecosystem players like Docker, Kubernetes, and Mesosphere, as well as cloud providers like AWS and Google. These native integrations customers service­oriented visibility, and the flexibility to choose the right mix of tools for their environment.”

      About Sysdig

      Sysdig (Twitter: @sysdig), the container­native visibility company, is creating a new generation of performance management solutions to deliver monitoring, alerting, and troubleshooting in a microservices­friendly architecture. The company’s open source sysdig technology has attracted a community of hundreds of thousands of developers, administrators and other IT professionals looking for deep visibility into systems and containers. Sysdig Cloud is the first and only comprehensive, container­native monitoring solution for applications and infrastructures.


  • 3 golden rules of microservices deployments

    3 golden rules of microservices deployments

    As a developer, you value the principles of SOA. You aspire to build applications as a set of consumable services via endpoints. Remember how Amazon used SOA to build the AWS platform and how Google is emulating AWS? However, not all is hunky-dory in the SOA world.

    Developing is one thing but running, managing, and maintaining services is a whole other beast. When it comes to the latter, many enterprises still act monolithic. They run and manage applications services as a unit on one or many servers. This approach fails to scale when the services themselves scale or when you need to update and maintain them regularly. So do you lament over the spiking costs and time spent on these efforts or fix the problem?

    Recent trends point to microservices as the answer. By definition, microservices are much smaller than services. In fact, Wikipedia says a microservice performs a small task often just one. There are many articles that go in deep about microservices architecture, but we cover an important part here, which is deployment automation. In other words, our daily job.

    The self-contained, independent, and reusable principles of microservice architecture help solve the problem of scaling and maintaining application services.

    • Self-contained. Microservices are standalone operations that run without requiring other services. That means each runs on its own. You can scale each up or down and replace a service individually instead of updating the entire monolith given the business need and load.
    • Reusable. Microservices are self-contained so you can reuse them for other applications and functions. We’re talking of reusing already deployed microservices.
    • Independent. Microservices are platform agnostic, which means you can design them independent of infrastructure needs to run anywhere, in any cloud.

    So is it easy to shift from SOA-based architecture to microservices? Adopting microservices is not without challenges. To name some, you need to modularize existing software services as self-contained units, you need to configure the microservices to communicate with each other, and you need lots of deployment and test automation.

    To address these challenges out of the box, we recommend a DevOps solution like ElasticBox. Take a look at how ElasticBox supports microservice deployments.

    1. Modularize self-contained microservices

    The box model in ElasticBox wraps each microservice as a standalone component in a service catalog that you can reuse across applications. A script box automates the lifecycle of microservices using Bash, Puppet, Chef, SaltStack, Ansible, PowerShell; a container automates Dockerfile deploys; a CloudFormation box automates AWS resource stacks.

    2. Connect microservices via bindings

    More microservices means more endpoints to manage. Such endpoints handle REST or other protocol communications over the network. With ElasticBox bindings, network references are as easy to manipulate as programming variables. Want to route database connections to another MySQL service? It’s easy to do. Just point the services to deploy with a different binding value.

    3. Deploy microservices independently

    Boxes are inherently agnostic. Put infrastructure metadata for CPU, memory, storage, additional disks, virtual networks, firewalls, load balancing, and autoscaling in deployment policies attached to a cloud service like AWS, Google cloud, and more. Policies help you deploy the microservices defined in the script boxes to any platform and cloud. The orchestration engine in ElasticBox interacts with the cloud APIs to auto-provision virtual machines based on metadata from deployment policies. So it’s easy to spin up and destroy microservices on demand without disrupting service availability.

    ElasticBox can simplify microservices deployments. For instance the Jenkins ElasticBox plugin continuously integrates ElasticBox automation with Jenkins jobs to test and deliver what the software developments teams build continuously. So the next time you think SOA, think microservices instead.  Feel free to check out how ElasticBox can help.

  • Linux Containers & Security Implications

    Linux Containers & Security Implications

    Does the word “container” intimate containment, suggesting that containers are inherently secure? If it does, any such assumption of security may be the broadest Docker vulnerability to date.

    aaron cois“One of the biggest threats I see with Docker is its positioning and the implied security in the language. The reality is that these containers don’t contain anything,” says Aaron Cois, Researcher, CERT Division, Software Engineering Institute, Carnegie Mellon University. Yet, that is the implication.

    Just as those who thought Linux or VMs were secure enough on their own were mistaken, so those who believe that containers put a lid on security will be sorely disappointed. Today, Linux environments require network, OS / host security, Internet security, and web application security measures similar to those used with other platforms. Tools like security auditing / PEN testing, firewalls / WAFs, anvi-virus and anti-malware tools, DLP, IDS/IPS, remediation tools, and really the gamut of security measures similar to what Microsoft environments require are increasingly needed to defend data in Linux environments. “Likewise, operations can give developers tools to log into the VSphere console to create and change VMs while limiting their privileges,” says Cois.

    And so, containers also require appropriate security measures. “Developers and non-admin operations staff don’t need to log into the host command line to work, and no one in security wants them to,” says Cois. But today’s Docker workflow not only permits but requires it.

    The Root of the Problem…


    –THIS STORY HAS BEEN MOVED TO CONTAINER JOURNAL–


  • Copying Data From One Docker Container to Another

    Copying Data From One Docker Container to Another

    Docker containers can easily be compared to a directory. A Docker container holds everything that is required for an application to run including its dependencies and can be started, stopped, moved and deleted at will. When containers are activated they use Linux kernel namespaces. Each container operates in isolation from the server apart from networking and storage. Each container is created from a Docker image and one can have multiple containers running, depending upon the server hardware capacity. Docker containers are the run component of Docker.

    What are Docker images?

    Each Docker container is created from a Docker image, which can be built either by executing commands manually or automatically through Dockerfiles. Images can be basic either consisting of the operating-system fundamentals or a pre-built stack ready for launch. They are read only templates and consist of series of layers, so any new action or update leads to the addition of new layer on top of the previous one rather than replacing whole image entirely. This is how a new container is made.

    Copying data from one Docker Container to another:

    Copying of data from one container to another is essential and most important feature of Docker containers. Copying data to another container means having a backup that could be used if any kind of disaster occurs out of any situation in real time scenario.

    Using Data Volume Containers:

    Data volume is a directory available to a container but it is located outside of its root file system. Sharing data between the containers allows volume to bypass image layering. Any changes in the data are made directly, containers have dedicated directories in the /var/lib/docker directory and volumes are stored separately in/var/lib/docker/volumes/ by default. –v option of docker run can be used to copy volume data between the two containers.

    How to copy content from one container to another -An Illustration

    In this example we assume that Docker is running two instances of data volume container image mymod/dvc: v1. Following are the commands that are used to start the container

    # docker run –d –name dvc1 mymod/dvc:v1

    # docker run –d –name dvc2 mymod/dvc:v1

    Now to copy data to the host and to even mount the volume from another container, use cp command to copy data

    [root@host ~]# docker run –rm –v /var/tmp:/host:rw  \ –volumes- from dvc1 cp –r/var/www/html/host/dvc1_files

    The container mounts the host directory /var/tmp read-writable as /host, mounts all the volumes, including/var/www/html, that dvc1 exports, and copies the file hierarchy under /var/www/html to /host/dvc1_files, which corresponds to /var/tmp/dvc1_files on the host.

    Now to copy data from dvc1 host to another data volume container we use following command

    [root@host ~]# docker run –rm –v /var/tmp:/host:ro –volumes-from dvc2 \ cp –a –T /host/dvc1_files /var/www/html

    The container mounts the host directory /var/tmp read-only as /host, mounts the volumes exported by dvc2, and copies the file hierarchy under /host/dvc1_files (/var/tmp/dvc1_files on the host) to /var/www/html, which corresponds to a volume that dvc2 exports.

    Another method with which one can copy data is ADD command, a Dockerfile command. Source and destination form the two arguments for ADD command to run successfully. It copies the files or data from the source container into the destination container with its own filesystem.

    Conclusion:-

    Docker will certainly expose nicer ways to grow container service to support wider deployment platforms and the community is surely expected to build service layers around. Development of core capabilities, cross service management and messaging between the containers are the paths set by Docker. We’ve tried to demonstrate via this article that data can be copied and replicated in another Docker container thus can be used in any case of disaster as well as recovery. Docker provides the ability to easily differ containers. It improves debugging, fast sharing of the environment and quick deployment. Docker has an ability to put the containers directly from Dev or QA onto AWS. User can share data through volume containers, mount host directories to containers or even can export data from containers to archive files thus very flexible.

  • Shooting a Rocket Over Docker’s Bow

    Shooting a Rocket Over Docker’s Bow

    As momentum continues to build for the Docker containerization platform, some of the open source project’s biggest contributors argue that it has lost its way. Priorities have shifted at Docker from the ideal of building a standard container to instead supporting an entire containerization ecosystem. According to the developers at Linux disto company Core OS, it’s this move has left the entire Docker process “fundamentally flawed.” It’s why they announced this week a competing container runtime called Rocket that they hope will become the “simple composable building block” they’d originally envisioned Docker would be.

    “Unfortunately, a simple re-usable component is not how things are playing out,” wrote Alex Polvi of CoreOS in a blog about the launch. “Docker now is building tools for launching cloud servers, systems for clustering, and a wide range of functions: building images, running images, uploading, downloading, and eventually even overlay networking, all compiled into one monolithic binary running primarily as root on your server.”

    That’s an inherently risky prospect for security-conscious organizations, Polvi argues. What’s more, as Docker starts moving toward expanding the capabilities of its platform it will only increase its complexity and diminish its ability to integrate containers elsewhere. Which is why CoreOS is leading the charge for Rocket. Introduced as a prototype on GitHub this week, Rocket is a command line tool designed to run what it calls ‘App Containers.’ These can be a specification of an image format, container runtime or discovery mechanism.

    “Rocket is the first implementation of an App Container, but we do not expect it to be the only one,” Polvi says. “An open specification allows other systems do their own implementation of App Container without using Rocket at all. CoreOS fully supports and embraces alternative implementations.”

    It’s a big move considering that the company’s co-founder and CTO, Brandon Philips, is a huge Docker contributor and on the Docker governance board. However, CoreOS argues that the clients that run Docker on CoreOS are clamoring for something with the kind of flexibility that Docker seemed to promise early on.  So while CoreOS will continue to support Docker long into the future it hopes Rocket can help solve some problems that many of its clients have with the platform.

    “Our primary users have existing platforms that they want to integrate containers with,” Polvi says. “We need to fill the gap for companies that just want a way to securely and portably run a container.”

    Polvi says that as CoreOS designed Rocket around four major factors that its team believes are key for good design of a standard container. First, it should be independent and composable. Second, container images should be designed for easy, distributed retrieval. Third, it should be open so that independent implementations of tools can run in the same container consistently every time. That’s why CoreOS says that it’s developing an open specification so that other systems can implement an App Container without even using Rocket.

    And, fourth, security should be tantamount.

    “Isolation should be pluggable, and the crypto primitives for strong trust, image auditing and application identity should exist from day one,” Polvi explains. “Security primitives are very important to us, so we added an identity feature to the meta-data service. This means every instance of a running container is given a unique identity, coupled with a lightweight HSM-like service for signing.”

    This is a new approach for container environments, so CoreOS is especially seeking community feedback for this design. However, the entire project is essentially ready and waiting for community support. Those interested should  out the details on GitHub.