Tag: Configuration Management

  • Cloud Drift Detection With Policy-as-Code

    Cloud Drift Detection With Policy-as-Code

    Cloud configurations can change and change often. Introducing new technologies, releasing new features and supporting new business requirements entail a constant flow of configuration changes in web application development.

    However, drift occurs regardless of how well-designed your IaC implementation is. The term “drift” is used to denote a state in which the actual state of your infrastructure deviates from the configuration.

    This article examines cloud drift detection, why it occurs and how to remediate it.

    Understanding the Problem

    Cloud configurations are prone to change and can change frequently. Businesses often use infrastructure-as-code (IaC) to manage cloud provisioning changes. IaC makes it easier and more reliable for organizations to manage and facilitate changes to the cloud deployment process.

    However, inconsistencies in your IaC deployment process can lead to uncertainty about how and where your resources are provisioned, controlled and protected, resulting in lower productivity. No matter how robust your IaC implementation, drift can creep in.

    Changes to infrastructure that are made independently of the code responsible for provisioning can lead to considerable drift, and if not adequately monitored, can lead to significant security concerns.

    What is Drift?

    In the context of infrastructure and application management, drift refers to the system state in which the actual configuration and state of the system deviate from the intended or expected configuration and state.

    Drift can be caused by software updates, manual changes and incorrect configurations. Drift management is an essential aspect of infrastructure and application management. By detecting and correcting drift, organizations can ensure that their systems remain stable, secure and compliant with their policies and industry standards.

    Configuration Drift: Definition, Causes and Examples

    Configuration drift can creep in over time despite consistently building and configuring your servers. It refers to the state of the system when configuration changes are not in sync with the value previously set.

    For example, configuration drift can occur when you are yet to document the changes made to the production environment. This results in the production and staging environments getting out of sync.

    Some of the other causes of configuration drift are configuration changes because of applying patches and updating network equipment, the addition of new resources to the network and lack of clarity about the desired state of the system.

    You can leverage configuration drift management tools such as Netwrix and Aqua to detect configuration drift.

    Infrastructure Drift: Definition, Causes and Examples

    Infrastructure drift refers to a phenomenon in which the actual state of the infrastructure differs from its desired state because the defined configuration, settings or properties of the infrastructure and the actual state of the provisioned resources differ.

    Infrastructure drift may result from manual changes, updates outside of configuration management processes, conflicting IaC code, changes in network configurations, changes due to security settings and configuration differences during system upgrades and maintenance.

    To detect infrastructure drift, you can take advantage of infrastructure drift detection tools such as Terraform, CloudQuery and driftctl.

    Infrastructure Drift and Configuration Drift: How do they compare?

    Both configuration and infrastructure drift can lead to security vulnerabilities, compliance issues and operational challenges. Although infrastructure drift and configuration drift are related, they aren’t the same.

    Infrastructure drift refers to inconsistencies or discrepancies between the intended or desired state of the infrastructure and the actual state of the resources provided. Configuration drift refers to inconsistencies or discrepancies between the current configuration of a component or system and the intended or desired configuration.

    Infrastructure drift encompasses everything from physical components to virtual components to networks, storage and computing resources. Configuration drift, on the other hand, focuses on individual components or systems within the infrastructure and their configuration settings.

    What is Drift Detection?

    Drift detection in the context of cloud infrastructures typically compares the actual state of resources deployed in the cloud environment with the defined state described in IaC templates.

    Typically, this is automated by tools, scripts or services that analyze and compare configurations, resource states or event logs. These tools are adept at issuing notifications or alerts when discrepancies are detected.

    By detecting discrepancies, organizations can identify and resolve inconsistencies, security vulnerabilities and compliance violations. Consequently, the risks related to security breaches are reduced and remediation actions become easier to implement.

    Why Policy-as-Code for Cloud Drift Detection?

    Policy-as-code provides several benefits when used for cloud drift detection:

    • Early detection of drift: Policy-as-code helps detect drift early detection by comparing the current state of the cloud environment with the desired state defined in the policies. This helps identify problems and solve issues before they escalate to a catastrophic level.
    • Automated enforcement: Policy-as-code enables automated enforcement of policies, ensuring that the cloud environment complies with the defined rules and requirements. This helps reduce the potential risks associated with human errors.
    • Faster remediation: Policy-as-code enables faster remediation by automatically detecting drift and taking the necessary remediation actions such as rolling back changes, updating configurations or notifying relevant teams. This facilitates faster response times and reduces the risks associated with security breaches and downtime.
    • Enforce best practices, policies and guidelines: With policy-as-code, best practices, policies and security guidelines can be implemented automatically, reducing security and compliance risks.

    Steps for Drift Detection Using Policy-as-Code

    Here are the steps that you need to follow to detect and fix drift in your infrastructure:

    1. Define your policies: You should first define the policies that should be used to describe the desired state or the baseline of your cloud environment and cover security and compliance aspects of your cloud environment.
    2. Codify and deploy policies: Then these policies should be codified and stored in the version control system. The next step should be to deploy the policies to your cloud environment using a policy engine.
    3. Identify configuration changes: Once your policies have been deployed, the next step should be to identify any new resources that may introduce risks and compare them to the baseline you’ve defined.
    4. Evaluate and remediate: You should evaluate the state of the environment against the defined policies to detect any drift. As soon as any drift is detected, you should take corrective actions to remediate the issues by rolling back changes, updating configurations or notifying the relevant team members.
    5. Review policies: To ensure that the policies are up-to-date and relevant, it is imperative that you review them often and make changes to policies as needed.
    6. Update and deploy: The last step should be to update the code files and then deploy the solution yet again.

    Build a Successful Drift Detection Strategy

    Maintaining your infrastructure at the desired state, ensuring compliance and mitigating risks associated with configuration drifts requires a successful drift detection strategy. Here are key strategies you can adopt to build a successful drift detection strategy.

    Understand When Drift Becomes a Risk

    Drift can profoundly impact a system’s stability, security and compliance. When your server configuration deviates from its intended configuration, it might stop working or become vulnerable to security threats.

    Most importantly, this might be a significant threat to security if you don’t have proper monitoring in place. To prevent infrastructure drift and update your security tools, it is important to evaluate and communicate your adoption of IaC.

    Detecting Drift: Detecting drift Between IaC and the Cloud

    To mitigate the risks associated with drift, configurations that have been changed in real-time must be identified and reset. You can achieve this programmatically and continuously by comparing configuration changes between IaaS and IaC. Programmatically identifying the configuration changes, i.e., detecting the changes to the configuration using code, is the best strategy to reduce drift-related risks.

    From Drift Detection to Drift Remediation: Responding to drift

    By detecting drift, you’ve won half the battle–you should now devise strategies to remediate it. By keeping an eye on configuration drift and responding to it promptly, you ensure the consistency and reliability of your infrastructure, minimize security risks and keep your system in a consistent state.

    Figure 1: Detect and Remediate Drift in the Cloud

    It’s important to have effective configuration drift response procedures in place to ensure the stability and security of your environment and also keep it effective for change management and control. You can respond to drift in the following ways:

    • Develop mechanisms to detect and report configuration drift
    • Understand the underlying causes of drift
    • Documenting the drift, including affected resources, configuration deviations and impacts
    • Resolve the configuration drift and return the system to the desired state
    • Following change management processes and obtaining approvals prior to implementing changes
    • Monitor the system to ensure drift has been resolved and the configuration remains stable

    Key Strategies for Detecting Drifts Between IaC and the Cloud

    There are a few strategies that can be adopted for detecting drift.

    Detect Configuration Changes That may Introduce Risks

    To identify configuration changes that can introduce risks, you should monitor and analyze changes proactively. Here are some of the key strategies to do so:

    • Create a baseline configuration for your system.
    • Review the system logs regularly for any suspicious or unexpected configuration changes.
    • To capture detailed information about configuration changes, comprehensive logging is helpful.
    • Implement a change management process for managing configuration changes.
    • Take advantage of automated configuration management tools such as Chef, Puppet, Ansible, etc.
    • Leverage threat intelligence to ensure that you are always up to speed on the most recent vulnerabilities, security threats and attack trends.
    • Conduct training to increase awareness about configuration changes’ potential consequences and risks.

    Establish Baselines and Safely Auto-Remediate Drift

    Establishing baselines and safely auto-remediating drift involves setting a reference point for the desired state of your infrastructure and automatically adjusting any detected drift back into compliance with the baseline.

    You can maintain the desired state of your infrastructure, reduce manual effort and quickly resolve configuration drift by establishing baselines and implementing security processes for automatic remediation.

    This minimizes the impact of drift on your systems while improving your environment’s security, compliance and stability.

    Track all Configuration Changes in Your Cloud Environment

    Tracking all configuration changes to your cloud environment is critical to maintaining visibility, accountability and security. It can help you improve visibility, detect unauthorized or unintended changes and maintain compliance and accountability.

    This way, you can proactively manage your cloud infrastructure, identify potential security risks and ensure its integrity and stability.

    Below are the key strategies for tracking cloud configuration changes at a glance:

    • Ensure detailed logging for all cloud components, including infrastructure, applications and security
    • Track API calls and activities within your cloud environment with cloud monitoring and auditing
    • Set up alerts and notifications for critical deviations from established baselines
    • Implement configuration changes through formal change management processes
    • Manage cloud configuration with tools such as AWS Config and Azure Automation

    Managing Drift in Production

    To effectively manage drift in production, it is crucial to consistently observe the configuration and state of production systems, keeping them in line with the policies that outline the desired state.

    Here are a few guidelines to help you reduce production drift:

    • Specify the required state: Define the intended state of the production environment as a set of policies using declarative compliance tools.
    • Monitor continuously: To determine any deviations, use a monitoring tool to monitor the production environment or compare the system’s present state to the desired state to identify any deviations.
    • Identify the root cause: If drift is detected, it is crucial to identify its root cause. You can do this by examining the logs, analyzing system performance or observing the configuration alterations over time.
    • Rectify the drift: After determining the issue’s root, you should address it to align its compliance with the intended state. To do this, you may need to examine logs, examine configuration changes, and analyze system performance.
    • Automate the remediation process: To ensure that drift is automatically and quickly rectified, you should automate the remediation process. To achieve this, you can leverage a declarative compliance tool that can help you automatically implement the changes to bring the system back into conformity with the intended state.
    • Review and update policies: You should review and revise your policies to ensure they are still relevant and useful and stay updated. To achieve this, you may need to adjust the policies to reflect new compliance requirements or shift your business requirements.

    Summary

    By identifying drift in cloud environments, organizations can use policy-as-code to ensure that their cloud infrastructure is safe, compliant and secure. In this way, they can ensure compliance with industry best practices, regulatory standards and internal policies. This reduces the risks associated with configuration deviations and enables enterprises to maintain a secure and reliable cloud environment.

  • Russian Dev Exodus | Puppet IPO FAIL | Intel 18A Ahead of Sched.

    Russian Dev Exodus | Puppet IPO FAIL | Intel 18A Ahead of Sched.

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: More than 100,000 tech workers leave Russia, Perforce buys Puppet, and Intel moves faster than planned. (more…)

  • Knowledge Is Power

    Knowledge Is Power

    I was doing some research over the weekend, and it became abundantly clear that you can find an Ansible script to do pretty much any repetitive task in your infrastructure. This is good news for Ansible users, and the pool of available scripts will, no doubt, continue to grow as critical mass effect kicks in.

    My concern is for those that find a script that does what they want/need, and drop it into their infrastructure. This approach may be a good short-term fix, but is full of potential peril. Even a cursory read of a complex script is insufficient.

    We all know the watchwords of the day are “speed” and “agility,” but take some time to test and get to know those scripts. When (not if) they fail, you’re going to want a clue of what is going on in there to track it down, and you certainly want to understand what is being pulled into your infrastructure. While the community is likely to catch malicious scripts relatively quickly, the inclusion of questionable sources and cases where your infrastructure causes a script to have issues are more likely to make it to your desk.

    The easiest validation cycle is to:

    • Read it for understanding. Know what it is doing, why it is doing it and what it is including.
    • Run it in an isolated environment. A pod, a VPN, whatever, just somewhere that you can control ingress and egress.
    • Scan the results as you would anything in production. Make certain sources are valid for your organization, make certain inclusions are safe and validate that any vulnerabilities in the resulting systems are known and acceptable to your organization.
    • If you can, do runtime testing upon it to catch any real-time changes. Most “changes after install” type of software is either well known or not included, so this step is more peace of mind than mandatory.

    If your thought was “takes too long, not necessary,” the risk is on you. But on the list of weaknesses in DevOps, that mentality is definitely in the top three. “Takes too long” is an organizational concern that is different everywhere. “Not necessary” is only true until it isn’t. As an IT professional, having at least a passing familiarity with the environments you are creating is part of the job. Fail to do it at your own risk.

    Much like there are trusted sources for the various types of repo we access, trusted playbook developers are a list you can curate. I know of a few that, in a pinch, I’d be willing to drop a script from into my architecture with only a cursory review, then give it a more thorough going over later when there is more time. But I know that because I’ve read their scripts, and I get that they are also careful.

    While I have Ansible scripts on my mind because that’s what I was looking into, this advice applies to any and all automation scripts that pull from outside sources. Python and Node do a ton of this too, but only highly complex projects pull from a lot of disparate sources. Ansible and other infrastructure automation tools pull from a variety of sources almost by definition (because infrastructure is complex), so they deserve more attention.

    In the end, automating all the things changes nothing about responsibility. So, take the time to make certain you know what is going on in your environment, and why. If you are really motivated, take the time to sweep through and remove any references you are certain you don’t need — but nested dependencies make the ROI on this type of work minimal, in my experience.

    Meanwhile, you are keeping a ton of servers running and users happy. Keep rocking it, and keep looking for solutions like automation scripts to make you more responsive — just don’t relinquish your authority for the datacenter to random submitter on the internet — because responsibility will still be yours.

  • Speaking the Language of Applications

    Speaking the Language of Applications

    I arrived early to a meeting, and the pleasant security guard at AT&T suggested I take a look at their innovation museum while I wait. Among motion picture sound technology and life-size photos of switchboard operators on roller-skates stood a transistor prototype. The transistor was invented in Bell labs in 1947, and it changed the world. Steve Wozniak considered it the greatest innovation of all time in his 2014 article.

    But almost nobody needs to think about transistors anymore. The transistor had to become transparent and abstracted, so the next generations can build great things in higher level. The transistor made a huge influence on our lives as an enabler, but if people had to keep talking about transistors it wouldn’t be possible.

    Abstracting technologies is key to advancing to a higher level, making it possible to solve real business problems.

    The language of a client-focused business is applications. If we want to make a business execute faster these days, we need to make the development and release of its applications execute faster. But one thing stands in our way: the infrastructure. Applications reside on infrastructure–they are installed on servers, bundled in containers, on cloud instances, in networks, using storage.

    If we want to speak the language of applications, we need to abstract them from the infrastructure, and make the infrastructure transparent.

    The concept of abstracting applications is what stands at the basis of every new approach to application development and release around us.

    • Containers are all about abstracting services from specific infrastructure and making them mobile.
    • Serverless takes it to the extreme.
    • Public cloud makes it easier not to worry about owning physical infrastructure.

    Technology screams, “Think applications, soon you will not have to worry about infrastructure!”

    And yet, most of us mix applications and infrastructure in an unhealthy way when we try to automate them. It is unhealthy because mixing applications and infrastructure prevents reuse of automation assets and makes it very difficult to connect infrastructure usage to a business context.

    Understanding how mixing applications and infrastructure is manifested requires looking back into the evolution of infrastructure and application automation.

    The Evolution of Infrastructure: Manual Deployment and the Inception of Its Automation

    In the beginning there was manual. We got a server; it was sitting on a shelf. We got the application artifacts, maybe on a CD or a USB stick. We installed the application on the server. Our application was ready for use. When we needed to upgrade, we went back to the shelf and installed the update on our server. It was very hard to make this operation faster.

    This is where automation of applications and infrastructure started.


    Behind any automation tool or standard stands a model. This model reflects how its creators originally perceived the problem they were trying to solve. It consists of the entities they defined as first-class citizens, the operations they wanted to apply on these entities, their attributes.

    “All models are wrong, some are useful,” said George E. P. Box in 1976. This is true for automation models too. Automation models are usually nice and clean when we start off. But as the problems we try to solve transform, our models need to grow and adapt. Until at some point they are not useful anymore and we need to replace them with next generation modelling approaches.

    The Configuration Management Model

    Configuration management tools such as Puppet and Chef were originally built to manage application deployment and configuration on static infrastructure. This new approach to Ops optimized manually updating applications on servers. Better network connectivity made it possible for this model to thrive, with the ability to configure applications on servers remotely.

    But within a decade we witnessed the fast rise of immutable infrastructure. Immutable infrastructure is an approach to deploying applications where the infrastructure components are replaced instead of updated. This approach somewhat pulled the rug from under the configuration management model. With each update or change, the application must be re-deployed. This forced adding dynamic infrastructure provisioning to the configuration management model. Combining infrastructure automation and immutable infrastructure concepts into the configuration management model is a difficult task, since this model was never designed to accommodate something like that.

    The Infrastructure-as-Code Model

    Pure Infrastructure-as-Code tools were built to provision infrastructure dynamically. Terraform is an example for an open source tool that does this well. This model is created with infrastructure in mind.

    Whether we look into Terraform, AWS, CloudFormation or ARM templates, we will see the infrastructure is the starting point (defining network connectivity, VM instances and services) and the applications are an implicit addition. They are artifacts that happen to be deployed on and are tightly coupled to the infrastructure. We may look at a component that says “App A” but it actually stands for “specific infrastructure with app A installed on it.”

    This seems natural, because it’s the same way it worked in the good old physical-infrastructure world: We fetch a box, we install something on it. We focus on the infrastructure, because this is our starting point. The application is the artifacts we put on the infrastructure and scripts we run after we provision it. Presumably, the application cannot live without something to be on.

    Infrastructure-as-Code tools evolved the way open tools do–their base model was extended by the community because there was a need to automate applications deployment and not just infrastructure. But it is becoming difficult to extend this model to reflect a world where applications are built to move between clustered servers, and the starting point is no longer the infrastructure, but rather the application’s requirements.

    Mixing Infrastructure and Applications

    Trying to fit infrastructure provisioning and application deployment in a single model that was originally designed for just one of them creates issues. Infrastructure is lower level than applications. Applications reside on the infrastructure. The same app can reside on different infrastructure configurations. This critical relationship is completely flattened if you mix them.

    Moreover, from a business perspective it is important to make applications explicit. It’s our product. Our website. Our mobile app. The applications need to be the center of the attention and discussion. This kind of modelling puts applications in the shade of infrastructure.

    Four Great Reasons to Model Applications as a First-Class Citizen Right Now

    The models we use today are broken, and it is time to evolve. No matter if your applications reside in containers, or on cloud instances, or include native cloud services or a mix of them. Applications should be a first-class citizen, and not some artifact installed as an afterthought on the infrastructure we started from.

    The notion that applications should be abstracted from infrastructure doesn’t eliminate all the challenges of infrastructure provisioning and application deployment, but it creates a foundation for better and more scalable automation.

    1. Achieve Application Re-Use

    Modelling applications as a first-class citizen is the only way to make applications a re-usable element throughout the development and release pipeline.

    If there’s one thing I learned in my automation journey, it is that if automation doesn’t get frequently and consistently reused, you don’t get value for your money.

     2. The Path to Multi-Cloud

    Abstracting application is also the best approach for moving application workloads between cloud providers. If everything starts from infrastructure, we need to start from scratch when we move. If our applications are abstracted and defined separately—this definition stays the same when we move, only the infrastructure changes.

    3. The Path to Breaking Silos

    The vision of Dev, Sec, and Ops all dealing with the same language (code) is wonderful. But bringing everyone to the same code pool is not always easy. Applications and infrastructure are not the same thing, even though we can code both. Mixing them makes them unnecessarily hard to build and troubleshoot. It forces us to deal with fuzzy boundaries when it comes to responsibility for this code. Basing automation on a model that organizes the world in a way the different stakeholders can understand it, can help overcome this barrier.

    4. Connect Infrastructure to Business Needs

    Infrastructure-as-Code is a huge breakthrough, but the bigger story is about making application development and release faster. This doesn’t undermine the importance of infrastructure; infrastructure is the foundation of everything. But if we want to solve business problems, we need to talk the language of the business, and that’s the language of applications. Our automation should be built in a way that reflects this.

    — Maya Ber Lerner

  • Configuration Files and DevOps

    Configuration Files and DevOps

    When DevOps appeared on the scene, configuration file management tools already existed. They weren’t used by everyone, but a fair number of organizations saw the power of configuration file versioning/management, and were using them.

    An interesting thing seems to have happened while DevOps evolved. Those tools are more popular, but while we’ve standardized on things like Puppet and Chef for installs, and Jenkins for continuous integration/continuous delivery (CI/CD), configuration file management seems to have gotten less standardized.

    While it is easy to argue (convincingly, IMO) that most people use Git for configuration file versioning, there are a ton of other solutions out there being utilized also. And plenty of places that have no solution in the works.

    There are even a few new vendors cropping up that are basing their existence on the idea that configuration file management should be similar to using the source code git repository, but not the same as using the source code git repository.

    What Are We After?

    That brings us to the question, What is it that we hope to gain from configuration file management? Which should take us back one step further to ask, “Which configuration files?” There is a vast difference between configuration files for a piece of network gear, the configuration files for infrastructure apps such as Docker and the configuration files for your application.

    There is a valid argument that all of the above are relevant and should be stored somewhere, but that argument does not imply they should all be stored in the same manner, nor with the same frequency.

    What does make sense is standardization on a given platform with version control capabilities. The question then becomes, Which platform?

    And That’s Where We Are

    My company uses Git for this storage, right next to application code. But we use regular storage with a naming scheme for switch and router configuration backups because we want them backed up with our other file-based data. Most companies are similarly split.

    The simple answer is, “Throw it all into Git,” and I think that’s where most DevOps teams are. But I don’t think we have the long-term answer in front of us yet. A toolset that can manage and version, and is aware of the idiosyncrasies of popular hardware/software/cloud solution configuration files is likely where we’ll end up. That will offer easier use, ease of management, a centralized store for configurations and some automated check upon the inevitable manual configuration changes.

    Until Then …

    Until then, it is best not to vary too far from the best fit for your organization. We’re content that we know where to get all of our configuration files back from, even if it is split between two platforms. There is one single piece of hardware in our infrastructure that in an emergency would be lost, and that’s because it is massive and only supports backup to attached USB disk.

    For most organizations, Fit is “good enough,” and allows for spawning new copies of servers/apps with the correct configuration during the deploy process, so is probably where you want to be right now.

    For enterprise grade networking gear, the configuration files are complex, and unlikely to be hand-edited these days (though we all know that person who can). So any system that gives you a backup of the configuration file you can re-import is good enough.

    For now.

    — Don Macvittie

  • Patrick McClory on Building Successful DevOps Organizations

    Patrick McClory on Building Successful DevOps Organizations

    Patrick McClory has been writing code, managing DevOps and designing scalable application infrastructures for more than 10 years. Most recently, as COO and CTO of DualSpark, he served as an expert Amazon Web Services consultant, helping clients capitalize on the benefits of cloud architecture and design with modern and innovative software, infrastructure and automation strategies leveraging AWS. After DualSpark’s recent acquisition by Datapipe, McClory assumed the role of SVP of Platform Engineering and Delivery Services, where his expertise is put to good use overseeing Datapipe’s global automation and DevOps, as well as its strategic consulting and platform teams. In this role, he manages several teams, including Datapipe’s client-focused service delivery team focused on enabling customers to transform their businesses by leveraging cloud-based patterns and practices.

    devopsy.kinsta.cloud: Tell us a little about your cloud experience, your consulting background and your role with Datapipe?

    McClory: I found myself in the Amazon partner channel probably a little over eight years ago. I worked for a couple of Amazon partners, and then I eventually went to work for Amazon. After having helped lead some of their consulting work in their professional services organization, which was fairly fledgling at the time, I left to form my own organization. It proved to be an interesting divergence for me. Where I previously spent a lot of time helping clients solve technical cloud problems—which is typically technical and very straightforward—I found myself transitioning to the greater software- and people-problem challenges around effectively taking advantage of cloud technologies.

    That’s really how DualSpark was born, both in terms of cloud data architecture, design and consulting. We helped customers understand how to take advantage of the cloud from a business perspective, as well as dive all the way down into the deep, nitty-gritty of exactly how they should technically do it. After eight years of consulting in that world and Datapipe acquiring DualSpark, I found myself in an interesting place where I now run the consultative, the engineering, the client-face role for Datapipe. I also run our platform-engineering team. The big story behind that is trying to take all the knowledge and all the patterns and all of the collective wisdom that we’ve gained over the years, between myself and the team, and building product to help our customers get there faster.

    devopsy.kinsta.cloud: We’re many years into the movement toward DevOps. What do you think we’ve learned the biggest challenges to be when it comes to getting DevOps right?

    McClory: What we’ve learned is that the technical side of the argument, when it comes to actually achieving a DevOps workflow, is probably the least complicated. The real challenge is getting people aligned and focusing the effort in the right direction. For me, that’s been the challenge. But people gravitate toward the tools because they’re easy. Realistically, you can’t take advantage of the tools if you don’t get yourself organized and going in the right direction.

    I’m going to tell a story. There was probably a span of six months where I had the, “What continuous integration tool should I use?” discussion. Invariably, every time, everyone ends up with the same sets of tools. Everybody ends up with Jenkins and, realistically, no one’s always terribly happy with it. Still, it was a six-week conversation, no matter what they eventually chose. Then, rather than starting from nothing, I decided to come to these meetings with a pre-configured system. I would load it into their AWS account, or wherever made sense. They’d see Jenkins hooked up, fully, to their source control toolset. It was highly available and had all of the plug-ins they sought. We took away everything to discuss. We’d then take the next two hours to configure it, play around with the bells and whistles and knobs. Fit it to their purpose. They could always shift to something else down the line.

    We couldn’t believe it, but that tactic worked. I no longer had six-week discussions about CI and what tool to use. I had a two-hour, fit-for-purpose discussion. At that point, bells going off in my head, going this is very interesting. What if we could do this more deeply? What if we did this all the way through the entire stack? What if I gave people multiple options and we just went through and picked it, like a menu? I’m not going to say that’s the overall product design. It’s a little bit more complicated and more intricate than that. The whole goal is to help customers get to the transformative place where they want to be, faster, by avoiding some of the common pitfalls of technologists who like to chase shiny things.

    devopsy.kinsta.cloud: With that in mind, what are some of the biggest challenges when it comes to getting the processes and people in place?

    McClory: IT as an organizational concept within companies that hasn’t done themselves any favors in the last 20 years. There are several different takes on this, but all basically converge on the idea that since the IT service management boom, IT as a discipline hasn’t really matured. Since then, there have been many, many inflection points and/or maturity moments when IT can provide services. But there’s this awesome gap that continues to grow between what the typical IT organization can deliver and what the business is demanding. That’s where shadow IT shows up. It’s like to divergent lines and that gap is shadow IT.

    What’s happened is that IT never, and I say this with the internal acknowledgment that I’m a part of this community as well, really done a great job of connecting our mission to the value of the business. The cost center, the revenue center, there’s all these ways to look at it but at the end of the day, IT is a burden, not an enabler. That’s why a lot of these technologies in DevOps are such a focus. The pain is so great that organizations don’t want to fix the systemic problem because they need to stop the bleeding. Often, what we’ve found is that there’s a combination approach that’s really necessary to build trust within that relationship.

    devopsy.kinsta.cloud: What do you think IT teams must do to flip IT from that unhelpful department to become more aligned with business objectives and profitability? Not that IT must be a profit center, but be more aligned with the business.

    McClory: Being more aligned with delivering value, right? I think it’s two vectors. There’s the one half that’s easy and stereotypical and that’s just because that discipline hasn’t really aligned that way for so long. As silly as it sounds, I find that there’s so much animosity between business and technology organizations on the stereotypical kind of day. There’s a little bit of corporate therapist that we play and we help build bridges, help to realign, help to translate. It’s a surprisingly entrenched issue of people at an interpersonal level.

    It’s not simply between the technologist and the company and the business. It’s also even within the technology organization, between your typical developers and operations organizations. Getting those three views aligned to serving the value of the business is, a lot of times, a matter of helping people to acknowledge that other people are a part of it and that they’re all there to serve the same mission.

    On the other side, there’s also this misnomer that there is a silver bullet, from a tooling capabilities perspective. There are some great tools out here and I’ve both built partnerships with them and used their tooling heavily. One that comes to mind, particularly, is Chef. I love their tools. They don’t solve every problem I have, though. There’s a landscape of tooling that I tend to end up back at that standard configuration management, continuous integration, testing and deployment management, monitoring and alerting. You end up finding good options in each one. Not that they’re perfect solutions, but a lot of organizations are looking for that DevOps in a box. They’re looking for that one capability and they forget that it’s not one thing. Even if people have tried to market it that way. It’s very much a technology plus an organizational culture issue. Not a single technology.

    devopsy.kinsta.cloud: Where do you see your clients now in the curve of DevOps adoption?

    McClory: If you’re looking at a bell curve and cut it into quarters, I think we’re probably in the early phase of the second quarter of adoption. There’s a ton of interest and I think that’s what I would look at, in terms of volume. I see lots of people who’re interested. I don’t remember who said it but to paraphrase, there’s a lot of people talking about it. There are very few people who actually achieve it.

    At the same time, I don’t believe that, to your point, DevOps isn’t a destination, it’s a way of doing things. It puts you on a vector, it pushes you in a direction. It’s never about the destination, it’s about the journey.

    In that respect, I think there are a lot of DevOps practices that start to seep in at the cultural level. As organizations try to be more efficient, we see them coming into some of the automation practices and the tooling side of things much more eagerly than they are the organizational collaboration side. Even that’s starting to break down and, oddly enough, I don’t know that I would blame it on the influx of newer developers or younger developers into the market. Certainly, it plays a role as the—not to wax poetic—the culture of sharing economy, the open visibility outcry from the hipsters perspective, or the millennial view. I think a lot of that I really positively impacted organizations behind the scenes, to open up a lot of that collaboration and visibility that’s necessary to get DevOps right.

    — George V. Hulme

  • Survey: DevOps Divide Grows a Little Wider

    Survey: DevOps Divide Grows a Little Wider

    The gap between the number of organizations that have invested in DevOps is starting to narrow, and IT organizations that made the transition to DevOps earlier are starting to see accelerated returns on that investment, according to the latest survey by Puppet.

    The annual “State of DevOps Report” finds that out of 3,200 IT professionals surveyed, only 11 percent were part of organizations that could be considered high DevOps performers. High performers are deemed to have higher deployment frequencies, lower lead times for changes, better mean time to recovery (MTTR) and better change failure rates. The higher performers in this year’s survey are deploying applications 46 times faster than the same designated group of higher performers were last year.

    The survey also finds that higher-performing organizations have automated 72 percent of all configuration management processes. Those same high performers spend much less time (28 percent) employing manual configuration processes. Lower performers are spending almost half of their time (46 percent) on manual configuration.

    Just over a quarter (27 percent) of the respondents self-identified themselves as being part of a DevOps team, according to the survey. In contrast, only 16 percent said the same last year. Puppet CTO Nigel Kersten says those results suggest that understanding of the power of DevOps is increasing. It’s also apparent the early implementers of DevOps processes are enjoying a level of IT agility that is much greater than the average IT organization.

    In general, Kersten says that while much DevOps progress has been made, most IT organizations have automated only various pockets of silos. Developers, for example, may have automated some processes on their own, while IT operations specialists may have developed a custom script to automate the configuration of a handful of servers. Kersten notes IT leaders should be cognizant of the technical debt their organizations are incurring every time different elements of the IT organization employ different tools to automate the same basic processes time and again.

    Very few have automated their operations within the context of a continuous integration/continuous deployment (CI/CD) pipeline, says Kersten. That becomes more challenging to accomplish as new computing models based on containers, for example, are added to the enterprise mix. On a more positive note, Kersten says more processes are being well-defined, as they are bounded by an application programming interface (APIs). Those APIs then become the core technology over which IT automation frameworks are then laid.

    The issue many IT organizations have yet to confront is the degree to which they want to stumble toward DevOps versus implementing a concerted plan of action. Much of the DevOps progress to date has been driven from the bottom up inside many organizations. The time is now approaching for IT leaders to imbue DevOps as a part of the IT culture that permeates the entire organization.

    To one degree or another it’s a safe bet every organization will implement some form of DevOps going forward. The challenge  will be figuring out how to transform all those isolated instances into something more akin to an actual IT strategy.

    — Mike Vizard

  • 6 Big, Bad Mistakes in Configuration Management, Part 2

    6 Big, Bad Mistakes in Configuration Management, Part 2

    In Part One of my article on big, bad mistakes in configuration management, I reviewed the dangers of using the wrong tools for the configuration management job. Provisioning management tools, application release automation tools and continuous integration tools each have their place in your DevOps toolchain. But they should not be used as a substitute for ongoing configuration management. In this article I am focused less on misusing tools and more on bad practices, limited thinking and short-sightedness that should be avoided.

    Mistake No. 4: Direct Server Access to Production

    This one may not bite you … until it does. I’ve worked with many companies where developers have direct access to Production. This is not good. And, in many cases, it is a violation of compliance policies. Please don’t take offense, my developer friends. You shouldn’t want direct access to Production. I find that 9 times out of 10, your code is not the problem—the configuration is the problem. However, you’re being asked to log directly into the server to do comparisons between your environment (where it worked just fine) and Production. This leads to the, “How did he fix it?” problem, and it leads to the dreaded typos and other manual errors. I’ve witnessed companies lose millions of dollars in a matter of minutes because someone logged directly into a server and made an incorrect configuration change.

    The question is, How do you cut off direct access to Production? How do you quickly find configuration differences between environments without logging into the server? The answer is a good configuration management solution that quickly shows differences between the environments for all your tiers. This is easy when you’re doing file-to-file comparisons, but what about registry key comparisons, or WebSphere comparisons? Find a configuration management tool that gives you visibility fast, exactly when you need it, for the important parts of the stack that keep your applications running. And insist on a configuration management solution with robust RBAC (role-based access control) over what changes can be made, where and when they can be made, who can make them and even who can approve them.

    Mistake No. 5: Leaving Your DBAs Out of the Picture

    The majority of companies I work with have completely disconnected database and middleware teams—the DBAs don’t really know what the middleware team is doing and the middleware team has no visibility into what the DBAs are doing. I believe there are a couple reasons for this: people and technology. We won’t worry about the people aspect today, other than to say that each team thinks the other team is “quirky” J. From the technology aspect, traditional tools simply do not provide configuration visibility into both the middleware and the database tier. So the DBAs end up having one toolset, and the middleware team a completely different toolset. This prevents collaboration, orchestrated releases, and the complete configuration picture that’s needed to make sure your application is fully configured, performing, and running correctly.

    This is a big problem. In fact 37 percent of survey respondents admitted that they relied on scripting and manual processes to determine which databases were used by which applications in their ecosystems. And another 38 percent admitted they don’t even have a way to determine this information. Talk about blindfolds! My advice is to find a solution that both middleware and database teams can use. That doesn’t necessarily mean the DBAs will replace their favorite tools, but they’re now involved in the process, allowing that collaboration and orchestration that was missing.

    Also, if you use a single, integrated configuration management solution your management, middleware, OS and DBA teams will all have visibility into every aspect that makes the application run. The middleware team can see if there are schema changes that may be causing an application issue as opposed to spending hours looking for a middleware configuration issue they’ll never find, or vice versa. Having one unified tool cuts down on the mean time to diagnose because you can see all the tiers in one place.

    Mistake No. 6: Focusing Only a Single Part of the Stack

    The previous “big, bad mistake” segues nicely into this one: focusing on just a single part of the stack. There are many tiers supporting your application, and we’ve touched on several in this series—namely middleware, database and OS. Within each tier you may be supporting different technologies. Some applications may be running on IIS with a SQL Server back end while others run on WebSphere with an Oracle back end. Then you have the operating system settings to worry about: making sure registry keys are set, system services have the right accounts, filesystem permissions are accurate, all the correct versions of Linux packages are installed, etc.

    Based on a lack of comprehensive coverage up and down the application stack, many companies have chosen to explore configuration management tools for just a single part of it. These point tools tend to focus on the most business-critical applications, the one where they hit the most configuration issues or simply the one that’s most difficult to manage. This is not necessarily a bad thing to do, but take care not to be too single-minded. Try not to choose a configuration management solution that works well for one part of the stack but not others, or that works very well in one environment (Linux/Unix), but not very well in another (Windows). Managing these disparate point solutions, with maddening gaps and overlaps in coverage, can be exhausting.

    Choose a tool that’s extensible to other parts of the stack, business or other teams. My suggestion is to make a list of all present and future technologies you use that need configuration management support. Divide them into different parts of the stack and then rank them from “most onerous to manage and/or most business critical” to “nice to have.” Refer to this list when evaluating configuration management tools so you don’t lose sight of the forest from the trees. Make sure the tool can support all your top items and ask about their road map for your “nice to haves.”

    Tune into our upcoming webinar, which will touch on these topics as well.

    About the Author / Kristy McDougal

    Kristy McDougal leads Product and Sales Engineering for Orca, an application release and configuration automation solution for DevOps teams. Prior to launching Orca, Kristy was a Senior Pre-Sales Consultant within BMC Software’s worldwide DevOps specialist team. Before BMC, Kristy held technical positions at VaraLogix, Virtual Bridges, Global Foundries and Advanced Micro Devices. Her experience includes Unix systems administration, systems engineering, pre-sales consulting and post-sales services. Kristy is ITIL Foundation-certified and is an electrical engineering graduate of the University of Texas at Austin.
  • 6 Big, Bad Mistakes in Configuration Management, Part 1

    6 Big, Bad Mistakes in Configuration Management, Part 1

    Configuration problems come in many flavors. Some are mere nuisances. Often though, configuration errors can lead to more serious mishaps like application performance problems, policy compliance violations or even security vulnerabilities. They can often go undetected, quietly doing their damage in the background while everyone’s attention is focused elsewhere.

    Unfortunately, I find that configuration management is an area where many companies either 1) put it as a “last to solve” on their priority list (when arguably it’s quite important), or 2) try to solve it with a do-it-yourself fix, but in a way that’s not always extensible or that doesn’t end up working with their DevOps toolchain.

    Usually, I find configuration issues stemming from the age old problem: using the wrong tool for the job. In this blog I’ll address six big, bad mistakes of configuration management. (For the sake of brevity, three will be addressed here and three in an upcoming blog.)

    Before I get into it, though, there are so many definitions of configuration management that it warrants a brief summary so we’re all on the same page. I’m talking about the ongoing configuration management of the infrastructure tiers supporting your applications—the middleware, database and OS-level configurations that keep your applications’ lights on and everyone happy.

    Mistake No. 1: Only Considering Provisioning

    Notice I just mentioned the word “ongoing” in my definition of configuration management. I find that so often people forget to take the ever-important “ongoing” into consideration. I have many conversations with folks wanting to implement a “provisioning tool.” On the surface, they think they need just that: a tool that provisions infrastructure including all the tiers of the application. But when I probe further, what they’re really wanting is something that provisions and then continues to monitor, manage and fix. There’s a big difference there.

    Some tools do great at provisioning but lack the visibility and “ongoing” configuration management needs. Think of a provisioning tool as waving a bat at a piñata. Yes, you can “blow away your environment” and start over, but that blindfold prevents true visibility and ongoing interaction.

    When looking for configuration management, be sure to focus on your current and future needs. Do you just need a provisioning tool? Or do you need an ongoing configuration management tool? Or both? Most tools that tout doing both do one much better than the other, so be sure to do your research.

    Mistake No. 2: Using an ARA Tool to Manage Configurations

    In a previous position I spent quite a bit of time onsite with clients helping them automate their application deployment processes. What I found is that around 80 percent of “application deployment” tasks are actually configuration tasks. The application deployment is the easy part; it’s the configuration management aspect that causes all of the headaches. I would spend the majority of my time onsite hurriedly writing little scripts that would be hurriedly inserted into the deployment process that would set the application pool, restart the service, change a heap size, etc. I had to write the scripts because application deployment products are workflow automation engines with process wrapped around them. They are not meant to be infrastructure configuration management products.

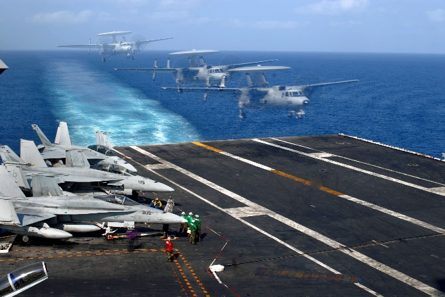
    It bears repeating: Traditional application deployment solutions are not meant to be infrastructure configuration management products. They can get you part of the way there, but 1) you’ll need to script it all, which is not extensible and defeats the true purpose of a tool, and 2) they simply catapult your application (one way only!) into the next environment (i.e. Test to Staging, Staging to Prod), so you can forget about the “ongoing” piece we discussed above. Compare that one-way catapult launch to the complexity of routinely engineering one safe launch (and landing!!!) after another on an aircraft carrier on the open seas. A mission-critical task like this requires advanced technologies, visibility, communication and coordination to account for constantly changing environmental factors.

    Mistake No. 3: Using a CI or Build Automation Tool When You Need Configuration Management

    As bad as misusing an application release tool when you really needed a configuration management solution, it’s even worse using a continuous integration tool for this. Like many DevOps solutions, CI tools are particularly helpful for developers. CI tools like Jenkins and Bamboo require Dev teams to share or check in their updated code into a repository. The CI tool then detects potential problems early by automatically verifying builds for the developer. From the Dev team’s perspective, there is no more wondering if their code is going to work, and they spend less time debugging and redoing. The financial benefits of CI and the early warning system they provide should be obvious and considered a must-have for developers.

    But while detecting coding errors early saves a lot of hassle for the Dev and Test teams, Ops teams do not directly benefit from CI. Here’s why: Operations teams are concerned with the application release into Production environments and then the ongoing configuration management of the entire application stack including the application, middleware, database and operating system. Once the (application) baton is passed to them, they require visibility into and intelligence about the application’s operating environments—well after Dev and UAT. As good as they are for Dev teams, CI tools are simply not equipped to provide ongoing operations support, visibility and coordination in Production that modern Configuration Management solutions provide.

    These are just a few big, bad mistakes in configuration management and they focus largely on misusing tools beyond their intended scope. I will follow up with a Part II companion article that addresses configuration management practices to be avoided.

    Tune into our upcoming webinar, which will touch on these topics as well.

    About the Author / Kristy McDougal

    Kristy McDougal leads Product and Sales Engineering for Orca, an application release and configuration automation solution for DevOps teams. Prior to launching Orca, Kristy was a Senior Pre-Sales Consultant within BMC Software’s worldwide DevOps specialist team. Before BMC, Kristy held technical positions at VaraLogix, Virtual Bridges, Global Foundries and Advanced Micro Devices. Her experience includes Unix systems administration, systems engineering, pre-sales consulting and post-sales services. Kristy is ITIL Foundation-certified and is an electrical engineering graduate of the University of Texas at Austin.