Tag: CD

  • Standardization, De Facto Style

    Standardization, De Facto Style

    The first decade or so of DevOps had one truth to it: It was about change. Not just change in the way that IT worked, but change in the way DevOps worked—particularly in the tools space, where products and product preferences both are in flux. We’re still seeing a massive change, but increasingly the effect is more like the ripples created when a rock is thrown into a pond than a tsunami, dumping change upon change.

    You could look at this one of two ways (and no doubt those who have more reason to dig into details than I have already done so): Either the slow but steady standardization typified by tools such as Jenkins and Puppet have enabled participation of enterprises in the DevOps life cycle, or the demands of enterprises for some amount of stability in their massively complex systems have driven standardization.

    Either way, the result is the same. We are seeing a lot of change further out, but the core technologies for build/test/deploy are settling into a few products by a few vendors. That is good for adoption, even if you would argue that it is bad for innovation. It means that skill sets are, at least to a certain extent, portable across DevOps teams and organizations, which for a long while was not true. When I was knee-deep in deployment technology, knowing how to use product A did not mean you knew how to use product B. The more people using one or the other, the better for employee mobility and the pool of available resources, as both people and support tools like standardized scripts.

    I recently was going through the offerings of a service provider in a space that doesn’t traditionally have DevOps enablement. The company’s offering included DevOps, so I drilled down. Seeing the company supported Jenkins, Jira and Xebia Labs made me feel better about the program it was putting together. It meant the company was adapting mainstream tools to a specialty market.

    That’s what spurred this blog. It’s been a long time that these things were seen as “new and shiny”; now, for a service provider to include them as proof it is serious about customers’ problems shows just how far we have come.

    There’s still a long way to go. The DevSecOps community is currently in the throes of growth, and lots of outer-edge DevOps tools are incompatible with each other and chosen per shop without a clear market leader. But we’re getting there. And at this point, a person going into DevOps who asks me what they should know will actually get an answer of “Learn X, Y, Z” rather than “You should learn X, but pick up some of X.1, X.2, and A too, then there’s Y …”

    The thing is, though de facto standardization is happening, to many (particularly enterprise) shops, this is all still new. So if you don’t know the recognizable tools yet, don’t worry too much; there will be opportunity to learn as they are rolled out across a given org.

    — Don Macvittie

  • CloudBees Acquires Codeship to Extend CI/CD Reach

    CloudBees Acquires Codeship to Extend CI/CD Reach

    CloudBees today signaled its DevOps ambitions to extend well beyond the Jenkins continuous integration/continuous deployment (CI/CD) platform by acquiring Codeship, a provider of a CI/CD platform that is delivered as a software-as-a-service (SaaS) application.

    The decision to acquire Codeship is being driven by the need to engage smaller DevOps teams that don’t have the time or expertise required to set up on-premises instances of Jenkins, said CloudBees CEO Sacha Labourey.

    Codeship today is being used by more than 100,000 developers spanning 2,400 customers. Many of those developers are working at smaller companies. But Labourey noted that small teams of developers inside larger companies also prefer to invoke a CI/CD platform as a service.

    “Different teams will decide to do different things in the same organization,” said Labourey.

    The Codeship platform is not based on Jenkins and there is no plan to rehost the Codeship service on Jenkins, says Laborey. Jenkins is designed to be highly customizable by the organization that employs it. The Codeship service is a highly opinionated instance of multitenant CI/CD platform that is designed to provide a turnkey experience capable of support lots of developers at once, explained Labourey.

    CloudBees will explore ways to bundle its core platform with the Codeship service for organizations that find themselves needing to deploy both a CI/CD platform on-premises in addition to a cloud service, he added.

    The acquisition of Codeship signals a wave of coming consolidation across the DevOps sector, Labourey said, predicting that over time, a much smaller number of companies will account for most of the DevOps software and services sold. Some will rise from the ranks of the pioneers of DevOps. Others will be the same companies that today dominate application lifecycle management (ALM) and software development lifecycle (SDLC) software in the enterprise. As DevOps continues to gain momentum in the enterprise, it’s now only a matter of time before legacy ALM and SDLC vendors are forced to modernize their portfolios by making acquisitions or partnering with companies such as CloudBees, he said.

    It’s too early to speculate how that consolidation might play out. But it’s clear the rise of microservices is about to force the DevOps issue in many enterprises. The rate at which DevOps processes have been adopted across enterprise has been uneven, but as organizations embrace microservices to build better applications faster, many will need to re-engineer their application development processes. There always will be monolithic enterprise applications that may be better-served by waterfall approaches to application development, but in time, the bulk of applications will be built employing microservices architectures that make it easier to update and manage applications employing modern DevOps best practices.

    How much those DevOps processes will be based on CI/CD platforms running in the cloud or on-premises is anybody’s guess. More than likely, most organizations will rely on a combination of both, depending on the size and scope of their efforts. Regardless of the approach, however, at a time when every company is becoming more aware of their dependency on software to compete, it will be those organizations that embrace DevOps processes best that will prosper at the expense of rivals.

    — Mike Vizard

  • The Role of Operations in a No-Ops World

    The Role of Operations in a No-Ops World

    It seems that every once in a while, we in high tech get wrapped up in the next thing that will eliminate work and/or jobs. Sometimes, as is the case with DevOps, we get something that reduces redundant work and actually makes our life easier in the long run. Most of the time, however, we don’t. XML was going to end programming, Java would make everyone a programmer, SOAP meant non-programmers could piece together chunks of code and create complex systems … the list goes on and on.

    Today’s trip on the merry-go-round is for Ops and DevOps. The love in some quarters is “No-Ops”—no operations necessary at all! The data center will run itself! But where is there meat to these claims, and where is it just not possible with today’s technology? Let’s take a look.

    SaaS is Today’s No-Ops Option

    If you want a nearly complete no-ops solution today, sign up for software as a service (SaaS). You’ll still have to manage users and access—the normal AAA stuff—but the application is built and managed by someone else. That’s as close to no-ops as we have in today’s world.

    Any other solution requires a fair amount of ops, no matter what we are told. Installing servers—be they in the data center on hardware, in VMs or in cloud instances—still requires work. Even if you have a tool such as Ansible or Kubernetes cranking hard for you and doing most of the repetitive heavy lifting, you are still tying the pieces together and making things work correctly. Networking is often left to operations/DevOps teams, and making servers into cattle requires operations heavy lifting, even if you are that automated. Apps break and troubleshooting is still a largely manual exercise, with automated help in figuring out what went wrong, but the fix still heavily in the hands of operations.

    Hints at an Future Sans Operations

    As is usually the case with these claims of ending some portion of the IT workload, there is some underlying benefit if you don’t get caught up in the hype. Remember that early in cloud some were telling us that there was no longer any reason for a local data center. Of course, there are a billion reasons, and each environment is different. But there is no denying cloud has opened up how we look at server deployment. The same is true for no-ops. There are a lot of reasons that it will not actually be no-ops for an entire project (let alone an entire data center), but there are huge benefits to gain from the idea.

    Serverless

    In serverless, you develop the code behind and API, then expose the API. The system is designed to run the code only when requests come in. Application firewalling is generally mandatory and built into the system. This partially a security feature, and partially the location used to determine what code needs to be called to service a given request. The idea in the cloud is that you only pay while your API is running, and all of the operations parts of the call are taken care of for you. That’s true, if you accept that, in serverless, developers are doing operations as part of development—app firewall configuration, even the simplified version of it that serverless uses, is definitely operations, not development. And troubleshooting between serverless and server-based apps that call the API is going to fall—at least to some degree—on operations. It must, since operations are the people who have network and internetwork knowledge.

    Serverless offers some great options for deployment, though, that undeniably reduce operations overhead. For things such as cloud-bursting, the benefit is pretty undeniable. It makes pay-as-you-grow cloud into a seriously granular proposition, and can eliminate the kind of bottlenecks that all code has by spinning up a new instance for each connection.

    Container Management

    With an increasing amount of functionality folded into container management tools, the ability to auto-scale applications (or, at least, instances of a part of an application) is a big step toward no-ops. Without manual intervention, the container management tool can expand or contract the application’s footprint in response to connections, response times, etc. The built-in routing, when it fits the needs of the organization, limit the amount of networking required to facilitate this scaling also. As time goes on, expect more automation to be folded into container management to make at least the maintenance of applications easier. The advertised ability to perform rolling upgrades on applications while keeping them live is a huge operational bonus too. It’s not precisely no-ops, but it certainly is less-grey-hair-ops.

    Dev/Test/Deploy

    Application release automation, the growth of continuous test/delivery/deployment and configuration automation tools all reduce ops as well. They don’t make for no-ops, but they do facilitate the concepts, reducing operations overhead while advancing the concepts of DevOps. Expect these tools to continue to grow. Most configuration management/application deployment tools work with a selection of networking devices/appliances already, expect that trend to continue. Again, it’s a reduction in ops—not quite no-ops, but a great step in that direction.

    And More

    We’ve looked at a couple of really cool technologies that forward the reduction in operations theme beyond what is listed here. Automation of auditing and full-on automation of security testing (combining code analysis with real time data to get better coverage than today) are just two examples. Keep an eye on the market as these toolsets mature.

    Keep Kicking It

    Meanwhile, Ops isn’t going away. Stay the expert while expanding your skills. As I (and others) have said before, a tool that reduces the hands-on aspects of operations is not a threat, it’s an opportunity. That freed-up time will be useful for all those projects you wish you could do, but didn’t have the time. Or, even better (we can debate that statement later), all of those things the business wishes you could do but you don’t have time.

    In the end, you are keeping the org running, and connected to the world. Embracing the parts of no-ops that make your job easier just makes sense. Don’t fall for the hype; just pick up the good bits, and keep rocking it.

    — Don Macvittie

  • DevOps Chat: Harness.io, Continuous Delivery as a Service w/ Steve Burton

    DevOps Chat: Harness.io, Continuous Delivery as a Service w/ Steve Burton

    Today marks the launch of Harness.io, continuous delivery as a service. The company is founded by some of the original team at AppDynamics. They want to take the same kind of approach AppDynamics brought to APM, to the CI/CD market. We caught up with Steve Burton, VP of product marketing at Harness to get the scoop on this exciting new company.

    As usual immediately below is the audio of our discussion and the transcript of our discussion follows after that.

     Audio

    Transcript

    [su_pullquote align=”right”][su_custom_gallery source=”media: 118147″ width=”300″ height=”300″]Steve Burton

    Steve is VP of Product Marketing at Harness, a new Continuous Delivery-As A-Service Platform. Prior to Harness, Steve ran Product Marketing at AppDynamics, Moogsoft and Glassdoor. Steve also started his career as a Java developer back in 2004 at Sapient. When he’s not playing around with technology he’s normally watching Formula 1 or researching cars on the internet. Twitter: @BurtonSays[/su_pullquote]

    Alan Shimel: Hey, everyone, it’s Alan Shimel, with another DevOps Chat here on devopsy.kinsta.cloud. Today’s chat is with Steve Burton, VP of products at an exciting new company – just launched today – called “Harness.” Steve, welcome.

    Steve Burton: Thanks, Alan. Great to be here.

    Shimel: Great to have you here and, hey, it’s a great day to launch a company, Steve.

    Burton: Yes. Sure.

    Shimel: Of course, you know, I’m reminded of what someone told me when I sold the first company I started, and they said, “Companies are like boats – the best two days are the day you buy ’em and the day you sell them.” So this is one of the good – this is one of the big days for ya. And speaking of that, though, Steve, before we get into what Harness is about and markets and stuff, you actually – you’re one of the founding team there, and the team’s really kind of a get-together of a lot of the guys who helped found AppDynamics, I guess, back in the day. Correct?

    Burton: Yeah, for sure, with a few AppDynamics guys here. We’ve also got people from Apple and Google as well, so there’s a nice mix. But, yeah, for sure. There’s Jyoti, there’s myself, Greg Howard, and Randy Boysen, so there’s – yeah, that’s what we love to do, is build start-ups.

    Shimel: Yeah. Getting the band back together. So, Steve, though, with Harness, though, you guys have taken an interesting kind of approach here in that, you know, you see a tremendous opportunity within the CICD market. Correct?

    Burton: Yeah. Yes. I mean, Harness has primarily kind of been built for continuous delivery as a service, so the kind of CD part of CICD, and we think there’s a big opportunity there. There’s a lot of excitement, there’s a lot of projects and customers, and there’s a lot of complexity to solve, and so, yeah, that’s what we’ve kind of founded the company to kinda help customers with.

    Shimel: Sure. And, Steve, I mean, here at devopsy.kinsta.cloud, we obviously follow the CD space pretty closely, and there’s certainly no lack of companies that have thrown their hat in the ring here, right, without naming names, from well-funded start-ups to big, traditional 800-pound gorillas, but the fact that no one has really captured a dominant market share probably indicates it’s because no one’s really come up with the killer CD app, if you will, or the – and if it’s not the app, maybe it’s the delivery means and everything else. Is that part of what drove you guys to, you know, go this route with Harness?

    Burton: Yeah, I mean, for sure. I mean, if you speak to Jyoti, one of the key reasons he founded the company was when he was, obviously, CEO and founder of AppDynamics, he met with a lot of enterprises and big customers, and they were telling him, “Hey, look, we have hundreds of DevOps engineers, but a lot of them are spending their time scripting and building automation platforms. And so there’s no real solution to help us kind of be like a Facebook or a Google, where we can do continuous delivery.” And so that was really the impetus for Jyoti to kind of take a step back and think, “This problem really isn’t solved yet.”

    Shimel: Yeah. No, I think you hit on something there ’cause there’s been some – not backlash, but there’s some talk on some of the DevOps channels that, “You know what? DevOps hasn’t been as successful as we thought it was going to be and a lot of organizations aren’t experiencing the success they hoped with DevOps.” And, frankly, a lot of it is subjective, not objective, and maybe some of it also has to do with hyped-up expectations that can never be met anyway.

    But, that being said, you hit on something there that I think is important, that, a lot of times, when we talk about DevOps teams and implementing DevOps, it’s time spent figuring out automation, right, and scripting automation. And, whether it be automated testing or automated integration or configuration or what have you, it’s kind of like groundwork, rather than actually doing the work. And you probably need to do the groundwork first, right, Steve? I mean, no one’s – I’m not saying that, but, with a SAS solution like Harness here, you can kinda not cheat, but you can get a head start on that.

    Burton: Yeah, for sure, and I think one thing we’ve tried to do is simplify continuous delivery, and so a lot of the scripting and automation that you might require teams of DevOps engineers to do, we feel we can give those teams a solid platform that they can build on top of, to do continuous delivery. And so I actually sympathize because, if you look at the complexity and the work involved to make continuous delivery work, it’s more than just provisioning infrastructure and configuration management. I mean, today, you’ve got release strategies, you’ve got canary deployments, you got blue-green. You think it’ll verify how those deployments succeed in production. You’ve got rollback, so, if things fail, how quickly can you roll back?

    And I think as well, from speaking to customers, one thing we hear a lot of is just the compliance and security around DevOps, and so DevOps is ultimately about empowering teams and giving freedom to developers and operations, but, at the same time, these companies need to control and audit and make sure that things are done correctly. So a lot of the boring stuff, like the credentials and secrets management and kind of visibility and reporting, that’s as much of the puzzle as a lot of the cool stuff.

    Shimel: Yeah, you’re talking my language, Steve. Certainly, security and compliance, and I tend to think compliance is the caboose on the security engine. You know, just doing compliance doesn’t make you secure. But, that being said, security and compliance are major – they could be your best friend or your worst enemy, in the continuous delivery game, right? If you do it right, you could automate a lot of that and shift it left. It could really help speed up a successful CD process, a successful experience. But if you don’t pay attention to it and you run afoul of your security and compliance, I mean, it’s like going back to “Go,” don’t collect the 200 bucks, and you’re starting from scratch. So it’s an important piece of the puzzle, for sure.

    Steve, give us a little background, though, in – you know, so Harness sees this and the team sees this opportunity with CD. It’s a SAS-based solution. What more can you tell our audience about what you guys are doing?

    Burton: Yeah. So, primarily, it’s SAS and we also offer on-premise software as well, so you can deploy either model. I think what we’re trying to do is three things, is one is automate the actual deployment aspects, and so, instead of needing kinda scripting or coding a lot of the configuration and wiring together all of your ecosystem, and so you kind of use CI in your repository tools, like Jenkins, Bamboo, JFrog, CircleCI; and then making those kind of work in sync with kind of Amazon cloud platforms, Kubernetes, Docker; and then, finally, all the configurations. So what we’ve tried to do is build reusable connectors and templates for all of the technologies in the ecosystem so that you can literally plug them together and build CD pipelines in minutes.

    And that sounds totally alien and kinda sounds too good to be true. We’ve managed to do it, but it’s been a lot of work and it’s been working with a lot of customers. And so, in the last 3, 4 months, we’ve literally had, I think, 270 kind of validation meetings with customers. We’ve got over 20 betas in deployment. And so it’s been understanding that complexity of how we can simplify the CD pipelines today. So, yeah, it’s still a lot of work to do, but I think we’re on the right path.

    Shimel: Excellent. And, of course, Steve, you mentioned something that I wanted to bring that out too, is that, you know, it’s sort of this “It takes a village” with CD, right? There’s no one tool that, soup to nuts, is going to do everything for you, and, as you mentioned, Harness already has integrations with a number of the most common tools that are out there, like a Jenkins and so forth.

    Burton: Yeah. Yeah, and I think, if you look at a lot of the solutions on the market, they require you to rewrite your CD process and change the way you do deployments and potentially replace tools you already have, and kinda that never really works because most customers have invested a lot of time and money and resources in those tools, in those processes. And so what we do is we can fit around your existing ecosystem and tools, as well as your processes, and so a lot of the customers who’ve gone through our beta program, within the first three or four hours, they’ve actually been able to get a CD pipeline up and running and reuse the Jenkins or reuse all of the cloud technologies and platforms, in addition to the monitoring tools as well.

    Shimel: Excellent. So, you know, though today’s launch day, Steve, you guys have actually put in months and months, if not year, already of work on this, but where do you think it goes next?

    Burton: Yeah. Yeah, so, in the intro, I talked about us building the building blocks for the automation and getting the CD pipelines built. We’ve also architected Harness to do continuous verification. What that means is, once you’ve deployed code or artifacts in production, we’re actually gonna use machine learning to understand whether that deployment had a positive or negative impact on the business. And so we’re gonna verify things like performance, response times, errors, throughputs, in addition to looking at application logs to see if there’s any regressions or anything that’s been introduced as part of the deployment.

    And so that’s what we’re excited about. That really, we believe, is unique to Harness – the ability to validate a production deployment. And if we see failures or we see anomalies, we can automatically roll back to the last working version for the customer, with no interruption to their business. So, for me, the future, it needs to be more than just deployment. If you don’t know the business impact of your deployment in production, then you could say there’s been a lot of work and time and effort for, potentially, nothing.

    And I remember, when I was a developer, I worked on projects for months and our success was hitting the go-live day. And once we hit the go-live day, it was operations’ responsibility to deploy it and we never really knew whether we had a positive impact or a negative impact. And I think, in today’s world, with kind of continuous delivery and DevOps and going from an idea to money as quickly as you can, you’ve really gotta know the business impact of every change. And if you don’t, you’re letting your company down.

    Shimel: Agreed. Agreed. So, Steve, it sounds – you know, this is something that I’ve always wondered about with DevOps, which is we put so much effort into automation and doing it better, you know, getting better code, automating all of the stuff, automating CI, automating CD to the point where we actually deploy, and then, all of a sudden, post-deployment, we’re on to the next thing or we’re looking for our feedback loops so we can develop the next iteration of it. And I guess sort of APM sort of filled that next post-deployment monitoring and so forth, but it sounds here like Harness wants to fill that gap in there. Is that fair to say?

    Burton: Yeah. Definitely. I think we wanna automate how customers verify their deployments, and so the APM market is like $5-billion market right now because, literally, every company’s building software and their software keeps breaking. One stat for you is 30 percent of application deployments fail. This was an article that Wired.com wrote – I think it was a few months ago – but that’s a staggering amount of failure. And the reactive way to deal with failure is to go and buy an APM product to help you kind of troubleshoot in production, when you do a deployment.

    The smarter way to do it today is to start and do canary deployments in production, where you roll out the application to a small amount of nodes or users and then verify it before you then roll it out across the rest of your application environment. And so you can kind of think of Harness as a safety net – we’re gonna let you deploy in production, we’ll help you with canary deployments, and, if we see something that’s wrong or we spot an anomaly, you can roll it backward with virtually no business impact

    Shimel: Got it. Got it. Well, Steve, believe it or not, we’re probably a little over time here already, but, hey, we tried. Steve, before we wrap up, though, for people who wanna find out more about Harness, where can they go?

    Burton: Yeah, they can go to harness.io, is our Web address, and we’ve got lots of videos and will be a free trial coming shortly. And you can actually subscribe for the early adopter program as well, if you wanna show your interest there.

    Shimel: Oh, that’s excellent. Excellent. And I’m sure there’s plenty of stuff on the website where people can find out more information of all of these things. Steve, congratulations to you, Jyoti, and the rest of the team. It sounds like you guys are on to your next great adventure and I’m sure it’s gonna be an amazing journey. We hope to have you back here soon and we’ll be watching Harness closely and seeing what it brings to the market. Congratulations.

    Burton: Yeah. Appreciate it. Thanks, Alan.

    Shimel: All right. Steve Burton, VP product at Harness, at harness.io, if you’re interested. Exciting new entry in the DevOps space. Best of luck, Steve, and we’ll see you soon. This is Alan Shimel for devopsy.kinsta.cloud, DevOps Chat. We’ll see you soon on the next DevOps Chat.

    — Alan Shimel

  • Continuous Testing: Crushing the Testing Bottleneck

    Continuous Testing: Crushing the Testing Bottleneck

    The practice of continuous delivery has been with us for many years, but it has started to see real adoption in the last couple of years. Continuous delivery is about automating and simplifying the process of delivering new features to the market at any given time, accelerating delivery and helping bring Dev and Ops together to make them jointly accountable for the release process.

    As continuous delivery is helping to break down barriers, culture and bottlenecks in the delivery pipeline, a new practice has evolved to help teams solve this most daunting challenge of the delivery pipeline: Quality.

    The practice is called continuous testing, which can be defined as:

    • Testing your change in an efficient way (so your tests are completing faster),
    • In an optimized way (so that you find issues as early as possible in the cycle),
    • Based on risk and priority (so you test what is important to your users and the business).

    Some may think of this as equivalent to test automation, but that premise would be wrong.

    Automated testing tools can execute tests repeatedly, provide reports on testing outcomes and show comparisons with previous test runs. This is a critical foundation for a continuous testing practice, but just a starting point.

    In a continuous testing practice, testing is not done just in the “testing” phase and not only by test teams. Testing is performed at the level of the build (for example, Unit Test and Security Test) and does not stop after the change has been deployed into the production, where testing can ensure great customer experiences. Here are some other key aspects of continuous testing.

    Continuous Testing Automates Test Environments

    Let me clarify what I mean by environment. Basically, you want to replicate the real-world situation much as possible for testing. A test environment contains the test cases to be run, the right test data and services available, and the right application version deployed in the right environment. The juxtaposition of these elements of an environment must come together automatically to ensure a continuous testing practice.

    Continuous Testing Amps Up Throughput

    A key premise of continuous testing is that you are continually maximizing efficiency. This is a must to keep up with the velocity and frequency of today’s modern software factory.

    You are doing testing earlier in the testing cycle (shift left) where problems are easier to fix and less expensive. You are doing more testing in parallel. You are automating the promotion and feedback during testing stages. And you are ideally able to prioritize the testing order based on the risk profile of the code so that you are testing higher risk areas first. All of this enables you to find issues quickly and roll forward if possible or roll back seamlessly.

    Continuous Testing Applies Intelligence

    Finally, continuous testing means you have the knowledge at your fingertips about the risk profile of a release so you can make more informed decisions. You should be able to see what was changed in the code and the implications. For example, was there a small change in the UI or a complex backend change that affected integrations and could break the APIs for the interface?

    You also need a detailed view of the quality level of the release, including which tests have failed, which tests have not been executed, whether you have tested the new or the risky areas. All this intelligence will help you to understand the quality profile of a release and make faster decisions about whether additional tests are needed or if a release is ready to go to production.

    Steps Toward Continuous Testing

    There is no perfectly prescribed way to put a continuous testing practice in place for your organization. For example, you may find that your biggest bottleneck of the moment is managing test data, so you should tackle that first. But here are five steps critical in your adoption of continuous testing:

    Step 1: Implement best-of-breed test automation tools—Functional, GUI, Performance, Security, etc.

    Step 2: Automate test environments with the right test data and virtual services to ensure real-world, always available testing.

    Step 3: Automate test requirements (you’ll find manual methods can no longer keep up).

    Step 4: Automate the automation—Connect your testing toolchain and stages. Automate promotion from one stage to the next. Automate feedback loops end to end.

    Step 5: Get smarter—Automatically align the right tests to the right app version. Automate testing sequence by risk profile of the code. Build release health profiles.

    About the Author / Uri Scheiner

    Uri Scheiner is a senior director of product management in the Continuous Delivery Business Unit of CA Technologies. He was previously a key architect and responsible for the product road map and vision at a leading release automation company Nolio, which was acquired by CA in 2012. Uri started his career as a software engineer at Mercury Interactive (acquired by HP in 2006) where he was responsible for developing several products for the DevOps and APM markets.

  • CloudBees Applies Analytics to DevOps

    CloudBees Applies Analytics to DevOps

    At the heart of many DevOps initiatives is an automation server based on open-source Jenkins software developed by CloudBees. At the recent Jenkins World 2017 conference, CloudBees showed that Jenkins is now becoming the foundational element through which DevOps teams can now manage a continuous integration/continuous deployment (CI/CD) process end to end.

    New additions to the portfolio include CloudBees DevOptics, an analytics application to aggregate data from software development pipelines as it moves through a Jenkins server. CloudBees CTO Kohsuke Kawaguchi says once organizations are armed with those insights they will be able to, for example, identify potential bottlenecks in their software development processes. CloudBees DevOptics creates a single point of reference on the status of any application delivery project, all the way down to individual commits, says Kawaguchi.

    CloudBees also launched CloudBees Jenkins Advisor, a free plug-in for a Jenkins environment that Kawaguchi says provides another watchful eye capable of continuously analyzing a Jenkins environment using algorithms the company developed. Cloudbess Jenkins Advisor comprises a knowledge base and diagnostic tools that can be employed to detect and resolve issues ranging from simple configuration issues to security and other forms of best practices.

    Finally, the company revamped the user interface provided with CloudBees Jenkins Enterprise, an implementation of Jenkins that comes pre-configured with built-in security and integrations with more than 1,400 DevOps tools. It also announced that a few select managed services providers are now building a practice around Cloudbees Jenkins Enterprise.

    CloudBees reports there are now more than 150,000 active installations of Jenkins worldwide that span a user community of more than a million. Those numbers represent a 50 percent growth rate from January of 2015.

    Most organizations employ DevOps processes to accelerate development of software. But along the way it’s not uncommon for many organizations to lose control over those processes as the amount of software being developed begins to overwhelm their management teams. CloudBees clearly sees providing tools to optimize DevOps processes based on Jenkins as its next big opportunity.

    In general, DevOps is much more of a journey than an event. But rather than being a simple article of faith, analytics can be used to show all the participants in a process that progress is in fact being made. Otherwise, resistance to increasing the number of application development projects being undertaken at the same time starts to mount. Whatever the reason for gathering those metrics, however, that old “Things Measured Are Things Done” maxim continues to apply. Those metrics also help IT organizations justify the return on investment in DevOps to senior managers.

    Of course, managing DevOps processes at scale is as much a cultural challenge as it is a technical issue. When many organizations first embrace DevOps there’s a lot of initial enthusiasm. But the further down the DevOps maturity curve an organization gets, the more they encounter various hurdles. Metrics collected and analyzed by the tools provided by CloudBees help organizations determine to what degree those hurdles are related to simple technical glitches versus organizational issues that are almost always a lot harder to resolve.

    — Mike Vizard

  • Differentiating Between CI Pipelines and DevOps Assembly Lines

    Differentiating Between CI Pipelines and DevOps Assembly Lines

    “What’s in a name?” wrote the greatest Bard who ever lived.

    All I can say is, he lived in simpler times, when DevOps and the confusing world of continuous integration (CI), continuous deployment (CD), CI/CD, the other CD, application release automation (ARA), pipelines, assembly lines, etc., didn’t exist.

    The biggest challenge today is that vendors use overloaded terms to describe completely different use cases. CI vendors claim to support CI/CD, even though the “D” here is just a deployment to a development environment and not staging or production. ARA vendors claim to enable continuous delivery, even though they do not include critical steps such as infrastructure provisioning, security patches or configuration management.

    The terms “pipelines” and “assembly lines” are relatively new. Multiple vendors have recently announced pipelines and assembly lines, and the differences aren’t obvious at first glance. So let’s do a deep dive.

    What are CI Pipelines?

    Continuous integration has evolved tremendously over the last few years. What started as a simple process of automating build and unit tests for each code change has evolved into a pretty complex workflow.

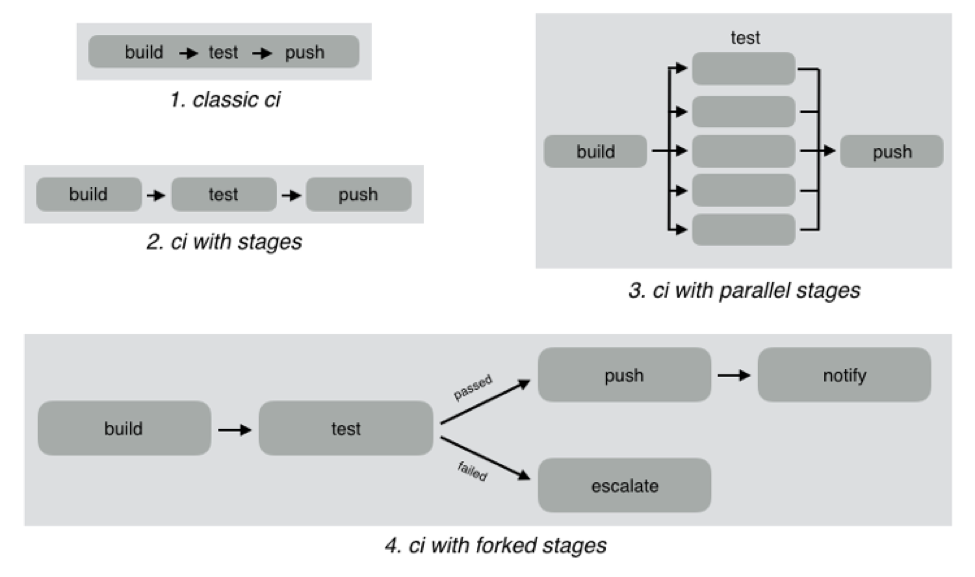
    As an example, look at the different CI workflows shown below:

    In classic CI, all build and test instructions were included in a single blob and instructions were executed serially. If all instructions executed successfully, CI was successful, and if anything failed, then it was marked failed. Almost all CI providers, until recently, offered just classic CI.

    However, as CI became mainstream, developers wanted to define more complex workflows with decision trees and parallelism. CI pipelines support this complexity, such as:

    • Defining the CI workflow in stages, so you can get results from a stage faster without having to wait for the entire workflow to finish. This also enables scenarios such as running a basic test group and only running the extended test suite if the basic tests pass.
    • Running stages in parallel, so you can split tests or test your code against different environments or language versions, and get faster feedback.
    • Forking your CI logic based on the results of a stage.

    While CI pipelines are a huge improvement over classic CI, they are still limited to developer-focused workflows. Jenkins, Teamcity, Shippable, Gitlab and CircleCI all support some form of CI pipelines.

    What are DevOps Assembly Lines?

    DevOps assembly lines are focused on automating and connecting activities performed by several teams, such as CI for devs, infrastructure provisioning and configuration management for ops, test automation for test, security patching for SecOps, semantic versioning and approval gates for release managers, deployments for multiple environments, and so on.

    Today, most organizations use various tools for automating specific DevOps activities. However, the DevOps toolchain is fragmented and gluing it together to achieve continuous delivery is a challenging task.

    Most teams adopt one of the following approaches:

    • Using cultural collaboration as the glue between silos. As an example, when a new application version is available, the test team creates a JIRA ticket and assigns to ops. Ops then copies the application version information into their deployment scripts and run them.
    • Writing ad-hoc scripts to trigger one activity from another, including passing state information through intermediate storage such as S3. In this case, the DevOps engineer would likely write a Jenkins job that runs automated tests, and then pushes application version information to S3. Another Jenkins job polls the S3 bucket, and when a change is detected, runs the deployment scripts.

    The first approach introduces inefficiency and unnecessary human-dependent steps. The second approach is better, but only works well for small teams working on a single application. It creates a Frankenstein of spaghetti automation when you have many applications or even a single application with microservices.

    DevOps assembly lines address this problem by focusing on gluing together these various DevOps activities into streamlined, event-driven workflows with the ability to easily share state and other information across activities.

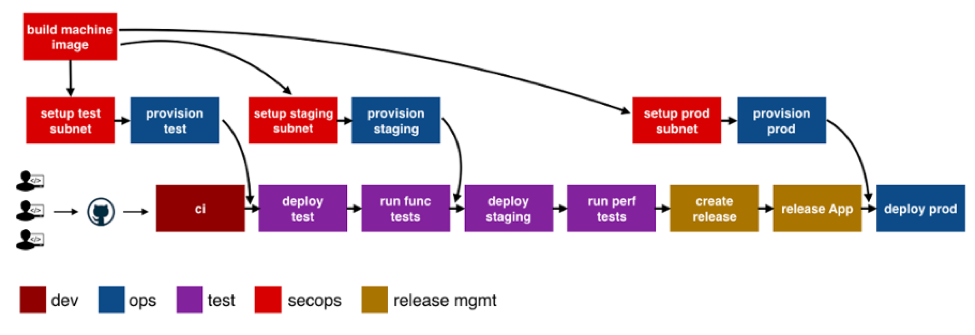
    The following image shows a typical assembly line for a single application or service:

    See the difference? The CI pipeline is just ONE activity in the assembly line. Each of the boxes in the picture above is a pipeline, just for different activities! Each has specific needs with respect to tools integration, runtime, configuration, notifications, etc. In addition, each pipeline is owned by a different team, yet needs to interact with other pipelines and exchange information. For example, if the ops team changes provisioning scripts for staging environment, the test team needs to redeploy the application and run performance tests.

    A DevOps assembly line is, therefore, a “pipeline of pipelines.”

    DevOps assembly lines need to support the following:

    • Ability to easily define workflows across multiple pipelines.
    • Versioned and reusable workflows, enabling rapid changes and scaling for multiple applications and/or microservices.
    • Integrations with all popular source control systems, clouds, artifact repositories, DevOps tools, languages, services, etc.
    • Runtime to execute every pipeline, including pre-installed tools and CLIs, and the ability to use the right runtime, depending on pipeline type.
    • Accelerators/playbooks for common pipelines and tools.
    • Ability to pass state and other information while triggering dependent pipelines.
    • Automatic triggers or manual approval gates between each pipeline.
    • Configurable notifications for each stage of every pipeline.
    • Release automation features such as semantic versioning of packages.
    • Audit trails for each pipeline, with the ability to go back or forward to a specific state.
    • Abstraction of all sensitive information like passwords, tokens, keys, etc. for security reasons.
    • Roles and permissions restricting assembly line and pipeline actions.
    • Manage DevOps infrastructure, including spinning VMs and containers up and down as required.
    • Visibility into each pipeline and stage, including logs, status and versioned data.
    • Metrics and Analytics across pipelines to help identify bottlenecks.

    In short, DevOps assembly lines help automate and scale end-to-end workflows across all teams and tools, enabling continuous delivery.

    About the Author / Manisha Sahasrabudh

    Manisha Sahasrabudhe is co-founder and vice president of product management at Shippable. Prior to Shippable, Sahasrabudhe was senior program manager at Microsoft. She can be found online at Linkedin.
     

  • DevOps Chat: The Continuous Delivery Map w/ Scott Wilson, Automic

    DevOps Chat: The Continuous Delivery Map w/ Scott Wilson, Automic

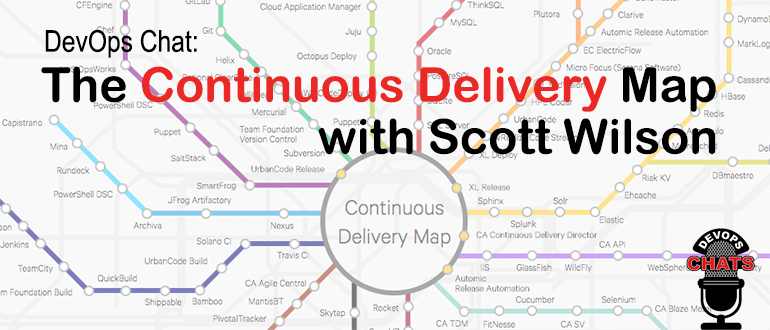
    Wouldn’t it be nice to have the entire continuous delivery topography laid out in a nice map that shows how they are all interconnected? Sort of like a subway or metro map? Well now you have it and it is interactive! The good folks at Automic, a CA Technologies company just released their Continuous Delivery Map. It is really cool and they are adding to it all the time.

    I caught up with Scott Wilson of Automic and had a chat about the Continuous Delivery Map. As usual the streaming audio of our conversation is immediately below, followed by a transcript of our chat.

    Audio

    Transcript

    Alan Shimel:                Hey, everyone, Alan Shimel, devopsy.kinsta.cloud here for another DevOps Chat. Welcome and welcome to our guest, Scott Wilson, Automic, a CA Technologies company. Scott, welcome back to DevOps Chat

    Scott Wilson:               Thank you, Alan. I’m glad to be here.

    Alan Shimel:                Glad you’re here with me. So, Scott, you know, lot going on with Automic, obviously – always is – but I wanted to focus in today on some pretty cool interactive graphic – well, it’s more than just a graphic. It’s really a whole project that you guys have launched and it’s called the “continuous delivery map.” For those following along at home, if you wanted to check it out, you can get to it at automic.com/continuous-delivery-tools and – dash or a hyphen. Scott, you know, assuming people are listening to us but not able to get to the site this second, can you describe for us what the continuous delivery map is?

    Scott Wilson:               Yeah, so the continuous delivery map is really just a way to visualize a topography, if you will, of all the different tools that are in the continuous delivery value chain, and there are lots of tools. And we found, in talking with a lot of prospects and just other companies in the industry, that amongst IT professionals there’s a bit of confusion on what kind of the best use case is for many of the tools, mostly, Alan, due to so many of these tools having a great deal of crossover functionality, right? It’s kind of muddied, blurred the lines a bit.

    And so, in thinking about a good way to help people out and kind of visualize the tool chain used to get an application into production environments, we took inspiration from metro rail systems, like the London tube or the New York subway, and so we built out a map that looks similar to that.

    Alan Shimel:                Yeah. I mean, for those of you, as I say, who maybe can’t get to a computer right this second, as you’re listening to this, it really is. It’s based on a subway map or a tube or it could be the Washington metro or the Boston or Tokyo or anyplace else, in that you have a central hub and then there’re different lines that are color-coded. And each of these color-coded lines represent a lineage or a line of a particular functionality in the continuous delivery world. So, for instance, there’s a line for cloud, IaaS and PaaS. Another line for middleware, another one for CI tools. Another one for artifact repositories. And, along that line, the stops are all of the different companies that kind of play within that are or are on that, and it’s not just companies – it’s actually the products of these companies that play on that particular branch, if you will.

    So it’s actually pretty cool, Scott, and what I like about it too is, though, look, plainly and clearly, Automic is a vendor. I mean, there’s no favorites here. You’ve done a pretty exhaustive mapping or the whole topography of the continuous delivery world, it looks like, to me anyway.

    Scott Wilson:               Absolutely. We really wanted this to be agnostic for the tools. We’re really just trying to help the community understand, you know, the landscape for continuous delivery, and, as you mentioned, the central hub is really the way you would bind all those many plethora of tools into a coherent pipeline, right, to safely and reliably deliver apps to production environments. And, yeah, this definitely respects that. Ultimately, we’re gonna be opening this up to the community so that people can comment or keep this updated ’cause there’re always new tools coming on board and other tools or open-source projects that kind of fall out of vogue, so we’re looking to really make this more interactive and far – we’ll keep it up to date.

    Alan Shimel:                Yep. And, you know, again, trying to visualize or paint a picture for people who don’t have it in front of them, at every stop on every branch, if you will, it’s a link, and if you click on that link, it gives you a little pop-up with a little information about that particular company or product but also links through to their full websites or what have you. So it really is – I could see this being a really useful tool for anyone interested in the CD kind of world. There have been – I mean, clearly, Scott, right? Full disclosure: there’ve been other companies that have tried to organize, if we will, the CD world, but, really, using this paradigm of the subway map and the branches and lines, if you will – maybe it’s just ’cause I’m from New York and I’m used to subway maps –

    [Laughter]

    – makes a lot of sense to me.

    Scott Wilson:               Right. Well, we’ve heard that feedback as well that that’s just – well, you know, continuous delivery’s about movement, right? You’re moving things along and it just seems to help visualize it. You know, a lot of the data from what other folks have done is similar, right – a big list of tools – but just being able to put it in a format like this, we’re finding a lot of people go, “Ah, this makes sense. I would use these set of tools. Source code management fits here and deployment automation fits there.”

    And it’s helpful because I think, without presenting it this way, you’re just left to a hodgepodge of tools and you’re like, “Yep, I got ten of these and two of those and I’m good.” When you look at it in this format, you realize, “Oh, well, I could actually go further. I could do more or I could better organize things,” or maybe even take some of the burden off a tool that you keep having it be more than it was designed for and actually use a best-of in another category, or, as we represent it as, a color-coded rail line.

    Alan Shimel:                Yeah. Yeah. And, of course, you know, the thing about projects like this, Scott, is they’re, in some ways, a never-ending story. They’re constantly morphing, changing, growing. And, I mean, the good news is you’ve got a great start right here; the bad news is you guys need now to keep this up, week in, week out, month after month. What are the plans, going forward, to keep it current and fresh?

    Scott Wilson:               Excellent observation and point. We are looking to ultimately open this up to the community, so this page will not only be as it is now; it’ll be far more interactive, where visitors can come in and recommend tools that aren’t on here, maybe further defining particular lines or branches that we have, upvoting, downvoting various tools, and, yeah, so we’re looking to have that community help us keep it up to date. In just doing the research for this and playing with many of these tools and looking at their viability to be on the map, as you said, it was a ton of work. And so it’d be impossible, with the growing market, to do that on our own, and we’re definitely looking forward to collaborate with the DevOps community at large in keeping this current, the information current and fresh and, of course, far more interactive and useful, as we go forward.

    Alan Shimel:                Yeah. I mean, you know what? I mean, this is great and I don’t know how you would visualize it, but it would be great to show sort of connected dots, in terms of how companies or products actually integrate or work together. But that –

    Scott Wilson:               So, yeah, not to give away – [chuckles] – so much what we’re planning, but, yes, you’re absolutely correct. That is something that is on our roadmap, what we’re planning. Indeed, what we think would be useful for this is to allow us to kind of rank or order the tools and use a kind of a most popular or what the market, the community says, “Now this is the best practice set of tools.” A simple example would be SQL Server and Oracle. Right? If you’re going down the RDBMS line, the database line, then, well, those two are kind of the giants. And so by ordering them such a way, you would be able to come in, list the tools that you have, and be able to visually see, “Are you kind of following what everyone, what the consensus best practice is? Or are you have a lot of outliers?” And I suspect a few outliers here and there are okay, but, you know, if you’re going two four outlines, you might be putting yourself at risk.

    And sometimes I think it’s just to help you answer that big question, is “I don’t know. Should we go with this tool or this tool?” Well, you could come here and, in future releases, be able to see what the community is saying the best of or the next best of, right, and have it ordered and you’d be able to see that in a nice map, visual way, to understand and help you to, hopefully, make decisions on what tooling you should consider or not.

    Alan Shimel:                You can also see if you’re taking the express or going on the locals. There’s a lot that a clever marketing person and someone with a good knowledge of the market here in the CD space can really make some hay with this, Scott. And, you know, beyond cute, it’s actually pretty – a really useful tool here.

    Scott Wilson:               Yeah. Appreciate that. Like I said, we’re looking to make it far more useful and what you hinted to and what I’ve just discussed is really make it really interactive and help you measure yourself against what the market or the community is doing, what the norms are, best practices and so forth.


    Alan Shimel:                So I’ll include a link to this, Scott, in our show notes when we publish, but, for those who may be listening on iTunes or SoundCloud or audio only, again, the URL for this CD map is automic.com/continuous – dash or hyphen – delivery – dash or hyphen – tools. And you could check it out there. Scott, you know, in real DevOps fashion, upgrades here will be continuous, right? There’s not a Linux version planned or anything like that, I would assume

    Scott Wilson:               Correct. Yes. So we have continuous sprints planned. New vendors are actually in our current sprint, that are coming out, and, yeah, so you’re absolutely right. If we’re gonna do something on continuous delivery, then we ourselves are looking to be agile and looking to keep it fresh and then, ultimately, have one of the inputs to those sprints be the community, community feedback and input.

    Alan Shimel:                Got it. So, Scott, this is really great. Congratulations to the whole team at Automic who worked on it. It’s a piece of work here that I think is highly useful. What else is new at Automic, Scott? Anything noteworthy you wanna report on

    Scott Wilson:               Well, what we’re shipping here lately, in the next few weeks, is a incremental release of our application release automation product, version 12.1. There are several enhancements that are coming out, going GA here, in the coming weeks. We’re pretty excited about that and some of the additional enhancements. There’ll be a lot of information coming out in a few weeks about all of that and the functionality and things that we’re doing with that. And then, you know, just additionally, the growth and recognition within the CA company, as an automation business unit, and, yeah, we’re keeping pretty busy with automating not just things within the continuous delivery value stream or DevOps tool chain, but also within the CA ecosystem itself. There’s a lot of growth. And so, really, what’s happening with Automic is we’re really able to help show how we can automate, really, the modern software factory.

    Alan Shimel:                Yep.

    Scott Wilson:               That’s kind of one of the – falls in line with what CA is trying to do, one of the core tenets. They’re trying to reach out to the community and the marketplace.

    Alan Shimel:                Absolutely. All about software development life cycle and software supply chains.

    Scott Wilson:               Yeah.

    Alan Shimel:                Well, Scott, thanks for giving us a peek behind the scenes at the continuous delivery map. We’ll try to feature this on devopsy.kinsta.cloud and we’ll be watching as it continues to develop, adding even more features or functionality, but it’s pretty cool stuff.

    Scott Wilson:               Well, thank you very much and, as always, I love being here and grateful you had me.

    Alan Shimel:                Well, we’ll have you back on again then. You know, Scott, flattery will get you everywhere.

    Scott Wilson:               [Laughs]

    Alan Shimel:                Thanks

    Scott Wilson:               That’s so true, isn’t it?

    Alan Shimel:                Yep. We’ll have you on again. Scott Wilson, Automic, a CA Technology company, talking about their new continuous delivery map here on DevOps Chat. Scott, thanks for coming. Hey, everyone, thanks for listening. Hope to see you soon on another DevOps Chat. Until then, I’m Alan Shimel for devopsy.kinsta.cloud and we’re out of here. Thank you.

    — Alan Shimel

  • XebiaLabs Shows Off ARA, More at Jenkins World

    XebiaLabs Shows Off ARA, More at Jenkins World

    In this third spotlight on companies attending Jenkns World, another worth checking out came to mind, so I am taking a look at what XebiaLabs intends to do while there. XebiaLabs is one of the leading application release automation (ARA) vendors, and has a long history of working with Jenkins, so it’s a little more mainstream than the other companies I’ve written about.

    But the thing is that Jenkins’ and XebiaLabs’ tools do work well together, offering an end-to-end build/deploy process that is repeatable and can be repurposed for different targets or different applications.

    While Jenkins handles CI/CD, XebiaLabs ties in the deployment pieces to complete the picture and make a streamlined system. When I experimented with XL Release and XL Deploy, I used them to call Jenkins as part of the release process. Interestingly, you can also call them from within Jenkins, which dovetails well with what another vendor I looked at—CloudCoreo—is doing. The ability to control the process from Jenkins is nice and has uses in the early development phases, but XebiaLabs raises the level of release management—something Jenkins is not doing (yet). The bit that ties CI/CD to automated deployment should be running the show, IMO. But I can imagine environments where kicking off all the build/release cycle from within a Jenkins job would be the preference.

    Anyway, on to what XebiaLabs is doing at Jenkins World!

    Key for XebiaLabs this year will be showcasing its DevOps platform, which is both XL products and talking about how the company is advancing integration between these products and Jenkins. Its recent Templates as Code (the link is to an earlier version, from January, but talks about its goals with Templates as Code, so it’s a good start if this is new to you) implementation that made it easier for developers to work with its products is being enhanced, and I’d love it if someone took a look at it and told me what they think. I can probably get someone at XebiaLabs on the phone to talk about it, but real users often have a better take on suitability in the wild.

    The important bit for many of you will be XebiaLabs’ Periodic Table of DevOps Tools, which I know several people would love to have as a poster in their office. For cool factor, it’s hard to beat. The company will have tubes with the periodic table available, so drop by to snag one. Last year it ran out of them relatively quickly, so be early. Bonus points to anyone who snags an extra and sends it to me for my office (ha ha).

    Aside from the Periodic Table of DevOps, XebiaLabs also will have copies of “The DevOps Handbook,” which I recommend. For those who haven’t read it, the format is different than “The Phoenix Project,” but it is the next logical step in that progression. Finally, the company will have its own book, “The IT Manager’s Guide to Continuous Delivery,” which I haven’t read, but having read XebiaLabs’ corporate blog for a while now, I predict will have some good ideas in it.

    I admit an interest in how recent changes to XebiaLabs’ DevOps platform improve the experience across the org (or don’t improve it). I haven’t used its tools since the new “pipeline as code” changes were introduced in January, so I honestly have no idea. If you go and stick around for a demo, let me know what you think.

    — Don Macvittie

  • Don’t Underestimate the Work

    Don’t Underestimate the Work

    It is relatively common in human endeavor to attempt to figure out how much work will be involved in a project, and be wrong. The more complex the work being done and the organizational system doing it, the further off estimates can be. This was one of the drivers for both Agile and DevOps: to take smaller steps with less dependencies and complexity.

    The complexity problem is true in the path to application release automation (ARA) as well. ARA merges continuous test/continuous delivery with deployment automation, but both of these toolsets are complex and continuing to evolve. When you think about it, it is somewhat amazing that ARA can handle the breadth of functionality it is covering, while both sides are shifting and growing as well as it does.

    Construction Crane
    Construction Crane, compliments of Pixabay

    When you approach ARA, you should make certain you have a handle on the amount of work that it will take to get the system up and running. It’s not simple, even if you’re already using a full CI/CD environment. But it’s worth the work, so here are some of the things to watch out for.

    Multiple Targets

    First on the hit list is on the deployment side. One of the strengths of ARA is the ability to deploy to any environment. The ARA system has to know about each environment in enough detail to enable deployment on it. It must know how to deploy servers, where to get OS, what needs to be added on to the OS, and how to get the application onto these systems. Increasingly, programmable network elements and security configuration fall into this category also. While tools such as Chef and Terraform can help in this regard, if you’re not already using them, they’ll have to be configured if not already, and then linked into your ARA tool. Understanding the path from here to there is critical to early success with ARA.

    Databases

    This is one of the more vexing problems. While most ARA tools offer the ability to configure databases and database connections, your datasets generally don’t hop around so easily. So if you’re testing and deploying on separate networks, you’ll need to make sure that the relevant tables are on those networks. This struggle impacts moves to the cloud, changes from a fully test network to production or any other change that requires the database server be accessible when it hasn’t been in the past. The work to solve these problems is pretty wide. In some cases, such as purely internal or purely cloud, merely routing from the relevant app instances to the database server will do it; but, in the case of across-the-internet changes, it will take a lot more work. Make certain you understand what challenges you will face before moving.

    Tooling Sets

    Much of the external needs of an application are baked into the app build process through tools such as NPM or Git. But those tools don’t cover everything necessary for the entire app ecosystem. Agents, per-tool databases, small tools used occasionally—make certain you have a list of what makes the app work, and make certain they’re configured to be built in by the ARA tool. This sounds obvious, but watching a team learn by trying to deploy and fix broken parts only to do it again is not only painful, it also leaves a “Did we get everything?” impression. I saw one app break on deploy because the team didn’t include curl. Yes, curl in the deployment. Test had it in the environment, production did not.

    Get an inventory of both application development dependencies (libraries, etc.) and deployment dependencies (databases, reporting tools, agents for monitoring, etc.), and save yourself some pain.

    Decrease Your Work by Asking Questions

    ARA gives you a repeatable build/deploy process that can be used to target the environments you need while reducing manual scripting and steps. But before you throw in, sit with your vendor’s tech people and ask them to walk you through stumbling points, they likely know far more gotchas than I do, because it’s their job, and unless you got the new guy for an SE, have probably seen more. And getting ARA up and fully functional quickly allows you to focus on other DevOps needs, such as improving automated testing.

    — Don Macvittie