Tag: automation

  • A Three Step Roadmap for Enterprise DevOps

    A Three Step Roadmap for Enterprise DevOps

    The extremes of application release velocity are converging in the enterprise. Whereas Fortune 500 enterprises may have historically taken months to years for each release cycle, they are exploring new approaches from new age Internet technology firms that release new versions of an application several times in a day.

    According to a recent report on DevOps adoption, 86% of IT and business decision makers have either implemented DevOps or will roll out DevOps initiatives within the next 3 years. There is a strong appetite for enterprise DevOps, but where do you start?

    For DevOps projects, Ops will need to shift from a systems management approach to a programmatic approach. Ops should work with Dev to figure out the automation required to provision and deploy the application. Here is a three step roadmap for enterprise DevOps for those organizations looking to roll out successful DevOps initiatives:

    Step 1: Select The Right Application Candidates.

    Not every enterprise application is a right candidate for DevOps. Traditional applications are not architected for DevOps velocity, whereas enterprise applications designed with agile and iterative techniques are excellent candidates for DevOps. DevOps may be an overkill  for applications where the underlying business process rarely changes. Dev and IT Ops should choose one or two applications for DevOps style implementation.

    Step 2: Manage Your Application Lifecycle With Automation.

    Provision applications as part of the build process itself. During deployment, Ops should be able to execute a piece of code to identify application monitoring needs. Your automation framework should manage application health without manual intervention.

    • Can you fix application issues using runbooks?
    • Do you have scripts for scaling, maintaining, and load balancing the application?
    • How do you plan for new releases?
    • How do you upgrade the application?

    Treat your infrastructure as code. Application configuration, deployment, and maintenance all need to be part of an automation framework. Ops should build concurrency with the application. You should be able to configure, deploy, and bring the entire application live within no time.

    Step 3: Embrace Compliance Driven Operations.

    Your IT Ops automation framework should deliver the right visibility to support more frequent releases without complex manual processes.

    • Are you able to automate monitoring of the infrastructure for delivering the best end user experience?
    • How do you ensure that the right infrastructure resources are available for running the application?
    • Can you keep your infrastructure current by maintaining the right patch levels?

    Enterprises can modernize application delivery pipelines by selecting the right application candidates, managing application lifecycles with automation, and embracing compliance driven operations. While you might never deploy code 23,000 times a day like Amazon.com, the Enterprise DevOps framework will help you release applications faster, with higher quality and lesser risk of deployment failure.

    About the Author / Varma Kunaparaju

    YaCNNVuUVarma Kunaparaju is CTO at Vistara and a seasoned technologist with over 20 years of experience leading engineering teams to deliver enterprise software. Reach him on twitter at: @varma1


  • Continuous Testing – Accelerated !

    Continuous Testing – Accelerated !

    Except for cases where test duration is the point of the test, as indicated in my prior blog “Isn’t Continuous Testing a Longevity Test Anti-pattern?”, faster continuous testing cycles are preferred because failing early and often is a DevOps goal. There are multiple reasons for this, but it should be evident that faster tests reduce the wait time to get results and since there are typically many development team members looking for results the developer time savings multiplier effect is huge for every minute of test time saved on each CI/CT cycle. When aggregated over multiple code branches a few minutes saved per test can be man-years of time saved over a year!

    So what can be done to accelerate continuous testing? Frankly a thorough answer to this topic could fill a book. Below are some suggestions in a checklist format intended to be useful for DevOps .

    1. Organize the team for speed: When team members and the organization are explicitly selected for CT speed the entire DevOps process will be accelerated.
      • A test architect familiar with the principles of best practices test environments and continuous test design is critical to design and tune continuous testing for speed. The architect establishes the CT strategy and speed goal relative to the coverage goal.
      • A test analysis team reviews test results so no time is wasted on results analysis.
      • Developers and test members are trained on best practices test design and their test scripts are peer-reviewed to ensure they comply with the strategy.
    2. Select powerful test resources: Powerful, dedicated, scalable resources will accelerate all test processes and shorten the time to results.
      • Select the fastest processors, low latency storage and I/O to initialize and execute both the test systems and system-under-test entities quickly.
      • Dedicate resources that have longer initialization times so they can be pre-initialized.
      • Virtualize resources that can be scaled horizontally without sacrificing speed.
      • If affordable, arrange enough resources to run ALL tests in parallel.

    3. Choose test tools that are designed for fast test execution: Look for the following features when you are evaluating test tools. Not only will this save you a lot of headaches in the long term, it will give you the flexibility to design tests that integrate with other DevOps tools.
      • Restful APIs that do not require wait states between commands and responses
      • Priority queuing of test cases
      • Creation of test topologies that can be pre-loaded
      • Ability to spawn out tests in parallel to run on any number of machines
      • The ability to park a test that needs to wait for an event and return to it after proceeding with subsequent tests
      • Caching features that enable initialization and results data to be processed for one test while the tool proceeds to execute other tests
      • Multiple devices, session types and results data processing utilities implemented as an embedded part of the tool and not requiring slow speed scripting
      • The ability to render commonly used test utility functions in a fast execution language.

    4. Organize test schedules and test suites to fail early: The sequence and approach for scheduling of test cases greatly affects the speed of testing. If possible the scheduler should launch all tests in parallel as soon as the build is ready. Otherwise priority schemes are needed.
      • Organize the test scheduler and test suites to avoid any unnecessary tests.
      • Cache initialization and topologies data and resources ahead of the next test execution.
      • Check the test environment before running tests, abort if invalid conditions are detected.
      • Organize tests so the most important ones are run first.
      • Set a failure escape threshold and abort the test if exceeded.
      • Eliminate dependencies between tests so that each one can run standalone or in parallel. Queue the next test while a test is running.
      • Use smart gray box testing methods to limit test selection to the most important tests according to the software change and skip tests that are low risk.
      • Run longer tests in parallel with shorter ones.

    5.Design test cases to fail early: The test cases themselves need to be designed with the strategy to get test results as fast as possible.
    • Design each test case with a single unique test purpose and make it self-contained so it may be scheduled to run standalone or in parallel with any other test case.
    • If a test case has multiple verdicts arrange the highest priority verdicts first and close the test at the first failure.
    • Prune or refactors tests that have a low failure history.
    • Shorten dead-script timers, and make any wait timers conditional so they can expire as soon as the condition is met.
    • Reduce the number of test iterations to fit a time budget.
    • Reduce communication wait times by using the fastest protocols. Optimize the most frequently used utilities.

    1. Arrange test results reduce to minimize analysis wait times: Arrange the test results to be consumable as soon as the tests are run so the system does not bottleneck.
      • Report test results as the tests are run and accumulate the results across parallel test targets.
      • Establish thresholds for aggregated test results and abort the tests and release test resources to be used by other tests if the thresholds are exceeded for any run.
      • Keep track of test timings and adjust the test schedules according the average and peak run times for each test case.
      • Separate test result report processes to persistent resources so no test process is waiting to finish a report and the test process can proceed to the next test in parallel with test results.
      • Correlate the test results to the changes and use trends analysis to help speed up diagnostics and as an input to test selection such that the most failing test cases are given higher weight in future test runs.

    The above is a partial list of suggestions for accelerating continuous testing that have been proven to yield good results for accelerating continuous testing and DevOps.

    At Spirent we think testing has a bright future in DevOps. You can read more about our views at Spirent.com/solutions/devops

    What do you think of these suggestions and do you have others that should be mentioned?

  • Webinar: Application Release Automation at Scale

    Webinar: Application Release Automation at Scale

    Logo_EC_corp_Large_Web_RGB

    Organizations of all shapes and sizes depend on feature-packed application releases to keep end users productive and happy. As application complexity grows, managing deployments manually becomes more difficult and slows down the pace of business.

    Join Amy DeMartine, Sr. Analyst at Forrester research and Mike Hamrick, Software Configuration Management Lead at Lockheed Martin, servicing CMS Centers for Medicare & Medicaid Services, as they discuss:

    1) How Application Release Automation (ARA) solutions eliminate error-prone manual work, decrease risk and increase uptime

    2) How Infrastructure and Operations teams in large organizations overcome modern service delivery challenges

    3) Best-practices and tools for overcoming the challenges of ARA at scale


    Event recorded Thursday April 2nd, 2015

    Click here to register to see it On Demand


    Video

    Slides

    [seoslides embed_id=”a3d2f6e4e229″ script_src=”https://devopsy.kinsta.cloud/embed-script/electric-cloud-webinar/6046/” overview_src=”https://devopsy.kinsta.cloud/slides/electric-cloud-webinar/” site_src=”https://devopsy.kinsta.cloud” site_title=”devopsy.kinsta.cloud” title=”Electric Cloud Webinar” /]


  • Building software quality into your Continuous Delivery pipeline

    Building software quality into your Continuous Delivery pipeline

    The modern software development landscape places a premium on speed. It’s good to be first to market. If you’re going to fail then you should fail fast. A rapidly evolving product can be shaped according to customer feedback, and fast turnaround allows you to stamp out defects and hone the software for your audience.

    A continuous delivery pipeline enables you to act and deliver more quickly. But you need to build in quality metrics to ensure it retains a laser focus, and doesn’t become an out-of-control fire hose. It may require some front-loaded effort and resources to set an accurate measure, but the resultant software quality turns short term cost into long term savings.

    Plan for quality

    You can build the expectation of quality into your software development process from the start. Design your tests before a line of code is written. Create a test architecture that can be woven into your CD pipeline. Build a self-adjusting system that applies the right tests at the appropriate time in development, covering unit tests through to performance testing. That way you always have the real-time insight you need into your software quality.

    Why wait?

    Test-driven development can save time and resources. By waiting for functionality to be developed before writing up your automated functional tests you’re creating more steps to complete than is necessary, and slowing down the process.

    You need real examples of each feature and piece of functionality in order to design and implement it anyway, so why not create them from the beginning? They can serve as acceptance tests and keep developers focused on the core requirements for your software.

    This can only work if you ensure that you have group buy-in from day one. All stakeholders must be involved in the acceptance test design. If you fail to get the input you need about what constitutes a holistic view of your software quality, then you can expect feedback that raises new concerns down the line. By that time it will be more difficult and expensive to retro-fit new quality metrics.

    Aim for automation

    The more of your acceptance criteria you can automate, the better. It provides you with a mechanism for taking the temperature of your software whenever you want to, for a clear picture of its health.

    Naturally, there will be acceptance tests that you can’t automate. You shouldn’t try to automate everything. There’s no substitute for human insight and it’s notoriously difficult to predict your end user’s first impressions.

    Functional tests are ideal candidates for automation, provided your test architecture considers optimization for regression and remains flexible enough to accommodate new examples when required. For the most efficient use of your resources you need to build in an understanding of dependencies. You need control over the decision on what to test and when, based on the quality attributes you’re examining.

    Failures will be flagged at the earliest eventuality for all stakeholders, maximizing your opportunity to address them quickly. By building these quality metrics into your CD pipeline you can go live with confidence.


    About the Author/Viktor Clerc

    author-342342342Viktor Clerc is product manager for testing applications at XebiaLabs, a provider of automation software for DevOps and Continuous Delivery helping companies to accelerate the delivery of new software. You may reach him at vclerc@xebia.com.


  • Isn’t Continuous Testing a Longevity Test Anti-pattern?

    Isn’t Continuous Testing a Longevity Test Anti-pattern?

    Accordingly to Jim Coplien: “an anti-pattern is something that looks like a good idea, but which backfires badly when applied. “ In DevOps context, continuous testing is an attractive solution for the narrow context of testing specific software components quickly (in cycles measured in minutes or hours) but may be “bad” if the system that the software is a component of has failure modes (E.g., effects of memory leaks) that will only be observed during long term testing over several days and if the time between releases is greater than that. In other words, the pattern of quick test cycles prescribed by continuous testing appears to be a contrary Anti-pattern to the fundamental concept of long duration “longevity” testing. So what are the well formulated positive patterns that are applicable in its stead?

    In my prior blog entitled “From QA to Continuous Testing” I indicated “QA test experts that are most skilled in the best practices of test design are valued because they will produce the best quality products.” QA test experts assert that it is unwise to release a software product that has not been tested for durations comparable to the lifecycle of a release. Only tests that are run for a significantly long time compared to the release cadence are deemed sufficient. Just how long is long enough? This is a subject for further discussion beyond the scope of this short article, but my own observation is that best practices test environments run accelerated level load and impulse load traffic patterns on a build candidate for at least 48 hours or more before a release is determined sufficiently tested for at least limited deployment. Even 48 hours is much longer than typical “continuous testing” cycles. So “what positive continuous longevity testing patterns are applicable in its stead?”

    Continuous Longevity Testing Patterns may sound like an oxymoron but in fact longevity testing is compatible within the context of continuous testing principles. Below I describe three Continuous Longevity Testing Patterns that are sometimes used.

    Pattern 1: Longevity testing time windows are reserved such as weekends. In this pattern the regular Continuous Integration/Test cycles are interrupted during the weekend and longevity tests are only run on the build that was last created prior to the weekend time window. This has the advantage of not requiring any special test resources other than the resources used for regular CT tests and does not require any sophisticated scheduling to orchestrate the test environment. The disadvantage is that the longevity test results are only available weekly, it is hard to diagnose which build caused a longevity failure and problems with release candidates will delay the release for a week until the next longevity test run validates the fixes.

    Pattern 2: Longevity parallel testing is scheduled frequently, perhaps as frequently as every few builds, or perhaps daily. This pattern has the advantages that the regular Continuous Integration/Test cycles are not interrupted any time (they run 24/7), the longevity test results are available for more builds than Pattern 1, which reduces diagnostic complexity and may reduce release delays, but has a disadvantage that separate test resources must be reserved for each longevity test in parallel with the regular CT tests. For complex systems under test with many test targets and lots of builds this can be very expensive so there is a tradeoff between test resource costs, and the cost of delays if not done frequently enough.

    Pattern 3: Intelligent longevity testing is scheduled only when certain conditions trigger the longevity tests to be started according to smart rules that correlate software changes to problems with longevity performance. This pattern has the same advantages as Pattern 2 and has the further advantage that the cost of test resources is usually much less than Pattern 2 if the rules for the triggers don’t fire too frequently. The disadvantage is the entire scheme depends on the creation of a rules engine and rules that understand the risk of changes for long duration testing. If the rules are too lenient then this pattern might allow too many longevity failures to escape but if the rules are too tight then this pattern is not any better than pattern 2 and yet more complex to implement.

    So which Continuous Longevity Testing Pattern is best? The best answer is the one that best matches organizations’ goals for release cadence, cost of testing, and risk.

    So indeed, Continuous Testing is a Longevity Test Anti-pattern but fortunately DevOps infrastructures implemented according to best practices have a variety of complementary Continuous Longevity Testing Patterns to choose from.

    At Spirent we think testing has a bright future in DevOps. You can read more about our views at
    Spirent.com/solutions/devops

    What do you think of these patterns or do you have others that should be mentioned?


  • DevOps & Continuous Change

    DevOps & Continuous Change

    A remark by a colleague while waiting for the coffee machine to complete its cycle started my train of thought. “Should we have multiple minor releases or just do a few major ones in a year?”

    In large organizations, due to many factors, the turnaround time for a single successful release is quite extensive; but if the conceptual change which we are talking about bringing whilst using the #DEVOPS methodology would not only reduce these long cycles but deliver quicker and quality software.

    I have already discussed in my earlier article “DEVOPS: Getting our organizations aligned” on the traditional approach and how the combination of this two (DEV & OPS) has been proven beneficial in various organizations and how many are still hesitant in embarking on that path.

    Continuous Change which encompasses both Continuous Integration and Delivery is paramount to achieving this objective. To attain the objective of delivering rapid and consistent value to the stakeholders regularly, we have to have Continuous Change happening.

    I am sure we have already moved out from the Mainframe era to a more Distributed systems state. But unfortunately we have yet to let go of that culture where we pile up components on a single quasi Distributed Application, instead of creating smaller independent, yet interdependent systems.

    So, back to the same question; shall we go with a few Dinosaur sized, labored releases or make multiple short and swifter runs? In my opinion, we should strive towards the leaner model. Easier said than done you say! Agree. If I have to, then I would go about it this way:

    In an environment having a suite of Distributed Applications, start with Analyzing the components which make up the Major release, List out the changes (fixes and new features) which are planned, asses functional and technological impact, Identify dependencies, upstream/downstream connectivity’s, architectural deficiencies, list out the identified subset of components or group of components by functionality, which can go as an independent release.

    I am resisting the urge to say ‘standalone’ as with the current set of complex intervened collection of applications, it would be an incorrect statement. It would rather be a subset of components which can be independently upgraded. Now the big task is to review and decide if this subset or group would add functional value to the overall suite of applications without the rest of components going in.

    Once identified, the success of this release working as expected would be in the extensive testing (Unit/ Regression/Performance) of these components, and as we gain confidence in this split and deploy procedure, we can start with, prioritizing and scheduling critical must have features or bug fixes which also should be backward compatible with other components lagging behind. We can even come up with scenarios where these components are not just getting updated frequently, but would also have multiple independent tracks. Of course it goes without saying the testing and signoff process is strictly followed albeit in a shorter window.

    Deployments to production have always been a source of heartburn to the OPS teams, we have often seen finger pointing and firefights to contain change fails. In order to maintain stability and maximize availability, stricter controls and reduced deployment windows are put in place. In promoting frequent and smaller component level changes, OPS will also be in control of what’s going in, and smaller component level releases can be rolled back quickly within the Green-Zone window if the change is not working as expected. Though I would categorize this rollback, as a process fail than a deployment fail, and should be reviewed very seriously with right mitigation plan and lessons learnt retrospection, Continuous learning after every successful or failed sprint ensures competent and confident releases.

    Another major factor impacting multiple runs of Production releases is the long Green-Zone windows, by moving to the quicker and leaner deployments cycles, these requests can be substantially reduced, and can eventually aim to reach a stage where changes are deployed online without extensive downtime.

    Similarly, frequent maintenance activities when there are no planned deployments, effectively has the same risk on environment unavailability. Analyzing and moving to a state where these activities are conducted online without a Green-Zone would alleviate the maintenance downtimes and ensure seamless availability, adding stakeholder value.

    I have not touched on the Continuous Integration or the Automation of the deployment process for obvious reasons, we can’t achieve the objective of Continuous Change without having the Integration process in place where incremental changes to code are build into a package swiftly and seamlessly, even a sanity or basic testing might be integrated to ensure the quality of the builds. Same goes for automating the deployments, develop & integrate tools required for rapid deployments. We have seen instances where automating a single activity or revisiting a process has created substantial time savings.

    While it’s easy to propose changes to the Release Process or advocate rapid deployment cycles, we have to ensure adequate checks and balances are in place, compliance adherence and audit trails are created.

    Now to the most important measure of this article, Cost Savings!

    Proponents of the Dinosaur Releases would argue that the common activities which entail a single release like the builds, Testing, Release Management, OPS availability or reduced GZ would cut costs and multiple runs to PROD would logically increase costs.

    But it’s definitely the other way around, we wouldn’t need to feed the Dino anymore, it will be a cost worthy rapid delivery with optimized resources, a leaner process where DEV and OPS are working together to ensure quality value added deliverables are made available to business faster.. This cultural change and collaborative effort also creates new vistas of growth and provides a perfect platform to excel. The cost benefit analysis would eventually be in favor of Continuous Delivery.

    Opportunity cost is another variable which has not been considered; an innovation or a new feature available to customers quickly with reduced time to market cycle will provide the much needed edge in these competitive times. I recall some conversations where a few must have’s were pushed out due to various reasons, frustrating the business.

    DEVOPS was never meant to replace the traditional approach to software development; rather it is an efficient use of the existing resources within a collaborative model to rapidly deliver quality software products. A major cultural shift in our approach is required and to reach that goal we need to embrace the shades of grays, many a times over 50 (sorry, couldn’t resist) when it’s not truly black or white.

    Thank you for the time.

    Visit my blog http://askhurram.com/

    Read On, Live On.


  • From QA to Continuous Testing

    From QA to Continuous Testing

    My prior blog “DevOps – It’s All About Continuous Testing” posits that QA testers don’t need to fear DevOps because continuous testing QA is a central part of DevOps infrastructures that are implemented according to best practices. That is not to say however that continuous testing is precisely the same as traditional QA testing or that QA test engineers can rest on their laurels in the new world of DevOps and continuous testing.

    Traditional QA testing is a serial process that constitutes a distinct phase that follows the development phase and is conducted by an SQA test team “independent” of the development team. The idea was clearly described by Glenford Myers in his seminal books “Software Reliability – Principles and Practices” and “The Art of Software Testing” published in 1976 and 1979 respectively. According to Myers “4th Axiom [of testing] “It is impossible to test your own program”. Myers felt programmers shouldn’t do any testing, even unit testing. While the application of this axiom to unit testing was not followed by most practitioners in the software industry, the idea of independent software functional and system level testing has been a widely accepted practice for many years. The underlying rationale is that it is “impossible” for the same person (the developer) to objectively test his/her own code due to the inherent bias to want the code to work, while a good QA tester must have the opposite attitude to want to break it in order to uncover bugs in the code. If you follow this logic only “unusual” developers would be able to perform both roles successfully and therefore building a team based on this rare personal quality is essentially not practical.

    Despite the obvious logic of “independent QA test” concept, many very complex software projects without an independent QA test team resulted in extremely high quality products. There are many high quality open source software products that had no independent test organization behind each release version. Meanwhile there are countless examples of software projects that had massive independent test resources that resulted in products that failed miserably. How can this be? Perhaps it is not “who” is doing the test that matters but rather it is the quality and frequency of the testing itself that is important.

    Continuous testing, with its fundamental concept of “fail early and fail often”, is the new QA test method of choice. Sure, testing is still essential and QA test experts that are most skilled in the best practices of test design are valued because they will produce the best quality products. Years of software engineering experiences have demonstrated that developers can learn these skills if they are taught and even “normal” developers can do a great job of testing. Instead of QA testing “after development”, testing is conducted continuously as the software is developed, build-by-build, feature-by-feature. Obviously it is better to find bugs earlier rather than later. So why didn’t we always have continuous testing as part of development processes?

    Several industry developments converged to make continuous testing the winning method for software engineering quality assurance. Numerous “modern” test methods such as agile testing, test driven development, behavior test methods, model based testing, and automated regression testing, to name a few, describe how quality software can be accomplished without the need for an independent QA test team. The advent of Agile development processes and DevOps infrastructures, in which development build-test cycles are accelerated to minutes or hours instead of days or weeks, has accelerated the development and adoption of automation and orchestration tools and methods. There is simply no other way to get a reasonable amount of testing done on each build-test cycle unless the tests themselves and the environment for testing are supported by orchestration tools and reliable regression tests are systematically automated as the product is developed.

    Meanwhile virtualization technologies have enabled a wide variety of product test topologies to be stood up on demand at a speed compatible with the rapid build test cycles and yet not require expensive dedicated equipment configurations. It is this combination of improved test methods, Agile processes, continuous integration speed afforded by automation and orchestration tools, and low-cost test dynamically configurable infrastructures afforded by virtualization that has resulted in DevOps.

    Continuous testing is “the new QA.”

    At Spirent we think testing has a bright future in DevOps. You can read more about our views at spirent.com/solutions/devops

  • Measure Twice. Automate Once.

    Measure Twice. Automate Once.

    “Shipping” code may start with the completion of development but it doesn’t end until after the operational delivery process ends. Just like any fulfillment process, shipping is actually just the kick off of an often arduous journey that ultimately delivers the app to the end user.

    Ship It

    Back in the old days (when they still let me write code) one of our favorite phrases was “ship it” to indicate completeness of a task. That’s because the ultimate goal was, of course, to “ship” the code off to the users so they could start doing whatever it was they were going to do with it*.

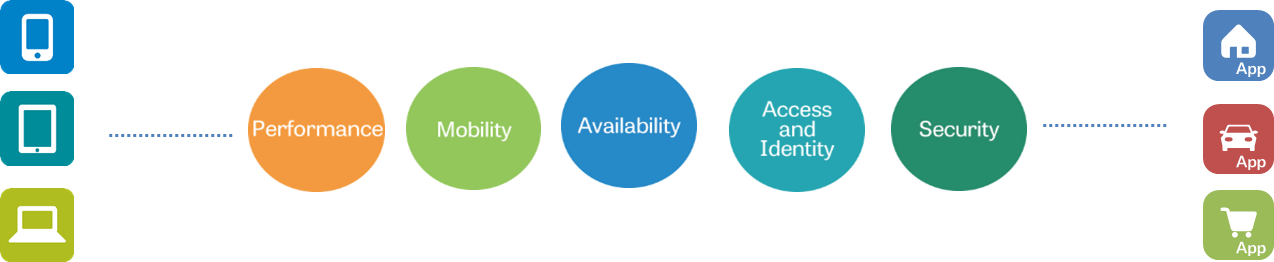
    But the reality was, of course, even when we were really ready to “ship it” to users that it didn’t actually get to users for varying amounts of time. Like shipping anything today, it depends on the shipment method. In terms of today’s enterprise IT, “shipping method” is really a metaphor for the operational approach to deploying all the infrastructure – the “middle boxes” – with the services required to actually deliver a secure, fast and available application to its ultimate users.

    app-services-2

    We know from various studies that this takes time. From days to weeks to even months. And we know we don’t like that and we want to improve it. Which is where DevOps comes in, or NetOps or SDN or SDDC or SDO or whatever you want to call it.

    Speeding up the deployment process is certainly one of the goals of operationalizing the network, but without a baseline how do we know if we’ve gotten faster in the first place?

    That’s a piece of the DevOps puzzle we’ve been ignoring – the need to measure the deployment process. You might notice that “measure” is bolded and in red, that a visual clue meant to reinforce the importance of the measurement aspect of DevOps. If you aren’t measuring how long it takes to deliver that app from dev to its destination – production use by an end-user – then you have no idea which pieces of the process are holding you back. You can’t effectively determine where automation might be applied to improve the time it takes to get to market. You don’t know exactly where the obstacles are that need to be addressed in the first place.

    While we can make some assumptions based on long experience and research and point to handoffs across the IT silos, the reality is that there probably isn’t just one handoff between ops and the network and there may be multiple intra-IT group handoffs. For example, the network ops that handles provisioning network services might not be the same team that handles load balancing and performance services. But they’re both within the “network” silo. There may be multiple handoffs back and forth as various services also need networking services on top of the ones required by the app itself.

    Image Credit: Gaping Void
    Image Credit: Gaping Void

    Without some kind of measurement of how long each of the various steps is taking it’s impossible to determine exactly where the bottlenecks in the app deployment process are in your organization. I can not only determine where that Minecraft Lego set I ordered for my son’s birthday is right now, I can see how long it’s taken to get from each point in the process. I know it goes from point A to point B in X days, and from point B to point C in Y days, and I know if there’s a winter storm that it’s going to cause a slowdown in that second step (which is called a movement in the logistics vernacular, in case you were wondering. I knew you were, you’re welcome!)

    Measure Twice. Automate Once.

    The hidden value in setting out to measure the deployment process is in pulling together an understanding of the process itself. It’s in finding redundancies and discovering sub-processes that are running in serial but could be running in parallel to improve them. It’s not necessarily about automating the whole thing up front, it’s about understanding what the process is and making it more efficient – whether through elimination, reorganization or automation (or all three).

    You don’t simply want to be automating things willy nilly without any idea whether it’s going to do any good. As my dad taught me about working with wood, you measure twice and cut once. With DevOps you want to measure twice (at least) and automate once. Otherwise you may be wasting cycles on one-off tasks or tasks so specific to one application that automation has no real value because it’s not the same across applications.

    The key is to start with defining what you’re going to measure, do the measurement and then analyze it to determine what you need to improve.

    Because automating just for automation’s sake isn’t any more fruitful in the end than adopting technology for technology’s sake.


    * I say “whatever” because over the course of my career I’ve worked on tax software, GIS software, communications and transportation and logistics systems. There’s a lot of variance there in what end users might be doing with “the app”.

  • Crowdsourced Software Testing

    Crowdsourced Software Testing

    As a developer or technical architect, there is no better feeling than taking pride in giving a quality product or service result to your customers.  Now, with computer trends going rapidly towards cloud services and mobile devices, regular company IT development teams are finding their testing capabilities more and more limiting. They are faced with faster releases with more complex products. How do they keep up?

    (more…)

  • Security Should Be the Top Driver for DevOps

    Security Should Be the Top Driver for DevOps

    I’ve often said that the driving factor for many companies in adopting a comprehensive information security program are the dreaded “F” and “A” words – FUD and Audit. Technically FUD is an acronym for fear, uncertainty and doubt. And it might be better said that audit is the action used to hopefully demonstrate compliance and trust.

    Just a few years ago, the predominant drivers for security spending were regulatory and compliance requirements. While compliance remains a driver today, the primary moving force for many is the concern of cybercrime. Fear of being the next Sony, Target, Chase or countless other victims is driving information security budgets to be readdressed.

    In a recent CA survey the top obstacle (28%) to DevOps in their organization were security or compliance concerns. Yet, in the same study, a huge percentage (88%) already have or plan to adopt DevOps in the next 5 years. The dichotomy of the situation has not escaped me. Organizations are in a situation where they are actively spending money on DevOps and information security, but at the same time view these two initiatives as counter.

    The answer is simple, information security teams need to adopt DevOps principles.

    While a widely agreed upon definition of DevOps is still up for grabs, its safe to say that DevOps is generally inclusive of a few core tools and principles. First, DevOps promotes a culture of cooperation and sharing among different groups in an organization. Second, DevOps promotes the use of heavy automation, decreasing time to market and agile development.

    Information security’s goals are the CIA triad – confidentiality, integrity and availability. Security teams argue that DevOps is the antithesis of good security. Constant change, open culture and automation smack directly in the face of security’s tactics of compartmentalization and tight process control.

    Here is a little secret – DevOps is winning, information security is losing.

    DevOps teams are deploying code faster and faster. They are reducing time to market and increasing revenue. Information security teams, well, lets just say that they continue to be in the news for the wrong reasons.

    The second little secret – the companies which are really winning are using DevOps tools and principles everywhere in their organization. Even in information security. Imagine overseeing infrastructure configurations with code that ensures compliance 24×7 across an entire organization. Or picture being able to instrument thousands of data points to benchmark security performance over time. Conceptualize being in charge of an automatic closed-loop security system which automatically takes action to mitigate attacks based on shared threat intelligence. These are possible with DevOps.

    For all that DevOps provides, security should not be a hinderance to DevOps adoption. Instead, security should be a top driver for adopting DevOps. Using DevOps to create the next generation information security program might just be your only hope in combating the next cyber threat.