Tag: automation

  • Get the Full DevOps Picture with our Continuous Delivery Map

    Get the Full DevOps Picture with our Continuous Delivery Map

    Automation and continuous delivery are shifting from being industry trends to becoming industry standards for fast and effective app deployment. To compete in today’s market, organizations must adopt technologies and applications for more rapid deployment. But with so many tools available, this is incredibly challenging without knowing which specific tools and methodologies are most effective.

    Automic, now part of CA Technologies BU, has been a leader in this space and just launched the “Continuous Delivery Map,” inspired by the London Tube. Designed to be interactive and instructive, this subway-like map helps customers easily visualize and assess the best use cases for continuous delivery tools for their own digital transformation and reduce the confusion for IT professionals.

    Before I get into the specifics though, I wanted to share a few trends I’ve been following that have ultimately led to development of this map. In recent years, we’ve seen an expansion of freeware and open-source offerings for automated tasks within IT. But organizations must consider and address the long-term sustainability of these software products since the cost of adoption could be risky. It may only be useful for two to three years, until community developers move onto the next new thing—leaving orgs with the costly task of rewriting delivery pipelines or automation mechanics every three to five years. This is compounded by the fact that the term “DevOps’ itself has even become a trend”—it’s catchy and grabs attention, so everyone is branding themselves as a DevOps tool, even if it’s not a core use case of a tool. Now, there is increased confusion on what tools are available, what aspect of DevOps they’re most valuable for, how sustainable they are, and what the market thinks about them.

    Over the past few years, I’ve also seen some organizational shifts as well. Starting at the top, I have noticed that CEOs have recognized the competitive advantages of applying DevOps practices, including faster software production, greater revenue gains and better responses to market conditions. Leadership teams are now responding with mandates for DevOps implementations in their own orgs, and C-level hiring and firing decisions are being influenced by their awareness of DevOps. Separately but related, development and operations teams have continued to fundamentally work and solve problems differently, with developers working in a linear fashion, solving problems sequentially and operations working in a circular fashion with frequent interruptions. Automation is the key to making operations agile because it will reduce interrupt-driven processes and practices. An agile operations team will empower true DevOps because Ops members will have time to collaborate and contribute to DevOps practices. Without it DevOps really means DevNoOps.

    Enter the Continuous Delivery Map

    We developed the Continuous Delivery Map to help our customers and the industry at large understand the hundreds of available DevOps tools across several “lines.” We sought to create a centralized, unbiased way for IT professionals’ research and visualize how DevOps fits into customers’ continuous delivery pipelines. After thinking more about patterns that fit a delivery pipeline, we settled on a metro rail system similar to the London Tube or New York Subway. Now, with this map, customers can easily visualize the ‘tooling’ in their continuous delivery process with an understanding of the tools best use cases. You’ll see we have several “lines” from middleware to continuous integration to toolchain orchestration—all with more information on each product in each line.

    As the tool evolves, we hope the map will become a platform that uses data and feedback to rank the tools, capturing a market consensus on best-in-class DevOps tools. Customers will then be able to truly see and choose the best tools in various categories that meet specific continuous delivery needs and strategies.

    — Scott Willson

  • DevOps Predictions for the Future

    DevOps Predictions for the Future

     Among the few powerful trends we had experienced in the recent times, one is undoubtedly the adoption of DevOps practices. As we are move closer to 2018, it is becoming more obvious that DevOps is becoming mainstream, with many large organizations getting on board with DevOps.

    DevOps Within Enterprises

    DevOps is becoming the standard way of working for businesses. Adoption of DevOps within the organization is rising on a broader scale, and businesses are trending toward it.

    Enterprises of today are well-aware of the trending technology services in modernizing environments. DevOps is growing its recognition due to changes in complexities of today’s software that lies more in the diverse set of operation systems and platforms. It is less about doing things a particular way and more about moving the business forward and turning technology into a strategic advantage.

    DevOps builds upon best practices to help drive enterprise performance in the modern digital economy. It offers organizations a new way to deliver value to their customers quickly. An increasing number of businesses are recognizing the power that DevOps can bring for operational efficiency and overall performance.

    DevOps Key Trends

    As businesses are trending toward DevOps adoption, let’s look at the changing landscape and key trends in DevOps, along with its trajectory.

    Some of the DevOps trends include:

    • Many organizations will challenge agile and recognize DevOps as the new ALM methodology.
    • Many DevOps automation tools are going to roll up.
    • Automation and testing would gain their prominence.
    • DevOps Engineers are highest paid IT practitioners today.
    • Testing and deployment are done more frequently as Ops people are getting their DevOps knowledge in production for testing and automation operations.

    DevOps Predictions

    Based on the market so far, here are my predictions for the future of DevOps.

    Adoption of Microservices and Containers

    Several software enterprises are pushing toward microservices infrastructure. Microservices architect an enterprise solution, independently, over a set of services.

    Microservices are best-suited for DevOps due to its features including:

    • Isolated nature
    • Improvised cycle times
    • Well-defined interfaces
    • Aligned architecture

    Containerization also is growing in popularity. Containers are designed to run one process at a time with minimal deployment, serving as an ideal deployment model. According to one study, 50 percent of enterprises are expected to run containers in production by the end of 2018.

    If an enterprise has decided to leverage microservices and containers, it is highly essential to incorporate solutions that support microservices and containers along with traditional application model.

    Culture, the Top Prerequisite

    Culture is the key differentiator for DevOps. Culture and process are the principal paths for the successful DevOps journey. Culture breaks down the organizational silos and encourages integration across all the groups that need to work together to achieve a great business outcome. Implementing DevOps culture makes an organization achieve success easier. It even enables continuous learning environment that will see bigger benefits.

    Notion of Shifting Left

    DevOps tools and solutions always prefer to shift left. DevOps orchestration tools automate from end to end, making traceability easier. Activities that are performed traditionally, at the later stages of development and release process, are making a shift to the left of the pipeline. The ultimate goal of it is to recognize issues earlier, along with performance and disaster recovery testing.

    Downtime   

    Adopting DevOps holds a lot of benefits. For one, it enables enterprises to ensure uptime and enhance cadence and quality. High-performing IT organizations employing DevOps practices deploy 200 times more frequently than the low-performing enterprises. Similarly, they also enjoy faster recovery from failure and minimize downtime.

    Collaboration of Big Data and DevOps

    Big Data and DevOps are together taking a step forward toward the design of predictive analytics. DevOps has now become an expert in automating the process and automating configuration.

    Consolidation is Critical

    Large and complex organizations are focusing on consolidation and standardization of DevOps processes so as to scale DevOps within the enterprise. A shared and self-service DevOps automation enables end-to-end pipelines. Eventually, consolidation allows reusability, visibility, auditability and security.

    Supporting Hybrid

    “Hybrid-everything” makes DevOps solutions future-ready to support any tool, application and process in the hyper-hybrid state. “Hybrid” state of existence is achieved for infrastructure, architecture, release pipelines and more. 

    DevOps Monitoring                       

    Until now, the focus has been on pre-production provisioning. However, more attention is being given to the post-deploy feedback loop. With the application of new architectures including microservices, new monitoring technologies and pricing models are effectively introduced.

    Expansion of DevOps Across IT

    DevOps is maturing in other areas such as database management, security and testing, all with the goal of application release.

    Business-centric Agile

    The development methodology approach is becoming more critical to the continuous integration and continuous delivery process.

    DevOps Skills 

    People with DevOps skills are in demand in the industry and expected to proliferate as businesses are witnessing great results from DevOps. Organizations incorporating DevOps training practices are extremely high-functioning. If you aim to build your career in DevOps, below are certain notable skills.

    Most common DevOps positions include:

    • Site reliability engineer
    • DevOps engineer

    The core skills of DevOps are:

    • Coding skills
    • Knowledge of automation tools
    • Communication skills

    Roles of a DevOps Engineer

    Many DevOps developers find interest in deployment and network operations. A core set of DevOps skills includes:

    • Ability to code and script using various technologies and tools.
    • Close relation with Systems and IT operations.
    • Strong base of automation tools and its skills.
    • Incremental code testing and deployment.
    • Strong focus on data management skills and business outcomes.

    Final Words…

    DevOps skills will only continue to grow and DevOps is here to stay. Dev and Ops teams are increasingly moving to rapid development and reliable, high-performance services delivery.

    DevOps is being adopted by more and more companies, particularly smaller enterprises. Many industries today are keen on incorporating DevOps and its key points into their respective departments. It will continue to evolve for the foreseeable future, by incorporating executives and other business units into it. Companies that utilize DevOps effectively will experience higher innovation and quality and easier adoption to other changing conditions.

    Adoption of DevOps enables applications and technology solutions. It power businesses with faster and better quality. Investing in DevOps helps organizations better develop and release software.

    About the Author / Sirisha Paladhi

    Sirisha Paladhi is a content writer at TekSlate. During her career, she has written many articles on technology innovations.


    LinkedIn URL: https://www.linkedin.com/in/paladhi-sirisha-74987881/


  • Next-Generation DevOps: Self-Learning Systems

    Next-Generation DevOps: Self-Learning Systems

    The massive enterprise movement toward all things “digital” has accelerated the adoption of DevOps in all kinds of projects, but particularly in digital transformation initiatives. Apart from the productivity benefits gained by automating software development and rollout, the increased agility has helped move DevOps adoption to gain critical mass in a relatively short time.

    However, challenges remain, particularly in ensuring the alignment of the three dimensions of business systems enabled by DevOps—people, process and technology—are coordinated enough to achieve desired outcomes. The “churn” in each of these three dimensions with every software release—particularly given constantly changing technology, constantly evolving operating procedures to support business requirements and end users and the impact the churn has on the “people” dimension—cannot be underestimated.

    To mitigate this churn, it is essential to implement a DevOps “composite system” that manages it methodically and systematically to bring some order to the seemingly chaotic mess of managing multiple moving systems at the same time. The composite system should essentially be able to deliver the following capabilities to address people, process and technology:

    A Visibility Dashboard for all Stakeholders in the DevOps Value Chain

    Visibility and relevance of their work is of prime importance for people to feel connected to a mission. In a typical software development life cycle (SDLC) in an Agile methodology executed through DevOps, there are many stakeholders involved, including business stakeholders, developers, testers, and support services personnel. In an integrated life cycle of constant and continuous software development, testing and rollout, the cycle can seem complex and never-ending. For a successful and motivated team committed to do their best, systems should provide a visibility dashboard customized to each individual based on their role in a project. The dashboard could involve gamification and relative performance visibility of trends at an individual and group/project level.

    The purpose of such a dashboard is not just to improve visibility and individual performance but also bring in alignment and connect each member of a DevOps team with a broader mission of the project/company.

    Event-driven Technology Automation Spurred by API Integration

    The sheer complexity and number of technologies and platforms involved in a DevOps life cycle can be unnerving and intimidating at the same time. Ultimately, the aim of deploying technology to a process is to simplify and create efficient systems. To this end, DevOps technology architecture must be governed by two critical design principles:

    1. An event-driven architecture that enables asynchronous integration of data generated by different tools and technologies involved.
    2. An API-enabled interface at each level of DevOps process flow so that a change in underlying tooling does not (or should not) have an impact on the business.

    Data Driven Self-Learning Systems to Constantly Streamline and Improve Processes

    In systems heavily laden with interconnected tools and technology, a typical DevOps process is heavily automated. However, this is just a “first generation” maturity of DevOps evolution. Just as with the people dimension, where team members are constantly measured, benchmarked and improved, systems and processes need to evolve continuously.

    Because of automation, integrated DevOps systems generate lots of data (systemic/process-related data including build cycle times, testing cycle times and operational data such as issue resolution) that can be harnessed and plowed back in. Next-gen maturity in DevOps is achieved through a data-enabled feedback engine that constantly improves the quality of DevOps processes and their performance. Advanced data analytics and machine learning algorithms can be implemented to monitor, track and improve DevOps performance metrics.

    In summary, to implement next-generation DevOps, organizations need to consider a holistic approach to manage changes at people, technology and process levels. Each of these dimensions require unique needs and a keen understanding of what it takes to make a DevOps system work for all stakeholders involved.

    About the Author / Madhavan Krishnan

    Madhavan Krishnan serves as vice president of Cloud & DevOps solutions at Virtusa. In this role, Madhavan is responsible for competency development, client solutions, and practice team development from Asia and P&L. With more than 17 years of global IT industry experience across multiple technology and business roles, Madhavan’s experience cuts across different dimensions of Virtusa’s IT Services business including global delivery, enterprise architecture, incubating and scaling technology practices with P&L responsibility, and presales and business development. Madhavan is an active participant in various industry and client forums including CII, MAIT and RFID World Asia, and was a member of RFID Integration Consortium in 2005.

  • 10 Rules for Writing Automated Tests

    10 Rules for Writing Automated Tests

    Over the recent months many of our customers asked for our guidance and building their test suites properly. Performance, ease of management and scalability were key priorities for them. We decided to share our suggestions with the broader audience.

    We came up with the list while building our own test suite. Since we strongly believe in dogfooding, Testim is tested using Testim. We also learned a lot working with a variety of companies from small startups to large enterprises.

    Rule 1: Prioritize

    Most apps include thousands of scenarios. Testing the functionality and correctness is merely one step of the way to shipping high-quality software and meeting users expectations. There’s performance testing (speed and responsiveness in a normal state or under load/stress), visual testing (checking that 1+1 = 2 is one thing, but many visual bugs can make it a very bad experience), and so on.

    Start by listing the most important user flows, for example login, add to cart, checkout, etc. Order the list by those more vital for user conversion.

    Try to sort by first adding those that must succeed e.g. create account, checkout and payment. You can use your analytics tools (e.g. Google Analytics, Mixpanel, Kissmetrics, Woopra) to find which are the common scenarios. We also found Segment.io to be useful.

    Rule 2: Reduce, Recycle, Reuse

    The next step is to break the user’s scenarios down to simple, single purpose, almost atomic flows. e.g. “Create user,” “Login,”  “Send email,” etc. Create a test for each of these flows. When completed, compare this to the the user stories.

    Naming convention – Defining a good naming convention is an important part. For example, including the component name in the flow name, which can result in flow structure (e.g  “Account.login“ and “Account.logout”).

    Reuse components. Don’t Copy/paste – for non-experienced developers/testers, a copy/paste seems like a reuse. However, the challenge is to update those steps when the flow changes. Even a single step/line that repeats in hundreds of tests is a huge hassle.

    Rule 3: Create Structured, Single-Purpose Tests

    Single purpose tests verify one thing only!

    Single purpose tests are easier to create and maintain, they will also run faster compared to longer and complex ones. Ideally, they should only fail if the feature they test is broken or one of its dependencies (which we’ll try to minimize). If you test several features and the first one fails, you know nothing about the other features, since you haven’t reached them.

    A test should consist of three parts:

    1. Setup – e.g. login
      Those steps gets the AUT (application under test) to the state required for testing. This could vary by the test: sometimes you only require a login. you require a complex structure to pre-exist.
      Note: Premature optimization is not a good practice. Implementing the login flow (user/pass fields) is an easy way to start, and if you reuse the same login in all your tests, it wouldn’t be difficult to change the implementation later on to a quick implementation (e.g. by using cookies), so there’s no need to start with the speed optimization if you know it’s easily fixed.
    2. Actions – the flow you want to test.
      Continuing with our aforementioned “login” example above, unlike the setup steps, which require the login to be completed successfully (don’t care in which way), testing the “login” itself is a different task, and should not be reused.
    3. Validations – validate UI state, validate DB – the result you expect.
      There are different validations.his depends greatly on whether you’re testing data which is being updated from production on a weekly basis, or whether it’s the same Test Data.
      In UI testing, the basic validations are done on elements in the UI.

      • Validate an element is visible.
      • Validate an element comprises some text.
      • Validate an element is in a specific state.
      • Visual Validation – validate the is comprising the expected text, image and has the correct styling (e.g. font, layout).

    Using a predefined dataset has the advantage of making the validations easier, as when we know the exact setup state, you also know the precise expected state after the stimuli steps were completed.

    If the dataset is updated, you get different scenarios which you didn’t expect (as different user use your application differently), making it harder to debug failures (as the scenario might not be reproducible).

    Example: A test for a login could look like:

    • Set initial state:
      • Open AUT
      • Navigate to the signup page
    • Actions:
      • Choose a random username and it to a variable named username
        g. “user” + Date.now() + “@mailinator.com”.
      • Sign up for new account by using username.
        • Set username to username
        • Set random password
        • Click submit
      • Validations:
        • Open mailinator.com
        • Navigate to “inbox”
        • Look for email to username
        • Check that there is one email with the expected link.
        • Click on the link
        • Login with username and pass
        • Validate login was successful

    Note: One of the biggest differences between unit tests and end-to-end tests is the overhead. Opening a browser and logging-in to the AUT used to be extremely slow, pushing testers to perform many tests after reaching the Setup state, saving valuable time. Today, with docker, it’s much faster to boot a browser up, the speed of the browser help developers to write applications that load quickly, minimizing the  overhead of writing end-to-end tests.

    Rule 4: Tests’ Initial State Should Always be Consistent

    Since automated tests always repeat the same set of steps, they should always start from the same initial state. The most common maintenance issues when running automated tests are ensuring the integrity of the initial state. Since automated tests depend on that state, if it is not consistent test results won’t be, either. The initial state is usually derived from user previous actions.

    For example:

    1. Adding an item to a list that already contains it (from previous test run).
    2. Views that behave differently for new users and returning users.
    3. Application redirect automatically if user already logged in.

    Possible solutions:

    • Create new user for each test run
    • Use a dedicated app environment for test automation, as opposed to using your production one.
    • Seed your application with initial data before each suite run, also known as fixtures.
    • Use conditions on steps/group to handle dual cases in test which are hard to set.
    • Eliminate dependencies between tests. The AUT’s state after “Test_1” shouldn’t affect the flow of “Test_2”.

    Rule 5: Compose Complex Tests from Simple Steps

    Complex tests should emulate real user scenarios, you should prefer composing those test from simple tests parts (shared steps) instead of recording the entire scenario directly. Since you already tested all the simple actions in the simple tests, the complex tests should only fail on integration issues (this is where Rule No. 2 comes in handy).

    Make sure to order your suite to run the simple tests first. It will give you indication when something is wrong in the complex tests when running the whole suite.

    Rule 6: Add Validations in Turnover Points

    Validations are usually used at the end of the test to signal the test is in a passed/failed state. It is also best to add them at points of major changes as a checkpoint to stop the test if an action failed. Since validation will run until its timeout reached, like all steps, it is also a mechanism to wait for a long async operations in your app (e.g. fetching data from server, continuous view rendering, etc.) before running the next steps.

    Examples:

    1. On action completion – navigation, form submission, modal display, etc.
    2. After major DOM changes add validations to ensure you are in the new state before trying to play next steps.
    3. Following a client-server communication which change app state – e.g. data submitted successfully message, etc.

    Rule 7: No Sleep to Improve Stability

    Sleep with random duration (what I call magic numbers) is one of the main sources of flaky tests. Although all apps are asynchronous in nature, there are rare cases where a human doesn’t know when the page is ready and perform the next action. The same should be true for automated tests.

    The reason to avoid static sleep is you rarely know the load of machine upon you run the test on. Only in performance testing do you have the machine to yourself (knowing for sure all CPU and memory are for you). Since you probably use virtual machines or Docker you will get timeouts if you set the sleep too slow, or slow tests if you set it too high.

    In most cases you add a wait-for-condition step, which waits just like a human would, or sometimes waits for some internal state (e.g. javascript value).

    At Testim we provide all kinds of built-in wait-fors, ranging from wait for element to be visible to wait for a specific text (you use also variables and regex), wait for some visual change (e.g. color change) or code-based changes.

    Rule 8: Use a Minimum Two Levels of Abstractions

    If your test is composed mostly of user interactions, such as clicks and set-text actions, then you’re probably doing something wrong. If you used low-level frameworks (e.g. Selenium), you might have heard of the PageObject Design Pattern, which recommends to separate the business logic (e.g. login) from the low-level implementation (e.g. set username, set password and click login button). This is true for Testim as well. Having layers contribute to reuse reduces the maintenance and allows other members of the organization to quickly understand what happen, as sometimes the testers write the tests but the developers run them (before merging new code). The developers in this case need to understand quickly what the test does, and what is the bug.

    Rule 9: Reduce the Occurrences of Conditions

    A test should have as few as possible conditions (if-statements). Those that have many are usually unpredictable (don’t know the exact state you’re in) or complex (you might even see loops, too). Try to simplify your tests by:

    • Start your test at a predefined state;
    • Disable random popups; and
    • Disable random A/B testing, and choose a specific flow.

    Rule 10: Write Independent and Isolated Tests

    An important methodology of test authoring is creating self contained, independent flows. This allows to run tests in high parallelism, which is crucial for scaling the test suites. If, for example, you have 1,000 tests that run for a minute each, running them one by one will take more than 16 hours. Minutes, at full concurrency, can cut this testing time to 1 minute.

    Having a fast build reduces the feedback time between the moment that developers commit their code and the moment they knows their feature is production ready and can lead to true agile development cycle.

    In Summary

    Proper planning of your tests can make a big difference in your development process. The ability to get fast feedback, adapt tests to new user flows quickly and quickly analyze the results, identify bugs and get enough information to quickly fix them. Proper planning can also save a lot of time and expenses. Suites that are not properly planned require high maintenance and keep the R&D team away from building new functionality and increasing coverage. Finally proper planning can help expand the responsibility for quality beyond the Q&A organization and let others contribute.

    About the Author / Oren Rubin

    Oren RubinOren Rubin is CEO of testim.io. He has over 20 years of experience in the software industry, building mostly test-related products for developers at IBM, Wix, Cadence, Applitools, and Testim.io. In addition to being a busy entrepreneur, Oren is a community activist and and the co-organizer of the Selenium-Israel meetup and the Israeli Google Developer Group meetup. He has taught at Technion University, and mentored at the Google Launchpad Accelerator. Connect with him on LinkedIn and Twitter.

  • Automation: Where Did My Mind Go? Or, No Need to Remember

    Automation: Where Did My Mind Go? Or, No Need to Remember

    Allow me to share a secret: My handwriting is atrocious. If it were not for the keyboard upon which my fingers are tapping and the laptop that is processing the result of my taps, this article would not be happening.

    I’ve always had poor handwriting. But, it’s gotten worse over time. Other than the occasional grocery list, I don’t write things out by hand anymore. It’s just me and the keyboards on my laptop and phone. Luckily, my mind still works—sort of. The stuff I produce has gotten better. Using a computer allows me to edit faster. But, I don’t retrieve words as quickly as I used to. I find myself using online tools continually during a writing session. I could blame age for the impediment. And that may be the case. But still, a part of me says, “Why remember words when I can just grope around a thesaurus to find what I need?” That I can still spell most words correctly is a bit of miracle. But then again, a computer has been correcting my spelling for the last 25 years.

    I’ll share another secret: I don’t remember phone numbers anymore. At one time, I had all the phone numbers associated with all those close to me committed to memory. I knew the phone numbers of my sister, parents, in-laws, friends, steady customers and even my favorite restaurants. I didn’t have to look anything up online. I just carried the numbers around in my head. Now, the only numbers I have memorized are my own and my wife’s. When I want to talk to my sister, I look up her name in the contact list on my cell phone and hit the “call” button. When I am in my bluetooth-enabled car, I just say, “call sister.” The machines do the rest.

    I can still sum a short list of numbers in my head. Also, I can multiply two numbers together as long as neither number is greater than a thousand. If I want to do multiple operations—say, add some numbers up and then divide by another—I need to use a calculator. I haven’t tried to do this sort of arithmetic on paper in a long time. Maybe I can, maybe I can’t. Dunno. It’s just easier to use a calculator.

    I still read a lot. But I find that I spend more time learning things by watching videos on YouTube. In fact, I just got through brushing up on JMeter by watching a playlist of 20 videos on the topic. It took me about two days. I can’t remember the last time I spent two days completely engaged in reading a technology book. It’s embarrassing to say this, given that I am a technology writer.

    But, there is good news here: I can still make change. I learned how to do this before cash registers reported the change to give back upon purchase. You start with the sale amount and work your way through the cash drawer taking out coins and bills until you reach the amount the customer gave you. Funny that I should remember this small piece of mental acrobatics. But, then again, I haven’t used a cash register in a very long time. Making change has yet to be made simple for me.

    However, the computers I use continually throughout my day make things very simple. They allow me to write out my thoughts clearly. They tell me when to pay my bills. They correct my spelling. They make going to the grocery store a breeze. I just take want I want from the shelves, put my credit card into the card reader at the automated checkout line and pay only what is due—no cash required, no change made.

    Automation has made me really smart in a few areas and helpless in most others. I can design an elegant microservice. I am wicked good at working my way through the ins and outs of Amazon Web Services. I can create the automation code that tests my software so that Jenkins can move everything along the deployment path easily and reliably. Yet, I have no idea how to fix my car when the warning lights go off. I don’t know how to repair my cell phone when it stops working. If my voice-responsive TV no longer delivers video on demand, I’m not even sure who to call. The cable company? Netflix? Linksys? Samsung? Denon? When my microwave breaks down, I throw it out.

    My world is simple on the surface and yet terribly complex underneath.

    At one time, the complexities were more apparent. Information was not at our fingertips. Research meant hours in the library poring over the card catalog. Chemistry was part of professional photography. Acting meant memorizing a script that had to be recited over a period of hours, not minutes. Things were more difficult then. But, we sort of figured it out. We had the ability to negotiate the complexities of life. We had no choice. The machines had yet to be invented.

    Now the machines have been invented. Overall, they have been good to us. Smallpox is gone. Lasik is here. Doors open before us automatically, no pushing required. Delivery is overnight, if not same day. Should I want to run my program on a supercomputer, all I need is an AWS account bound to a credit card. Just 1 percent of the population in the United States feeds the rest of the country. We don’t lack for toilet paper.

    Technology is a wonderful thing.

    But, I can’t help but wonder what becomes of a culture when everything is automated to essential simplicity. What happens over generations when we no longer need to know how to write legibly, remember a phone number or make change? How will our minds work when the stuff that used to make our minds work goes away? I don’t know. I am still trying to figure it out. In the meantime, I’ll leave it up to you to decide.

    — Bob Reselman

  • New Relic Delivers on AI Promise to Automate IT Operations

    New Relic Delivers on AI Promise to Automate IT Operations

    New Relic at a FutureStack 2017 conference unveiled an instance of its monitoring tools that employs machine learning technologies and other forms of artificial intelligence (AI) to provide advice on how to optimize an IT environment.

    Nadya Duke Boone, director of product management for New Relic, says New Relic Applied Intelligence (NRAI) will be made available as part of the company’s Digital Intelligence Platform. In addition, New Relic is making available three dedicated NRAI capabilities in the form of Radar, NRQL Baseline Alerting and New Relic APM Error Profiles services. These services are designed to help IT operations teams spot abnormal behavior across billions of pieces of data and predict where problems may arise. The services ultimately will surface prescriptive recommendations for problems before they occur.

    The goal, says Duke Boone, is to leverage New Relic’s software-as-a-service (SaaS) approach to IT monitoring tools democratize access to AI technologies. That’s possible, she says, because of the massive amount of data New Relic collects. That data is then fed into machine learning algorithms to detect patterns indicative of a variety of potential issues.

    Duke Boone says that intelligence is then delivered as a personalized Radar news feed that is similar to a social media news feed. That news alert might, for example, might inform an IT administrator that, based on characteristics of their IT environment, an issue is likely to arise. IT operations teams also have the option to integrate that Radar news feed with a collaboration platform such as Slack to alert the rest of the IT operations team to a potential issue.

    NRQL Baseline Alerting allows IT operations team to set thresholds for specific applications that when exceeded will generate an alert. New Relic APM Error Profiles allows IT administrators to launch queries against NRAI to detect potential issues that might arise from outlier applications in the IT environment, adds Duke Boone.

    New Relic doesn’t see AI replacing IT operations teams as much as augmenting them, Duke Boone notes. Most organizations can’t hire enough IT staff to manage their IT environment. As those IT environments become more complex, it’s becoming clear that IT professionals will need to leverage AI technologies to keep all the applications they deployed running optimally, she says.

    New Relic has been investing extensively in AI ever since it previewed these capabilities in the form of a Project Seymour initiative it revealed last year. Now the company and its rivals are locked in an arms race to develop and implement machine learning algorithms that should enable IT operations teams to manage applications at unprecedented levels of scale.

    In some quarters AI is viewed as an existential threat to the IT operations teams. In reality, AI will be used to automatically resolve low-level issues that collectively conspire to rob IT organizations of the time they need to focus on new innovative ideas that add value to the business. In fact, assuming many of those issues will be soon disappear it’s conceivable that all the drudgery associated with managing IT today made soon just fade away.

    — Mike Vizard

  • NodeSource, AppDynamics Ally for Node.js DevOps

    NodeSource, AppDynamics Ally for Node.js DevOps

    The prevalence of Node.js as the most widely deployed instance of JavaScript is putting a lot of pressure on DevOps teams to find ways to automate the management of Node.js applications. To provide the visibility needed to achieve that goal, NodeSource has announced it has integrated its N|Solid development environment with the application monitoring tools developed by AppDynamics.

    Pravin Halady, product manager for NodeSource, says one of the things that differentiates N|Solid, which is based on Node.js, most is the amount of telemetry data NodeSource is able to collect from Node.js applications. The alliance with AppDynamics provides a mechanism for DevOps teams to now tap into that data to better manage those applications alongside the panoply of existing applications they need to support and manage, says Halady.

    AppDynamics already supports Node.js. But Halady says the alliance with NodeSource provides deeper visibility into, for example, asynchronous activity. Advanced metrics can be used to augment the basic Node.js metrics that AppDynamics currently provides to better ensure service level agreements (SLAs) are both achieved and maintained, Halady says.

    Adoption of Node,js exploded across the enterprise once it became feasible several years ago to deploy JavaScript code on both the client and the server. That capability in many ways fulfilled the early promise of Java in the eyes of many developers. But DevOps teams have been slow to include support for JavaScript applications within their DevOps processes, mainly because of a lack of visibility. Now that the base of Node.js applications in the enterprise has reached a level of critical mass, tools vendors such as AppDynamics are looking to provide that visibility by expanding the scope of support they provide for Node.js.

    Halady says NodeSource chose to partner with AppDynamics in part because in the wake of AppDynamics being acquired by Cisco Systems, it’s clear that NodeSource needs to participate in the end-to-end visibility platforms that larger companies are starting to build. Cisco has already made significant investments in a Cisco Tetration analytics application in addition to committing to imbuing the IT infrastructure environment it provides with machine-learning algorithms. That data will then be combined with data about applications collected by AppDynamics to identify the source of any potential performance issue faster. NodeSource, adds Halady, will look to foster similar agreement with other providers of application monitoring tools.

    In the meantime, DevOps team can take heart in the fact the Node.js Foundation is making providing visibility into DevOps environments a higher priority. The number of Node.js applications in the enterprise is only expected to increase. There’s a high correlation between usage of Node.js and containers that collectively are being used to facilitate the development of microservices. As those microservices bgin to replace monolithic applications developed originally developed in languages such as Java, the size and scope of the DevOps challenge exponentially increases.

    Application development in the enterprise is going to be polyglot well into the next decade. Today there are more programming languages being actively used in the enterprise than any time in history. In fact, the days when IT operations could mandate what technologies developers can employ are long over.

    — Mike Vizard

  • DevOps, Continuous Delivery – It’s All About Automation

    DevOps, Continuous Delivery – It’s All About Automation

    I spent a large portion of my career in the networking industry, marketing routers, switches and other gear that makes the internet work. Networking—like many industries—is currently undergoing a revolution that is in large part driven by software. Functions that used to be delivered as a standalone device can now run in software (not unlike the apps on your smartphone); and software is also being relied on more to make decisions about how traffic is routed through the network.

    I still read up on the networking industry occasionally, and if you’re looking for an expert opinion or just good journalism in this space, you’d be hard-pressed to find a better source than Craig Matsumoto. Craig wrote an interesting opinion piece called “NFV, SDN, Big Data – It’s All About Automation.” You don’t have to know what those acronyms mean to understand the premise.

    What’s interesting is that the same premise can be applied to many of the things that promise to make software development easier, faster and cheaper. DevOps, continuous delivery, continuous testing—all rely on automation to be successful.

    DevOps, of course, requires more than just automation—as it’s also a cultural shift—but automation plays a huge role. The three main components of successful DevOps are commonly cited as tools (or technology), process and people (or culture). Automation is the primary goal of the first two: tools that enable you to automate previously manual tasks, and then establishing the processes that allow you to take advantage of this automation.

    The same can be said of continuous delivery or continuous testing. Continuous testing relies on being able to automatically generate test cases, automatically create virtualized testing environments and create automated calls for testing.

    The premise of a modern software factory also relies on automation. Any modern factory, whether it’s producing cars or toothbrushes, strives to improve efficiencies by eliminating as many manual tasks as possible.

    The fact that software development and operations are lagging behind other industries in terms of automating the production of its goods (i.e., software) is maybe a bit ironic, given that software development is typically seen as more technologically advanced.

    However, it’s also a result of the maturity of the industry and that fact that coding, by its nature, cannot be automated. But the tasks that surround the actual writing of code certainly can be automated, and that’s what the modern software factory promises. The more you can automate, the more successful you will be in delivering quality software faster, with reduced risk and costs.

    Automation seems to bring with it concerns about employment—that is, there is a not-unfounded fear that it’s possible to automate oneself out of a job. However, there was an interesting study that came out, focusing on the automobile industry—one of the most well-known examples of factory automation. The study concluded that:

    In the last six years, (2010–2015), according to the IFR (International Federation of Robotics), US industry has installed around 135,000 new industrial robots. The principal driver is automation in the car industry. During this same period, (2010–2015), the number of employees in the automotive sector increased by 230,000.

    Essentially, automation not only improved production velocity and quality, it also resulted in a net increase in employment.

    The message is clear: Automate what you can and only rely on manual tasks for what you must. If you focus on automating your software development life cycle, not only will you be able to deliver software faster, cheaper and with better quality, but you also will be well on your way to achieving continuous delivery and DevOps.

    — Brendan Hayes

  • Redefining NoOps to Better Inform IT Decision-Making

    Redefining NoOps to Better Inform IT Decision-Making

    It is safe to say that since the term NoOps escaped from its confines as an assembly language instruction (NOP or NOOP mnemonic for no operation) and in microelectronics (NoOps or null instructions inserted into pipeline, creating bubbles*) into enterprise IT, it has caused more than its fair share of consternation and controversy in the DevOps community. This is hardly surprising, when some of the more prominent claims for NoOps placed emphasis on ending operations entirely, threatening the jobs and livelihoods of thousands of knowledge workers. As with previous movements for automation, NoOps came under immediate attack—and, somewhat ironically, the criticism came from IT industry workers. For better or worse, IT has more than its fair share of hyperbole, religiosity and grandstanding, with the NoOps debate being no exception.

    As someone who started his technology career as a developer, moved into infrastructure and is now accountable for resources being allocated to IT, I find the debate does little to inform my decision-making. In this article I want to share my definition of NoOps with the broader community to clear path for greater adoption of NoOps principles among the DevOps community. I see both of these communities as being distinct and yet highly complementary, as long as our ultimate goal is to generate value for the organizations we choose to work for and, by extension, the customers which they serve.

    NoOps as an Ideological Principle

    Various definitions of DevOps have been refined and become more stable over time. I don’t believe it would be particularly controversial to recognize DevOps as a culture, a methodology for creating high-quality applications and delivering them into production in the most efficient manner. In my book, “NoDev NoOps NoIT,” I choose to define NoOps as a guiding principle that makes assertions to help IT decision-makers inform their decisions. It is more useful to separate our notions of DevOps and NoOps into methodological and ideological categories, because doing so strengthens our understanding of both terms and equips us to make better IT decisions.

    Before we examine the assertions made by the NoOps principle, I want clarify why I have rejected other definitions of NoOps and critiques of NoOps itself.

    NoOps Spells the End of Operations

    One of the most common and enduring uses of the word “NoOps” is to refer to eliminating IT operations entirely. The problem with such definitions is that they conveniently scope IT operations in a manner that allows them to be eliminated. IT operations roles are not static in the face of changing technology; arguably, they evolve more rapidly than application roles. The original activities of racking, stacking, cabling and administering IT infrastructures in a typical enterprise has been hugely diminished by outsourcing, commoditization and the advent of cloud infrastructure. However, new activities in software development life cycle, automated provisioning, monitoring, metering and security have created new roles for infrastructure/operations developers. NoOps is not about eliminating IT operations; rather, it is concerned with maximizing automation in IT operations.

    NoOps is the Evolution of DevOps

    While superficially it may well seem that NoOps takes DevOps to its logical conclusion, this line of thinking chooses to ignore the huge swath of DevOps methodology that does not overlap with the automation of operations or the fact that DevOps is itself an evolving methodology. I simply don’t find this definition to be particularly useful in day-to-day decision-making. At best, it’s a dimly lit observation.

    DevOps is NoOps—NoOps is Just a Confusing Term

    The idea of NoOps is an expression of the benefits of automation. How we choose to define the term will dictate its utility. If we choose to define it in a fashion that leads to confusion, then fault lies with the definition and not with the idea itself, which I believe is a powerful one that should not be ignored. Attempting to simply define away NoOps is as wrong-headed as stating that NoOps is the end of operations. Overloading DevOps methodology to encompass NoOps ideology stretches the definition of DevOps beyond its useful boundaries.

    NoOps Assertions: Eliminate All Manual Intervention in IT Operations

    Eliminating manual intervention in IT operations is a fundamental assertion of NoOps. This assertion is made from an understanding of the benefits of the automation and the observation that the very tools we use in IT—computers—were invented to automate conative and algorithmic processes.

    While we may never be able to fully automate every aspect of our operations—for example, some regulators demand four-eyes processes for approval and execution—we must rigorously challenge the unthinking orthodoxy that currently governs many IT processes.

    Automate, simplify and standardize: I subscribe to this mantra but one has to proceed in the right order; that is, simplify, standardize and then automate. Otherwise, you literally risk making an ASS out of your IT automation efforts.

    I can say with a high degree of certainty that any failure to automate a process could probably be traced back having made no attempt to simplify the process before automating it. No attempt was made to challenge the process, to question who is doing what and why before automating it. Indeed, no effort, was made to question the existence of the process in the first instance.

    Once a process has been simplified, standardizing it follows almost naturally. Stakeholders adopt your process because it is simple, it saves them time and generates value for them.

    The opposite is also true: A poorly thought-out, complex process will never win buy-in from users. Any attempt to put lipstick on such a pig will be fraught difficulty, often resulting in the vast majority of users and stakeholders finding exceptions to your attempts to increase adoption of the offending process. 

    NoOps Assertions: Eliminate All Dependencies Between Application Developers and Infrastructure/Operations Developers

    As the trend toward software-defined everything matures, we need to change our organizational structure to adapt with the new landscape. Within enterprise IT, the war between application and operation teams is over, even if there are still combatants that don’t realize that the application teams won. In the software-defined paradigm we are all developers. Application developers write business/end user logic and infrastructure/operations developers write run-book instructions using the tools and APIs made available to them by infrastructure-as-a-service (IaaS) and platform-as-a-service (PaaS) vendors. Both of these types of developers write code and we find more and more frequently it is the same individuals writing both application and infrastructure code; hence, the rise of the full stack developer and the full spectrum technologist.

    As a CTO I organize my technology division into three teams: Application Development, Infrastructure Development and User Experience Development. These teams are physically situated next to each other and work toward a single technology strategy defined by a NoOps ideology and DevOps methodology.

    In Summary

    When we are presented with ideas that are threatening and challenge fundamental elements of our existence, such as the way we work, the best response is to seek out opportunities presented by those ideas and adapt to them. For the DevOps community, the first step in engaging with NoOps is to accept the ideology is based on a very real and powerful foundation of automation. As a community we can choose to dismiss NoOps or we can choose to embrace the possibilities it offers and allow it to enrich DevOps methodology. I would posit that those among in the DevOps community who can adapt to a NoOps reality will not only survive but thrive.

    About the Author / Hussein Badakhchani

    Hussein Badakhchani is a Distinguished Technologist and author with over 20 years of professional experience in financial services technology. Having worked for institutions such as the Bankers Automated Clearing System (BACS), Deutsche Bank and VocaLink – MasterCard, Hussein has a proven track record of delivery in some of the most competitive global capital markets. As a trusted academic, practitioner and adviser, Hussein also provides critical analysis of technology to executive and investment decision makers in government, banking, financial, commercial and defense sectors. He is the author of “NoDev NoOps NoIT,” principles governing the ideology, methodology and praxeology of informed IT decision-making. Connect with him on LinkedIn.

    *”Microelectronics,” by Jerry C. Whitaker.

  • Automation: This Time, It’s Different

    Automation: This Time, It’s Different

    It took about 200,000 years for mankind to be able to figure out how to get an airplane to fly. The event took place Dec. 17, 1903, on a field in Kitty Hawk, N.C., when Wilbur Wright piloted the airplane he had made with his brother, Orville, into the air. The flight lasted for 12 seconds. The aircraft covered a distance of 120 feet. The next two flights went a distance of 175 and 200 feet, respectively. The last flight of the day covered a little more than 800 feet. The plane stayed in the air for 59 seconds, at an altitude never greater than 10 feet, before striking the ground and incurring minor damage.

    Although the flights were a significant technological breakthrough, they had absolutely no commercial value. Other forms of transportation could go further and travel for longer periods.

    Almost two years later, having learned from their mistakes, the Wright Brothers were able to keep an airplane flying for 38 minutes, covering a distance of 25 miles at a speed of 40 mph. The aircraft was 30 percent faster than a horse at full gallop, but still slower than a passenger train running at an average speed of 60 mph. Commercial viability was in sight.

    In June of 1919, 16 years after the Wright’s first flight at Kitty Hawk, Capt. John Alcock and Lt. Arthur Whitten Brown of the United Kingdom flew 1,690 miles from Newfoundland to Clifden, Ireland, in a little more than 16 hours. Fifty years later, it took 73 hours and and 5 minutes for the crew of Apollo 11 to fly the 238,857 miles from Cape Canaveral, Fla., to the moon.

    Think about it. It took mankind 200,00 years of technological progress to get a plane in the air, but only 63 years after that to travel to the moon. It’s pretty miraculous, in a way. Technology does not just move forward. It careens ahead exponentially.
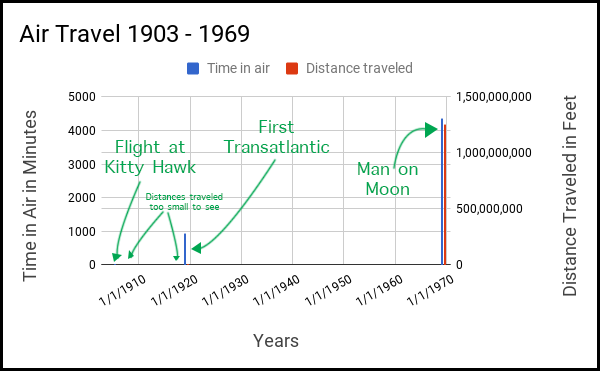
     

    Figure 1: Mankind was able to travel from 12 feet to 238,857 miles by air in 63 years

    What was the stuff of science fiction in my childhood—think video conferencing—is commonplace today. And it’s cheaper than we ever imagined possible. The future possibilities of technology are limitless. Anything can come to be, given enough time.

    But, when it comes to considering artificial intelligence and machine autonomy, there are still a lot of people out there who think that the notion of machines taking over most of the jobs that humans do is far-fetched, if not daffy. According to conventional wisdom, history’s pattern is that for every job eliminated by technology, more are produced. And should machines displace humans from the workforce entirely, that day is a long way off.

    That’s what my grandmother thought. She was born in 1900. If you had told her when she was a teenage girl that the flying contraption she was reading about in the newspapers would have the result of putting a man on the moon in her lifetime, she would think you crazy, and rightly so. She had no historical precedent to think otherwise. Remember, in her day horses still pulled plows. Everything except birds and hot air balloons were land-bound. Yet, despite her disbelief, there came a time when she sat in front of a television to watch Neil Armstrong descend from the Apollo 11 Landing Module to put the first human footprint on the moon. She thought it would never happen. And yet, it did.

    Yes, the historical pattern has been that technology eliminates jobs and creates new ones for humans to do. When the automobile replaced the horse, the out-of-work blacksmiths went to work in factories that filled the ever-expanding industrial landscape. And, with each wave of technological innovation, there were the harbingers of doom predicting the demise of human labor. Each generation of naysayers uttered, “This time it’s different.” Conventional wisdom points out that it never is.

    That was then and this is now. This is the time of the autonomous machine. This time it is different.

    The Rise of the Autonomous Machine

    Machine autonomy is the ability for a device to make decisions and conduct itself independent from ongoing instruction, very much the way a human does. The most telling example is an automated stock trading program used by financial investors. The program is at work continually buying and selling stock with the goal of turning a profit. Certain safeguards are built in to prevent disaster. But for the most part, the application is left on its own to achieve its goal: to make money.

    Until very recently, machine autonomy was confined to software applications such as the stock trading example described above. However, modern robotics makes it so that not only can a machine “think” autonomously, it now also can move autonomously. The most apparent example is the self-driving car.

    Integrating physical and cognitive autonomy into machine behavior changes the game. In prior days, a taxi required a human driver to get the passenger’s destination, find the best route, drive the vehicle and collect payment for the ride. All a passenger needed to do was jump in the back seat and tell the driver where to go. The human driver figured out the rest. As technology improves, the passenger still will jump into the back seat, but in an autonomous vehicle that gets routing information and traffic conditions from a wireless connection to the internet.

    The ramifications are profound.

    For example, let’s imagine we have a diseased tree in our front yard that needs to be removed. Today, we call a landscaping company. The tree removal crew shows up, we point to the diseased tree and ask the foreman to remove it. That’s the only instruction we need to give. The landscaping crew has the ability to act autonomously to do whatever is necessary to remove the tree safely.

    Now, imagine the crew brings along a robot to help with the task. At this point, it’s safe to say that current robotic technology requires a lot of human guidance to remove the tree; the robot is more an aid than an independent worker. The robot might have no other ability than to pick up tree cuttings and take them to a truck to be hauled away. Or, the robot might be able to handle a tree-cutting tool to assist with demolition. Still, the independence of the robot it limited. Either its activities are limited to repeatable tasks limited in scope, or it can act in an ad hoc manner by taking one instruction at a time from a human. The robot is dependent on human instruction to get work done.

    However, let’s imagine that robot technology is on the trajectory of exponential innovation that has been the historic norm. Remember, in the scheme of 200,000 years of homo sapien activity, 63 years from a field in Kitty Hawk to the moon is but a blip in the historical timeline. Autonomous lumberjack robots are entirely possible.

    You call up a landscaping company. A crew of three lumberjack robots show up in an autonomously driven vehicle. These robots know everything there is to know about tree removal and they can do all the physical activities required. The “lead” robot asks you which tree needs removing. You point to the tree. The crew figures out the rest on its own, right down to charging your credit card for work done. Plausible? If you answer no, pretend you are my grandmother and you’ve just been asked whether you think it’s plausible that a man will walk on the moon in your lifetime.

    So the question remains, What happened to the human crew? Did they become data scientists? Don’t answer this question yet. We’ll get to it in moment. First, we need to talk about the next milestone on the road to complete machine autonomy: artificial general intelligence (AGI).

    Narrow AI and AGI

    In the tree-removal scenario described above, all robotic activity—autonomous or otherwise—was confined to a single task: removing a tree. The scope of work is limited. Working within a limited scope of behavior is called narrow AI (artificial intelligence).

    Examples of narrow AI are cutting down a tree, trading a stock, finding a date on Friday night, composing a song, making a pizza, etc. We’re going to see a lot of narrow AI emerge in the next few years. Venture capitalists such as Khosla Ventures, Greylock Partners and Goldman Sachs are already putting money into advancing narrow AI technologies. However, narrow AI is but a stepping stone to get across the pond to the final destination: general AI.

    Think of of it this way: If Kitty Hawk is the starting point of AI, the first transatlantic flight is narrow AI. AGI is landing on the moon.

    What will general AI look like? Let’s go back to the landscaping example.

    We’re back in your front yard sitting in some lawn chairs having ice tea on a hot summer’s night. A driverless vehicle shows up. Two robots emerge. One approaches you and asks your permission to deposit $500 in your PayPal account in exchange for cutting down a diseased tree in your front yard. “OK,” you say, “but how do you know the tree is diseased and why are you giving me $500?”

    While the second robot gets to work, the first robot responds, “The county keeps drones in the air 24/7 analyzing the landscape. A drone did a spectral analysis of your property and noticed the diseased tree. In addition to reporting back the location of the tree, the drone also included a full biological profile. If you don’t remove the tree, the disease will spread. That’s the bad news. The good news is that it’s a cherry tree. And it seems that only 10 percent of the tree is diseased. The rest is perfectly good wood. The price of cherry wood is quite high on the commodity markets right now. Also, there’s a legal statute that requires the county to reimburse property owners when a private landscape is altered for general good. So, the county sold a futures contract on the wood it can reclaim from your tree. The $500 we want to put in your PayPal account reflects your share of the revenue received from the futures contract plus the amount of the reimbursement entitlement required by law.”

    This is what AGI looks like. AGI is the ability for a machine to think in broad terms, using a multitude of knowledge domains. Combining AGI with the advances in physical robotic capabilities expected on the horizon produces a result in which machine autonomy is not only possible, but will exceed human capability.

    If you think AGI is a fantastic notion, go talk to Yves Bergquist, CEO over at Novamente. The company is actively working to improve AGI for general commercial use. One application Novamente is developing uses AGI to determine, if not create, movie scripts with a high probability for profitability. To quote Bergquist: “A story is an algorithm.”

    Making a modern-day Hollywood blockbuster is a billion-dollar undertaking. Given the choice, studios would rather not roll the dice. However, when it comes to scripts, predicting a winner is difficult. Of all the human endeavors that are tough to emulate with artificial intelligence, creative storytelling ranks high. Writing a script requires working in a multitude of knowledge domains: story, character, plotlines, scene design and historical continuity, to name a few. Narrow AI is not suited to the task. You need AGI. There’s too much to consider. In a way, it’s surprising to think of Hollywood is the perfect incubator for developing real-world AGI. But it makes sense. AGI might produce a few flops. But, it’s a whole lot safer to lose at the box office than to lose on the battlefield.

    Given companies such as Novamente, the entertainment industry might well become the incubator in which AGI is perfected. Then, if the trend in rate of technological innovation continues, eventually AGI will become viable everywhere. Then what? What happens when a machine can do everything a human does only faster and better?

    A Turkey’s Life

    Understanding the long-term impacts of a given technology has not been one of the highlights of human endeavor. As cars became commonplace, few people considered the possibility that too many would create too much carbon monoxide and thus threaten the health of the earth’s population. And nobody really thought about what was going to happen to the displaced blacksmith who was no longer needed to make shoes for a diminishing number of horses. Events just ran their course with little or no forethought.

    But, it’s getting better. Some people do think ahead. Military planners consider the improbable as do financial analysts. It’s called risk analysis. These are the people that get paid to think outside the box, so to speak. They understand the even small possibilities might happen. Whether they are heeded or not is another story.

    Today, machine autonomy is real. The possibility exists that in our lifetime automated AI will indeed be able to do everything a human does. And, the machine will do it better at less expense. There will be no new jobs for humans to do as old ones are destroyed. A machine will be able to do the new job faster and cheaper—even those jobs that require a significant amount of AGI. Then, what will happen to the humans?

    We have to think about it today!

    Sadly, few are. We are not hearing any articulation in general industry or in government, at any level, about ideas to address the the impact of automation on human employment as machine autonomy and AGI become more prevalent in the economy. It seems as though most people are relying on the old logic of the conventional wisdom.

    Conventional wisdom is easy to accept. The U.S. economy is reported to be at practically full employment levels. Employers are complaining about how difficult it is to find qualified workers. The stock market is achieving historic heights. Given history and current events, of course it’s reasonable to say there always will be jobs for humans to do.

    This assertion works until the day fully autonomous machines appear on the landscape. Then, conventional wisdom will be that which is uttered by turkeys on the day before Thanksgiving.

    What do I mean? Allow me to elaborate using a previously written analogy.

    Imagine you are a turkey on a farm. Every day the farmer comes by to feed you. This goes on for one week, two weeks, 10 weeks. Given your history, you are completely justified to predict that your future will be one of satisfying meals. It’s always been this way; how could it be otherwise? You go day in and day out predicting that the next day will be full of food and sunshine. You are correct … right up until the day before Thanksgiving.

    In other words, there are things that happen independent of historical precedent. The trick is to imagine what such events might be.

    Everybody agrees that AI is here and that machine autonomy is growing. The conventional wisdom is that, based on historical observation, there have always been jobs as technology grows. Many think the full replacement of human labor by autonomous machines is a possibility, but one that is coming in the far, distant future. When Wilbur Wright took off in 1903, my grandmother’s distant future as was 1969. Those 63 years passed in no time. She lived to see a man land on the moon. Those of us alive today are seeing the beginnings of true machine autonomy appearing on the technology landscape. A world of full machine autonomy is more than probable in the lifetimes of our grandchildren. It will happen. What will be the impact? What will they do if their labor is no longer required?

    Back in 1903, as automobiles began to chug along the planet’s roads, we missed predicting the possibility of air pollution and global warming. Today, will we allow conventional wisdom to prevail and miss preparing for the impact that full machine autonomy will have on human employment? Or will we plan ahead? Hopefully, we’ve learned from our mistakes.

    I’ll leave it to you to decide.

    Author’s Note: The analogy of prediction in terms of historical precedence is taken from the book, “The Black Swan,” by Nassim Nicholas Taleb

    — Bob Reselman