Category: News

  • Zenhub Brings Generative AI to Software Project Management

    Zenhub this week made available an edition of its project management platform for software engineering teams that makes use of generative artificial intelligence (AI) to summarize reports and identify bottlenecks to help streamline DevOps workflows.

    Aaron Upright, the co-founder of Zenhub, said the company plans to work with each Zenhub AI customer to enable them to securely use their personal data to train an AI model using the ChatGPT platform to make DevOps teams more productive.

    For example, DevOps teams will be able to use historical sprint data to identify bottlenecks more easily. Natural language processing (NLP) will also enable teams to reduce the impact of project label sprawl by making it easier to associate related projects regardless of naming conventions.

    Overall, the quality of data being collected will also improve story point estimations, noted Upright.

    It’s still early days as far as the usage of generative AI within the context of project management applications is concerned, but the potential AI has to transform the role of project managers is already apparent as more data is collected and analyzed by AI models. Rather than reacting to changes to project schedules as they occur, it should become easier for project managers to proactively surface issues that might have previously delayed or derailed a software development effort.

    Project managers should also be able to better track the return on investment (ROI) metrics for any given project as changes occur, added Upright.

    In theory, project managers augmented by AI models should be able to simultaneously manage more complex development efforts at levels of scale that previously would have been unachievable. The challenge is making sure project managers have visibility into the suggestions being made by AI platforms. Often when presented with conflicting data they will make up an inaccurate response, also known as a hallucination.

    However, the narrower the range of data used to train an AI model the more accurate it tends to become. The critical issue many organizations will initially face is vetting the quality of the data being used to train the AI model. In addition, organizations will also need to make sure that no biases have been inadvertently injected into an AI model because the data used to train it was either flawed or inaccurate.

    Ultimately, the amount of toil that project managers regularly experience should decline considerably as AI continues to advance. The expectation should be that AI will soon be pervasively applied across multiple project management applications. The race is now on to deliver on that promise.

    In the meantime, project managers might want to start assessing which tasks they perform daily that are likely to be automated. This will enable them to add higher levels of value by having the time needed to focus more on strategic imperatives. After all, every minute spent checking to see whether data is accurate is one less minute spent understanding what needs to be done to affect a better project management outcome.

  • 80% of Bosses ‘Regret’ Stopping WFH ¦ PSA: Disable STS!

    80% of Bosses ‘Regret’ Stopping WFH ¦ PSA: Disable STS!

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: Rethinking return-to-office mandates and a ridiculous, ancient Windows bug. (more…)

  • OpenELA Commits to Building RHEL-Compatible Operating Systems

    OpenELA Commits to Building RHEL-Compatible Operating Systems

    CIQ, Oracle and SUSE are pooling their collective efforts to form the Open Enterprise Linux Association (OpenELA), a trade group committed to developing Linux distributions compatible with Red Hat Enterprise Linux (RHEL) by providing open and free Enterprise Linux (EL) source code starting later this year.

    EL is the base operating system that RHEL and SUSE Linux Enterprise, Oracle Enterprise Linux, Ubuntu from Canonical and Rocky Linux from CIQ are built upon.

    The effort is a direct response to a decision made by Red Hat to no longer make the source code for RHEL available to organizations that want to build RHEL-compatible platforms based on a Linux distribution. In place of RHEL, the code to enable downstream distributions of Linux that would be compatible with RHEL will be provided. The initial OpenELA will be on RHEL versions EL8, EL9 and possibly EL7.

    Wim Coekaerts, executive vice president of software development at Oracle, said there have already been instances where organizations migrated from one distribution of Linux to another. The goal of OpenELA is to reduce fragmentation that might occur with RHEL source code no longer available to the open source community.

    Alan Clark, a member of the SUSE office of the CTO, added that this approach will preserve the flexibility organizations have today as it is specifically applied to RHEL-compatible platforms.

    It may be a while before RHEL-compatible distributions of Linux based on EL are available, but the time and effort required to replace the operating system is much less than in prior years. It’s not clear to what degree IT organizations are concerned about the Red Hat decision, but if they are, they will need to decide to what level they will swap out operating systems versus deploying a different distribution of Linux for new application environments going forward.

    Conflicts involving various forks of projects continue to be an issue for the open source community. Mostly those forks are created because of differences in business models, but other factors play a role including the pace of innovation and, regrettably, personality conflicts among maintainers of open source software projects.

    Regardless of the root cause for creating multiple distributions of any given project, each variant adds complexity that DevOps teams need to navigate. Dependencies on specific versions of open source software can create issues when specific capabilities are not available on another platform that a DevOps team is using to deploy an application. As a result, some organizations prefer a proprietary platform such as Windows simply because they perceive navigating the compatibility issues they may encounter to be more challenging than they can handle.

    The trade-off is that open source software drives innovation faster as the pace at which contributions are made accelerates over time. It’s like most democratic processes—it’s a little messier than any other form of governance.

  • System Initiative Open Sources Digital Twin Tool for DevOps

    System Initiative Open Sources Digital Twin Tool for DevOps

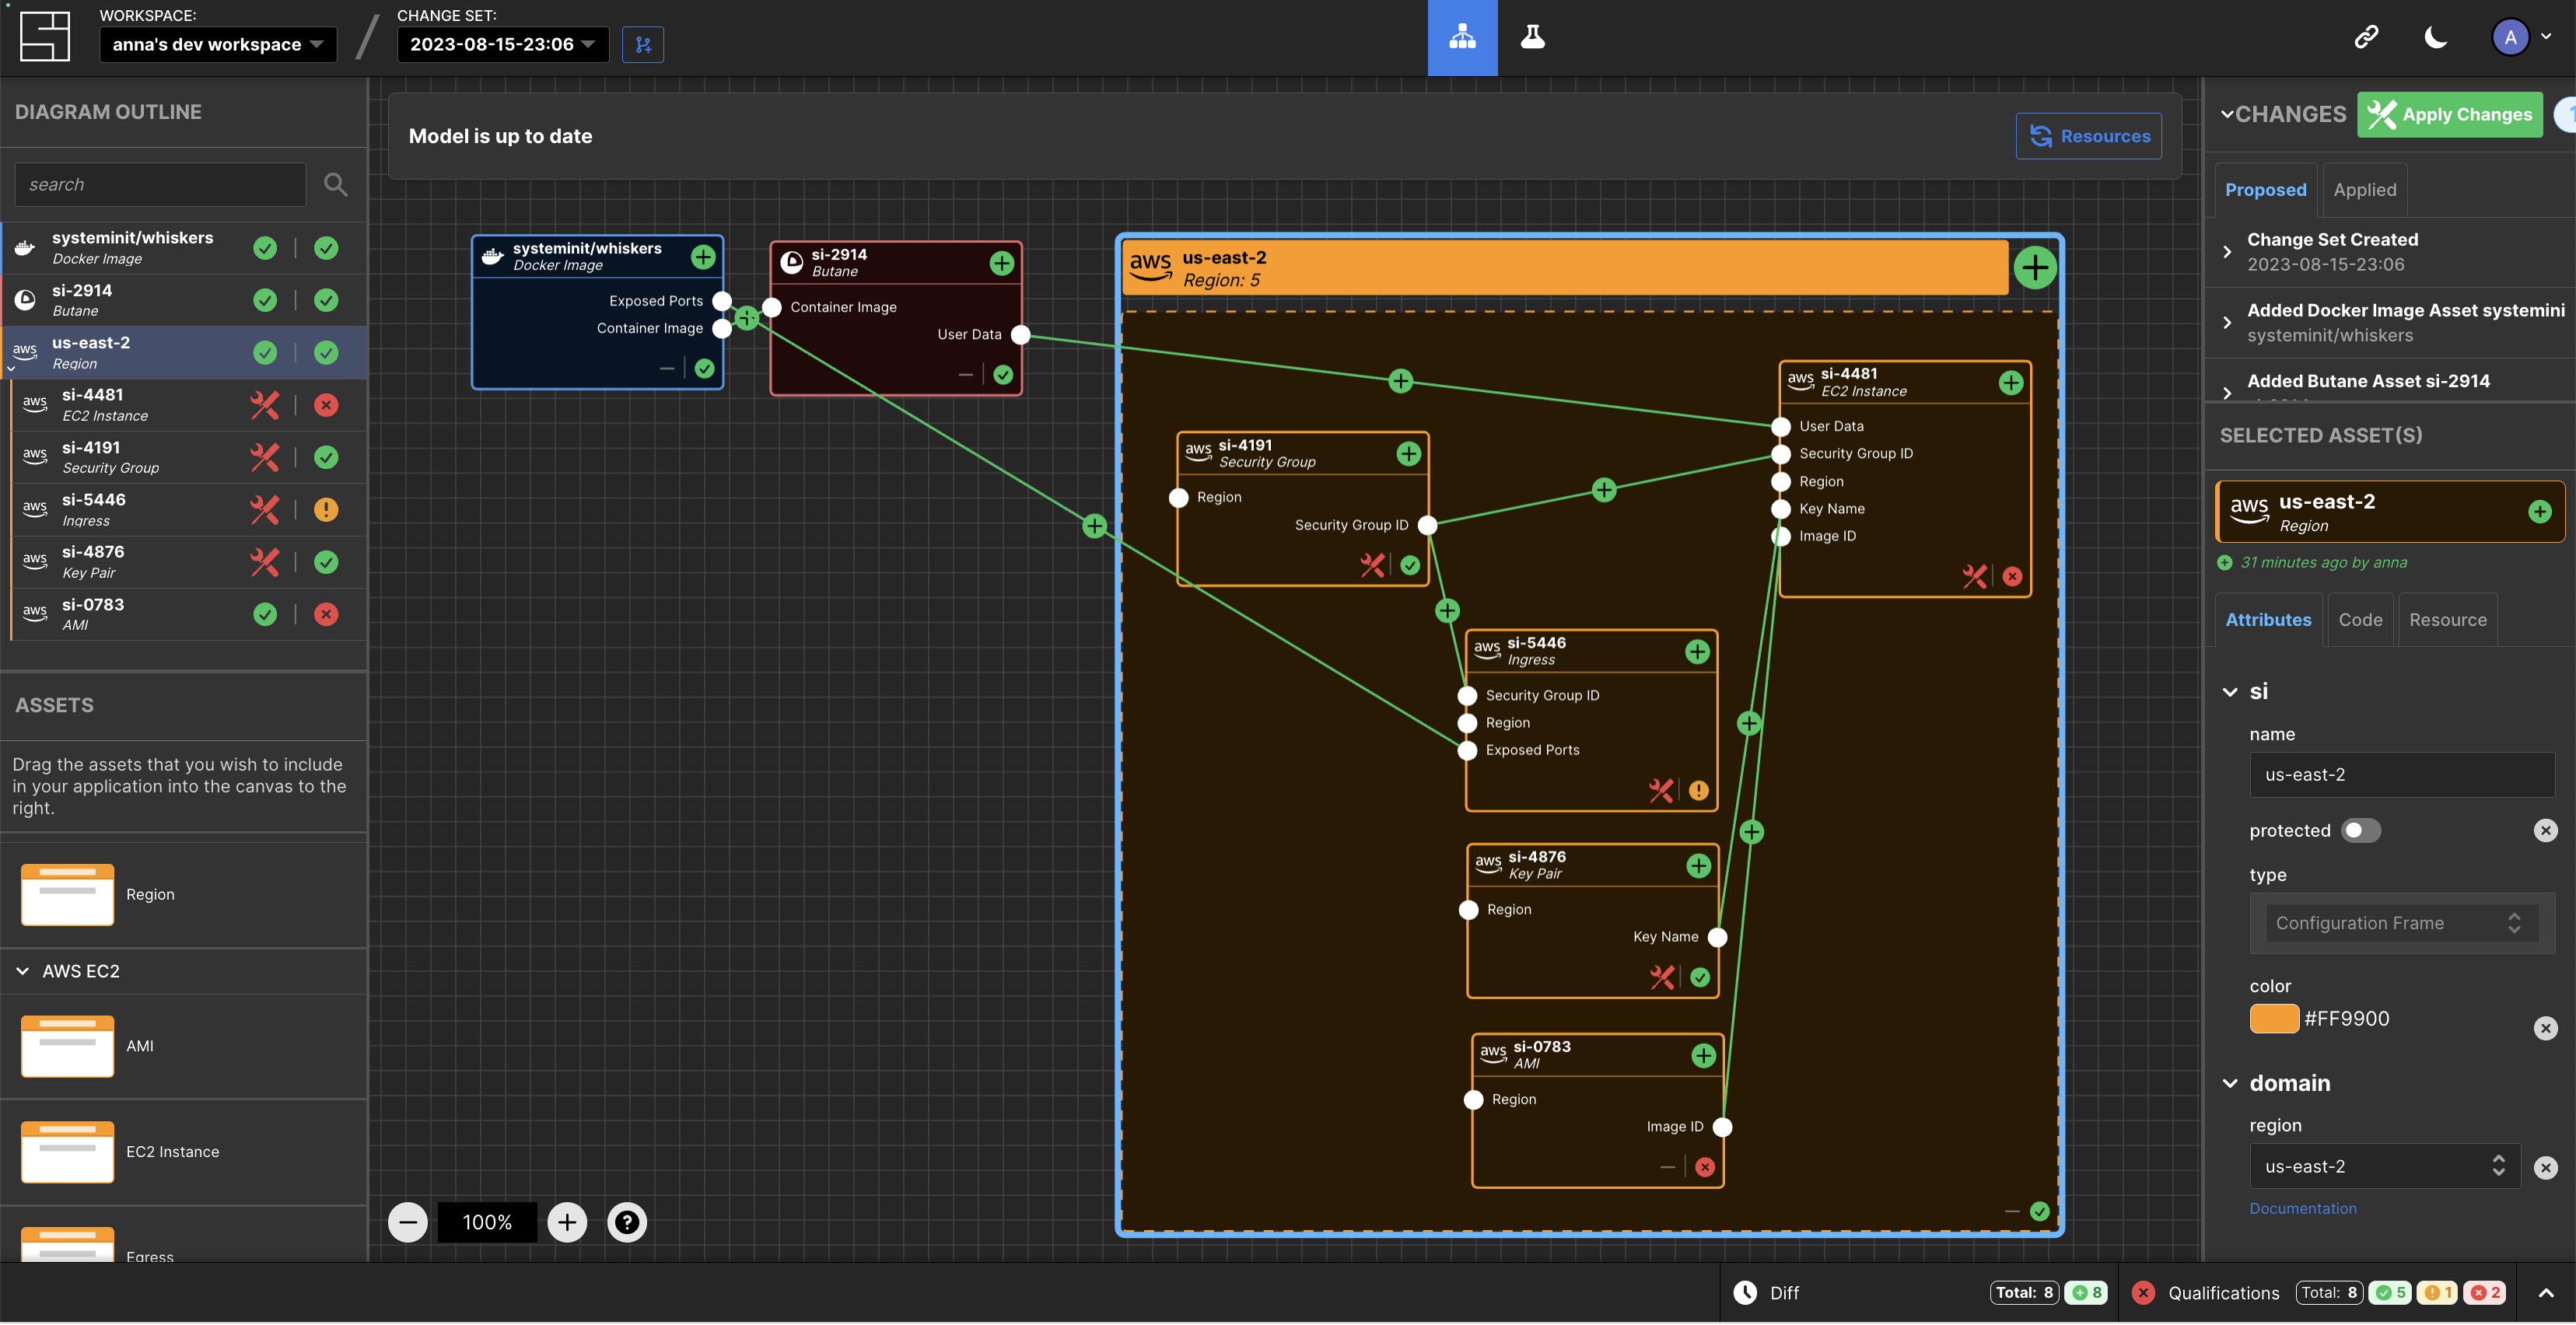
    System Initiative (SI) today announced it is making the digital twin tool it developed to manage DevOps workflows available under an open source Apache 2.0 license.

    Company CEO Adam Jacob said the approach will enable third parties to contribute to a project that is still early in its development cycle while SI provides commercial support via a subscription service.

    SI has developed a tool that creates a digital twin of a DevOps environment that provides a level of abstraction that makes it simpler to manage complex workflows at scale.

    At the core of that effort are models of IT environments created by the SI platform accessed via a visual interface. The automation framework built into the platform uses the relationships between models to infer configuration dynamically and generates typescript code that a DevOps team can then apply to automate a task.

    Feedback loops are provided in real-time to give insight into the viability of a configuration, in addition to eliminating the need for state files to track and ‘plan’ versus ‘apply’ stages.

    This approach streamlines a lot of the complexity that creates bottlenecks in DevOps workflows in what heralds the arrival of a new DevOps 2.0 era, said Jacob.

    In general, SI is making a case for an alternative approach to managing DevOps as the existing platforms and framework are fundamentally broken, added Jacob. Models that create digital twins of DevOps environments represent the arrival of a new era of software development and deployment, he noted.

    As more organizations realize their dependency on software to drive digital processes many are then looking to improve the productivity of developers and the DevOps teams that support them. Unfortunately, many DevOps teams are supporting DevOps workflows using custom code that varies widely in quality. Rather than rely on a DevOps engineer to write code, the SI digital twin tool will create code that can be applied more consistently to create DevOps workflows programmatically.

    One of the reasons few organizations today have fully automated DevOps across the application development and deployment process is that it’s simply too difficult to achieve using legacy tools and DevOps platforms. It’s not clear to what degree a digital twin approach to managing DevOps will resolve that issue, but when coupled with the arrival of artificial intelligence (AI) capabilities the way DevOps is managed is clearly about to transform.

    It may take a while for that transition to occur, but DevOps teams that have historically embraced automation are at the very least going to aggressively experiment with technologies that promise to eliminate much of the drudgery that makes DevOps more tedious than need be. The issue, as always, will be determining which technologies live up to the current level of hype being generated in a way that can be easily adopted.

  • Latest Redis Update Streamlines Management of Platform

    Latest Redis Update Streamlines Management of Platform

    Redis made a unified release of its namesake data store available today for consistent deployment across all supported platforms. Previously, the pace at which upgrades were made was staggered across different offerings only as they became available.

    At the same time, Redis is moving to unify client libraries used to access its open source data store by working directly with the community maintainers of the five most popular client libraries—Jedis (Java), node-redis (NodeJS), redis-py (Python), NRedisStack (.Net), and Go-Redis (Go).

    Other capabilities added to version 7.2 of the platform include support for auto-tiering, to more easily migrate less frequently accessed data to less expensive storage devices. This is managed via an enhanced interface for the Redis cluster management and data integration tools, available in preview. Both make it possible to consume data in real-time from another data source, such as a SQL database. Developers can also take advantage of triggers and functions to build those types of applications.

    Redis is also previewing a search tool for vector data used to create generative artificial intelligence (AI) applications. Rather than employing a separate vector database to build these applications, the Redis platform supports this data type to enable generative AI applications to run alongside other classes of applications accessing the same data.

    Redis CEO Rowan Trollope said collectively these efforts will help DevOps teams reduce costs and streamline the management of upgrades to the platform and updates to applications accessing it.

    Most organizations initially adopt Redis to provide a layer of cache using a data store that runs in-memory. However, as more applications are developed many organizations wind up using Redis as their primary database for applications that require a lot of interactivity, noted Trollope.

    While developers primarily make that architectural decision, the overall management of the Redis data store falls to DevOps teams that will now find it easier to streamline workflows across multiple instances of Redis running in the cloud, or on a Kubernetes cluster, added Trollope.

    Of course, in some cases, organizations still rely on database administrators and data engineers to manage those workflows, but as DevOps continues to evolve, more instances of data stores are being incorporated into workflows managed by a DevOps team. The ultimate goal should be to align DevOps and DataOps best practices to increase the productivity of developers and data science teams building generative AI applications using vector data to customize an existing large language model (LLM).

    Regardless of the motivation, what’s clear is the volume of data that needs to run in-memory continues to increase substantially. As that shift continues to occur, more latency-sensitive applications are being deployed. Maintaining the performance of those applications across a highly distributed enterprise environment with multiple service dependencies requires a level of DevOps expertise that is still difficult to find and retain.

  • Five Great DevOps Job Opportunities

    Five Great DevOps Job Opportunities

    DevOps.com is now providing a weekly DevOps jobs report through which opportunities for DevOps professionals will be highlighted to better serve our audience.

    Our goal in these challenging economic times is to make it easier for DevOps professionals to advance their careers.

    Of course, the pool of available DevOps talent is still relatively constrained, so when one DevOps professional takes on a new role it tends to create an opportunity for others.

    The five job postings shared this week are selected based on the company looking to hire, the vertical industry segment and, naturally, the pay scale being offered.

    We’re also committed to providing additional insights into the state of the DevOps job market. In the meantime, for your consideration:

    LinkedIn

    Well
    Raleigh-Durham-Chapel Hill, North Carolina
    Principal DevOps Engineer – Team Lead
    $180,000 to $200,000

    CareerBuilder.com

    Apple
    Cupertino, California
    Cloud DevOps Engineer – Enterprise Systems
    $138,900

    Indeed.com

    General Dynamics Information Technology
    Indianapolis, Indiana
    Capado Salesforce DevOps Engineer
    $116,000 to $174,000

    SimplyHired

    John Hancock
    Boston, Massachusetts
    Senior DevOps Engineer
    $109,000 to $138,000

    Dice.com

    IT Trailblazers
    Houston, Texas
    DevOps Lead
    $100,000 to $120,000

  • Teleport Assist Leverages Generative AI to Democratize DevOps

    Teleport Assist Leverages Generative AI to Democratize DevOps

    Teleport has made available a chat interface, dubbed Teleport Assist, that makes use of OpenAI’s generative artificial intelligence (AI) application programming interfaces (APIs) to enable DevOps teams to troubleshoot infrastructure issues more easily.

    Using the natural language interface (NLI) provided by Teleport Assist, DevOps engineers can ask questions and give instructions in English to massive fleets of servers. Capabilities include being able to suggest commands and scripts for debugging and resolving common issues and then generating commands for review before they are applied.

    In future versions of Teleport Assist, support for other cloud resources, such as SQL databases and Kubernetes clusters, will be added. Teleport Assist currently supports Secure Shell (SSH) and bash scripts, with support for additional languages and interfaces to be added over time.

    Teleport CEO Ev Kontsevoy said it’s already clear that many of the scripts that DevOps engineers rely on today for IT management will be replaced by generative AI platforms. The average IT administrator will be able to invoke DevOps platforms via an NLI that eliminates the need for extensive programming expertise, he added.

    In effect, the NLI surfaced by generative AI platforms will serve to democratize DevOps expertise, Kontsevoy noted.

    It’s still early days as far as the adoption of generative AI by DevOps engineers is concerned, but it’s already apparent that its impact will be profound. It will increase the pace at which applications are built while making it easier for software engineers to manage large codebases. Most of the generative AI advances thus far improve developer productivity, but tools such as Teleport Assist show how generative AI will also make it easier for more organizations to adopt DevOps best practices that previously were limited to organizations that could afford to hire and retain significant numbers of software engineers.

    At their core, generative AI platforms are fundamentally changing the way humans interact with machines. Instead of requiring a developer or engineer to create a level of abstraction to communicate with a machine, it’s now possible for machines to understand the language humans use to communicate with each other. A a natural language interface will soon enable DevOps engineers to ask generative AI platforms to not only surface suggestions but also debug applications and even write code. The accuracy and quality of those results will vary depending on how the large language models (LLMs) that trained those platforms were, but over time there will be a wide range of LLMs that are trained to be used within specific domains such as DevOps.

    The issue is determining how to organize DevOps teams as more tasks become automated. Generative AI doesn’t replace the need for IT professionals, but it does make it simpler to manage IT at unprecedented levels of scale. In fact, at this point, the proverbial generative AI genie is out of the bottle, so there is no going back. The only thing left to decide is how quickly generative AI becomes pervasively applied.

  • Mezmo Simplifies Management of DevOps Telemetry Data

    Mezmo Simplifies Management of DevOps Telemetry Data

    Mezmo has added additional capabilities to streamline the flow of telemetry data within DevOps workflows as part of an effort to make it simpler to surface insights and reduce the total cost of observability.

    The company has also added integrations with more data sources to the Telemetry Pipeline platform, along with controls that make it simpler to optimize data storage and usage. For example, an Events-to-Metrics Processor capability identifies and extracts metrics from logs to make them easier for third-party tools to consume.

    Mezmo CEO Tucker Callaway said these additions collectively make it simpler to surface insights that will make DevOps workflows more efficient. Previously, the company added capabilities such as rollback and redeploy, sequential parsing, error history management and data sample management to enable DevOps teams to manage telemetry data more efficiently.

    In effect, Mezmo is making it easier to apply engineering best practices to the massive amounts of telemetry data generated across DevOps workflows, he noted.

    No one knows for certain if all that data will require the addition of data engineers to DevOps teams, but as DevOps continues to evolve, it’s clear there is a need to cost-effectively manage data at scale. DevOps teams that embrace observability are quickly discovering that storing logs, traces and metrics for an extended amount of time can quickly become cost prohibitive. Naturally, there’s a lot more sensitivity to those costs during challenging economic times.

    In theory, of course, various forms of artificial intelligence should automate data engineering best practices, but in the meantime, there simply isn’t enough data engineering expertise available. The need for a platform to optimize the flow of telemetry data across DevOps workflows is becoming more acute.

    It’s not clear how quickly DevOps teams are embracing observability, but it’s clear that relying on predefined metrics to monitor IT environments is no longer sufficient. DevOps teams need to be able to query telemetry data to, for example, identify bottlenecks created by dependencies between microservices. Resolving those issues can’t be slowed down by a lack of data to query. Most problems can usually be traced back to a recent update to an application, but there are always going to be some issues that require access to historical data. That historical data should be quickly and easily available, especially since application downtime directly equates to lost revenue for many organizations.

    Observability, regardless of cost, is rapidly becoming a requirement for DevOps teams’ success as application environments become more complex in the cloud-native era. Dependencies between the microservices that make up those applications are too difficult to track and analyze without the aid of an observability platform. The challenge is not every observability platform provider is equally concerned about how much it costs to store all that data. Striking the right balance between the amount of telemetry data collected and the cost of storing it has become a much larger concern.

  • Google’s Shiny New AI Dev Environment — the ‘Experimental’ Project IDX

    Google’s Shiny New AI Dev Environment — the ‘Experimental’ Project IDX

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: Google’s full-stack, browser based development environment in the cloud. It’s not just a Copilot clone, but aims to help you “get an app from zero to production.” (more…)

  • Datadog Updates Aim to Improve Logging, Testing Efficiency

    Datadog Updates Aim to Improve Logging, Testing Efficiency

    At its recent DASH 2023 conference, Datadog revealed Flex Logs and Intelligent Test Runner, two major new capabilities aimed at improving logging and testing efficiency for engineering teams.

    Omri Sass, director of product management at Datadog, said Flex Logs introduces a new middle tier of log storage between real-time querying and cold archives. As Sass explained, this provides a cheaper option for retaining logs beyond the typical two weeks for occasional analytics and investigations. By decoupling storage from compute for reading logs, teams can independently scale each based on their needs. This enables retaining rich log data for months or years to uncover long-term trends, he said.

    In addition, Sass noted that Flex Logs helps address common log analysis limitations around storage costs and rehydrating archives. The feature better aligns log pricing with specific use cases beyond just troubleshooting. According to Sass, this evolution in log storage tiers will likely shift more logs from legacy on-premises systems to its cloud platform.

    The second capability, Intelligent Test Runner, leverages observability signals to optimize CI test suites. As Sass explained, comprehensive test automation in CI pipelines often increases deployment times and flakes. Intelligent Test Runner inspects code changes to determine associated tests, ignoring irrelevant ones, which helps avoid long wait times for minor changes just to exercise unaffected areas.

    By tapping into existing telemetry around code commits, test health and runtimes, the feature adapts testing to each code modification. Sass explained that observability data has matured enough to enable real-time optimization like this. The end result is faster CI validation, so engineering teams can ship updates more rapidly.

    Sass highlighted how Flex Logs and Intelligent Test Runner are Datadog’s attempts to address real pain points developers face around managing log data life cycles and CI speed bumps. Sass said he believes this combination of depth in core disciplines like logs and application performance monitoring (APM), along with expanding into adjacent developer workflows, is key to solving these issues through innovation.

    Looking to the future, the observability space continues to evolve rapidly as emerging technologies and practices expand monitoring beyond traditional IT infrastructure. Companies handling modern workloads expect their observability platform to provide comprehensive visibility as development toolchains and architectures grow more complex, with the next generation of observability likely incorporating advanced analytics, automation and AI to help engineers tame systems at ever-increasing scale and speed.