Category: Features

  • But What About When You Fail?

    But What About When You Fail?

    One thing Agile and DevOps definitely brought IT was a more accepting view of the whole “mistakes happen” mantra. Crashing systems is no longer a guarantee of a free ticket out the door. Indeed, off the top of my head, I can think of at least two cases where a CIO themselves checked in sloppy code and it trashed the system—CIOs at orgs big enough that they probably should not have been coding in the first place.

    And that brings us to today’s blog. The standard response to “But what if there is a bad update?” is “We’ll just roll out a new version!” That works in some instances. In a lot of instances—most that involve GitOps as part of DevOps—it doesn’t. Implosions can be huge and take out chunks of infrastructure. So you need a better plan than just assuming you can fix it with a forward update. Do you have rollback capability? Are you making use of it, assuring all is set to roll back if needed? Testing to make sure rollback works with the other changes made across the system in this update?

    That is part of the problem. Fixing with a new update is the best option, simply because in the age of massively distributed, microservices-based solutions, rolling back comes with a ton of baggage—enough that it may not be viable for you. Okay. So you can’t quickly roll forward. You can’t quickly roll back. Quick! What do you do?!

    And I don’t have the answer to that question, because I’m not in your organization working on your systems. At some point, all IT is personal. And this is one of those points. You need to know what your best options are if an update spirals everything, and you need to have a plan to implement it. But what your best options are is not going to be the same as the next org. This is that point.

    One option is to keep the ability to build the entire system. That’s a large setup, but every minute systems are down is hurting the company. And that’s what you need to plan for. Think of it as disaster planning for DevOps. A man-made disaster that destroys systems and infrastructure.

    So, like any other disaster planning scenario, walk through the chain that makes the system work, identify weaknesses and list ways to address them. Then test those to make certain they do what you hope they will. Then, set up an automated system to keep this whole plan up-to-date.

    In short, we’re in a new automated landscape, and we need a new automated tool to pull our rears out of the fire when the inevitable happens. Be it from dev error or malicious attacker, it is a safe bet that, sooner or later, you will have a massive systems outage that your DevOps toolchain can’t adequately address. Know what you are going to do. Or at least have thought about it, so you’re not just starting to think it through while coworkers and customers can’t access systems.

    And keep rocking it. This is just another layer of protection for all the hard work you’re doing. Take the extra step. Like insurance, if you ever need it, you will absolutely be glad you did.

  • Global Next-Generation Software Engineering Conference

    Global Next-Generation Software Engineering Conference

    GNGSEC sounds the clarion call for software engineering change!

    The pandemic made 2020 the year where we see some of this decade’s most exciting digital technologies become commercially viable, and others finally go mainstream. Software is the core of digital transformation. In the digital era, the methods by which we produce software also need to be digitized. In the software engineering field, the adoption of AI, big data, cloud computing and cloud-native are accelerating the digitization for businesses.

    Global Next Generation Software Engineering Conference (GNSEC) focuses on a full range of software engineering technologies and is committed to defining the standard of the next generation of software engineering. The event will gather 1000+ Attendees and it will be live with virtual experience where senior software engineers, architects, and team leads connect, learn, and grow. Experts and developers from various backgrounds will be sharing their cutting-edge technical practical experience and cases.

    The majority of the attendees of this event will be from the Southeast Asia region (Singapore, Thailand, Indonesia, Philippines, Malaysia, Vietnam), India and China. Due to the current travel restriction, GNSEC 2021 will be virtually presented via Airmeet. It will offer attendees with virtual exhibitions, virtual conference, peer networking session, business matching session, virtual discussion group.

    Global Next Generation Software Engineering Conference (GNSEC) is co-presented by DAOPS Foundation and Escom Events. The event is part of digital innovation series events that features AI, DevOps, Cybersecurity and digital transformation. Previously the event was presented in Shanghai, Shenzhen, Beijing, California and Hong Kong.

    There will be more than 30 speakers from DBS Bank, ING, IBM, Daimler, Tencent, JD.COM, DevOps Institute, Gitlab, New Relic, SUSE and more to share ideas, experiences and case studies in software engineering.

    Register here to join​​ the event with us to rebuild software engineering.

  • ReleaseIQ Adds Orchestration Tool for Multiple Instances of Jenkins

    ReleaseIQ Adds Orchestration Tool for Multiple Instances of Jenkins

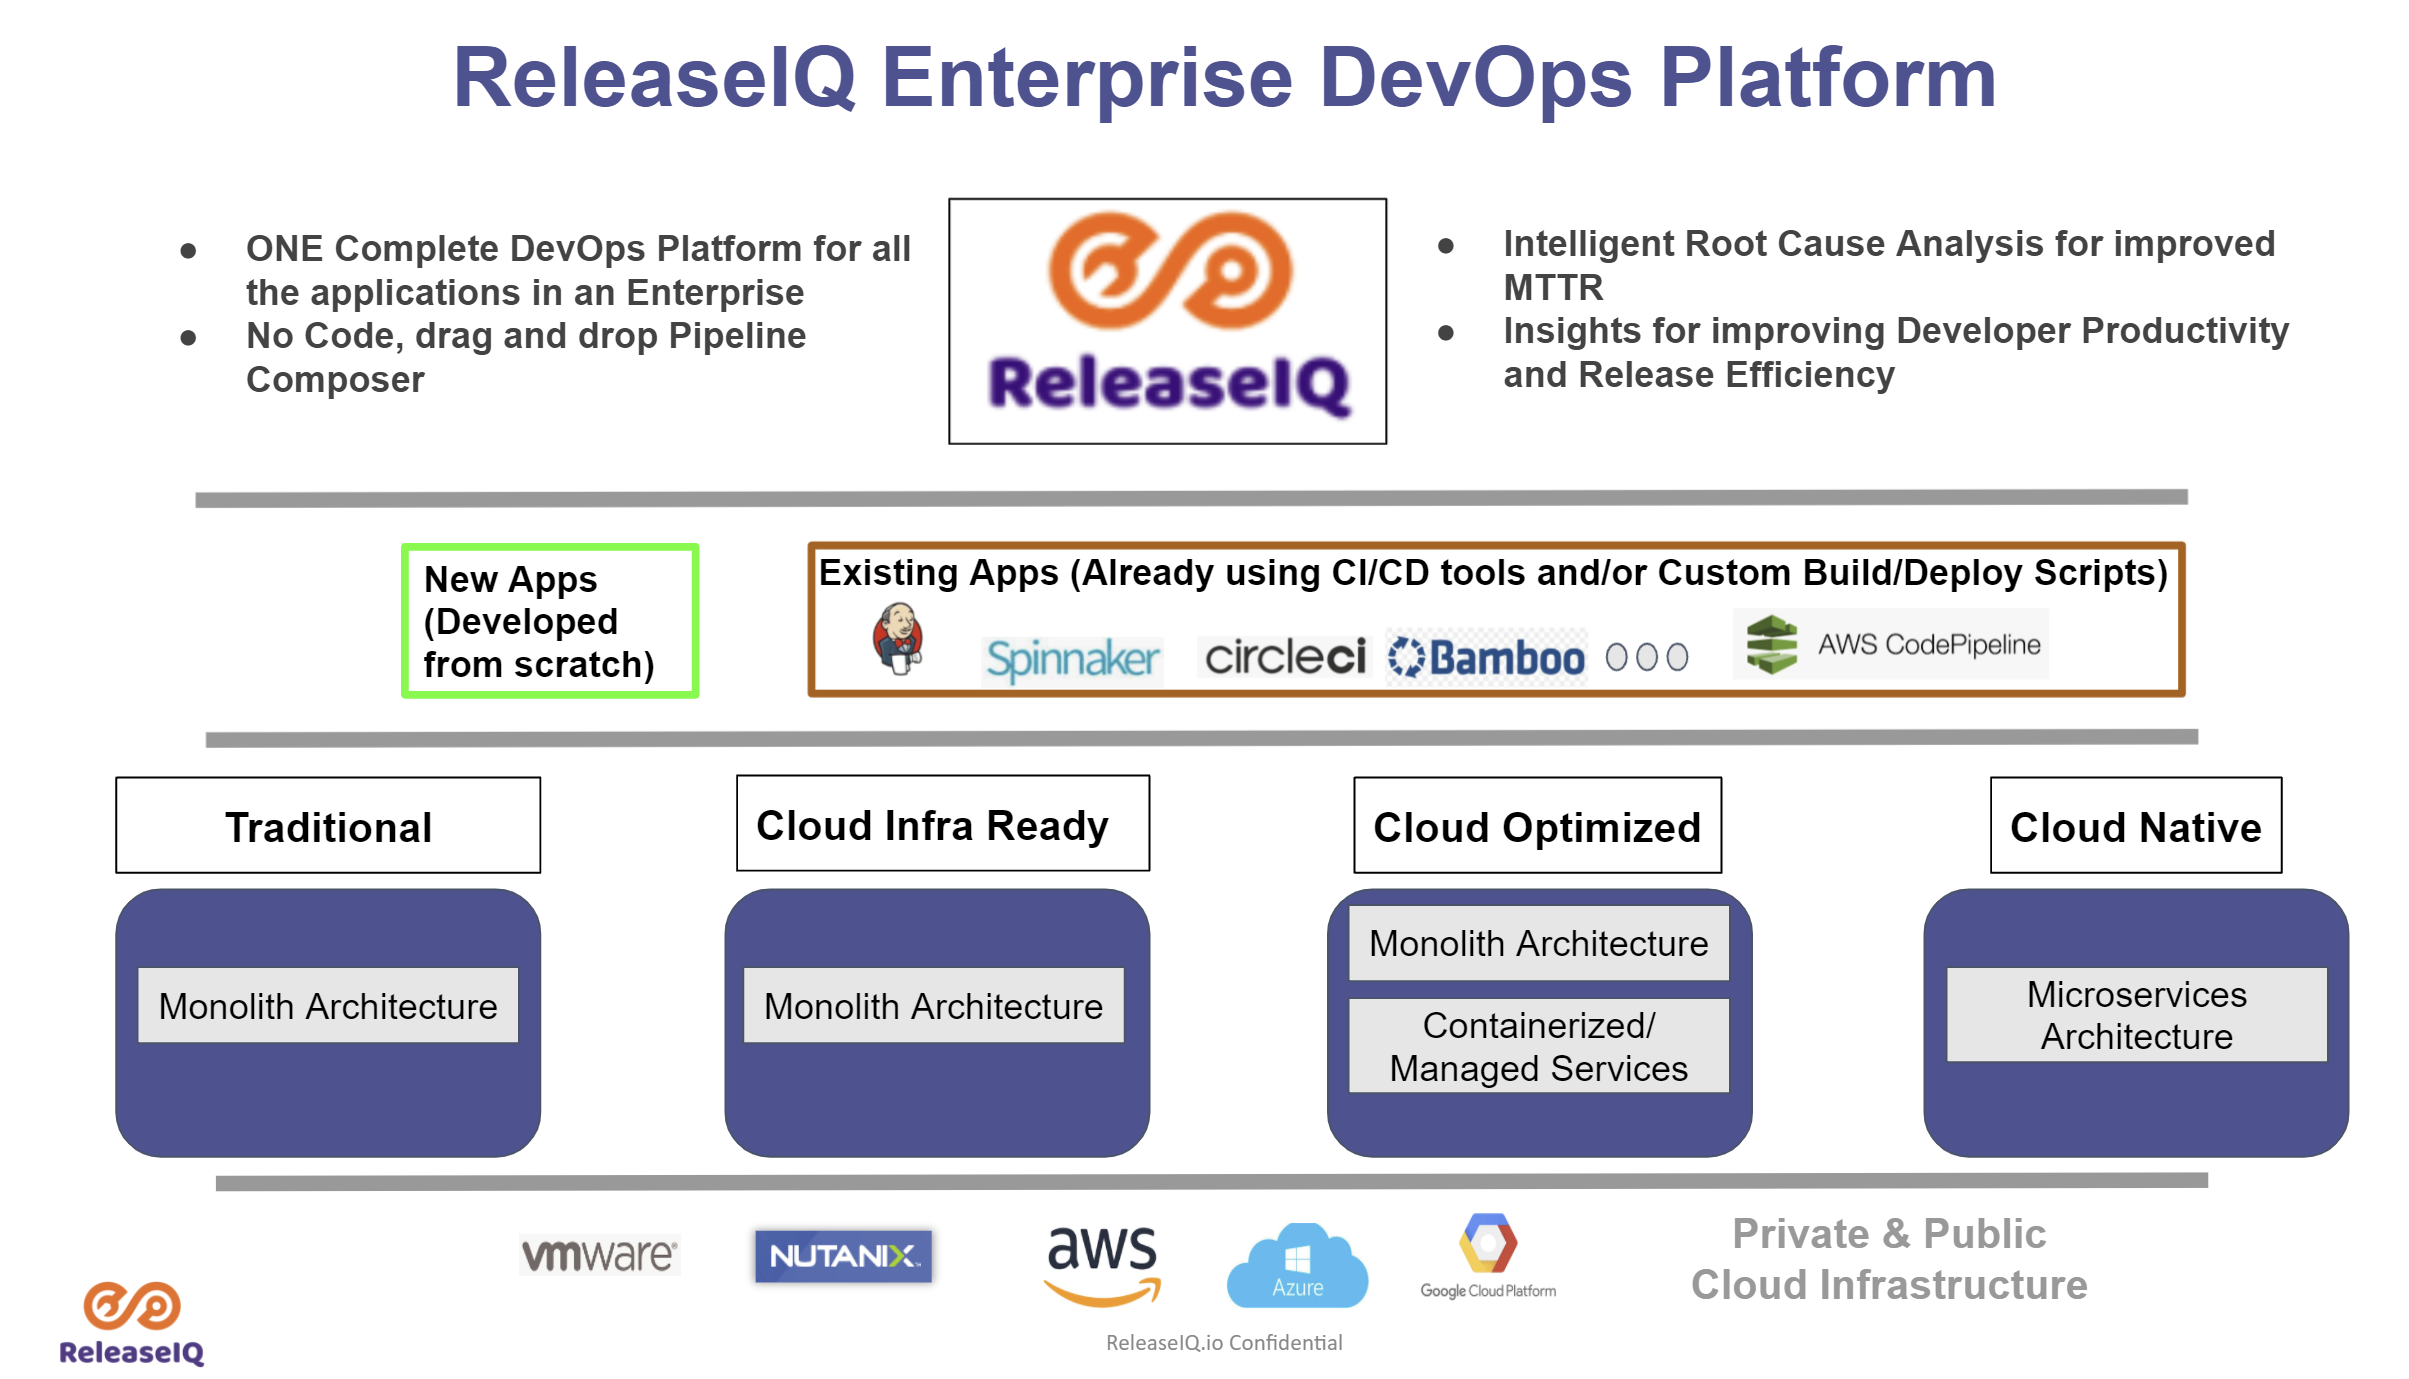
    ReleaseIQ has launched an orchestration framework for the open source continuous integration/continuous delivery (CI/CD) environment that makes it possible for DevOps teams to orchestrate pipelines across multiple instances of Jenkins.

    Seetharam Param, ReleaseIQ CEO, said ReleaseIQ Essentials for Jenkins is an implementation of an existing orchestration platform that enables DevOps teams to orchestrate pipelines across heterogeneous CI/CD platforms.

    The challenge is that organizations that have standardized on Jenkins typically have multiple instances being used by not only different IT operations teams but also owners of, for example, ancillary quality assurance processes. ReleaseIQ Essentials for Jenkins provides an alternative approach to the orchestration tools that CloudBees, the original developer for Jenkins, provides, said Param.

    Jenkins today is being advanced independently of CloudBees as an open source project managed by the Continuous Delivery (CD) Foundation, which is an arm of the Linux Foundation. Founding members of the CD Foundation include CloudBees along with Alauda, Alibaba, Anchore, Armory, Autodesk, Capital One, CircleCI, DeployHub, GitLab, Google, Huawei, JFrog, Netflix, Puppet, Red Hat, SAP and Snyk.

    ReleaseIQ Essentials for Jenkins optimizes execution of jobs and pipelines and also provides DevOps teams with a no-code graphical interface to build pipelines.

    DevOps teams can also import and execute Jenkins pipelines and jobs in addition to being able to pre-merge pipelines.
    Finally, DevOps teams are provided insights based on key metrics the platform automatically tracks on their behalf. Those metrics make it possible to quickly discover and fix pipeline issues across multiple Jenkins instances via console log aggregation, noted Param.

    It’s not clear to what degree DevOps teams that have standardized on Jenkins might swap out one orchestration tool for another. However, Param said more organizations are either wary of becoming locked into a specific CI/CD platform or now find themselves in a position where they need to continue employing multiple CI/CD platforms from different vendors. The ReleaseIQ platform provides a means for orchestrating pipelines regardless of how many different CI/CD platforms are employed, noted Param.

    It’s clear the need to embrace orchestration tools is becoming more pronounced. DevOps teams are spending too much time manually maintaining DevOps pipelines. The need for tools to automate the management of DevOps workflows is becoming critical as the number of application development projects that are simultaneously being launched continues to grow. Arguably one of the reasons that DevOps processes are not as widely embraced as they might be is the level of expertise required today to manage all the pipelines that make up a workflow.

    Of course, the level of DevOps maturity varies greatly by organization. It’s not uncommon for even different teams within the same organizations to have significantly different levels of proficiency. The challenge and the opportunity now is to provide those DevOps teams with tools that operate at a high enough level of abstraction to make DevOps accessible to every IT professional regardless of the level of programming expertise they may or may not have.

  • The Role of APIs in Mainframe Modernization

    The Role of APIs in Mainframe Modernization

    Mainframes are historically clunky systems. They are incredibly secure and can process impressive calculations, yet they are complex to manage and challenging to extract data from. This reality is at odds with modern cloud-native infrastructure, which emphasizes distributed computing and portable microservices. So, how can existing mainframes adapt to this connected, data-driven economy?

    I recently met with Dr. Alex Heublein, president at Adaptigent, to talk about the state of legacy modernization. According to Heublein, many mainframes are here to stay for the foreseeable future. However, enterprises are continuing to get value from these systems by adding an integration layer on top of them. By using a REST API layer on top of a mainframe, enterprises could finally open up these systems. This could facilitate bidirectional communication with newer cloud-native services, enable phase migration and edge closer to real-time processing.

    State of Mainframe Modernization

    The software industry changes every day. “Nothing in the tech field is permanent,” said Heublein, yet some legacy technologies will persist into the foreseeable future. In terms of mainframe adoption, Heublein sees a couple of categories of users. First are the large financial services organizations, such as large banks and insurance companies, which are considerably invested in their mainframe architectures and which will likely continue to rely on mainframe environments for their policy management and core infrastructure. “I think there’s a lot of good reasons for that,” explained Heublein. “If you want to process billions of transactions a day, [mainframe] is still a good option.”

    That said, regulations and market pressures are influencing a global movement toward open banking. For example, PSD2 mandates open banking in Europe and industry consortiums like Financial Data Exchange (FDX) are directing it in the U.S. market. These initiatives are encouraging financial services to transform their legacy environments and spurring cloud migration, especially for applications that aren’t mission-critical.

    Heublein pointed out a few different patterns in enterprise mainframe modernization. One approach is that enterprises are rewriting or re-architecting old COBOL applications and keeping them on-premises. Or they are porting and re-platforming the application; moving a COBOL app to a Windows or Linux system, for example. Finally, some are shifting straight to the cloud. For solutions that don’t need to be on the mainframe, enterprises may shift toward cloud-native to free up capacity.

    APIs Enable Legacy Modernization

    Distributed cloud technology is helping businesses scale to the right level. Yet, it’s difficult to jump off the mainframe entirely, noted Heublein. “Very rarely can you take all your stuff and move it all at once,” he said. “It’s a tough pill to swallow.” It’s especially difficult to move core banking infrastructure to a distributed environment—an instant shift could introduce security risks. For this reason, he recommended a ‘phase migration’ approach in which individual components are slowly migrated. For example, an insurance provider may shift their claims engine, policy engine and ratings engine to the cloud one at a time.

    As a result of phase migration, however, engineers must simultaneously support both on-premises and cloud-based applications. They must also ensure bidirectional communication so that these systems can exchange data. This is where a REST API transactional layer is necessary, Heublein explained. Such a layer could enable bidirectional communication between the mainframe and cloud-native applications, abstracting complexity when calling out to the modern world, or intercepting cloud data and filtering it into a format mainframe technologies can process.

    To increase developer usability, abstracting complexity from the mainframe integration process will be the key to building out connectivity. This could involve a codeless development approach with a COBOL sub-routine to call external systems, Heublein said. Automatic restructuring of data will be necessary to enable fluent bidirectional communication, too.

    Four Business Drivers of Mainframe Integration

    So what is the end result of putting an integration layer on top of mainframe systems? According to Heublein, there are four key business benefits of using such an abstraction layer:

    1. Orchestration: Software ecosystems often need to make multiple calls to different applications to collect and transform data. Yet, mainframe environments are very complex and challenging to integrate with. More usable integration fabric for mainframe systems could enable better orchestration of workflows in a developer-friendly manner. By using a REST interface, all apps could be calling the same interface, thus greatly simplifying orchestration between disparate services.
    2. Sustained Adaptability: The world is rapidly accelerating, and enterprises need to maintain and modify these APIs very quickly. Organizations require “sustained adaptability” to adapt and survive in the digital world, said Heublein. Mainframe systems, however, were not designed for the 21st century. Thus, low-code integration layers are critical to empowering rapid development.
    3. Data Transformation: Data is powerful for the business. Data is not only a commodity in and of itself but also is required for AI and machine learning. However, mainframes have a completely different way of encoding data. Thus, there is a need to transform this data into a modern format that businesses can consume. An integration layer between these systems can deliver an improved data consumption model.
    4. Real-Time Processing: You may think online payments happen in real-time; however, payment apps like Venmo are really just an abstraction layer over bank transactions, which may clear as little as twice a day. In short, mainframes are not great at real-time processing. However, more usable integrations to this infrastructure could enable user-facing applications to interact more closely to real-time.

    Another concern is security. Opening up mainframe environments that house core financial infrastructure must be done with extreme care—especially as API attacks remain the number-one rising threat in the software landscape. All organizations building out new integrations will require a secure layer from an outbound standpoint. Heublein said this often involves placing an API management layer or gateway in front of the integration layer. This system enables authorization and functions like a firewall between the internal and external world. It can also enable logging and prevent denial of service attacks, he explained.

    Improving Agility for Legacy Systems

    Legacy systems are entrenched in older technology and carry lots of technical debt, forcing operations to move at a slower pace. Maintainers are also culturally a bit different than the newer breed of cloud-native engineers. “Mainframe people are not … fast,” said Heublein.

    DevOps folks want to build, test and promote projects to production very quickly and, arguably, this agility is necessary to satisfy rising digital innovation demands. Improving integration capabilities for on-premises systems could enable businesses to better utilize preexisting investments while also improving agility.

    Low-code/no-code capabilities could also increase collaboration potential, Heublein added, which could bridge the gap between on-premises engineers and fast-moving business folks. When adopting low-code/no-code tools for mainframe integration, he cautioned against general-purpose citizen developer frameworks. Whereas universal integration layers can work well for many situations, he stressed that a very specific boundary box is best for building APIs for mission-critical applications.

    How is your organization approaching modernization for legacy systems? Let us know in the comments below!

  • Perforce Melds Artifact Package Manager with Version Control Platform

    Perforce Melds Artifact Package Manager with Version Control Platform

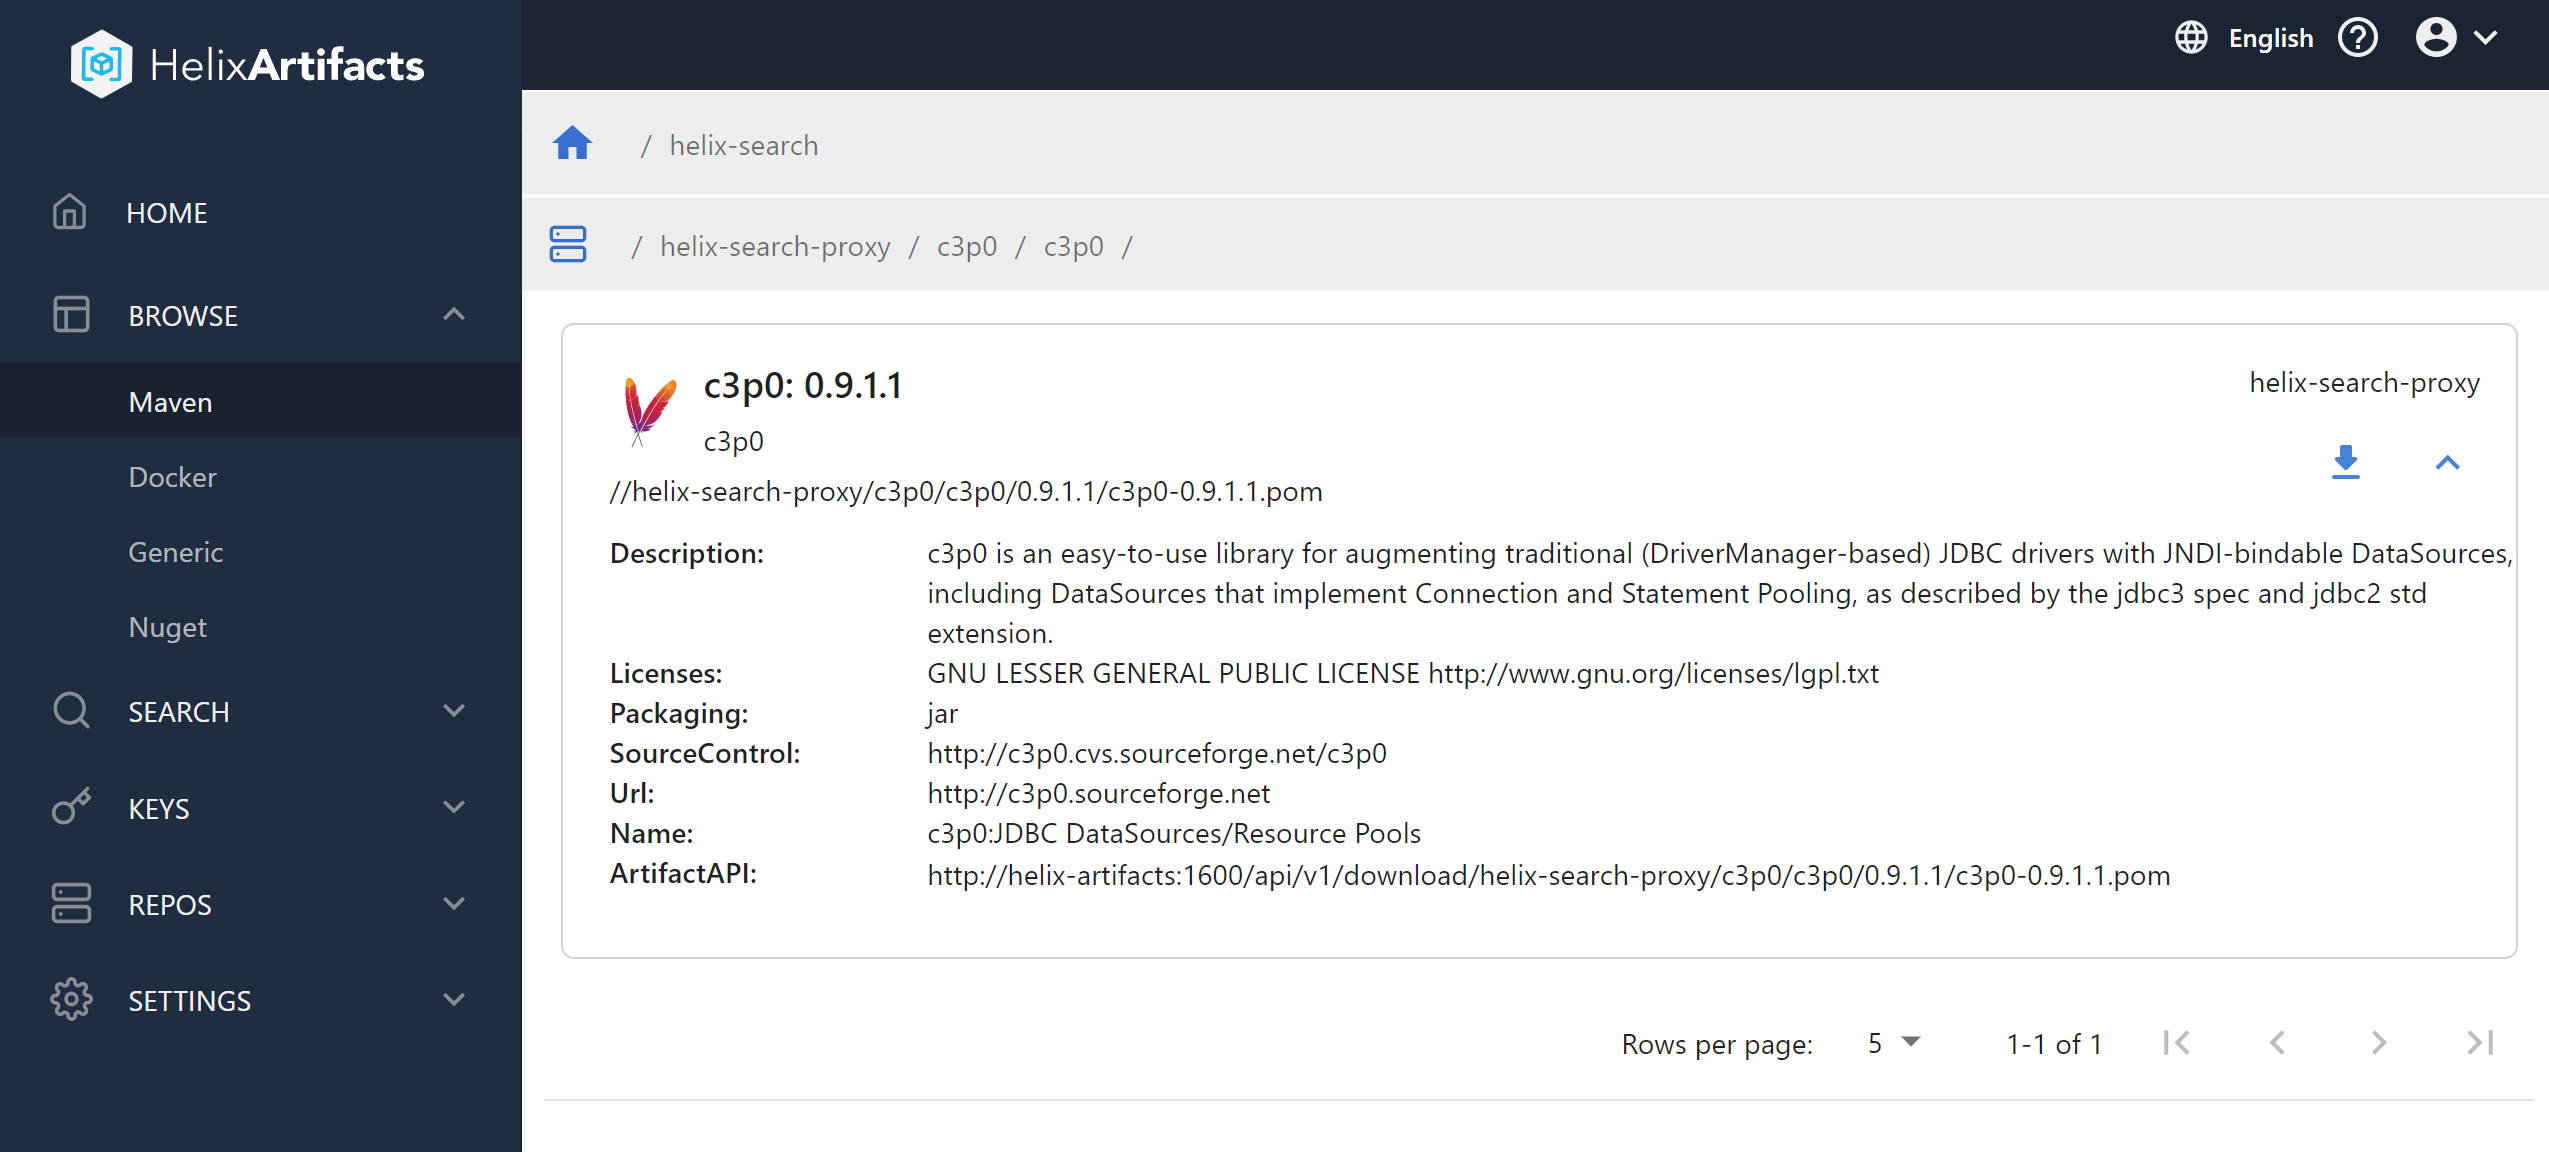
    Perforce Software has added a universal package manager, dubbed Helix Artifacts, to its portfolio that enables users of its Helix Core version control platform to store and track source code.

    Gerhard Krüger, product manager for Helix Core digital asset management at Perforce Software, said the goal is to enable DevOps teams that employ Helix Core to access a package manager without having to exit Helix Core.

    That approach also provides a more secure and cost-effective way to store, consume and distribute artifacts that also serves to improve developer productivity, he added. The ability to manage artifacts on top of a version control platform also means DevOps teams will not need to set up additional storage infrastructure or configure separate security permissions just to distribute software packages, noted Krüger.

    Perforce

    Helix Artifacts is a self-hosted package manager that functions as a translator for packages such as NuGet, Maven or Docker that enables them to communicate directly with Helix Core as well as build systems and integrated developer environments (IDEs). Helix Artifacts is made available via a per-server subscription model that costs substantially less than rival approaches to managing artifacts, Perforce Software claims.

    Most DevOps teams are trying to strike a balance between employing best-of-breed tools to build applications and the need to reduce complexity and, ultimately, cost. As such, any time a tool becomes a feature of another platform that a DevOps team uses, there will be a review of the processes being employed. Many DevOps teams are trying to reduce the amount of time they spent maintaining tool integrations.

    There’s also now a lot more focus on software supply chain security. Each new tool generally creates yet another set of credentials that need to be protected as cybercriminals continue to aggressively attempt to inset malware into applications before they are deployed in a production environment. It’s not clear to what degree DevOps teams are looking to consolidate toolchains, but given those rising security concerns, it’s only a matter of time before security teams start to ask why the DevOps toolchain attack surface is so wide.

    In the meantime, the number of organizations that have widely embraced DevOps best practices across the enterprise continues to steadily grow. Over the past decade, most organizations have had at least one application development team embrace DevOps. However, as the pressure to build software to drive digital business transformation initiatives has steadily increased since the onslaught of the COVID-19 pandemic, the need to apply DevOps best practices to accelerate application development has become more pronounced. As a result, more organizations than ever are looking to standardize their application development efforts on a smaller number of platforms to reduce friction.

    It’s too early to say whether the rate at which applications are being developed and deployed since the start of the pandemic has actually increased. The one thing that is certain, however, is the bulk of organizations are now trying to accelerate like never before.

  • 4 Tips To Plug The Cloud IT Skills Gap

    4 Tips To Plug The Cloud IT Skills Gap

    Technical talent is few and far between. The programming world faces a developer shortage, and with this shortage comes a lack of cloud know-how. By now, most organizations have become multi-cloud, yet 86% of IT professionals believe a lack of these skills will slow down cloud projects.

    As more teams transition from older architectures to cloud environments, the IT skills gap could pose a severe bottleneck to software development and deployment. Cloud servers require ongoing maintenance, and managing security and compliance is challenging, even for seasoned developers. Furthermore, it’s easy to overspend in the cloud—without keen insight into vendor nuances, it becomes challenging to select the most cost-effective package for the application at hand.

    I recently talked with Joe Spurrier, chief technology officer and co-founder, cloudtamer.io, to see how teams can improve their cloud strategies while navigating a short supply of IT cloud know-how. According to Spurrier, increasing automation, sharing reusable templates, centralizing best practices and maintaining agnosticism are strategies to amplify cloud results. Below, we’ll expand on these areas to see how they maximize cloud benefits while retaining a lean engineering footprint.

    Automation, Automation, Automation

    “Automation is key to furthering your adoption and use of the cloud,” said Spurrier. The drive to automate comes as no surprise to many DevOps and SRE professionals whose goal is to automate their job away. When automating the cloud, infrastructure-as-code (IaC) is a fundamental necessity. “If you’re getting into cloud, you should probably have some scripting skills,” said Spurrier.

    Automation can significantly aid scalability when setting up additional accounts since engineers must replicate similar operations, such as server provisioning, deployment patterns, monitoring and so on. Automation is also essential for shift-left testing and to increase observability into production environments. “It’s one thing to deploy an application via automation, but another to have tests in automation—that’s the next level,” said Spurrier.

    Now that so many tools are API-driven, orchestration becomes programmable. A cloud service provider’s CLIs or SDKs could also be leveraged to hook into these integrations to construct such automation.

    On the flip side, too much automation for high-level privileges could backfire. “Someone could break into a data center, steal a server, disconnect it, then run off,” Spurrier explained. Thus, automation will require a higher sense of security to ensure that every change is appropriately authorized and logged.

    Reusable Templating

    Along with automation, documenting operational processes to be shared amongst engineering teams is vital for maximizing efficiency in a lean talent landscape. The key here is to make the process self-documenting and reusable, stresses Spurrier. This will most likely involve someone on the team creating shared libraries and repositories for other team members to leverage.

    One such example is Amazon’s golden AMI pipeline. Golden AMIs are virtual machines that teams can “standardize through configuration, consistent security patching and hardening.” Golden AMIs can also enable a repeatable process for performing monitoring, logging and even distribution to business units.

    Reusable patterns are important for building CI/CD systems so that when you commit code, it is automatically deployed to preferred cloud providers. In general, Spurrier recommends building shared repositories that are easy to clone, with step-by-step instructions for usage. Sample applications that demonstrate components in different languages can also aid developer usability and save time.

    Adopt Centers of Cloud Excellence

    Another way to encourage better adoption is by creating a center of cloud excellence (CoCE). For an enterprise, having a cloud-centric project management group can be very helpful to organize knowledge and offer support. A CoCE could centralize operations, supply engineers with pre-configured containers and help distribute access to cloud accounts.

    A CoCE is a good way to start to unite disparate teams around shared best practices, said Spurrier. Depending on your organization’s needs and workloads, a CoCE will focus on varying skills, he added. In the beginning, a company may have just one center for cloud knowledge. However, as adoption grows, dedicated centers may likely emerge around specific cloud providers, too.

    Retain Agnosticism

    Contrary to popular belief, multi-cloud steups aren’t always about lift and shift. Business units often adopt a particular cloud to suit specific workload requirements. For example, researchers may choose GCP for its data science functions, or Microsoft shops may prefer Azure.

    In a multi-cloud world, management layers could help retain a modicum of vendor neutrality. For example, take Cloud Custodian, a tool developed at Capitol One and recently contributed to the CNCF. Using Cloud Custodian, engineers can run security checks across AWS, Azure and GCP and generate metrics for reporting. Such control and insights could empower teams to automate some of the multi-cloud management burdens.

    When working with multi-cloud, it’s also good to consider agnostic tooling that can work across different providers, like Terraform or Kubernetes, Spurrier said.

    Templating

    Cloud transformation is ongoing at most organizations. With this rise, more cloud-native processes and tools are emerging. Yet, with talent in short supply, DevOps isn’t always fully prepared. To review, we covered four ways businesses can circumnavigate this issue to get an edge:

    • Increased cloud automation is a necessary response to a slimmer labor pool. Though building automation requires upfront technical skill, it pays dividends in increased efficiencies.
    • Reusable libraries and templates can rapidly configure new projects and do so consistently across business units.
    • Consider maintaining a center of cloud excellence to centralize policies and offer support.
    • Opt for agnostic tools. This helps to retain vendor neutrality and apply consistent controls across clouds.

    Of these above strategies, Spurrier emphasized the importance of creating shared templates. When used right, a templating approach can be very effective, he says. “If you have a templating model, it should be easy for DevOps teams to migrate to new features. If you’re leveraging tools that set up templates, it’s easier to figure out how much infrastructure is going to cost.”

  • Sumo Logic Extends Observability Scope and Reach

    Sumo Logic Extends Observability Scope and Reach

    During the online Illuminate user conference, Sumo Logic revealed how it is integrating capabilities it gained with the June 2021 acquisition of Sensu, a provider of open source monitoring tools, with its continuous intelligence platform in addition to adding support for data collected via open source OpenTelemetry software.

    Sensu Go, a set of tools for implementing monitoring-as-code, is now a core part of the Continuous Intelligence Platform. The company is also now making available in beta Sumo Logic OpenTelemetry Distro and Ecosystem Support, a single agent through which all logs, metrics and traces can be collected from instrumented applications. Sumo Logic is also supports the AWS OpenTelemetry Distro, an offering from AWS that provides similar capabilities. Sumo Logic has also increased the capabilities of Sumo Logic Free to include monitoring-as-code tools created Sensu.

    Bruno Kurtic, vice president of product and strategy, said as responsibility for managing applications shifts left toward developers it’s critical to provide observability capabilities that can be programmatically infused into applications. As part of that effort, Sumo Logic is now also offering Sensu Plus, which provides access to an analytics engine for the data the platform collects.

    Sumo Logic is also adding machine learning algorithms to provide more context to the alerts the platform generated via an Alert Response feature that is part of the core platform.

    The company is also adding support for the operator software that Red Hat created to make it simple to deploy Sumo Logic Continuous Intelligence Platform alongside the Red Hat OpenShift platform for building and deploying applications on top of Kubernetes clusters. In addition, Sumo Logic is also providing integration with a total of 38 either new or updated observability applications that integrate with a wide range of third-party platforms.

    Finally, Sumo Logic is extending the security observability platform it provides based on its platform to add support for containers and serverless computing functions alongside virtual machines and integrations with third-party endpoint detection and response (EDR), network detection and response (NDR), threat intelligence and managed detection and response (MDR) platforms. The company has also added or updated 26 applications for specific third-party platforms.

    Kurtic said Sumo Logic makes it possible for developers and IT operations teams alike to observe an IT environment on an end-to-end basis via a single pane of glass. In some cases, the members of an IT operations team will require a user interface to manage that environment. Developers, meanwhile, might prefer an application programming interface (API) through which observability data is made accessible from within a continuous integration/continuous delivery (CI/CD) platform.

    Regardless of the type of user, however, IT teams should not have to hire their own data science team to analyze observability data. Instead, the observability platform should embed machine learning algorithms that surface all the benefits of data science without the need to hire additional headcount, he said.

    One way or another, DevOps teams will soon routinely benefit from the additional levels of context that observability platforms provide. The challenge will then be determining how best to fix a raft of issues that many DevOps teams today simply didn’t know existed.

  • CloudBees Acquires Neuralprints to Shift Compliance Left

    CloudBees Acquires Neuralprints to Shift Compliance Left

    At the online DevOps World 2021 conference today, CloudBees revealed it has acquired Neuralprints to provide the core technology for CloudBees Compliance, a real-time compliance and risk analysis platform that it will roll out in the first quarter of 2022.

    At the same time, CloudBees has enhanced the feature management capabilities of its namesake continuous integration/continuous delivery (CI/CD) platform to provide greater visibility into and control over feature flags that are now widely used to add new capabilities to applications.

    Prakash Sethuraman, chief information security officer (CISO) for CloudBees, said CloudBees Compliance will make it possible for DevOps teams to continuously enforce compliance policies as part of an effort to better secure their software supply chains. Those DevOps teams will be able to enforce compliance across code, binary artifacts, data, identity and infrastructure environments in a way that provides developers and IT operations teams with instant actionable feedback to enable issues to be addressed long before an application is deployed in a production environment.

    CloudBees Compliance is based on a mix of open source and proprietary technologies developed by Neuralprints and will be made available for on-premises IT environments as well as via a software-as-a-service (SaaS) application. The goal is to enable organizations to manage compliance as code as part of any effort to shift more responsibility for application security further left toward DevOps teams, said Sethuraman.

    CloudBees Compliance

    A survey of 500 C-level executives published today found nearly half (45%) admit that initiatives to secure their software supply chains are halfway or less-than-halfway complete. Nevertheless, 95% claimed their software supply chains are secure (95%), with more than half (55%) posting they are very secure.

    A full 93% said they are prepared to deal with an issue such as ransomware or a cyberattack on their supply chain. However, nearly two-thirds (64%) admitted they are not sure who they would turn to first if their supply chain was attacked; with 58% admitting that, if they experienced an attack, they have no idea what their company would do. An equal percentage (64%) said it would take more than four days to fix the problem if they did experience an issue.

    Almost all C-level executives (95%) said they think more about securing the supply chain now than they did just two years ago, and 92% said a security issue would impact their brand. A total of 83% said security issues cause their developers to drop everything to review code, with 82% noting that caused the organization to spend less time on innovation.

    On the plus side, 95% of executives said container images are checked for high or critical vulnerabilities, while an equal number said automation access keys are set to expire automatically. A total of 92% said their company only accepts commits signed with a developer GPG key, while 90% said dependencies to trusted registries are limited at their organization, while 89% said administrative access to CI/CD tools is restricted (89%).

    Of course, what C-level executives believe and what actually occurs inside an organization are not always one and the same. A series of high-profile software supply chain breaches resulted in a number of organizations reviewing their software supply chains. At the same time, the Biden administration has issued an executive order requiring all federal agencies to conduct similar reviews.

    One way or another, most organizations will soon find themselves embracing a wider range of DevSecOps best practices to ensure the integrity of software supply chains no matter how secure they may think their software development platforms are today.

  • Red Hat Extends Scope of Ansible Automation Ambitions

    Red Hat Extends Scope of Ansible Automation Ambitions

    During the online Ansiblefest, Red Hat announced the availability of a preview edition of Red Hat Ansible Automation Platform 2 that is intended to make it easier to automate IT processes at scale.

    Richard Henshall, senior manager for Ansible product management at Red Hat, said previously most IT teams have been automating individual processes, but as organizations become more adept at creating playbooks to automate processes, they now need to find ways to manage multiple automations that are often dependent on one another.

    Ansible Automation Platform 2 also enables IT teams to automate processes that span both monolithic as well as cloud-native applications based on containers using an automation controller, formerly known as Ansible Tower, that is more tightly integrated with Red Hat OpenShift, an application development and deployment platform based on Kubernetes, using Red Hat Operator tools. There is also an automation mesh capability that connects disparate automation components together and provides status checks.

    Ansible Automation Platform 2 also introduces automation execution environments within Ansible Engine that make it possible to create self-contained automation spaces that can be easily replicated and repeated across an organization.

    Red Hat also includes an automation content navigator to helps teams validate that automation content is working as it should across even the largest environments, along with updates to the Red Hat Insights analytics service that enable issues that might occur with automation controllers to be surfaced and eliminated by automatically applying policies.

    Henshall said going forward, IT teams should expect to see Red Hat focus more on enabling events to be the catalyst for triggering automation. Today, most automated processes begin with an IT administrator triggering the process. However, as digital business transformation initiatives mature, it’s become apparent there will be a need to trigger automation when specific events occur.

    Henshall said while there are still many organizations that are just starting to automate IT processes, there are also many that are entering the next phase of maturity. As such, they now require an automation platform that makes it simpler to manage automation at scale.

    In general, Ansible is designed to make it possible for developers and IT operations teams alike to declaratively create automation without much programming expertise required. However, creating a playbook that works reliably still requires a deep understanding of the processes that are being automated. Most IT teams would be well advised to closely monitor processes when they are first automated to make sure they are performing tasks as anticipated.

    Ultimately, it’s now a question of when rather than if most IT processes will be automated. DevOps teams, of course, have always been at the forefront of automation, but now it’s clear that as IT environments become more complex—with the rise of both the cloud and edge computing platforms—enterprise IT teams need to embrace automation more aggressively. The biggest barrier to automation is simply finding someone who has the passion to automate a process to lead the charge, said Henshall.

    Naturally, most of those efforts will initially focus on repetitive, tedious and manual IT tasks, but the potential to automate IT processes at levels of unprecedented scale has never been greater.

  • The New(ish) Complexity

    The API economy and microservices architectures, led by Agile and DevOps, have introduced a massive amount of hidden complexity. I call it hidden complexity because we have a tendency in IT to focus on the problems in front of us, resolve them, then focus on the new problem in front of us. This leaves technical debt in little piles behind us, like the bits that fall off the ends of a snowplow blade (or the asphalt that squishes out the end of the steamroller for our southern friends).

    I was thinking about this when I was looking into how a majority of you handle scalability. The layers of complexity for scalability are surprising. In the past, we invested upfront to be prepared to scale to the levels we need. Today we allow expenses to grow as users grow. That is a great model if users are tied to revenue. If there is any fungibility at all in the correlation of users to revenue (and there almost always is), this is a potential disaster waiting to happen. “Our traffic spiked 200%, but revenue only grew 20%,” is pretty much the last thing your business leaders want to hear. Because in the “Pay as you grow” world, a 200% spike in users means a significant spike in overhead. How much overhead varies pretty wildly, of course, so I’ll just say “Guaranteed and significant” and leave it at that.

    This is a known bit of complexity, but those of you I’ve spoken with have done little to hedge against it. That’s … interesting. How many other hidden land mines are out there, being ignored by us?

    What can you do? That greatly depends upon your business. with internal systems, you have a lot of say in usage. External systems are where this is potentially an issue. You can pay your provider to block DDoS, so at least you’re not paying for that bandwidth if that happens—and most of the people I spoke with really do have some form of DDoS protection that stops traffic before it becomes a fee-generating hit. But for actual growth, the best you can do is get with business leaders and determine what influences the correlation between users and revenue. What makes those people upping your traffic actually spend money while they’re upping your traffic? What can you do to convince more of them to spend money? What services are you not offering that might be useful to those customers and not significantly increase overhead. Basically, this is the modern equivalent of the conversion problem. They’re on your site, how do you convert them to paying users of your site.

    We really can’t get more detailed than that—you know your business, and a media site is a different model than a retail site, for example—so you’ll have to develop beyond that. But have a plan that does what you can to make sure that when expenses go up, revenue goes with it.

    And keep rocking it. We’re outside the historical IT realm here—because you’re all rocking it so well that we have new things to worry about. Give those customers rockstar apps to work with and figure out how to make them paying customers. Develop those bonds with business leaders; you do indeed need each other.