Category: Features

  • New Relic I/O Aims to Simplify Instrumentation

    New Relic I/O Aims to Simplify Instrumentation

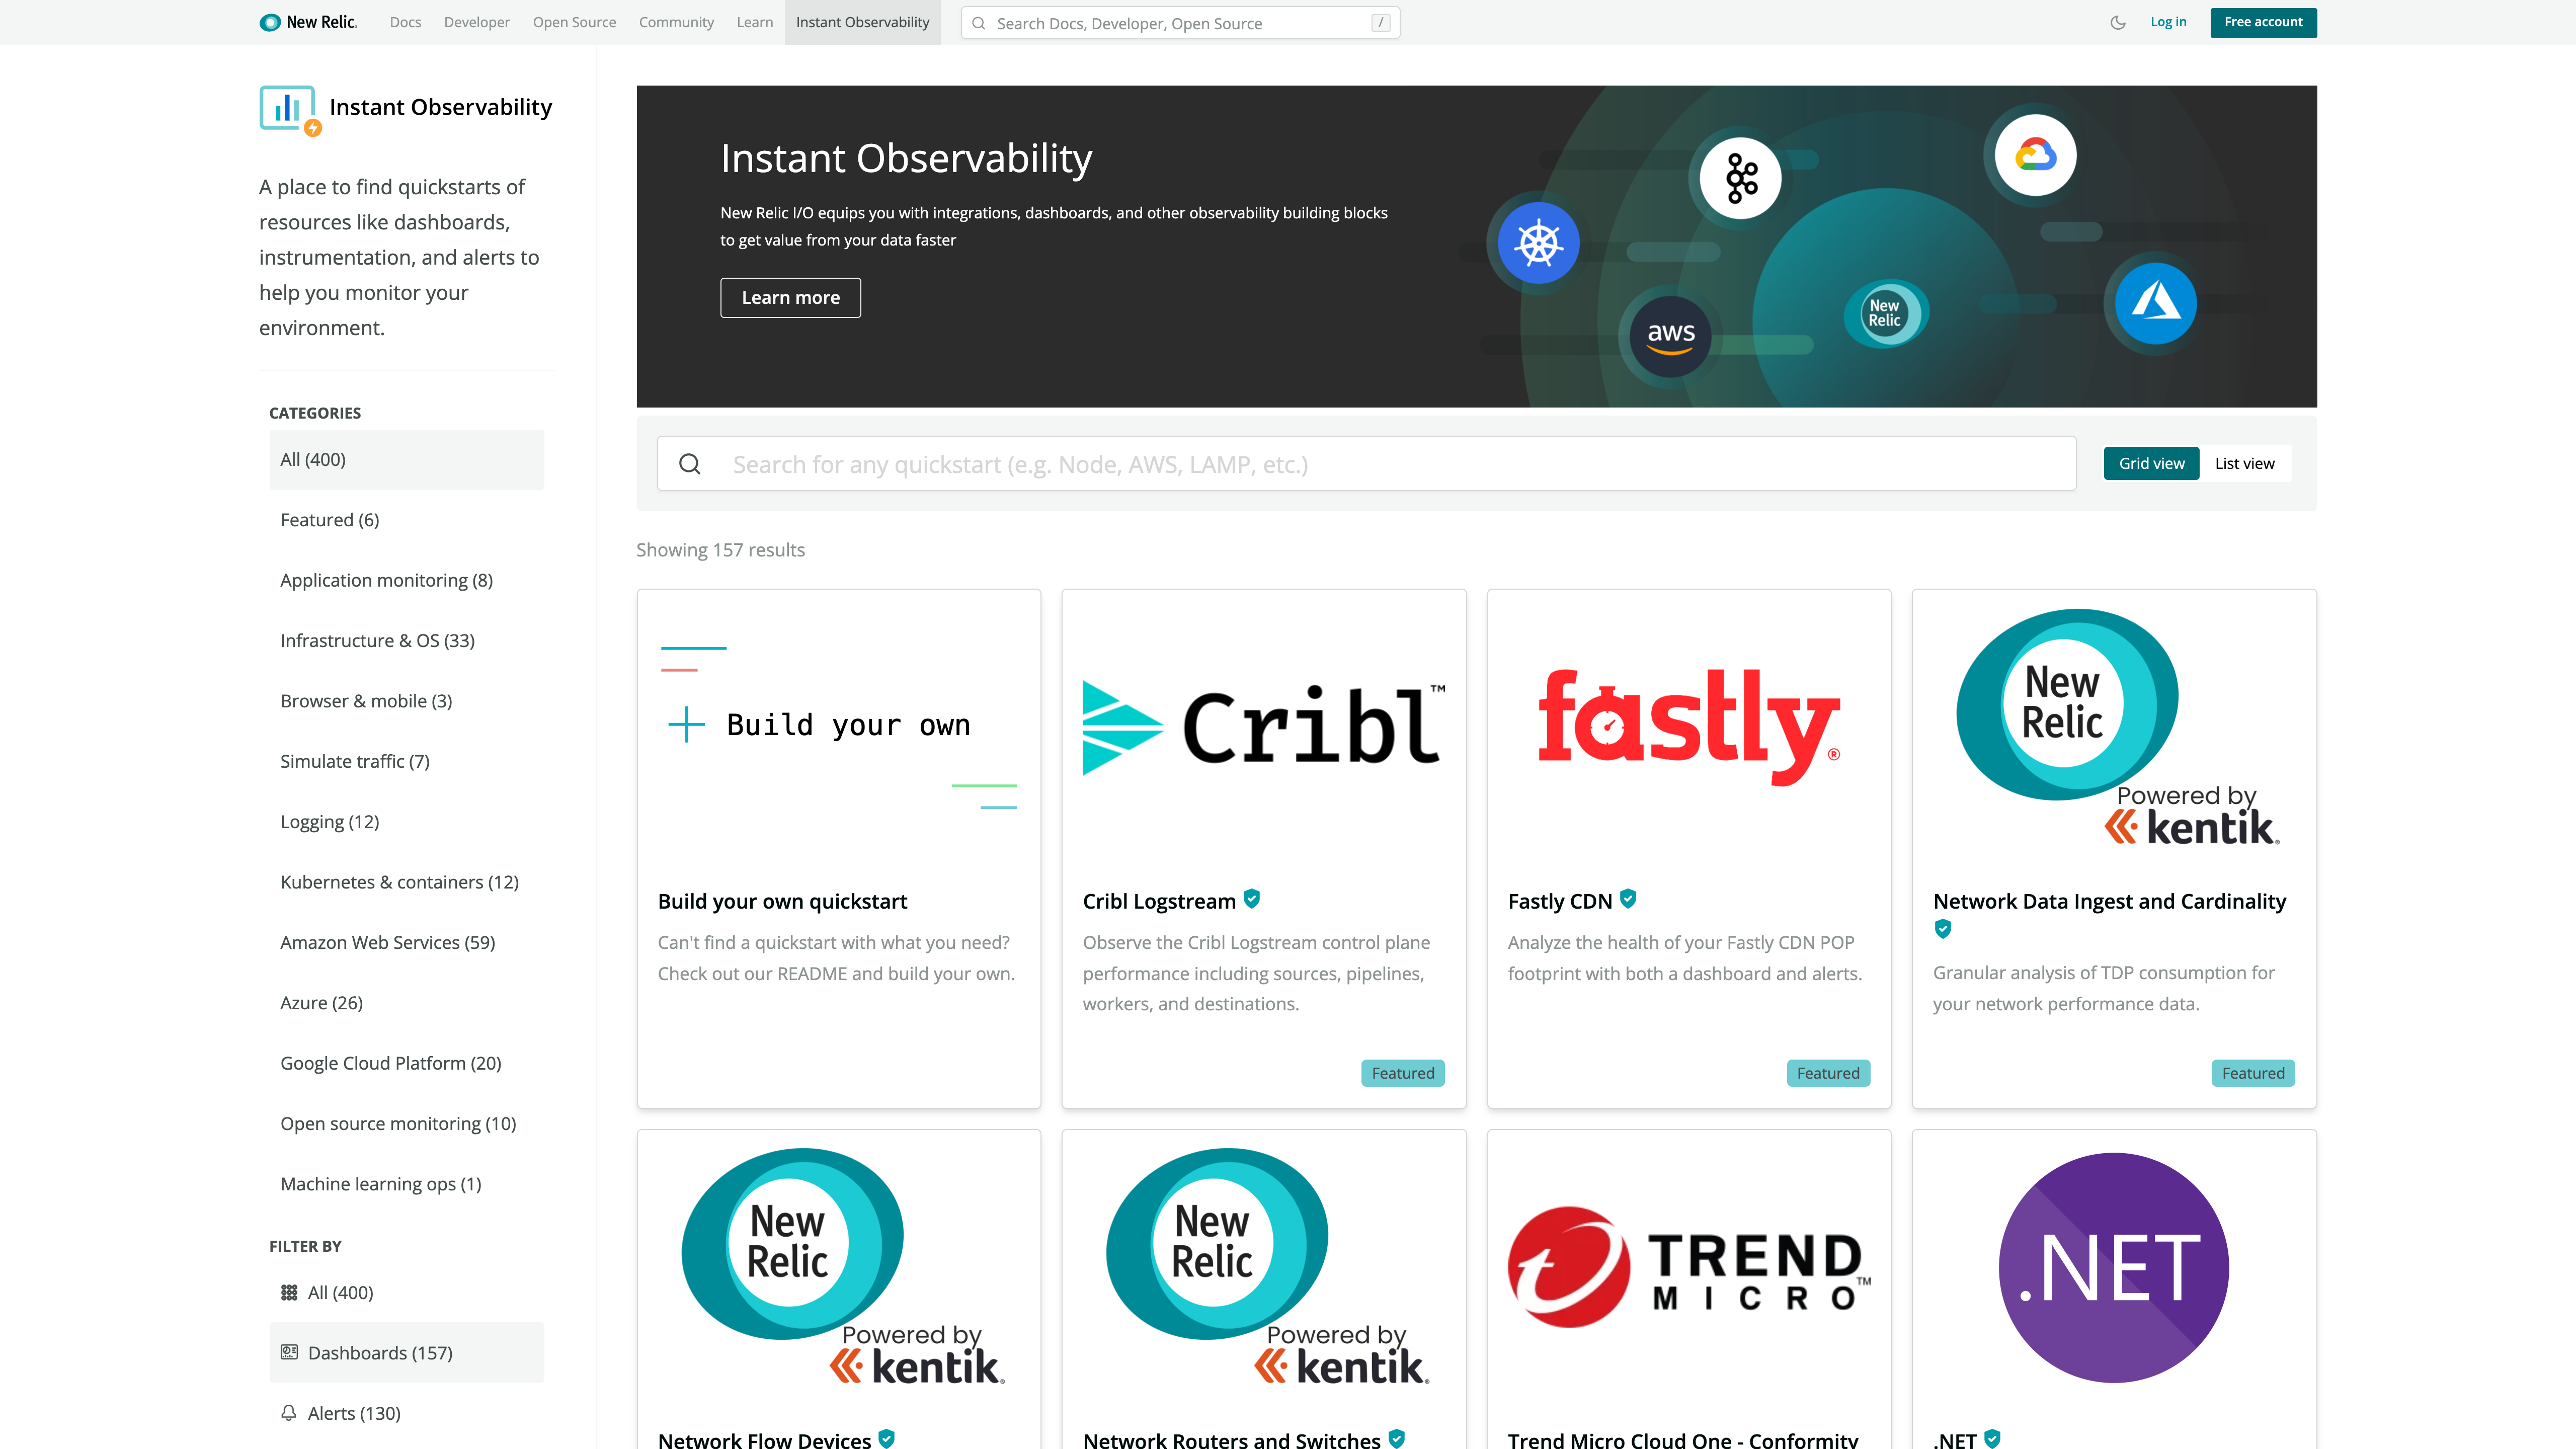
    New Relic today at the KubeCon + CloudNativeCon North America conference launched a New Relic Instant Observability (I/O) initiative through which it is making available open source tools to simplify application instrumentation.

    Marck Robinson, senior vice president for engineering at New Relic, said the catalog of tools will help DevOps teams instrument a much wider range of applications. New Relic will make those tools available as part of the free tier of its observability platform delivered via the cloud. DevOps teams will be able to use more than 400 pre-configured quickstarts to both instrument applications and create dashboards, Robinson said.

    New Relic itself is contributing quickstarts for cloud services, open source tools and platforms such as Kubernetes, Istio and Cassandra. Third-party vendors that have already contributed to the catalog include Cribl, Fastly, Gigamon, Kentik, Lacework and Trend Micro. Each contribution is being vetted by New Relic as part of an effort to foster the development of a larger open source observability ecosystem, noted Robinson.

    Robinson said overall, New Relic is trying to make it easier for DevOps teams to close an instrumentation gap that is impeding IT organizations from moving beyond monitoring to embrace true observability of their IT environments. The recent New Relic 2021 Observability Forecast report notes only a quarter of respondents (26%) have a mature observability practice, with the most commonly cited barriers to observability being a lack of resources (38%) and skills gaps (29%).

    As a result, DevOps teams often encounter a last-mile observability challenge when it comes to both instrumenting applications and then building their dashboards, said Robinson.

    As part of a larger effort to make it easier to instrument applications, New Relic has open sourced agent software, standardized on the OpenTelemetry tools being advanced under the auspices of the Cloud Native Computing Foundation (CNCF) and contributed the Pixie observability platform for Kubernetes environments to the CNCF.

    Observability in one some or another has always been a core tenet of any DevOps best practice. Initially, DevOps teams focused on continuous monitoring as the most effective way to proactively manage application environments. However, it can still take days, sometimes weeks, to discover the root cause of an issue. However, observability platforms are emerging that correlate events in a way that makes it easier for analytics tools to identify anomalous behavior indicative of a root cause of an IT issue. Armed with these insights, it becomes a lot simpler for IT teams to resolve issues faster.

    In contrast, monitoring focuses on predefined metrics to identify when a specific platform or application is performing within expectations. The metrics tracked generally focus on, for example, resource utilization. Observability, on the other hand, combines metrics, logs and traces—a specialized form of logging—to instrument applications in a way that makes it simpler to troubleshot issues without having to rely solely on a limited set of metrics that have been pre-defined to monitor a specific process.

    With the rise of microservices-based applications, the shift to the cloud and more end users than ever working remotely, the need for observability has never been more critical. The issue now is finding a way to make it much simpler to achieve.

  • Security is About People, not Technology

    Security is About People, not Technology

    Just a random thought of the day: We have the world’s best example of how many of our security woes are actually people problems, not technology problems.

    We all know that. We’ve all discussed it—but let’s consider this example and have a quick discussion about 2FA.

    Epic Games had a problem not unlike the rest of us. But it was costing them money every day, in part because of the nature of their user base. The problem? Attackers taking over the accounts of legitimate Fortnite users. In the world of gaming, scammers are rife because the player base is younger. At least since Ultima Online (1997), online games have been growing and Fortnite is at the forefront of that movement, with user counts unheard of before it became popular. That many users combined with hackers and scammers taking advantage of the younger demographic attracted to games—over 60% of Fortnite’s massive user base is under 24 years old—they do not provide a further breakdown, but there are certainly kids as young as six playing; and possibly even younger players).

    That made for a problem. Investment of time and money and energy for supporting customers having account issues was no doubt huge. I do not have an insider feeding me information, but simple math—and the evidence of steps they’ve taken—suggest that this is the case.

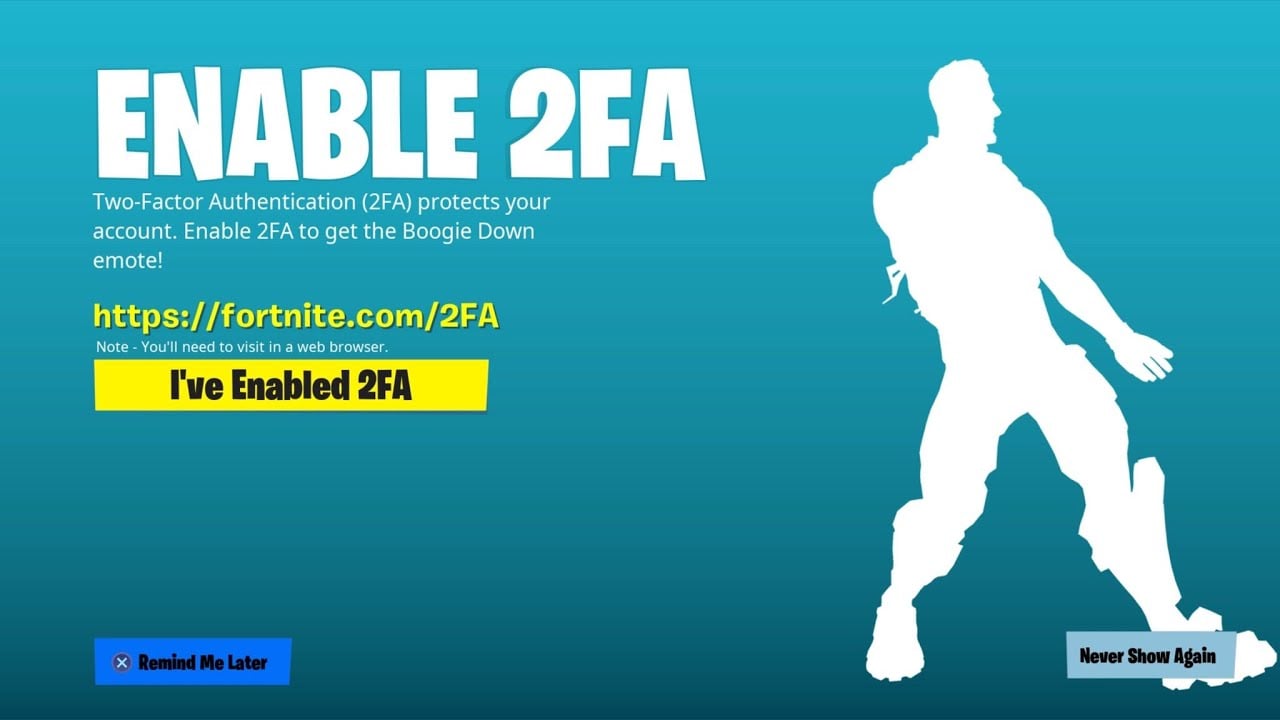
    So they did with kids what far too many of us don’t have the guts to do with our adult workforce. They implemented 2FA. While they did not require it—and, like most game companies, are tight-lipped about any kind of player statistics—they implemented it with a carrot-or-stick approach that, no doubt, has been successful. My gaming group of half a dozen all use it—because we either wanted the carrot or were avoiding the stick. It’s not really a stick. Call it carrot and wall. The carrot comes in two forms for the two most popular versions of the game: A free dance for your character (toon, if you prefer) to perform in Fortnite: Battle Royale.

    Fortnite Dance

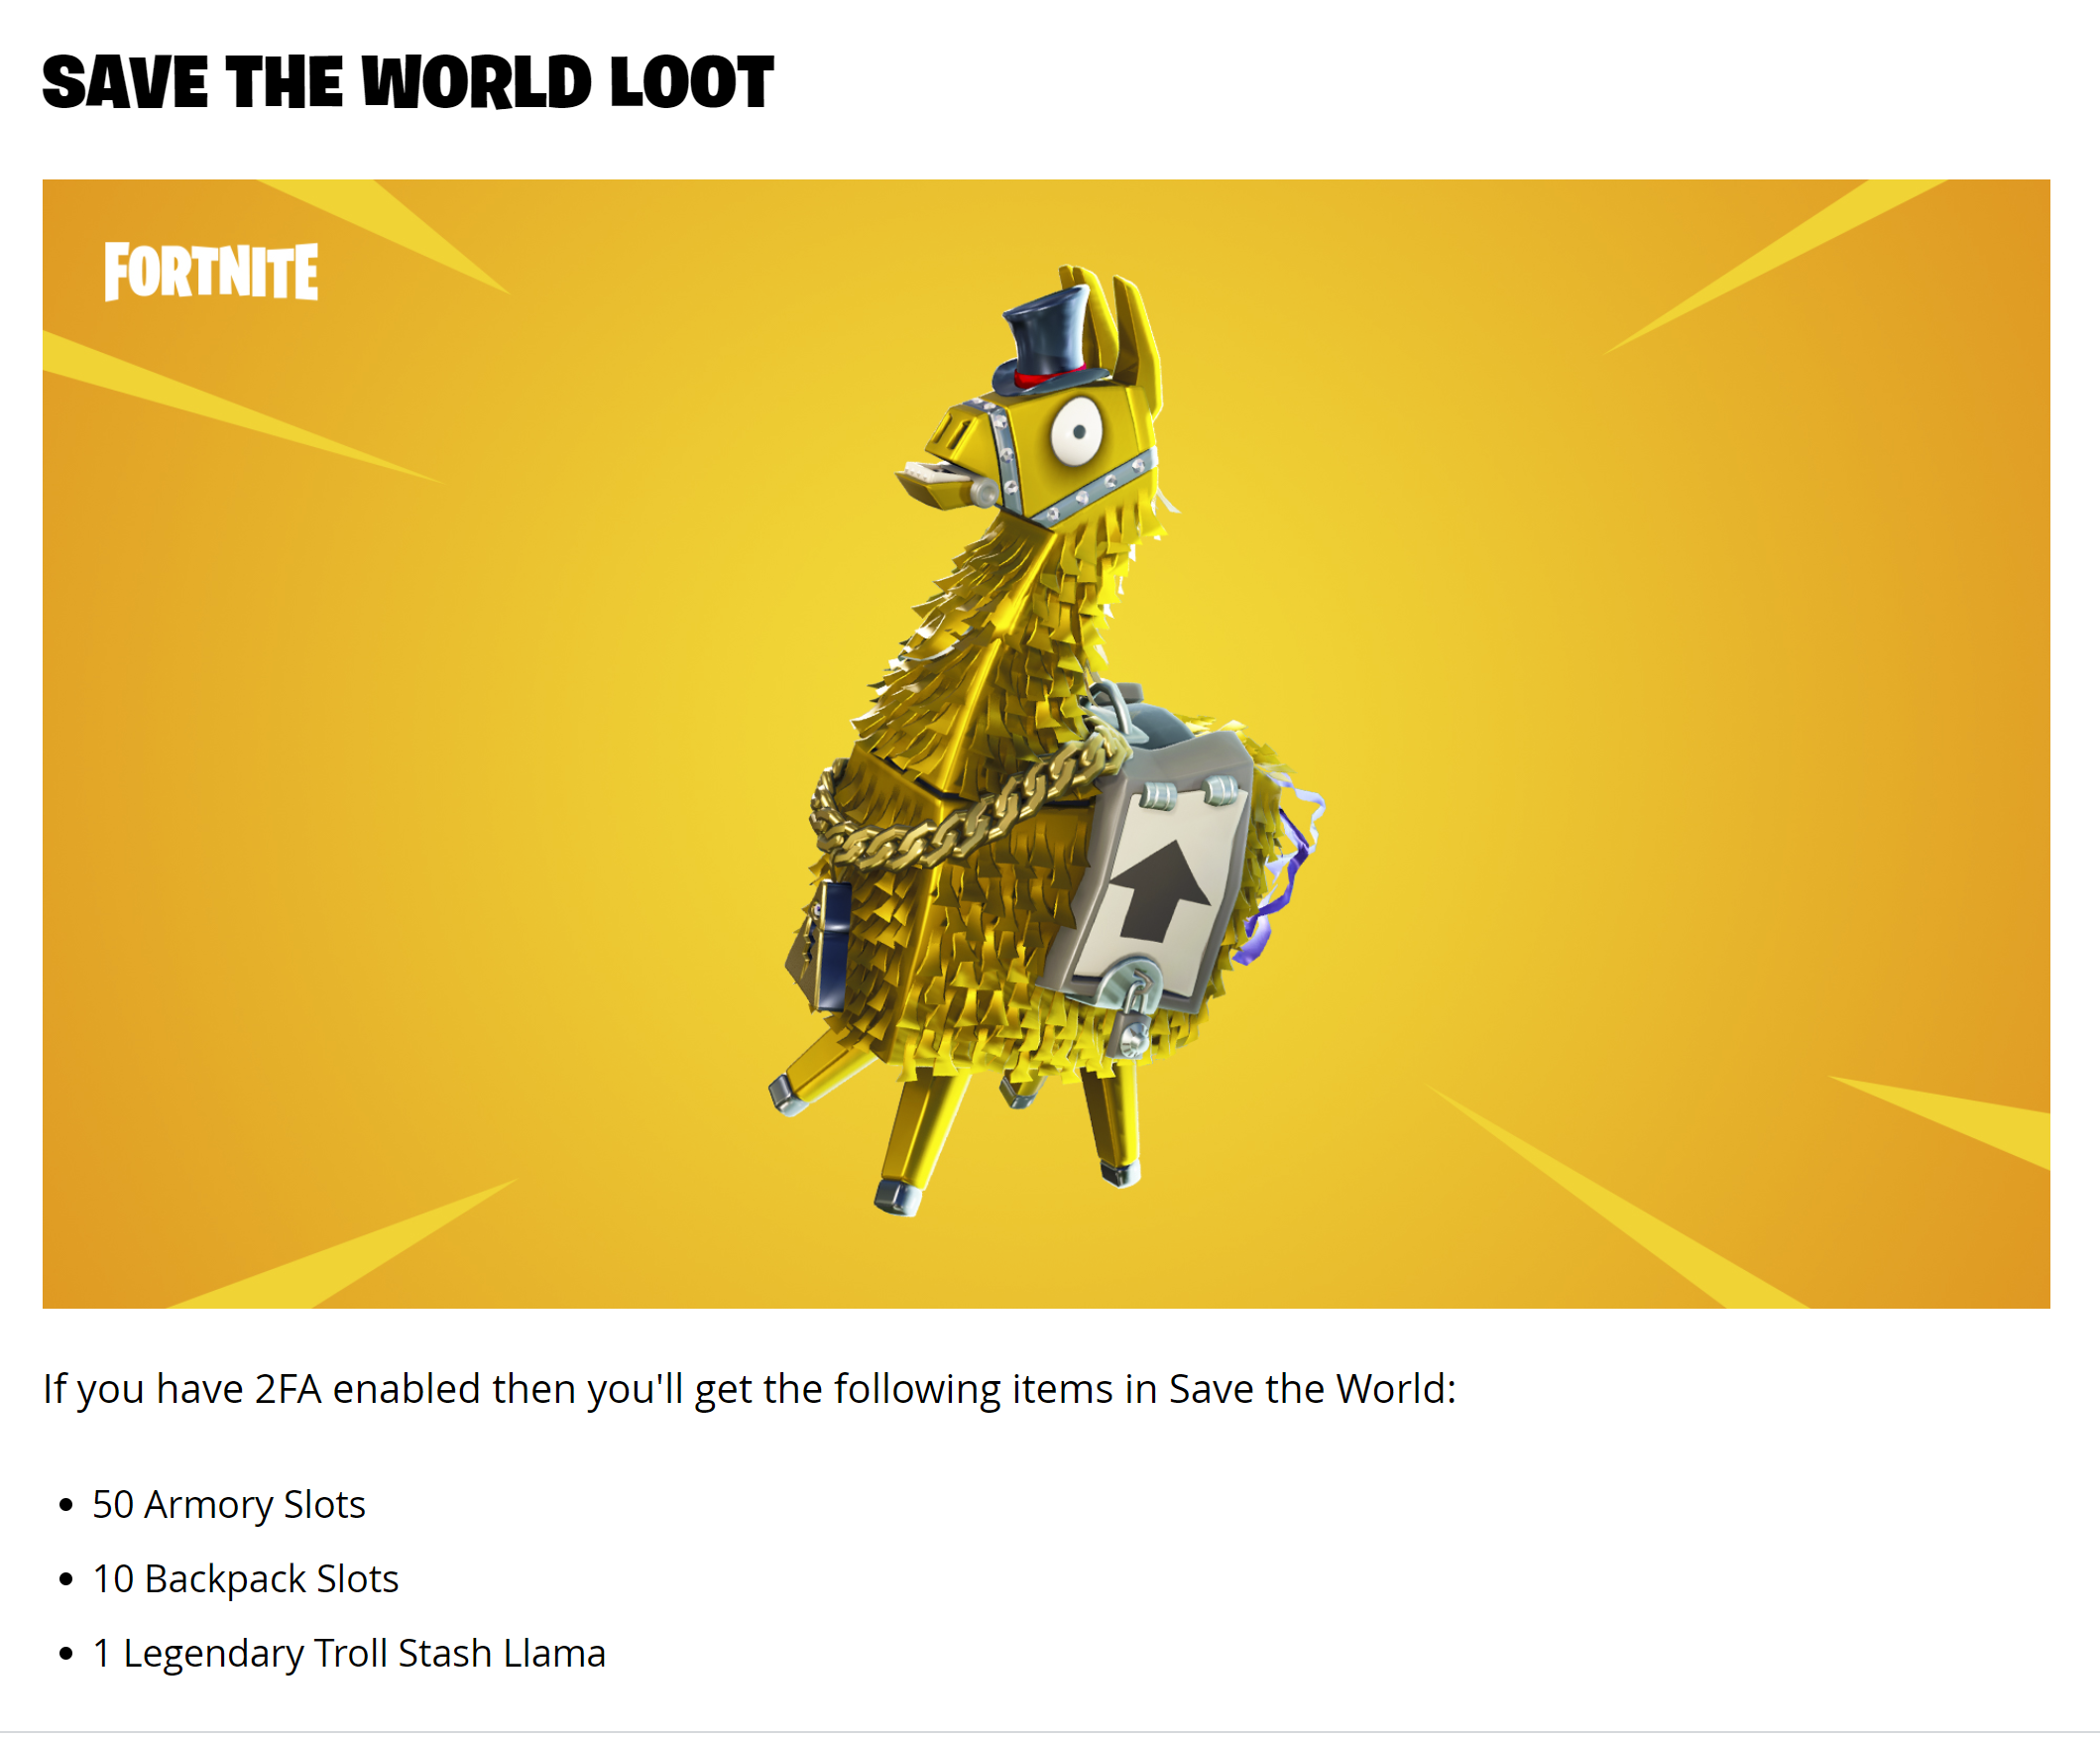
    And free gear in the paid version –  Fortnite: Save the World.

    Free gear

    For those of you who are not familiar, both of these are decent rewards; calculated by the Fortnite team to be compelling enough to warrant the steps, but not insane. The Save the World rewards are actually better in terms of usefulness, but the dance for Battle Royale is likely more popular.

    Then, they put up a wall. If you want to play competitive Fortnite, you must have 2FA turned on. It is possible that this was done to protect the sanctity of their tournaments, but it has the effect of providing the other half of the “reward and punish” equation. According to Compare Camp, 40 million players attempted to qualify for the game’s World Cup alone. So that is the minimum number of 2FA activated accounts—you cannot participate in competitive Fortnite without 2FA turned on.

    They then made turning 2FA on as easy as possible. You need to learn from this. It was harder for me to turn on 2FA and get it working for Discord than it was to turn it on and get it working for Fortnite. Strive to be as easy as Fortnite.

    At this point, we should all recognize that some form of 2FA, even the much-maligned ones like email (maligned because someone who compromises your email then has easier access to everything because 2FA is compromised), is almost essential. The cost of someone hijacking a valid user account—like the lead systems engineer or the CEO—is just too high to ignore. But some 2FA solutions are harder than others. So, we need to follow Epic Games’ lead, and make it as simple as possible, provide incentives to employees to turn it on and, if suitable, wield a stick. A minor ding on reviews until implementation is complete should be enough, if the incentives are nice. A free day off? A small bonus? You know your organization, both what management will agree to pay for and what users will find compelling.

    Get it done. The last thing you want is for your CEO to suddenly start saying/doing erratic things on corporate accounts. Unless they already do—then I suggest you consider looking for a new job. I know; there are 5,000 things to do and only a few of you. But this one is big. Don’t wait until you’ve lost accounts to turn on a pretty effective prevention mechanism.

  • The Inevitability of Multi-Cloud-Native Apps

    The Inevitability of Multi-Cloud-Native Apps

    We all know the story: Enterprises moved to the cloud. They learned about data center virtualization and multi-tenancy and self-service developer provisioning. Along came Kubernetes, and they moved to cloud-native, where they learned about automation, DevOps and infrastructure-as-code (IaC). Now, even though most enterprises are still figuring out how to do cloud-native at scale, there’s a new imperative they must master: Multi-cloud-native applications. And for almost every enterprise with a global footprint, the move to multi-cloud-native applications is not optional—it’s inevitable. 

    But before we explore why this is the case, let’s first retrace our steps. For almost every enterprise out there, the journey to the cloud started with adopting a public or private self-service infrastructure provisioning and management model. These enterprises quickly realized that this new IT model required a new set of tools to solve challenges they’d never before faced—enabling their developers with self-service provisioning, managing and operating infrastructure. Enterprises figured it out, but as soon as they figured out the cloud, they quickly had to gear up for the second phase: Automating and operationalizing an enterprise-wide rollout of cloud operating models throughout their entire developer organization. 

    Of course, this phase has its own set of challenges, and a rich ecosystem of tools emerged to address them. Even so, we all can agree that the majority of mainstream enterprises are still in this second phase. They’ve adopted cloud, they’ve expanded its use, and they’re grappling with the challenges around multi-tenancy, security, DevSecOps and governance. Hand-in-hand with this goes a whole new set of challenges around cost management. Suddenly, enterprises are faced with managing the variable costs of public cloud infrastructure: Optimizing compute infrastructure, utilization and capacity to rein in cloud spend. It’s an issue Sarah Wang and Martin Cassado took head-on in their research on the Trillion-Dollar Paradox.

    So, enterprises moved to the cloud and are now, for the most part, successfully grappling with scaling it. But nothing stays the same for long, and businesses drive IT to innovate. This is where cloud-native entered the picture to help enterprise software development teams become more agile and help businesses transform to deliver new services and experiences faster. In fact, the consumer experience this model makes possible has rapidly become the norm.

    Consistently delivering rapid software iteration across a global footprint forces DevOps organizations to grapple with an entirely new set of technical challenges: Leveraging containerized applications and microservices architectures in production across multiple Kubernetes clusters running in multiple geographies. Customers want an on-demand experience. This third phase is what we call multi-cloud-native, and it was pioneered by hyperscale IaaS players like Google, AWS, Azure and Tencent.

    The reality is, of course, that hyperscalers aren’t the only ones who have figured out how to deliver multi-cloud-native apps. Webscale innovators like Doordash, Uber, Twitter and Netflix have done it, too. To get there, they had to make and share their multi-cloud-native apps across every geography where their customers live. And, in turn, to make that happen they had to tackle a new set of challenges: Develop new tools and techniques like geographically distributed, planet-scale databases and analytics engines, application architectures that run apps on the backend close to the consumer in a multi-cloud-native way. This enabled them to do arbitrage across fleets of infrastructure capacity across regions, all while giving their customers that instant experience they increasingly grew to expect.

    What enterprises must realize is that this experience consumers have grown to expect from webscalers is rapidly becoming the same experience they expect when accessing their bank account, their insurance apps and their tax records. For almost every planet-scale enterprise, this sets up a whole new set of challenges: To span multiple clouds and multiple geographies running multiple Kubernetes clusters, you now must worry about new ways to do autoscaling, self-healing, disaster recovery, operations management and cost optimization—all of which are things that you’re just now getting figured out for virtual machines (VMs) and clusters in single regions.

    Enterprises must face the reality that cloud-native application models are not the destination but rather a waypoint on a journey to becoming multi-cloud-native. Because the consumer experiences delivered by webscalers make this the inevitable destination.

    The Enterprise Journey: Cloud, Cloud-Native and Multi-Cloud-Native

    Don’t take my word for it.

    Uber and Twitter public disclosures describe how the multi-cloud-native model is an integral part of their strategic game plan. Hybrid and multi-cloud are part of this, too, leveraging Kubernetes as a cluster manager, but they still need tools to manage all those clusters across multiple environments in multiple regions at planet scale.

    The bottom line is that the architecture that webscale companies are using today is the same one enterprises will need to adopt tomorrow to remain competitive. Alternatively, these enterprises will cede market share and relevance to the next webscale innovator to disrupt an industry. In adopting this model of building multi-cloud-native apps, enterprises will have to deal with unified access management, controlling multiple clusters, resource management and more, all across multiple regions and clusters of capacity, aggregating versus disaggregating cluster resources, using logical services that span clouds versus namespaces that span a single cluster.

    The Enterprise Solution: Planet-Scale Cluster Manager

    They will need a planet-scale cluster manager to do this; something that can observe costs, operations, performance and SLAs across clusters, across public and private clouds, spanning VMs and Kubernetes through a single pane of glass so they can operate above the clouds in an automated, easy-to-use way. Band-aid solutions like running multiple spreadsheet models to figure out how to optimize are not scalable. What’s needed are tools like machine learning to automate and optimize at scale, bin packing technology to intelligently and automatically optimize across a planet-scale infrastructure fleet and high levels of automation either with humans in or out of the loop. That’s how hyperscalers and webscalers are already doing it.

    Every planet-scale enterprise is multi-cloud-native, running data-driven apps. It’s not a fiction: It’s already happening across webscale companies, not just hyperscalers. Multi-cloud-native is the path that every enterprise is going to need to follow if they want to transform themselves to compete with the next webscale upstart. The good news is, the pioneers have left us a map to follow.


    To hear more about cloud-native topics, join the Cloud Native Computing Foundation and the cloud-native community at KubeCon+CloudNativeCon North America 2021 – October 11-15, 2021
  • LF Networking (LFN) Adds to Open Source Portfolio

    LF Networking (LFN) Adds to Open Source Portfolio

    At the online Open Networking & Edge Summit + Kubernetes on Edge Day event LF Networking (LFN), an arm of the Linux Foundation focused on networking, today added several projects that promise to make it simpler to programmatically manage networking services based on open source software.

    Walmart is contributing a L3AF project for managing network applications that make use of an extended Berkeley Packet Filter (eBPF) capability that allows applications to run in a sandbox at the microkernel level of an operating system. Intel and Aarna Networks, meanwhile, are donating the seed code from an EMCO project that provides a universal control plane to securely connect and deploy workloads across distributed computing environments that span everything from the edge to the cloud.

    Arpit Joshipura, general manager for networking, edge and internet of things (IoT) for the Linux Foundation, said the L3AF project adds a control plane for managing those applications to the LFN portfolio that addresses load balancing, rate limiting, traffic mirroring, flow exporter, packet manipulation, performance tuning and other management tasks. Earlier this year, the Linux Foundation set up a separate eBPF Foundation to further advance development and adoption of eBPF across multiple operating systems.

    At the same time, LFN also revealed today that Project Alvarium, a tool for measuring how well data is being delivered to devices that was originally created by Dell, and eKuiper, an existing open source lightweight IoT data analytics and streaming platform, are now part of the LF EDGE portfolio of projects.

    Finally, an open source mobile edge computing project, dubbed Edge Gallery, that was originally created by Huawei has been contributed to the Linux Foundation.

    Joshipura said the LFN continues to gain momentum as more vendors contribute core technologies that, ultimately, don’t provide them with enough differentiated value to continue to develop on their own. The LFN today also revealed that VMware and F5 Networks have joined the LF EDGE consortium as premier members, while mimik and Veena, Inc. have become general members of LFN and the Eclipse Foundation has become an associate member.

    The LFN also provides a mechanism that promotes adoption of those technologies more widely than any one vendor can achieve on its own. The total cost of delivering next-generation edge computing platforms based on wireless 5G networks will also be sharply reduced as LFN projects continue to mature, said Joshipura.

    In general, the rate at which various LFN projects are updated continues to accelerate, said Joshipura. The Akraino project for creating blueprints for edge computing platforms recently delivered its fifth update to address use cases involving smart cities, cloud-native multi-tenant environments and vehicular networks. An EdgeX Foundry project for IoT platforms, meanwhile, recently revamped its application programming interfaces (APIs) to make them more secure and enable more message-based communications. The Home Edge project will also soon issue a Drewberries update that will address code stabilization, scripting, APIs, data synchronization and security.

    It’s now only a matter of time before these LFN projects become more integrated with DevOps workflows as IT teams seek to give developers more programmatic control over network services. The issue now is deciding not so much whether to integrate network operations and DevOps teams but rather determining to what degree those teams will need to fold into each other.

  • Snyk Extends Tools Portfolio to Drive DevSecOps Adoption

    Snyk Extends Tools Portfolio to Drive DevSecOps Adoption

    During its online SnykCon 2021 conference this week, Snyk extended Snyk Code, a static application security testing (SAST) tool that already supports the Java, JavaScript and Python programming languages to include support for C#, Ruby, PHP and Go.

    At the same time, Snyk Open Source, a platform for remediating open source vulnerabilities, has been extended to provide native integration with Atlassian BitBucket and AWS CodePipeline platforms for driving DevOps workflows. Snyk has also tightened integrations with platforms from DigitalOcean and HashiCorp.

    Snyk also added support for the Elixir programming language and package managers Yarn 2 and Poetry alongside integration with a C++ scanning tool from FossilID, a provider of a software composition analysis (SCA) tool for open source code that Snyk acquired earlier this year.

    The Snyk Container platform is now integrated with the open source Trivy container scanning tools and with Snyk’s vulnerability database in addition to adding support for container registries such as Quay, GitHub Container Registry, GitLab, Google Artifact Registry and Harbor.

    The Snyk infrastructure-as-code platform now also makes it possible to detect configuration issues in Kubernetes manifests in Terraform code in a way that is compatible with cloud platforms from Amazon Web Services (AWS), Microsoft Azure and Google Cloud Platform (GCP).

    Snyk also is adding support for version 3 of OpenAPI, which the company reports is three times faster than the previous version. That API is also the foundation for Snyk Apps that the company will continue to roll out.

    Finally, Snyk launched both a new free developer security education program, dubbed Snyk Learn, through which developers can attain and measure their level of DevSecOps expertise and Snyk Impact, an effort to foster collaboration among developers involving a wide range of socio-economic issues.

    Company president Guy Podjamy said as DevsecOps continues to evolve, the primary focus remains on developers and DevOps teams. However, as an issue, DevSecOps is also becoming more important at both the C-level within organizations as well as individual security operations teams. As such, and in the wake of recent high-profile security breaches, the sense of urgency surrounding DevSecOps is now a lot higher. The fundamental challenge organizations are trying to address is finding a way to improve overall application security without slowing down the pace at which applications are built, noted Podjamy.

    Snyk itself revealed it has secured an additional $530 million round of funding to address those issues. The company has now raised a total of $775 million to date with a valuation of $8.5 billion. Snyk also revealed it has increased annual recurring revenue (ARR) by 154% year-over-year from a customer base that now spans more than 1,200 organizations, including Asurion, Google, Intuit, MongoDB, New Relic, Revolut and Salesforce. Snyk customers and users collectively have run more than 300 million tests in the last 12 months to fix more than 30 million vulnerabilities in a 90-day period of time, the company claims.

    It may be a while before most organizations have embedded security tools within every DevOps workflow. However, given the resources being poured into DevSecOps, it may be more a question when DevSecOps will be finally achieved rather than if.

  • BMC Acquires StreamWeaver to Advance AIOps Strategy

    BMC Acquires StreamWeaver to Advance AIOps Strategy

    BMC has acquired StreamWeaver, a provider of a platform that makes it simpler to capture streaming data in real-time, as part of an effort to extend the BMC Helix IT operations platform infused with artificial intelligence (AIOps). Financial terms of the transaction were not disclosed.

    Margaret Lee, general manager and senior vice president for digital service and operations management for BMC, said StreamWeaver brings with it a wide range of integrations with multiple data sources that BMC will use to both train AI models and improve overall observability. While connecting to data sources is relatively straightforward, the challenge now is collecting that data in real-time in a way that is easily repeatable for IT operations teams, noted Lee.

    In general, AIOps continues to gain traction as IT environments become increasingly complex. Most IT operations teams are not going to be able to manage highly distributed computing environments without augmenting their IT staff with some AI, said Lee.

    Naturally, many rote tasks that were once performed manually by IT operations professionals will become increasingly automated. However, there will always be a need for IT personnel, noted Lee.

    Arguably, there may come a day when IT professionals will not want to work for organizations that don’t have an AIOps platform in place simply because the tasks assigned to them would otherwise be considered archaic, especially if they involve a series of tedious tasks that not many IT professionals really want to perform.

    At the same time, AIOps should reduce overall risk by making it easier for IT operations teams to proactively identify issues before they disrupt an application service. That’s especially critical as IT environments—increasingly with microservices-based applications constructed using containers—and serverless computing frameworks are being deployed with greater frequency alongside legacy monolithic applications.

    BMC has been making a case for AIOps as far back as 2017. However, since then, a wave of startups and IT operations incumbents have either built an AIOps platform from the ground up or updated an existing platform with AI capabilities. It’s difficult to assess which vendors are now ahead in terms of the AIOps race, but one thing that is certain is that IT organizations now have plenty of options.

    From a cultural perspective, however, not every organization is entirely comfortable with AIOps. While some IT professionals remain skeptical, others view AI as an existential threat to their existence. Most IT teams are also concerned about the potential impact any flawed AI model might have on IT operations—it’s one thing for a human to make a mistake, but an AI model making a mistake at scale could be catastrophic.

    There are few IT organizations that are embracing AIOps across the board, but most do recognize that AIOps platforms, in one form or another, are inevitably here to stay. After all, machine learning algorithms never forget anything they learn. Nor do they ever take a day off or decide to leave when offered higher pay. The challenge is figuring out exactly where the interface between IT staff and algorithms is going to be—not just today, but also in the near future.

  • Verica Launches Database for Sharing IT Incident Reports

    Verica Launches Database for Sharing IT Incident Reports

    Verica, a provider of an incident management platform, announced this week it is making available a database to make incident reports publicly available via a single repository.

    Courtney Nash, senior research analyst at Verica, said the Verica Open Incident Database (VOID) initiative is part of an effort to enable organizations to learn from outages and failures caused by software. Today, reports about such incidents tend to be difficult to find because they are scattered all across the internet, she added.

    That lack of transparency makes it difficult to compare and contrast incidents in a way that surfaces meaningful insights, noted Nash.

    Launch partners for the VOID include Indeed, NS1, Adaptive Capacity Labs, Security Scorecard and Auxon. Each will provide support to help fund the development, research and dissemination of knowledge generated by the project.

    The VOID contains more than just standard company postmortems or status updates, added Nash. Verica is committed to applying metadata to better understand how individuals, companies, media and others reacted during an incident.

    One early finding already derived from this initiative is that mean-time-to-resolve (MTTR) is proving to be an inaccurate metric due to the varied distribution of incident data. Other findings include the fact that only one-quarter of incident reports took the time to identify the root cause of an issue, while less than 1% took the time to study incident reports of near-misses.

    In general, there’s now more riding on the performance and availability of IT environments than ever. Digital business transformation became all the rage in the wake of the economic downturn brought on by the COVD-19 pandemic. As the economy continues to recover, businesses now expect IT to respond and pivot to changing conditions no matter how sudden.

    DevOps teams have, of course, learned to expect the unexpected by embracing modern incident management based on DevOps best practices that enable IT teams to adroitly respond to any outage or sudden degradation in application performance. The most important thing to remember about incident management is that practice makes perfect. While practice runs may never precisely mirror an actual crisis, organizations that have processes that are well-known by their IT incident teams and that practice ‘fire drills’ tend to respond both faster and better. After all, the more muscle memory there is to call on the more resilient the organization will be.

    It’s not clear to what degree IT organizations will be willing to share incident reports. However, there is an opportunity for IT professionals to come together that is similar to how engineers from different airlines collaborated to make flying safer for the general public, said Nash. In fact, with so many processes now dependent on software, it’s amazing there have not been more catastrophic events due to software issues. It’s even arguable that it’s only a matter of time before such levels of collaboration are mandated.

    In the meantime, the first step toward achieving that goal may simply be sharing a report with colleagues so they can learn from previous mistakes.

  • Perforce Charts Testing Course After BlazeMeter Acquisition

    Perforce Charts Testing Course After BlazeMeter Acquisition

    Perforce Software has acquired BlazeMeter from Broadcom as part of an effort to extend the scope of its testing tools beyond the Perfecto tools for testing mobile and web applications it acquired in 2018.

    Broadcom gained control over BlazeMeter after it acquired CA Technologies in 2018. CA Technologies acquired BlazeMeter in 2016. Terms of the latest acquisition involving BlazeMeter were not disclosed.

    Tim Russell, chief product officer for Perforce, said BlazeMeter adds a complete platform that spans everything from load and performance testing to application programming interface (API) testing. The goal is to enable DevOps teams to push continuous testing further left as part of an effort to accelerate the development and deployment of applications, added Russell.

    The need for continuous testing has become more pronounced as more organizations launch multiple digital business transformation initiatives, noted Russell. The real challenge will be finding ways to embed continuous testing within DevOps processes at a sufficient level of scale, added Russell.

    In fact, the quality of the digital experience those applications provide ultimately determines the degree to which those efforts are likely to succeed, which Russell noted is why so many enterprise IT organizations are reengineering their application testing processes.

    In general, organizations are taking two paths to shift testing further left. Some are giving application performance testing tools to developers to employ during DevOps sprints while others are trying to bring application testers into the application development process earlier. In some cases, organizations are doing both as part of a comprehensive effort to discover issues before applications are deployed in a production environment. Those issue are naturally more expensive to fix after an application has been deployed.

    Perforce, for now, expects to continue to make BlazeMeter and Perfecto available as a set of complementary cloud-based services with some cross-pollination of capabilities occurring over time, said Russell.

    In the longer term, it’s apparent that more artificial intelligence (AI)-based analytics will be embedded within cloud-based platforms that can collect enough data to build meaningful models of development processes. IT teams should also expect to see testing tools make greater use of computer vision algorithms to surface issues.

    One away or another, the entire application testing process is about to become a lot more automated as more organizations are simultaneously building multiple applications. That may not necessarily reduce the need for either a developer or tester to create and manage that process, but it does mean the amount of testing time required for each application should continue to steadily decline in the months and years ahead.

    Hopefully, all that effort will lead to better application experiences being provided to end users more consistently. There is nothing quite as frustrating for any application development team than to discover that 90% of the functionality of an application is not being used because end users are not able to easily surface it. Worse yet, of course, is when an application turns out to be too slow once it is deployed. In either case, it’s difficult to regain that initial end-user enthusiasm for any new application experience after it’s been lost, simply because no one thought through all the use cases that should have been tested much earlier in the application development life cycle.

  • 4 Container Orchestration Security Concerns

    4 Container Orchestration Security Concerns

    Container orchestration is a must-have technical skill, according to 51% of respondents to the 2021 Upskilling survey from DevOps Institute. So, it’s no surprise, then, that container technology is becoming increasingly popular. However, container environments are far more complex and dynamic than other infrastructure, making container security essential. Security ensures containers are running as intended, protecting the infrastructure, software supply chain, runtime and everything in between. 

    If you’re looking to use container-based applications within your software infrastructure, you may want to keep in mind the security risks that come with this technology. To help, I asked DevOps Institute Ambassadors to weigh in on the security concerns they have with container orchestration. Here’s what they shared: 

    Anshul Lalit, head of technology and transformation, Kongsberg Digital

    “One of the most common security concerns with container orchestration is that it shares the host operating system and the host kernel. Thus, it raises the concern that a host OS or kernel vulnerability could potentially be taken advantage of and exploited in a container. An example of this is the recent attacks on Linux’s mmap syscall. Though you can avoid this by using defined best practices, it’s worth noting that any compromise in the host OS could compromise containers in that host. This scenario is in contrast to a virtual machine (VM), in which the guest OS and the host OS and kernel share no common binaries and are thus inherently separated.

    Similarly, a rogue process, a vulnerable container image that is running, and a security vulnerability in the orchestrator can all provide an attacker a means to get their foot in the door. For example, if a container is designed to run with root privileges, an attacker running a vulnerability scanner on the orchestration host will quickly find the vulnerable container.

    Users should follow best practices for securing the containers running in a container orchestration platform by providing a Linux security module, for example, that can enforce a policy that will protect against a rogue container or user from extracting sensitive data from the host system.”

    Supratip Banerjee, solutions architect, Principal Global Services

    “Containers are creating new challenges for cloud security. While these structures are dynamic and automated, new threat vectors are also present for precisely the same reasons containers are useful. DevOps and SecOps teams must be aware and prepared for these possible issues:

    • Containers, unlike virtual machines, share the host operating system on which they execute. If settings are not correctly maintained, the host and containers may be exposed to security concerns.
    • Orchestration automation adds a degree of complexity which can lead to misconfigurations that overprovision access and, as a result, an expanded attack surface.
    • Containers are constructed using pictures kept in public or private repositories; they are frequently reliant on other images, and a single flaw in any of them might spread across thousands of containers.
    • Because containers are ephemeral, IP address-based security measures are ineffective and complicate forensic investigations.”

    Parveen Arora, co-founder and director, VVnT SeQuor

    “If your project(s) involves the use of containers, you will have decomposed your application into its various constituent services, which, while beneficial, isn’t necessarily as secure as if you are using VMs. Since container platforms like Docker borrow code libraries from the host, they’re fundamentally not as secure as VMs. Vulnerabilities in a container environment can therefore allow malicious software to break out of a container and infect the host environment.”

    Vishnu Vasudevan, head of product engineering and development, Opsera

    “The security challenge, especially when it comes to container orchestration, is people think they can spin up their own image or they can download the image from the cloud and start using it. It’s not as easy as everybody thinks. There are vulnerabilities being introduced every minute. You need to have a security tool and processes that can automatically scan for every container that is being splintered. Furthermore, a team needs to create shared practices around blue-green deployments or rollbacks of the container changes that are being pushed into production. 

    From the pandemic alone, we have seen significant cloud movement, but on average, 50 vulnerabilities are introduced every day. In fact, there are people just waiting for loopholes where they can execute malicious scripts. And some people, especially people who are in mining, try to gain visibility into vulnerabilities within cloud accounts and penetrate them to run huge containers for their own cloud mining purposes. On average, it can take 280 days to even detect any vulnerabilities or a hack into the system. 

    Companies using containers must consider threat vulnerability management as part of their orchestration strategy. Do you think the team is experienced enough to scan 50 vulnerabilities a day and fix them? Probably not, since release velocity is shortening a release cycle to one or two weeks for modern application initiatives. This creates a lot of technical debt that can accumulate rapidly, which is why threat vulnerability tactics and processes must be considered when moving to the cloud.”

    Learn more about container orchestration and similar topics by registering for an upcoming SKILup Day. 

  • Welcome to Techstrong Group

    Welcome to Techstrong Group

    Today is a big day in the neighborhood. What neighborhood, you ask? If you are involved in DevOps, cloud-native, cybersecurity or digital transformation, you are in that neighborhood. Today we launch Techstrong Group. Techstrong Group is a combination of all the companies I have been involved in within this neighborhood. It represents the greatest breadth of brands, services, content and tools to help those in our neighborhood. It is the power source for people and technology.

    The combination of MediaOps—the people behind DevOps.com, Security Boulevard, Container Journal, Techstrong TV and more—along with the DevOps Institute, Accelerated Strategies Group and Prospera Events makes Techstrong Group the most comprehensive provider of thought leadership and information to people and companies in our field.

    Techstrong Group also represents the coming together of everything I have worked on over the last eight years. When I launched DevOps.com back in 2013, I knew we were at a pivotal point in technology adoption. The internet had changed the world, but another transformation was coming. This digital transformation didn’t start with the COVID-19 pandemic, but it illuminated the fact that if you weren’t transforming digitally, it would be difficult—if not impossible—to thrive in this new normal.

    This belief that DevOps would be a catalyst in changing the world was shared with me by Jayne Groll, one of my co-founders at DevOps Institute and now my co-founder at Techstrong Group. Over the last six or seven years, Jayne has worked tirelessly to help the “Humans of DevOps” and now will continue that mission as Chief Strategy Officer at Techstrong Group.

    Along the way, I have had a chance to meet and work with some tremendous people. My longtime friend Mitchell Ashley, who was a co-founder at StillSecure with me (along with Rajat Bhargava, who founded StillSecure), founded Accelerated Strategies Group. He is now CTO of Techstrong Group, as well as principal at Techstrong Research, which is where the Accelerated Strategies Group business will operate (more about that in a moment).

    Sean Lowery, another friend who founded and runs Prospera Events, the people behind the InnoTech conferences for more than a dozen years, has also joined Techstrong Group, in our Techstrong Live events business unit. We are excited to have Sean and the whole Prospera team as part of Techstrong Group and officially welcome them to the family.

    I would be remiss if I didn’t mention some other important people in the Techstrong Group team. Parker Yates, our Chief Revenue Officer, has been in this adventure with me since day one. Andre Pino, who joined us from CloudBees, heads up our marketing and operations team as Chief Marketing Officer. He is assisted by Heidi Gilmore who as VP of Marketing has really cranked up our marketing efforts. Charlene O’Hanlon, who started with me at MediaOps more than five years ago as a contract editor, is now Chief Content Officer. Marc Halcrow, who has helped Jayne make DevOps Institute the market leader it is, is now our SVP of Corporate Development and Strategic Partnerships. Finally, our newest executive member, Jason Baum, heads up our Techstrong Association and membership efforts.

    Of course, these are just the executive team members. Techstrong Group is more than 50 people strong with dozens of other contributors. We are grateful for every one of them, who have made what we do possible.

    But none of this would be possible without you. We believe we serve today’s “Masters of the Universe,” the people who are making our digital world possible. The worlds of DevOps, cloud-native, cybersecurity, which are all part of digital transformation, are remaking the world before our eyes. We know you; we believe we know what you want and how we can help.

    It is critical for technology professionals at all levels to understand how technology can improve business processes, revenue, profitability and customer satisfaction. Techstrong Group’s goal is to create a place where technology leaders and practitioners gather to exchange ideas and continually learn, grow and succeed.

    To help with this mission, we have organized into several distinct business units:

    •     Techstrong Media: The business unit with most of the existing MediaOps brands—DevOps.com, Container Journal, Security Boulevard and Techstrong TV.
    •     Techstrong Associations: The business unit comprised of DevOps Institute and the Humans of DevOps association.
    •     Techstrong Research: Our analyst and research business, which includes Accelerated Strategies Group.
    •     Techstrong Live: Our events-focused business unit, which produces both in-person and virtual events.
    •     Techstrong Education: You will be hearing more about Techstrong Education in the coming weeks and months.

    Over the coming weeks and months, you will see more of the full Techstrong Group vision roll out. I hope you find it compelling and will entrust us with the greatest gift you can give: your time. We value you and your time; we know our mission and will continue to try and make sure we live up to our tagline, “The power source for people and technology.”

    So, welcome to Techstrong Group. We don’t view today as the culmination of our story; rather, it is the end of our prologue. Now the true adventure begins. Strap in: The world is an exciting place right now and we want to help you get the most out of it.