Category: Features

  • GraphQL’s Greatest Strength is Also its Greatest Weakness

    GraphQL’s Greatest Strength is Also its Greatest Weakness

    Michael Scott: Why don’t I tell you what my greatest weaknesses are? I work too hard, I care too much and sometimes I can be too invested in my job.
    David Wallace: Okay. And your strengths?
    Michael Scott: Well, my weaknesses are actually strengths.
    David Wallace: Oh. Yes. Very good.

    GraphQL is a new query language that offers a simple way to interact with structured data. The best thing about GraphQL’s design is its convenient data fetching process which enables the requesting party to collect limitless data and perform multiple actions, all with a single API call. This interaction method makes it super useful and very easy to use. However, from a security perspective, its greatest strength could also be its greatest weakness.

    I recently met with Elad Koren, chief product officer, Salt Security, to understand the nuances of GraphQL security. According to Koren, GraphQL affords better usability than REST APIs, yet its bundled request model may compromise systems that don’t employ proper object-level authorization checks. Also, since developers interact with GraphQL services differently than typical web APIs, hackers could avoid detection by typical firewalls, requiring a new approach to security.

    These concerns aren’t dealbreakers for adoption; rather they are a reality check for those using GraphQL in production. Below, we’ll explore some potential weaknesses and look at some general mitigations that providers can take to improve the confidentiality of their GraphQL endpoints.

    What is GraphQL?

    GraphQL was initially developed by Facebook and open sourced in 2015. It’s a query language that makes data retrieval and manipulation with external sources very easy. Instead of programming and linking together complex calls with traditional HTTP API requests, GraphQL enables a client to bundle queries into a single request. This design pattern reduces the under- and over-fetching pattern that REST APIs typically suffer from.

    “You get exactly what you need, not more or less,” described Koren. This makes GraphQL a popular choice for modern database mechanics over REST, as it’s similar to SQL querying.

    Adoption of GraphQL is steadily growing; a 2020 RapidAPI survey found GraphQL usage had quadrupled. GraphQL is now used by 22.5% of API developers. But when it comes to overall API design patterns, REST is still the dominant architectural style used by 93.4% of APIs, found Postman’s 2020 State of API Report.

    GraphQL is promising and has a number of benefits, but remains in an early adoption phase. “It’s still a technology that early adopters are starting to look into—it’s not so widespread,” said Koren. Due to its age, GraphQL security practices are immature, exposing a few potential vulnerabilities for platforms that use GraphQL.

    Unique Security Concerns

    So, what are some unique security concerns in the GraphQL paradigm? Well, according to Koren, it begins with a lack of understanding. “Security is not necessarily top-of-mind most of the time,” he said. “When developers choose to implement GraphQL, they assume that they’re not using APIs anymore and that traditional REST API vulnerabilities do not apply.”

    In fact, the opposite may be true. GraphQL APIs can easily suffer from broken object-level authorization, OWASP’s number-one API vulnerability, just as REST APIs do. But, with greater ease of access to many underlying systems, a single GraphQL query could exfiltrate much more information than a typical API request. If the GraphQL provider does not have granular authorization checks for each particular method and resource, a GraphQL endpoint could suffer from data overexposure.

    Another issue concerns spotting malicious behavior. Typically, when hackers perform reconnaissance on an API, they brute-force it with many requests; trying different namespaces and changing user agents in the process. With REST APIs, this sort of malicious behavior is easier to catch with standard web application firewalls (WAFs) since it’s easier to notice hundreds of peculiar malformed requests. However, with GraphQL, a hacker conducting query batching could completely fly under the radar of typical thresholds.

    This could easily lead to an account takeover, said Koren, who has seen this in production. He described a production payment service that used GraphQL; callers could perform mutations and capabilities they shouldn’t have been allowed to perform, such as pulling up other users’ account information and even initiating transactions.

    It’s easier to limit this type of nefarious traffic with REST APIs by assigning access parameters to each resource and handling authorization checks once at a time. But, this playbook is thrown out the door in GraphQL. “When you’re using a single point to access the data, you may have some false sense of security,” said Koren. In practice, having a single access point requires hard work to retain its integrity. A usable GraphQL frontend may also often mask a convoluted backend made of disparate API styles, Koren explained, making it much harder to correlate user authorizations to specific resources and mutations across various microservices.

    Tips to Mitigate Weaknesses

    So, with these weaknesses in mind, how should GraphQL-based platforms respond? Koren provided the following advice to protect GraphQL APIs:

    • Adopt a security mindset in development: It’s vital to start with a security culture from the beginning. Usability shouldn’t compromise security; ideally, they should complement each other.
    • Ensure proper authorization checks are in place: Whenever an asset is provided to the user, you need to consider whether the user is authorized to access it—especially if they are hitting multiple resources at once.
    • Set a new baseline specific to GraphQL: GraphQL owners need to adapt their perimeter security systems to look for new queues. These validations should consider typical REST API security checks and nuanced thresholds that consider nested queries and batch queries.
    • Know your API inventory: Maintain a clear picture of the underlying architecture of what is beneath the GraphQL endpoint. Verify the data sources and ensure they correctly correspond to user privileges.
    • Increase visibility into API calls: If possible, increase your visibility into queries, mutations, attributes, variables and underlying specifications and how they interact with each other.

    Strengthening GraphQL Endpoints

    API attacks are rapidly increasing. Gartner estimates APIs will become a top threat vector in 2022, and Salt Labs data showcased a shocking 300% growth in malicious API traffic in mid-2021.

    “Like any other innovative tech that comes into the mainstream, it will rise in popularity, but it will not surpass REST in the foreseeable future,” says Koren. Perhaps in three to four years, GraphQL’s current 20% adoption rate will rise to 30% to 50%. While GraphQL is still a relatively niche tool, its use is growing, especially among API-first cloud-native tech companies. And with this adoption will come novel security concerns.

    According to Koren, query batching makes catching malicious attacks using ordinary firewalls tricky. Thus, training a new baseline to discover anomalies unique to GraphQL will be necessary to find and limit hackers while they are still in the reconnaissance phase. Thus, we’ll likely see future security investment go into spotting these atypical GraphQL interactions.

    In general, perhaps the best advice is to treat GraphQL with the same level of intensity you would with any other type of API—if not more. As a single doorway to many underlying systems, GraphQL requires added security forethought and careful application of user authorization.

    With that squared away, hopefully, GraphQL’s greatest strength will remain just that—a great strength.

  • FinOps 101: Demystifying Cloud Financial Operations for DevOps

    FinOps 101: Demystifying Cloud Financial Operations for DevOps

    In an ideal world, all organizations would have a dedicated FinOps team—or at least a single specialist who could work to ensure that the cloud was operating in a financially savvy way. Of course, in reality, most organizations are strapped for skills and are operating lean teams where responsibilities are spread thickly across employees. In that case, DevOps professionals are likely to get left holding the FinOps bag and tasked with implementing FinOps best practices into their everyday cloud operations. If that sounds familiar—here’s your guide to getting started.

    The Cultural Shift of Considering FinOps

    In many ways, it’s not that great a leap for DevOps to start thinking about FinOps. After all, the underlying goals of both strategies are to optimize, improve and streamline operations. The difference is that DevOps is focused on software development and technical skills, while FinOps looks at the financial costs of operating on the cloud.

    The biggest challenge is that sometimes these goals may be at odds with each other. If DevOps teams are tasked with getting new software releases and fixes out of the gate as quickly as possible, that can often come at the expense of the most cost-effective solution. Think, for example, about AWS on-demand instances in the cloud. It’s arguably more FinOps-friendly to look for reserved instances, savings plans and committed use discounts and to put into place right-sizing opportunities where possible. However, with the pressure on DevOps teams to keep up an agile release cycle and offer quick fixes, anything that stands in the way of their flexibility and freedom can feel worth the price tag.

    As a result, it can be a true paradigm shift for engineers and DevOps teams to start thinking about FinOps first, especially if they already feel that their plate is full. Here are some best practices that can help to smooth over any bumps in the road.

    Make Engineers Accountable

    Don’t simply add new stakeholders who are responsible for cost management and FinOps, as they will quickly become adversaries of your engineers. Instead, ensure that your technical teams and developers realize that they are responsible for their cloud costs. They need to know what they are using and they need to codify and document how they are looking to use their budget more effectively.

    Of course, the business has a role in this too, showing engineers best practices for FinOps, such as shutting down idle resources, right-sizing instances or making smart architecture decisions. 

    Explain That FinOps Isn’t a Cost-Cutting Initiative

    If DevOps teams have been given the equivalent of a blank check thus far, it can be a tough sell to start tightening the purse strings. Explain to DevOps teams that you aren’t looking to cut their budget. In fact, you might even be increasing it!

    FinOps is all about smarter financial operations, so if engineers can show that they can save money in one direction, they can channel that to new features, technologies and tools that make them happy. Giving DevOps teams control over FinOps decisions offers more autonomy and control—and that’s a great thing.

    Ease the Mental Load With Low-Hanging Fruit

    Once DevOps teams get much-needed visibility over their cloud usage and realize that they are gaining responsibility and autonomy over their behavior, you want to guide them to recognize where they can make changes. Challenge all your DevOps stakeholders with the same KPIs, and see who can come up with innovative ways to incorporate cost savings into business-as-usual. Some KPIs that could be a great start include:

    • Coverage: Use of reserved instances, savings plans, spot instances or committed use discounts.
    • Right-sizing: The opportunity value of downsizing or terminating instances that are idle or underutilized.
    • Orphan/idle status: Tracking the percentage of orphaned EBS volumes or snapshots; you can drill down into a specific time period, such as over one month.
    • Forecast metrics: Consider using the variance between a forecasted bill and the actual costs and aim to reduce this as much as possible.
    • Incorrect assignation: This would highlight oversized or incorrect instance types, S3 or EBS storage on the wrong tier, unattached elastic IPs or poorly tagged/ untagged resources.
    • Peak hours: What percentage of development resources are running during peak hours or running when they could be shut down; for example, on weekends?

    Automation Incorporates FinOps Best Practices in a Hands-Off Way

    If this all sounds like a full-time job in and of itself—you’re not wrong. You’d be forgiven for wondering when DevOps teams are meant to actually develop and build! To keep engineers and technical teams productive, make sure that you’re offering the right tools and technology to lighten the load where possible, especially where automation and AI can do a better job than a room full of DevOps or FinOps experts.

    One example is automating the purchasing and selling of reserved instances in real-time, so that you’re never left buying on demand. Another is automating the removal or rightsizing of idle or underutilized resources, respectively. When your DevOps teams see that you’re offering the technology to make FinOps simple, they are much more likely to do their part elsewhere.

    DevOps and FinOps

    In recent years, security teams have championed the idea of DevOps ‘shifting left’ on security best practices to get security included in the process of agile software development during the build stages.

    Well, you heard it here first: It’s time for a similar shift for finance and cost optimization.

    Just as engineers can no longer get away with ignoring security in the way that they work, financial optimization needs to be front and center of DevOps teams’ day jobs. For this to work and for DevOps to incorporate FinOps goals seamlessly, businesses need to champion visibility for cloud usage, a culture of cost-optimization and a strong foundation of automation that bakes best practices into everyday work.

  • Choosing the Right Software Testing Metrics

    Choosing the Right Software Testing Metrics

    A software testing metric is a criterion to track the effectiveness of quality assurance efforts. First, you establish success indicators throughout the planning stage. Then, compare them with the received metric after the completion of the process.

    However, many software QA and test experts tend to focus on how the tests will be executed rather than on the actual information produced by the tests. By this I mean testers often focus on the mere satisfaction of completing all the tests. But is this always a good thing? You can have a 100% pass rate with all green indicators on your dashboard and it is still possible that your tests aren’t strong enough.

    This article will discuss five software testing metrics that might assist QA professionals in evaluating their success.

    Characteristics of a “Good” Testing Metric

    Let’s talk about the features a metric should ideally have.

    Relevant to Business Goals

    Critical KPIs should reflect the primary mission and purpose of a business; for example, monthly revenue growth or the number of new users. Each company chooses its metrics based on what they intend to achieve with their product. While it may seem attractive to succeed in all tests, focusing on the wrong goals can be deceiving. This may impact the app’s work and the entire complex system, such as headless commerce architecture.

    Allows for Growth

    Every metric should allow for improvement. What if you’ve achieved a 100% success rate? The goal may be to keep the metric at this level or to improve it further.

    Encourages Development of a Strategy

    When a metric gives a team a goal, it also motivates them to ask questions to develop a plan. Suppose you need to increase revenue. Consider whether the product requires new features to encourage more purchases. Is it necessary to create a new acquisition channel? Has the competitor launched any new products or features that are attracting new buyers?

    Trackable and Comprehensible

    Good metrics are simple to comprehend and follow. Otherwise, how will the people gathering them make informed decisions? Employees must understand what they can do to improve the outcome.

    Three Tips for Choosing and Measuring Software Testing Metrics

    1. Start by Asking Questions

    Your questions should cover three topics:
    1. What you’re measuring
    2. Strategies and tools to measure it
    3. Reasons to track it

    To avoid analyzing useless metrics, pay attention to the metrics definition process. Sometimes, a small number of backlog bugs means your QA team is doing its job. However, when you break down these bugs into high/medium/low priority issues, you’ll be able to better see the overall program quality and make the needed adjustments.

    2. Don’t Neglect Automation When Calculating QA Metrics

    Automation saves you time on manual data collection and helps ensure your metrics will always be relevant. Let’s assume you use Jira. Set up a Jira Query Language (JQL) request on your Confluence page if you need data on critical bugs every sprint. It will be updated frequently. Or you can employ other tools based on your preferred test management/task tracking system.

    3. Collect Comments and Gradually Improve Metrics

    Once you’ve set up and gathered all the metrics, the feedback and improvement processes start. Pay attention to feedback to improve the efficiency and clarity of your metrics and reports.

    Five Software Testing Metrics to Track

    Now let’s look at some specific examples. Note that different quality aspects matter to varying degrees depending on circumstances.

    1. User Satisfaction

    Here, you’ll want to see the client’s reaction to the product. You use user satisfaction surveys and support tickets that reveal bugs. If you track these quality metrics and work to improve them, the business will grow as you’ll see more satisfied and returning customers. If something’s wrong, you’ll have to do a causal problem analysis and remove the roadblocks.

    2. Process Metrics

    These are internal measurements that have a significant impact on your product quality. For example, you can track lead time and the time it takes between setting the task and code deployment and production.

    One more metric you could use is cycle time. It means time to build a feature after being given the approval to begin working on it. Finally, you can track the time it takes to solve difficulties. This could refer to the speed of resolving tickets or bugs once they’ve been reported.

    As these metrics can be hard to measure, another method to improve process efficiency is to detect where unfinished work starts to pile up in the queue. It can highlight a bottleneck that, if removed, could help your teams become more productive.

    3. Coverage Metrics

    Another indicator of test quality is test coverage. It informs us of the amount of tested code. It’s a method of ensuring that your tests check the code and how much they operate. In this case, it’s better to use a top-down strategy. The first step is analyzing module coverage. Then you consider functionality and, finally, data coverage in each functionality. It means how many different combinations of the potential data inputs you’re covering with tests.

    This group includes such metrics as:
    ● Requirements coverage percentage
    ● Unit test coverage
    ● Manual or exploratory test coverage
    ● Test cases by requirement category
    ● UI test coverage
    ● Integration and API test coverage

    4. Code Quality Metrics

    Evaluating code quality means categorizing the value of code into two categories: Good and bad. There is no single notion of quality because practically every developer defines for themselves what constitutes good code. How can you assess code quality? Tools like SonarQube let you reveal how much technical debt is in a system. You’ll need to classify issues and vulnerabilities, organize them by priority and select what you’re going to focus on.

    5. Bug or Incident Metrics

    Each issue differs in severity, so don’t give all issues equal weight. Some problems are simply suggestions for improvement. Determine which components of quality are more important than others for your company. That said, go beyond just the amount of defects when analyzing the metrics you’ll use.

    What can you extract from incident reports? These results can include:

    ● Total number of bugs
    ● Open defects
    ● Closed defects
    ● The time to close each incident report
    ● Changes since the last release

    Rules for Measuring Software Testing Metrics

    Evaluating metrics in software testing and estimating their success can be frustrating and vague. Here are some tips and suggestions you can use:

    1. Correlate your metrics with project, process and product goals. Keep in mind that a single indicator is not enough for a complete view of your software quality.
    2. Track the progress (or regress) throughout time. Streamline the data collection process through automation, store data in a collaborative resource like a Wiki/Confluence and review outcomes regularly.
    3. Report the statistics to the customer and the team to show your progress. Reports should be easy to understand, so make them helpful and user-friendly.
    4. Check to make sure if the metrics are valid. Keeping track of irrelevant metrics and displaying inaccurate data is out of the question.

    Measurement is an important activity in software testing, such as determining the number of successful tests against how many have failed. All the information you get comes to stakeholders. As a result, they can make informed decisions such as when to release an app.

    How can you monitor your test activities? You need to determine relevant software testing metrics. Choosing the correct testing metrics can be difficult. Frequently, teams opt for metrics that are out of sync with the overall business.

    What can the lack of adequate benchmarks cause? Stakeholders fail to measure progress, identify possibilities for development or control which testing tactics have the most positive impact. All things considered, QA teams need to track individual progress, skill level, and success, as well as code quality, bugs, and coverage.

  • Sustainability No Longer Just a Buzzword for Cloud IT

    Sustainability No Longer Just a Buzzword for Cloud IT

    A recent CloudBolt survey on IT sustainability finds that sustainability is no longer just a buzzword — the market is demanding real change, and it appears that environmental concerns finally are influencing large IT investments. For example, 67% say that a cloud provider’s sustainability initiatives are important in deciding whether to do business with them. A significant portion of organizations are even willing to pay a premium to support green initiatives!

    Below, I’ll review the report to find its major takeaways. We’ll see how sustainability is directing real action in cloud IT and briefly compare how the market perceives current green initiatives among three top cloud providers: AWS, GCP and Azure.

    Sustainability Gains Real-World Traction

    In June and July 2021, CloudBolt polled 256 global CxOs and tech leaders on its Pulse platform, and found that 76% of respondents now consider climate change an existential threat. Not only are IT purchasers factoring compute and cost, but a sustainability conscience is now influencing executives to direct sweeping change. In fact, 79% of respondents indicate their IT departments are expected to help their companies achieve specific sustainability initiatives driven by the board of directors of the C-suite.

    Interestingly, other studies found that a sustainability commitment results in tangible business outcomes. For instance, 88% of the research conducted by Oxford University and Arabesque showed that solid environmental, social and governance (ESG) practices result in better operational performance of firms and higher profits. This study also noted that 80% of the time, a company’s stock price is positively influenced by sustainability practices.

    Climate Conscience Guides Cloud Choices

    Most organizations now consider a cloud vendor’s sustainability initiatives when choosing whether to do business with that provider. A full 78% of respondents agree that the public/private cloud choices they make can materially affect the environment for better or worse. New environmental cloud commitments not only attempt to minimize carbon emissions from their data centers but factor in ecological ramifications and aim to erase companies’ historical carbon footprints, as well.

    Cloud consumers also want to contribute to addressing these green initiatives. An impressive 79% of respondents indicate that they will pay a premium to work with vendors who incorporate sustainability into their business. And 41% of companies are willing to pay a premium of 11 % to 15% of their current bills. This shows that sustainability is now a vital factor within the marketplace, and companies are willing to pay the price to increase their own environmental standing.

    Though this commitment is undoubtedly growing, the report did find that operational requirements such as security, cost and agility, still rank significantly higher than sustainability when comparing cloud providers. Though IT professionals recognize climate change as an existential threat, they still have day jobs and must keep operations moving.

    AWS: King of Green Clouds

    Slightly more than half (51%) of respondents agree that the industry-wide green energy commitment is real and growing among all cloud providers. However, when comparing the top three—Amazon Web Services (AWS), Azure and Google, AWS appears to be emerging as an IT sustainability leader; 41% of respondents perceived AWS as doing the most to address green initiatives.

    AWS is on track to power its entire operations with 100% renewable energy by 2025. With their solar plant investment in April 2021, Amazon became the largest corporate buyer of renewable energy in Europe. Around the globe, AWS has invested in a combination of on-site solar, solar farms and wind farms to power their data centers and Whole Foods divisions.

    To their credit, both Microsoft and Google also committed to climate pledges that affect their cloud footprint. Azure supports a similar initiative to reach 100% renewable energy by 2025, in addition to further investments to improve water, waste disposal and surrounding local ecosystems. Google Cloud’s commitment is to operate on carbon-free energy 24 hours a day by 2030, and the company has already achieved 100% renewable every year since 2017.

    Not only does AWS appear to be doing the most to address its environmental impact, it also retains the most market traction as a cloud leader. The majority of respondents (62%) said that AWS is winning the cloud wars while only 31% said Azure and just 7% said GCP.

    Final Thoughts

    It is heartening to see that ESG standards are having a measurable impact on a company’s cloud allegiances. The market now demands real change and is willing to pay the price for more ethical and sustainable cloud hosting.

    But choosing a cloud provider is only one aspect of reducing IT’s impact. As I’ve covered before, there are many ways IT can curb its climate impact. Such actions include optimizing overall infrastructure, shuttering zombie VMs, avoiding over-provisioning resources, increasing performance visibility, refactoring code and other measures. What’s great is that most of these initiatives have the added benefit of reducing cost to the business.

    The CloudBolt Industry Insights Report, The Truth About IT Sustainability: Paying More Green to Get More Green, surveyed 256 IT leaders on their perception of cloud sustainability. For additional insights, you can pick up a copy here.

  • Salt Security Adds Support for GraphQL APIs

    Salt Security Adds Support for GraphQL APIs

    Salt Security has extended its platform for securing application programming interfaces (APIs) to include support for APIs built using GraphQL.

    GraphQL is an open source data query and manipulation language for APIs that was originally developed by Facebook. It provides a more efficient approach to querying data than the REST APIs that are widely used today.

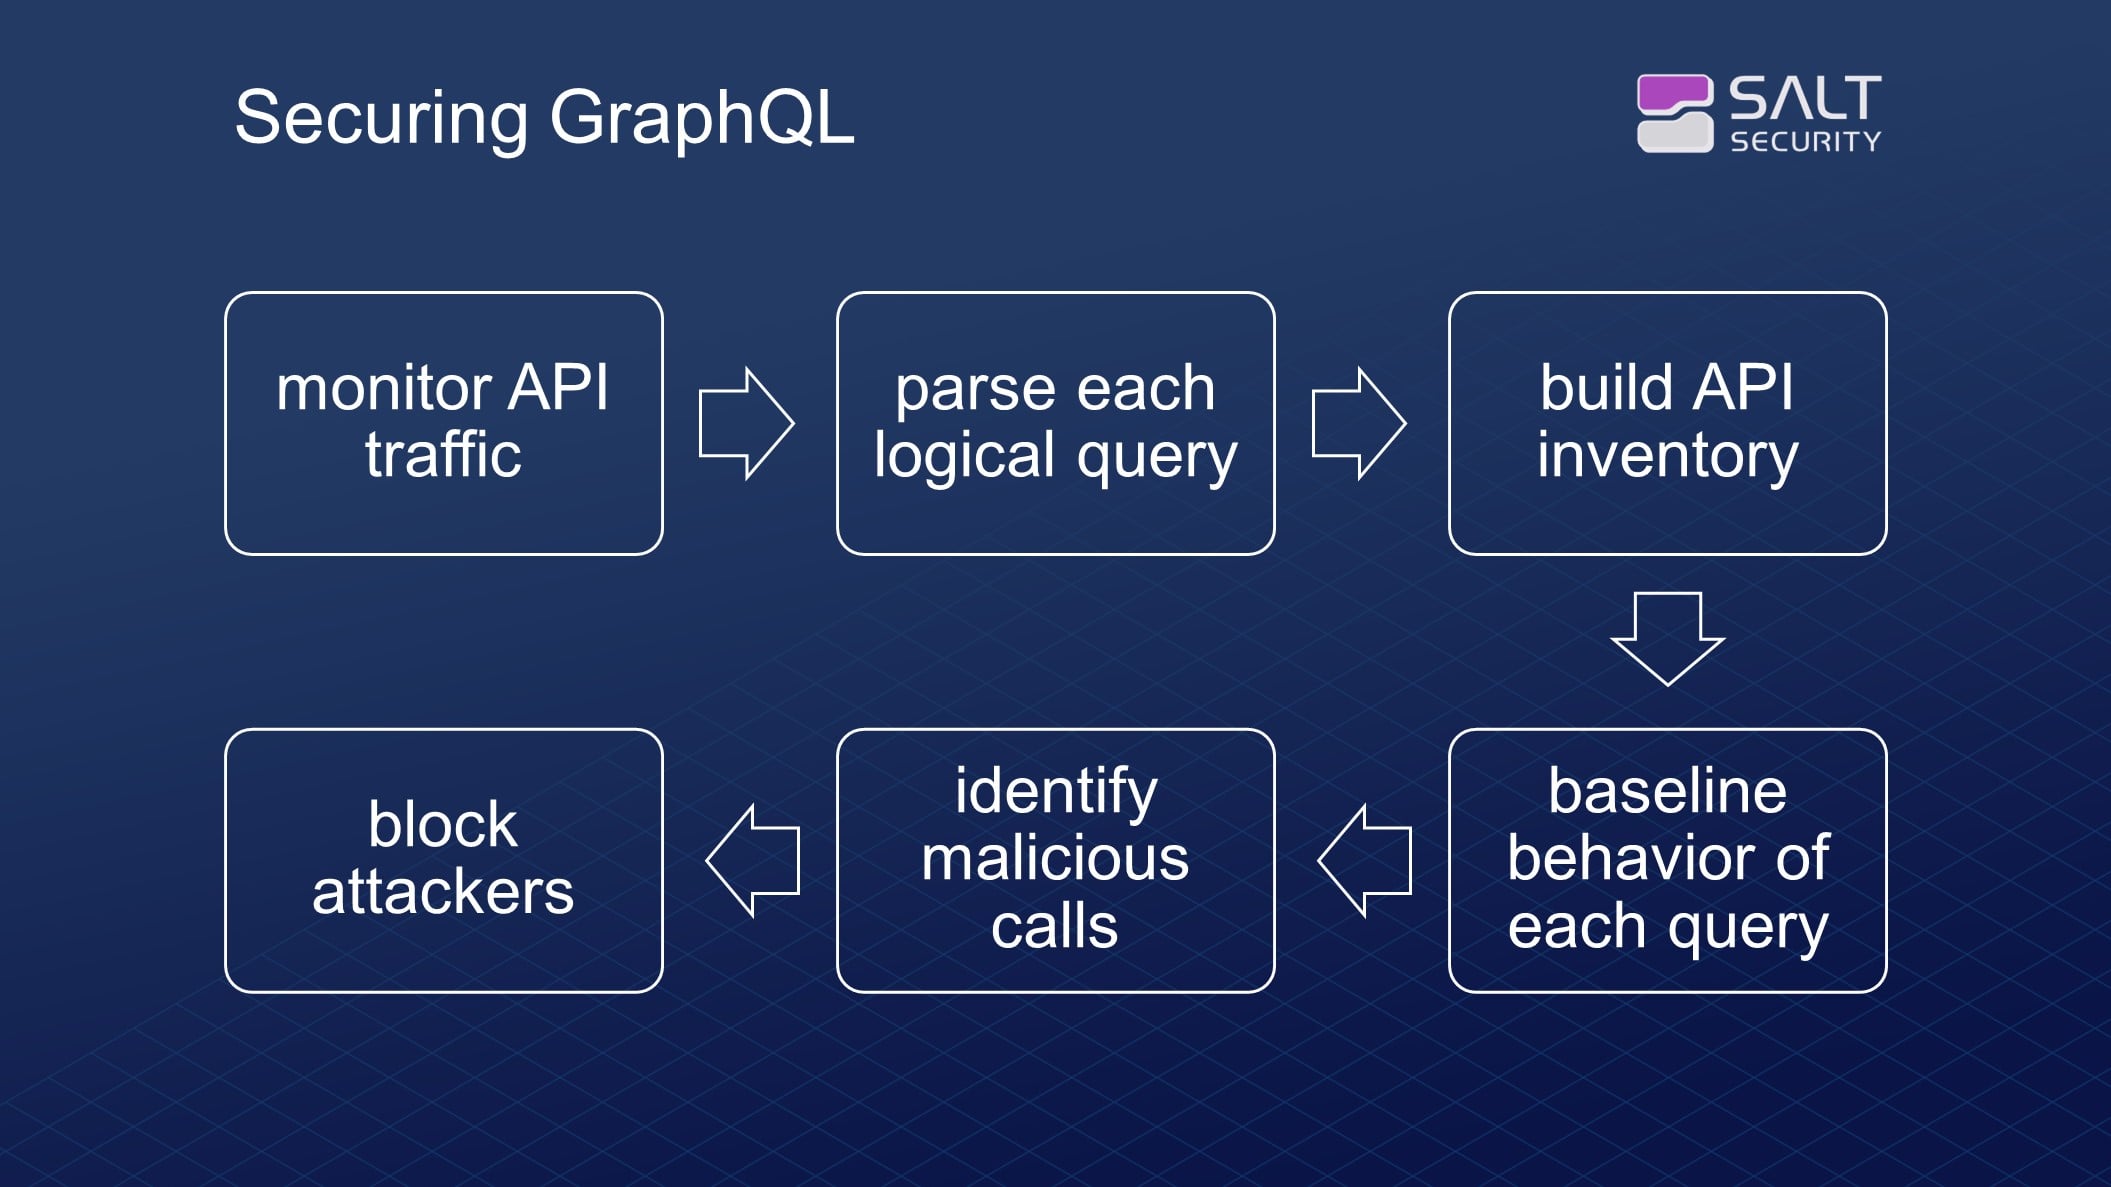
    Elad Koren, chief product officer for Salt Security, said adding support for GraphQL alongside existing support for REST APIs to the Salt Security API Protection platform will make it possible for security teams to discover those APIs, mitigate data exposure, stop attacks and eliminate vulnerabilities. The Salt platform parses the complex structure of each GraphQL query to identify unique object entities that are then used to create a complete inventory of the GraphQL APIs being employed.

    APIs built using GraphQL are more challenging to secure because of the unique call and response formats, noted Koren. Cybercriminals can also, for example, leverage GraphQL capabilities such as nested queries and query batching, to launch distributed denial of service (DDoS) attacks, he said.

    Many developers will tend to assume that, because GraphQL is relatively new, most cybercriminals are primarily focused on exploiting REST APIs. However, as more developers employ GraphQL, it’s only a matter of time before cybercriminals begin to find ways to exploit APIs that may not be as secure as the REST APIs that many organizations already know how to secure.

    The Salt Security platform itself is based on a big data engine that employs machine learning algorithms and other forms of artificial intelligence (AI) to identify attacks in real-time. It creates a baseline to identify legitimate system behavior while preventing cybercriminals from using penetration testing tools to perform reconnaissance.

    From a DevOps perspective, the Salt Security API Protection Platform integrates with tools such as Jira and Slack to ensure that remediation details are routed to the right development team in addition to helping track tickets to ensure remediation fixes are implemented. It also can be integrated with security information event management (SIEM) platforms from vendors such as Splunk and Sumo Logic to enable incident response for both DevSecOps and security operations teams.

    Most IT teams will not be replacing REST APIs with GraphQL-based APIs overnight. However, there will soon be enough APIs based on GraphQL to warrant additional security measures. Less clear is to what degree those security measures will be put in place by DevSecOps teams versus a security operations team.

    One way or another, however, the number of APIs that need to be secured is accelerating rapidly as organizations roll out a new generation of microservices-based applications that drive mission-critical digital business transformation initiatives. Each microservice has its own API that needs to be built and then secured. Unfortunately, most APIs are built by developers that don’t always have the greatest appreciation for security. As such, while more responsibility for API security is shifting left toward developers, many security teams would be well advised to make certain every API being deployed is fully secure.

  • Dynatrace Survey Sees Continuous Delivery Challenges Ahead

    Dynatrace Survey Sees Continuous Delivery Challenges Ahead

    A global survey of 1,300 application development and DevOps leaders conducted by the research firm Coleman Parkes on behalf of Dynatrace finds, on average, organizations expect to increase the frequency of their software releases by 58% over the next two years.

    Andreas Grabner, director of strategic partnerships at Dynatrace, an observability platform provider, said that while it’s clear organizations are embracing DevOps best practices to achieve that goal, the survey also found that more than a quarter (27%) of DevOps teams’ time is spent on manual continuous integration/continuous delivery (CI/CD) tasks. Nearly a quarter (22%) admit they’re often under so much pressure to meet the demand for application deployments that they must sacrifice code quality.

    In response, nearly two-thirds of respondents (62%) are investing in automation to eliminate manual tasks, while a similar percentage are looking to automate incident response processes. Another 45% are investing in observability tools, with nearly three-quarters (74%) noting that end-to-end observability will be essential to DevOps in the future.

    A full 98% also noted that extending DevOps to more applications will play a crucial role in driving digital transformation and optimizing customer experience. A total of 71% said a unified platform that seamlessly integrates their toolchains will be critical to scaling DevOps, while 79% said extending artificial intelligence to IT operations (AIOps) into the realm of DevOps is critical for their future success.

    Survey respondents, however, also identified siloed team cultures (75%) and application complexity (70%) as the primary barriers to achieving DevOps success. Organizations, as a result, are investing in the automation of manual CI/CD tasks (62%), eliminating manual incident response (62%) and end-to-end observability (45%).

    Grabner noted that, as more organizations build and deploy next-generation applications based on microservices constructed using containers and application programming interfaces (APIs), it will only become more challenging to automate DevOps processes. As part of an effort to reduce the cost of delivering those applications, Dynatrace donated Keptn, an open source enterprise-grade control plane for automating the continuous delivery of cloud-native applications, to the Cloud Native Computing Foundation (CNCF), added Grabner. The overall goal is to reduce the total cost of implementing DevOps as part of an effort to instrument more applications, he noted.

    While most organizations that have embraced DevOps have a good handle on how to implement continuous integration, achieving the continuous delivery side of the DevOps equation has proven to be more challenging. In the absence of standardization among the platforms, each application deployed on individual IT systems is a “snowflake,” in that it is unique to that platform. That issue, in part, is why so many IT teams still rely on manual processes to deploy applications.

    It’s only a matter of time before organizations begin to more aggressively automate the deployment of applications. That may become even easier to achieve if they standardize on a Kubernetes application programming interface (API) that can be implemented across any platform.

    In the meantime, however, it’s clear that, as the pace of digital business transformation increases, one of the most limiting factors organizations will encounter is the pace at which applications can be deployed and updated.

  • Postman Survey Shows Focus on Building and Deploying APIs

    Postman Survey Shows Focus on Building and Deploying APIs

    A survey of more than 28,000 developers and application programming interface (API) professionals published today by Postman found nearly half of respondents (49%) are now spending the majority of their time developing APIs. More than a quarter (28%) now spend 20 or more hours per week working with APIs.

    Kin Lane, chief evangelist for Postman, a provider of a platform for building APIs, said that shift reflects an increase in software development and integration activity that began at the start of the COVID-19 pandemic. Almost two-thirds of respondents (63%) said the pandemic somewhat or significantly affected their work, with almost half of those respondents noting that changes made with their organization were enabled and supported by APIs.

    Additionally, a full 94% of respondents said the investment of time and resources into APIs will increase or stay the same for the next 12 months. The biggest obstacle to creating APIs is lack of time (45%) while the biggest obstacle to consuming an API is lack of documentation (55%). In terms of API goals, the survey found that quality (80%), agility (66%) and reliability (65%) are the top three goals among survey respondents.

    However, the survey also noted only a third of respondents said they could build and deploy an API in anywhere from a single day to a week, with most requiring one week to a month. About one-third also said they deploy APIs to production between once per week and once per month. More than 80% of respondents noted that less than 25% of their changes fail while a similar percentage said they can recover in less than a day with a third reporting they fully recover in less than an hour.

    The Postman survey also found that more than three-quarters of respondents (76%) have less than five years of experience with API development. Only half of respondents indicated that they agree or strongly agree that the leadership of their API team has a clear sense of where their API practice should be in five years. However, microservices (58%) and Kubernetes (50%), containers (46%), serverless architecture (44%) and GraphQL (35%) were ranked among the technologies that respondents were most excited about heading into 2022.

    On the plus side, more than 60% of respondents felt their API leadership and governance teams demonstrated a “willingness to change” as well as duly considering “the interests and opinions of employees.” When it comes to regularly providing feedback and process, more than half of leadership and governance teams (53%) scored well.

    The top two ways API teams collaborate is via a dedicated collaboration platform (50%) or by publishing API artifacts to repositories such as GitLab, GitHub and Bitbucket (45%), according to the Postman survey. The most widely used DevOps tools are Jenkins (37%), Azure DevOps (26%), GitHub Actions (25%), AWS DevOps (23%) and GitLab Pipelines (22%).

    In terms of deploying APIs, continuous integration/continuous delivery (CI/CD) platforms are the most widely employed (57%), followed by deploying APIs in the cloud (38%), frameworks (34%) and custom-built deployment methods (27%).

    Just over 70% of respondents ranked security and performance as the top factors considered when integrating with an API. When producing an API, however, the top factors are integration with internal systems, integration with external systems, adding functionality to an internal system and enhancing functionality for an end customer. Similarly, when consuming an API the top factors are integration with external systems, adding functionality for end customers, adding functionality to internal systems and integration between internal systems.

    In general, Lane noted that, as more APIs are developed and deployed to drive various digital business transformation initiatives, organizations will need to pay more attention to API discovery and management. There’s a tendency for different teams within organizations to not only create redundant APIs but also forget about so-called zombie APIs that are no longer supported but can still be exploited by cybercriminals.

    Overall, Lane said the survey makes it clear more organizations are pursuing an API-first approach to digital transformation. The challenge now is managing all the APIs that can quickly become too much of a good thing.

  • Intel Woos DevOps Teams with API and Processor Advances

    Intel Woos DevOps Teams with API and Processor Advances

    During the online Intel Innovation 2021 event, Intel announced today a unified Developer Zone for accessing application programming interfaces (APIs) that it makes available via a oneAPI toolkit to IT teams that want to more easily invoke a wide range of processor types and classes.

    At the same time, the company also revealed it is creating a set of oneAPI centers of excellence that will make it easier for DevOps teams to consume those APIs. Partners participating in that initiative include Oak Ridge National Laboratory, University of California Berkeley, University of Durham and University of Tennessee. Intel will also make the Intel Graphics Visualization Institutes of Xellence part of this program.

    Next year, Intel is also promising to deliver oneAPI 2022 toolkits that will add 900 additional capabilities including an ability to develop applications for CPUs and graphical processor units using what Intel described as the first unified C++/SYCL/Fortran compiler.

    The company is also planning on making available Data Parallel Python tools in addition to expanding its Advisor accelerator performance modeling tools to include support for VTune Flame Graph to visualize performance hot spots.

    There will also be additional oneAPI integrations to add support for Microsoft Visual Studio Code and the Microsoft Windows Subsystem for Linux 2 platform. Intel also created an Intel oneAPI AI Analytics toolkit to enable out-of-the-box AI development that is supported by workstations running Linux from Dell Technologies, HP and Lenovo. Additionally, Microsoft and Intel have agreed to create a complete data science toolchain to Windows 11 that will become part of the Surface Laptop Studio framework for building applications.

    Greg Lavender, chief technology officer, senior vice president and general manager of the software and advanced technology group at Intel, said it’s critical to make sure that DevOps teams add support for the acceleration engine and extensions that Intel makes available within its processors to the runtime environments they deploy. Otherwise, developers will never be able to routinely invoke those capabilities to build next-generation applications.

    The company also revealed that next-generation Intel Xeon Scalable Processors, code-named Sapphire Rapids, will have additional acceleration engines to both simplify deployments at scale and optimize processors’ core utilization in a way that reduces power consumption. Overall, Intel is promising up to a 30x total performance gain for artificial intelligence (AI) applications running on these processors.

    Other hardware advances announced today include a 12th generation Intel Core family based on 7-nanometer processors and a Mount Evans project through which Intel is collaborating with Google Cloud to build processors based on application-specific integrated circuit (ASIC) chips.

    The company also unveiled an Intel ArcTM Alchemist family of graphics systems on chips (SoCs) that take advantage of machine learning algorithms to optimize performance and touted an Intel Tofino fabric processor (IFP) that adds intelligence to network switching via support for P4 programming tools.

    Finally, the company noted that an Aurora supercomputer, due out in 2022, will exceed two exaflops of peak double-precision compute performance.

    As Intel seeks to regain the processor high ground from rivals such as NVIDIA, ARM and AMD, it’s clear that the future of IT will be defined by a broad range of processor classes that all have unique capabilities. The challenge now is deciding which of those capabilities to actually make available to developers that are largely dependent on the runtime environment that DevOps teams decide to make available.

  • GitHub Expands Developer Productivity Tools Portfolio

    GitHub Expands Developer Productivity Tools Portfolio

    During the online GitHub Universe 2021 conference, GitHub today unveiled a bevy of updates intended to boost developer productivity by making it easier for developers to write code faster and collaborate more easily.

    The GitHub Copilot tool that GitHub developed in collaboration with OpenAI, a research and development lab, to help developers write better code faster is being extended via a technical preview to add support for Java and the integrated development environment (IDE) JetBrains.

    In addition, the Codespaces tools that GitHib makes available to pre-configure development environments is being extended to include support for devcontainer feature composition, the GitHub command line interface (CLI) and REST application programming interfaces (APIs) along with additional access controls.

    GitHub Actions has also been updated to add support for deployments using the OpenID Connect standard in addition to providing access to deployment environments to simplify approvals, improvements to reusable workflows and auto-scaling functionality for self-hosted runners.

    There is also now a Command palette tool in beta to help developers navigate GitHub along with a public beta of a GitHub Issues tool that makes it simpler for developers to filter, sort and group issues and pull requests. Additional features that have been added since GitHub Issues was first previewed include iteration support, reporting and data visualization tools and the ability to employ it across public projects.

    Finally, GitHub is adding, in beta, support for Ruby as a programming language that CodeQL analysis engine can now scan for vulnerabilities along with the ability to customize permissions for accessing GitHub Enterprise Cloud.

    Ryan Salva, vice president of product management for GitHub, said collectively GitHub is committed to making developers more productive by, for example, autocompleting code as developers write. Support for additional programming languages will also be forthcoming in the months ahead. The goal is not to leverage AI to replace developers but, rather, eliminate the drudgery that gets in the way of developers becoming more creative, noted Salva.

    There won’t come a day any time soon when developers won’t have to type to write code, but it is possible to leverage AI to provide a type-ahead capability that reduces coding errors, added Salva.

    The goal should be to enable developers to create more application experiences at a time when more organizations than ever are consuming applications that drive a wide range of digital business process transformation initiatives, said Salva.

    As part of that effort, Salva noted it’s also critical to reduce the amount of friction developers encounter writing code starting with setting up the development environment itself.

    It’s not clear yet what impact all the focus on developer productivity and collaboration will have on the rate at which applications are being built and deployed. However, as developers become more productive, the number of application development projects that can be launched simultaneously should increase. In fact, there may come a day when applications are being built faster than organizations can deploy them without adopting continuous delivery best practices that rely on higher levels of automation to install software.

    Regardless of that application delivery challenge, however, it’s a problem most organizations right now would consider themselves fortunate to have.

  • BMC Looks to Advance ServiceOps Approach to Managing IT

    BMC Looks to Advance ServiceOps Approach to Managing IT

    During an online BMC Exchange event, BMC announced it expanded its portfolio of IT management offerings as part of an ongoing effort to unify traditional IT service management and DevOps processes under an integrated ServiceOps framework.

    The latest additions to the BMC portfolio includes an update to its Control-M workload automation platform that adds observability tools for monitoring application and data workflows along with additional integrations for cloud services such as AWS Glue, Google Cloud Dataflow and Function and Microsoft Azure Data Factory and platforms such the data lake from Databricks.

    BMC is also making available a preview of a Control M Python client that will extend the reach of the workload automation platform to the code data science teams employ to build artificial intelligence (AI) models.

    In addition, BMC is adding a BMC Helix Digital Workplace studio to make it easier for IT teams to customize the software-as-a-service (SaaS) platform it provides for IT service management (ITSM). Finally, BMC is also making available a version of BMC Helix that is optimized for communications service providers.

    BMC CEO Ayman Sayed said overall the current emphasis on digital business transformation is driving a need to converge the management of multiple IT platforms as organizations reinvent how core processes work across their organization. It’s not possible to drive that level of reengineering across multiple IT platforms without centralizing the management of those platforms using a ServiceOps framework that unifies DevOps and existing ITSM platforms, he noted.

    At the same time, Sayed said organizations need to invest more in artificial intelligence to automate IT operations, also known as AIOps, to augment IT staff that is hard-pressed by the need to manage both emerging and legacy IT platforms. The latest investment BMC has made in AIOps came earlier this month with the acquisition of StreamWeaver, a provider of a set of tools that make it easier to collect massive amounts of data that can be used to more easily train AI models.

    It’s too early to say to what degree IT management processes might become unified. In addition to centralized IT teams, most organizations have business units that often drive their own IT initiatives. However, as organizations realize how many platforms a digital process needs to access the need to centralize the management of IT becomes more apparent. The issue each organization will need to determine is the degree to which that centralization needs to occur.

    It’s clear in the wake of the COVID-19 pandemic that many IT organizations have never been more agile. In some cases, those IT teams are now able to drive a rate of change that is too fast for many businesses to even absorb. In fact, it’s arguable that entire businesses will need to adopt DevOps principles to manage that rate of change.

    In the meantime, IT teams will need to take a harder look at how much time is being spent on manual tasks that could be automated in a way that enables them to be lot more productive than they are today.