Category: Continuous Delivery

  • Overheard at CloudBees Connect: The Reality of Delivering Modern Software

    Overheard at CloudBees Connect: The Reality of Delivering Modern Software

    What’s it like delivering modern software today? We posed that question to eight DevOps leaders from a diverse range of industries and development organizations. They were all participants in panel discussions I moderated at CloudBees Connect – held virtually this year. Needless to say, there were no short answers to our questions, but here’s a sampling of some key issues they’re focused on.

    • Balancing speed with security, compliance and quality. DevOps leaders say they constantly wrestle with getting the best of both worlds. Many err on the side of caution, but also take advantage of automation to embed security safeguards throughout the lifecycle without diminishing speed. “We want to empower our customers and our engineers, but we need to delight our auditors,” says Jennifer Hansen, director of product management and delivery experience at Capital One.
    • Standardization versus empowerment. You need both to thrive in today’s environment, panelists say. “The key is to find that sweet spot between maintaining a structure that your organization needs and giving developers the freedom to drive innovation,” says Daniel Ritchie, distinguished engineer at Broadridge Financial Solutions. Some standardization is helpful, and many programs have adopted common patterns and core toolsets to boost efficiency, but not at the expense of best in class tools that the developers want to use most.

    Sanmat Jhanjhari, lead DevOps engineer, Nationwide Building Society agrees. “Nationwide believes in empowering people and creating an environment that you have [what we call] accountable freedom…that’s one of the key pillars of [our] leadership framework.”

    “We really want them to be involved in the pipeline construction and to tell us what they need rather than for us to describe or define what they should be doing,” says Bob Kelley, director of delivery engineering, IHG.

    • Culture not tools. People and culture – more so than tools – are the key to building great software for customers. That’s why continued learning and skills development is a prime focus of Capital One’s Hansen. “We’re trying to create a shared experience and responsibility across everybody on our team.”
    • Scaling up. Organizations large and small need headroom to grow. Even smaller companies are preparing for the day they’ll need broad-reaching capabilities. Says Adam Robertson, head of DevOps at Pinger: “We’re building the foundational elements so we’re ready when we reach enterprise scale.”
    • Embracing the future. Leaders say they are enthusiastically embracing the latest development approaches and technologies, including microservices architectures and containerization in the cloud.
    • Winning over management. Convincing C-suite execs that DevOps is worth the investment can be tough. Jimmy McNamara, software engineering product manager at Fidelity Investments, says the best way to overcome resistance is to “use data to show real outcomes. It’s about articulating a vision of value and demonstrating that in a very tangible way.”
    • Driving collaboration. Leaders have adopted different techniques for promoting collaboration among developers. Some have created open source communities within the company, complete with templates and global libraries, to help developers contribute code and allow other teams to benefit from the contributions.
    • Move slow so you can move fast. Leaders say the best way to build momentum across teams is to first establish a consensus, so everyone has shared ownership and feels empowered at the same time. That may take time, they say, but if you invest upfront, you’re going to reap returns faster, longer and better later. “Instead of dictating to teams, we need to create consensus up front,” says Aoife Fitzmaurice, architect for enterprise cloud computing at Fidelity Investments. “If a certain choice wasn’t correct, let’s work together to make the right choice.”
    • Harvesting best practices. The diversity of practices across engineering teams can be a strength to development organizations, Fidelity’s McNamara says. DevOps can serve as a “central consultancy” that can “harvest their best practices” to empower the whole organization.

    What else is on the minds of DevOps leaders today? Listen to both panel discussions – captured in the award-winning CloudBees podcast, DevOps Radio, to dig deeper into the reality of delivering modern software today:

    • Episode 73: Live from CloudBees Connect – The Reality of Delivering Modern Software: Part 1 Listen Now
    • Episode 74: Live from CloudBees Connect- The Reality of Delivering Modern Software: Part 2 Listen Now
  • Fidelity drives Software Delivery Performance

    Fidelity drives Software Delivery Performance

    The following blog post is based on a presentation at CloudBees Connect. The full recorded session is available below.

    Wistia video thumbnail

    Few industries depend on software more than financial services. Jimmy McNamara, software engineering product manager at Fidelity, should know: He’s worked in the industry as a software developer and project manager for over two decades, most recently for Fidelity Investments, one of the largest investment firms in the world. Fidelity’s brokerage business alone manages multiple trillions of dollars for clients worldwide.

    With so much value at stake, McNamara says that Fidelity can’t afford to let its software products lag behind the industry. It’s why the company keeps more than 10,000 developers busy building and maintaining a broad range of business and customer applications. “Fidelity is a huge believer in IT,” he says. “It’s part of our core philosophy and business strategy. It’s something that’s constantly discussed at the highest levels in the company.”

    How great software is produced at Fidelity Investments

    McNamara’s job is to help Fidelity’s developers produce great software as fast as possible, but also as safely and securely as possible. Doing so requires him to strike a balance between enforcing security through a central platform and allowing developers to use the very best tools available. “Governance and security are non-negotiable,” he says. “But at the same time, we don’t want to get in the way of our developers if they want to leverage the latest technology.”

    To gain access to best-in-class development tools, Fidelity increasingly looks to the cloud. “There’s a huge number of new features and a ton of automation that can be achieved by operating in the cloud,” he says. “It’s a game-changer in terms of the ability to improve operational outcomes, realize market opportunities and grow the business.”

    To shift the balance toward cloud over time, McNamara prefers to pull rather than push the dev teams. “We establish new capabilities and we make sure those capabilities are better than before, so our developers are naturally drawn to them,” McNamara says. Almost always, developers find the cloud environments easier to use and more conducive to innovation. “Ideally they don’t need to worry about set up,” McNamara says. “They can just focus on innovation and writing code, and it’s a better experience than before.”

    Driven by data

    To stay on track, McNamara’s team is constantly measuring how well its evolving platform is performing and delivering value to the business. “We’re very focused on data,” McNamara says. “If you follow the data, you can get to where you need to go faster.” The team tracks a range of performance metrics, such as mean-time-to-recovery (MTTR) and how quickly they are providing the features that the business requests.

    The data helps his group prioritize new platform-improvement projects and spot trends early to get a jump on emerging problems. For example, his team may decide to add automation features ahead of time to prevent an issue from impacting the business. Moreover, having access to reliable data drives more fruitful discussions with stakeholders about the value of the group’s services. “It moves the discussion beyond opinion to a more accurate, value-based discussion that really drives our services roadmap,” McNamara says.

    In the past few years, the company’s embrace of cloud-based platforms has yielded tangible improvements, such as better operational resiliency, much of it driven by the cloud’s inherent elasticity.

    What’s more, the move has given developers a richer environment in which to learn and grow. “It’s great to see a team move to cloud-based platforms,” McNamara says. “You can witness the transformation of their skill set. Their whole role in the organization changes because of the new features available in the cloud. In the end, your developers are happier because they get access to more scale, more automation, and more features. Not only that, but their skills become more marketable.” McNamara also knows that having the best tools is key to recruiting and keeping top talent.

    To ensure a successful transition, McNamara suggests hiring engineers who are naturally curious and eager to embrace new things. “The key is to bring on really inquisitive people,” he says. “It’s all about people as far as I’m concerned.”

    For those who might be reluctant to give up on their traditional on-premise environments, McNamara suggests leading by example. “If you’re a central team or service like us, you should get your stuff out first. Show it off. Demonstrate how you’ve achieved the outcomes you’ve delivered.”

  • Testing with Feature Flags to Improve Developers Productivity

    Testing with Feature Flags to Improve Developers Productivity

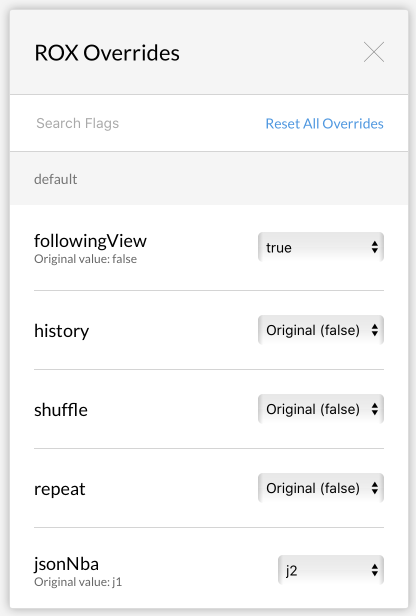
    Feature Flags can improve your continuous integration process in a number of ways. This post will focus on how CloudBees Feature Flags can help improve your developer productivity and shorten the feedback loop with the Flag Override view for frontend validation.  It includes Javascript in examples, but the override view can be used in all available platforms.

    The flag override view is a lightweight UI element that is very useful for debugging purposes. This override view exposes the current status for each flag set by developers and allows users to override these flags. All this is accomplished from within a handy popup in the UI of your local development instance or other instances used for quality assurance or user acceptance testing.

    For organizations, this view improves developer productivity by enabling them to rapidly validate the functionality of their newest code additions in your local environment frontend. To get started, first import the CloudBees Feature Flags SDK to your application:

    import Rox from 'rox-browser';

    Then, you will want to add the flag override view to your code. For example, this line adds the override view and controls where to display the view:

    <button className="btn btn-flags" onClick={() => Rox.showOverrides('bottom left')}>Flags View</button> 

    Check out the Browser side Javascript API for a full list of parameters.

    Once you have the override view in your local environment, you can toggle any and all frontend flags in your code to validate various code blocks and how they interact together.

    Now you can merge your work back to the master branch faster AND with more confidence!

    Shorten Feedback Loops with Feature Flags

    Quality assurance team(s) without access to the flag override view are typically stuck chasing each feature developer and waiting for them to modify code anytime QA needs to compare new and old functionality. This feedback loop could take hours if the developer is busy or days if the developer is on vacation, not to mention put a damper on developer productivity. With CloudBees Feature Flags and the flag override view, QA can shorten the feedback cycle by having complete freedom to toggle flags in their environment with the click of a button. There is no need to rope in developers to modify code, rebuild, and deploy just to update a flag. Now QA is empowered to work independently, without asking developers to break their focus or wasting precious business cycles.

    In conclusion, the flag override view is a handy screen designed for use in local and testing instances of your application frontend. The view helps developers rapidly prototype new functionality so they can get it merged to the mainline codebase faster. The view also helps QA folks work more independently of developer input and with more control of their experimentation all within a shorter feedback loop. Try the flag override view today!

    image1

  • Technical Debt Management with Feature Flags: Strategy & Best Practices

    Technical Debt Management with Feature Flags: Strategy & Best Practices

    Technical debt is accumulated as unmanaged flags accrue in an application’s code. And the associated marginal gain (i.e. each unmanaged flag added) directly impacts the amount of time and resources needed for testing. This can lead to more serious issues with the affected development, performance/testing and product processes becoming more expensive.

    As software teams grow and become more agile, it’s important to ensure a feature flag solution can scale. But it’s imperative that best practices and techniques are followed to avoid the technical debt accumulated by poor flag lifecycle strategy. This post will cover best practices for avoiding technical debt management when using feature flags.

    Strategic feature flag planning to avoid technical debt

    Sometimes, an ad hoc fix is necessary that can easily be resolved through an additional feature flag. All too often though, scenarios come up where teams feel pressured with time or resource constraints and resort to implementing feature flag gated code without a second thought. While this is somewhat of a normal byproduct of software development, planning is essential and a fundamental precursor to long-term success with feature flags.

    The time taken to plan prior to implementation assists in feature flag due diligence. Teams should ask themselves:

    • What will the flag be used for?
    • What team will use the flag?
    • How long will the flag be in use?

    The questions were listed in descending order. It’s important to realize this as each question helps filter flags, with the first dividing flags based on its high-level use and the last providing more granular detailed information. This preparation is critical to avoid the hassle of technical debt management later.

    How to Name Feature Flags to Avoid Technical Debt

    With these questions answered we can now begin naming flags. Companies have style guidelines for writing code, and should append these with its use of feature flags. Before creating a flag, cement the naming convention to be used; this will standardize the practice and help onboard future employees. Like variables, flag names are best left at the intersection of descriptive and terse (i.e. short and sweet).

    Some feature flag management solutions provide a namespace. This is the first funnel or way to search flags later on. A namespace should be used to identify how a flag will be used. For example, a set of flags should be defined to the namespace “releaseFlags” allowing for a separate group of “abTestFlags.”

    Once a flag has been created with a namespace, a label can denote which teams are using a flag. Since multiple labels can be applied in a flag management UI, it allows multiple teams to associate themselves with each flag.

    The description of a created flag provides verbose details, like flag creation date, or necessary information related to a dependency on another flag. This information is the last and most granular bit of the flag’s information.

    Best Practices in Flag Lifecycle Management 

    Review flags often. Flag management solutions can display and filter which flags are on, off or experiencing no traffic through an interface. But teams must be vigilant about removing flags and have a well-defined clean up process.

    Integration with tools like JIRA can help monitor and associate a ticket with the lifespan of each flag. Once a notification is sent that the flag is to be removed (e.g. the A/B test has finished, canary deployment was successful, etc.), the ensuing removal process is easily outlined from previously established naming conventions.

    After reviewing a flag’s description, dependencies can be noted and dealt with accordingly. we can review dependencies on all other associated flags. Referring back to the labels will delegate work as the responsible team will be notified to remove the flag from the code base.

    And where in the code should they look? Developers turn to the flag’s namespace, although it may exist across multiple tech stacks defined within an application. This is where an additional dashboard should be leveraged, specifically one that displays the environments and code languages a flag has been used in. With all of this information in place, it’s fairly easy to notify the responsible party and search within an IDE for all instances of the flag.

    Summary

    Naming conventions are the next most important element in feature flag management. Using an inverted pyramid mechanism helps define and sort flags from its highest tier of grouped buckets (i.e. type of flag) to its lowest where detailed information is defined.

    Managing flags throughout their lifecycles avoids the incurred technical debt they create. By constantly monitoring flag usage, teams can establish hard deadlines to clean up flags in code. Technical debt management – and the cleanup process – is simplified by sorting through knowledge communicated in naming conventions (in reverse order they were performed).

    These processes should be defined by a strategic feature flag plan, set up to avoid flags’ technical debt. If followed diligently, teams can leverage the unrealized gains to drive product innovation and ensure processes will scale.

  • How to Disable Code

    How to Disable Code

    The following is a guest post written by Carlos Schults.

    Being able to disable code in production is a power that many developers aren’t aware of. And that’s a shame. The ability to switch off some portions—or even complete features—of the codebase can dramatically improve the software development process by allowing best practices that can shorten feedback cycles and increase the overall quality.

    So, that’s what this post will cover: the mechanisms you can use to perform this switching off, why they’re useful and how to get started. Let’s dig in.

    Why Would You Want to Disable Code?

    Before we take a deep dive into feature flags, explaining what they are and how they’re implemented, you might be asking: Why would people want to switch off some parts of their codebase? What’s the benefit of doing that?

    To answer these questions, we need to go back in time to take a look at how software was developed a couple of decades ago. Time for a history lesson!

    Production Switch2

    The Dark Ages: Integration Hell

    Historically, integration has been one of the toughest challenges for teams trying to develop software together.

    Picture several teams inside an organization, working separately for several months, each one developing its own feature. While the teams were working in complete isolation, their versions of the application were evolving in different directions. Now they need to converge again into a single, non conflicting version. This is a Herculean task.

    That’s what “integration hell” means: the struggle to merge versions of the same application that have been allowed to diverge for too long.

    Enter the Solution: Continuous Integration

    “If it hurts, do it more often.” What this saying means is that there are problems we postpone solving because doing so is hard. What you often find with these kinds of problems is that solving them more frequently, before they accumulate, is way less painful—or even trivial.

    So, how can you make integrations less painful? Integrate more often.

    That’s continuous integration (CI) in a nutshell: Have your developers integrate their work with a public shared repository, at the very least once a day. Have a server trigger a build and run the automated test suite every time someone integrates their work. That way, if there are problems, they’re exposed sooner rather than later.

    How to switch

    How to Handle Partially Completed Features

    One challenge that many teams struggle with in CI is how to deal with features that aren’t complete. If developers are merging their code to the mainline, that means that any developments that take more than one day to complete will have to be split into several parts.

    How can you avoid the customer accessing unfinished functionality? There are some trivial scenarios with similarly trivial solutions, but harder scenarios call for a different approach: the ability to switch off a part of the code completely.

    Feature Flags to the Rescue

    Defining Feature Flags

    There are many names for the mechanisms that allow developers to switch a portion of their code off and on. Some call them “feature toggles” or “kill switches.” But “feature flags” is the most popular name, so that’s what we’ll use for the remainder of this post. So, what are feature flags?

    Put simply, feature flags are techniques that allow teams to change the behavior of an application without modifying the code. In general, flags are used to prevent users from accessing and using the changes introduced by some piece of code, because they’re not adequate for production yet for a number of reasons.

    Disable Code: What Are the Use Cases?

    We’ll now cover some of the most common use cases for disabling code in production.

    Switching Off Unfinished Features

    As you’ve seen, one of the main use cases for feature flags is preventing users from accessing features that aren’t ready for use yet.

    That way, programmers developing features that are more complex and take a longer time to complete aren’t prevented from integrating their work often and benefiting from it.

    Enabling A/B Testing

    The adoption of feature flags enables the use of several valuable practices in the software development process, one of which is A/B testing.

    A/B testing is a user experience research technique that consists of comparing two versions of a website or application to decide which one to keep. It entails randomly splitting users into two groups, A and B, and then delivering a different version of the application to each group. One group might receive the current production version, which we call the “control,” whereas the second group would receive the candidate for the new version, called the “treatment.”

    The testers then monitor the behavior of both groups and determine which of the versions achieved better results.

    Feature flags are a practical way to enable A/B testing because they allow you to quickly and conveniently change between the control and treatment versions of your application.

    FeatureFlags KillSwitch 2

    Enabling Canary Releases

    If you deliver the new version of your app to your entire userbase at once, 100 percent of your users will be impacted if the release is bad in some way. What if you could gradually roll out the new version instead? You’d first deploy to a small subset of users, monitoring that group to detect issues. If something went wrong, you could roll it back. If everything looked fine, you could then gradually release the version for larger groups.

    That’s a canary release in a nutshell. It’s another powerful technique that feature flags might help with.

    Customizing Features According to Users’ Preferences

    It’s not uncommon to have to customize your application according to the needs of specific users, and there are several ways in which software teams can accomplish that—some more efficient, and others less so (companies that create separate branches or entire repositories for each client come to mind).

    This is another area where feature flags could help, allowing teams to dynamically switch between different versions of the same functionality.

    Disable Code in Production 101

    How do you go about disabling code? That’s what we’re going to see now, in three increasingly sophisticated phases.

    First Stage: The Most Basic Approach

    We start with an approach that’s so primitive, it maybe shouldn’t be considered a feature flag at all. Consider the pseudocode below:

    calculateAdditionalWorkHours(Employee employee, Date start, Date end) {

    // return calculateAdditionalWorkHoursSameOldWay(employee, start, end);

    return calculateAdditionalWorkHoursImproved(employee, start, end);

    }

    In the code above, we’re just commenting out the old version of some method and replacing it with a new version. When we want the older version to be used, we just do the opposite. (Well, I said it was primitive.) This approach lacks one of the most fundamental properties of a feature flag—the ability to change how the application behaves without changing its code.

    However, it plants the seed for more sophisticated approaches.

    Second Stage: Taking the Decision Out of the Code

    The previous approach didn’t allow developers to select the desired version of the feature without changing the code. Fortunately, that’s not so hard to do. First, we introduce a logical variable to determine which version we’re going to use:

    calculateAdditionalWorkHours(Employee employee, Date start, Date end) {


        var result = useNewCalculation

    ? calculateAdditionalWorkHoursImproved(employee, start, end)

    : calculateAdditionalWorkHoursSameOldWay(employee, start, end);


        return result;

    }

    Then, we use some mechanism to be able to assign the value to the variable from an external source. We could use a configuration file:

    var useNewCalculation = config[newCalculation];

    Passing arguments to the application might be another option. What matters is that we now have the ability to modify how the app behaves from the outside, which is a great step toward “true” feature flagging.

    Keep in mind that the code examples you see are all pseudocode. Using your favorite programming language, there’s nothing stopping you from starting with this approach and taking it up a notch. You could, for instance, use classes to represent the features and design patterns (e.g., factories) to avoid if statements.

    FeatureFlags KillSwitch

    Stage 3: Full-Fledged Feature Flag Management

    The previous approach might be enough when your application has only a small number of flags. But as that number grows, things start to become messy.

    First, you have the issue of technical debt. Manually implemented feature flags can create terribly confusing conditional flows in your codebase. That only grows worse with new flags being introduced each day. Additionally, they might make the code harder to understand and navigate, especially for more junior developers, which is an invitation for bugs.

    Another problem is that as the number of flags grows, it becomes more and more common to forget to delete old, obsolete ones.

    The main problem of a homegrown approach is that it doesn’t give you an easy way to see and manage all of your flags at once. That’s why our third and final stage is a single piece of advice: Instead of rolling out your own feature flags approach, adopt a third-party feature flag management system.

    Feature Flags Kill Switch 3

    Feature Flags Are a CI/CD Enabler

    We’ve covered the mechanisms developers can use to disable portions of their codebase in production without having to touch the code. This capability is powerful and enables techniques such as A/B testing and canary releases, which are all hallmarks of a modern, agile-based software development process.

    The names for the techniques might vary—feature flags, feature toggles, feature flipper, and so on. The way in which the techniques are implemented can also vary—from a humble if statement to sophisticated cloud-based solutions.

    But no matter what you call them, you can’t overstate the benefit these mechanisms offer. They’re an enabler of Continuous Integration, which is essential for any modern software organization that wants to stay afloat.

    Carlos Schults is a .NET software developer with experience in both desktop and web development, and he’s now trying his hand at mobile. He has a passion for writing clean and concise code, and he’s interested in practices that help you improve app health, such as code review, automated testing, and continuous build.


  • CloudBees Connect Virtual Summit: Defining the Future of Software Development

    CloudBees Connect Virtual Summit: Defining the Future of Software Development

    CloudBees Connect Virtual Summit will bring together a global community of developers, CloudBees and Jenkins users, DevOps luminaries and continuous delivery experts for two full days of immersive learning, presented in a virtual reality environment. The event is scheduled to take place on May 19 at 11 a.m. EDT for North America, and on May 20 at 11 a.m. CET for the European audience.

    At CloudBees Connect, you will learn about the emerging trends and technologies shaping the future of software, including one of the most innovative trends in technology: continuous delivery. Continuous delivery allows you to deliver software faster and with lower risk, while preserving quality and reliability.

    Industry leaders will share their knowledge and expertise on CI/CD tools and best practices. You will learn how to successfully create a fully operational CD pipeline using containers, Kubernetes and Jenkins X; and how to automate security and privacy testing in your Jenkins CI/CD pipeline for continuous security.

    The event will consist of a series of workshops designed to provide great value to the attendees. Here are a few things you will learn by attending these workshops:

    • How your COBOL source code can be branched/merged/deployed using GitHub, CloudBees and Compuware tooling.
    • Best practices for continuously integrating code using CloudBees Core.
    • How to build and test applications using Jenkins Pipelines and Sauce Labs.
    • Solutions for the five most common Jenkins issues.
    • The role of feature flags in reducing risks associated with deployments.

    The workshops will feature a lineup of DevOps and continuous delivery leaders, including:

    • Oscar Medina, developer advocate at CloudBees
    • Viktor Farcic, Jenkins X product manager, principal software delivery strategist and developer advocate at CloudBees
    • Josh Grant, solution architect at Sauce Labs
    • Robert Kelley, director of delivery engineering at IHG
    • Stuart Ashby, DevOps specialist at Compuware
    • Alex Taylor, DevOps engineer at insightsoftware

    Discover what’s next from the CloudBees and Jenkins community, connect with industry experts and fellow developers, and get the skills and hands-on training you need in order to successfully deliver software.

    To check out the agenda, the full lineup of speakers and to register (for free), visit the CloudBees Connect website.

  • Broadridge’s Annie Michelia on Why DevOps and the Cloud Go Hand-In-Hand

    Broadridge’s Annie Michelia on Why DevOps and the Cloud Go Hand-In-Hand

    Brian Dawson: Hello. Welcome to DevOps Radio, live at DevOps World | Jenkins World 2019. I have the pleasure of having a chance to interview Annie Michelia. She is a database architect at Broadridge, and really not just a database architect. As we talked and as I understand your bio, you actually have a wide range of skills and it appears that you do a lot there at Broadridge. Can you start by telling us a bit about what you do and about how you arrived there?

    Annie Michelia: Yes. By trade, I’m an Oracle DBA, to start with. So I’ve been working as a database administrator for most of my professional life. Right now in Broadridge, I work as an architect, in the sense, I work with on-premise database technologies as well as AWS cloud technologies. So I play a major role in cloud initiative projects for lift and shifts. So that’s when the DevOps kicked in.

    Brian: Okay. While you’re there, can you tell me a bit about DevOps at Broadridge? You mentioned DevOps kicked in. I’m curious to know where you guys are on your DevOps journey in terms of Broadridge, and why you guys are pursuing it?

    Annie: That’s a good question. So we in Broadridge have been using DevOps practices for more than five years now, successfully, to do all the application deployments, infrastructure deployments seamlessly. So the database was always standing in the backbench because of its complexity, not just complexity. Also, the thing is we handle mission-critical business data, which is persistent data, which we cannot touch and play around with.

    Brian: Your systems of record that need to be maintained can’t break, right.

    Annie: True. We are a financial solutions company. So for financial services, the criticality plays a very high role. So that’s why it has been staying aside. So when we started the initiatives for the cloud, the management decision was they said everything has to flow through automation, so no manual deploys, no manual installs. So we started this initiative just for the cloud piece, so for the database side.

    Brian: Okay.

    Annie: So what we thought is whatever we did manually in the past for databases needs to be automated, not just infrastructure, but also the ongoing deployments.

    Brian: The delivery and the deployment portion of it.

    Annie: Exactly. So all the schema changes, code changes and data changes, everything has to be in a no-touch environment. So that’s when we started practicing DevOps for database.

    Brian: So DevOps and cloud went hand-in-hand for Broadridge.

    Annie: Exactly, yeah.

    Brian: Okay. What drove the decision to go to the cloud? Do you know? Was it cost, speed?

    Annie: That’s one of the reasons, also the technology. So we evolved. We don’t want to be using the old technologies. The other reason could be cost, because of the licensing for the traditional enterprise DMS’s. So that’s why the organization has made a decision to do a lift and shift of most of the applications to cloud. So when we moved to the cloud, the decision was made that the environment should be zero-touch.

    Brian: Okay. I’m going to want to drill into, in a moment, lift and shift, which people have different opinions and it has different meanings, and also, some of the challenges of really integrating data and traditional relational databases into a CI pipeline. But before we do, I’d like to ask have you seen benefits of DevOps so far? Is Broadridge benefiting? Are customers benefiting? If so, how?

    Annie: When we thought of this automation for databases, it was really, really scary because we are dealing with critical data. So it was taking, actually, quite a time to understand and to convince the customers for the automation piece. But the whole point, if you look around the process itself, the manual process took a lot of time, but not just the time. The process, when you see it in manual, it actually involved multi-team participation. So not just the time, not just the human errors or something like that, it took multiple technical people from various teams to do a simple deployment process.

    Normally, the DBAs are doing – most of the time, the product – I’m sorry. Most of the time, the production support DBAs, who are hired to do production support, end up doing deployments all the time. We are a quite large company, so we have a lot of applications to support. So rather than doing the real production support work, the DBAs ended up doing deployments all day and weekends.

    Brian: And that’s at the cost of both the DBAs and potentially production support is now lacking, potentially, and not as responsive, right?

    Annie: True, yeah. When it comes to automation, one real big drawback is doing the manual setup of deployment. There is no traceability for what we deployed and where we deployed. Did we do it in a test environment? Was it successful? Are we ready to do it in production? Can we go forward? So there is no traceability, so that creates a big chaos.

    So when you break all this stuff into the DevOps automation, you have a version-controlled deployment. So there is a big traceability, and you know what you do in test, which can be promoted to production or not. So that’s the biggest advantage I see as a DBA over other constraints like time and other things.

    Brian: Right. You gain efficiencies.

    Annie: Efficiency, reliability.

    Brian: Visibility, traceability, which is huge. Now, I cannot claim by any means to be a database expert. I will share, I spent a bunch of years in the game industry as a software engineer/programming, and I didn’t quite get the importance of databases, the science behind it, the complexity. As I moved into the other phase of my career, more focused around enterprise development, and began to spend more time in traditional databases, I realized how complex it can be. Something I learned there is really in that space there are a lot of manual controls into place.

    Annie: True, yeah.

    Brian: A lot of responsibility put in the experts’ hands, because traceability was not really built into the database updates and migration process.

    Annie: That’s a little bit different. For a simple deployment, multiple teams are dependent on it and everybody ought to be on the spot for installation, validation, and then verification. So in this automation process, with a push of a button in Jenkins, that’s how we put it together. Any nontechnical person can run this. So there is not DB involvement. There is no one’s involvement, not a development involvement or a service delivery team’s involvement. Any nontechnical person can push a button from Jenkins, which can do all the magic.

    Brian: Okay.

    Annie: It retrieves the artifact from source control, extracts, makes a SQL connection, executes. Before execution, if there is a requirement for database backup, pre-deployment backup, advance into it, it takes the backup and runs the deployment, creates the log file, publishes the logs to all the interested parties.

    Brian: Awesome.

    Annie: Just the push of a button. So Jenkins does all the magic.

    Brian: I always love to hear Jenkins doing all of the magic.

    Annie: Yeah. That’s the only tool we are using for this automation.

    Brian: I’m going to want to dig into the hows of how you did this. Again, before we shift, I have a precursor question. Are you seeing customer or business benefit from this process? I think the internal benefit is immense. We talked about productivity, visibility, traceability. Is there error reduction? Is there reduction of failure rates that are bettering the service for the customer?

    Annie: Exactly. When we do the same thing manually, the errors may not be huge or quantifiable, but the impact of even one error is huge because we are in the financial industry.

    Brian: Yes, right. It could be millions, billions of dollar error, one error in data.

    Annie: Exactly. So we are fined with the _____, so we’ll be fined or penalized. The penalty is really huge for a single mistake in a year. So we completely eradicated the incidents. That’s a bigger achievement I could see.

    Brian: So the DevOps automation provided more reliability, safety, and security for your customers.

    Annie: Yes.

    Brian: I bet if we were to measure blood pressure, it probably also lowered blood pressure for the DBAs and team members.

    Annie: That is true, yeah.

    Brian: So let’s talk a bit about the technical implementation. Look, I’ll admit that oftentimes when we talk about DevOps and how to implement DevOps, there are some rough edges and some difficult areas that oftentimes the luminaries, evangelists, speakers tend to sort of gloss over. Security is one of those that isn’t fully integrated. Oftentimes, it’s difficult. Management of environments has improved considerably. But data is one that I think people still struggle with.

    Now, you guys chose to lift and shift. What I’ve seen a lot of greenfield teams do is sort of move directly to cloud technology, move directly to NoSQL databases, possibly do some level of ETL, but largely say, “We’re going to take our traditional data store and leave it behind because it’s so difficult.” You guys chose to lift and shift and bring along the data in the databases that you had invested in, correct?

    Annie: Correct.

    Brian: It sounds like it was challenging.

    Annie: It’s a challenge, but when you look at the organization’s perspective, the total infrastructure maintenance cost is completely removed or eradicated. So the technical people can spend more of their time on architecting things, rather than sitting and supporting things, the traditional work. So it’s just we are losing the job, but the nature of the job has been elevated.

    Brian: Right. You can focus on things that matter.

    Annie: Yeah.

    Brian: Can you share with me –? We talked a bit about some of the technical difficulties. Maybe you can take me on a journey. Tell me a bit about what the solution looks like at Broadridge, for integrating first your traditional relational databases into CI/CD. And what are the solutions? What challenge did you run into? How did you implement it? We’d love to understand some more of the details.

    Annie: Okay. We just use two tools to do this. One is for the source control, GitLab. So we just tell the developers to check in their code in GitLab. And when it’s ready for deployment and when it converts to an artifact, then the process can kick in. So a nontechnical person will run this build from Jenkins. So this is the whole point.

    The first and very – difficulty, I would say, is the understanding. The whole Jenkins is integrated with the other tools, like GitLab or Nexus or any other tool. So that was a challenging thing for me.

    We really need to understand how they can talk to each other, with what credentials. So that’s the starting point. So, luckily, our DevOps team has a very good standardized process. So they have created service accounts for each technology, for each build. So those cannot be shared. The password cannot be given to the individuals.

    So the service accounts can talk to the other tools, the other DevOps tools. It could be GitLab or Nexus or whatever. So that’s the first challenge from my side.

    Brian: And do you use credential management in Jenkins for this?

    Annie: Yeah. We have credentials created in Jenkins itself, which is highly encrypted. So Jenkins uses the credential file to talk to the other tools.

    Brian: Talk and execute the automation or orchestrate.

    Annie: Exactly. The same applies for the database credentials as well. In our setup, as I said before, when you click the button, the system downloads the artifact, makes SQL connections. It’s how it’s going to make the connection. So it needs credentials.

    So we instruct the developers to submit a configuration file for us, which just had the connection information, nothing more than that. So what is your target server name, target DB name? Which object do you want to backup or do you want to skip the backup? So it’s like a ten-line config file. They just need to say yes or no or they need to fill the right-hand side.

    So we just give them the template. So they are just going to fill the right-hand side of the config file. So there they give us all the connection information, but the credentials are managed by DBAs. So we create the user name and password in the credentials file to make the connections.

    Brian: Okay. And then they are submitting – to stay in the technical implementation level for a bit, the developers, one, I notice you’re shifting left. They’re empowered to deliver at a speed that they need to deliver versus filling out a ticket, having a phone call, crafting an email. You guys are empowered as the DBA or the database team to focus on higher order, higher level issues. So there’s a lot of benefit there.

    Now, I’m curious. Was it a shift for the developers? Are the developers directly submitting SQL or DDL?

    Annie: No. They’re not allowed to. The Jenkins setup is like we have non-prod and prod server setup. In non-prod, the developers can play around with it, like in a development environment. So they can submit a sample artifact, and they can just try to run the code – sorry – Jenkins job to understand how it works. That’s all they can do. Then when the artifact is ready to be promoted for the higher environments, they can’t touch anything. So there is a different promotion process we have on the DevOps team.

    Brian: Okay. I was curious about that. Right.

    Annie: The DevOps team actually has a process. They call it a promote artifact process. So even they can’t do anything about it. Once they say the code is tested in development, the process kicks in that promotes the artifact to a different source repository. So after that, they have no luxury to go and change the code. So that’s done. So when you test something in development, that is going to production. So that’s the word I use, traceability, right.

    Brian: Right, and it’s similar to retrieving application artifacts and the value of binary repositories, which is build once and promote.

    Annie: That’s it, yeah. I wouldn’t say it’s continuous delivery, but we are targeting that continuous delivery. What I understood is when you push a button for development, when it completes, it goes to QA prod. So that’s what continuous delivery, what I understood so far. So that is not actually in place, because that is actually handled, coordinated within teams, because there is a different change control process.

    Brian: Right. So there’s manual intervention. You’re automating, but your automation has to work with existing change control processes.

    Annie: Exactly, yeah.

    Brian: And in reality, when we’re dealing with data in a financial institution, those change control or change management processes are likely going to stay.

    Annie: Exactly.

    Brian: It’s not practical or not –

    Annie: Yeah. We have a governance team to approve the change for production. So that’s when there is an intervention. But even there is a manual … that’s like a release management flow. So that flows automatically. Then when it’s ready to go, the button can be pushed for prod. So CI in place, CD on the way.

    Brian: Right. CI in place, CD with manual gates is in place.

    Annie: Exactly. That’s the right word.

    Brian: People get on themselves. I speak to many organizations, “Well, we haven’t implementing continuous delivery.” I maintain that at the end of the day that there’s objectives for higher quality, optimization of effort, and increased velocity. If you can do that while still maintaining your manual checks, well, you’ve achieved your goal. It might not be pure continuous delivery. Maybe you guys will get there one day, but –

    Annie: Exactly. I don’t believe in this CI/CD.

    Brian: There’s a place for it at Broadridge today. But that’s where the DevOps comes in. I’m curious. Alignment is always a struggle, right. So this, yes, you still have governance in place. These changing systems, cloud, DevOps and automation must have changed the way you work and have had sort of some cultural implications.

    What did Broadridge do to get teams aligned, to get everybody sort of shifting into this new way of working?

    Annie: Right now in Broadridge, every week have center of practice conferences, where we educate people to understand the existing model. Then we tell them how to onboard themselves into this process. So we educate them.

    We have Confluence pages created for them. So we publish periodically. Then in every COP and COE meeting, which is conducted by the DevOps team, they invite us as a guest, as a speaker, to tell them how any team can get into this process. So every day we get customers. That’s how I would say it.

    So we have multiple application teams. After each and every meeting, we would get five to ten emails saying, “Hey, I want to jump into this process.” Even this morning I got an e-mail. I’m out of the office. I got an e-mail saying, “Hey, I want to jump into the process.” I said, “I’ll give you a demo by next week.” So that’s how it goes.

    So people are interested to come. Even though they know the criticality, but they love the process because it eradicates the manual time and errors completely. So that’s a big thing they look at.

    Brian: Would you say that marketing – so you’re getting people aligned by taking a service approach. I heard you use the words, “We’re getting customers every day.”

    Annie: Yeah, that’s what I feel. I belong to the shared services group from the technology solutions team. So we provide solutions to the teams. That’s our goal, so I see them as a customer.

    Brian: Okay. Like a business that’s customer-facing, it sounds like there’s education and awareness. There’s training and marketing.

    Annie: Yep. That’s what we do every week.

    Brian: Continual training and marketing has let to alignment and adoption. And how important was it that you show success? What I’m also gathering is as part of this, you’re positioning what the benefits are of adopting your service. Right?

    Annie: Mm-hmm.

    Brian: I guess I’d ask how important to the growth has it been that you guys transparently share your successes and possibly even some of your struggles and failures?

    Annie: Normally, after we present the first framework, we get a lot of suggestions from the application teams. So I took this very positively. They actually told me, “Hey, your interface could look like this, man. It could look prettier.” I agreed to it because I was only focusing on the logic of the implementation, not the interface look itself. But when it comes from the development teams, they are already well-versed in programming.

    So they tell me, “You could change this. You could modify this. You could put less parameters.” So I adopted those things. So it’s not just a one-way knowledge-share. It’s like a two-way understanding, yeah.

    Brian: Awesome. I’d say for our listeners as well as you, when I hear you talk about creating a baseline, communicating that and getting the feedback from the developers, it very much aligns with software delivery management messaging you’re going to hear at the keynote at CloudBees today, and this concept of not just automating, but continuously improving, so you can get stuff out there, get feedback, and make it better.

    Annie: Better, yeah.

    Brian: So yeah, look at SDM. I hear a bit of your experience being similar. I.e., it’s not just business to customer. It’s also internal critical systems, where you can bring these to bear.

    So can you tell me, in terms of security and compliance, and you’ve touched a bit upon this in terms of data, but the security and compliance, as you stated, is tantamount, is critical in financial institutions. How do you guys leverage DevOps to help ensure audit and compliance, and help ensure that you’re achieving your security and compliance goals at Broadridge?

    Annie: Basically, first and foremost, I would say the source control artifact. That is the first level in auditing and security. So if you want to go back and see, you have a service ticket with a version control artifact. So you know what was installed, on which date, on which server. That is so helpful for auditing purposes.

    Brian: Okay.

    Annie: So for the security purpose as well, since the credentials are managed locally in Jenkins as an encrypted file, it is very secure and it’s not –

    Brian: Centralized secure –

    Annie: A centralized place, so that it’s not being shared with multiple teams or multiple people. Normally, DBAs hold the credentials, but now, no one is holding any credentials. So once it’s created, it’s stored. That’s it. It works very well.

    Brian: Awesome. Thank you. Now I’m curious. I’m going to ask a couple of sort of fun questions, but questions we also like to help inform our audience about who our guests are. So one of those is who is your favorite DevOps superhero and why?

    Annie: I would pick someone from my company. I’m sorry. I’m being selfish. Daniel Ritchie I would say.

    Brian: Daniel Ritchie.

    Annie: Yeah. He’s the man who introduced DevOps to me. Because when I had an interest, I approached him. Everyone in my company said Daniel is the go-to guy. So I approached him. He spent quite a few hours with me, explained about the DevOps CI/CD process. That actually impressed me to do this framework. So I would say he’s my hero.

    Brian: So let’s dig into – Daniel or Danny?

    Annie: Daniel Ritchie.

    Brian: Daniel Ritchie. Thank you, Daniel, and hello, Daniel. So what’s Daniel’s role at Broadridge?

    Annie: He’s a DevOps architect at Broadridge, and he has been wonders for the past five or six years.

    Brian: Awesome. I also noticed this loop here of there’s curiosity. There’s someone that has some experience and expertise. They service the curiosity with that. So it’s sharing and training. People marketed Daniel to you, to be able to go find him. Then now, you’re doing the same, to spread the word within your company.

    Annie: Yeah, true.

    Brian: So yeah, it’s awesome and I love how it underscores that at the end of the day, while there may be top-down components to DevOps improvements, at the end of the day, DevOps is really about sharing, collaboration, and community. I think what you’ve shared with us has demonstrated that.

    Annie: Thank you.

    Brian: So to shift, I like to ask guests to share what we call a dev-oops moment. And that’s not D-E-V-O-P-S, but rather D-E-V-O-O-O-P-S. That’s a moment where either dangerously, precariously or humorously something went wrong and you learned from it. Do you have a dev-oops moment that you can share with us?

    Annie: Yeah. When I was initially developing the framework, I didn’t know how to mask the password in Python script, because I’m not a developer. So when I ran the build, I saw the password displayed on the console output. It was like, “Oops.” I was like –

    Brian: And now you’re like, “How do I get rid of it? Where are the logs?”

    Annie: Then I went back to the CloudBees, how to wrap the password. Then I found the syntax, came back and had –

    [Crosstalk]

    Brian: Shhh. Nobody tell anybody.

    Annie: Yeah. So that was an embarrassing moment for me, but that was just with me, so I just canceled the build.

    Brian: That’s good to know. I’ll tell you. I have had something similar happen. I don’t think it was in a critical environment, but I didn’t catch it right away. So that meant that I’m SSH into servers, combing through logs, trying to figure out everywhere where this unmasked password would have leaked.

    So thank you for sharing that. That’s why those DevOps moments are important. And in that, you said you were able to go to CloudBees and they explained it.

    Annie: Yeah.

    Brian: Do you happen to recall how you masked it?

    Annie: I saw some blocks, block spots, and those guys were really good. So I just posted a question and I got an answer instantly. Yeah, within like a few minutes I got an answer, with syntax, so I could wrap like this. They gave some examples.

    Brian: Then on interpretation and complexity it’ll obfuscate it.

    Annie: I just used it for my thing and then I went back and learned.

    Brian: Also a lesson about testing locally first, right, before it went into the pipeline.

    Annie: Exactly.

    Brian: Awesome. Do you have any final thoughts that you’d like to share with us, in addition to the experience and knowledge you’ve already provided, any final words for the listeners?

    Annie: No. I’m so glad that I’m here to share my experience about the framework we have. I’m so happy to be here.

    Brian: Awesome. I’m going to poke and prod you a little more. Now that you’re at DevOps World/Jenkins World, was this your first one or have you –?

    Annie: Yeah, very first one.

    Brian: Okay. What are you looking forward to getting out of it?

    Annie: I would like to know about the things which I do not know so far, because my level of DevOps is very limited. So I would like to know how I can improvise my framework with the available sources. So I looked into the topics and they were so interesting.

    Brian:Awesome, great. I’m pretty convinced that in terms of better understanding CI/CD, DevOps and what you can do in particular to do it, to apply it within and enterprise, you will learn more here. I’d love to hear from you, if I see you again later in the show. I’d love to hear from you how your experience has been and what you’ve learned.

    Annie: Thank you so much.

    Brian: All right. Thank you, Annie.

  • Autodesk Builds Better Software Faster with CloudBees Core

    Autodesk Builds Better Software Faster with CloudBees Core

    Autodesk Builds Better Software Faster with CloudBees Core

    Autodesk embraces DevOps, CI & CD to strengthen its competitive market position and deliver higher quality software and features to its customers even faster.

     I am convinced that we could not have done this without CloudBees. 
    George Swan
    Senior Director, Build Platform
    [su_youtube url=”https://www.youtube.com/watch?v=1gwHCV_njDg&feature=youtu.be”]
  • Whitepaper – Easily Build Continuous Delivery Pipelines with Jenkins and Pipeline Plugin

    Whitepaper – Easily Build Continuous Delivery Pipelines with Jenkins and Pipeline Plugin

    Easily-Build-Continuous-Delivery-Pipelines-with-Jenkins-and-Pipeline-Plugin

    Organizations have been orchestrating pipelines with Jenkins for years. As Jenkins and continuous delivery experience deepens, organizations want to move beyond simple pipelines and chart complex flows that map to their specific software delivery processes. For Jenkins users, creating and managing complex pipelines just became easier with Jenkins and the Jenkins Pipeline plugin. Learn what it is, what it does for you, and how to set up your delivery pipelines using it.

    Download this whitepaper and learn how you can deliver software at the speed of ideas.

    [su_button url=”https://www.cloudbees.com/resource/whitepaper/easily-build-continuous-delivery-pipelines-jenkins-and-pipeline-plugin” target=”blank” background=”#ef2d3f”]Download Now[/su_button]

  • 8 CI/CD Best Practices for Your DevOps Journey

    8 CI/CD Best Practices for Your DevOps Journey

    According to a recent IDC study, the worldwide DevOps software market reached $2.9 billion in 2017 and is forecasted to reach $6.6 billion in 2022. With over 50% of organizations embracing DevOps last year, continuous integration (CI) and continuous delivery (CD) have become an integral part of the software development process.

    Your business is likely embarking on a DevOps transformation of its own. In this blog post, we will discuss CI/CD best practices that can help accelerate adoption no matter where you are in your DevOps journey.

    But first, let’s take a step back and set the stage for why we practice DevOps in the first place.

    Shifting left with CI/CD and the promise of continuous everything

    Continuous integration and continuous delivery refers to the process of developing and delivering software in short cycles of build-configure-deploy-test-release underpinned by automation. In short, we do CI/CD to deliver higher-quality software frequently and predictably.

    CI has become practically ubiquitous to software development. Therefore it is not surprise that as the bread and butter of development, CI is a key practice in DevOps organizations.

    CD is not as widely adopted as CI, but is key to shifting left. CD starts with development, building, unit testing, static code analysis (SCA) and static analysis security testing (SAST) on CI. Eventually, the pipeline extends the automation to functional, integration, performance and security testing, along with configuration management and deployment. These are critical areas for automation — and in a DevOps context they are essential.

    I would even make the jump and say that if you aren’t doing CD, you aren’t doing DevOps well. Why? Because traditional IT operations don’t get involved until AFTER deployment into production – when real users begin hitting the application. How can you expect IT operations to shift left and embrace a culture of DevOps if there is a giant, unautomated chasm in your software delivery pipeline? Asking them to shift left in this context is paramount to asking them to jump of a cliff. If you are doing CI alone, you are likely sole inhabitants of ‘Developer Island’. It might be sunny there, but you are decidedly alone and separate from the rest of the business.

    I know what you’re thinking. This all makes great sense, so why isn’t the CD pipeline automation the norm? The answer is simple… this stuff can be hard and transformation doesn’t happen overnight. It usually begins on the left with CI and as the DevOps initiative matures, CD is the next logical step. It’s certainly not serial out of necessity, but this is the adoption pattern we often see.

    In fact, I have news. Not only does your DevOps transformation not happen overnight, it’s never over. This is all about continuous improvement, which means nothing sits still. There isn’t a DevOps train that terminates at the end of the line. The minute you’ve mastered these best practices, new ones will emerge because every day we as a community get better at delivering software.

    Which brings me to the topic of shift left and continuous everything! When you have both CI and CD pipeline automation in place, you are in a fantastic position from a tools perspective to shift left. This is a perspective shift from problem detection to prevention which means testing earlier, and earlier – effectively shortening test cycle times while preserving code quality. The result? Better software, delivered more quickly that shortens the feedback loop between end users and developers.

    But shifting left isn’t just about tools. It’s also about people and practices – the proverbial DevOps trinity. It means everybody has a stake in the reliable, repeatable delivery of high value software. It means that the documentation team joins the engineering team when stories are being picked for a release. It means that product marketing comes to that same meeting with research on the market opportunity for such a feature. It means that product managers sit on analyst inquiry calls with the analyst relations team. It means that passionate customers beta test features and give meaningful feedback that can be immediately acted upon. It means that before a feature is even released, sales is trained, primed and ready to do pipeline generation. It means DevOps is at the very heart of the business and every function from marketing, to sales to support and services is totally informed and invested from ideation onward. No more chucking features over the wall. No more islands. No more excuses. That’s continuous everything.

    Effective and comprehensive measurement and monitoring

    So you’ve got a CI/CD strategy. You’re shifting left. Now what? A critical – and often overlooked step in DevOps transformation is measurement. It’s time to take credit for how increasingly amazing you are doing! (or understand where you are falling short, DevOps is about honestly accepting and addressing failure or in efficiencies…together). You need visibility in order to know which lever to pull next in your path to continuous improvement. You’re delivering code faster than ever! But how’s the quality? Is it failing tests? Is it unstable in production? How much rework is required? You won’t know if you don’t track it. Implementing and measuring the success of the best practices in DevOps is crucial if you wish to make your automation cycle faster over time. If, like many, you jumped headlong into your DevOps journey without putting monitoring in place – it’s not too late. Consider keeping track of the deployment frequency, change lead time, change success/failure rate, mean time to recovery (MTTR), and the rate of security tests passes in your organization to stay on top of your DevOps transformation.

    8 CI/CD Best Practices to get you started in DevOps

    1. Take a ‘security first approach’

    It’s not possible to overemphasize the need for security in a world where breaches and vulnerabilities continue to cause massive reputation and financial losses to businesses of all sizes and capabilities. Since the CI/CD system offers access to your codebase and credentials to deploy in various environments, it is often the prime target. Recall the infamous Uber breach where hackers gained access to AWS credentials that were embedded in the GitHub software repository – stealing the personal information of 57 million users and 600,000 drivers. Uber then paid to cover it up, but that’s a different story. It’s certainly not uncommon for credentials to be stored in private repositories for automation purposes. Therefore, you should consider isolating your CI/CD systems, placing them in secure internal networks. VPNs, strong two-factor authentication and identity and access management systems will help you enforce ‘the principle of least privilege’ and restrict exposure to threats. For example, containerize your agents and place them on secure networks. In addition, you should also ensure that security is baked into the development process from start to finish. This is commonly known as DevSecOps.

    2. Assess your organization’s readiness to utilize a  microservices architecture

    For effective implementation of DevOps, a microservices architecture is the best way forward. However, re-architecting your existing applications can be a daunting task, and you may consider an incremental approach where you maintain your mission-critical systems and weave the new architecture around it. This will help you gradually replace the old system with the new architecture.

    3. Implement tracking and version control tools

    Tools like Jira and Bugzilla can help you achieve better visibility into the progress of your software and collaborate easily with distributed teams. You will also need a version control system like Git, which creates a ‘single source of truth’ for your team, allows tracking of changes in the code-base, and is a life-saver whenever a rollback is required. By enabling the teams to collaborate and integrate changes into the shared repository, GitOps can significantly improve your MTTR.

    4. Commit daily, reduce branching

    The goal of reducing (or even gasp… eliminating) branching is to spend more time on development and less time on version control. However, to make the most of GitOps, developers are expected to commit directly to the main branch or merge changes from their local branches in at least once a day. This will force developers to deal with smaller, bite-size bits of integration pain instead of the massive integration pain (and associated rework) that happens when attempting to merge many branches into the trunk just before release.

    5. Build only once

    Eliminate any practices where source code is built multiple times. Even if the software has to be built, packaged, or bundled, you should execute that step only once and promote your binaries. Most successful CI implementations include the build process as the first step in the CI/CD cycle to package the software in a clean environment. This eliminates oversights and reduces the chance for errors to be introduced and/or missed anytime later. Further, the resulting artifact should be versioned and uploaded to Git each time so that whenever it is pulled the build does not change.

    6. Decide which processes and tests to automate first

    While an incremental approach to automation sounds good, organizations transitioning from manual to automated processes often find it difficult to decide which processes to automate first. For example, it is beneficial to automate the process for compiling the code first. As developers need to commit code on a daily basis, it makes sense to do automated smoke tests. Unit tests are usually automated first to reduce the workload on developers.

    Consequently, you can automate functional testing, followed by UI testing. Functional tests do not usually require frequent updates in the automation script, unlike UI tests which have more frequent  changes. The main idea is to think about all possible dependencies and evaluate their impact to prioritize automation sensibly.

    7. Release often

    Frequent releases are only possible if the software is in a release-ready state and you have tested it in a production-like environment. That’s why the best practice is to add a deployment stage which closely resembles the production environment before the release. Some release best practices include:

    • Canary deployment. Releasing to a subset of users, testing with that base and rolling it out to the wider population if successful (or rolling it back for iteration if it’s not).

    • Blue green deployment. You begin with two identical production environments. One is live in production. The other is idle. When a new release is rolled out the changes are pushed to the idle environment. Then they switch – the environment containing the new release becomes the live environment. If something goes wrong, you can immediately roll back to the other environment (the one that does not contain the new release). If all is well – the environments are brought to parity once more.

    • A/B Testing. A/B testing is similar in flavor to – but not to be confused with- blue green deployments. A/B testing is a way of testing features within the application for things like usability. The better performing variant of the feature wins. This is not a release methodology.

    8. Use on-demand testing environments

    You should consider running tests in containers as this approach allows the quality assurance team to reduce the number of environment variables and changes present between the development and production environments. The primary advantage of using such ephemeral testing environments is that they add agility to your CI/CD cycle. The QA team does not have to pull a build from a CI server and install it in a separate testing environment; instead, it can run tests against a container image. It is much easier to spin up containers (they have no separate installation or configuration requirement) and also destroy them when not needed.

    Where to begin?

    The primary goal of DevOps or CI/CD best practices is to automate the process of building, testing and releasing software. This means you will need access to DevOps tools that help you simplify automation as well as get better visibility into the progress of your software. Further, there should be a mechanism to track DevOps performance metrics throughout the software delivery lifecycle and raise alerts for quick recovery when something goes wrong in release or deployment.

    Deciding which DevOps tools to implement and where to invest first can cause “analysis paralysis” – even in organizations that have been working through their DevOps transformation for some time. You can avoid getting stuck in a similar position and jumpstart your DevOps transformation with the CloudBees Starter Kit. Learn more about this starter kit here.

    Additional resources