Category: IT as Code

  • Akamai Brings Web Application and API Security Together

    Akamai Brings Web Application and API Security Together

    Akamai Technologies, Inc. this week launched a service that consolidates the process of securing both web applications and application programming interfaces (APIs).

    Amol Mathur, vice president of product management and strategy for Akamai, said with the launch of App & API Protector the managed security services provider is making it easier for IT teams to embrace DevSecOps best practices via a converged web application and API (WAAP) service rather than using separate tools and services to secure them individually.

    The service is also designed to continuously discover API requests that are then automatically inspected for malicious code. Optional API security controls can be enforced based on policies defined by internal IT teams.

    In addition, the company provides access to a multidimensional threat scoring model, dubbed Adaptive, that combines data collected by Akamai with data and metadata from each web and API request to help organizations better understand which threats require immediate attention. Security events are also continuously analyzed using machine learning algorithms to deliver highly accurate policy-by-policy tuning recommendations that can be implemented via a single click.

    Akamai security researchers also make use of machine learning and data mining techniques to continuously analyze over 303TB of daily attack data that is used to automatically update protections. Alternatively, organizations can opt to manually evaluate that data themselves to minimize any unexpected impacts those updates might have on their applications.

    Other capabilities include built-in bot mitigation tools that are informed by a directory of more than 1,500 known bots, integrations with the Akamai command-line interface (CLI), Terraform or scripts used to drive automated pipelines spanning a continuous integration/continuous delivery (CI/CD) platform.

    Akamai

    A recent report published by Akamai found that between January 2020 and June 2021 there were more than 11 billion total attempted attacks made over an 18-month period. The most common attack vector was SQL injection (SQLi) at 6 billion attacks, followed by local file inclusion (LFI) with 3.3 billion attacks and cross-site scripting (XSS) with 1.019 billion attacks.

    The report also found credential stuffing attacks reached more than one billion attacks and peaked between January 2021 and May 2021. Distributed denial-of-service (DDoS) attacks reached a peak of 90 in January of 2021.

    Akamai has been making a case for outsourcing the management of web application and API security via the content delivery network (CDN) it created. Its CDN provides a layer of isolation between web-facing applications and the rest of the enterprise. The challenge organizations now routinely face is that, as they move to deploy cloud-native applications based on microservices, responsibility for security has become more decentralized. The security services provided by Akamai create an opportunity to better manage application security via a single pane of glass at a time when there is more focus than ever on securing software supply chains, said Mathur.

    It’s not clear to what degree organizations are going to rely more on managed security services as part of a larger effort to embrace DevSecOps best practices. However, at a time when application security expertise is hard to come by, it’s becoming apparent that, in many instances, relying on an external service provider to secure application environments is the simplest way to quickly improve the overall security posture of any organization.

  • Data Theorem Adds Runtime Protection Enabled by Observability

    Data Theorem Adds Runtime Protection Enabled by Observability

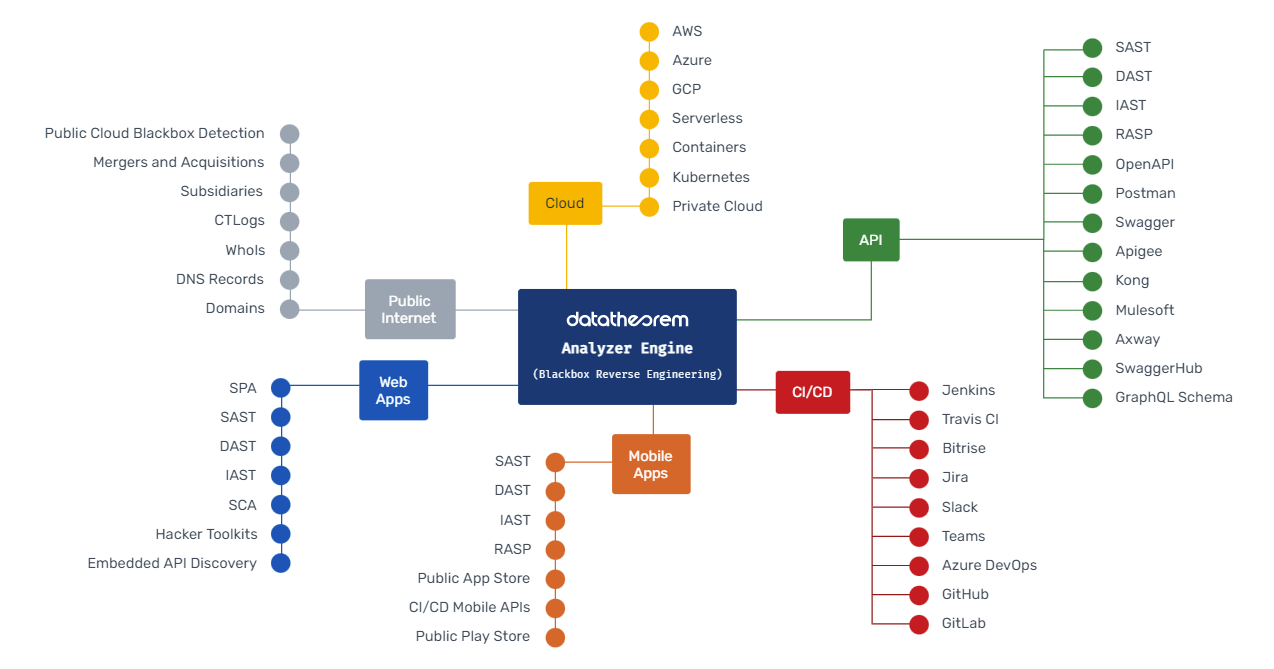
    Data Theorem, Inc. this week added an Active Protection offering to its portfolio of application security services that makes it possible for DevOps teams to embed observability and runtime defenses in their applications via a software development kit (SDK).

    The Data Theorem cloud services are based on Trustkit, an open source framework the company created to make it easier to employ secure socket layer (SSL) to encrypt connections and Analyzer Engine, its runtime analytics engine.

    The company is now extending its services to make it possible to embed observability capabilities by collecting logs and traces. Those logs and traces are then used to enforce runtime security policies that protect applications from known attacks from malicious sources and other common attack vectors as defined by the Open Web Application Security Project (OWASP) Foundation. It also prevents violations of encryption levels, authentication types and authorization rules along with a variety of custom rule checks, including preventing broken object-level authorization (BOLA) attacks.

    Doug Dooley, Data Theorem COO, said Active Protection can be applied across any application stack, including microservices applications based on cloud-native frameworks. In contrast, existing approaches to securing application runtimes based on web application firewalls (WAFs), runtime application self-protection (RASPs) or endpoint detection and response (EDR) agents cannot be applied to cloud-native applications based on containers and serverless computing frameworks.

    Active Protection solves that issue because it is designed to be applied via the Data Theorem software development kit (SDK) or using application extensions made available via a serverless computing framework or as a container sidecar.

    Dooley noted that the Active Protection service is also designed to be fully integrated with DevSecOps workflows that are increasingly being driven via continuous integration/continuous delivery (CI/CD) platforms to enable continuous, automated security inspection and remediation. The company claims to have detected more than one billion application incidents and is currently used by more than 8,000 applications.

    Developers don’t generally set out to build and deploy insecure applications. The issue is most developers don’t have a lot of security expertise, so it’s easy for mistakes to be made. Organizations looking to embrace DevSecOps best practices need to find a way to achieve that goal in a way that developers can easily embrace. The more automated the checks for security issues become during the application development process, the more likely it is developers will make additional efforts to remediate vulnerabilities long before an application is ever deployed in a production environment. In effect, DevSecOps is easier to achieve when addressed from the bottom up rather than via an edict from above without any real implementation plan in place.

    It’s still early days as far as DevSecOps is concerned, but as best practices for DevOps continue to evolve, there may come a day when security is just another gate that needs to be passed within the context of a larger DevOps workflow. In the meantime, DevOps teams and cybersecurity teams should put aside their differences and work together as the number of attacks launched against applications increases.

  • 4 Strategies to Manage Freelancers with In-House Dev Teams

    4 Strategies to Manage Freelancers with In-House Dev Teams

    Remote workers are a growing segment of the global workforce. Freelancers account for a big part of that segment, especially when development teams need to bring in specialized skillsets for upcoming projects. Working with freelancers offers many benefits, but there can also be challenges when integrating freelancers with in-house teams.

    Here are four strategies to help in-house developers effectively manage freelancers in their development teams:

    1.    Keep Remote Workers in the Loop

    Don’t leave freelancers and remote workers in the dark about your overall business direction and goals. If a freelancer is only joining the team temporarily to handle one part of a project, it might not seem necessary to give them the full details about the project’s goals and the reasons behind your decisions.

    However, providing this information enables every member of the team to fully understand what you need from the products and features they are working on and how they will serve the end user. It also helps to create common goals and motivations that the team can work toward together, rather than keeping your remote workers’ tasks separate from other members of the development team.

    2.    Make Consistent Feedback a Priority

    In an OfficeVibe survey, 96% of employees said they wanted to get regular feedback from their managers, but 32% said they receive feedback less than once every three months. Freelancers and remote workers arguably need more feedback than in-office employees, for several reasons.

    Freelancers and remote workers are often less exposed to the wider business context in which they are developing products and features. This can make it harder to assess and optimize their output from the viewpoint of an end user. Just as importantly, it can make it less clear what the other members of the team are working on and how their output affects their colleagues’ work.

    “Without consistent feedback, even the most talented developers in a team can invest a lot of time in a non-feasible solution. An ongoing feedback loop is one of the best ways to support a team and enable them to put their skills to use,” said Irene Avdus, a product manager at TextMagic, which has offices in multiple countries and which regularly brings on freelance talent.

    Giving freelancers and remote workers consistent and regular feedback doesn’t just help them improve their output for a better end result. It also helps them to fit in with the workflow of the rest of the team, enabling the project to go more smoothly for everyone.

    3.    Provide Growth Opportunities

    “Great leaders invest in their employee’s career development and steer them from being a one-trick pony,” said Phidelia Johnson, Pac-J Investment Services executive director of HR.

    When it comes to upgrading a team’s skillset, companies tend to skip over freelancers and remote workers in favor of employees they see as more permanent. However, opportunities to develop skills and advance their career are just as important to remote workers and freelancers as they are to any other employee.

    As a result, the perception of remote workers and freelancers as more temporary team members can be a bit of a self-fulfilling prophecy. When companies don’t invest in developing employees’ skills outside of their in-house teams, it is to be expected that remote workers will move on after the project is done to advance their careers.

    Often, treating remote workers as temporary doesn’t result in any less training, anyway. Whenever you add a new freelancer to your development team, there will be a certain amount of training and onboarding necessary to get them up to speed with how your team works. In fact, this can often be a major time and resources investment

    “In a lot of situations, the biggest challenge of working in data engineering or BI is not learning technology X or Y—it is being able to pick up quickly all the business rules and processes of the department you are building your pipeline or dashboard for,” said Mohamed Khalil Ouachikh, ArmedAngels data engineer and BI specialist.

    Rather than spending time onboarding new remote workers with each development cycle, investing in upgrading and expanding the skills of current team members and freelancers can result in a more capable team that is already familiar and comfortable with your business and the needs of your clients.

    4.    Informal Team Meetings

    Making people feel like part of a team is important to ensure they can collaborate and coordinate effectively with other members. Both of these factors are crucial to developing any successful product.

    Why is this relevant to managing freelancers in your development team?

    Remote workers don’t have the same opportunities to connect with colleagues as in-house employees unless you provide them. As many as 20% of remote workers say they feel isolated from their colleagues. This can take a toll on their emotional well-being, and that lack of social connection to coworkers will also affect their ability to collaborate.

     As a result, they may not be able to communicate as effectively with other team members. Building connections between team members let them understand each other more easily and reduce miscommunications that could lead to development mistakes and delays.

    Informal meetings via webinar platforms or video conferencing solutions can have a significant positive impact in this area. A weekly meeting gives everyone a chance to talk about what they are working on and their challenges. As a result, every team member, including freelancers, has the chance to lend their skills to a colleague’s work and help the team pull together toward achieving a common goal.

    Just as importantly, it gives remote workers a much-needed opportunity to connect with their colleagues socially and chat about things other than work. Besides the importance of team-building, this develops more of a connection between remote workers and your business. Inviting freelance developers to all meetings and social events is a great way to ensure greater inclusivity, and it can pay off if freelancers later take full-time positions at the company.

    Make Freelancers Part of the Team

    Keeping freelancers in the loop and ensuring they have the same opportunities and voice as other employees ensure they have the same level of investment in a project’s success as every other member of the team. The tools and the opportunity to coordinate with colleagues and receive feedback are critical parts of this. Following these strategies will help you integrate and manage your freelancers more effectively.


  • Dynatrace Adds Security Gates to Advance DevSecOps Adoption

    Dynatrace Adds Security Gates to Advance DevSecOps Adoption

    Dynatrace today added a security gates capability to its observability platform to make it easier to automatically embrace DevSecOps best practices within an application delivery pipeline.

    Steve Tack, senior vice president for product management at Dynatrace, said the security gates function much the same as the quality gates that Dynatrace previously added to that platform in that each release is now also automatically assessed to ensure only secure code is being deployed.

    The Dynatrace platform now uses a Davis artificial intelligence (AI) engine to scan for vulnerabilities in application workloads in real-time and then prioritizes them based on the risk they pose, noted Tack. The goal is to make it simpler for organizations to incorporate security reviews in application development processes in a way that doesn’t necessarily require developers to become security experts, he added.

    Instead, the core DevOps platforms should be capable of identifying issues that can be remediated before an application is ever deployed in a production environment, said Tack.

    Dynatrace earlier added an ability to automatically identify the software libraries and open source packages that present the greatest security risk. The security gates capability now extends the scope of that effort to include applications as they are constructed using custom code.

    In general, most organizations are looking for ways to embrace DevSecOps best practices. The challenge is achieving that goal without unduly slowing down the rate at which applications are developed. In fact, a recent survey commissioned by Dynatrace found, on average, organizations expect to increase the frequency of their software releases by 58% over the next two years. However, nearly a quarter (22%) of respondents admit they’re often under so much pressure to meet the demand for application deployments that they must sacrifice code quality, which broadly includes security issues.

    It’s not clear to what degree security reviews will automatically be included within a quality assurance process, but Tack said the goal should be to limit human involvement in the application deployment process as much as possible. The issue many development teams encounter today is that applications are being rejected by cybersecurity teams that are reviewing applications just before they are deployed, noted Tack. As a result, developers are racing to build applications faster only to see them rejected and returned to them at the last possible moment, he added.

    In the wake of a series of high-profile software supply chain breaches, the focus on DevSecOps has increased substantially within most organizations. It’s often not precisely clear who is responsible for application security, but as DevOps platforms continue to evolve, there may come a day when security issues are routinely addressed within every DevOps workflow.

    In the meantime, there needs to be a lot more focus on bridging the divide between DevOps and security teams. Given the chronic shortage of security professionals, there’s no doubt DevOps teams need to assume more responsibility for application security. The challenge and the opportunity is finding a way to achieve that goal with the least amount of friction possible.

  • Grafana Labs Expands into Incident Management Realm

    Grafana Labs Expands into Incident Management Realm

    During its online ObservabilityCON 2021 conference, Grafana Labs this week previewed an incident management platform in addition to making available an on-premises edition of its distributed tracing tool.

    Tom Wilkie, vice president of product for Grafana Labs, said the Grafana OnCall incident management platform is a natural extension of the observability tools the company already provides using the widely employed open source Grafana dashboard. The platform, which is expected to be generally available in 2022, is based on software Grafana Labs gained by acquiring Amixr earlier this year.

    Grafana OnCall unifies all the alerts created by Grafana, Prometheus and the Alertmanager tool the Prometheus community created to streamline the number of alerts generated by the platform. The goal is to reduce the alert fatigue a DevOps team might experience when dealing with an IT issue that can be traced back to a single root cause, noted Wilkie.

    Grafana

    At the same time, Grafana Labs made Grafana Enterprise Traces available for on-premises IT environments. It is based on Grafana Tempo, a cloud service that makes it possible to store and then analyze distributed traces using inexpensive object storage resources. The latest version of the core open source Tempo project has also been updated to add service graphs and the ability to search recent traces.

    Grafana Labs this week also updated Loki, an open source log management platform, to add support for out-of-order log lines, custom log retention policies per log stream and per tenant and a deletion API that makes it easy to scrub log data. Version 2.4 of Loki also adds additional high-availability capabilities.

    Other updates to the Grafana Labs platform include support for recorded queries, a set of pre-built dashboards that enable users to quickly drill into their Prometheus metrics data, the ability to consume metrics from the AWS CloudWatch service provided by Amazon Web Services (AWS), improvements to its ability to monitor Kubernetes clusters and updates to the open source load testing tool the company gained by acquiring k6 last year.

    Grafana Labs is also committing to expanding its integration with Microsoft Azure cloud service alongside its integrations with AWS, noted Wilkie.

    While competition among providers of observability platforms is already fierce, Wilkie said an observability platform based on an open source dashboard that can already collect data from more than 100 sources provides a unique advantage. At the core of the Grafana Labs platform is a centralized framework for collecting data generated primarily by the open source Prometheus monitoring platform being developed under the auspices of the Cloud Native Computing Foundation (CNCF).

    While Prometheus is used most often in Kubernetes environments, it is starting to gain traction in monolithic application environments as well; it provides an open source approach to defining a de facto standard for collecting metrics and other data that can be consumed by an observability platform.

    It’s not clear yet to what degree IT teams are distinguishing between monitoring and observability. Monitoring focuses on predefined metrics to identify when a specific platform or application is performing within expectations. Observability combines metrics, logs and traces to instrument applications in a way that makes it simpler to troubleshoot issues without relying solely on a limited set of metrics that are pre-defined and monitor a specific process or function.

    Regardless of whether IT teams view observability as being distinct from monitoring, it’s clear that the ability to manage IT environments is improving at a rapid rate. The challenge, of course, is the IT environment itself is becoming more complex with each passing day.

  • The Need for Agile, Adaptable IT Infrastructure

    The Need for Agile, Adaptable IT Infrastructure

    Through the adoption of Agile concepts and new best practices such as automated testing, organizations can move beyond the innovation curve and bolster their IT infrastructure. In fact, the need to build agile and resilient IT infrastructure has become increasingly pertinent over the past 18 months. 

    From remote working and managing the diverse needs of employees in remote locations to the growing rates of cybercrime, the move from the physical world to the virtual one has seriously impacted the ability of organizations to operate. It comes as no surprise that business leaders are increasingly investing more in new tools and technologies to improve their IT infrastructure, transform operations and drive business value. 

    That said, it still remains relatively rare for enterprises to wholly adopt Agile approaches and techniques, despite the fact that doing so can help improve the efficiency at which goods and services hit the market. The fact is that many technology companies still do not use Agile as it is difficult to implement at scale. In addition, Agile transformation demands a cultural change, which can often take time. 

    Nevertheless, sooner or later, Agile IT will need to be implemented across businesses in various industry sectors, as well as across all branches of an organization. Our experience has been that Agile transformation will help your business grow and succeed. 

    What is Agile IT? 

    Agile is a philosophy—a mindset that can be applied to improve the provisioning, management and operation of digital infrastructure. Agile promotes business-led development, whereby a product owner and software development team collaborate as a single entity to deliver tasks that are prioritized based on business value. These tasks are also delivered over a short timeframe, such as via two-week sprints. 

    Essentially, your infrastructure is far more likely to be both secure and resilient if Agile concepts are implemented throughout the software engineering process. As a result, new digital products can be delivered to customers more quickly. For example, Agile ways of working include making small, iterative changes to deliver high-quality results with speed. You can also spin up infrastructure when needed, which keeps the cost of innovation down. 

    The Differences Between Agile and Traditional IT Infrastructure? 

    Infrastructure agility is best achieved using modern solutions such as cloud technology. This significantly differs from the traditional approach of having on-premises infrastructure, which cannot be scaled up or down as needed. In fact, on-premises solutions often require extensive upfront capital, while investing in cloud resources works on a pay-as-you-go model to deliver flexibility and elasticity for strategic needs. 

    The conflict between adaptive software methods and predictive methods is another significant difference between these approaches. Development teams follow a comprehensive plan in traditional waterfall approaches, and any changes must go through stringent change control management. Agile requirements, on the other hand, require flexibility, allowing teams to adjust to changes as soon as they occur. This method is suitable for smaller projects that must be performed quickly and efficiently. 

    Benefits of Implementing Flexible IT Infrastructure

    The advantages of having Agile IT infrastructure are numerous. In fact, the adoption of Agile methods not only promotes business growth but is also a great way to reduce costs and improve team performance. By working in sprints, teams can turn around features more often and nurture their value throughout the business. Agile transformation also enables organizations to offer new products or solutions to customers faster, gain early feedback and make changes if necessary, thus avoiding error from the very beginning. 

    Cost optimization is another benefit to consider. With Agile infrastructure housed in the public cloud, IT leaders can expand or decommission resources based on consumer demand. Cloud companies’ pay-as-you-go strategy also ensures that costs are kept to a minimum viable level. For example, maximum limitations can be set for the scaling out of resources. Most importantly, agile working methods eliminate the need for substantial upfront investments, resulting in a higher return on investment (ROI). 

    How to Achieve Agility

    The benefits of Agile transformation are clear; however, the journey to achieving this can take time. First and foremost, becoming Agile requires a clear understanding of what it means and why it is important for your business’ competitive context. Once the ‘what’ and ‘why’ are defined, the ‘how’ becomes easy. The three core steps to achieving this agility are: 

    1. Implementing new methods
      Instead of trying to rework existing IT management tasks and procedures, it is often better to think of new ones as part of the Agile journey. This will ensure that your system’s performance and availability are in line with your core goals. 
    2. Investing in the right tools
      Agile is all about delivering smaller outcomes quickly. To achieve this speed, automating key stages of the software development process is key. There are a host of tools available to undertake this automation, including hybrid cloud solutions that can seamlessly switch between the public and private cloud. A careful selection of the tools that best fit your needs and the correct implementation of these throughout the organization is paramount to achieving success. 
    3. Changing the culture
      To become an agile business, the entire organization requires a cultural change—from how the business discovers a problem to how that problem is resolved by technology teams and monitored in production to enable a faster feedback loop. At every stage of the process, team members need to perform tasks differently, which often requires training, buy-in from the wider team and a collaborative approach. 

    Investment in Agile IT is a smart decision for business leaders hoping to transform their operations, ensure resilience and drive business value. By choosing infrastructure that caters to these needs, you can save money and ensure confidence at critical moments. 

  • How Dispersed Can We Be?

    How Dispersed Can We Be?

    It is interesting to consider DevOps from the storage perspective. DevOps in general—and specifically newer development and deployment models—tried to pretend that long-term storage was not a necessary component of software delivery. In short, it appears that because there wasn’t a good answer to long-term state in stateless development models, the storage and databases that used state were hand-waved away. Which, of course, failed. Container deployment models did the same thing and failed just as miserably. Oh, containers didn’t fail, but the attempt to ignore persistent storage did; from the very beginning, it was clear that was going to happen. We were doing early container implementations and working through how to ensure that containers ABC had access to the same shared storage. That need never went away and was never going to. Apps can run without persistence, but business doesn’t run without persistent data.

    Checking out the wave of cool new products like, for example, Ionir (disclosure—I know more about them simply because I’m friends with their CMO. Other vendors likely have good solutions, too) makes me realize the answers that we needed were right in front of us. And not just the answer to persistent storage, but to storage portability, which has been a problem from the beginning of the cloud. Data gravity is the idea that data holds apps in place. Tools like Ionir reduce the gravity of data. A lot. They can’t get rid of data gravity, because some platforms charge for data storage, data ingress and egress, etc. but that becomes a TCO operations problem rather than a near-insurmountable tech problem.

    But just as interesting is this: What if the slow but steady increase in core Internet speeds will allow us to access data from anywhere? We could do that now, but performant applications struggle if you force them to leave cloud A and go to your data center or to cloud B to get a dataset. Yet we use APIs that do just that on a regular basis. What are Google Maps and Google Places if not simply big old honking databases? And yet we call out to them from just about every platform.

    So, it’s worth trying out and seeing if the idea of data gravity is maybe an obsolete idea for you. For some applications that really do need super-fast response times, the concept is still relevant. But for many applications? Where your app sits in relation to data may not be as important as you think. Write or grab an API wrapper for a critical dataset and throw a simple test app up on a different platform. See what you get. If it performs well, consider putting apps where it makes sense and using a wrapper API with secrets to grant access to data from any validated app.

    Some of you are doing this already. Not many, but it’s out there. Excellent job; keep rolling!

    Everyone else is kicking rear and taking names, with the world still online every day because of your collective work. So keep rocking it, but consider if you really need the application close to the data these days and, if you do, how data mobility tools might facilitate moving data to the app—something most of us would not have considered for large datasets before the last year or so.

  • Debunking 6 Stubborn Public Cloud Myths

    Debunking 6 Stubborn Public Cloud Myths

    A lot of enterprises migrate to the public cloud because they see everyone else doing it. And while you should stay up on the latest and greatest innovations—which often happen in the cloud—you need to be aware of the realities and understand different migration strategies. You need to know why you’re moving to the cloud. What’s your goal? And what outcomes are you seeking? Make sure you know what you’re getting your enterprise into before moving forward in your journey. Here are six stubborn myths that persist about the public cloud and the realities you’re facing.

    1. Cloud Technology is not a Project, it’s a Constant

    Be aware that while there is a starting point to becoming more cloud-native—the migration—there is no stopping point. The migration occurs, but the transformation, development, innovation and optimization is never over.

    There are endless applications and tools to consider; your organization will evolve over time, technology changes regularly and user preferences change even faster. Fueled by your new operating system, cloud computing puts you into continuous motion. While continuous motion is positive for outcomes, you need to be ready to ride the wave regardless of where it goes. Once you get on, success requires that you stay there.

    2. Flex-Agility is Necessary to Survival

    Flexibility + agility = flex-agility, and you need it in the cloud. Flex-agility enables enterprises to adapt to the risks and unknowns occurring in the world. The pandemic continues to highlight the need for flex-agility in business. Organizations further along in their cloud journeys were able to quickly establish remote workforces, adjust customer interactions, communicate completely and effectively and, ultimately, continue running. While the pandemic was unprecedented, more commonly, flex-agility is necessary in natural disasters like floods, hurricanes and tornadoes; after a ransomware or phishing attack; or when an employee’s device is lost, stolen or destroyed.

    3. You Still Have to Move Faster Than the Competition

    Gaining or maintaining your competitive edge in the cloud has a lot to do with speed. Whether it’s the dog-eat-dog nature of your industry, macroeconomics or a political environment, these are the things that speed up innovation. You might not have any control over these factors, but they’re shaping the way consumers interact with brands. Again, when you think about how digital transformation evolved during the pandemic, you saw winning businesses move the fastest. The cloud is an amazing opportunity to meet all the demands of your environment but if you’re not looking forward, forecasting trends and moving faster than the competition, you could fall behind.

    4. People are Riskier than Technology

    In many ways, technology is the easiest part of an enterprise cloud strategy. It’s people that introduce much of the risk involved. You may have a great strategy with clean processes and tactics, but if the execution is poor, the business can’t succeed. A recent survey revealed that 85% of organizations report deficits in cloud expertise, with the top three areas being cloud platforms, cloud-native engineering and security. While business owners acknowledge the importance of these skills, they’re still struggling to attract the caliber of talent necessary.

    In addition to partnering with cloud service experts to ensure a capable team, organizations are also reinventing their technical culture to work more like a startup. This can incentivize the cloud-capable with hybrid work environments, an emphasis on collaboration, use of the agile framework and fostering innovation.

    5. Cost-Savings is Not the Best Reason to Migrate

    Buy-in from executives is key for any enterprise transitioning to the cloud. Budget and resources are necessary to continue moving forward, but the business value of a cloud transformation isn’t entirely about cost savings. Really, it’s about repurposing dollars to achieve other things. At the end of the day, companies are focused on getting customers, keeping customers and growing customers, and that’s what the cloud helps to support.

    By innovating products and services in a cloud environment, an organization is able to give customers new experiences, sell them new things and delight them with helpful customer service and a solid user experience. The cloud isn’t a cost center, it’s a business enabler, and that’s what leadership needs to hear.

    6. Cloud Migration Isn’t Always the Right Answer

    Many enterprises believe that the process of moving to the cloud will solve all of their problems. Unfortunately, the cloud is just the most popular technology operating system platform available today. Sure, it can help you reach your goals with easy-to-use functionality, automated tools and modern business solutions, but it takes effort to use and apply those resources for success.

    For most organizations, moving to the cloud is the right answer, but it could be the wrong time. The organization might not know how it wants to use cloud functionality. Maybe outcomes haven’t been identified yet, the business strategy doesn’t have buy-in from leadership or technicians aren’t aware of the potential opportunities. Another issue stalling migration is internal expertise (or lack thereof). If your technicians aren’t cloud-savvy enough to handle all the moving parts, bring on a collaborative cloud advisor to ensure success.

  • Microsoft Expands Azure DevOps Portfolio

    Microsoft Expands Azure DevOps Portfolio

    Microsoft has made available a bevy of updates to its DevOps portfolio that, collectively, are intended to increase its share of a wave of applications that will be rolled out across the extended enterprise.

    Additions to the Microsoft DevOps portfolio were announced at the Microsoft Ignite 2021 conference and include DevOps Workflow Generator, a free tool designed to help DevOps teams visualize their toolchain, and updates to Azure Automanage, a framework for automating the management of virtual machines on Windows Server and, in preview, on Linux.

    At the same time, Microsoft has added support for open source OpenTelemetry agent software to Azure Monitor and made available a preview of Azure Chaos Studio, a service for testing application resiliency.

    Microsoft is also making available a preview of Windows Server 2022 that adds secure-code capabilities for workloads deployed on the platform. Microsoft also previewed updates to backed databases such as SQL Server 2022, Cosmos and its implementation of the Redis database created by Redis Labs.

    Finally, Microsoft has also made available a preview of integration between GitHub Actions for automating software development tasks and Azure Active Directory (Azure AD) using Open ID Connect, an authentication protocol advanced by the OpenID Consortium.

    Microsoft CEO Satya Nadella told conference attendees the next 10 years will witness more digitization than the previous four decades as IT shifts from an era defined by mobile and cloud computing to one defined by ubiquitous computing and ambient intelligence.

    Applications built in everything from procedural code to the Microsoft Power Fx, a low-code tool that Microsoft created using the programming language it originally built for users of the Microsoft Excel spreadsheet. Microsoft envisions those applications will primarily be built on its cloud and distributed everywhere. On the backend, a range of database and artificial intelligence (AI) services will be invoked primarily via application programming interfaces (APIs).

    Of course, every major cloud service provider has similar ambitions. Most organizations today are not standardizing on a single cloud. Rather, they are determining which class of workloads run best on which cloud computing platform regardless of whether that approach increases the total cost of IT. Each additional platform adopted typically requires IT teams to master separate tools. However, Microsoft is now also making a case for a cloud-native framework that can be deployed anywhere to build, deploy and manage applications.

    In the meantime, the number of workloads deployed on cloud services continues to grow. The market research firm Canalys reported worldwide spending on cloud infrastructure services reached $49.4 billion in the third quarter of 2021, a 35% increase. Microsoft currently trails Amazon Web Services (AWS) in overall market share but continues to steadily make gains. Microsoft and AWS collectively account for roughly half of all cloud infrastructure service consumption.

    DevOps best practices will need to evolve to meet the challenges of multi-cloud computing. In addition to cloud platforms and on-premises IT environments, applications are now starting to be deployed at the edge in greater numbers. DevOps teams need to be able to continuously deploy applications and their associated updates across a wide range of platforms. The challenge, of course, is that all those platforms have unique attributes that make truly automating the entire process on an end-to-end basis an elusive goal.

  • Driving Software Delivery Automation With AI/ML

    Driving Software Delivery Automation With AI/ML

    What if we could use an artificial intelligence (AI) engine to predict the next lines of software code to build? What if machine learning (ML) could trigger the creation of automated test cases to validate our solutions?

    Automation has been a focus for the information and communications technology (ICT) industry for years, and there are some lessons that could apply to the software developer community, too, as well as other verticals. Today, more streamlined execution of operational and software delivery processes, such as continuous integration, continuous delivery and continuous deployment (CI/CD) in app development, continue to drive new levels of cost reductions, allowing products to get to market and update faster. 

    However, with the increased amount of data comes more complex ecosystems and the need for the next level of automation. Hyperautomation, or the use of AI/ML to further streamline processes, could build on these CI/CD processes, revolutionize the way multiple industries deliver software and optimize operational processes.

    Today’s Network Complexities and Challenges

    In the telecommunications industry, disruptions from hyperscalers and other innovative players, as well as increasing levels of investment in 5G technology, are forcing the hand of communications service providers (CSPs). This is causing them to turn to automation to improve their levels of operational efficiency and innovation to keep up with the need to push frequent updates. 

    However, challenges remain in the form of:

    • Total cost of ownership and operating costs: With more frequent needs for upgrading existing networks, additional levels of automation including AI/ML and hyperautomation are required to manage and maintain today’s complex networks. 
    • Time to market: In an increasingly competitive market, the CSP’s ability to react to market needs and/or new marketing ideas and to rapidly launch those needs and ideas to their end users and enterprise customers is a key competitive differentiator. 
    • Customer experience: Digitalizing business processes, providing an increased level of self-service and seeking ways to optimize customers’ overall journey remains an important need.
    • Employee productivity: In an effort to increase revenue, more efficiently drive their networks and improve end user customer experience, CSPs also need to increase employee productivity. They can do this by engaging their employees to solve bigger problems. As a result, the simplest and most repetitive low-level tasks can be automated.

    The Power of AI and ML

    The automation journey started with breaking down complex processes into smaller parts and automating discrete parts using scripts, runbook automation (RBA) and/or robotic process automation (RPA). 

    With the introduction of AI emulating human intelligence through mechanical and computational processes and ML using algorithms that learn from data to make predictions and decisions, CSPs can now bring automation and hyperautomation to the next level. 

    The potential use cases for the delivery and maintenance of telco software solutions are unlimited, and many of these lessons can be applied to other sectors. Some examples include:

    Autonomous Fault and Anomaly Detection for Cloud-Native Solutions

    Today’s network solutions are deployed on containers and microservices. The identification of issues and assurance of service quality becomes increasingly challenging with thousands of workloads running in parallel. Container failure can cause severe service disruptions. In fact, a single service failure or abnormal behavior could have a butterfly effect on the overall system and negatively affect customer satisfaction. 

    A proactive, AI-based monitoring solution can continuously search for anomalous behavior in the environment. Different container metrics and logs can automatically analyze and detect problems proactively and help find the right corrective actions for the application workflows. This is based on identifying anomalies in the container orchestration metrics related to pods, workloads and namespace. These techniques enable a more reliable and predictable application runtime environment with higher service quality and faster identification and resolution of system faults and, ultimately, a better overall customer experience

    Machine Learning-Triggered Closed-Loop Automation

    Large clusters of compute, storage and networking resources are managed throughout a data center to enable the deployment of custom workloads. Due to the inherent nature of applications running on the virtualized and cloud infrastructure, there are usage highs and lows which need constant infrastructure component deployment or reconfiguration of the cluster to ensure cost-efficient service availability. 

    A machine learning-based solution can detect anomalies in the infrastructure. Specifically, with closed-loop automation, enterprises can bring in a layer of intelligence over the current setup to monitor application performance and infrastructure metrics and identify anomalies that require immediate system attention. If those are found, they can trigger the automated addition of capacity to the infrastructure. When anomalies have subsided and once the utilization is capable of being handled by the original capacity, the solution can consistently monitor metrics to roll back the virtual or cloud-native functions. This allows for an efficient and fully automated use of network capacity, minimizing human oversight.

    Smart Code Recommendations

    One of the most clear-cut ways tools can reduce the effort of software development for programmers is through code completion. AI-powered code completion is a convenient way to access descriptions of functions and their parameter lists. These solutions also speed up software development by reducing keyboard input and the necessity of name memorization. They also allow users to refer less frequently to external documentation, as interactive documentation appears dynamically in the form of tooltips. AI-powered code completion can also use an automatically generated in-memory database of classes, variable names and other constructs or references based on machine learning to open code repositories.

    AI-Driven Test Recommendation

    Significant time is spent understanding solution requirements and identifying critical scenarios for testing. This is usually followed by a manual test plan creation and execution. To solve this, AI/ML techniques can be applied to identify what tests will need to be done during each cycle of the software development stage, including automating the analysis of required documentation. This can be used to increase overall test-cycle time and improve productivity. 

    AI-Enabled Test Automation

    API testing is critical for validating application logic and needs to go beyond the GUI layer to validate the core of an application. This implies complexity because the protocols are usually difficult to understand, the API inventory is usually large and sequencing of the API calls is critical to a successful test specification and execution. With AI/ML and natural language processing techniques, the analysis of the solution test plan can be automated to obtain recommendations on what test frameworks to utilize, identify and suggest the parameters for each test case, identify the API call sequence and automate the development of test cases based on reusable functions. This can increase overall quality of service, simplify change management, improve the productivity of the testing team and offer more reliable test cases.

    Test Failure Analytics

    During execution of automated test cases, multiple failures can be observed in various logs. Manually analyzing the logs and correlating them with the application issues can be time-consuming. Also, the identification of unreliable tests impacting system stability is complex. 

    AI/ML techniques such as vectorization, K-means clustering or topic modeling can be applied to automate the collection of test logs across applications and label failures including the type of cluster failed tests. The test subject matter expert (SME) is provided with a failure analysis report summarizing issues and problems automatically from many logs across applications, simplifying the identification of issues in test automation areas or scripts. These techniques can significantly increase test productivity and overall troubleshooting time.

    Accelerated Root Cause Identification and Analysis (RCI&A)

    When a problem occurs in a telco network, it tends to cause a ripple effect, affecting other integrated services and creating an alert storm. In such scenarios, root cause identification can become complex and cumbersome. Event aggregation and synchronization are needed to reduce environment complexity and variance. 

    Machine learning weighted analysis techniques can be used to determine the influence individual IT metrics have in affecting the overall health and performance of hosted applications and services so that pinpointing the root cause of any service impact in real-time can become easier for the team operating the network. Efficient AI/ML techniques for accelerated RCI&A can lead to significant timeline reductions. 

    AI/ML Driving Operational Innovation and Market Agility

    In telco, there is great potential for AI/ML-driven use cases to further improve the cloud-native journey and enable an IT-like software life cycle management process for the solutions of the future.

    More broadly, highly automated and self-healing networks will drive higher levels of efficiency and customer satisfaction. This includes faster testing with less resources; more efficient utilization of network resources and cloud infrastructure; faster time-to-market with more software releases per year with similar capacity as well as an increased quality for faster and more agile monetization of the CSPs capabilities.