Category: IT as Code

  • Palo Alto Networks Buys Cider Security to Lock Down Pipelines

    Palo Alto Networks Buys Cider Security to Lock Down Pipelines

    Palo Alto Networks this week extended its efforts to secure application environments by agreeing to acquire Cider Security, a provider of a platform for securing continuous integration/continuous delivery (CI/CD) platforms, for approximately $195 million in cash.

    The acquisition of Cider Security, scheduled to close this quarter, will extend the reach of the company’s Prisma Cloud platform that was updated last year to include a set of tools for securing infrastructure-as-code (IaC) used to provision IT infrastructure. Palo Alto Networks previously acquired Bridgecrew, which had developed an open source Checkov policy-as-code tool. Last month, Palo Alto Networks added software composition analysis tools to Prisma Cloud, as well.

    Cider Security developed what it described as an operating system for application security. The solution creates a graph that enables DevOps teams to visualize the relationships between all elements that make up a software development environment, including code. It then makes it possible to apply a set of controls to remediate any vulnerabilities and attack paths that might be identified using any number of third-party scanning tools.

    Palo Alto Networks CEO Nikesh Arora told industry analysts the acquisition is an example of the company doubling down on securing software supply chains alongside its existing portfolio of platforms and services for securing production environments.

    It’s not yet clear who is in charge of DevOps platform security, but increasingly there will be some type of central security function that works with application development teams to lock down software supply chains, said Mike Rothman, general manager for Techstrong Research, an arm of the parent company of devopsy.kinsta.cloud. “There’s going to be a central security group focused on securing the pipeline,” he said.

    As Palo Alto Networks continues to extend the reach of Prisma Cloud left, it continues to make a case for centralizing the management of cybersecurity through a portfolio of platforms that can be centrally managed via the cloud. It’s not clear how much organizations are centralizing management of security across their software supply chains and production environments, but Arora noted that interest in consolidating security vendors is high as organizations look to reduce the total cost of cybersecurity.

    In the meantime, organizations of all sizes are looking to employ DevSecOps best practices to better secure software supply chains in the wake of a series of recent high-profile breaches. In addition to scanning code for vulnerabilities, many of those organizations are starting to realize the tools and platforms used to build applications are also vulnerable to cyberattacks. The goal of those attacks is to insert malware that will manifest itself in any number of downstream applications that are eventually deployed in a production environment.

    It’s not yet apparent just how compromised those tools and platforms may be, but it’s clear software consumers are moving toward holding developers more accountable for vulnerabilities. The best-known example of those requirements is an executive order issued by the Biden administration that will require federal agencies to include software bills of materials (SBOMs) that list known vulnerabilities. Many enterprise IT organizations are expected to adopt similar requirements.

    One way or another, however, the tools and platforms that make up a software supply chain, along with the code they produce, are going to be subject to much greater scrutiny than ever before.

  • Infrastructure Abstraction Will Be Key to Managing Multi-Cloud

    Infrastructure Abstraction Will Be Key to Managing Multi-Cloud

    There’s no doubt we’re now living in a hybrid multi-cloud age. Companies are using major cloud providers like AWS, Azure and GCP with niche cloud computing providers emerging within the market. Simultaneously, many organizations still retain workloads in on-premises data centers or embrace colocation. Regardless of deployment pattern, DevOps teams desire the same elasticity as the cloud, but it’s becoming increasingly difficult to consistently manage the nuances of each service provider.

    To support today’s distributed polyglot architectures, a common layer could ease issues when deploying applications and provisioning various servers. By decoupling the infrastructure control plane from specific cloud providers, a unified management console could bring visibility into cost and performance, empowering CloudOps with knowledge before they commit. But engineering such an outcome would rely on plugins for each environment and a robust set of APIs to enable programmatic control.

    I recently met with Jake Warner, Cycle.io, to explore how increased infrastructure abstraction can solve the above problems. According to Warner, a standard layer for computing management is needed to enable consistent control over multi-cloud and bespoke on-premise environments. Below, we’ll define this concept and consider the benefits infrastructure abstraction could bring to modern enterprise software development.

    The Problems Facing Infrastructure Management

    We like to think that the cloud is pervasive and that everyone’s on board with a similar computing style. However, this is far from the truth. Multi-cloud is rising, and 95% of businesses are making multi-cloud a strategic priority in 2022, a Valtix study found. Yet only about half of respondents felt they had the appropriate tools and skills required to execute a multi-cloud strategy.

    “There’s a lot of value in multi-cloud, including reducing risk, ensuring better uptime and the flexibility to select the best hardware for the use case,” said Warner. “But multi-cloud is extremely complex.” Using multiple clouds means supporting increasingly variable operational processes for each environment. Whether it’s AWS, GCP, Azure, Equinix or Vultr, operators also require a deep level of visibility into telemetry data. This becomes complicated to track as software is increasingly modular and distributed across multiple computing regions.

    Furthermore, on-premises data centers are far from dead—surprisingly, a Spiceworks study found that 98% of enterprises still used on-premises servers. Traditional servers are often preferred due to corporate restrictions or to meet security compliance mandates. It could also be a cultural case of “if it works, don’t fix it.” The dilemma is that you can’t easily obtain common cloud features like auto-scaling and load balancing while on your own infrastructure.

    Another issue Warner described is that traditional platform-as-a-service (PaaS) companies present inherent limitations if you aim to build substantive applications and services. “Many of these PaaS offerings make it really easy to get started but, more often than not, developers are quickly forced to make compromises with their approach. These compromises can create long-term technical issues, especially when it’s time to scale,” he said. “Need a server with a specific hardware configuration in a targeted region? Good luck. For most PaaS companies, their exit ramp is just as defined as their on-ramp.”

    Movements Toward Infrastructure Abstraction

    We’re already seeing movement within the market to manage the operational burdens of multi-cloud. One example is the Infrastructure Abstraction Layer (IAL), open sourced by Cycle.io, which Warner explained can act as a standardized system for deployments. With the specification, an infrastructure provider can generate an API endpoint to enable the provisioning of infrastructure without requiring a deep integration between both services. With this endpoint live, an application development platform or orchestrator gains the ability to send standardized JSON payloads to provision servers, allocate IPs, configure regions and a number of other requests. The response, another JSON payload, confirms that the desired request has been completed and includes a unique ID.

    With more programmatic control over infrastructure, an engineer could interface with a standardized list of all the servers, across a number of providers, to deploy to and act upon this information in one unified console. This layer is an opportune location to help compare costs and server configurations for different regions too. It’s also an advantageous spot to filter by proximity to showcase the closest available servers to optimize delivery.

    Benefits of Unifying Multi-Cloud Deployment

    Decoupling the infrastructure management layer from service providers can bring potential benefits to DevOps, said Warner. For one, it enables operators to extend infrastructure automation into their private data centers, helping them achieve the same programmability they would have in the cloud. A degree of standardization can remove many of the cons of multi-cloud, too—”Developers can move from one provider to another provider without any major changes along the way,” he said.

    Of course, IT doesn’t want an added burden. This is why an API-based solution is required to enable programmability, said Warner. By taking a RESTful API approach to managing a hybrid infrastructure, operators could create custom flows based on fine-grained environmental characteristics that change over time, like latency, expense or location. “One of the neat things is it allows infrastructure providers to constantly make tweaks and improvements without having to resubmit their integration with an underlying platform,” said Warner.

    The Flexibility of LowOps

    Today’s software deployment is increasingly wide and varied—a recent HashiCorp report found that 76% of organizations are already multi-cloud. Multi-cloud brings many advantages, yet it also multiplies the number of operational tasks required. At the same time, organizations want to leverage investments into on-premises data centers for as long as they are economically viable. Automating DevOps for such a varied infrastructure can be difficult without a unified layer decoupled from each niche computing area.

    According to Warner, companies require a LowOps platform and the flexibility to abstract this automation on their own infrastructure when appropriate, which can vary widely. For example, operators may be working with a fleet of tens of thousands of IoT devices. Furthermore, as we’ve covered previously, a LowOps method can be beneficial to small-to-medium-sized companies that may lack the resources to support complex infrastructure like Kubernetes.

    Could something like IAL ever become an open standard? Well, at the time of writing, the IAL specification has only been implemented by Cycle.io and a few of its infrastructure partners, but there’s no reason it couldn’t be extrapolated into a common specification down the line, said Warner. He even foresees a community marketplace or shared registry for infrastructure abstractions, enabling platforms to support hundreds of cloud providers.

    In conclusion, the need for LowOps, combined with the rise of multi-cloud and the staying power of on-premises data centers, is fueling a requirement for a decoupled management center. Infrastructure abstraction could enable the convenience of a PaaS while empowering operators with custom infrastructure choices.

  • Fiberplane Notebook Tool Fosters DevOps Collaboration

    Fiberplane Notebook Tool Fosters DevOps Collaboration

    Fiberplane today announced it is making available a public beta of a namesake real-time collaboration notebook specifically designed for DevOps teams that need to quickly debug IT infrastructure.

    Fiberplane CEO Micha Hernandez van Leuffen said in the wake of the COVID-19 pandemic, it’s clear that the structure of DevOps teams has permanently changed now that more members of those teams work remotely. The challenge is that the tools provided to DevOps teams to manage IT environments were not designed to foster the level of collaboration that is now required, he added.

    Dashboards that were designed in a different era need to be replaced with tools that make it simpler for DevOps teams to collaboratively debug infrastructure in real-time, noted Hernandez van Leuffen.

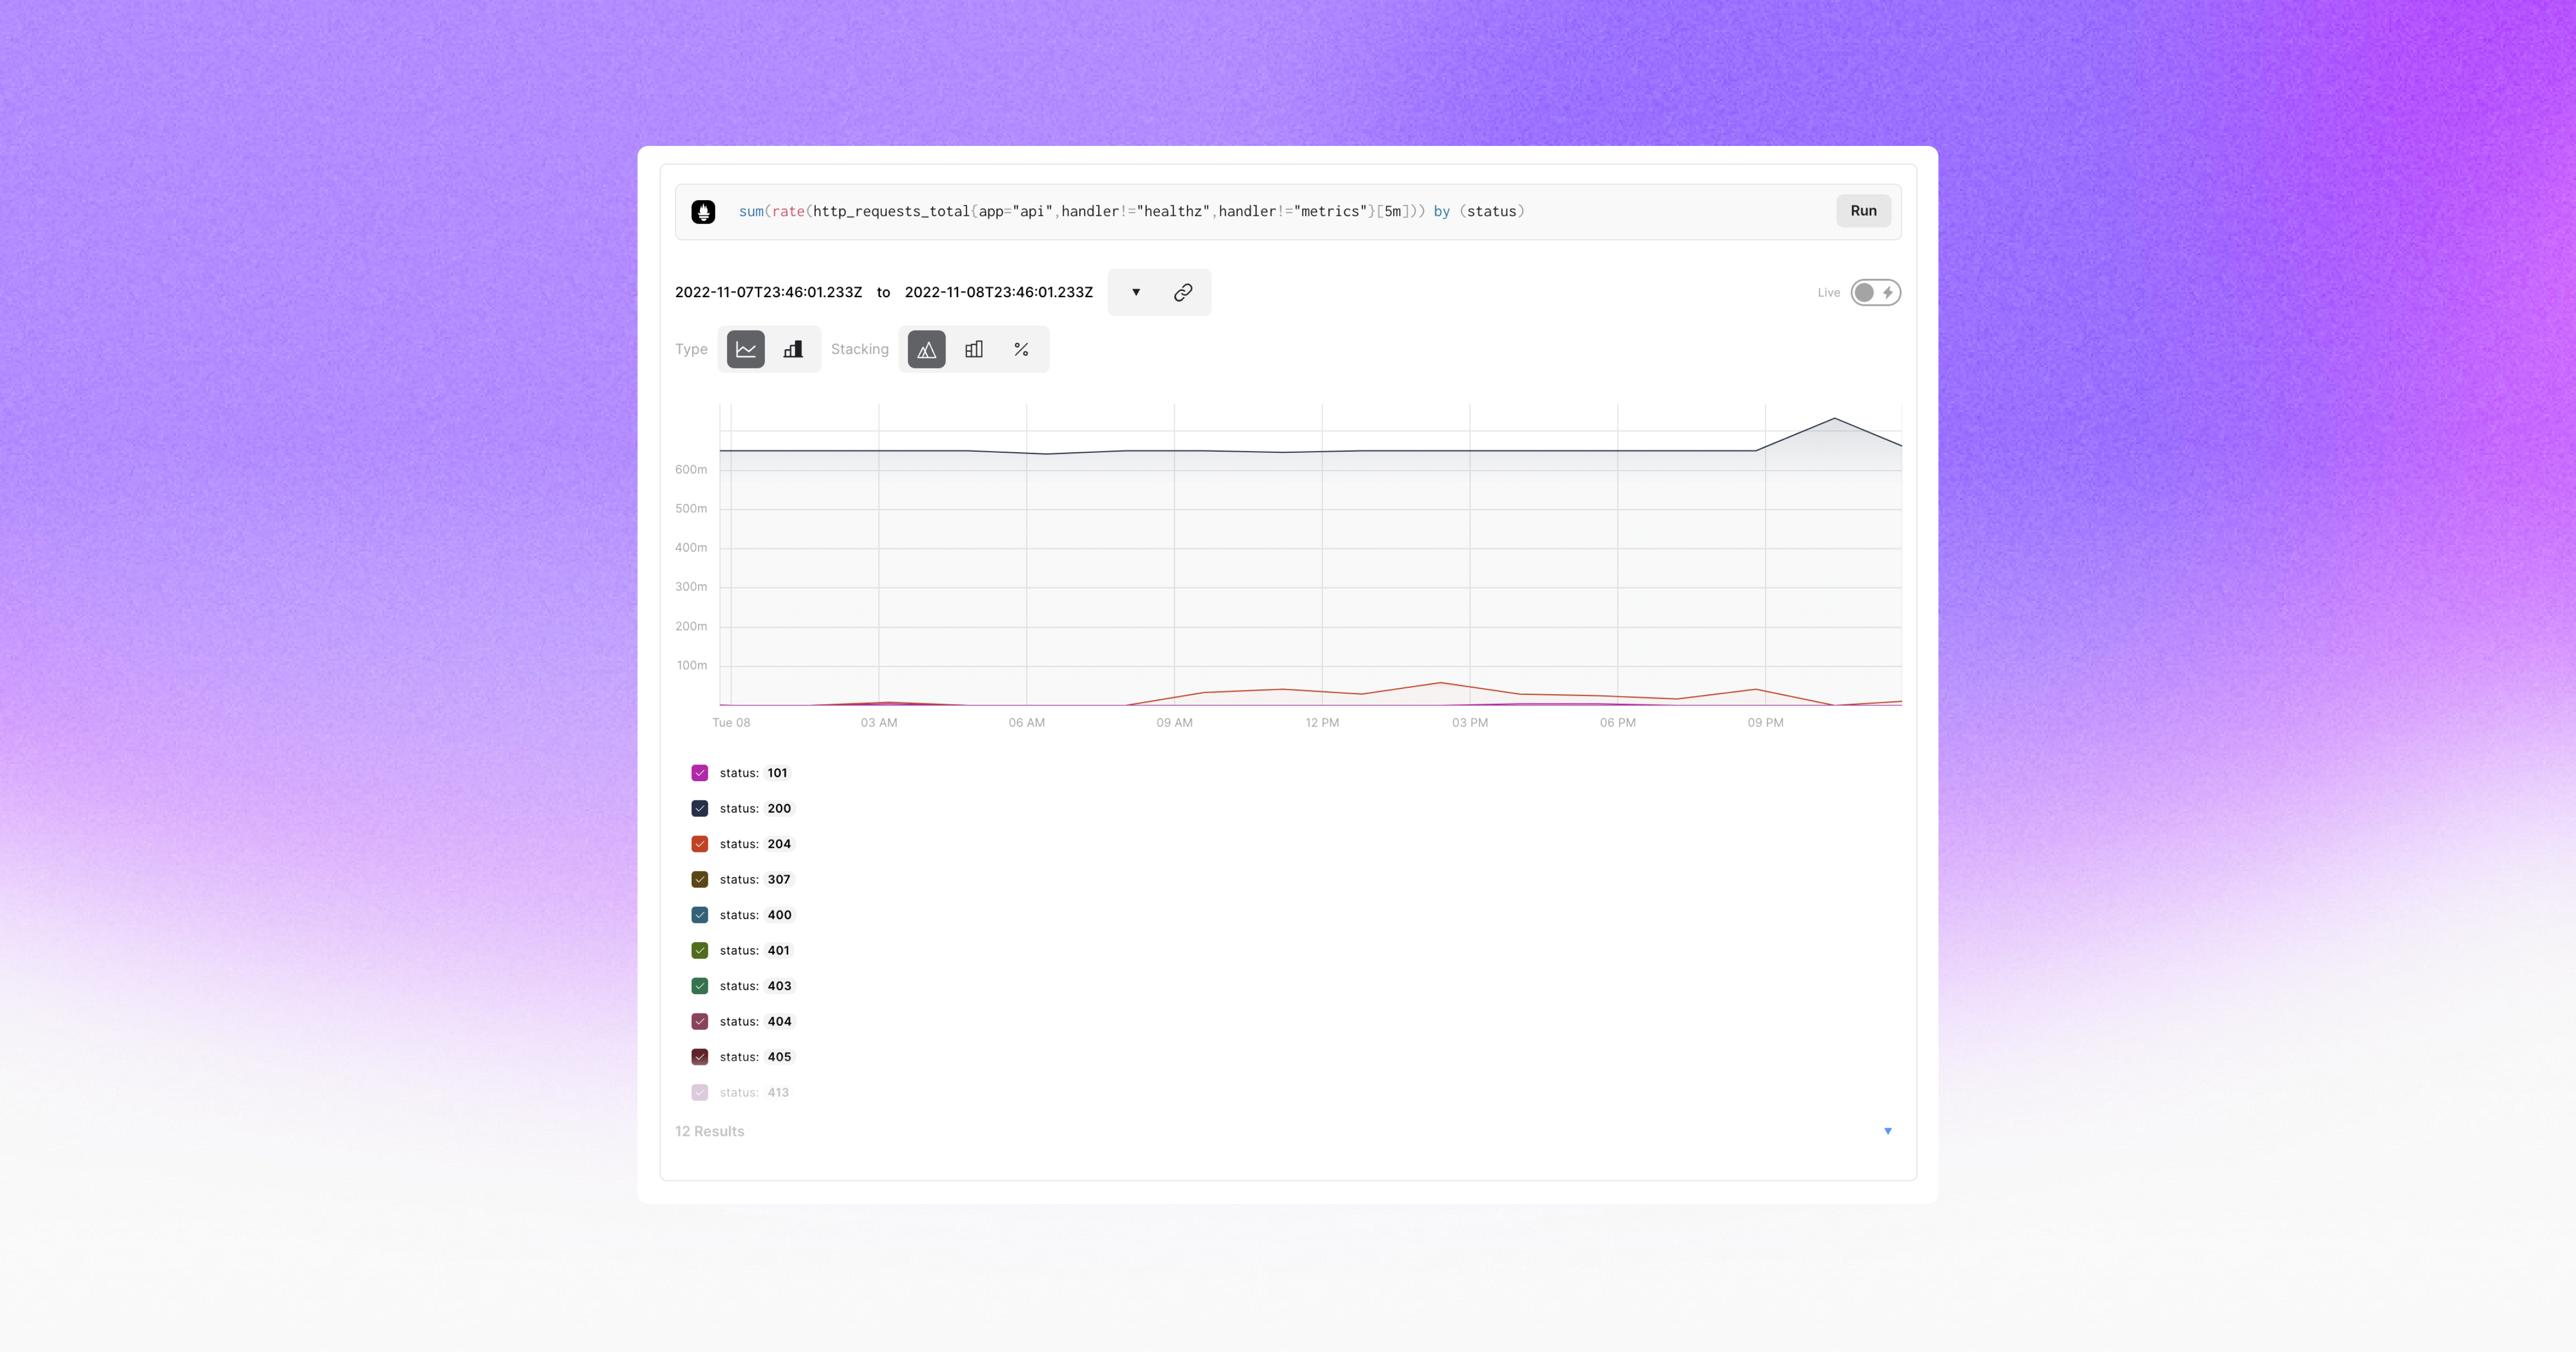
    The Fiberplane notebook achieves that goal by using the same operational transformation algorithm used in Google Docs to enable teams to easily collaborate around a document or spreadsheet. The core platform itself is built in Rust and WebAssembly (Wasm), which Hernandez van Leuffen said makes it simpler to integrate Fiberplane as a plug-in into an existing DevOps workflow. Inside a Fiberplane Notebook, DevOps teams can, for example, write and run PromQL queries and display Prometheus charts alongside other data presented via an integrated graph.

    Fiberplane Notebook’s initial integrations are for Grafana Loki, Elasticsearch and Prometheus monitoring tools. It also exposes both an application programming interface (API) and command line interface (CLI) to automate notebook creation based on specific external events, such as monitoring alerts.

    In effect, Fiberplane is taking the concept of notebooks used for collaboration by data science teams and applying it to DevOps workflows, said Hernandez van Leuffen. The goal is to improve DevOps teams’ productivity by reducing the amount of time it takes to resolve any issue, he added.

    As IT environments become more distributed in the age of the cloud and microservices, troubleshooting issues invariably spans the responsibilities of multiple members of an IT team. Fiberplane, in effect, makes it possible to spin up a virtual war room that enables the members of an IT organization to collaborate until the issue of the moment is resolved.

    The speed at which any IT issue is resolved has become a crucial metric. Given the complexity of IT environments, it’s inevitable that incidents will arise. Ideally, IT teams would discover those issues before they disrupt the business. However, in reality, the metrics organizations use to evaluate the effectiveness of a DevOps team are, unfairly or not, how quickly IT issues are resolved once they are discovered. The longer it takes for a distributed DevOps team to marshal its resources the more likely it becomes that team will be perceived as being inefficient—regardless of what level of application availability is actually achieved.

    Savvy DevOps teams, of course, have implemented a wide range of incident management best practices that create a level of muscle memory for responding to a wide range of issues. The trouble is there will always be unforeseen issues that arise. DevOps teams, as a result, need to find ways to quickly focus on an issue that, for one reason or another, were simply too unpredictable to anticipate; they need to expect the unexpected.

  • Critical Vulnerability Discovered in Open Source Backstage Platform

    Critical Vulnerability Discovered in Open Source Backstage Platform

    Oxeye today disclosed that it has discovered a critical vulnerability in the open source Backstage software used to build developer portals. Backstage was originally created by Spotify.

    A 1.5.1 update to the Backstage platform remediated a sandbox escape vulnerability that can occur via a third-party Scaffolder plug-in that could be used to conduct unauthenticated remote code execution (RCE).

    Oxeye CTO Ron Vider said Oxeye worked with Spotify to responsibly disclose the issue and enabled a patch to be created prior to the disclosure of the vulnerability, which Spotify gave a 9.8 out of 10 severity rating.

    Backstage is now being advanced under the auspices of the Cloud Native Computing Foundation (CNCF), but is already widely used by organizations such as American Airlines, Netflix, Splunk, Fidelity Investments, Epic Games and Palo Alto Networks, as well as by Spotify.

    The vulnerability is another example of a potential template-based attack through which run shell commands can be manipulated to inject malware into an application development environment.

    In general, separating the logic from the presentation layer as much as possible can greatly reduce exposure to the most dangerous template-based attacks.

    Vider said Oxyeye is focusing its vulnerability research on cloud-native platforms such as Backstage that are generally being used to build modern applications based on a microservices architecture. It’s not clear to what degree organizations have transitioned away from more monolithic approaches to building applications, but it’s clear that a much larger percentage of applications are now being constructed using microservices.

    Cybercriminals, of course, are targeting these platforms as part of a sustained effort to compromise software supply chains in the hope that the malware they inject will find its way into multiple downstream applications. Those attacks, in turn, are convincing more organizations to embrace DevSecOps best practices to better ensure the integrity of their software supply chains. The challenge is many of those attacks are being aimed at open source software projects that don’t always have enough resources to quickly develop a patch in the event a zero-day vulnerability is disclosed.

    While it’s impossible to know the extent to which cybercriminals are already exploiting vulnerabilities in DevOps platforms, the level of cybersecurity scrutiny being applied has dramatically increased in the wake of a series of high-profile breaches. The Biden administration has even gone so far as to issue an executive order requiring federal agencies to better secure their software supply chains. As a result, DevOps teams should expect there to be a lot more DevOps platform vulnerability disclosures in the months ahead, and that those vulnerabilities will require immediate patching.

    Like it or not, software supply chains are going to become more secure. The only thing left to be determined is the level of pain that will be experienced as more vulnerabilities are discovered in the DevOps platforms that were used to construct them.

  • Codenotary Automates SBOM Creation

    Codenotary Automates SBOM Creation

    Codenotary today launched a tool that enables an application to automatically generate a software bill of materials (SBOM) by adding a single line to its source code.

    Codenotary CEO Moshe Bar said TrueSBOM makes it possible to self-report the components used to construct applications to any organization that uses them for the first time. In contrast, existing SBOMs only provide a snapshot of the components of an application at the time it was initially created, he added.

    IT organizations are being asked to trust application providers that all the modules specified in the SBOM are the only components being used. Codenotary is making a case for an approach that enables the organization consuming that software to spin up an SBOM in real-time on demand.

    From a DevSecOps perspective, adding a single line of code to the application to enable TrueSBOM should also eliminate the need to create and maintain separate text files to generate an SBOM.

    Awareness of the need for SBOMs has skyrocketed since the Biden administration’s executive order made it clear that federal agencies would require them from any software provider starting next year. Many enterprise IT organizations are likely to follow suit as part of a larger effort to better secure software supply chains in the wake of a series of high-profile cybersecurity breaches.

    That approach also makes it a lot simpler for organizations to accurately pinpoint where components are actually running any time a new zero-day vulnerability is discovered, added Bar.

    Priced at $1,450 per application stack per year, there are also lower-cost instances of TrueSBOM available for applications based on either a serverless framework or using the portable WebAssembly (Wasm) format.

    Most internal DevOps teams already have a good handle on what software components are being employed with the applications they deploy, said Bar. The issue is that the organizations that use that software can’t easily verify what components are being employed, he added. That’s problematic because an organization may have decided to prohibit deployment of a specific software component because of a known vulnerability. Rather than trust a text file created by the provider of an application, TrueSBOM allows the user of an application to maintain control over their software environment, noted Bar.

    It’s not yet clear how most organizations will operationalize SBOMs now that more of them are being created. Ideally, organizations should be able to approve only software that has components that have been verified to be secure. Armed with those insights, over time, it should become simpler to start reducing security technical debt with more secure applications, added Bar.

    The challenge, of course, is that the Codenotary solution requires the addition of one line of code to an application. However, as SBOM mandates become more stringent, the number of application providers that are anxious to comply with rules for securing software supply chains should increase. The issue now is finding a way for both the developer and consumer of that software to streamline a verification process that, in its current form, is too cumbersome to effectively manage.

  • Aqua Security Claims Compliance With Biden’s Executive Order

    Aqua Security Claims Compliance With Biden’s Executive Order

    Aqua Security this week claimed it is the first software supply chain security platform provider to meet the attestation requirements as defined by an executive order issued to federal agencies last year by the Biden administration.

    A supplementary memo issued by the Biden administration required federal agencies to collect compliance attestation letters for all software they use by September 14, 2023. Those attestation letters need to confirm that the software development environments they employ are secure, that sources of code are trusted and that code vulnerabilities have been remediated, provenance for data and code is being tracked using a software bill of materials (SBOM) and that these processes are being consistently maintained.

    Eilon Elhadad, senior director of supply chain security for Aqua Security, said Aqua Security was able to meet those requirements within 100 days of the issuance of that memo. The Aqua Security platform for securing software supply chains is based on a platform it gained with the acquisition late last year of Argon, a provider of a set of tools that provides an agentless approach to integrating with continuous integration/continuous delivery (CI/CD) platforms that maps the development environment. Armed with those insights, it then becomes possible to prioritize and automate the remediation of vulnerabilities based on security best practices and compliance rules, noted Elhadad.

    The Argon platform also includes code-tampering detection technology that performs validity checks to make sure the integrity of the build process has not been compromised.

    Naturally, there’s plenty of time for other security platform providers to comply with the requirements set forth in Biden’s executive order. However, software development teams are also in a race against time. In the wake of a series of high-profile breaches, it’s become apparent how vulnerable software supply chains really are. Cybercriminals have increased their efforts to compromise developer credentials so they can embed malware in software components and activate them downstream if future application incorporate that component, noted Elhadad.

    It’s not clear how closely enterprise IT organizations are tracking the efforts of the U.S. government to secure its software supply chain, but any entity that builds software used by any of those agencies will be impacted. Advocates of DevSecOps best practices within enterprise IT organizations will undoubtedly use the Biden administration’s requirements to define a minimum baseline for securing software supply chains.

    In the meantime, a new front has clearly been opened in the cybersecurity war. The more applications are targeted, the greater the impetus for shifting responsibility further left toward application development teams becomes. The challenge is not just scanning the code being written by developers, but also making sure the software build created by development teams has not been compromised by bad actors that have inserted themselves into the process, noted Elhadad.

    Given the magnitude of the effort required, it’s not likely that every software supply chain will be secured any time soon. However, the responsibility for securing those software supply chains is weighing more heavily on DevOps teams.

  • IBM Adds Fully Managed VMware Service to Cloud Portfolio

    IBM Adds Fully Managed VMware Service to Cloud Portfolio

    At the VMware Explore 2022 Europe conference, IBM this week announced an IBM Cloud for VMware-as-a-Service offering that integrates instances of VMware Cloud with the infrastructure-as-a-service (IaaS) platform managed by IBM in the cloud.

    Rohit Badlaney, vice president of product management and strategy for IBM Cloud, said now that VMware Cloud can be consumed as a subscription service, it’s now possible for IBM to integrate it with its cloud platform to create a fully managed service. Previously, IT organizations would have had to separately license VMware Cloud and deploy it on IBM Cloud themselves, he noted.

    In general, Badlaney said IBM is focused on working with organizations in highly regulated industries that need to run complex workloads in the cloud. IBM is not interested in competing against other cloud service providers to run workloads on commodity infrastructure, he added.

    The majority of applications that run in the cloud today consume a narrow range of memory and storage resources. The IBM cloud is clearly more focused on providing higher-margin services to complement the cloud infrastructure it makes available via its data centers. Less clear is to what degree monolithic applications running in on-premises IT environments are being lifted and shifted to the cloud. While there is clearly a segment of organizations that no longer want to operate their own data centers, the bulk of applications continue to run in on-premises IT environments. The reasons for this include everything from performance requirements and security concerns to regulatory compliance issues.

    However, since most on-premises applications run on VMware virtual machines, much of the focus on cloud migration has revolved around platforms that would not require IT teams to refactor applications to run on a different virtual machine platform. IBM is also betting that, given the current state of the global economy, more organizations will soon be opting to not manage their own data centers. Cloud platforms managed by a third party would enable those organizations to focus more of their own internal IT efforts on application development and deployment.

    Each organization will need to determine for itself whether to treat IT as an operating versus a capital expense, depending on which approach makes the most economic sense. Organizations that have embraced DevOps workflows would need to align the way they build and deploy applications to a managed service.

    In theory, of course, a managed cloud computing service makes IT teams more agile and efficient. Less IT infrastructure winds up being overprovisioned by developers that can programmatically spin up resources on demand. Of course, there are a lot of IT stacks other than VMware Cloud that can be deployed in the cloud. IBM, for example, makes available the Red Hat OpenShift platform to run cloud-native applications on Kubernetes clusters. IBM has not yet committed to offering the VMware Tanzu platform for running those types of applications.

    Not every application is going to wind up running in the cloud, but what is certain is that application environments are becoming more complex to manage in the next era of cloud computing.

  • Rust Momentum Intensifies | Elon Says No WFH

    Rust Momentum Intensifies | Elon Says No WFH

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: People won’t shut up about Rustlang, and Musk mandates Twitter teams return to the office. (more…)

  • A DevOps Reset for a Multi-Cloud World

    A DevOps Reset for a Multi-Cloud World

    In the world of DevOps, only two things really matter: 

    • To release applications and updates as quickly as possible
    • To have access to resources (processing, storage, networks) able to run those apps, as cost-effectively as possible. 

    The measures used to achieve these twin goals should work together seamlessly–otherwise, you’re inefficient. But software development and IT operations have been on separate journeys, and it now takes layers of tools, specialized expertise and lots of precious time to distribute and manage applications where they need to run. Organizations tolerate all this complexity (and the delays and costs that come with it) since they see no alternative. But what if there was an easier way?  I’ll examine the two fundamental shifts driving software development and IT operations and see why current processes are so cumbersome.  

    Shift One: From Monolithic Applications to Microservices

    In the beginning, applications were monolithic, with all functions and code packaged together. That approach was manageable when apps were updated once or twice a year, but not when updates are expected multiple times each day. Finally someone realized that applications would be much easier to build, improve and maintain if they were divided into smaller units called microservices—independent, loosely coupled, individually deployable services, each one addressing a specific function. 

    To support microservices, a technology stack has emerged, similar to steps on a ladder:

    • To make them portable, microservices are packaged in containers—a lightweight, standard way for applications to move between environments and run independently. Everything needed to run the microservice such as settings, system tools, libraries and dependencies is packaged inside the container.
    • A single application could have hundreds of containers associated with it. How do you manage them? Along came Kubernetes (aka K8s), open source software for deploying and orchestrating containers within a cluster of virtual machines. (Note the word cluster—the significance will be discussed momentarily.)
    • Since microservices are updated constantly, how do you make sure the correct version is running? Along came GitOps to provide version control for all updates to all those microservices. Git repositories provide a single source of truth for the desired application state, as well as a record of every code change.

    Finally, we need to set up continuous integration/continuous delivery (CI/CD) for rolling out application improvements and new features. Along came ArgoCD, a GitOps continuous delivery tool for Kubernetes that continuously monitors running applications, compares the current, live state against the target state specified in a Git repository, and resolves discrepancies.

    Shift Two:  From On-Premises to Multi-Cloud 

    Not long ago, IT departments were having hot debates about this strange new concept called the public cloud and whether it could possibly play a role in their operations. But once they discovered how easy it was to spin up resources, the floodgates opened.

    The first tentative steps typically involved hybrid clouds combining an on-site private cloud with spillover into a public cloud for workload spikes. These initial forays mushroomed to dozens or hundreds of clouds, in different locations and with different providers. It’s a mind shift happening in enterprises globally—where they once had a small number of clouds, now their cloud operations are huge, growing and boundless. Companies are also discovering that the cloud is not just an easier, more cost-effective way to run their applications, it unlocks new opportunities.

    Now there are core clouds, edge clouds for hyper-local applications, regional clouds, clouds for high availability and resilience and more. Edge computing is another option, where low latency is required for operations at the customer-facing frontend cloud while backend processing happens in the primary cloud. But this is just the beginning.

    Continuous Delivery is Now Way Too Complicated

    Today, an application may have dozens of microservices distributed across different clouds that need to work together—perhaps some in cloud one, a few in cloud two, others in cloud 40, etc. The scale gets huge very quickly; for example, if 100 microservices are being delivered to 100 clouds, there are 10,000 mutations that have to be configured and managed. 

    This is the new normal, and DevOps needs to adapt to it. Processes should mesh transparently, but connecting microservices across multiple clouds and cloud instances requires inter-cluster communication, which Kubernetes (and GitOps/ArgoCD on top of it) does not natively support.

    To make all this work requires specialized skill sets, so organizations hire teams with expertise in continuous delivery, multi-cloud, networking, security and automation. The first step involves distributing K8s containers to clouds where the microservices are going to run. Some enterprises create their own distribution system, others choose to download, install, and manage third-party software such as open source ArgoCD.

    The second step is more complex: Securely connecting those microservices across different clouds and K8s clusters. This involves integrating complex service meshes, load balancers, API gateways and network/firewall automation tools, all feeding into a centralized console for configuration and monitoring.

    The result is inevitable: Lots of extra costs, inefficiency, potential security risk and delayed time to market with resulting risks to the business. Development teams update microservices daily but depend on CloudOps, NetOps, SecOps and other flavors of Ops to deliver them to the different clouds and clusters where they need to run. 

    Despite the best efforts of these different stakeholders, it can take days or weeks to update cloud networks and security for each change.

    Simplifying Multi-Cloud Operations With an Overlay Network

    When hundreds of microservices are being distributed across more and more clouds and updated constantly, you need an alternative—one that streamlines current operations without sacrificing security or application performance. Let’s set aside traditional methods and think about how it should be done.

    First, the solution should be easy to use, so DevOps people don’t have to be proficient with the underlying technology or be dependent on NetOps, SecOps and/or CloudOps people who are. Instead, just provide some basic information about the Git repository and the clouds where you want the microservices to run, and an overlay network handles the rest.

    It should be comprehensive—integrating ArgoCD, the service mesh, the K8s ingress gateway, zero-trust security, resilience/failover, load balancing and multi-cloud networking — all those elements that normally require assembling and configuring individual tools.

    It should make multi-cloud Kubernetes application operations easy to manage, with a single dashboard where you can securely deploy, connect and monitor microservices in all your clouds and clusters.

    Finally, the solution should be available as a service, rather than having to install an ArgoCD server and try to manage it yourself (or hire a team to support it). And if you have questions or need help, competent people should be available to give you a hand.

    Disruptive – In a Good Way

    Get ready for self-service multi-cloud Kubernetes decoupled from the underlying networking and security details. It’s an approach that’s about to upend how microservices are deployed and managed, so DevOps can get back to what really matters:  Delivering applications as fast as possible, on the resources where they need to run. The ability to deliver new features in a fraction of the previous times while significantly reducing costs and without compromising security will mean a competitive advantage and a stronger bottom line. 

  • VMware Extends Equinix Alliance to Drive Managed Hosting Service

    VMware Extends Equinix Alliance to Drive Managed Hosting Service

    VMware today announced it has extended its alliance with Equinix to launch a managed distributed cloud service that runs instances of its cloud computing platform in hosted IT environments.

    Announced at the VMware Explore 2022 Europe conference, the VMware Cloud on Equinix Metal service takes advantage of more than 240 Equinix data centers in 71 major metro areas around the world to deploy instances of the VMware Cloud platform running atop the company’s virtual machine software.

    Narayan Bharadwaj, vice president of cloud solutions at VMware, said this VMware service extends the scope and reach of the company’s multi-cloud computing strategy beyond the scope of the major hyperscalers and traditional on-premises IT environments.

    The goal is to provide a managed IT environment that provides an alternative for deploying latency-sensitive applications closer to the network edge where data can be processed and analyzed in near-real-time, he noted. In addition, Equinix’s hosted IT environment also makes it possible for IT teams to more easily comply with requirements in highly regulated industries.

    It’s not clear what percentage of applications today are running in managed hosted environments versus a public cloud or local data center. But as more organizations decide not to operate data centers themselves, many of them are discovering managed hosting services are preferable to the cloud for reasons spanning everything from application performance and cost and security to compliance.

    In some cases, organizations are determining that certain classes of longer-running applications initially deployed in the cloud are actually less expensive to run in an on-premises IT environment, noted Bharadwaj. A managed hosting option often provides the flexibility benefits of the cloud at a lower cost for those applications, he added.

    As cloud computing evolves, it’s become apparent that IT is becoming more distributed than ever. Many organizations are finding they now have a mix of applications running on public clouds, in co-location facilities and traditional on-premises IT environments. The challenge is that with each new platform employed to run applications, the total cost of managing IT increases. Regardless of any potential infrastructure cost savings, each platform typically requires a set of dedicated specialists to master the frameworks need to manage it. In fact, the single biggest IT expense remains the cost of labor. VMware is making a case for a familiar IT framework that can be deployed anywhere to rein in those costs.

    DevOps, of course, was created to provide a new approach to automating the management of IT at scale. However, DevOps continues to be employed unevenly, largely because there are not enough IT professionals with the programming skills required to successfully manage IT-as-code. Managed services are gaining traction because, in most cases, they shift the responsibility for managing DevOps workflows onto a vendor such as VMware.

    It remains to be seen just how automated the management of IT will become in the months and years ahead. However, it’s apparent that, in the era of the cloud, more organizations are opting to rely on third parties to manage infrastructure so they can devote more resources to building and deploying applications.