Category: DevOps Toolbox

  • Securing the Software Supply Chain with Behavioral Analysis

    Securing the Software Supply Chain with Behavioral Analysis

    Lately, software supply chains find themselves in a very interesting and uncomfortable position—the industry spotlight—and not in a good way. While significant and costly breaches such as  SolarWinds or Kaseya make front-page news, supply chain attack tactics (e.g. typosquatting or dependency confusion) that target package managers such as npm, PyPI or WinGet can poison downstream applications or compromise developer credentials.  

    The software engineering community has been steadily increasing its use of third-party and open source solutions to help create new offerings. In fact, over the last five years, there has been a 259% increase in the use of open source.

    One reason for this is the simple fact that creating new applications takes time and can strain budgets that are already tight. With open source code, software engineers gain fast access to pre-existing code that’s already demonstrated a proven ability to address the very unique challenge they are looking to solve. By removing the need to reinvent the wheel, the development timeframe is accelerated, the costs are lowered and teams are freed to focus on the creation of new and unique features that the customers demand.

    At this point, turning to third-party code may seem like a no-brainer. However, it can also open the door to potential risks. This is especially true with engineers who, rather than checking software to ensure it is secure and compliant, take the providers’ assurances as gospel. 

    They are not alone. Other groups will try to conduct their initial due diligence at the onset if that’s possible. Soon after they then ease into a “set it and forget it” approach, where they fail to update the code over time. As a result, while the code may appear secure initially, vulnerabilities can emerge over time, and if the software is not continually updated, bad actors can leverage an unprotected window of opportunity. In fact, according to Enterprise Security Group’s “Modern Application Development Security” eBook, 48% of organizations regularly push vulnerable code. The same research also found that 60 percent of organizations have had production application vulnerabilities exploited.

    Organizations conduct static application security testing (SAST) and dynamic application security testing (DAST) to assess pre-production code vulnerabilities. They will also scan with AV before releasing software, examine signing certificates, and code quality. Yet, despite these efforts, they remain challenged by gaps in security processes and the ability to sufficiently inspect large, complex and multi-layered software packages. What’s missing is the ability to conduct in-depth analysis to pinpoint behavioral differences between compiled software versions.  

    Malicious tampering can often involve changing how the software interacts with the system on which it is deployed.  Differential behavior analysis highlighted below makes it easier to detect those unusual changes. For example, having an application suddenly add a pre-install script that downloads files via certutil is highly unusual. If the addition was planned, reasons for the change would be well documented and it would be associated with a significant new feature. For this type of change to happen in any other scenario is suspicious and deserves further investigation before the software is released. In this case, such action would have caught ua-parser-js developer’s account compromise.

    supply chain

    With the software supply chain at risk and with shared code the new normal, what’s needed is software assurance. 

    Software assurance allows teams to inspect every application layer within an installation package for the presence of software tampering, malware and other indicators of software supply chain attacks.   

    Begin the software assurance process with the deep inspection step through recursive package decomposition. The resulting software bill of materials (SBOM) becomes so much more than a build manifest (a list of components that should be in the final build). It becomes the means to determine exactly which components have unacceptable build quality or those that contain unwanted software behaviors. This enables developers to verify the code they are working with and take appropriate action to protect their customers and partners from the majority of software risks. These assessments include:

    • Software grading: The software package and every included component can be graded based on the types and severity of security issues found. Using a grading system makes it easy for software buyers to gauge the level of risk posed by a software package and determine whether additional deployment measures can be taken to mitigate those risks. For developers, component grading makes it easier to prioritize their remediation efforts and aids in the selection of higher-quality third-party components.  
    • Application hardening: Activating specific build or compiler options can mitigate vulnerabilities and protect applications against attack—but only if they are implemented correctly. Assessing whether these mitigations are correctly implemented ensures that these protection mechanisms will work as expected. 
    • Binary behavior analysis: This allows teams to fully understand how each software component interacts with the system on which it will run. The ability to understand third-party component behaviors, even when developers have no access to the source code, delivers a more comprehensive understanding of supply chain risks. Checking for unusual software behaviors or unexpected behavioral changes between one version and the next is often the only way to identify software tampering by a malicious actor. The ability to have this final check before distribution enables software developers to validate that the software being released is trustworthy.

    For companies that are using software to create business value or producing software that is mission-critical for their customers, turning a blind eye or making software assurance assumptions can no longer be tolerated. In today’s climate where increasingly sophisticated threats loom, inspecting software and monitoring updates for signs of tampering, malicious or unwanted additions is essential and must become a part of standard software development practice. 

  • Why Do You Need GitHub Backup?

    Why Do You Need GitHub Backup?

    You’ve probably heard the joke that there are two types of people in IT: Those who do backups and those who will start. Though it’s still valid, this joke has become less relevant to businesses and professionals. The IT industry has been increasing expenditures on security for years, and backup is a critical area. However, despite the growing awareness of the need for backups and the wide availability of modern backup solutions, the problem still exists. The number of security breaches is growing, and the topic of data security looks like an endless arms race. So what can organizations do?

    First, let’s analyze some data and trends. Year over year, the number of cyberattacks, especially ransomware, is increasing. The year 2020 saw attacks intensifying due to the pandemic and the sudden shift to remote work, for which, unfortunately, not everyone was prepared. Once organizations got better at enabling effective work-from-home models, the hope was that everything could settle into a new normal. Unfortunately, the new norm became these increased attacks.

    It’s a bit like the metaphysical yin and yang—two opposing but complementary forces. One drives the other. Suffice it to say that the estimated cost of the global damage caused by ransomware in 2021 is as high as $20B! And a ransomware attack occurs, on average, every 11 seconds around the world.

    According to an Identity Theft Resource Center (ITRC) report, by the end of September 2021, there were more incidents of this type than during all of 2020. The authors of the report emphasized that they found 26 cases where cloud databases were unsecured. As a result, hackers were able to access confidential data belonging to 99 million people.

    Git Threats: Are my Bitbucket/GitLab/GitHub Repositories Secure? 

    Back in May 2019, ransomware attacks impacted hundreds of repositories on GitHub, GitLab and Bitbucket. The attack wiped away all the data and left only one piece of information: The amount of ransom demanded and a method of payment. Eventually, most of the data was recovered but the cost and the amount of time spent recovering from the attack was enormous.

    According to the Cisco Benchmark Study, approximately 40% of companies experienced downtime longer than eight hours due to a major failure. And 39% reported that at least half of their systems had been affected by a serious breach. According to IBM, the total average cost of a data protection breach on a global basis is as much as $3.86M, and the highest ransom demanded by cybercriminals in 2020 was $15 million. These numbers are scary. On the other hand, in most cases of successful ransomware attacks, the ransom is ultimately not paid; even if organizations do not pay the ransom, the mere fact that they fell victim and experienced failure or downtime can be very expensive.

    GitHub as Backup Tool

    GitHub provides many useful security tools. However, we must be aware of two things: What does GitHub backup really mean and what are its features? And what responsibility do cloud services providers have versus users’ responsibility for security? Let’s start with the latter.

    Most cloud service providers (including Amazon, Microsoft, Google, IBM, Salesforce, GitHub or Atlassian) operate on the basis of the so-called shared responsibility model. Users of cloud services most often assume that providers are fully responsible for their protection. However, providers are primarily responsible only for ensuring the security and availability of infrastructure, software and access, period. Users are responsible for the security of the business data stored as part of these services. So users themselves have to take care of backup and disaster recovery plans and solutions. In short: Providers are responsible for the security of the cloud itself and users are responsible for data security in the cloud. And at this point, it is worth pointing out that, according to data from the UK’s CybSafe, in 2019, 90% of data breaches were caused by user error.

    It can happen to any of us—a ransomware attack, phishing, loss of access to a GitHub account or an entire computer or simply overwriting another developer’s work in a repository. It affects both individual users and large corporations. In July of 2019, Ubuntu Security reported that the credentials for a company-owned GitHub account were compromised. Hackers used these compromised credentials to create repositories, issues, pull requests, etc. The attack did not cause a major crash, but repairing the damage took some work and restoring some repositories or issue trackers to the previous state was difficult.

    There are some common features any good backup should have:

    • Automation (i.e. daily backups)
    • AES encryption with its own encryption key
    • Versioning
    • Long-term data retention
    • Disaster recovery process
    • Easy monitoring (audit logs, email notifications)
    • Central management
    • Multi-tenancy (to manage admins, privileges and roles)
    • Scalability

    Based on these criteria, GitHub (and other similar hosting services) cannot be considered a proper backup tool. GitHub is a great open source project, but its purpose is completely different.

    How to Back Up Manually

    Since the cloud service itself is not enough, how can you take care of GitHub backup? Well, you could do it on your own. And often, especially in small businesses, this is the preferred method. It may seem like a good idea at first. Knowing Git well, we can create appropriate scripts that create backups for us that give us full control over what is happening without having to pay anyone for it. But this is very risk and not profitable in the long run. Disk space costs money; our employees’ time to create scripts and perform the backup is another cost. And the most important thing, in this case, is that these scripts must be maintained and updated all the time, so they constantly generate additional costs. Any change in such a script may cause an error and, as a result, deprive an organization of a working backup. Of course you could also create an appropriate mechanism to test it, but that’s an additional cost. Manual GitHub backups do not end with writing a single script.

    I’ve experienced this myself. In one project, backups were generated using such a script and then kept on our own servers. It was cheaper this way. But we did not have any validation of the created backup. One day, while updating the backup scripts, we did a manual test and it turned out that we had a serious problem—the backup was created correctly but its name did not change, so we kept overwriting the same archive constantly! The effect? It turned out that we didn’t have any copies older than one month! Luckily for us, they weren’t needed because the systems and databases were working properly at that time and there weren’t any incidents, but it makes me cringe just thinking about “What if …?”

    All in all, manually writing backup scripts is not a very good idea for many reasons. The low cost of this solution is only theoretical; with time, the cost of maintaining this mechanism increases and, in practice, often only one or two people are responsible for it, which creates additional risk. Okay, you might have more control, but overall you are wasting time and money. The backup itself is also not enough, because you need a proper restoration solution for systems or data in the event of an incident. There’s also the question of how to create a backup of the script that creates the backup? Are you sure you cannot make better use of your employees’ working time?

    How Much Does it Cost?

    It is difficult to accurately measure this; it all depends on the level of complexity of systems, the number of repositories, the skills of your team, etc. However, you can estimate how much the lack of access to services or programmers’ downtime will cost. You can also calculate the development and maintenance costs of writing, testing, maintaining and updating your own backup scripts. The history of GitHub attacks and crashes shows that the data is usually recoverable, which is good news. On the other hand, the time when services are unavailable or when teams are unable to work can be very costly.

    Third-Party GitHub Backup Tools

    Another solution—and, in my opinion, a better one—is to use third-party backup software.

    In fact, in the GitHub documentation, it is recommended:

     “Backing up a repository: You can use the API or a third-party tool to back up your repository.”

    If you can use the GitHub API, why do you need a third-party GitHub backup tool? Well, first of all, such applications are created by experts in a given field who have knowledge, experience and stay up-to-date on the current security trends. Second, these solutions are ready and available right away; you don’t have to spend time and money reinventing the wheel. Yes, there is a cost, but in the long run (taking into account the factors described earlier) the cost usually turns out to be much lower than a bespoke solution. Outsourcing backup management responsibilities may be incredibly beneficial and will allow us to focus on developing our business instead of managing GitHub repository backup all over again.

    When it comes to backup, be smart. If external third-party tools allow us to develop our products faster and more efficiently, then we should not hesitate to use them. And never forget to implement proper backups and disaster recovery plans. Taking care of it today will help ensure a more secure future.

  • GraphQL as a Meta Layer

    GraphQL as a Meta Layer

    There’s a lot of interest in GraphQL lately. The query language is excellent for data retrieval, and it could act as a more usable mechanism to evolve the traditional REST API integration approach. But as adoption grows steadily, architects are now considering the implications of managing GraphQL at scale.

    Certain issues may hinder GraphQL in practice. To review, security concerns require a nuanced approach to authorization. This is because it wraps multiple data retrieval points into a single request. Without native caching, performance could also suffer. Changeability is also required to continually update the graph, which may ruffle feathers with those seasoned in the world of REST where a guiding tenet is to build for longevity using web-compliant methods.

    According to Jens Neuse, CTO, WunderGraph, there is a simple way to mitigate most of these issues and harmoniously work with various API styles. To Neuse, the core problem is that GraphQL is not meant to be exposed over the internet. Instead, he advocates for interacting through a gateway. Such an intermediary would enable more implicit calls and proper authentication and authorization for specific underlying functions and resources. Using GraphQL as an internal integration layer could also help combine disparate APIs into a similar language, exposing GraphQL-like usability for frontend developers while allowing them to hit any API style on the backend.

    Below, we’ll consider the drawbacks of exposing GraphQL directly and see how an intermediary layer could benefit development. We’ll also uncover what open source software is on the horizon that could power this setup.

    Why GraphQL Shouldn’t be Exposed Publicly

    Facebook, the creator of GraphQL, uses an internal GraphQL API to power all of its apps across Android, iOS and web browsers. (This is not to be confused with their public Graph API). Interestingly, if we look at Facebook’s use of GraphQL, we see these endpoints are not exposed to the public web at all.

    It’s true. Open up Developer Tools in Chrome, and you’ll see there is not a single mention of a root HTTP endpoint like https://api.graphql/. Functions name GraphQL, sure, but they call it more implicitly. Other companies, like Twitter and Airbnb, use a similar abstracted approach to interact with a private GraphQL.

    In fact, most GraphQL APIs are not public. APIs.guru only charts 35 public GraphQL APIs—notable services include GitHub’s GraphQL API, Shopify Storefront and GitLab. This number is minuscule compared to the total number of public APIs, at over 24,000 according to ProgrammableWeb.

    A Layer In Between

    If we treat it as Facebook intended (and how they use it in production today), it could reverse the issues above, said Neuse. “These problems come down to our core belief that GraphQL is not supposed to be exposed over the internet,” he said.

    But if clients do not access a GraphQL endpoint, what are they interacting with? According to Neuse, the ideal architecture involves a layer between the client and the server. Such a layer would validate queries and represent verbose calls with simple functions. The process would involve a handshake as follows:

    1. Take query, store it on a server.
    2. Validate it; make sure it’s not malicious.
    3. Send back a handle to the client.
    4. Then, execute the query.

    Such a process could also enact universal policies on a per-function basis, thus solving potential authorization issues when fetching data from multiple backend services with a single query.

    “The issue is that using the query language comes with a cost,” Neuse said. “Not exposing GraphQL directly but ‘compiling’ it to a JSON-RPC API when deploying solves these problems.”

    Thus, the scalability issue isn’t so much an issue of size but of access. “GraphQL can be very valuable, even in small environments,” said Neuse.

    The Next Evolution of a Virtual Graph

    Another potential benefit of using GraphQL as an intermediary is combining APIs; a “virtual graph,” as Neuse calls it. This virtual graph offers a common integration language to interact with various API styles, whether REST, GraphQL, gRPC or webhook, in a GraphQL-like manner.

    Consider the ease with which package managers like npm enable developers to instantly install dependencies. For example, installing a package like React.js is as simple as initiating the command npm install react within Terminal.

    On the other hand, the API integration is very cumbersome. Users must read through documentation, create an account on a third-party site and download an SDK to call the service in their preferred language. So, why isn’t looping in dependencies like APIs and cloud services as simple as other common dependencies?

    According to Neuse, one reason is that the REST paradigm is obsessed with the resource constraint—aside from HATEOAS, it lacks a concept of relationships between data and fields. A virtual graph could enable a straightforward process similar to package managers, said Neuse. Interestingly, the WunderGraph team plans to open source a project that allows just that ability.

    GraphQL as a Meta Layer

    Many folks assume that GraphQL and REST are mutually exclusive. However, as we’ve seen, there are ways to use them in combination. Plus, with an abstraction layer, the REST versus GraphQL comparison becomes just an underlying technical nuance.

    “If you compare GraphQL to other specifications, like OpenAPI spec, you see GraphQL has the fastest-growing community,” said Neuse. As of 2021, JSON Schema is the most popular, used by 75% of developers, followed by Swagger 2.0 (54%), OpenAPI 3.0 (40%) and GraphQL (31%) according to the Postman State of API Report. While this number may be small now, 35% of respondents also said they plan to use GraphQL in the coming year.

    “It’s a very, very interesting movement,” said Neuse. What began at Facebook as a framework for data fetching for React apps has now expanded into something much bigger. Within this second new movement, largely driven by companies like Apollo and Hasura, GraphQL becomes the new data layer, he said.

    “Still, everybody is looking at GraphQL thinking they must migrate from REST—this is the wrong direction,” said Neuse. Instead of migrating all existing REST APIs to GraphQL, he predicts the industry will coalesce on using GraphQL as the integration language for querying REST APIs. A meta layer, if you will.

    Of course, meta has been a bit co-opted lately with Facebook’s rebranding …

  • ServiceNow Acquires DotWalk to Gain AI for App Testing

    ServiceNow Acquires DotWalk to Gain AI for App Testing

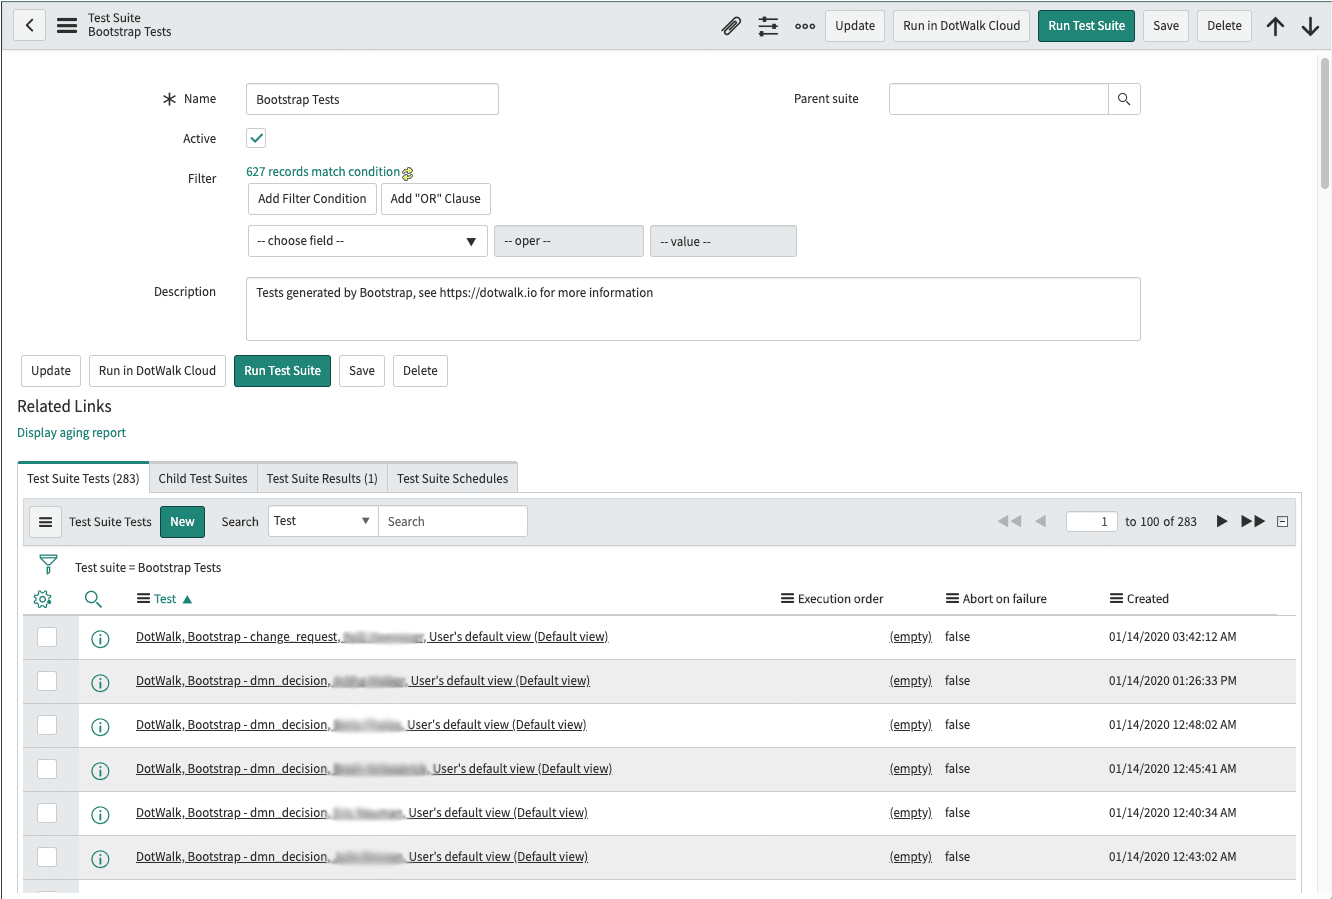
    ServiceNow today revealed it has acquired DotWalk to gain an artificial intelligence (AI)-infused application testing capability that runs natively on its software-as-a-service (SaaS) platform.

    Joe Davis, senior vice president for platform engineering at ServiceNow, said that testing capability will be made available free of charge to all organizations that build custom applications on the company’s platform.

    The number of custom applications being built on the ServiceNow platform has risen sharply since the start of the pandemic. Many organizations have taken advantage of the low-code tools provided by ServiceNow to build a range of applications that use the company’s SaaS applications as a foundation. That approach enables them to more quickly build applications that drive a wide range of digital business transformation initiatives.

    Davis said ServiceNow is committed to enabling organizations to improve the quality of those applications using a DotWalk testing capability that eliminates the need for developers to build and run tests themselves or for organizations to hire dedicated application testing teams.

    ServiceNow

    ServiceNow decided to acquire DotWalk because the company built a testing platform using machine learning algorithms specifically for the ServiceNow platform, noted Davis. The DotWalk tools also analyze logs in the background to identify and validate error sources that can arise during any application upgrade process.

    While there are a large number of professional developers that build applications on the ServiceNow platform, the company is also trying to encourage more so-called citizen developers to build applications. The challenge is many of the end users building applications lack an appreciation for design, security and what it takes to make sure an application scales as more users employ it. Testing tools infused with AI should make it easier for developers, regardless of experience, to build enterprise-class applications.

    Of course, professional developers will also benefit from AI-infused testing tools. Many developers have a tendency to cut short the application development process as they rush to meet application delivery deadlines. The end result, however, is that an application must be updated almost immediately after it has been deployed in a production environment. Testing tools that make use of AI will enable professional developers to more easily run tests they don’t have to build and then maintain, said Davis.

    One way or another, the number of custom applications built on SaaS platforms will increase as organizations digitize more processes. In the last year, more organizations have become adept at extending these platforms using a wide range of low-code tools that automate many aspects of application development. A significant percentage of those organizations are now also adopting DevOps best practices to better manage the pace at which those applications are developed and deployed.

    In the meantime, it’s too early to say precisely how AI will transform application testing. However, one thing that is certain is that even as the number of custom apps grows, applications will be more thoroughly tested before being deployed in a production environment.

  • Netlify Acquires OneGraph to Integrate GraphQL APIs

    Netlify Acquires OneGraph to Integrate GraphQL APIs

    Netlify this week announced it has acquired OneGraph, a provider of a platform that simplifies the integration and management of application programming interfaces (APIs) based on the GraphQL query language.

    At the same time, the company is committing $1 million to sponsor open source projects and setting aside $10 million for a Netlify Jamstack Innovation Fund that will help drive the development of emerging technologies. Those technologies will be consumed via the platform the company created based on Javascript, APIs and a markup language (referred to as Jamstack) to accelerate web application and website development. Rather than becoming investors in those companies, Netlify intends to make those funds available to advance the development of technologies that benefit the overall community.

    Fresh from raising an additional $105 million in funding, Netlify CEO Matt Biilmann said Netlify is committed to an ecosystem through which developers will be able to consume a wider range of services via both REST and GraphQL-based APIs. OneGraph will provide the core foundation for adding support for GraphQL to the Netlify platform, he noted.

    Overall, Netlify is trying to reduce the friction that developers encounter building web applications and the sites they run on, added Biilmann. That’s becoming especially critical as developers increasingly build microservices-based applications that invoke APIs to consume backend services that are made available via the Netlify platform, he added.

    Earlier this year, the company made available Netlify Build Plugins that provide DevOps teams with a set of continuous integration/continuous delivery (CI/CD) workflows for building websites and web applications. Designed to be launched from within a Netlify platform, those plugin makes it possible to build a web application or website that can be launched directly from within a Git repository.

    The overall Jamstack philosophy enables DevOps teams to separate the development of frontends and backends of websites and applications. That approach is agnostic as far as any specific JavaScript framework is concerned, but it does define a way to automate the build process for a web application or website.

    A recent survey of more than 3,000 Jamstack developers published by Netlify finds one-third of survey respondents have worked on sites serving millions of users over the last year. Nearly two-thirds of survey respondents (62%) work outside the tech industry, including in advertising and marketing (21%), media and publishing (14%), education (14%), financial services (13%) and business support and logistics (13%). Well over a third (38%) work for a technology company. About a quarter (26%) have more than 10 years of experience. Top Jamstack benefits cited by all types of developers are performance, uptime, speed of development, security, compliance and avoiding vendor lock-in, the survey found.

    Jamstack is, of course, not the only framework for building web applications and the sites they run on. DevOps teams are increasingly being tasked with building a much wider range of external applications to drive digital transformation initiatives that are typically built using some type of JavaScript framework. The next big DevOps challenge, of course, is that as the number of applications being built continues to increase, so does the number of applications that need to be maintained and continuously updated.

  • Kyndryl Aligns with Microsoft in the Cloud

    Kyndryl Aligns with Microsoft in the Cloud

    Following its spinout from IBM, Kyndryl has allied with Microsoft to increase the scope of IT services it provides on the Azure public cloud.

    Stephen Leonard, leader of global alliances and partnerships for Kyndryl, said that as part of this initiative, Kyndryl will be expanding the scope of the services it provides to both organizations building and deploying applications as well as those looking to migrate existing applications to the Microsoft Azure cloud.

    Over time, Kyndryl will expand its cloud services to include additional public clouds as part of a larger effort to enable organizations to embrace a hybrid cloud approach to enterprise IT that spans multiple on-premises and cloud computing environments.

    In the meantime, as part of the first partnership established by Kyndryl, the two companies are committing to providing services to address data modernization and governance, security and application workloads infused with artificial intelligence (AI) capabilities. The two companies also plan to establish a co-innovation lab. Microsoft is also committing to establishing a Kyndryl University for Microsoft.

    Leonard said given the overall shortage of IT expertise, more organizations than ever are relying on external IT services to, for example, accelerate application development. Kyndryl plans to work with those organizations to best evaluate where specific classes of application workloads might best be deployed, he noted.

    It’s become increasingly clear that more organizations are attempting to integrate third-party IT services within DevOps workflows. In some cases, that means standardizing on an opinionated DevOps workflow defined by the IT services provider. In other cases, the IT services provider is focused on a specific task such as securely provisioning infrastructure on behalf of developers.

    Regardless of the approach, however, DevOps workflows are evolving into a team sport made up of both internal and external IT professionals that are trying to bridge the cultural divide that always exists between different organizations. Which IT services provider organizations ultimately select often has as much to do with how flexible they are from a cultural perspective as much as it does their technical expertise.

    For its part, Microsoft is counting on IT services providers such as Kyndryl to increase the total number of workloads running on its cloud. Now that Kyndryl is independent of IBM, it is free to establish partnerships that previously would have been more complex to navigate.

    Of course, it’s up to each organization to determine the degree to which they prefer to work with a larger IT services provider versus a smaller rival that may specialize in one specific area or that is simply a better fit for a smaller company. The one thing that is certain is that as IT continues to become more complex, it’s not feasible for organizations to hire all the IT talent they require on a full-time basis. Organizations will need to carefully evaluate when it makes more sense to consume certain IT services as a function provided by someone else versus attempting to hire and retain talent to maintain that service themselves.

  • Nvidia/ARM Wavering | Google Outage Outrage | Backblaze IPO on Fire

    Nvidia/ARM Wavering | Google Outage Outrage | Backblaze IPO on Fire

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    Nvidia Can’t be Allowed to Buy Arm

    First up this week: Nvidia’s faltering attempt to buy Arm: Regulators around the world are alarmed by the idea. And now the UK—the legal home of the company—has taken the next step, which could nix the deal.

    Analysis: RISCy home for ARM

    This matters because ownership of the ARM ISA and the core designs would be a huge strategic stick to beat Nvidia’s competition with. Arm doesn’t make chips—it licenses technology to Nvidia and many of its competitors—AMD, Apple, Broadcom, Samsung and Qualcomm, to name but five. So this deal really shouldn’t go through, regardless of Nvidia’s fluffy PR reassurances.

    ARM chips aren’t just found in 99% of smartphones, but are an increasing fixture in the datacenter—especially where “performance per Watt” is important. They’re even found in exascale iron, including the Riken Fugaku, the world’s fastest supercomputer.

    Helen Thomas: Nvidia faces tough Arm wrestle

    It is one thing for a regulator to give your deal a thorough going-over. It is another for it to imply publicly that your assurances [aren’t] credible. … Nvidia got both from the UK’s Competition and Markets Authority. … The CMA’s full phase 1 report doesn’t make for easy reading.
    …
    The transaction, which was announced in September 2020, is bogged down in regulatory reviews around the world: … Arm’s “neutral” business model has always made it a difficult acquisition. … Arm licenses its designs to other chipmakers, providing scope to restrict rivals’ access.
    …
    Arm was a political talking point in 2016, when its sale to SoftBank … was waved through with embarrassing ease. There is now a much more muscular political take on UK national security concerns with a particular focus on tech.


    But if it’s owned by a Japanese company, why is the UK getting involved? Glad you asked—Aighearach answers:

    What did they buy? Shares of a UK company. … Then it is a UK company! … Buying shares is buying ownership, but it doesn’t move the company to another jurisdiction.
    …
    This blathering about “sold to a Japanese firm” is getting old.


    Nvidia claims, “The transaction will … boost competition and innovation.” Falmari finds that hilarious:

    Did Nvidia’s spokesperson previously work as a stand-up comedian? Because as jokes go, “boost competition” is a whopper. [Do you think] that’s what a company like Nvidia wants—to boost the competition?


    Google Cloud Outage has Ripple Effect

    Google’s load balancers all went offline for two hours on Tuesday. Aside from the knock-on Google Cloud failures, DevOps tools such as BigCommerce, Datadog, Deno, Discord, Egnyte, Evernote, Linear, Netlify and Toggl were reported to be affected. But perhaps the worst impact was felt by the poor, unfortunate users of Pokémon GO.

    Analysis: Paralysis

    In theory, putting all your eggs in one basket is okay—so long as that basket can reliably stop your eggs smashing on the pavement. But this isn’t the first time we’ve seen Google Cloud issues such as this; I can’t imagine it’s the last.

    Steven J. Vaughan-Nichols: Google glitch triggers major internet outage

    The result? Many of us have seen 404 errors when trying to get to some of our favorite web pages. … There appears to be more major sites having problems than not.
    …
    The specific problem seems to be with the GCP load balancers. These, working with Google’s Cloud Delivery Network (CDN) [are] designed to stop website failures and Distributed Denial of Service (DDoS) attacks by putting your website behind a single anycast IP.


    Are you feeling a touch of déjà vu? jeffbee, too:

    This is a sort of repetitive outage for Google. They’ve wiped out the GSLB configs before.

    A year ago there was also that big outage where they blanked out the whole Gmail delivery config and started rejecting all mail. … Config safety is not their strong suit.


    The #3 IaaS provider won’t get to #2 if it keeps this up. Here’s u/totopapa:

    I’m trying to convince my company to switch from AWS to GCP but an outage like this one is definitely a showstopper.


    Backblaze IPO Burns Brightly

    Backblaze is now NAS:BLZE. In its first week, the stock jumped 60%.

    Backblaze is well known for its tiny-margin consumer backup product and its open-source “storage pod” hardware—but is less well known for its DevOps-focused “B2” cloud storage service.

    Analysis: Can it Avoid Death-by-Packrats?

    Backblaze is trying to grow this newer DevOps business, without losing its classic consumer chops. But many of its former competitors have essentially dumped their “unlimited” offerings—it’s the old tragedy-of-the-commons problem.

    Jordan Novet: Backblaze [goes] public on small valuation and minimal funding

    In an era of blockbuster market debuts preceded by astronomical private financing rounds, Backblaze … a cloud service for backing up data … is a throwback to a time when sub-billion-dollar companies routinely went public to raise capital and build their profile … to win the trust of customers.
    …
    Backblaze shares climbed 24% in their debut on Thursday and another 12% on Friday, lifting the price to $22.31 and giving the company a market cap of around $650 million. … By the standards of its peers, Backblaze is a micro-cap.
    …
    One of Backblaze’s competitors is Amazon, the world’s fourth most valuable U.S. company. … Backblaze currently stores two exabytes of data — that’s 2 million terabytes — and has a half-million paying customers.


    Donovan Jones: Backblaze Targets $100 Million IPO

    The firm provides cloud-based storage services to small businesses and individuals worldwide. BLZE has grown revenue and gross profit impressively through the 2020 pandemic period and the IPO appears fairly valued, so is worth a close look.
    …
    The firm’s financials show strong revenue and gross profit growth. … The firm’s dollar-based net revenue retention rate for 2020 was 114%—a solid result. … The market opportunity for providing cloud-based storage services to small businesses and individuals is large and expected to grow at a material rate. … As for valuation, compared to partial competitor Dropbox, management is seeking the same Enterprise Value/Revenue multiple. [However] the combined revenue growth rate and EBITDA percentage rate … was 3% as of June 30, 2021, so the firm needs improvement in this regard.


    But there’s a long way to go, opines John Kozubik (aka rsync):

    Of the ~500,000 customers, 70,000 are B2 customers and 430,000 are “backup” customers—which are flat-rate “unlimited” users. … Roughly 85% of the user-base are paying $7/mo for “unlimited backup.”
    …
    These flat-rate users are very fickle and price-sensitive. … Roughly 85% of the user-base are paying $7/mo for “unlimited backup.” … It’s a fools errand to pursue this market and I assume the pivot to B2 was to build something more sustainable with a much higher price and usage ceiling.


    The Moral of the Story: Success is a journey, not a destination


    You have been reading The Long View by Richi Jennings. You can contact him at @RiCHi or tlv@richi.uk.

    Image: Kristin Wilson (via Unsplash)

  • Managing GraphQL at Scale

    Managing GraphQL at Scale

    GraphQL, the query language invented by Facebook, has attracted a lot of interest as a means to conveniently access data programmatically. GraphQL structures internal services with a unified schema for data, empowering product engineers to easily grab what they want from many microservices to populate the user interfaces (UIs) they’re creating. By unifying company data into a single graph, GraphQL combines the benefits of SQL with the ubiquity of API access.

    However, GraphQL does introduce some challenges when you’re trying to scale it across a large enterprise and partner ecosystem. For example, since GraphQL channels all requests through a single endpoint, security must carefully segment access to all the underlying infrastructure to avoid data overexposure. Matt DeBergalis, Apollo’s co-founder and CTO, also identified potential issues around changeability and performance when adopting a graph at scale.

    As the use of GraphQL within large organizations grows, development teams will have to overcome these obstacles—especially if companies intend to productize public APIs and reuse the same single graph company-wide. I recently met with DeBergalis for an update on managing GraphQL at scale. According to DeBergalis, we’re still in the early days of the graph revolution. And, future GraphQL maturity will require more rules-based declarative architecture, efficiency improvements and the adaptability to enact agile iteration of graph schemas.

    State of GraphQL Adoption

    So, what is driving the rise of GraphQL? Well, DeBergalis noted three key contributing factors:

    1. Many many microservices. In recent years, there has been an explosion of microservices. These modular services can be challenging to wrangle and are often exposed inconsistently throughout a software ecosystem.
    2. The rise of omnichannel platforms. Product engineers must now port the same data across disparate devices, whether streaming in a browser or on a Peloton screen.
    3. Users expect a hefty, data-rich experience. Expectations are at an all-time high. It’s now expected that an e-commerce shop, for example, will include product recommendations, auto-fill keyword search, pricing by geography and many more advanced features.

    Juggling all these factors creates a “complexity bottleneck,” DeBergalis explained.

    GraphQL responds to such complexity, helping unify the backend to enable product developers to fetch precisely what their client applications require. And, GraphQL adoption took off pretty quickly, particularly among product engineering teams, DeBergalis added. GaphQL plays nicely with familiar languages and frameworks like JavaScript, React and Relay. It’s also a bit different than previous trends, with demand being driven more by the database folks; “query people are really leading the charge,” he said.

    With the right technology stack, developers can add a graph layer between the underlying core APIs and the UI they are building, creating a universal API with a self-documenting schema. “For the developer, the amazing thing about GraphQL is throwing away all this boiler code,” DeBargalis said. GraphQL acts as “a foundation for tomorrow” to help deliver future business requirements, he said.

    With regard to architectural styles for APIs, 94% still use REST and 31% use GraphQL, according to the 2021 State of API Report from Postman. Though this percentage may seem small now, GraphQL adoption is steadily growing among large companies, such as PayPal, Netflix, Shopify, GitHub and Airbnb.

    Three Issues When Scaling GraphQL

    Using GraphQL is like using a mobile phone. You wouldn’t want to use a different phone every time you called a different number, would you? You would rather have all your contacts accessible from the same device. Similarly, GraphQL excels the more functionality is added.

    “Due to the network effect, a graph becomes more interesting as we publish more into it,” said DeBergalis. “What we have found is that GraphQL is most interesting and valuable at scale.” So, what are some inevitable consequences of GraphQL at scale? DeBergalis outlines three main architectural issues.

    Performance

    Performance downsides are one disadvantage that developers often cite when considering GraphQL. GraphQL has no built-in caching features, and the payload query could introduce additional latencies. Mitigating lower-level issues around throughput and reliability will likely require additional tooling from the community, DeBargalis said. This is partially why the Apollo team has begun to embrace Rust in new attempts to make infrastructure for GraphQL routing hyperefficient.

    Changeability

    A second problem enterprises may encounter when scaling GraphQL is embracing agility for such an all-encompassing fabric. “The companies that do GraphQL really well change it all the time—they treat it like a product,” said DeBergalis. This agility is at odds with the traditional REST API approach of building for longevity, which makes that approach extremely averse to breaking change.

    The reality is that when a company embraces a single graph, it may be pushing hundreds of schema changes every day. Different internal teams may maintain their own slice of the graph, defining it differently. Plus, maintenance roles may shift from team to team over time, noted DeBergalis. “If you try to waterfall what your inventory model should look like, you won’t get anywhere,” he said.

    Balancing change and stability will likely require a two-pronged approach to GraphQL. You want to continually iterate the graph with experimental features but also depend on certain functionality to preserve backward compatibility for client integrations. Satisfying both sides will likely require a change management strategy for iterating quickly, as well as enterprise-grade service level agreements (SLAs) to retain a firm bedrock on which to build more permanent data models.

    DeBergalis also described how observability is important for obtaining a clear picture of graph environments. This is one area where GraphQL shines—since clients request precisely what they need, you are never left wondering which methods are fetched but not implemented in production, as could happen with REST API management. According to DeBargalis, tracking fine-grained GraphQL usage with KPIs can help direct how the data model should evolve over time.

    Authorization

    Finally, perhaps the most significant concern surrounding GraphQL at scale is apportioning the appropriate access to users and devices. As a single unified endpoint can connect to a vast array of data behind the scenes, large GraphQL implementations will require a strategy for how that one unified graph can be implemented in parts.

    Without the proper access control, GraphQL could improperly expose personally identifiable information (PII). For example, a FinTech company may have a rule that requires a customer service representative to only have visibility into a customer’s transaction history if the customer has filed a support ticket in the last few days. Or consider data custody—a business working in the EU must comply with regulations on where data can and can’t live.

    Safeguarding GraphQL will require a declarative setting that integrates authorization control and context into GraphQL queries. To implement this, DeBergalis advocated for a command-and-control style. First, you build the schema around the data and problem statement. Next, you integrate rules field-by-field, marking sensitive touchpoints as PII.

    With rules baked into the query, you can have a more solid understanding of the surrounding context. “Authorization is actually a lot better at graph level,” said DeBergalis. “It’s the layer that has semantic understanding.”

    Future of GraphQL Scalability

    “Once you have a graph, you want to use it for everything,” said DeBergalis. The heritage of GraphQL is JavaScript, the language of the product world. And, the graph approach delivers an excellent experience for product engineers. The sheer usability and productivity benefits of GraphQL indicate incredible potential for projected use in the years to come.

    As we’ve discussed, scaling GraphQL across an enterprise will likely require performance improvements, a path for schema adaptability, policies to handle authorization for queries and greater accountability for business metrics. While GraphQL certainly has existing momentum among a subgroup of engineers, there are plenty of opportunities to introduce more training and educational curriculum to spread greater awareness.

    Furthermore, for those coming from a traditional REST API mindset, GraphQL is a bit of a new paradigm that will require some massaging to expose graph endpoints as a productized API. Doing so will likely involve marking select parts of the larger graph to expose to partners. “Starting with an internal GraphQL use case works really well, but productization around GraphQL is coming,” said DeBergalis.

    The value of a unified graph is so strong, and the bottom-up hunger for a graph environment is so intense that increased GraphQL adoption feels like a given. “At this stage, the focus is on expansion,” said DeBergalis. “How do we roll this out to more teams?”

    “We know there’s going to be a graph in every company—not a lot of little ones,” said DeBergalis. “Every company’s going to need a graph.” When that day comes, the architectural challenge will be breaking apart the graph into pieces. “That’s the next big frontier.”

  • Google Makes Fuzz Testing Integration Tool Available

    Google Makes Fuzz Testing Integration Tool Available

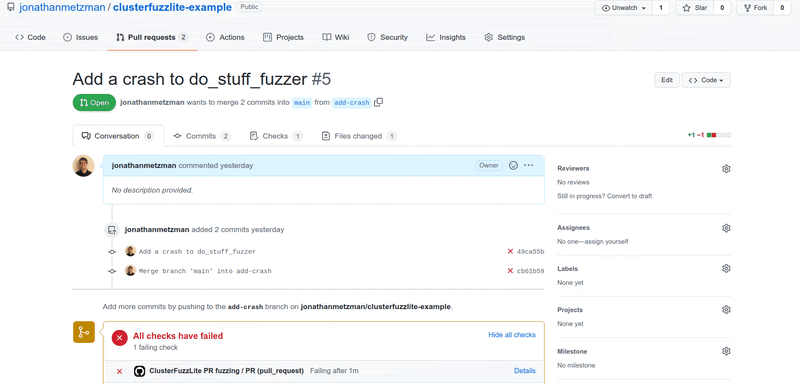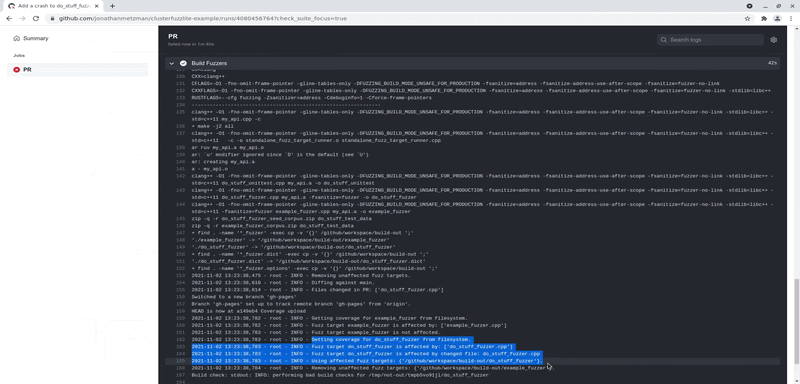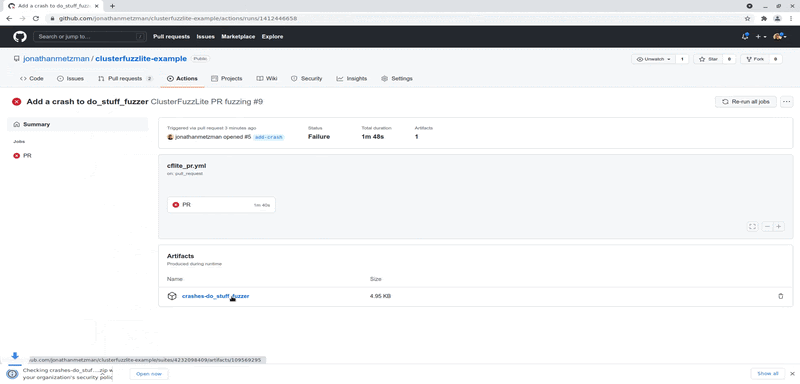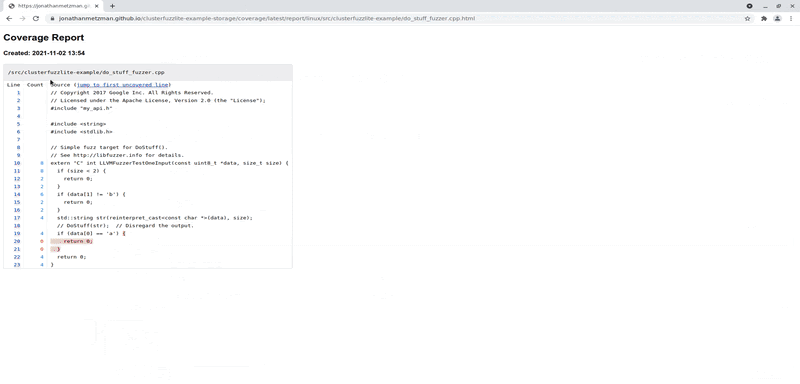
    Google today made available a ClusterFuzzLite tool that makes it simpler to incorporate fuzz testing into a DevOps workflow.

    Fuzz testing refers to an automated software testing technique that involves providing invalid, unexpected or random data as inputs to an application to discover issues such as potential memory leaks.

    Jonathan Metzman, a senior software engineer for Google, said ClusterFuzzLite is a lighter-weight version of a tool that Google makes available to its internal development teams. It is not a fuzz testing tool itself, but rather a tool that makes it easier to surface the results of a fuzz test within a DevOps workflow. Once those results are surfaced, it then becomes easier for developers to address issues before an application is deployed in a production environment.

    Core capabilities enabled by ClusterFuzzLite include continuous fuzzing, sanitizer support, corpus management and report generation tools. The goal is to make fuzz testing more accessible to a broader range of developers as part of an overall effort to embrace DevSecOps best practices, noted Metzman.

    ClusterFuzzLite currently supports GitHub Actions and Google Cloud Build, but Metzman said it is easily extensible to other DevOps platforms. It is designed to run as part of a DevOps workflow by adding a few lines of code to a continuous integration/continuous delivery (CI/CD) workflow.

    Google has already made ClusterFuzzLite available to open source projects, but is now providing additional access for commercial developers. Since its release in 2016, over 500 critical open source projects have integrated into the Google fuzz testing program for open source software, resulting in over 6,500 vulnerabilities and 21,000 functional bugs being fixed.

    In the wake of recent guidelines issued by the U.S. National Institute of Standards and Technology (NIST) that were themselves in response to an executive order issued by president Biden, the number of organizations using fuzz testing is expected to increase now that NIST has determined that fuzz testing is a minimum standard requirement for code verification.

    For several years, Google has been making a concerted effort to improve the security of open source software. The challenge for all developers is finding a way to build more secure applications without slowing down the rate at which they are deployed. Fuzz testing makes it possible to identify issues much earlier in the application development life cycle versus just before an application is deployed.

    Less clear, of course, is whether developers are starting to use these tools on their own or if the increased adoption is because of a concerted effort by their organization to embrace DevSecOps best practices. Regardless of the motivation, however, the overall state of application security should continue to improve as it becomes simpler for developers to invoke more advanced testing tools.

    In the meantime, organizations of all sizes are reviewing how they construct software in the wake of a series of high-profile security breaches. In theory, at least, increased focus on software supply chains should prevent issues from arising after deployment when they become much more costly to remediate.

  • Neo4j Will Use Funds to Expand Managed Cloud Database

    Neo4j Will Use Funds to Expand Managed Cloud Database

    In July 2021, Neo4j announced a large round of fundraising—its largest to date. Philip Rathle talked with Alan Shimel about how the capital will be used to further Neo4j’s go-to-market strategy and what that means for DevOps professionals. The video of the conversation is below, followed by a transcript.


    Announcer: This is Digital Anarchist.

    Alan Shimel: Hey, everyone, welcome to another Tech Strong TV segment. My guest right now is Philip Rathle. Philip is with Neo4j, VP Product. Hey, Philip, welcome to Tech Strong TV.

    Philip Rathle: Thanks, Alan. Pleasure to be here.

    Alan Shimel: Absolutely. Philip, we’ve interviewed folks from Neo4j before, but I don’t know if everyone in our audience is familiar with the company. So, why don’t we start there? Why don’t you give us a little company background, maybe a little bit of your own background as well?

    Philip Rathle: Sure. Let me start with the second and tie it in. The thing that really attracted me to this company when I joined a bit over nine years ago was the idea that the most valuable thing in data, in my opinion, has always been the model and what’s built into the model. It’s how things are related, and what this company was doing was leaning into that some more at a time where the data space—and you look at everything that happened in NoSQL was about really simplifying the data model so that you could do this very, very high level volume and scale, but very simple data problems, store and retrieve. And in order to do that, you can lighten up on certain of the more technically complex requirements like, you don’t need acid if you’re not doing complex relationships and store and retrieve of shopping cart data at a massive scale.

    And so, what Neo4j’s been doing for more than a decade now is solving the problem of how to understand context and causality in your data through looking at how things are related. So, if you look at my relationship with—I don’t know, let’s look at an insurance scenario—with my car, other people who drive my car, other vehicles I might own, other things that I might own like a house and then line on that, and a business and lines on that and then bringing that together, suddenly, you’re into these complex kinds of enterprise data scenarios that have always been a challenge, persistently. And I lived through a lot of those as a consultant trying to fix those, kind of on a one-off basis.

    And so, what Neo4j did was something that, in the database space at the time was a bit crazy is build an engine ground up that assumed that you could do random I/O really well. Because if I’m going to understand relationships, a query can go any which way through the data, potentially very, very deep if I’m in a 20-level deep supply chain, for instance, following an item or a big payment network and looking for fraud detection, the fraud patterns or money launderings so that I can catch those. Those are all about patterns in the data, so Neo4j is a company that’s built a database from the ground up, looking to help users understand the relationships and the data so that they could understand context, causality, second order, third order, fourth order effects more deeply.

    Alan Shimel: Got it, got it. What about a little of your own background?

    Philip Rathle: I did consulting for the first half or third of my career, and a lot of that culminated in ending up as the person between the business and the IT problem. I really liked understanding what problems were being solved and then using new technology and seeing what we could bring to bear to solve the business problems.

    And I ended up working a lot with data and databases and a lot of large systems. I started at Accenture back when it was Anderson Consulting, then went into kind of a boutique company that worked on high end, large database deployments called Tanning Technology. And there, I realized I was doing—I later realized this was a step towards product management or I guess today you would call it product management. And ultimately, co-founded a startup, tried that for a few years around master data management, customer data integration; wrong market, wrong time—that’s maybe a story for another day. And then got into Embarcadero Technologies, which makes database tools.

    Alan Shimel: Mm-hmm.

    Philip Rathle: So, I worked there for about seven years, ended up heading up the database product portfolio, about a dozen tools for managing databases as well as a database interface database. Then learned about Neo4j, so, all of the cool stuff that was happening in data about 10 years ago, and thought, “I wanna be a part of this, kind of ground up, creating new ways of managing data.” And yeah, the rest is history. I’ve been heading up Product Management since then. I was employee number 30, and we’re at 550 growing way past 600 this year.

    Alan Shimel: Excellent. Very cool. So, I think we’ve laid a lot of the ground work, here. Phil, recently Neo4j announced a rather large raise. Why don’t you give us—a capital raise—why don’t you give us some information on that?

    Philip Rathle: Yeah, we did. So, as a company, you know, those of you who, probably every listener knows how it works with startups, right? You raise money, you put that money into primarily R&D, improving the product, and other areas of the business, and then you grow and, you know, at some point, there’s some kind of exit for us. We’re looking to be a big, independent company, and for that, databases are highly capital intensive, very complex technologies. It’s not enough to have just the database, you need tooling around it, especially when it’s a new kind of model.

    So, we just made a massive fundraise. We had already raised over $100,000,000.00 over the course of the years. This single fundraising event is $325,000,000.00, it’s the biggest fundraise ever for any database company in history. So, we’re pretty excited about it.

    Alan Shimel: For good reason—congratulations. You know, I’ve been involved in companies that have raised money, significant money over the years—that’s a lot of money, man. [Laughter] That’s a really big raise.

    Now, of course, you know, our audience says, “Whew, another big number.” We’re hearing a lot of big numbers lately. What does it mean for them? What does it mean for them, what does it mean for Neo4j to have that kinda capital? What’s the payoff, here?

    Philip Rathle: Yeah, I mean, it’s pretty much product, product, product with a little bit of a dash of regional expansion. So, on the product side, Neo4j recently launched—so, late 2019, we launched a self-serve version of the database as a service. So, it starts at $65.00 a month, credit card swipe. You can get a fully managed Neo4j database in the cloud and turn it on, it runs. You don’t need to worry about managing the database. And we launched an enterprise tier last year. Right now, it runs on, you can choose between GCP, AWS, of course, Azure and others are coming, and Work in Progress. 

    So, one area is to really keep improving the cloud product since the preferred way of consuming databases these days has flipped to cloud very, very fast over—you know, whereas just in the last couple years. Another one is graph data science. So, last—a bit over a year ago, we entered the, we expanded what Neo4j can do, which typically has been a developer oriented database with database drivers and more for transactional operational applications. 

    What we’ve been seeing over the last few years is that a lot of the kind of next step in machine learning and data science and AI is getting information about the connections in the data and in the network into your machine learning algorithm. And that whole art and science is graph data science, and we have a graph data science for a Neo4j offering, which is a graph data science library, together with a database, together with Bloom, which is a visualization and exploration tool. And that offering has really taken off in the last year, both in terms of demand, customers, and also, it’s become really mature in a short time. But there’s still a long way to go; it’s a brand-new space. 

    So, those are the two primary areas, and then I’ll add the third is just continuing to mature the database, continuing to make it scale, handling larger and larger amounts of data. By the way, as part of our announcement at our annual conference, we also a trillion-relationship graph.

    Alan Shimel: Wow.

    Philip Rathle: Just showing how, across 1,000 machines like—actually, trying to spin up this many machines on AWS, Amazon couldn’t provision the machines fast enough. [Laughter] We’ve never seen this kind of error.

    Alan Shimel: Right.

    Philip Rathle: But there’s no end to performance, scalability, security, more features, more richness, et cetera. So, those are the main areas, and like I said, a dash of regional expansion, really growing beyond—our primary markets have been U.S. and Europe with some customers in other parts of the world, but this will help us expand more in other parts of the world.

    Alan Shimel: Excellent. You know, I think one lesson that I learned during my career, and I think it’d be wise to share with the audience is—you know, there’s a latency time between the time you raise money and the time that money finds its way into products that are released, right?

    Philip Rathle: Yeah, that’s very true.

    Alan Shimel: Because, okay, now we’ve raised money, we gotta go hire people. We have the idea of what we wanna do, right? But, you know, we gotta flesh out those plans, we gotta get the people power, the technology process in place.

    When do you think we’ll see some of these great things that you’re talking about that, you know, this money raise has enabled actually come out to market?

    Philip Rathle: That’s a great question. So, prior to the fundraise, we were close to maxed out in hiring. And when I say close to maxed out, there’s a certain rate at which you can efficiently hire, and then beyond that, you kind of need to have people on their own off in the background, but that can’t contribute to the code base, because it’s not even structured to be able to have more than a certain number of people contribute. So, we’re—and that’s less true with new areas that we’re growing out. So, we’ve seen this one coming now for a few months, and so, we—that, plus just early in COVID, like, last April, we actually froze hiring for a bit and said we don’t know where things are going and we don’t wanna be in a position where we have to lay people off, that would just be horrible. Let’s just pause hiring.

    And then our business kept, you know, fortunately, doing well. And so, we started to wrap up, but I’d say—so, two answers, maybe. One answer is, you’re already starting to see the results of a really aggressive ramp in product and engineering. My team is doubling this year, and it’s close to doubled already. The engineering team is growing by about 50 percent. But what this also means is, we can keep hiring and we can keep—and whenever we have new products, new areas, we can form entirely new teams there. 

    So, I’d say the answer is now, but it also means that, on a steady state, continued basis, you’re gonna continue to see some really significant product releases from quarter to quarter, year to year.

    Alan Shimel: I would imagine. I would imagine—and beyond, with raising that kinda money, beyond. Anyway, Philip, we’re running out of time. You know what, did we mention the website?

    Philip Rathle: The website is Neo4j.com.

    Alan Shimel: That’s N-E-O—

    Philip Rathle: The number 4 and the letter J.

    Alan Shimel: Letter J—dot com.

    Philip Rathle: And you’ve got all kinds of info, resources for getting started. We’re huge on open source, we’re huge on education. And I should mention that our vocation has been not just making our own company successful—first of all, it’s about making users successful and making an impact in the world. But then not just making an impact in the world by making our product succeed, but making the category succeed. Because this is something that our founder penciled out on a napkin once upon a time. 

    So, we see ourselves in some ways as helping to grow the graph database space and just, you know, we celebrate when other companies go launch graph databases, because that means it’s good for the world. We’ve done a lot of work in the standards area and so on to make it more mature and better. So, you’ll see an open source version, there’s a free sandbox you can get started with, there’s a free version of our cloud product. Or, both on the developer side, on the data science side, lots of docs, good community out there, a Discord group, questions, QA on ________, you name it, it’s all out there. We’d welcome any and all of you listeners to check it out.

    Alan Shimel: Cool. Alright, we’re out. Philip Rathle, Neo4j—thanks for joining us on Tech Strong TV here today. Congratulations to you and the whole team on an outstanding raise, and now, let’s see you put it to work.

    Philip Rathle: Thank you.

    Alan Shimel: Alrighty. Be well. This is Alan. We’re gonna take a break here on Tech Strong TV. We’ll be right back with our next guest.

    [End of Audio]