Category: DevOps Practice

  • Dev of core-js Will Flip Table ¦ Another 451 PyPI Maldeps

    Dev of core-js Will Flip Table ¦ Another 451 PyPI Maldeps

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: Denis Pushkarev is fed up with core-js freeloaders, and hundreds more malicious packages found at PyPI. (more…)

  • Technical Debt is a Major Threat to Innovation

    Technical Debt is a Major Threat to Innovation

    A survey published today suggested that technical debt is starting to take a heavier toll as IT environments continue to become more complex to manage.

    The survey of 400 IT leaders at organizations with 1,500 employees was conducted by Foundry, the market research arm of International Data Group (IDG) on behalf of Insight Enterprises, a provider of IT services. The survey found that 86% of respondents reported their organization was impacted by technical debt over the past 12 months, with the top areas affected being the ability to innovate (43%), meet service level agreements (41%) and avoid downtime (37%).

    Technical debt is created when organizations cut corners and leave known bugs in the race to meet application delivery deadlines. Application code is often not as thoroughly tested as it should be. In some cases, it turns out that what was intended to be a minimum viable product doesn’t scale all that well. Quick fixes needed to improve performance are also frequently undocumented. Inefficient code also winds up consuming more IT infrastructure than required, which adversely impacts everything from cloud costs to the amount of carbon generated.

    Juan Orlandini, chief architect for the Cloud + Data Center Transformation (CDCT) division of Insight Enterprises, said every organization struggles with technical debt; it will never be eliminated, but it does need to be contained, he added.

    The challenge is instead of trying to keep the proverbial IT lights on during the COVID-19 era, IT teams are now being asked to innovate to advance digital business transformation initiatives, said Orlandini. A full 87% of survey respondents cited modernizing critical applications as a key success driver.

    As a result, many organizations are embracing platform engineering to bring more structure to their DevOps processes, he noted. The challenge, however, is striking a balance between a more centralized approach to DevOps and maintaining the ability of developers to innovate, said Orlandini.

    The issue, of course, is that in addition to massive technical debt, the latest generation of applications are more distributed than ever. The survey found 91% of respondents now rely on multiple public cloud providers for different workloads, with 54% of data residing on a public cloud. However, the survey also found on-premises IT environments are still relevant, with 20% planning to repatriate select public cloud workloads to an on-premises model over the next 12 months.

    Nearly three-quarters (72%) of respondents also noted data volumes are growing faster than their ability to manage them, with 64% ranking implementation of a data governance program to improve data management as their top data-related objective this year. Just over a third (35%) of the data estate is now, on average, driven by edge workloads, with 29% of respondents reporting that at least 50% of data volumes now reside on the edge. Nearly two-thirds (64%) expected that to increase in the next 12 months.

    A total of 85% of respondents also indicated their organization is using artificial intelligence (AI) to some degree to drive business insights and/or efficiencies, although only 36% reported having optimized their use of AI and machine learning (ML) across the enterprise.

    Finally, cybersecurity also remains problematic, with 51% reporting they were impacted by a cybersecurity breach over the past 12 months. Just 20% resolved their issue in one day, while 31% needed less than a week. Nearly half (49%) required one week or more to recover.

    It’s clear that IT isn’t becoming any easier to manage. IT teams need to find ways to build and deploy new applications while reducing technical debt so it doesn’t strangle future innovation.

  • Fiberplane Adds Wasm Plug-in Framework for DevOps Notebook

    Fiberplane Adds Wasm Plug-in Framework for DevOps Notebook

    Fiberplane today announced it is extending the reach of a real-time collaboration notebook designed for DevOps teams by making available tools for building plug-ins based on the WebAssembly (Wasm) framework.

    Micha Hernandez van Leuffen, Fiberplane CEO, said these plug-ins, dubbed providers, will make it much simpler for anyone to connect the Fiberplane notebook to other DevOps tools and platforms.

    The Fiberplane notebook uses the same operational transformation algorithm used in Google Docs to enable teams to easily collaborate around a document or spreadsheet. The core platform itself is built in Rust and WebAssembly. That approach enables a DevOps team to, for example, write and run PromQL queries and display Prometheus charts alongside other data presented via an integrated graph. Wasm makes it possible to run those providers both in the browser and on a backend platform.

    Fiberplane also announced it is open sourcing its Provider Development Kit (PDK), written in Rust, to enable organizations or third-party developers to create additional plug-ins. A Fiberplane Daemon then executes the plug-ins. The overall goal is to provide an open format based on Wasm for consuming DevOps data, noted Hernandez van Leuffen.

    The full open source Fiberplane WebAssembly-based Plugin System includes a Fp-bindgen to provide the bindings generator for building plug-ins, the Provider Development Kit (PDK), a toolchain for building plug-ins, a set of pre-configured plug-ins for Prometheus, ElasticSearch, Sentry, Grafana Loki, Cloudwatch and a generic HTTP provider, the Fiberplane command line interface and the Fiberplane Daemon.

    Fiberplane is essentially taking the concept of notebooks used for collaboration by data science teams and applying it to DevOps workflows. The goal is to improve DevOps teams’ productivity by reducing the amount of time it takes to sort through multiple types and classes of DevOps data to resolve an issue.

    As IT environments become more distributed in the age of the cloud and microservices, troubleshooting issues now invariably spans the responsibilities of multiple members of an IT team. Fiberplane, in effect, makes it possible to spin up a virtual war room that enables the members of an IT organization to collaborate until the issue of the moment is resolved.

    The speed at which any IT issue is resolved has become a crucial metric. Given the complexity of IT environments, it’s inevitable that incidents will arise. Ideally, IT teams would discover those issues before they disrupt the business. However, in reality, the metrics organizations use to evaluate the effectiveness of a DevOps team are often how quickly IT issues are resolved once they are discovered. The longer it takes for a distributed DevOps team to marshal its resources, the more likely it becomes that team will be perceived as being inefficient—regardless of what level of application availability is actually achieved.

    Most DevOps teams have, of course, implemented a wide range of incident management best practices that create a level of muscle memory for responding to a wide range of issues. The trouble is there will always be unforeseen issues that arise. DevOps teams, as a result, need to find ways to quickly focus on an unpredictable issue that they didn’t anticipate.

  • Quali Update Strengthens Infrastructure Security

    Quali Update Strengthens Infrastructure Security

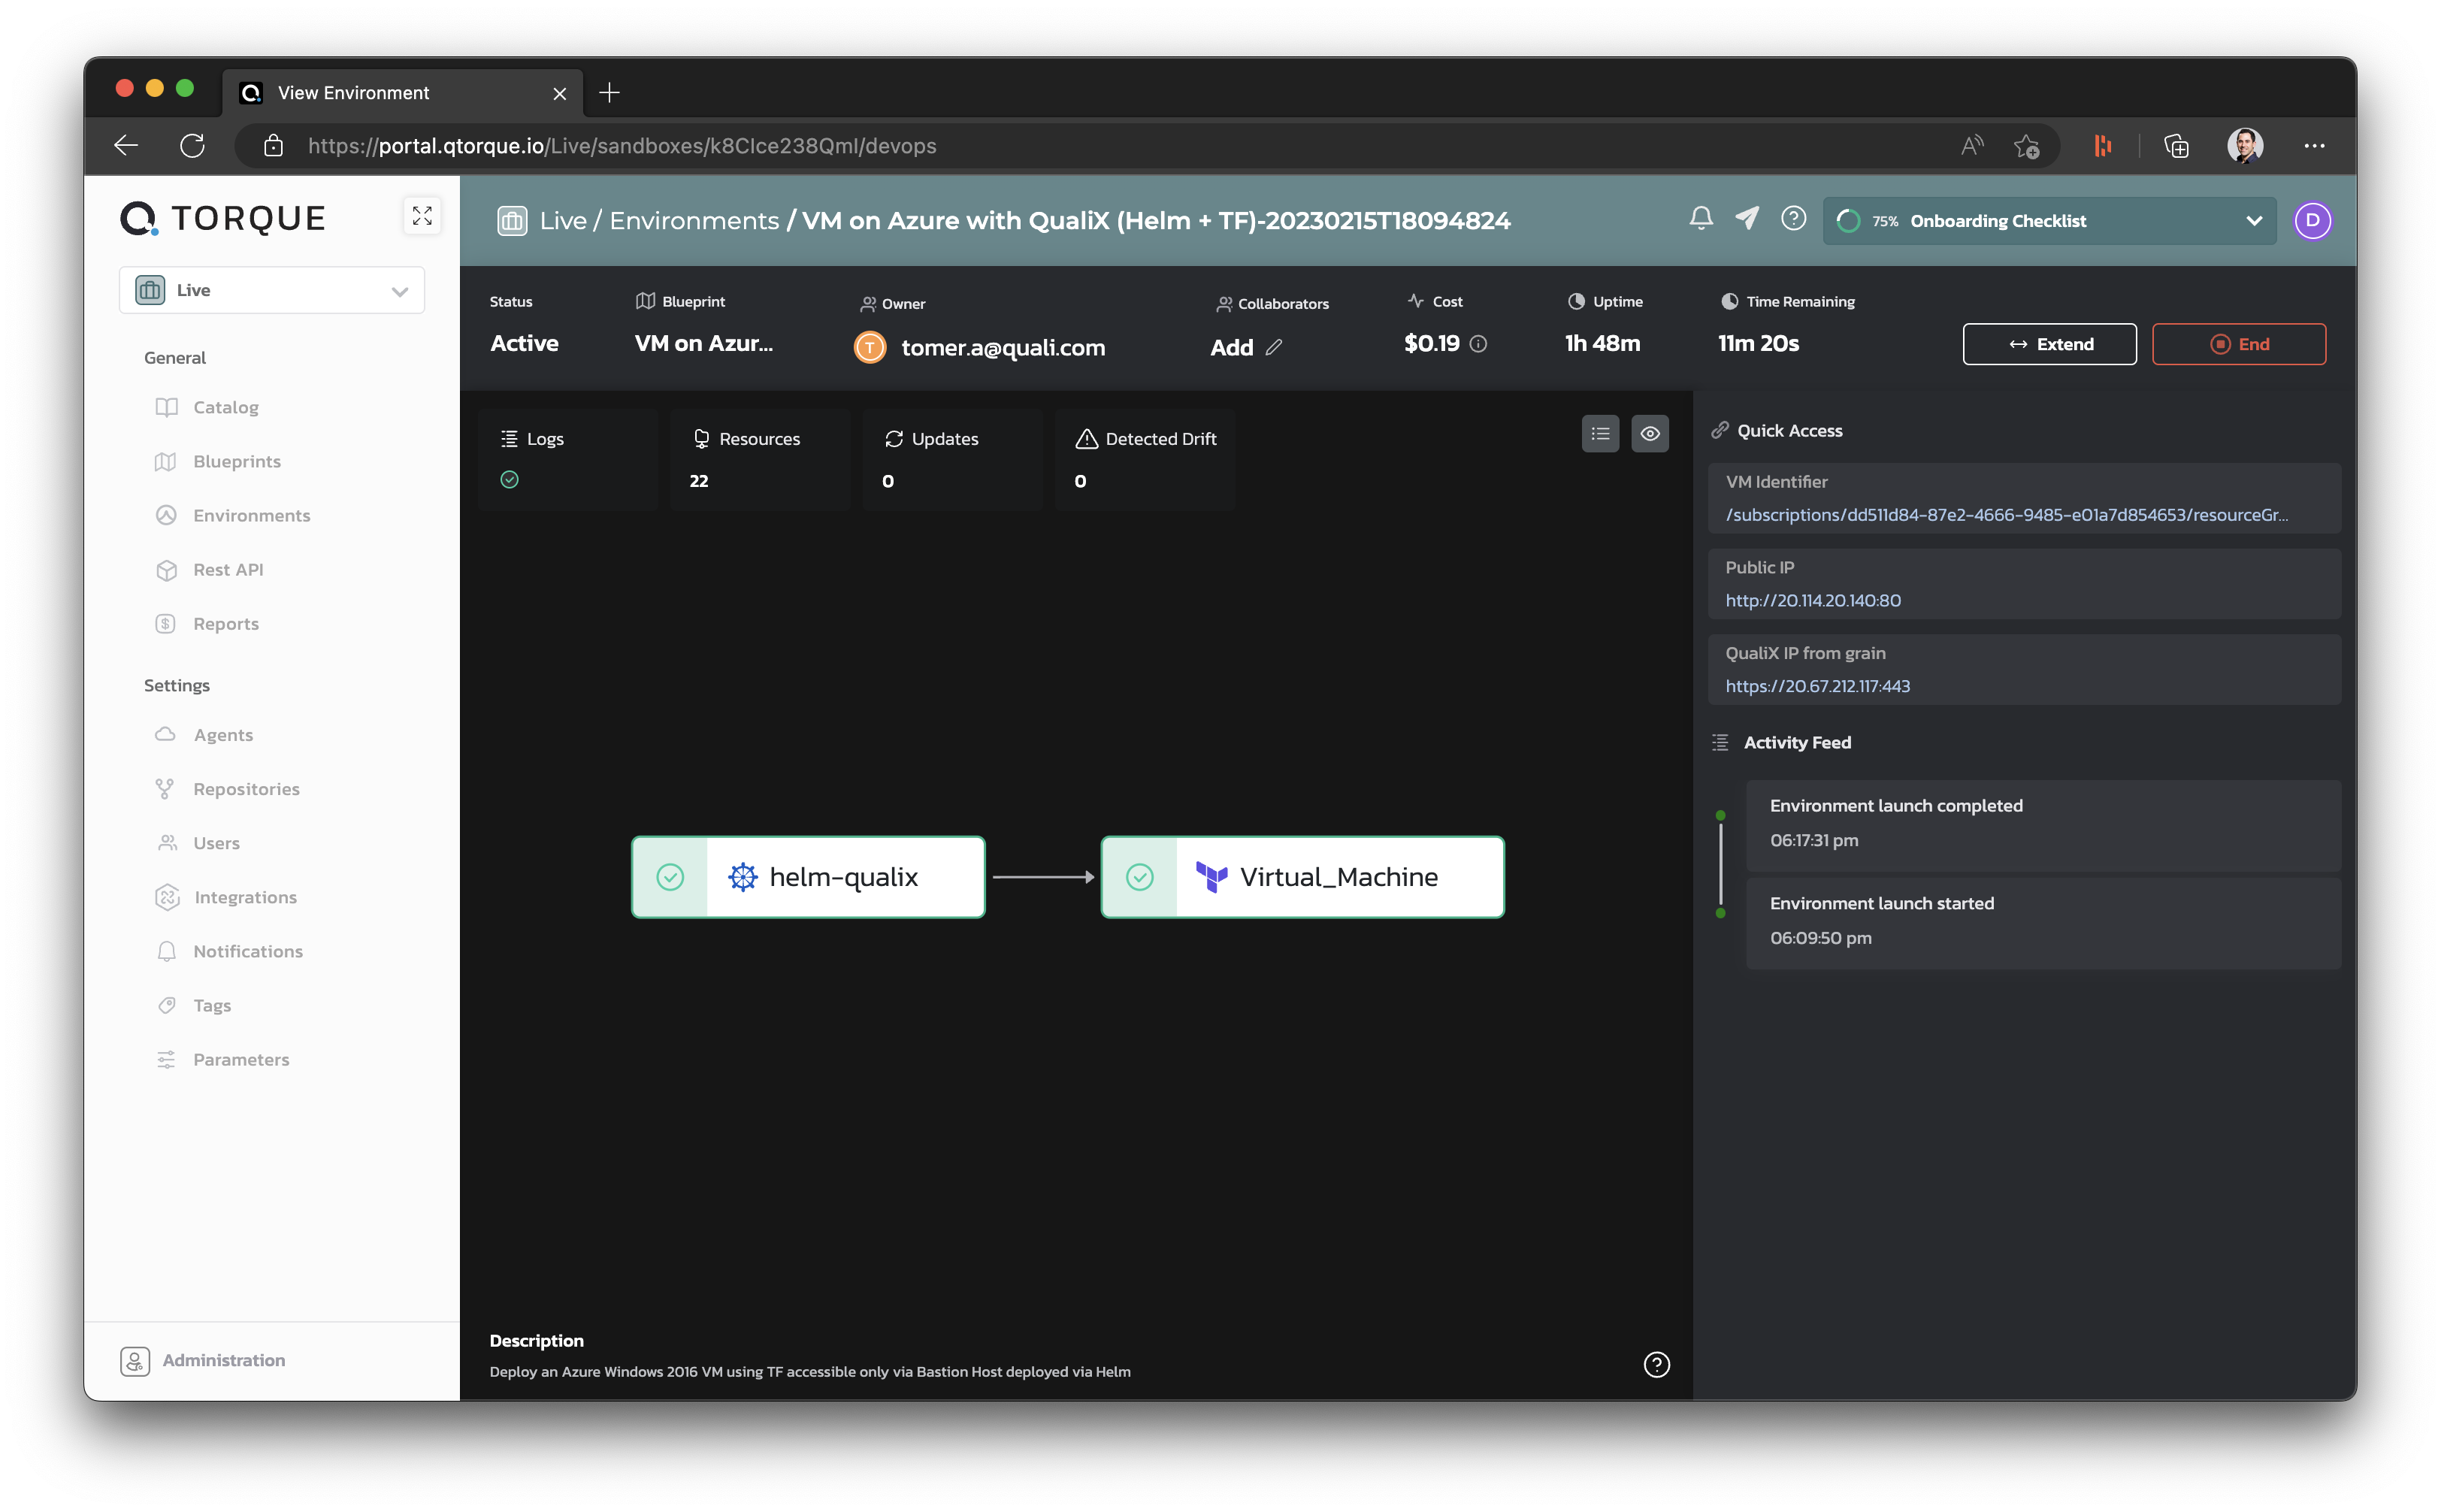
    Quali today announced enhancements to its Torque automated infrastructure platform to add support for security scans and Open Policy Agent (OPA) software being advanced under the auspices of the Cloud Native Computing Foundation (CNCF).

    OPA enables organizations to implement cybersecurity policies as code. The challenge many organizations have encountered is that not many developers have mastered the programming language required to implement OPA. Quali is embedding OPA in a platform that enables IT teams to implement it using a graphical tool that enables central management and application of those policies.

    David Ben Shabat, vice president of research and development at Quali, said the overall goal is to implement scans and policies in a way that reduces the number of misconfigurations that are made when organizations provision infrastructure-as-code (IaC).

    As part of that effort, Torque now flags any policies that fail validation. In addition, administrators can pick and choose which OPA policies to import, including both out-of-the-box and existing custom policies. Those policies then enable Torque to automate approvals or denials of deployments based on compliance with those policies after scans and other health checks have been run.

    Quali has been making a case for policy-based triggers for cost controls, automated start-up, shut down and pausing of IT environments to give IT teams more control over infrastructure using a software-as-a-service (SaaS) platform. That approach enables IT teams to provide a set of guardrails for provisioning infrastructure that prevent mistakes from being made, noted Ben Shabat. Those controls can be applied using the graphical tool Quali provides or programmatically via an application programming interface (API) that Quali exposes, noted Ben Shabat.

    It’s not uncommon for a port to be left open, for example, which cybercriminals later exploit to exfiltrate data. Quali is offering a DevOps platform that allows for central application of policies that act as guardrails to prevent developers from making these types of mistakes as an alternative to scripts created using tools such as Terraform. That approach also provides more visibility into how infrastructure resources are being consumed.

    Every minute a developer spends managing infrastructure is one less minute they could be spending writing code. As application environments become more complex, it is becoming more challenging for developers to manage infrastructure-as-code. The issue is that DevOps teams who could provision infrastructure for developers are overwhelmed by the number of projects they need to manage. As a result, DevOps teams are becoming bottlenecks. Naturally, that only encourages more developers to provision infrastructure on their own, leading to more mistakes.

    It’s not clear whether IT organizations will look for an alternative to provision infrastructure in a way that doesn’t require developers to have as much infrastructure expertise. However, as organizations look to lock down software supply chains, the way infrastructure is provisioned using code will, in many cases, need to be reconsidered within the context of a larger DevSecOps workflow.

  • Watching the Watchers: Solving the Problem of Meta-Permissions

    Watching the Watchers: Solving the Problem of Meta-Permissions

    The move to the cloud and microservices has introduced new challenges in managing permissions. Software has been broken down into small, independently-deployable microservices, each with its own unique set of permissions. These permissions make it excruciatingly hard to ensure and track correct access. While this technological shift is challenging, it pales in comparison to the cultural and organizational shifts it has caused—one of which is the challenge of authorization for authorization. The challenge of authorization for authorization, or “controlling access control,” is a crucial but often misunderstood aspect of system design, and  its recursive nature is quite confusing.

    At its core, authorization for authorization deals with ‘meta-permissions’—the permission to grant and revoke permissions for the designed system.

    Controlling Access Control

    Deciding who can do things inside an application is one thing. Deciding who can decide (or, in other words, dealing with meta-permissions) is another story entirely. Once you start dealing with authorization for authorization, there are two main problems to contend with: Recursiveness, which is a technical challenge, and the question of trust, which can be hard to handle and can have dire consequences if handled incorrectly.

    Naively, developers often choose to be the superusers—the ones calling the shots; retaining all of the power with them. This can produce a very stable and secure application, but will quickly put a strain on precious R&D resources, turning developers into bottlenecks for the entire business operation.

    The opposite approach—delegating all of the power away from developers to other stakeholders—is equally dangerous, often creating a slow-moving, inefficient bureaucracy (looking at you, security and compliance) or an unstable, risk-filled environment (looking at you, sales and product).

    At the end of the day, it’s a question of balance—one that varies for every company and application.

    When building this balance, it’s important to empower the various stakeholders (and customers) working with the application, giving them a significant amount of control and decision-making abilities to enable the business to move quickly and securely while enabling developers to monitor the flow without becoming a bottleneck.

    To keep you on track as you tackle this challenge, here are some guidelines, do’s, and don’ts:

    Common Pitfalls to Avoid

    ● Don’t mix up authentication and authorization: This might seem trivial, but it happens all the time. Authentication is the process of identifying the user, while authorization is the process of granting access to specific resources based on the authenticated user’s roles or privileges. Solutions are required for both.

    ● Thinking you won’t need authorization for authorization: Simple systems may require meta-permissions functionality and advanced ones will undoubtedly need it. It’s important to consider when you’d need this ability and set the groundwork for it accordingly.

    ● Limiting access control to the vendor side: It’s not enough to delegate access control from developers to the rest of the organization. Doing so merely moves the bottleneck up the chain. To appropriately delegate the workload, you must be able to assign at least some access controls to the end customers themselves, providing them with true self-service.

    ● Thinking access control is limited to direct human use: Your first users are likely to be human users, but with increasing automation, more and more of your “users” will be automated agents—other applications and AI agents acting on behalf of humans. You will need to cater to them, too, and it might be sooner than you think.

    ● Delaying providing interfaces to non-technical people: A powerful interface that’s intuitive to non-technical users is crucial for access control systems.

    Best Practices

    ● Create a cascading waterfall of trust and permissions: By creating a cascading system of permissions and trust, you can ensure that the right permissions are granted to the right users at the right time. Often, developers and security would be the main source of this waterfall, but it mustn’t end with them. Design your flow to gradually delegate more and more between the different levels with each level empowering the ones below it.

    ● Assign an owner: To avoid conflicts, such as two admins being able to remove each other, always have a primary admin, or “owner,” who takes precedence to avoid conflict. Owners often cannot be removed without transferring the title first.

    ● Identify bottlenecks early on: Identify potential bottlenecks in permission delegation (permissions that are hard to delegate, or manage) and have a plan and interfaces to mitigate in advance before friction piles up.

    ● Use a classic policy model (e.g. RBAC, ABAC) for your meta-policy: Just like with your regular permissions, there’s no need to reinvent the wheel. Start with common policy models first.

    ● Use the same policy model for your meta-policy: This can help to ensure consistency and ease of understanding across the system, lowering the cognitive load on system managers and users.

    ● Have meta audit logs: The information on who changed the meta-permissions is just as critical, if not more so, than who changed the permissions. Log it and track it.

    ● Build on top of existing AuthZ for AuthZ: Use tools that have authorization for authorization already baked into them (such as Permit.io), saving the effort of starting this from scratch.

    In conclusion, solving the problem of meta-permissions requires a multifaceted approach that considers both the technical and cultural challenges associated with modern software systems. By following the best practices outlined above and by carefully thinking through the design of the interfaces and trust flows that govern the system, it is possible to create a system that is secure, usable and ready to accelerate to the velocity required by modern cloud-empowered business today.

  • Back to Basics

    Back to Basics

    We here at DevOps.com do sometimes suffer from The Curse of Knowledge. We write about DevOps regularly for an audience that is doing or managing DevOps. We assume knowledge, but there are still a fair number of people and organizations who are unclear about some of the terminology/technology that we talk about.

    So if you are a regular reader of my blog, this might be a redundant post—but read on because it might have info you haven’t had a reason to consider yet.

    I’m going to start with the obvious—how most readers got here to begin with: DevOps. DevOps is automating the build process so that builds are automated and repeatable. Teamed with Agile development, DevOps means that development teams can rapidly iterate through development and generate regular updates to their applications. Everything else in this blog is based on the premise that it is running in a DevOps environment.

    Continuous integration: Typified by Jenkins, continuous integration (CI) is the part of DevOps that runs the automated builds. It includes reporting and defect resolution only in the sense that it feeds into other systems that track defects. With CI in place, a developer or DevOps engineer can say, “Okay, ready to test a build,” and with one command, can kick off a build that will result in a finished artifact. Or result in a built product, anyway. ‘Finished’ is optional, and the target of CI is not generally a running application.

    Continuous delivery: One of the most confusing things for new DevOps people is CD. The way that the space evolved, there are actually two things that CD could stand for; continuous delivery–automated build of the complete application —or continuous deployment—delivery of a running application onto infrastructure. Continuous delivery is straightforward and means all the bits of the application are code complete–or at least the current state of the application is complete enough to build an application. Continuous deployment is much more convoluted. It might mean deployed to a development environment for developer-level testing or a test environment for running automated (continuous testing) tests on or in production. It might be a staged rollout, where users are siphoned over, or it might be a hard rollout where the old version is replaced by the new in a manner similar to ripping a Band-Aid off.

    Continuous test: Automated testing is at the heart of continuous test (CT), and it is only now becoming a real possibility for most short-staffed enterprises. Advancements in machine learning (ML) mean that tests can be run, results filtered to eliminate false or duplicate results, and IT staff is only notified of the important bits. Unlike traditional testing, staff is required only to create the tests and to look at meaningful results.

    Infrastructure-as-Code: Infrastructure-as-Code (IaC) is the ability to define all relevant elements of infrastructure with text files. Often this is done in YAML and sometimes in a variety of other formats. The idea is that infrastructure provisioning can be on-demand and adaptable. It is certainly more agile to change a text file from port 80 to 8080 and then run a command to process the text file–now the port is documented and whenever needed the command can be re-run to move to a known state. IaC largely relies upon software implementations over physical. While the idea of software-defined networking (SDN) has fallen out of favor, the underlying principles are everywhere and part of IaC, for example.

    GitOps: All the rage these days, GitOps is probably best defined as applying DevOps to operations. That does sound weird, but I like to break it up as “traditional DevOps is DevOps, while IaC (to a lesser extent) and GitOps (to a huge extent) are DevOps.” The point being that GitOps uses the text files generated in IaC and worker nodes generally designed for continuous deployment and then performs operations tasks based on those text files. If IaC defines the entire environment that an application needs and DevOps defines all of the sources that an application is composed of, bundling the two together will enable full-on automation from conception to decommissioning. When a new version of a source file or configuration file is checked into Git, the system then makes certain that every instance of the application is updated with the new version. Of course, this process, like every one listed here, is far more complex than that in implementation; we are talking about ‘what, not how’ at this level.

    All of this really is the very tip of the iceberg, but that was the goal here – to offer readers a place to start if they’re finding themselves looking at DevOps for the first time. As you dig deeper, things like DevSecOps and test driven development (TDD), or defect tracking and Agile methodologies start to play into the landscape, and maybe I’ll write an intro bit for those also. But this time, we’re out of space.

    As always, keep rocking it. No matter which or how much of the above you are using, if the organization’s applications are up and running, that’s you. And you deserve more kudos than you are likely getting. But keep grinding through—the rest of us get it, and thank you.

    Image source: Photo by Towfiqu barbhuiya on Unsplash

  • Organizations Prioritizing Java Application Modernization

    Organizations Prioritizing Java Application Modernization

    A survey found that modernizing existing Java applications is a higher priority than other projects for 87% of respondents, with more than 80% of these applications expected to be re-engineered over the next five years. The survey polled 450 IT professionals working in organizations in the U.S. and United Kingdom that have more than 500 employees.

    Conducted by the market research firm Vanson Bourne on behalf of Diffblue, a provider of a generative artificial intelligence (AI) platform for refactoring applications and generating unit tests, the survey also found enterprises plan to invest nearly half (45%) of their software development resources on modernization of existing applications versus developing new ones. A full 90% of respondents expected to rely on automation to accomplish those tasks, the survey found.

    Specifically, survey respondents reported they planned to rely on automation to improve security (50%), increase development velocity (45%) and improve developer experience (42%). Well over half of respondents (58%) said they had already been working on these projects for more than 12 months.

    If organizations don’t modernize Java applications, more than half of respondents (51%) said too much time would be spent on unproductive coding, while 50% said development velocity would be adversely affected. The biggest obstacles cited are choosing the right technical approach (45%) and securing budget (42%).

    More than half of organizations (59%) have created a dedicated modernization budget to support their efforts. Nealy half (48%) said funds are being provided by business teams for projects, while 49% said general operating budgets have increased.

    Diffblue CEO Matthew Lodge said it’s clear there is a huge commitment to application modernization. The reality is the majority of work IT teams do involves applications that have already been deployed. The challenge they face is that the effort required to modernize these applications is still far too dependent on manual processes, he added.

    Overall, the survey found 96% of respondents considered Java applications extremely or very important to their organizations. On average, 65% reported additional Java applications are still being developed. Only 4% said they planned to migrate away from Java as part of a modernization effort.

    Over half of the respondents expected to use Java 11 (53%) or Java 17 (56%) in their applications, compared to 19% using Java 8. More than a quarter (27%) expected to use a forthcoming Java 21 release. A full 100% expected to use the Spring framework to build these applications, with more than half (54%) planning to upgrade to the latest version that supports Java 17. A full 97% said unit testing is an “extremely” or “very important” element of their application modernization effort.

    After experiencing something akin to a mid-life crisis, Java has itself been modernized with the release of Java 17, noted Lodge. The Java community is now adopting many concepts that may have been pioneered in other programming languages, he added.

    Regardless of whether organizations are modernizing existing Java applications or writing new ones, the one thing that appears certain is the venerable programming language isn’t about to disappear any time soon.

  • DevOps Done Right: How to Succeed in DevOps From Day One

    DevOps Done Right: How to Succeed in DevOps From Day One

    Whether you are diving into DevOps for the first time or trying to do it right this time, DevOps Onramp provides all the information you need for a successful DevOps journey. Join us on May 4, 2023, to learn how to get started with DevOps—and how to do it right.

    You’ll learn:

    • DevOps best practices, processes and the tools you’ll need
    • Tips and tricks from experienced practitioners sharing their real-world experiences
    • The basics of DevOps
    • How to choose the right technologies
    • Common challenges and how to overcome them
    • The benefits of DevOps as a methodology and a career
    • And more!

    As organizations face increasing pressure to adapt faster and become more agile, getting DevOps right and adopting a DevOps mindset is crucial to deliver high-quality software faster and increase business value. And that opens up great opportunities for anyone looking to start a new career or pivot from an existing role in technology.

    DevOps has become the standard of software development methodologies and it’s critical for successful digital transformation. Adopting DevOps—and doing it the right way—can benefit not only your organization but also your customers and end users by fostering innovation, reducing time to market, increasing development productivity, improving product quality and reliability and reducing costs.

    That’s why many big companies, such as Amazon, Netflix, Facebook and many others have adopted a DevOps mindset—and DevOps practices. And as more businesses are looking to move to the cloud and transition into DevOps, there are plenty of job opportunities available for DevOps engineers at various levels.

    DevOps is a growing field with a lot of opportunities for professional growth. According to a research study by Global Market Insights Inc., the DevOps market is expected to surpass $30 billion by 2028. Due to the high demand for skilled DevOps engineers and the shortage of qualified DevOps professionals in the industry, there is no better time to upskill than now.

    Whether you are diving into DevOps for the first time or trying to do it right this time, DevOps Onramp provides all the information you need for a successful DevOps journey.

    At DevOps Onramp Virtual Summit, taking place on May 4, 2023, you’ll get all the knowledge you need to get started with DevOps —and how to do it right. Join us to learn about DevOps best practices, processes and tools and get tips and tricks from experienced practitioners sharing their real-world experiences. We’ll go through the basics of DevOps, how to choose the right technologies, common challenges and the benefits of DevOps.

    One thing is for sure: The future of DevOps is very promising. The rush has started—don’t be left behind!

    DevOps Onramp Virtual Summit - Submit your talk

    If you’re interested in becoming a sponsor, please contact us. For more information, please visit the DevOps Onramp website.

  • The Evolution of DevOps: Developer Productivity and Platforms

    The Evolution of DevOps: Developer Productivity and Platforms

    This article is part two in a series of three on the rise of platform engineering and its role in improving the developer experience. Read part one here.

    Developer experience is business-critical in organizations of all sizes and across all industries. In the first article of this series, I make the case that the cloud-native developer experience will be shaped and eased not only by platform engineering but also by the vital support of DevOps and/or PlatformOps teams. This flies in the face of the recent and somewhat controversial assertion that DevOps is facing extinction. In fact, it’s possible that DevOps is more important than ever, even if the role of DevOps has changed in the era of cloud-native development, supported by centralized developer platforms.

    Business stakeholders who depend on reliable, stable, scalable and secure software shipping fast and consistently understand the business case for an integrated DevOps team, and most developers and their teams understand the challenges of coding, shipping and running cloud-native software without the guideposts offered by a platform (and the DevOps team). The complexities of Kubernetes and microservices (and their contingencies) make getting to productivity difficult, which is why developer platforms are touted as the magic-bullet solution. But these platforms don’t build and maintain themselves, and the concept hasn’t quite reached the level of maturity at which developer platforms are available as commercial, out-of-the-box offerings.

    Developer Platforms: Who Paves the Developer Path?

    DevOps is not dead and claiming that it is ignores the need for the surrounding, supporting roles that pave the developer path. DevOps is evolving, in some cases into PlatformOps, and keeps workflows flowing and manages operations that support developers’ ability to ship their work into the world.

    Who paves the developer path? It’s actually a cooperative process between developers and DevOps/site reliability engineering (SRE) teams. In discussions with DevOps and SRE leaders about cloud-native development, one trend was a throughline: DevOps and SREs continue to play an instructive role in helping guide developers to realize the possibilities of self-service through supporting platforms.

    The level of full-service ownership this amounts to for developers varies depending on the organization and its goals. But the role of DevOps is still clear. For developers, there is a significant learning curve, and DevOps can help clear the way to the centralized developer platform. This platform, assuming all goes as planned, will not only improve the developer experience but also relieve DevOps teams of the firefighting that has been typical of their job until now. Paving the path provides an opportunity for DevOps/SREs to both develop better operational support mechanisms for developers as well as engage in more long-term and strategic operational work.

    DevOps Ways: Unlocking Developer Productivity via Developer Platforms

    Helping unlock developer productivity is one aspect of powering a positive developer experience. And the shift to a developer-first platform model reinforces the business commitment to the developer experience. It becomes defined by its optimized tools and workflows, which make up developer platforms. The platform approach also supports wider adoption of cloud-native development across larger organizations and broader industries beyond the more niche applications we’ve seen, thanks to clearer guideposts and abstractions.

    But becoming dev-first doesn’t kill off ops, which has been one recent point of contention. In fact, the three ways of DevOps continue to be critical:

    ● The First Way: Flow/Systems Thinking
    ● The Second Way: Amplify Feedback Loops
    ● The Third Way: Culture of Continual Experimentation and Learning

    Quoting industry luminary Gene Kim, “The First Way emphasizes the performance of the entire system, as opposed to the performance of a specific silo of work or department—this as can be as large a division (e.g., Development or IT Operations) or as small as an individual contributor (e.g., a developer, system administrator).” Essentially, it doesn’t matter who constructs the platform as long as they are thinking about the entire value stream, starting with customer requirements which, for an internal platform, are driven by developers.

    The Second Way is focused on creating right-to-left feedback loops. To quote Kim again, “The outcomes of the Second Way include understanding and responding to all customers, internal and external, shortening and amplifying all feedback loops, and embedding knowledge where we need it.” For platforms, this hints at embedding both developers in platform teams and ops in development teams.

    The Third Way is focused on creating a culture that fosters two things: Continuous experimentation, taking risks and learning from failure and understanding that repetition and practice is the prerequisite to mastery. The platform you build today won’t be the platform you need tomorrow. This is why the ‘big bang’ approach to building platforms doesn’t work. Think big, start small and iterate fast. This is something DevOps is designed to do.

    In supporting the cloud-native paradigm, DevOps is far from dead. It’s a shifting discipline that involves a focus on centralizing workflows and infrastructure to improve the developer experience and reduce their cognitive toil. This toil stems from developer guesswork, and DevOps is best positioned to remove that obstacle. If we concede that developer experience is central to business success, and devex depends on being able to code, ship and run quickly and safely, DevOps is the fixer who enables crucial self-service access for developers and, as we will explore in the third and final part of the series, “platforms” the developer experience.

  • Understanding the Infrastructure Automation Maturity Model

    Understanding the Infrastructure Automation Maturity Model

    Nearly every company wants to evolve its digital transformation and increase the pace of software delivery and operations. And infrastructure automation is a new means to achieve these ends. It supports the emerging discipline of platform engineering and can increase scalability and reactivity to unforeseen events, enabling software ecosystems to be more anti-fragile. Increased infrastructure automation also helps free up engineers from focusing too much on managing DevOps when they really should be building out new features.

    But introducing more infrastructure abstraction can be met with certain challenges. This is often because departments have a wide range of cultures, processes and tooling already in place. With varying maturity levels across teams, it can be challenging to gauge where a company is before attempting to introduce new automation across the board. And as further evolution may require significant changes, having a baseline is key to planning for the future.

    I recently chatted with David Williams, senior vice president of market strategy at Quali, about an internal technique they’ve been using at Quali to gauge the maturity of their clients’ infrastructure automation. Their infrastructure automation maturity model breaks down the journey into four unique stages, moving from the least-mature ad-hoc automation to the most-mature autonomous solutions. Below, we’ll review this model and consider what questions need to be asked to ascertain where your team sits on the spectrum. We’ll see how enterprises can leverage such a model to hone in on improving their software operations.

    Four Questions to Determine Infrastructure Maturity

    DevOps is still a wild west in terms of how people approach it, said Williams. So before attempting to mandate sweeping cultural changes, it helps to first determine the base level of DevOps maturity within an organization. Here are four questions that can quickly assess the state of infrastructure automation within an organization.

    1. What Culture Already Exists?

    First, it’s good to evaluate the culture that already exists. How do teams deliver value and how is this value measured? Perhaps throughput or code quality is measured with specific metrics or SLAs. Understanding the DevOps attitude (and aptitude) within the organization will highlight pre-existing capabilities and show how teams collaborate.

    2. How Are People Organized?

    The genetic makeup of teams can dictate much about development and operations. How are teams organized? Are they large, siloed teams? Or are they two-pizza-sized teams? Understanding team organization and communication patterns are necessary to identify bottlenecks.

    3. What Processes Are Already in Place?

    Next, consider the development timelines and procedures already established and in use. Are teams applying SAFe, Lean, Agile or Scrum methodologies? What are these exact processes and how mature are they? Answers to these questions will demonstrate general release cadences and how teams drive productization.

    4. What Infrastructure Automation is Already Being Used?

    Lastly, you’ll need a window into what level of infrastructure automation, if any, is already in use today. How is it delivered? How is it managed? How is the success of this automation measured, and what is the overall outcome? You will likely find that automation is typically quite siloed and teams have differing approaches. This auditing is vital to identify what works well and what doesn’t.

    The Four Levels of the Infrastructure Automation Maturity Model

    Asking the above questions will quickly determine an organization’s “readiness state,” said Williams. But how do these answers map to the overall maturity of the organization’s infrastructure automation? Well, he shared four basic levels of infrastructure automation maturity that are commonly found in practice throughout today’s software development environments, ranging from bespoke scripts to more robust self-defining automation.

    Level 1: Ad-hoc

    The most basic level of infrastructure automation is ad-hoc integrations involving a mix of old and new technology. This level is chaotic and fragmented, with varying processes used throughout the organization. These bespoke integrations and scripts also may not have excellent visibility, limiting the potential for reusability within an organization.

    Level 2: Automation

    Next is having automation that is specifically tied to a certain technology stack. Nowadays, organizations are commonly hybrid multi-cloud, having adopted automation piecemeal with each new stack. This often results in multiple silos of automation stacks that are blind to each other. At this maturity level, one automation might fire off another automated procedure and so on, but engineers aren’t 100% aware of how they influence each other.

    Level 3: Frictionless

    The next level of infrastructure maturity begins to take the reins with more intentional automation adoption. At this stage, organizations embrace an internal developer platform, similar to Spotify’s Backstage, that helps engineers deliver and manage infrastructure more seamlessly. This tooling is more advanced than other levels integrating key commands into the developer’s IDE. Doing so eliminates the need to switch between environments and reduces friction.

    Level 4: Self-Defining

    Finally, the most advanced form of automation involves deeper intelligence within application operations, including the ability to dynamically optimize infrastructure. At this stage, infrastructure is self-defining, meaning production applications can automatically adapt, be self-governed and enable bursting and non-bursting capabilities. Such intelligence is typically proprietary to cloud providers, said Williams, yet companies often desire this intelligence inherent at the application level. Williams describes this stage as the “intelligent allocation of resources in line with application life cycle requirements.”

    Benefits of Self-Defining Infrastructure Automation

    Self-defining infrastructure automation has many benefits for companies, including having the infrastructure in line with application needs, scalability and measuring usage to optimize cloud spending. Many points within the software development life cycle could warrant increased automation, such as infrastructure-as-code (IaC), deployment release engines, configuration, traffic scalability, cloud management, containerization and documentation. But it’s not until you open conversations around infrastructure automation maturity and understand who is responsible for managing it that you can hone in on what areas can be improved.