Category: DevOps Practice

  • The Linux Foundation Adds Free Jenkins Training Course

    The Linux Foundation Adds Free Jenkins Training Course

    The Linux Foundation, in collaboration with the Continuous Delivery Foundation (CDF), today launched a free introductory course to the open source Jenkins continuous integration/continuous delivery (CI/CD) platform as part of what it plans will become a series of free and paid online DevOps tools courses.

    Clyde Seepersad, general manager of training at the Linux Foundation, said that while the foundation already provides access to some higher-level conceptual DevOps courses, the launch of the CDF last year provides a knowledge base from which the Linux Foundation can now provide online courses specific to DevOps tools. The CDF is an arm of The Linux Foundation.

    The Linux Foundation will also provide courses on Spinnaker, a CD platform, and other DevOps tools that, along with Jenkins, are now being developed under the auspices of the CDF, he added.

    In general, Seepersad said demand for DevOps expertise is increasing as organizations more aggressively embrace digital business transformation initiatives in the wake of the COVID-19 pandemic. At the same time, IT teams are adopting a wider range of cloud-native technologies to build more flexible and resilient applications. DevOps platforms such as Jenkins make it possible for IT teams to build those applications faster.

    The challenge many organizations underestimate is the extent of changes to their internal IT culture required to make that transition, Seepersad said—too many organizations still put tools into the hands of developers without really thinking through the workflow issues between developers and IT operations teams.

    The most important thing for any organization to do, he said, is to make sure there is an open DevOps dialogue versus tiptoeing around issues that will tend to increase resistance only further.

    Ultimately, free training should help expand the overall size of the DevOps community at a time when many IT professionals are trying to increase their skills. DevOps professionals not only command higher salaries, but they are also less likely to be laid off. DevOps teams oversee the development and deployment of applications and can also programmatically manage levels of infrastructure that IT administrators relying on traditional graphical user interface (GUI) tools can’t match. That’s a critical issue when many IT organizations these days are trying to do a lot more with even less.

    There’s nothing quite like an economic crisis to focus everyone’s mind. The biggest DevOps challenge any organization typically faces is overcoming inertia. Too many IT professionals have relatively narrow skillsets that conspire to increase the total size of the IT organization. In addition to relying on increased levels of automation to reduce costs, IT leaders want to be able to scale IT environments without having to increase headcount.

    It may take a little while longer for the transition to DevOps to fully play out. However, it’s now more of a question of existential survival rather than if or even to what degree to embrace DevOps. Organizations that don’t embrace DevOps processes to ruthlessly automate the management of IT now might very well never get another chance.

  • The Top 5 Challenges to Overcome with Heroku Logging

    The Top 5 Challenges to Overcome with Heroku Logging

    Heroku can be a very powerful tool for monitoring the massive amount of data generated by your applications, systems, APIs and add-ons.

    One thing you may have discovered with Heroku logging is that making sense of data within your log files can be time-consuming. When you’re running large numbers of applications which process tons of data each day, the sheer volume of data that appears in the logs can seem overwhelming.

    Managing Massive Log Output 

    Due to the sheer amount of data that is gathered, it’s important to find ways of making the process a little bit easier, limit information to what is useful and organize what you have into digestible pieces.

    Parsing with Drains

    Using Logplex and log drains can help you filter out large chunks of your logs. Syslog drains will help you move any system messages to another server for archiving purposes.  HTTPS drains can help you better take control of your system messaging for sending it to third-party apps for analysis. 

    By assigning clear indicators that identify the application, system or API that creates a log, these can be streamed into channels that can be better understood in relation to their given purposes. 

    Log Retention Period

    While we may think that more information is always good, there is a limit to the amount that we can process. Some log data becomes meaningless or redundant after a certain length of time. It is wise to set realistic log retention periods on data based on business needs.

    Limit Verbosity

    Don’t log everything. Turning on debugging is appropriate during development and if there is a specific problem that needs investigating, but in most cases, these shouldn’t be stored. 

    Complexity in Stream Patterns

    The challenge with large amounts of data is that there may be subtle differences between successful activity and erratic behavior. The details may be small, and essentially invisible to the naked eye unless examined carefully. 

    Use Regex for Identifying Patterns

    Through the use of log analytics tools, you can set these to pick up specified regex patterns to subtle changes or variations in your logs that can provide meaningful insights. 

    Different Log Data Needs

    You may have people with different needs who wish to make use of the information you gain in your Heroku logs. While you have data that is of interest to developers and QA engineers, there are other tech-savvy users who may wish to gain business intelligence (BI) from the massive output of data, to be able to identify key performance indicators (KPI).

    Analytics Tools

    Using intelligent add-on analytics applications can help by filtering and sorting information into usable chunks that can be understood by users in different roles. By accurately filtering, you can provide intelligent real-time alerts for a specific application or system behavior to those who may wish to make use of it. 

    Application Issue Forecasting

    One of the best potential uses of your detailed Heroku logs involves the opportunities to spot patterns of problems that have occurred in the past and use them to predict problems that may occur in the future.

    As an expert, you may be able to spot patterns in your logs, however, even the smartest and most attentive engineers will not be able to manually define every scenario worth detecting.

    Occasionally patterns will occur that are only detectable through the rote process of comparing and contrasting working behavior with non-working behavior. Often, the subtleties are too small for a human to be able to notice the difference.

    Machine Learning Assistance

    Naturally, utilizing ML-powered techniques can help catch the unknowns. By investing in ML, using some of the better libraries or choosing a Heroku logging add-on with these capabilities, you can monitor your applications and infrastructure with less effort. 

    Securing Sensitive Data

    With the rapid pace of CI/CD, a large amount of activity regularly flows through your pipelines from development into production. Throughout this process, it’s possible for sensitive data to start appearing in logs. While your teams may be diligent about keeping control over OAuth credentials, security keys, authentication tokens and more, nobody is perfect. Sensitive security credentials can accidentally make their way onto production servers. Sensitive customer data can also accidentally find its way into public logs if mistakes are made.

    Credential Detection and Security Alerts

    Logs can serve as a saving point for the identification of sensitive information. Using a parsing engine, these can be immediately redacted for compliant log management. By monitoring your log files for any patterns which could include secret keys or other potential security breaches, you’ll be able to continue ingesting critical log data without increasing business risk.

    Heroku Private Spaces

    With Heroku Enterprise, you can make use of Heroku Private Spaces which are an isolated network of private apps and data services, which will help you keep sensitive data separate from public interference. If you are handling a large amount of sensitive customer data, ensuring that any information gets filtered into these places will help you remain compliant with GDPR and other privacy-related regulations.   

    Conclusion

    Heroku can be a fantastic solution for monitoring the activity which goes on in your cloud clusters.  However, unless you have solid analytical tools in place, you may find yourself spending a lot of time wondering how to make use of this sea of data that has been collected. Consider using an add-on as an analytic layer to help spot patterns, organize data better and create smart alerts to make sure your operations continue to run smoothly.

  • Working with SAFe and Microservices: Learnings from Developers

    Working with SAFe and Microservices: Learnings from Developers

    As developers, the prospect of working for a big company might bring about feelings of oppression, rather than opportunity. Envisaging endless team syncs, pointless meetings and processes wrapped up in bureaucracy inside a set of procedures. It’s easy to imagine why some are put off. For many though, the fear comes from the thought of being lost in a corporate structure where input is not valued, and skills are wasted.

    But every day, as developer concepts become further rooted into corporate behaviors, the line between the two worlds continues to blur. Products are no longer dreamed up in product silos, but from agile teams made up of a diverse cross section of a company. Marketing has dropped drip campaigns in favor of A/B testing, rapid iterations of messaging and data-driven analytics. Big companies no longer mean old school thinking, but fast-changing, inclusive places to really make an impact and be heard. 

    Working within the Scaled Agile Framework (SAFe) with an agile architecture of microservices helps us to do our jobs, but the learnings we’d like to share in this article are universal. An organization may not require the SAFe methodology, but the experiences and methods of working can be applied to many roles and are based on three fundamental questions every developer should ask themselves. 

    How Do I Plan My Day? 

    As with any role, a good start for us is knowing that the previous day went well; that the code we wrote meets the standards required for deployment. Before that, our individual microservices teams will meet to discuss immediate priorities. We let one another know what’s top of mind for us, and any issues we might be facing — and we resolve them together before a midday Scrum meeting.

    The Scrum meeting involves the Scrum master, product owner and the developer team and gives us a chance to give feedback and dive into the wider challenges or blockers we’re facing with our own tasks. We might be thought of as solitary creatures, but we actually tend to solve problems together. So, while we have ownership of our own tasks, problem solving comes from collaboration.  

    Whether working within the agile framework or not, communication is a huge part of our lives. Our advice to developers everywhere is to be vocal about the need to engage within their organizations. And to business IT decision makers, we know that not every firm has the deep pockets to fund a dedicated DevOps team to implement new tools, change culture or break down silos, but there are many communications and open source DevOps tools that boost collaboration and improve workflows — most are well-known to developers. So, give them the chance to explore how they might bring efficiencies to their work. Help them help the business and maybe suggest trialing some new tools. 

    How Do I Upskill on the Job?

    Developers are problem solvers. We love the opportunity to help each other overcome challenges. Peer-to-peer communication doesn’t just allow us to get back on course quicker, it lets different teams share knowledge and pitch in to solve problems. We don’t mind being transparent with our peers when we face an issue – in fact, we quite like it, as the offshoot of working together often leads to new skills and technical knowledge. 

    Learning the interactions between each microservice, for example, helps us map out the architecture and understand how our own work fits into the bigger picture. The more we talk, the more we see where bottlenecks might occur — and the better equipped we are to achieve larger objectives. As we have complete ownership of our services, from initial coding to deployment, it is our duty to ensure our services perform as they should in production. 

    This ownership is something all developers should aim for. Even when working in a more rigid waterfall approach, opportunities to collaborate should be seized and encouraged — even if the only payoff is personal development. Implementing a system of peer code reviews, for example, not only delivers more robust releases, it fosters a collaborative mindset.

    Do I Need to Be in this Meeting?

    Working with SAFe methodology allows the job to be broken down into iterations linked to business objectives. The most significant of these is determined by meetings that occur every four months, where goals are set and roadmaps established to achieve them. Engineering teams then divide up the features that will be passed on to the developer teams, who break them down into two-week sprints. 

    The sprints are what the developer teams work to, under direction from the Scrum masters and product owners. Breaking iterations into smaller sprints ensures we have defined goals, which keep meetings and interactions on track (i.e., daily Scrum meetings and bi-weekly sprint meetings). Without this focus, there’s a risk of derailing the prep required to focus on writing and reviewing code. If we need a discussion about certain features, we make sure to identify exactly who needs to be in that meeting. Above all, we’re all about optimizing our time together. The longer we spend away from our desks, the less time we have to perform our core roles. 

    Whatever your part in the software development lifecycle, never be afraid of asking the question, “Do I need to be here?” Your energies may be best used elsewhere.

    As you can see, these three questions are critical to developers but can be applied to just about any role in just about any organization. Planning, learning and focusing – seems we’re not so different after all.


    Tomasz Rumpca


    This article was co-authored by Tomasz Rumpca, Java developer and team lead at Finastra. Tomasz works on FusionFabric.cloud, Finastra’s open development platform solution. He is passionate about Java-related technologies and building user-friendly software. Outside of work, he enjoys spending time outdoors with his friends and family.

  • Quality at Speed During the COVID-19 Pandemic

    Quality at Speed During the COVID-19 Pandemic

    Think back to 2015. The U.S. economy was in the early phases of a growth spurt that would continue for years. Ninety-five percent of organizations were practicing agile, to some extent (State of Agile, VersionOne). And the proportion of the IT budget allocated to QA and testing had just increased from 18% to 26% (World Quality Report, Capgemini). 

    “Quality at speed” became the catchphrase of the year in the testing world. With all the buzz around DevOps and agile, it was clear that speed mattered. In reality, most teams weren’t quite there yet. Agile adoption was still low (less than 50% of teams within each organization actually practiced it) and maturity was even lower (only 17% of those practicing it reported mature adoptions). Still, the writing on the wall was clear. Leaders wanted more application development, faster — so testers should at least prepare for the pending storm.  

    From that point forward, organizations across almost every industry all progressed to a sweet spot where time-to-market pressure was relatively high and cost pressure was moderate. By the end of 2019, quality at speed had graduated from buzzword to business as usual at most organizations. 

    But then came COVID-19. Now, we’re in the midst of a global pandemic. Every business, every non-profit and every governmental agency is impacted — but in different ways. 

    Speed expectations suddenly shifted into overdrive for an unlikely assortment of organizations, including government agencies and non-profits, healthcare and pharmaceutical companies, online retailers, online conferencing providers and telecoms. Yes, everyone had already been working to accelerate their software delivery processes. And many enterprise organizations had made great strides toward scaling the adoption of agile and DevOps. But, very few of these organizations were previously delivering applications at the extreme speeds required right now.

    For another group, cost reduction suddenly became the top priority. Airlines, hotels, as well as other travel and leisure organizations experienced such dramatic changes in fortune that speed became a non-issue. The focus shifted to increasing cost efficiency in an effort to offset some of these staggering losses. 

    Assuming that high quality cannot be compromised, this leaves both of these groups with distinctly different — yet equally daunting — challenges from a quality perspective. 

    The organizations in the first group suddenly needed to build, test and release applications at the speed of a startup — but with the added burden of legacy systems, complex application landscapes and intense regulatory scrutiny. Quality at speed remains the goal, but the “speed” part is much, much faster. 

    The organizations in the second group need to determine how to continue meeting strict quality expectations with a significantly slimmer testing budget. Quality at speed isn’t so important right now. Speed gets replaced by the other corner of the classic cost-quality-speed triangle, making the new mantra “quality at cost.” 

    It’s hard to find good news in the current situation. But, from the software testing perspective at least, there’s some consolation. Whether you’re facing unprecedented time-to-market pressure or extreme cost pressure, the same core “test efficiency” strategies will help you either way. 

    Here’s a quick overview of ways you can test more efficiently at different steps of the software testing process.

    Selecting and Designing Test Cases

    I’m addressing these two steps together because they both face a common challenge: intuition. Most modern business systems are insanely complex — so complex that it’s just not feasible for most testers to intuitively identify the best set of tests to cover a specific test need. Having a more systematic way to find the smallest — yet most powerful — set of tests will save you both time and money. 

    For designing test cases for progression testing, methodologies like linear expansion and pairwise testing can help, and augmented intelligence can dramatically simplify them for you. 

    For selecting what test cases should be run for regression testing, consider change impact analysis. Some approaches identify which objects are impacted by a given change, then help you narrow the test scope to the impacted objects. This often reduces the testing scope by 15%. Not bad, but you can do much better.

    AI-powered change impact analysis pinpoints exactly what needs to be tested in a given update, based on whether the changes put an object at risk. With this approach, you can reduce testing efforts by 85% or more. Not only is this approach faster and cheaper, it’s much more efficient at uncovering defects. The number of defects that hit production are reduced by 75% to 95%, sometimes even 100% (no defects in production).

    Automation and Execution

    Here, technical scripting is the top time and cost drain. Some level of maintenance is required to keep scripts running, and this maintenance will cut into your test efficiency. One way to combat this challenge is to take a model-based approach to test automation. Such approaches have been field-tested for years, and proven to solve the test maintenance nightmare that’s doomed all-too-many test automation initiatives. 

    The new kid on the block is AI-driven UI test automation. This is a big topic that warrants a much deeper discussion — but here’s a quick overview. Specify tests in natural language. Build the tests even before the actual UI is ready. Use the same tests as the technical implementation changes. Understand dynamic behavior like a human tester would. Test absolutely any technology — faster than a human eye. Curious? Stay tuned. 

    Analysis of Results

    When it comes to results analysis, false positives are the vampire sucking your resources. False positives are tests that fail even though the application is behaving correctly.  They will really kill you in terms of cost and speed. First, someone needs to figure out why the test failed. This might involve manually checking the related application functionality, inspecting the test automation, reviewing the test data, checking whether every element of the test environment is up and working as expected — maybe even all of the above. Once the exact problem is found, it needs to be fixed. Then, the test needs to be rerun. If it still fails, rinse and repeat.

    How do you stop false positives? To start, stabilize the automation with model-based test automation or the AI-driven testing I mentioned in the previous section. As you move into more advanced automation scenarios, stateful test data management and service virtualization can help you stabilize tests to the point that they’re fit for CI/CD. Then, your final challenge is to deal with the flaky tests resulting from things like asynchronous application behavior, concurrency issues and test order dependencies. Again, AI and ML can offer tremendous assistance here—in flagging potential false positives, and even in helping you identify the cause and optimal resolution. 

    Final Thoughts

    COVID-19 split up the original quality at speed sweet spot into the extreme speed camp and the extreme cost-savings camp. In both cases, the same core strategies to increase your test efficiency will help you increase speed as well as reduce testing costs. If you’re under extreme time pressure, showing that you also reduced costs while meeting speed expectations certainly won’t hurt. If you’re currently reducing costs because your industry is essentially paused, taking these steps now will prepare you to speed it back up when the world becomes more normal again.

  • How DevOps Powered by AI and Machine Learning Is Delivering Business Transformation

    How DevOps Powered by AI and Machine Learning Is Delivering Business Transformation

    The use of artificial intelligence (AI) and machine learning (ML) is fundamentally changing the way we think about DevOps. Most notably, it is delivering a new form of DevOps that recognizes the need to have systems that are intelligent by design and underpinned by comprehensive security (DevSecOps). For many, this will be the crucial next step if DevOps is to shorten the software development lifecycle for all connected intelligent systems, ensuring the continuous delivery of secure high-quality software.

    By now, most organizations understand DevOps is a substantial discipline that they must adopt – according to Deloitte, organizations adopting DevOps see an 18%-21% reduction in time to market. By breaking down the silos between business and IT operations, DevOps can ensure consistent levels of productivity, efficiency and service delivery, all of which hold weight in these times of heightened uncertainty.

    To put it simply, DevOps can help businesses compete in already congested marketplaces. Through a foundation of continuous integration (CI) and continuous delivery (CD), organizations can ensure the customer receives the product they demand in the fastest time possible, while mitigating any elongated frustrations experienced from a lack of harmony between systems engineers and operations teams. Incorporating AI and ML into that DevOps strategy will take things to the next level.

    AI and ML Are the Next Evolutionary Step for DevOps

    Today’s companies are data-driven and being built as digital platforms. However, just 28% of organizations are currently succeeding in their digital transformation journeys. Increasingly, corporations are looking at what AI and ML can do to help them realize their transformative ambitions.

    Both the AI and ML markets are expected to experience huge growth over the next three to four years. Analyst firm IDC, predicts worldwide spending on AI systems will reach a href=”https://www.marketresearchfuture.com/reports/machine-learning-market-2494″>42.8% by 2024.

    What AI and ML reveals for these companies, and the increasing value of what Al, ML and devices can do together, are changing the way organizations view the world as they digitally transform. Coupling AI and ML with DevOps will lead to a significant shift in what DevOps gets involved with. 

    Primarily, it sets DevOps front and center of an organization’s wider digital transformation ambitions. If digital companies run on living data, then the development of these intelligent systems is an enticing environment for DevOps to prove its wider value to the organization like never before.

    Security Takes the Center Stage

    According to a TechTarget survey of key IT decision makers, cybersecurity and risk management were found to be the number one area for spending this year, with more than 53% of respondents saying they saw budgets increase in this area. And security is a crucial element that any organization employing a DevOps strategy should be considering. 

    DevSecOps is the simple premise that everyone involved in the software development cycle is responsible for security. In fact, the saying “security is everyone’s responsibility,” is a mantra that has been repeated often, and just as often ignored. Embedding security within every part of the development process, ensures security and compliance monitoring tools keep pace with the speed and agility that DevOps offers. It is a common understanding that security is the biggest block to the rapid and seamless development and deployment of systems, as security solutions have not traditionally been built to test and code at the speed DevOps requires. 

    Ultimately though, more automation from the start, reducing the need for manual configuration from security architect is where DevSecOps shines. This reduces the chance of misadministration and occurring faults, which can lead to downtime, and potential breaches or attacks. Quite often, the best ways to secure your organization is through simple hygiene factors, such as regular patching and software updates. 

    The reality is that every organization employing DevOps should really be approaching it as DevSecOps. Security is of ever growing importance to each and every organization and, through empowering it with AI and ML processes, it can be enhanced too, simplifying the processing of data to easily identify threats or potential vulnerabilities in the security makeup. 

    Reaching Beyond Human Capability

    The future will be made up of connected intelligent systems that span the intelligent edge, all the way to the cloud. The expectations of these systems are based on the lifecycle of a typical mobile application with constant feature enhancements. But, how do you know what to deliver next, especially when things are moving so quickly, and as developers are inundated with information and data from a number of different sources? This data deluge can be powerful, but it can also be overwhelming.

    Crucially, this is where the power of AI and ML comes into play. AI and ML will aid developers in making sense of the information housed across various data warehouses. In DevSecOps, there has always been an approach to automate everything, and AI and ML will be instrumental in automating the analysis and processing of data – a task that is now far beyond the capabilities of humans.

    Incorporating AI and ML will enable developers to better understand and use the data at hand. This will see developers understand not only the error, or the occurrence of a fault, but the detail of what happened in the run up to the fault – vastly reducing the chances of incurring that fault again. AI and ML will also be responsible for enabling the transformation from diagnostics to prognostics across any and all tools and systems, making it easier for developers to anticipate, identify and resolve faults or errors. 

    Increasingly, we’ll see organizations benefit and drive value from real-time insights. They’ll do this through AI and ML frameworks deployed on active systems to deliver optimizations based on real-time development, validation and operational data. This level of real-time actionable insight bolsters DevSecOps’ ability to achieve CI and CD, through improved, reduced mean time to resolution, easing the impact on operations and, ultimately, enhancing the end-user experience. It remains to be seen if incorporating AI and ML into the DevSecOps cycle will achieve the delivery of self-healing systems that can detect and resolve issues without the need for human intervention. With true AI, however, this might well be possible.

    The benefits and potential use cases of AI and ML are widely acclaimed, and while we are still some way from seeing their full potential, the capabilities they currently possess are revolutionizing many sectors. The fact is, if DevSecOps is to continue to keep pace with the vastly growing digital data economy, then it will become reliant on advanced technologies such as AI and ML. Data is powerful if used correctly, but with so much of it to process and analyze, that can be a challenge.

    A move toward secure automated processes is the progressive step that many organizations need to consider if they are to realize their digital transformation ambitions. Organizations cannot continue to do things the traditional way and expect to get the results that the new world is looking for.

  • Chef Extends IT Automation Reach

    Chef Extends IT Automation Reach

    Chef, at its online ChefConf 2020 event today, launched Chef Compliance and Chef Desktop as well as additional enhancements to the tools it provides for application deployment automation.

    John Wyss, vice president of product for Chef, said Chef Desktop enables IT teams to write their own configuration and compliance requirements as human-readable code using YAML files to manage and secure entire fleets of endpoints via a centralized console. It includes pre-written configuration code and curated content that can be employed to both audit and harden desktop operating systems.

    IT teams will now avail themselves of a zero-touch process for enrolling and provisioning endpoints while at the same time automating software deployment and management, Wyss said. That includes being able to enforce security policies using configuration profiles, data encryption and system updates.

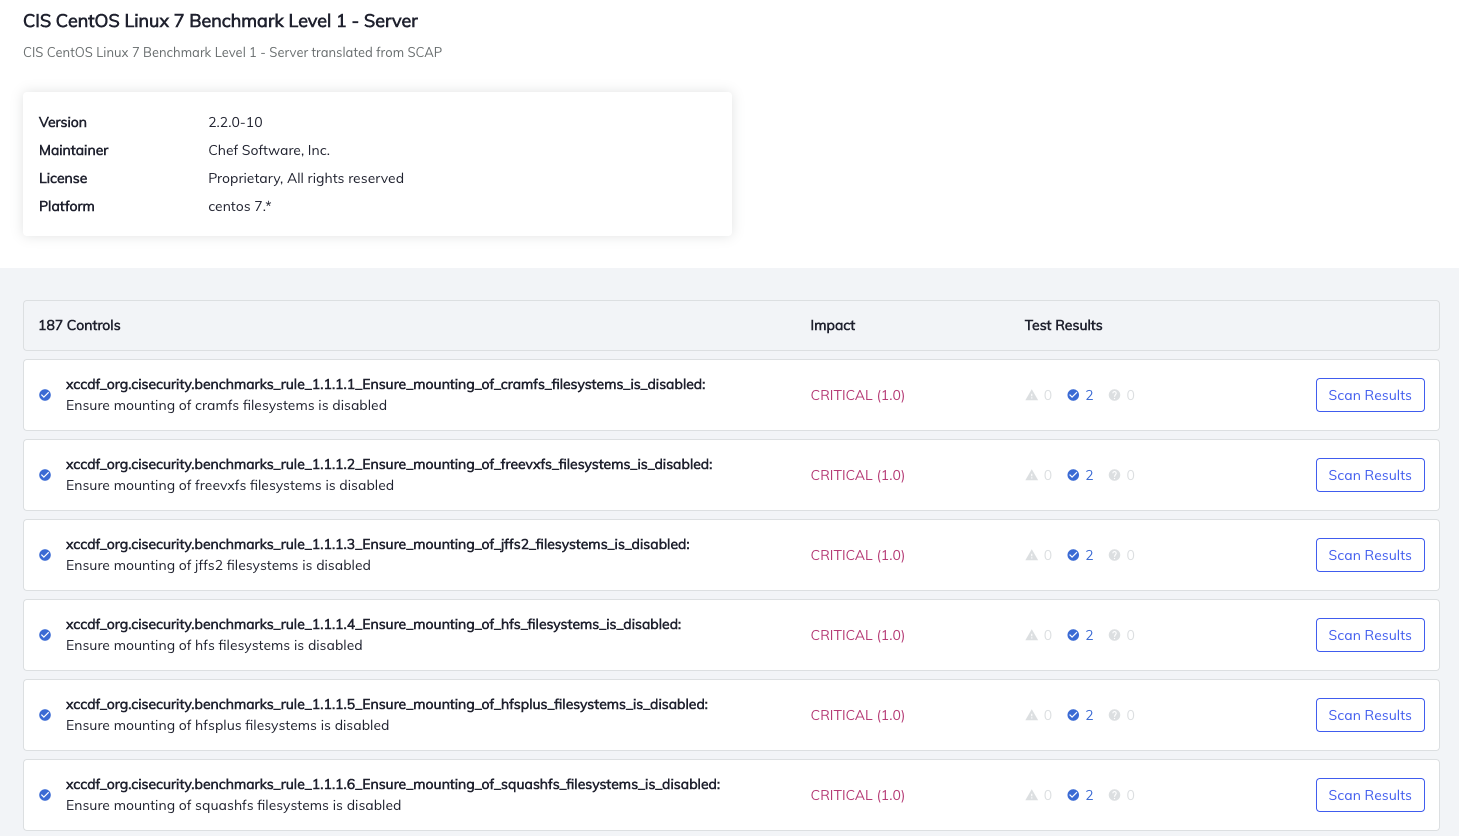
    Chef Compliance, meanwhile, is built on top of Chef InSpec, an open source framework for testing and auditing applications and infrastructure. Chef Compliance takes Chef InSpec further by including tools to automatically audit IT environments based on the specifications defined by the Center for Internet Security (CIS) and Security Technology Implementation Guide (STIG).

    Those audits can then be applied to automate the remediation process without having to write code if IT teams so choose, said Wyss. The goal is to provide DevSecOps teams with a unified language for managing security and compliance, he added.

    Finally, Chef has updated Chef Enterprise Automation Stack to include analytics to filter and update views for disconnected services and receive real-time health-check messages and status alerts. Chef has also added rapid rollback, package cleanup and layered container support, and has made it easier to manage package settings and deploy packages across multiple platforms.

    Collectively, these capabilities should make it easier for DevOps teams to reduce process friction across the entire DevOps life cycle.

    In the wake of the economic downturn brought on by the COVID-19 pandemic, interest in IT automation is on the rise. Many organizations are either freezing IT headcount or, worse, yet, reducing the size of their IT staff. At the same time, IT environment is becoming more complex, especially if most employees continue to work from home. IT teams now need a common set of tools for managing not only application deployments on servers or in the cloud but also endpoints. Ultimately, that approach should also go a long way toward reducing the total cost of IT.

    In fact, in the wake of the downturn more organizations than ever are receptive to automating IT processes. What was once viewed as potentially an existential threat to the existence of the IT staff has become the only way to manage IT at scale, at a time when cutbacks are broad-based. Organizations that don’t find a way to automate the management of IT are likely to incur significantly higher costs than those that do. Arguably, the issue is no longer what to automate and when, but rather how much and how soon, as both applications and the end users accessing them become ever more distributed.

  • Survey Surfaces Tension Between Software Speed and Quality

    Survey Surfaces Tension Between Software Speed and Quality

    A survey of 600 software professionals at organizations with more than 1,000 employees published today by OverOps, a provider of software analytics tools, finds the need to ensure quality still trumps the need for speed within most organizations.

    According to the survey results, 70% of respondents say quality is their paramount concern and they would rather delay a product road map than risk a critical error impacting their users. More than half of the survey respondents (53%) said they encounter such critical or customer-impacting issues in production at least one or more times a month. Two out of three survey participants report spending at least a day per week troubleshooting issues in their code, with 30% spending anywhere from two days to a full week.

    Nevertheless, organizations continue to invest DevOps (58%) to accelerate application development. Among those organizations, continuous integration (54%) and continuous delivery (42%) platforms were the top priority.

    Other areas of investment include microservices/containers (45%), static analysis (37%) and dynamic code analysis (27%).

    Nearly half of respondents (45%) said pressure to move fast was one of their top software quality challenges. More than half of respondents (59%) said they release new code/features anywhere from bi-weekly to multiple times a day.

    Despite investments in DevOps, however, a quarter of participants also said that over 40% of critical production issues are first reported by end users or customers rather than internal systems.

    OverOps CTO Tal Weiss said the survey makes it clear there needs to be more focus on software quality. The challenge organizations face is finding a way to achieve that goal while still accelerating the rate at which code is delivered. Too many organizations are measuring the lines of code delivered without taking into account how often they run into issues in production environments because of the quality of the code deployed.

    Of course, whenever a project falls behind one of the first places any organization looks to make up ground is by reducing the amount of time allocated to testing. However, many organizations are also integrating testing within CI/CD platforms to make sure critical testing processes are not skipped in the name of making a deadline.

    It’s not clear whether software being deployed today is any higher or lower in quality than software developed using legacy waterfall approaches. As long as humans write code, there will always be issues. Proponents of DevOps will argue that deploying smaller amounts of code more frequently helps mitigate that issue. If errors are discovered, it’s easier for DevOps teams to not only roll back that smaller update but also more quickly discover the source of any issue. Sometimes that issue may have more to do with the platform the code is being deployed on than the code itself.

    Regardless of the approach to developing software, there is clearly more at stake than ever. As organizations embrace digital business transformation the quality of any software update can have a major impact on the business. The challenge is first eliminating as many of those disruptions as possible and then, secondly, minimizing their potential impact on the business as quickly as possible.

  • How Embedded Real-Time Engagement Makes the Internet More Inclusive

    How Embedded Real-Time Engagement Makes the Internet More Inclusive

    We hear the word “inclusivity” thrown about quite a bit these days. Some would call it a buzzword, but inclusivity is important to consider given all the innovation we have seen in the past decade. From powerful smartphones to VR video games, technological capabilities keep moving ahead in leaps and bounds.

    However, factors like geographic location, disabilities and socioeconomic standing  prevent some of us from reaping the technological benefits as much as others. The good news is, when incorporated correctly, technology can close these gaps and improve access to important resources and engagement on a global scale.

    What Does Inclusivity in Technology Actually Look Like?

    Simply put, inclusivity in technology is a concerted effort by developers (and the businesses that hire them) to create with empathy. It also means approaching accessibility as an opportunity, not a burden. This sounds easy, but the reality is that mobile and desktop apps are becoming increasingly sophisticated. Today, almost every single platform we use has a social component and provides elements of real-time engagement.

    From live streaming, to broadcasting, to video chat and beyond, real-time engagement technology is bringing new services and communication capabilities to the masses in amazing new ways. In fact, it has reached incredible prevalence in all industries as consumers demand the ability to connect with others as they do just about everything online. This includes shopping, playing video games, collaborating with coworkers, working out and even getting an education — name the activity and there’s a need for voice and video capabilities to improve it online.

    But, there are still glaring inequalities in who can enjoy the services we can now access through real-time engagement technology. While there are many different ways to weave inclusivity into a program’s design, here are just a few to consider.

    Borders Are for Maps, Not Your Apps

    Where we are born shouldn’t be the deciding factor of whether or not we can enjoy the technological revolution. However, limited access to 5G and technology still makes it hard for some communities to access real-time engagement platforms. Take for example a remote, rural village served by 2G internet while major metropolitan centers with 5G access can stream everything from sports events to yoga classes.

    Building on a dedicated real-time communications network can be the great equalizer. Unlike public networks, dedicated networks deliver scalable, sub-second and low-latency results from anywhere in the world. This is made possible with algorithms that monitor in real-time and select the most efficient routing path automatically. The end result is a high-availability network that sees no boundaries.

    Dedicated networks are already making a huge difference. Doki Doki, a voice technology company, announced a partnership to work with South African National Council for the Blind to bring Dabel, an audio streaming app, to blind users in underserved regions of Africa. By integrating Agora’s dedicated network, Doki Doki was able to ensure that Dabel could cross borders and reach users on low-bandwidth networks and on lower-powered devices.

    Design with Users with Disabilities in Mind

    Many companies do not do enough to accommodate users with disabilities. For example, those who are hard of hearing might not be able to enjoy audio features of certain applications. In this day and age, that’s simply unacceptable. While developers might be challenged to create an equally rich experience for all users, they can lead the charge to design inclusively by making modifications to popular apps and platforms that  keep accessibility in mind.

    According to the National Institute on Deafness and Other Communications Disorders, at least 10% of Americans (roughly 25 million) deal with some level of hearing loss that ranges from mild to total deafness. To communicate, this community uses the widely adopted American Sign Language (ASL) system. But not everyone knows ASL, which can make communication difficult. People with hearing impairments can communicate via interpreters when available, but this option isn’t often available online. This creates obvious barriers to free-flowing and natural conversation on real-time engagement platforms.

    As developers, we can empower end-users with hearing impairments by building a sign language recognition app into platforms that translates ASL gestures into text and speech in real-time. This kind of app lets users sign-in to a video chat while the application simultaneously uses machine learning and augmented reality to translate ASL into spoken word or text.

    The utility of this technology can be limitless when applied more widely. Consider for a moment a mobile therapy application. The beauty of these apps is that users can quickly access mental health services when they need them the most. But, what if a therapist who knows ASL isn’t online when a person who is hearing impaired needs a session? Integrated sign language recognition would reduce barriers to having a meaningful virtual experience for a wider range of users.

    Expand Access to Essential Resources Like Healthcare

    Providing widely-available, quality healthcare is a central value across many cultures, but for many, the quality of healthcare can vary greatly based on physical resources. If physical infrastructure is lagging, why not turn to digital platforms to try and lessen gaps in care?

    In early March, DrFirst, a pioneer in telehealth, announced the creation of Backline, a powerful collaboration tool that allows healthcare providers and patients to communicate from anywhere in the world. By way of powerful, real-time engagement features, clinicians can remotely treat symptoms, discuss care plans and even correspond with EMTs in emergencies. For patients that live in underserved regions or who may be contagious, this alternate avenue could mean the difference between life and death.

    Developing to Deliver Solutions

    As developers, we have the power to help connect people around the world and deliver valuable resources with minimal barriers to access. With the pandemic upending any notion we had of a normal life, this has never been more apparent. Innovation is springing up in diverse places as we watch industries undergo swift digital transformations in an attempt to stay relevant.

    As we ride this wave of ingenuity, we should remember that access means more than just being able to download an app and run it on your phone or web browser. Today, we have sophisticated technology that can be leveraged to bring tech to people and places that have been historically underserved. Developers who create technology with that consciousness in mind can help deliver technological solutions that will improve societies in countless ways.

  • BMC Software Closes Compuware Deal, Sets Course

    BMC Software Closes Compuware Deal, Sets Course

    BMC Software today announced it has formally completed its acquisition of Compuware as part of an expanded effort to modernize mainframe environments.

    Bill Miller, president of ZSolutions at BMC, said now that the deal has been closed the combined companies will be able to more tightly integrate Compuware’s Topaz application development and deployment platform with the BMC Automated Mainframe Intelligence platform, as part of an Autonomous Digital Enterprise (ADE) initiative based on ongoing investments BMC is making in AIOps.

    Chris O’Malley, CEO of Compuware, said that level of integration will, for example, make it easier to automate the deployment of database and provisioning of mainframe resources using tools from BMC within a set of DevOps processes optimized for mainframe environments.

    The goal is to make the mainframe just one more target platform on which DevOps teams can build and deploy applications faster, added O’Malley. That’s becoming a bigger requirement in the wake of the economic downturn brought on by the COVID-19 pandemic, he said, as organizations prioritize digital business transformation initiatives that will inevitably require updates to mainframe applications.

    Rather than increasing technical debt by duplicating existing capabilities, O’Malley said more organizations will look to modernize mainframe applications to make them more accessible to a wide variety of front-end applications.

    The rate at which IT organizations that deploy applications on mainframes have been adopting DevOps has been uneven at best. Mainframe applications are often considered to be among the most mission-critical in the enterprise. Therefore, IT teams have relied on waterfall processes to build and deploy mainframe applications in a more deliberate fashion.

    At the same time, however, the use of Linux on mainframes has increased considerably in the last several years. The applications deployed on Linux operating systems on the mainframe frequently employ the same DevOps processes to deploy applications on Linux running on distributed computing systems.

    BMC’s ambitions, of course, far exceed the mainframe. The company has a portfolio of tools for managing both distributed computing and mainframe platforms. During the economic downturn, BMC is betting many IT teams will be under increased pressure to reduce the total cost of IT by centralizing the management of mainframes and distributed computing systems, among other moves.

    Of course, BMC is not the only IT vendor with similar ambitions. IBM and Broadcom, which acquired CA Technologies, are moving down a similar path. IT organizations will need to determine which providers enable them to best streamline management processes.

    In the meantime, it remains to be seen how much organizations remain committed to the mainframe. It’s generally not feasible for most organizations to move a transaction processing application running on zOS into the cloud. However, it doesn’t necessarily follow that those IT organizations will continue to invest in building and deploying new applications on mainframes instead of making them more accessible via application programming interfaces (APIs).

    Regardless of the strategy adopted, however, it is not likely that after being around for more than 50 years, mainframes will be disappearing anytime soon.

  • 5 Reasons Why Your App Needs an Error Monitoring System

    5 Reasons Why Your App Needs an Error Monitoring System

    All software applications have errors. Bugs are simply part of software development. That’s why engineering organizations need to know exactly what errors are occurring so decisions can be made around which bugs to fix.

    The fastest way to identify and fix application errors is to implement error monitoring software. However, not all solutions are created equal, and the best error monitoring systems do more than error alerting. They provide insights into the stability of the software, give developers metrics for addressing technical debt and enable better decision making around building features versus fixing bugs.

    The result? Happier developers who build better apps that match customer expectations.

    Here are five specific reasons why engineering organizations should adopt an error monitoring system.

    Error Monitoring Improves Application Health

    At its core, an error monitoring system addresses the challenge to find, fix and prioritize software bugs. However, what makes an error monitoring solution stand out is stability scores, which make it easier to maintain a healthy app.

    • Calculated with real-time error rates and session data, stability scores reflect the percentage of successful user interactions per release. 
    • They tell the real story about the impact of errors and technical debt and provide a single, unifying metric that speaks directly to the overall application health.
    • Stability scores can be used across teams to set stability targets (critical stability and target stability), which in turn can determine whether the app is healthy enough for building new features, or if it’s time to fix bugs.

    An Error Monitoring Solution Increases Team Productivity

    With a lack of detailed information about the source and factors contributing to a bug or crash, developers must conduct research to pinpoint errors, which is a time-intensive process.

    Without Error Monitoring With Error Monitoring
    Sixty percent of developer time wasted investigating and fixing errors, often in code they didn’t write. Forty percent increase in developer productivity with the exact location and source of the error provided by error monitoring solution.

    From detection to resolution, error monitoring with stability scores determines whether debugging needs to be part of the workload and which errors should be addressed first. In addition, the best error monitoring tools help prioritize business-critical and revenue-impacting errors to ensure alignment from top to bottom within an organization.

    Understanding Your Application Errors Can Reduce Costs and Increase Revenue

    With an error monitoring service that catches errors quickly, engineers save time, avoid critical errors and deliver crash-free applications that users want to spend money on. New features can also be rolled out on time with fewer errors, which makes developers and users happy. 

    • On average, companies lose $1,500 per engineer each month over debugging.
    • Knight Capital Group lost $440 million in a mere 30 minutes due to a software bug.

    Technical issues are the number one reason apps get deleted. Thankfully, companies that deliver smooth app experiences benefit from loyal users who trust and spend money on their brand.

    Error Monitoring Retains Development Talent and Boosts Morale

    Technical debt is hard on engineers, both from a productivity and emotional perspective. Without a common language to explain its impact to other teams, developers often become frustrated at bearing the burden of technical debt, which can cause disengagement and encourage developers to leave.

    Error monitoring management and stability scores bring complete visibility and cross-team agreement around software stability and prioritization of errors. Stability scores provide:

    • A common vernacular for discussion between engineering, product, QA and release teams about when it’s time to fix bugs versus build new features.
    • A metrics-driven reflection of the impact of technical debt on the product and clear demonstration about when it’s time to address it.
    • A singular goal for application stability, which turns development and product teams into allies and increases morale across the organization.

    Error Handling Impacts User Satisfaction and Usage, and Safeguards App Store Ratings

    Apps play an important role in our personal and professional lives. Widespread app adoption and daily usage point to why application errors are becoming unacceptable to users, who aren’t shy about speaking up when errors do occur. 

    • Ninety- six percent of mobile app users write bad reviews for sub-par apps.
    • Forty-two percent of 0-star app ratings in the Google Play Store mention app stability and bugs.

    The best way to ensure users have a positive customer experience is to use error monitoring to catch errors in real-time so you can respond immediately. Error monitoring provides a hope for avoiding poor app store ratings and for keeping customers satisfied.