Category: DevOps Practice

  • RapidAPI Adds Library to Invoke Kafka via API

    RapidAPI Adds Library to Invoke Kafka via API

    RapidAPI announced it has added support for the open source Kafka messaging software as another type of application programming interface (API) that DevOps teams can centrally access.

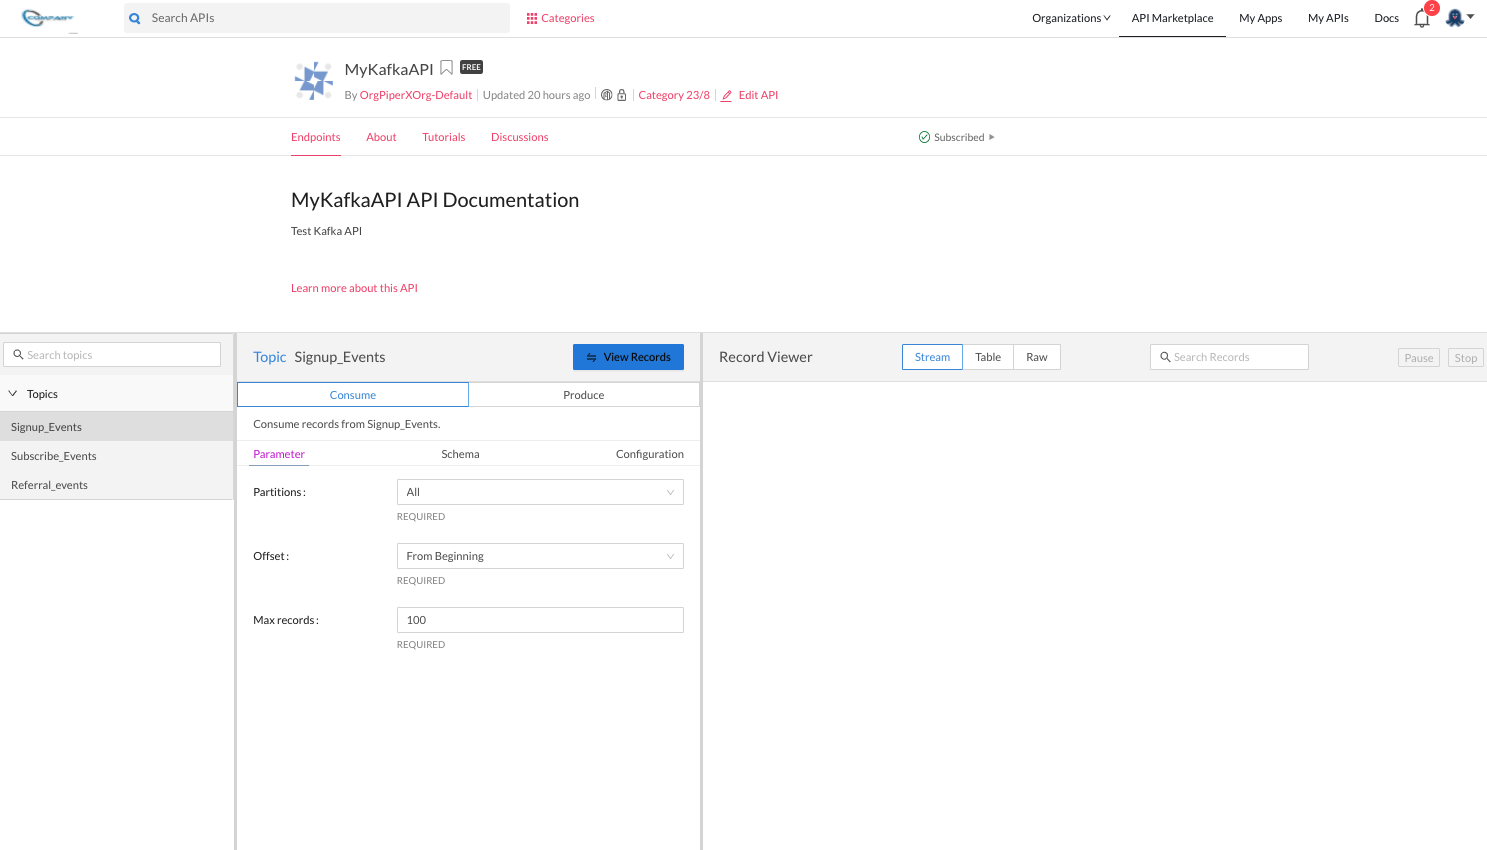
    An open source library provided by RapidAPI, available in beta, makes it possible to discover Kafka clusters and topics, view schemas and test and consume records from a browser via either the RapidAPI Marketplace or the RapidAPI Enterprise Hub. The library is based on Apache Avro and Confluent wire formats found in the open source confluent-schema-registry library. RapidAPI extended that library to add support for JSON and a protocol buffer, which is now being shared with the open source Kafka community.

    RapidAPI CEO Iddo Gino said DevOps teams can now discover all available Kafka clusters and instances in the same location where they find, test and connect to microservices based on REST, SOAP and GraphQL APIs. That effort is designed to complement initiatives, such as the AsyncAPI specification, that is now being advanced under the auspices of the Linux Foundation, Gino noted.

    RapidAPI is adding this capability because usage of Kafka to enable asynchronous communication across event-driven applications has significantly increased, Gino said. As the number of digital business transformation initiatives increased in the wake of the COVID-19 pandemic, Gino said reliance on asynchronous messaging platforms such as Kafka became a requirement. In many cases, synchronous communications across highly distributed applications simply isn’t feasible, Gino added.

    That doesn’t mean asynchronous requirements will replace the need for traditional synchronous APIs. Rather, developers will find themselves incorporating a greater mix of both as enterprise IT environments become more distributed, noted Gino. Applications are increasingly become one large puzzle that developers need to construct using various classes of APIs, added Gino.

    The library created by RapidAPI is expected to be generally available in the third quarter. In the meantime, adoption of Kafka continues to accelerate. The open source community that oversees development of Kafka, under the auspices of the Apache Software Foundation, claims more than 80% of all Fortune 100 companies are using the platform for everything from constructing data pipelines to running streaming analytics applications. In some cases, data is being queried directly while in transit versus waiting for it to be stored on-premises or in the cloud.

    Regardless of how Kafka is employed, developers are rediscovering event-driven architectures, that can trace their lineage to the 1980s, for building applications. The difference now is there an open source framework for handling the asynchronous communications required to build and deploy those applications at scale.

    It’s not quite clear how the rise of event-driven applications will impact DevOps workflows, as event-driven applications become more commonly built and deployed. However, as the APIs become more widely employed within the context of these applications, it should become simpler to incorporate them.

    The challenge is event-driven architectures typically requires developers to think differently about how their applications are structured, so it might be a while before Kafka – and other similar platforms – are pervasively employed across the enterprise.

  • How Low-CodeOps Can Transform DevOps

    How Low-CodeOps Can Transform DevOps

    Over the past year, enterprise adoption of low-code software development platforms surged across the world economy as COVID-19’s economic consequences drove an unprecedented number of digital initiatives. Enterprises are turning to low-code platforms to rapidly build new apps that empower customers, remote workers and external end users conducting business operations or pivoting to new opportunities.

    Accelerating software development, however, only solves half the puzzle of a digital-first approach. Quickly getting solutions into users’ hands requires careful planning to determine how these new applications will function within the organization’s overall software operations strategy. This is often conducted across multiple cloud deployments.

    But the real prize comes when low-code’s underlying principles of automation and abstraction are extended into the DevOps domain of software maintenance and management. The ability to push out a continuous pipeline of software updates with the click of mouse, with streamlined testing and quality assurance, requires a platform that automates myriad, time-consuming tasks associated with building, testing, releasing and maintaining applications in an enterprise-grade production environment. This inevitably leads to the concept of “low-code operations;” or, to coin a phrase, “Low-CodeOps.”

    Indeed, unless the benefits of abstraction and automation — in this case, primarily speed — extend to operations and deployment, the real benefits of low-code development are elusive. A platform that lets you build an app in six days but requires six months to deploy is no solution at all.

    Harnessing the Cloud for Game-Changing Results

    To witness the vital role seamless cloud operations played in business innovation, look no further than biotech giant Moderna and its success in Operation Warp Speed. Moderna used the public cloud to pull together geographically dispersed collaborators, integrate scientific insights and refine its production cycle, enabling the company to deliver its first batch of mRNA vaccine samples a mere 42 days after the COVID-19 virus genome was sequenced. The time-to-value for this solution was definitely warp speed.

    And, it’s safe to assume, expensive. Cloud engineers and DevOps system administrators are highly skilled specialists who roll up their sleeves at 2 a.m. to fix unexpected glitches buried deep in the connected ecosystem of software operations. They figure out how to make the software actually run. Enterprises, no doubt, wish they could hire more of them.

    But the same shortage of skilled IT professionals that fueled today’s demand for low-code software development also impacts DevOps. In this case, the same low-code platform is the solution, empowering a wider cross-functional, collaborative team to reduce operational burdens — in a word, Low-CodeOps.

    Essential Features of Low-CodeOps

    To achieve a frictionless handoff when moving applications and data to the cloud, a production environment leveraging low-code principles will deliver on these key principles of low-code operations:

    Performance monitoring: Daily monitoring and log checks of platform infrastructure are the backbone of modern DevOps operations, ensuring that complex interdependencies are running smoothly. Automated dashboard monitoring can transform hours spent on these repetitive tasks into opportunities for engineering teams to focus on innovation, while still ensuring the health and performance of enterprise software portfolios. The tooling needs to enable automated end-to-end visibility into application workloads and performance characteristics of upstream and downstream services.

    Compliance: Every economic sector is subject to specific government regulations. Software platforms and DevOp teams must keep track of every requirement when integrating new functionality into software upgrades. Banking customers must deploy digital solutions on infrastructure that’s earned ISO/IEC 27001 certification. Healthcare solutions must conform to federally mandated HIPAA requirements. Defense contractors must be FedRAMP certified. Data—the lynchpin of any digital solution—is subject to privacy laws that differ across nations and borders. Imagine having to manually recheck every iteration of your application deployments for compliance. Luckily, low-code operations mean having an automated, system-wide compliance framework in place. This makes short work of service organization (SOC) audits and reporting.

    Security: Cyberattacks that lead to system outages and disruptions are a growing concern in our digitally connected world. Well-resourced cloud giants are not exempt from damaging cyberattacks, such as last year’s SolarWinds hack. Resilience is key. Ongoing security scanning can halt automatic software deployments when suspicious changes are detected. Prevention is always best. Monitoring tools identify vulnerabilities, enabling systems to quickly come back online and help prevent outages that can last for hours or days.

    Infrastructure independence: Widespread enterprise adoption of multi-cloud and hybrid cloud for operational efficiencies has made flexible infrastructure the new standard. Organizations are bypassing single-vendor lock-in to spread workloads across multiple cloud partners. That means DevOps needs streamlined configuration and management tools that can track relationships between resources and keep track of compliance issues. Geopolitical considerations may enter the equation when cloud providers turn out to have close ties with governments antagonistic to other global trading partners. Monitoring instruments that provide observability across the range of vendors consuming enterprise data and applications is mission-critical.

    Resilience: Snafus happen. Platforms can automate continuous domain-level metrics to correlate performance from different sources (including logs, metrics, application tracing and outside penetration testing), speeding up detection and response time. Fast auditing and debugging tools, combined with real-time dashboard monitoring and system-wide alerts, plus an ounce of detection, equals a pound of cure. For agile DevOps teams, reactive firefighting is transformed into resilient firepower.

    Adopting an All-in-One Low-CodeOps Approach

    Low-code’s power to enable frequent iterations of software ideation, creation and deployment may seem contrary to the DevOps mission to minimize risks. However, the same radical abstraction and automation that has made software development faster, higher quality and more accessible to a larger cohort of developers can also reduce the operational burden of landscape management. Every low-code vendor touts the governance features in its platform. But the nuts and bolts of governance require some assembly, including system-wide actionable monitoring, testing alerts and compliance safeguards. Low-CodeOps combines the most efficient, agile, flexible development platform and powerful, streamlined operations tools, infusing both domains with solid guardrails for operational control and predictability. Adopting this approach will greatly increase time-to-value for enterprises, putting innovative digital solutions directly into the hands of end-users with the click of a mouse.

  • Continuous Testing: The Quest for Quality at Speed

    Continuous Testing: The Quest for Quality at Speed

    The DevOps goal to reduce lead times by accelerating software deliveries presents a serious challenge for assuring the quality of the software that is delivered. As I indicated In my SlideShare post, “The Quest for Quality at Speed,” testing activities span end-to-end software value streams and often account for more than 50% of bottlenecks.

    The answer to these DevOps testing challenges is referred to as continuous testing (CT), which is more than simply automating tests. My blueprint for continuous testing identifies eight pillars of practices, each with strategies to reduce bottlenecks. In this article, I enumerate the strategies for each of the eight pillars of continuous testing and explain how to approach implementation for greater adoption of CT across an organization.

    Continuous Testing Pillars

    Continuous Testing Tenets

    There are five tenets which are guiding principles that enable continuous testing:
    • Shift Left: Conduct each test as early in the pipeline as possible.
    • Fail Early: Arrange the tests so the most likely problems are found during the earliest possible stage in the DevOps pipeline.
    • Fail Often: Run tests frequently and with many different conditions.
    • Test Fast: Arrange tests to run in quick cycles.
    • Be Relevant: Focus on the most important tests and results.

    Leadership and Culture

    Leadership and culture practices have a major impact on influencing behaviors and habits of everyone involved in testing across the DevOps value stream. Bottlenecks to CT include inadequate funding of testing due to lack of quality vision and goals at the executive level, and bottlenecks caused by distrust and lack of cooperation between Dev, QA and Ops. Executive sponsors need to clarify the definition of quality for the organization, and emphasize quality’s importance. Executives can communicate the vision and goals for quality and establish incentives that foster a culture of collaborative behavior.

    Test Strategies and Plans

    Test strategies and plans are needed to guide testing approaches for each product/service pipeline. Bottlenecks to CT include confusion caused by lack of product/service test strategies, and unplanned testing activities and resources are not included sufficiently in planning process. It is important to establish test coverage standards, test case standards, gate criterion and planning process that include testing requirements. CT strategies include making sure test coverage requirements are defined, all types of tests required are identified, allocate tests that are required at input gates, indicate test results are required at output gates and enforce that test tasks are included in planning backlogs and sprints.

    Test Management

    Test management is needed to coordinate testing resources and test schedules. Bottlenecks to CT include poor utilization of test resources due to lack of visibility and schedule bottlenecks due to lack of coordination of test schedules. It is important to have a database of tests and test resources, and test scheduling tools. CT strategies include version management of tests and resources, an inventory of test resources and dynamic test scheduling.

    Test Automation

    Designing, creating, selecting and executing tests in an automated fashion to get to a verdict as fast as possible is the primary strategy to accelerate testing. Bottlenecks to CT include slow test creation, slow test execution and slow time to realize verdicts. It is important to have effective automation strategies for test design, test creation, test selection, and test execution. CT strategies include test design templates, advanced test creation tools (E.g., TDD, keyword, behavior, model-based), dynamic test selection, tests designed for fast verdicts and horizontal and vertical scaling tests.

    Test Tools

    Test tools are designed to automate specific types of tests and integrate with DevOps platforms through APIs for orchestration, execution and reporting. Bottlenecks to CT include test tools that are not designed to scale, limited test configurations and lack of complete APIs, which make integration with DevOps platforms inefficient and error-prone. It is important to have scalable test tools with good APIs. CT strategies include limiting the selection of test tools to ones that are DevOps-ready or DevOps-native and that have well-defined, stable APIs.

    Test Environment Management

    Scheduling and setting up resources into the needed topologies for running different types of tests for developers and testers can be a major bottleneck if not managed efficiently. Bottlenecks to CT include lack of test resource scheduling, which causes conflicts for resources, manual test setups, which are time consuming, causing long wait times for testing and delayed retesting. It is important to have test resources scheduling, test environment orchestration and resource utilization management. CT strategies include test environment inventory tools, test environment sharing tools, test environment orchestration tools and monitoring test environment utilization.

    Test Results Analysis

    Reporting and analyzing test results can be a major bottleneck after test execution is completed. Bottlenecks to CT include poorly written tests which can report confusing results and that take a lot of time to analyze. It is important to have design standards for test results and test results reporting standards. CT strategies include test verdict design in test cases, common test reporting tools and test analysis tools.

    Steps To Implement Continuous Testing

    Start with one or two services and a small set of critical CT practices, then expand to more services and more advanced CT practices.

    A gap assessment is a great way to determine the current state of CT practices, and will help focus the implementation plan. Given a list of practices from each of the pillars in the continuous test blueprint, a cross-functional team of developers, testers and ops people can assign scores to measure importance and current level of practice to generate a gap score. The combined set of gap scores will give guide and direct current priorities for the CT plan.

    For example, beginning CT priorities could be to establish a strategy sponsor, define quality goals, obtain an inventory of test resources and requirements, put in place version management for tests and test standards, tool selection and test refactoring to match the standards.

    An intermediate CT goal could be to complete tool integrations with DevOps platforms, automate test scheduling, orchestrate test environments and optimize test results reporting.

    With maturity, advanced CT goals could be to put in place advanced test creation strategies, accelerated test execution, automated test environment management and optimize test results analysis.

    What This Means

    Testing activities are typically a major source of bottlenecks that slow the quest for quality at speed. Continuous test strategies that accelerate all aspects of testing can have a major impact on speeding up lead time for continuous delivery of quality software. Implementation strategies that start by applying specific continuous test strategies to a targeted small number of applications, and then expand to more advanced strategies applied to more applications is an effective approach to CT adoption across the organization.

  • Survey Sees Application Testing Shifting Further Left

    Survey Sees Application Testing Shifting Further Left

    PractiTest, a test management platform provider, published a report today that suggests professional application testers have become more adept at working within DevOps workflows.

    The annual survey of more than 1,000 application testing professionals finds that 80% of all application testing within organizations is being done by test engineers, test leads, testers and automation testers. A full 92% of survey respondents also noted they are working within the context of an agile methodology, while 42% cited DevOps specifically. Half of respondents said they work within the framework of a continuous integration/continuous delivery (CI/CD) platform.

    Significantly, more than half of respondents (59%) said testing is shifting left within their organization, but only a third (33%) said programmers participate in the testing process.

    PractiTest CEO Yaniv Iny said that level of DevOps inclusion suggests that, rather than shifting testing completely left on to the shoulders of application developers, a more nuanced approach to application testing is taking hold as professional testers learn to work within the sprints that make up a DevOps workflow. A full 90% of respondents said testing has become more automated within their quality assurance (QA) processes.

    By now, most application testers have come to terms with automation and, increasingly, AI, said Iny. The assumption now is that large swaths of the testing process will be automated, Iny added. A full 97% of respondents said that functional testing automation was either important or very important for them to succeed, while 96% said test automation patterns, principles and practices are also critical.

    Usage of behavior-driven development (BDD) as a testing model has also increased, with 27% of organizations now employing it to go beyond simply testing functions.

    However, the survey also found that, instead of automation decreasing the size of testing teams, those teams are getting larger. The number of organizations with 16 or more testers increased by 10% to 34% compared to a year ago. That suggests organizations are launching either more complex application development projects or launching multiple projects at the same time as they embrace digital business transformation initiatives, Iny said.

    The survey found nearly 70% of respondents have at least five years of experience. Nearly three-quarters (71%) of respondents reported that their income was not affected by the economic downturn brought on by the COVID-19 pandemic. However, nearly half of respondents (54%) reported that they were concerned about job stability, an increase of more than 30% from a year ago.

    The pandemic did change the way testers acquire new skills. The number of testers reporting that they attended online conferences, meetups and seminars increased to just under half (49.5%), up from 40.5% in 2019. Participation in online communities and forums grew to 44%, while only a third of respondents receiving any kind of formal training.

    Testing professionals with five to 10 years of experience earned an average salary of $89,000 in North America, which compares to $76,000 in Australia/New Zealand, the survey also found.

    Application testing as a distinct discipline doesn’t appear to be fading away anytime soon. Rather, organizations appear to be investing even more in testing to deliver higher-quality applications.

  • Low-Code and DevOps: Friends or Foes?

    Low-Code and DevOps: Friends or Foes?

    What does low-code mean, and who is it really for?

    Over the last few years, I’ve seen many articles associating “low-code” with “citizen developers” or with people who don’t have deep development skills. Users can arrange visual elements, or fill in forms with key information and publish the result as an application.

    But tools for citizen developers are only one part of the low-code story. There is also a growing number of tools for professional developers, and I want to talk about those, too.

    Both citizen developers and professional developers have a role to play in application development and automation projects, and low-code has something to offer both of them.

    Low-code is Not a Market, it’s an Approach

    Low-code does mean providing visual and graphical tools and simple frameworks that mask more complex coded operations, so the application designer does not have to directly touch the code that performs desired operations. These apps are naturally limited, as the resulting application can’t be highly customized if you can’t touch the code.

    With these kinds of visual tools, anyone can create a simple application within the limits of the tool. But when we pull back and look at what is needed to create larger, more complex applications – ones that need to communicate with other enterprise systems, or need extensive customization, or cross organizational boundaries, or need to pay attention to governance requirements, for example – the visual-only approach is frequently insufficient. In complex cases, developer expertise is often needed, and developers have to get “under the hood” to tinker with code.

    There is no “low-code market.” We are bringing tools to people who need them to develop specific projects. A comprehensive low-code approach to application development and automation means offering both visual programming and coding capability. For usability reasons, these tools are clearly separated and presented to the development team in a way that allows citizen developers to work on certain elements and developers to work on others, all on the same platform.

    We know that it’s possible to serve professional developers with low-code, too. A low-code approach also includes drag-and-drop tools that developers can use – for example, to develop APIs, or to integrate the application with other systems, or to customize front-end interfaces. Of course, when code is required, developers should be able to use their own tools and frameworks and not be limited by low-code tools. Platforms that offer a hybrid approach are likely to be most useful to mixed-skills development teams.

    The Hybrid Approach

    Strictly low-code tools can serve simple automation use cases. More broadly, automation platforms offer a hybrid of low-code and coding capabilities for more complex automation use cases.

    For critical enterprise applications, both business and developer inputs are usually needed. Having tools for both of them means not leaving anyone out.

    Low-code tools will continue to become more mainstream. Low-code is not a fad or a passing trend, but a quiet revolution that will see greater incorporation into more business tools.

    Here Come the Digital Natives!

    More vendors are offering low-code tools for digital process automation, business intelligence, robotic process automation, identity management and data integration, to name just a few.

    As automation platforms and other low-code tools mature, a greater number of people are getting used to working with them. Developers are less hesitant about incorporating non-developers into their teams, as everyone gains a better understanding of the benefits of these platforms.

    The younger generations entering the workplace today are digital natives. They are fearless about diving into technology and working hands-on. So, these low-code tools are ready for them, and they are ready to put them to work.

    Low-code is breaking down technical barriers to work in the automation space, making smooth collaboration between business and development easier.

    Low-Code Can Be a Double-Edged Sword

    Automation and development teams are also becoming more aware of vulnerabilities and compliance issues as citizen developers roll up their sleeves and join the technical team.

    Low-code tools are a double-edged sword. They facilitate teamwork, but issues with security and data governance may not be top-of-mind for non-developers. If you have a big team working on automation and/or application development and delivery, the need to build in governance becomes even more important.

    Using a shared platform will help manage and mitigate these issues with security and governance. This will become even easier as the platform tools evolve and mature, so DevOps teams can use them to help mitigate some of these issues.

    Does Low-Code Have a Place in DevOps?

    We are definitely seeing the impact of low-code on development environments and DevOps. Remember, low-code started with small applications, and while DevOps-style teamwork and workflows may not be needed there, as the use of low-code platforms becomes the norm for critical enterprise projects, DevOps will be a necessary part of the mix. This is where low-code is having a more obvious impact; Agile methodologies using low code platforms for iteration, for continuous improvement and for continuous delivery. These applications aren’t one-and-done. They need to be maintained, improved and delivered, again and again.

    Low code isn’t going away. On the contrary – it’s going everywhere.

  • 4 Ways to Overcome Agile Transformation Obstacles

    4 Ways to Overcome Agile Transformation Obstacles

    If an organization desires a successful Agile transformation, the first step is to shift its thinking from ‘doing Agile’ to ‘being agile.’ Unfortunately, a commonly shared belief that Agile is just a software development methodology keeps too many companies stuck in the ‘doing Agile’ mindset.

    This belief ties back to the principles of Agile thinking from frameworks like Scrum or Lean. Most of these methodologies were focused on teams of developers. Naturally, the vocabulary and tools derived from these methods are unique to software development. While development has evolved away from waterfall approaches, the rest of the organization tends to run into cultural challenges downstream because the vocabulary and ways of working are foreign.

    When an organization begins to lose progress downstream, it is too focused ‘doing Agile’ rather than ‘being agile.’ In order to shift the mindset toward ‘being agile,’ a new mindset must be adopted across the organization. These four insights offer ways to overcome obstacles along the way:

    Instill Agile Thinking Across the Organization

    The first step toward instilling agile thinking is to establish common vocabulary and define what it means to be agile. A common vocabulary and understanding of agility helps teams across the organization understand and see that agility is more than doing sprints.

    As an organizational strategy, agility equates to flexibility – the ability to adapt to changing business requirements. It also means being collaborative and making complex processes more lightweight. Instilling this type of agile thinking into everyone at the organization leads to success. DevOps, for example, successfully instills this type of thinking through value stream management.

    Essentially, this hurdle boils down to setting common goals and creating a common understanding of what ‘agile’ means across the organization.

    Achieve Autonomy Through Self-Organization

    Agile frameworks encourage self-organization. When teams self-organize they are given a task to do. However, no one tells them how they’re going to accomplish it. A self-organizing team gains a certain amount of autonomy, which leads to empowerment.

    With self-organization also comes risk. The organization must learn how to embrace risk, how to look at failure as an opportunity to improve and how to empower teams in a more self-regulating way. When teams self-regulate and self-organize, it’s a team win when they are successful. This develops a sense of communal pride.

    When breaches or too many failures do happen in a self-regulating system, the policies and consequences naturally occur. However, the key differentiator is that these environments are not driven by the policies. Rather, the objectives drive the behavior. When objectives are being met, empowerment stands.

    Agile software development, DevOps and site reliability engineering (SRE) are intended to be self-regulating systems, but all first require leadership to create psychologically safe environments, blameless postmortems and more. There is no room for a blame culture in a self-regulating system, and the organization must be agile enough to meet the demands of the system.

    Leverage Intelligent Lightweight Process

    Agility does not equate to a complete absence of process. It means there is enough process in place to ensure consistency, improve flow between people and teams and that automation replicates the process simply and effectively.

    IT organizations must understand that it is possible to move away from complex and authority-based processes and continue to leverage an element of process.

    Intelligent Process Means Intelligent Automation

    Although humans are the driving force behind agility, automation helps them go faster with more consistency. However, there is no such thing as ‘being agile’ with automation alone. Agile cannot be bought, and it’s important to get teams thinking that way. Automation should complement Agile, but not define it.

    When investing in automation, a cost/benefit analysis is critical. When considering automation, think in terms of two key metrics: time and quality. With two equally important metrics, the organization cannot become dependent on one aspect or another.

    For example, you can’t go faster with a manual process. You also can’t go faster with only automation, because the automation alone doesn’t replicate your intelligent lightweight process. And, you can’t go faster just by having a process, because the process can become very bureaucratic.

    Process is just a means of getting there, but it needs people and automation to make the processes come alive. People, process and automation all play an essential role in creating an intelligent process.

    Successful Agile transformation is more a way of thinking and behaving than simply following a framework. From a human perspective, an organization that experiences true agility, as we’ve defined it today, allows humans to exercise their competencies, grow skills, collaboratively celebrate success and learn from failures.

    If you’d like to learn more about Agile Transformation, especially in regards to Agile Testing, you can register for the next SKILup Day on April 22. Please register for SKILup Day: Agile Test Management for the Enterprise here.

  • How lulu Became a Lemon: A Digital Transformation Fail

    How lulu Became a Lemon: A Digital Transformation Fail

    Many people sometimes have a tough time figuring out what exactly digital transformation is and why it’s so important. I want to tell you a real-life story of how a once-respected brand, lululemon, has failed the digital transformation journey and, as a result, may fail in a new retail landscape.

    The story starts innocently enough with my desire to get my wife a lululemon gift card for her birthday. She has gotten her vaccines and is returning to the gym, so I figured it was a great time to get new workout clothes. I purchased a gift card on March 15 to be delivered via email a few weeks later on her birthday. It was a simple digital transaction that for any company that has its digital transformation act together would be a no-brainer. Well, this is where lulu turns off the tracks and turns into a digital lemon.

    On the day of my wife’s birthday, I had planned that she would wake up and see how thoughtful I was in getting her the gift card. She didn’t say anything about the card, though, so I finally asked if she received the gift card. She didn’t know what I was talking about. I had her check her spam folder, nothing. Nope, no gift card.

    Thus began a day that would see me reach out and communicate with the lulu team no fewer than six times. It seems that lulu uses a third party for digital gift cards. Each time I reached out to a lululemon “educator” (that is what they call them, and did I get an education), I was told a different story:

    1.  A simple apology and card being emailed, give it an hour.
    2. Sorry, it must be that email address, do you have another email address? Give it an hour.
    3. Hmm, seems our third-party gift card provider is having problems today.
    4. We located your card, it was sent to: tlaynguyen@gmail.com  could I check that email? (I would love to, but that isn’t an email address I have.)
    5. Well, we have no control over when the third party sends emails.
    6. Digital gift cards are non-refundable, even if you didn’t receive it. Sorry, can’t help you.
    7. You have blocked our emails from your computer.

    At this point I realized that lululemon, while maybe making great workout gear, is analog to the core. A simple digital transaction like this had them tied in knots, wasted hours of my time and so turned off my wife that she is looking elsewhere for her new workout gear.

    This past year has taught us that retailers that can’t hop on the digital transformation train are heading for the precipice. It seems as though lululemon may have already gone over the deep end. The company better hope the malls fill up quickly because in a digital world, lulu is truly a lemon.

  • The Single-Sentence Postmortem

    The Single-Sentence Postmortem

    Do you have four seconds?  In the time it takes you to read this sentence you could be done with your incident’s postmortem.

    “But my postmortem has 8 sections!  I have to construct a critical timeline, restate my followup tasks, show the major milestones, evaluate root cause…”

    Stop right there.

    First of all, your incident management system should be automatically capturing your timeline, follow-up tasks and major milestones as they happen — so you shouldn’t be worrying about reproducing that content at all.

    Second of all, the most critical thing a responder can bring to a postmortem, in the moments right after the incident concludes, is the one-sentence personal context of what actually happened. It’s the same sentence they’d say to a co-worker in the lunch room when asked what went wrong. But to achieve organizational resilience, the knowledge in that sentence has to be captured and distributed. I can’t emphasize this enough – a single sentence can unlock 80% of the value. Writing something, anything, is so much better than writing nothing, and yet, too often, we see companies skip this part of the incident management process.

    Modern incident management, as a practice, was born on factory floors.  Instead of firing the person who was considered accountable for a major incident, having that person write up their view of what happened was more impactful at preventing future incidents. That’s because only the responder has the complete context to shed light on the contextual, systemic failures that actually caused incidents, as compared to the outside view of management and other employees who will often see problems as human-centered or due to obvious oversights (using 20/20 hindsight).

    When asked if he would fire an employee who made a $600,000 mistake at IBM, Thomas J. Watson famously replied, “No! I just spent $600,000 training him – why would I want somebody to hire his experience?”

    The reality is that any amount of your unique perspective as a responder is invaluable when compared to nothing, and without it, the chances of your company learning from these mistakes is slim. That’s why we encourage a unique approach: we tell our customers to spend four seconds on their postmortem.

    Especially for those new to incident response and management practices, it’s important to develop a practice of doing postmortems right away, as soon as the incident closes. As quickly as possible, open up your postmortem, jump to the ‘What Happened?’ section, and write one useful sentence. That’s it.

    Once you do that, we know that one of two things will happen:

    1) You’ll have other things to do, so you’ll publish the postmortem, and that one critical piece of knowledge will be shared throughout the company. That is infinitely better than nothing. 

    2) Or, you’ll realize you have more to say and get it done, right then and there.

    Like putting your running shoes on even if you don’t want to go for a run — at the very least, you’re up and active; at most, you’ll get out there and rack up some miles.

    Working with companies across industries and seeing thousands of incidents filed; hearing the stories of hundreds of companies’ incident management implementations has taught us that the alternative to a quick postmortem often isn’t often a more in-depth one, it’s no postmortem at all.

    So if you’ve just finished an incident– and if you’re about to pick up your coffee and move on to the next task at hand – instead, spend four seconds writing one sentence. It could make all the difference.

  • Languages and DevOps: Network

    Languages and DevOps: Network

    It is fun to discuss the changes in network operations over the last couple decades. We’ve come full circle, and, honestly, ended up in a better place. Network specialists were super command-line wizards who kept us going, with few GUIs in sight. Everyone thought the next iteration would be GUIs, so network operations could be accessible to more than a few command-line specialists. “Everyone” was mostly right; we did head in that direction. It was optional, and many network operations friends pointed out that you could still do more, faster with the command line. Before GUIs had the opportunity to catch up with command lines, though, automation came along. And then DevOps. And finally,* configuration-as-code. Pretty quickly, the ability to do everything through an individual product’s GUI was determined to be a weakness. Network operations personnel were dealing with more vendors to handle the networkification (it is too a word! I just made it up) of common development activities, like some aspects of security. And now, APIs and command lines rule the juncture of DevOps and networking.

    *Finally – so far, at least

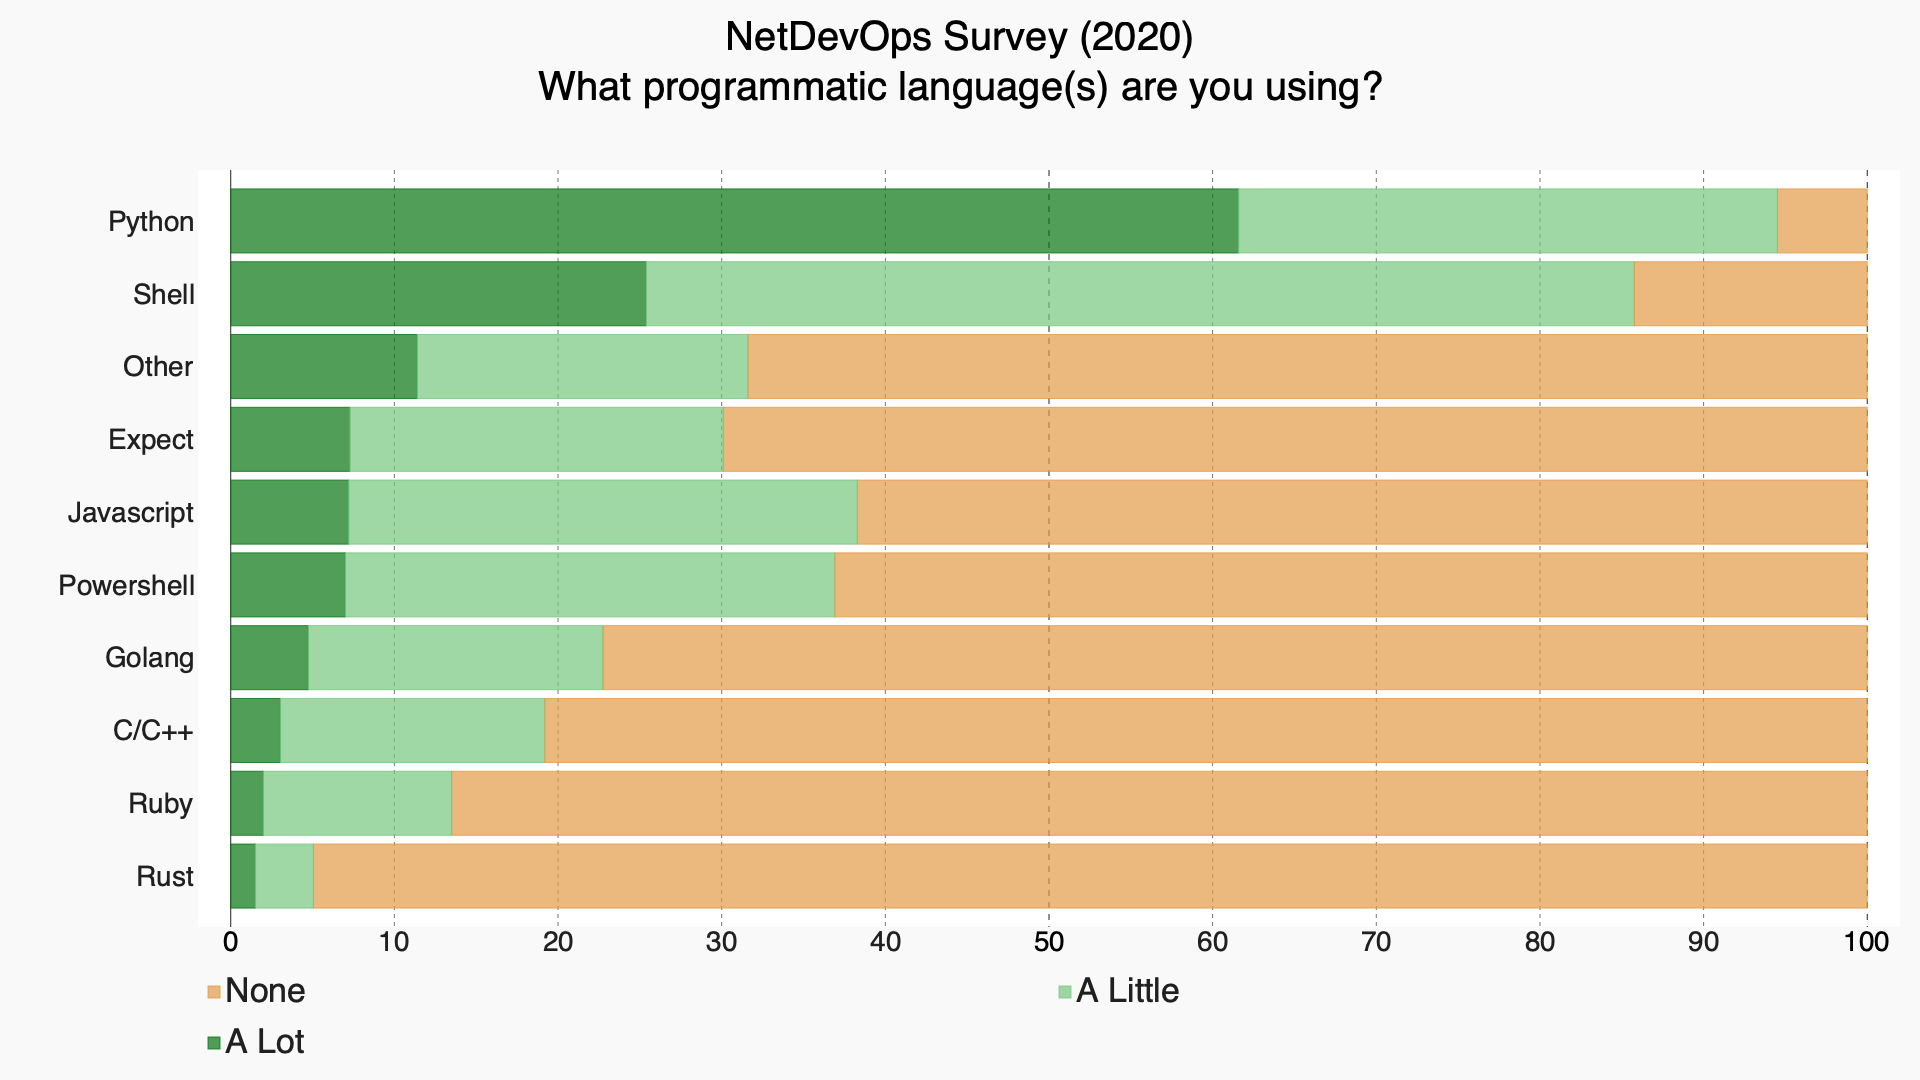
    And that shows in languages. Shell scripting and Python run this show, with little competition from any other language. We could get into a massive discussion about whether shell scripting is programming, but we won’t, because at least in networking, it most definitely is considered to be programming.

    One time, when we were tracking down a problem that involved all of IT, I was sitting with the serious network geeks and marveling at their ability to make everything they wanted happen from the command line in an instant, and their ability to parse command output. I’m no slouch when it comes to networking, but they easily put me to shame. I got to chatting with a few of them, and the consensus was that they loved computing but hated programming. Networking made sense to them. This explains why networking DevOps people are continuing to use Shell scripting and adopting Python at the same time.

    Python and Shell

    Shell is a given in networking. There are a lot of extant Shell scripts for doing all sorts of things, and the need to automate to keep up with Agile makes shell scripting a logical choice.

    Python enters the picture because it is “common ground.” It is intuitive enough for most networking people to do what they need to get done, and known or knowable to most developers. When it comes to usage, Python has overtaken Shell; (don’t take my word for it, check out the excellent work of the NetDevOps survey on GitHub, or just glance at the graphic below, created by them) in fact, Shell and Python command so much of the network development space that you are probably better off just making sure you’ve got those down, and focusing your free time on other issues like completely different networking commands, or even skills for data center versus cloud. The ROI would be better.

    But Wait, There’s More

    The key operational changes recently have been around GitOps and reporting back into the DevOps toolchain. People no longer want your appliance or application to have a pretty GUI, they want it to report in to the tools that provide automation and a larger-picture GUI. Many vendors are there already, but many are not yet. That creates a need for tools – products, open source projects, or internally developed – to do that integration while waiting for the vendors to catch up. These, again, are well-served by Python, though other languages that can handle APIs are viable, too.

    We’re headed for a world where systems detect anomalies and react to rectify them, but we’re not there yet – not on a strategic scale, at least. And we probably won’t be for some time, as automating massive network changes is a scary proposition and will take time to use these systems for detection, monitoring what they could have done, before organizations are willing to let them “just do it.”

    Carry On

    Meanwhile, NetDevOps is getting folded into DevOps proper, and in many organizations, using infrastructure-as-code or GitOps, is being deployed and managed like any other part of the life cycle. So we are moving along. For my network peeps, your job will continue to change, but it certainly won’t go away. You’re essential to smooth-running systems, and while the network may become even more virtual, it will still be networking. And under that virtual network will be … a physical network. So keep kicking it, and carving a path from users to apps, while protecting those apps and ensuring they have adequate resources. Oh, and if I spin up another instance at midnight, you’ll hop on and make sure it’s got traffic directed to it, right? RIGHT?!

  • DevOps Skills Increasing Among Salesforce Developers

    DevOps Skills Increasing Among Salesforce Developers

    A survey of 521 attendees at a recent online Future of Salesforce DevOps Summit event hosted by Gearset, a provider of a continuous integration/continuous delivery (CI/CD) platform for Salesforce developers, found just under half (47%) of respondents now release software at least multiple times a week, with another 29% releasing software weekly or biweekly.

    More than half of respondents (52%) also noted they now can deploy software in less than an hour.

    Gearset CEO Kevin Boyle said the survey suggested the level of DevOps maturity among developers building applications on top of the Salesforce software-as-a-service (SaaS) platform is increasing rapidly. In the wake of the COVID-19 pandemic, many organizations embraced SaaS platforms to accelerate their digital business transformation initiatives rather than building entire applications from scratch.

    However, the biggest benefit cited by survey respondents was not the ability to release applications faster, but rather the improvements to application quality (77%), followed by increased productivity (69%) and enhanced collaboration (46%). Other benefits cited included reduced complexity thanks to automation; increased agility; more reliable releases and time and cost savings.

    Overall, the survey identifies source code control, CI/CD, unit testing, change monitoring and backups of metadata and data as being the most widely implemented DevOps capabilities that have been adopted. Over the next 12 months, capabilities that will see the most increased adoption among survey respondents include CI/CD, static code analysis and sandbox seeding with data.

    Survey respondents said their top obstacles to adoption of DevOps are ramp-up time, followed by difficulties adopting source control and a perceived steep learning curve. For many organizations that have adopted Salesforce, the intimidation factor when it comes to adopting DevOps best practices is still fairly high, Boyle noted.

    Most recently, Gearset added a free training platform, dubbed DevOps Launchpad, that employs gamification techniques to make DevOps more accessible to developers. Topics covered include version control fundamentals, Git branching strategies and Salesforce backups.

    Gearset counts McKesson, Zillow, Traction on Demand, Intercom, Accenture, IBM and Johnson & Johnson among its customers. It’s not clear to what degree appreciation for DevOps has risen among smaller companies. However, as the number of custom applications deployed as extensions to the Salesforce platform increases, it is apparent that manual processes for building and deploying applications will not scale. The Salesforce platform itself is uniquely constructed using a set of objects and tables that generally lead organizations to adopt a DevOps platform built for that environment. However, it is possible to build and deploy applications using a DevOps platform designed for building and deploying applications that might need to span multiple platforms. Those applications would be integrated with the Salesforce platform at an application programming interface (API) level.

    Regardless of how custom applications are built and deployed, it’s clear Salesforce platforms are becoming more widely used in enterprise IT environments. Each DevOps team will need to determine how best to integrate those platforms within the context of their overall DevOps strategy.