How much time do you spend optimizing your delivery pipeline? My guess is none. Many teams have figured out great ways to automate their releases, and some even automate testing and monitoring. But they don’t often take the next step and learn from those results to refine the delivery processes.
Category: Doin’ DevOps
-

Who’s side are you on anyway? DevOps Culture
Shame on you! Yes you, because there is a good chance you are thinking about DevOps all wrong. If you are a developer you might be thinking DevOps means IT goes away and you control all the infrastructure. If you are from IT you are thinking that DevOps is just automating what you already do, more. You’re like a seagull from “Finding Nemo”, trying to claim ownership of this DevOps thing. “Mine!”. And both of you are wrong.
-
The Double-Edged DevOps Job Title
Last month at GWO in Atlanta I met Nathen Harvey with Chef. I liked his DevOps presentation, “DevOp With Me!”, especially how he used “Walk This Way” by Run DMC and Aerosmith as an example for how collaboration in a DevOps environment often ends up playing out. They literally break down walls in the music video.
While not all of Nathen’s presentations are safe for work ( many include some explicit language. It’s safe to assume so unless clearly labeled otherwise) they are all entertaining and informative. I’d encourage you to check his stuff out, especially if you’d like to know more about how and why Chef and DevOps mix well.
I asked Nathen if he minded me linking his deck and giving him a shout out in a blog post. I even promised to say nice things about him. The answer he gave me only reconfirmed he does really get it:
Of course! (even if it’s not all nice things, as long as they’re honest)
If I’m being completely honest I have to admit this changed the topic of this blog post. I liked the idea of setting devOps to music so much I was going to post a DevOps playlist. I may still write or talk about that another time. It ended up being pretty easy to think of other songs that would fit for one reason or another. It actually even makes for a decent drinking game in the right crowd.
Instead I’m going to talk about the one thing I know Nathen and I don’t see eye to eye on. Nathen’s an advocate for doing away with using the word “DevOps” to describe a role or a team. I, being a DevOps Engineer, strongly disagree with this perspective. When I asked Nathen about this he responded with a single question:
Can you describe what you do without using the word DevOps?
It’s true there are a lot of folks with the word DevOps in their title that are adequately described as a systems administrator or a build automation engineer. Coming up with job titles that don’t contain the word DevOps is also a decent drinking game in the right company. A good serious answer for me would be ombudsman or public advocate. I think KTLO (keep the lights on) custodian would also accurately describe how I’m earning a large part of my keep these days. Still, the job I interviewed for was DevOps Engineer, and for now I’m going to keep using those words to describe what I do. I like Nathen’s Socratic response to why we shouldn’t be describing people and teams with the word DevOps, but what I am doing isn’t accurately described by other job titles where I work. If another title is a better fit for the work you do where you’re at, then I would encourage you to take Nathen’s advice.
The more common reason I’m given as to why I should have changed my job title on day one is really pretty disappointing. I’ve read more than once that I should be concerned that my head will be the first one on a pike should the devOps movement fail. This really isn’t a concern I have.
First of all, DevOps does work. I’m not sure who would dispute that the CAMS model for DevOps is made of things any organization should be trying to improve Kaizen style. I’d even say that improving Culture, Automation, Measurement, and Sharing together results in a sum that is greater than any of its parts.
There are however places that aren’t ready to embrace the change needed for this type of improvement. I caught a quote from @filler when @RealGeneKim retweeted it last November:
If you’re concerned about a lack of progress in echo chamber, go offer yourself up in a different forum. And bring cookies.
Advice I took quite literally. I found a job with a DevOps title at a place that was actively trying to change. I regularly bring in food. Just this past week I baked six dozen toll house cookies from scratch for a DevOps round table meeting I hosted. Why? Because I genuinely give a damn. I want people to come to that meeting to listen and to share. People who are passionate about technology and have faith that there’s always a better path. This group should find such a round table conversation quite enjoyable. The cookies help us remember this is supposed to be fun. They help keep the mood collaborative instead of conflicting. Such a job shouldn’t be left to baked goods that have been sitting on a shelf for weeks. If I want the best from the people I’m working with then I should give them my best whenever I can. It’s often the smaller details that could be neglected or ignored without issue that are noticed and have a more lasting impact.
Some of you right now are in an environment where the bigger details that are making life difficult for everyone are actively being ignored. You may have been told not to worry about them or that the real solution is for everyone to work weekends. This is garbage and you know it. Please do not change your title to something safe and hide under your desk while in the office. Be the change you want to see in the world. There are lots of opportunities to help organizations make this transition. Find one that’s a good fit for you and make the jump.
My advice for businesses is to be very careful when you describe a position as a DevOps role. We know this to be a very specific thing, but if you’re simply shoving the word DevOps into a job title in an attempt to attract talent there’s a good chance you’re in for a rude awakening. The person applying for that position knows there’s always room for improvement. They know that any transition is going to cause some friction but are willing to work through it. They’re also not scared to rock the boat. So, if your organization is not ready and willing to collaborate as one big team it won’t take too long for your devOps staff to go somewhere else on their own. Threatening their job security in an effort to maintain the status quo will only accelerate the process. You may very well end up with a lower head count at the company picnic as warned, but if it’s because all of your talent moved on to greener pastures you’ve effectively turned a bad situation into a terrible one.
If you’re a DevOp-er that has a work environment in that gray area between heaven and a coal mine I’d encourage you to push the envelope. Share your honest opinion with someone you know doesn’t agree with you. Set up a meeting to discuss conflicting perspectives diplomatically. Drop an F bomb in a conference room if it will wake the room up and get some blood pumping (use sparingly and with caution). Don’t expect people not to get upset. Instead, try really heard to shut up, listen to everything they’re trying to say and do your best to give them what they need. If DevOps is anywhere near your title then you have some responsibility in getting these conversations started. If your current employer didn’t know this when they used DevOps as an adjective then shame on them.
-
The Cloud IDE and it’s impact on DevOps
Recently I did an interview with IBMs Ken Walker. Co-lead on the Eclipse Orion Project, a cloud-based integrated development environment (IDE). My interest in Cloud IDEs peaked at the beginning of the year and has been steadily growing since the interview and being an active user of Cloud9 ( My current favorite Cloud IDE). During this time I realized the Cloud IDE has the ability to totally transform teams. We all know where the IDE belongs in the developers life, but what, if any, is the Cloud IDEs impact on the DevOps movement?
-

DevOps culture meets the SLA
The goal of every SaaS provider should be 100% availability – it should be ingrained in their culture. But it’s far more common to see a series of nines. Numerically, these are clearly not the same value and culturally, they are a world apart. When you have an availability target that is less that 100%, you are explicitly tolerating some amount of downtime. It changes the requirements, the perspective of all those involved in delivering the application to your customers. When we think of the nines, I think we invariably fall into thinking about the differences between them – especially the technical differences. But to get to 100%, you need culture. A culture that is fanatically dedicated to achieving that goal.
A review
This is tired ground, but let’s take another look at what the most common SLA measurement is and what it means. System availability is measured as a ratio of the number of minutes of actual availability over some period of time – a week, a month, a quarter, a year. We usually talk in terms of the monthly SLA for a 30 day month. 99.9% availability is 43.8 minutes of downtime per month. 99.99% is 4.32 minutes per month, and 99.999% is just 25.9 seconds per month.
What I find interesting about these numbers is the implication of trying to assure a higher SLA. You can achieve 99.9% with process and dedication. But that won’t get you to 99.99%. To achieve that, you need at least fail-over automation. To get the fifth nine, you need self-healing automation. Each of these numbers represents an order of magnitude increase in availability. Likewise, the effort and expertise required to attain that availability is greater.
What’s your relationship to the SLA?
When there is a disruption of service, the first obligation an organization has is to restore that service as quickly as possible with the least amount of risk. In mature organizations, there are typically automated and self-healing processes that provide a first line of defense for the most common types of failures. But there are always unanticipated problems that can manifest at any time. The expertise required to address those varies depending on the nature of the problem. It might require someone who primarily identifies as development, or dba or security. Everyone else attending to that problem is secondary to the key resource required to fix it. I have spent many hours feeling helpless during outage war rooms because I was not person with the specific skills required to solve the problem. When you expand this problem out, you begin to see that in order to prevent the outage from occurring again, you need that key resource to be thinking about outage/problem mitigation all the time, rather than in response to a specific incident.
Sometime, during times of trouble like this, I’ll be approached and asked what we should do to address this problem. On many occasions, my answer has been, “we need to build a system that doesn’t have outages.” After an awkward silence, the asker begins to realize that the askee is actually quite serious. And I am. The problem is that to truly attain that goal, or something reasonably close to it, you need everyone involved at all times at some level.
SLAs are meaningless
About 15 years ago, I experienced a catastrophic failure in a name brand storage array I inherited by way of employment. It was one of those managed, completely redundant, fault-tolerant arrays that consumed a considerable amount of OpEx with a 99.5% availability in the SLA. When it inevitably failed (you knew that was coming, right?) and I looked up the contract, I found that we could not claim a material breach of performance unless the availability of the storage device fell below 85%. I was stunned. My business would be dead long before 85%.
Likewise, you can have a 99.95% month, but if the tiny amount of downtime happens to impact your biggest and most demanding customer, the SLA is immaterial. They become angry and are at risk as a customer because you have failed them. What I learned as an operations executive is that the commitment behind the SLA is far more important than the SLA itself. Put another way, you can make bad situations into positive ones if you handle them exceptionally well every time. That means ruthless dedication to uptime from everyone in the company, from rank-and-file individual contributors to the CEO, all the time, not just during the incident. If that really is a goal – and it’s infused into the culture of the company – everyone you interact with will see it and understand that commitment.
There’s another artifact of SLAs that can be detrimental. When the focus is on the availability number, the target is too low. The goal of every SaaS provider should be 100% uptime. When your goal is 99.9%, you effectively have a budget of downtime that you can draw from while still exceeding your goal. Here’s an example from my own experience. I once had a service that required periodic downtime for maintenance. One month, I had incurred 30 minutes of downtime via an unplanned incident against that service – a service with a 99.9% SLA. We also had a software update planned for that month that was going to require 20 minutes of downtime. I had the update moved to the following month so that it wouldn’t blow the SLA for the current month. It didn’t make much sense at the time and didn’t feel very customer-centric either, but as Dr. Eliyahu M. Goldratt wrote in The Goal, “Tell me how you will measure me and I will tell you how I will behave.” I had a chance to hit the SLA for that month, so I did everything I could to hit it. Given that I deferred a software update that would have delivered new features to my customers, the choice I made seemed arbitrary and was counter to being a customer-focused organization.
It takes a culture
One truly exciting thing about the DevOps movement is that it advocates the spread of knowledge throughout the organization. From my selfish operations perspective, that means that individuals who formerly would only be contacted in the event of dire emergency now have a much more visceral connection to the availability and performance of their services. By being exposed to the operations experience, those formerly external parties now see challenges and problems. And most people in our industry love a good challenge. What I get from this exchange is the injection of new perspectives and a diverse and healthy debate about subjects that have long since been worn out living only in the realm of operations. To have the attention of that level and breadth of expertise is a fantastic opportunity for me to evangelize availability and performance. More importantly, if all that talent is super motivated to achieve 100% uptime, performance and availability are going to follow. Anything less is a compromise and I don’t want to compromise on behalf of my customers. I want them delighted 100% of the time.
-
Meet Infrastructure as Code
Maybe you have already heard the terms “Programmable Infrastructure” and “Infrastructure as code”. But even if you have not, if you are interested in DevOps it’s something you need to know. Most new lingo causes me to roll my eyes. But in this case, it’s not just new lingo, it’s an entirely new concept. Besides making the nerdy feel cool when they say it, these terms describe a new idea of what an application consists of. (more…)
-

An outage war room primer
One aspect of the DevOps movement I’ve seen adopted at numerous companies is the idea that everyone supports their products by being on-call for any incidents that occur in the production environment. This responsibility often leads to participation in the outage war room. For those of you who may be new to this experience, I’m offering this primer from a grey-hair ops guy who’s served countless hours in every manner of war room you could imagine, some that stretch the bounds of that imagination, and a few that I just still can’t talk about. Been there. Done that. Still doing it.
In all that time, however, I’ve observed four distinct war room dynamics that can cause conflict. Understanding how that conflict arises is key to mitigating it.
The war room is a stressful place
This statement sounds obvious, but it’s fundamental to understanding the tensions that can arise in a war room. The clock is ticking. In fact, the clock has already been ticking for some time when you join the room. These things don’t happen instantaneously. When you get the call to join a war room, the problem has already manifested and is causing an impact. Even with automation, it takes time to notify people and have them connect to the war room, in whatever form that takes. In environments with a very high SLA target, the set up time for the war room alone can exceed the monthly allowance for downtime. So once you get into the war room, it’s serious business. The clock keeps ticking.
The war room is often a stressful place as a result. Tensions, and even tempers, can run high. But each and every person in the war room has an obligation to keep themselves under control. Tension and stress feed on each other, and if you succumb, it makes it worse for everyone. Even more important, if you get angry, emotional, or display some other decidedly not cool way of coping with the situation, you are likely to lose the confidence of your peers. That really sucks, so it’s important to force yourself to project calm confidence and be deliberate and measured in your actions. If you have the opportunity (and the ability) and can help to disperse some of that tension, do it. Those are the kinds of moments that build credibility.
And there is another very personal connection to the outage that can be stressful. A professional, worst-case scenario. In the worst case, you are actually responsible for the whole mess. When that happens, you are going to be in your own special hell in the war room. But you should know exactly what is expected of you – the one thing you can do that will really make a difference. You need to tell everyone exactly what you did, without skipping anything, and without regard to how stupid it might sound in hindsight. As in, “I continued to run through all the commands in the procedure even though they were failing with errors and even though I had guidance to stop and seek help if they failed.” To help prop you up in this most difficult of tasks, consider this: everyone else in the room has done the same thing. We’ve all been there. If we haven’t, it’s probably just a matter of time. So you have to swallow your pride, tell the whole story and then get actively involved in fixing things, because that’s what the war room is all about.
The goal of the war room is to restore service as quickly as possible
A war room is bad. If you are in one, it probably means that your customers are impacted. You have an obligation, working with the rest of the team, to recover the service in the most effective and least risky way. In a perfect world, that method is also fast, but life doesn’t always work out that way. If there is no obvious and simple solution, though, things can slow down a bit and we see different approaches forming across groups of people in the war room. Some, traditionally the operations staff, want a way to restore service quickly by a reboot, reset or other “big red button” kind of operation. Others feel it’s important to fully understand the nature of the problem before taking action. These are clearly often opposing goals.
One way this manifests in war rooms is when, in order to further analyze the problem, someone asks to run some experiments, or capture data, or otherwise use the production environment to debug the problem. If there is no method available to recover service with a reasonable level of risk, such experiments may be justified. Otherwise, the team has an obligation to execute whatever procedure they have to bring the system back up, even if that destroys information that might be helpful to the root cause investigation.
Another thing I see happen frequently is when the someone jumps the gun in trying to fix things. It plays out like this:
Jane: Do you think we should reboot the server?
Dick: I’ll get set up for it.
Jane: I think we should do it.
Dick: Done!
Jane: Wait…
A good war room manager will easily spot and work through these kinds of conflicts. If there is such a person on your war room, listen to them and obey them. The war rooms I’ve participated in are not democracies. They are run by a strong leader who is empowered to make extremely critical decisions. It’s crucial to respect that authority in the heat of the moment rather than try to be the hero. Not so coincidentally, this is my next point.
We need solutions, not heroes
In a war room, you need to separate your ego from your idea. The war room does not need heroes. The war room needs solutions. Be advised that no matter what part of the organization you come from, your idea is probably going to go up against some alternative ideas. They will not be judged, generally speaking, on how clever or elegant they are. They will be judged on how effectively they can recover the service and how much risk there is. And if yours is not the chosen idea, it does not mean that you suck. The only people who really suck in a war room are those who interfere with the process of service recovery. You know, the people who interrupt the flow of a critical conversation to ask for a status update, or who won’t stop debating a relatively minor point when the team really needs to focus on a larger issue. That kind of thing. But I digress.
Sometimes, the right path forward does not actually address the root cause of the problem.
Sometimes, the right path forward precludes ever figuring out what the root cause is.
Heroes have a hard time coping with that.
You must accept that you may never know why
The incident and problem management processes in most reasonably mature organizations are designed to recover the service, find the root cause and then ensure that it never happens again. But reality is often different than these goals. Incidents sometimes last a lot longer than you like, as when you discover that something has been broken for a long time and you did not know about it. And we should all know by this point that sometimes you never really know why it happened. You just can’t figure it out. It sucks, but again, it doesn’t mean that you suck. It means that the cost of determining the root cause has crossed the point at which it is feasible to continue, given the impact of the problem when it manifests. That’s just common business acumen, but it’s worth stating. Because when you realize that this is a possible outcome, it can give you a better perspective on evaluating your options. Suddenly, restarting the system and walking away from any run-time state information that might be helpful in root cause determination seems more viable. And those are the kinds of trade-offs that everyone in the war room has to come to terms with.
Conclusion
It sucks being called into a war room due to an outage. It is the very definition of failure in the SaaS world. But you can make a bad situation into a great and positive experience if you handle it properly. You can take an event that should mean that you suck and turn it into something that demonstrates your excellence. Being an effective member of the war room is a way for you, as an individual contributor, to demonstrate that awesomeness. You do it through calm, reasoned action and sound leadership. That builds confidence and trust. I guarantee you that your peers in the war room will notice and respect you for it and your customers will benefit from it. Let’s not let any of them down.
-

No DevOps Roadmap? No Problem.
I’m a huge fan of The Phoenix Project and I’m honored to count Gene Kim both as one of my professional inspirations and also as a personal friend. There is, however, a dangerous precipice inside of the Phoenix Project that, if misunderstood, could cause many DevOps practitioners and enterprise IT shops a daunting problem in adopting and progressing in the ways of DevOps.
Roadmap or Roadblock?
One of the main concepts discussed in both Kim’s The Phoenix Project and Goldratt’s The Goal is “the bottleneck” and what what to do about it. The basic premise explained is that all actions to increase throughput before a bottleneck, pile work up at the bottleneck and all actions to increase throughput after a bottleneck create a void of work to address after the bottleneck. The logical conclusion from this idea is that: in order to have a net positive effect on throughput, action must be taken at the, holistically viewed, tightest constraint on throughput within the operational system.
This concept model is both accurate and valuable as the IT shop and the manufacturing floor have a lot in common. The power of this concept model, also happens to be where the aforementioned dangerous precipice is revealed – getting alignment on which bottlenecks to focus on can turn into a multi-month effort in many enterprises which can require consultants, workshops, deep-dives, process studies and other activities that are at once highly valuable and not always likely to be approved by a shop that has not fully bought in to the three ways of DevOps.
One of the lesser understood secrets of corporate america is that even when you have formal authority, permission is required to do almost anything of substance. One “no” from the wrong party can kill even the most promising initiatives. This “veto effect” doesn’t require an absolute “no” either. Much like a parent saying “let me think about it”, the veto effect only requires the absence of a “yes”. This absence can take the form of “maybe”, “let me think about it”, “let’s wait and see”, or even a “run this by the other department heads and see what they think”.
Given that any reasonably sophisticated roadmap takes more than a few weeks to develop, vett and roadshow around a medium to large enterprise, a mature DevOps roadmap suffers from a classic chicken/egg paradox for many organizations. I extend my deepest sympathies to those who have found that a clear and easily understood roadmap can somehow both provide and require the catalyst to consensus and permission to proceed in the ways of DevOps. You can take heart, however, in the fact that neither you, nor DevOps, are alone in this conundrum as this is what can be referred to as “the corporate condition” that we must all bear.
While company may not always provide solace to the miserable, there is however, another way.
Just Follow the Sun
What is this one side road still available to you that has the power to relieve almost any non-alignment traffic jam? Start heading west! Just like the American pioneers, you can start following the sun to the wide open spaces of DevOps land where automation is plentiful and provable performance gains via instrumentation are gold. All you need is one or two comrades with some skills worthy of the road ahead and you can be off!
Just because you can’t get the unix team to automate environment creation, doesn’t mean you can’t head west and automate your build processes. Just because you can’t automate your entire production deployment doesn’t mean you can’t head west and automate your performance testing and benchmarking processes. Just because you can’t get everyone to agree on the tightest constraint, doesn’t mean you can’t head west and alleviate the ones you already know about. To head west on any of these things, you don’t need full concensus, you only need a traveling partner or two.
The Trail Has Already Been Marked
For mid to large size enterprises, a true DevOps transformation happens over the course of three or more years. Allowing a lack of consensus to become a total standstill is not the right answer. The tool at your disposal to overcome the veto affect is public consciousness.
Take UX design principles for example. It was less than a decade ago that design activities were considered a luxury item that produced pretty pictures; and then Apple happened and tipped public consciousness over. How many people are willing to casually veto design now?
When public consciousness to the value of DevOps tips over, it will no longer be you going to the powers that be to get the “OK to proceed”. It will be them coming to you and asking “what is taking so long?”. In that one moment, you’ll be able to fire back at them: “Here’s my roadmapping proposal. I’d love to have you be my business owner!”
-
Are the Milliseconds Worth It?
The pressure to prove one’s coding prowess can make a developer do some very clever and creative things with their source code. Sometimes it’s just a unique approach, but every once in a while this cleverness may shave a few milliseconds off of some performance metrics as well. In the end it’s not worth it. While this may seem like the type of innovation we want from our peers I’ve come to the conclusion it often does more harm than good. A quote that ran across my twitter feed a few weeks ago sums it up nicely: “So if you’re as clever as you can be when you write it, how will you ever debug it?” This pearl of wisdom comes from a book called “The Elements of Programming Style”. It’s a programming book from 1978 that is still entirely relevant. There’s a Wikipedia article you can check out if you’re not ready to take my word for it.
I know I’ve coded something in a unique fashion, and was quite sure I was being brilliant at the time, only to go back later and have absolutely no clue why I wrote the code the way I did. If I added comments I may be able to find my place again but sometimes it takes a while. What about when another developer runs into one of these bright ideas? Will any amount of meditation or contemplation allow them to make sense of what I was doing when I wrote it? Should a new or junior developer be expected to have some out of body experience before being able to work with me? Of course not. I hate it when I do this to myself, never mind when I run across someone else’s flash of genius. I certainly try to keep other devs from going through this type of mind freak as often as I can.
While this exercise can make for a fun parlor game and help extend our knowledge of the language we’re coding in it causes more problems than it solves in a team environment. A wiser developer sticks with a tried and true approach. They’ve been around long enough to know that the code needs to make sense to any garden variety developer that may be working with it in the future (which may in fact be the developer that wrote it in the first place).
I first learned this lesson years ago while tutoring mathematics. I had a developed an algorithm to generate the unit circle. Computer Science majors I was tutoring in math had an easier time using this to quickly generate the circle on scratch paper than arbitrarily memorizing it or understanding the standard proof that shows a bunch of triangles somehow morphing into a circle.
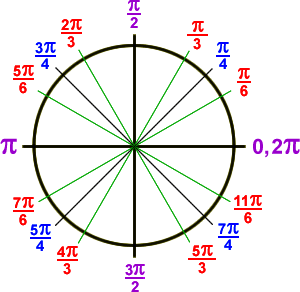
Radian Values of the Unit Circle The algorithm requires a certain amount of seed data. One must know that a full circle is 2π radians in circumference. This puts the other quarter circle measures at π/2, π, 3π/4 respectively. Only a simple understanding of fractions is required to see this. Next we need to fill the first quadrant, which is only three more values, π/6, π/4, and π/3. From here the algorithm helps us extrapolate the remaining radian values for the circle.
First Quadrant: π/6, π/4, and π/3 (initial seed values, you have to remember these)
Second Quadrant: π – First Quadrant Corollary Value ( e.g., 3π/3 – π/3 = 2π/3, our 2nd quadrant value)
Third Quadrant: π + First Quadrant Corollary Value ( e.g., 3π/3 + π/3 = 4π/3, our 3rd quadrant value)
Fourth Quadrant: 2π – First Quadrant Corollary Value (e.g., 6π/3 – π/3 = 5π/3, our 4th quadrant value)
So, the formula for quadrants two through four can take the form of (n – s), (n + s), and (2n -s), where n = π and ‘s’ is one of the three seed values from the first quadrant. Three simple equations that any CS major should be entirely comfortable with using. There are a few other notes on this proof to get the coordinates, signs, and degree measurements correct. This is not a post about mathematics however, so I’ll leave that as a exercise for the more mathematically inclined to complete on their own time.
Other mathematicians where not as impressed as the CS majors and the student athletes were with this. Watching students that actively despised math struggle with memorizing the unit circle in an effort to complete their core was part of the fun of being good with numbers. It was suggested (by some troll of a jerk) that I might be a math noob myself, some poser that wasn’t any smarter than the fools he was tutoring. Impostor syndrome set in and I I felt I had no choice but to prove my mathematical prowess.
First I went big and reproved what I was doing with a Klien Four-Group. The trolls were quick to point out that this, like my first model, wasn’t a circle at all but just a bunch of points on a plane. Next I came back with a version using a rotational matrix. This did in fact generate a full circle with any value you like on it. The trolls had no more jabs for me but they also fell short of any compliment or encouragement for the work I had done.
As for the students I was helping, none of them quite understood the issue I had encountered. They viewed those trolls as nothing but trolls. Peers that only laughed at their struggle and refused to even try to help them. I ultimately found out my students were concerned that I had gotten sucked into this quagmire. The research I was doing was beyond their understanding and they were still using the first model I developed. It did exactly what they needed it to do. I was informed I should take the rising grades as evidence that my work was of merit and move on to a more productive use of my time and energy.
It was only then I noticed the trolls did have a point. The Klien Four-Group model and my original algorithm weren’t circles at all, just dots with values attached to them. A mathematician would have issue with this where a developer would not, since an object oriented developer should have a deeply rooted appreciation for abstraction. A class called Tree rarely resembles what we know to be a tree. It’s the use case that ends up being important. To a paper company a tree only needs to be represented by the amount of pulp they can expect it to produce. To an apple farmer it probably boils down to the number of apples the tree puts out and maybe its location in an orchard. What we take to be a tree, its size, the shape of its leaves, how it smells, the sound it makes when the wind catches it, are all details beyond the scope of most software we’ll ever write.
This happens to be a huge blocker for most new OOP developers, especially the ones that are good at math. The object model I was using to teach CS students how to do trigonometry ended up being the perfect tool to teach mathematicians how object oriented programming works. The rotational matrix version is important because sometimes non-standard values are needed. It’s useful to show how a method call may use standard values or extend onto another model, like the rotational matrix, when standard values don’t apply.
Mathematicians appreciate the Klien Four-Group model and I’m happy to show it off when I have the chance. More importantly, it’s a reminder to not get too fancy with math they’re putting into software. The math is beautiful more than it’s clever, and I’ve written code I feel the same way about. Like most works of art it stems from a hobby and should be left out of any applied scenario if it’s not practical. If we can get the same result with something that’s simple, something that’s easy to understand, easy to use, and even common, then that’s what we should use every single time because it will be easy to maintain. Wisdom is nothing more than knowledge applied over time. Time and time again I’ve come to the conclusion that maintainability trumps performance. We should be quick to sacrifice any minimal performance gain that makes our code difficult to understand. If a major performance gain is within reach then we’d be wise to abstract any strange code that was used to obtain it. I’d also advise you to comment the living day lights out of it as well, since you may need to remember how it worked yourself someday.
-

The Importance of the Bus Driver
The topic of DevOps has been a topic for many a debate over recent
monthsyears. Without adding fuel to the fire I’d like to present a slightly different take on the DevOps culture.The phrase ‘what if I was hit by a bus?’ can often be heard within the vicinity of software development teams. It relates to a measurement known as the ‘bus factor‘. Individual talent should not be discouraged, however when it becomes silo’d that talent translates to risk for a business. Try to think back over your career – do the following sound familiar?
“I don’t know how to do that, X usually does that”
“X is away at the moment so we’ll need to put that on hold”
“X left yesterday and didn’t cover this in their handover”
If you have read ‘Phoenix Project‘ – think of Brent…
Using the fated bus driver I’d like to take us on a journey (excuse the pun) through a DevOps culture.
In-sourcing the bus driver
You work for a small green minded startup. Being green minded and wanting to help your staff, you decide to buy a bus to get everyone to work in the morning. Realising that you don’t actually have a dedicated bus driver, you decide to take it in turns to drive the bus in the morning. Everyone gets involved, everyone knows how to drive the bus, everyone knows which route is best.
Idea 1
Don’t over engineer your processes. At this stage you’re already exhibiting DevOps characteristics!
The talented bus driver
Your small team has performed really well, people like what you do and now your team isn’t quite so small. There are now over 50 people on your bus in the morning. It wasn’t long until you realised that Sarah is the best bus driver you have. Inevitably, Sarah usually just takes up driving the bus each and every morning.
If Sarah is off, Mike takes over but he often makes people late for work and tends to hit a lot of parked cars.
Furthermore the bus recently broke down when Sarah was off, Mike and your bus passengers all took a look at the engine and tried to help but there seemed to be a ‘magic’ piece of string holding two parts together.
When they consulted the bus manufacturer manual, this piece of string was no where to be seen. Mike had to call Sarah whilst on holiday!
Mike calls the bus company to ask for a replacement bus, to be told it will be 2 hours until a second bus arrives. The team sit and wait patiently.
Idea 2
Try to identify your tipping point. Some key indicators are reliance on individuals, information silo’s, phrases such as ‘oh I didn’t know it functioned like that in production’, production environments start to diverge (without communication) from development environments.
How many production environments have the web server, app server, database, load balancer et al all running on the same machine? Is this how your development teams work? Does this differ to the view of the operations team?
Your bus stops
We’ve identified a few problems but lets focus on the positives. Firstly, let’s celebrate actually spotting the problem, it is very easy to continue with the status quo. Our second success was the reaction of our bus passengers. When the bus broke down, instead of complaining, the bus passengers tried to help mend the bus.
Idea 3
When and where your bus stops is less important than who it stops for. It might be stating the obvious, however if you wish to move towards a DevOps culture you need talented team members. You need people that care for the organisation and their profession. A desire to share knowledge for a greater goal.
If your team are not interested or do not care, then no matter how much you say DevOps you need to boost their interest first.
Hopefully you’ll start to hear your teams utter phrases such as “What does production look like?”, “You could do this slightly differently you know”…
What if your talented bus driver has an RTA?
There are no doubting Sarah’s talents – I mean come on, she was able to fix a bus engine with a piece of string, knew the best bus routes and always got your team to work on time…
What would we do if Sarah left or was, somewhat ironically, hit by a bus?
Idea 4
Could your organisation raise the value of sharing and encourage knowledge share?
Assuming you’ve got the right people on the bus, you might also find that other staff members have ideas for improvement when you explain the current process. Your Sarah(s) should not fear sharing their knowledge and should be rewarded/encouraged for doing so.
One of your passengers may even know a faster journey to work or a better way to fix the bus engine.
The bus seating plan
Although you didn’t enforce it, you start to find groups forming on your bus journey, all your teenagers are sat together at the back playing music on their phones…..
Idea 5
Don’t let job titles restrict conversations. Water cooler chats are incredibly productive and help teams share ideas.
Replacement bus service
When the bus broke down Mike was able to order a replacement but it had a 2 hour turnaround time.
Would it be better if we always had 2 or 3 buses running? If each bus had enough capacity for all 50 passengers we’d probably always make sure people were on time for work.
It would be even better if all bus drivers knew the routes that Sarah used, all buses had the same piece of magic string and all bus drivers knew what the magic string did.
Idea 6
Something my team often hear me say is ‘Design for failure, don’t just react to it‘. When designing your applications and services try to think how the system can accommodate failing services better rather than what actions you might take in the event of failure.
The same might be said for your human resources. Have your teams got a shared knowledge? What would your bus factor score be?
Journey times
Try to keep your passengers informed of your progress – you could let them know their ETA for work. Informed passengers tend to be more engaged and understanding. For example when telephoning a business, do you prefer to know what position you are in ‘the queue’ or would you rather sit on the line waiting without knowledge of when you may be spoken to?
Idea 7
Monitoring might be considered a key technical section of DevOps adoption. There are many, many tools that can help with this such as StatsD, Graphite, Librato, New relic, AppDynamics etc but whichever medium you choose, try to make sure your ops stats are in full view of your various teams not simply your ops staff. Get them in front of your dev team, support team, sales team, HR team they impact every member of staff.
Hopefully, you will be surprised at an increased level of employee engagement. When ops are in war rooms fire fighting problems, each team member will understand the pressures they are under, some team members will also express a desire to help.
You have arrived at your destination
At this stage I may have flogged the bus concept a little too far. Are the concepts here a guide for the adoption of a DevOps culture? Does the ‘D’ word have to be attached to the guidelines above? I’ll let the community decide.