Category: DevOps Culture

  • Sonar Adds Secrets Detection to Code Analysis Portfolio

    Sonar Adds Secrets Detection to Code Analysis Portfolio

    Sonar has added a secrets detection capability to its portfolio of tools for analyzing code and DevOps workflows.

    Designed to be applied to both finding secrets in code repositories and as applications are developed using an integrated development environment (IDE), this capability is being added to SonarLint, SonarQube and the managed SonarCloud service to identify, for example, passwords, application programming interface (API) keys, encryption keys, tokens, database credentials and other private information.

    Sonar co-CEO Olivier Gaudin said the goal is to eliminate secrets that are accidentally or maliciously stored in source code to improve software supply chain security.

    While it’s important to discover secrets in codebases, Sonar is making a concerted effort to make it simpler for developers to discover secrets before they find their way into a codebase that is one step away from a production environment, noted Gaudin. The SonarLint static analysis tool the company provides can now discover secrets in microseconds using the syntactic and semantic analysis engines the company has now extended, he added. No developer is going to wait five to 10 minutes for a code scan to be completed, said Gaudin.

    A Learn as You Code tool also explains how each secret found in a code segment poses a security risk. The overall goal is not only to remove secrets but, ultimately, reduce the number of instances where secrets are discovered in code, said Gaudin.

    Most organizations today are at varying stages of embracing DevSecOps best practices to improve software supply chain security. It’s not clear how readily secrets management is being embraced as part of those modernization efforts, but as cybercriminals routinely scan for application secrets stored in clear text that can be used to compromise application security, the need to encrypt secrets becomes a higher priority.

    There is, of course, no shortage of tools for detecting secrets. Sonar is now simply making a case for managing secret detection as part of a larger effort to reduce vulnerabilities in code that cybercriminals can exploit. That approach should help reduce the total cost of securing a software supply chain at a time when forthcoming regulations are going to make organizations that deploy software more accountable for application security.

    In the meantime, thanks to the rise of generative artificial intelligence (AI), the volume of code that needs to be scanned will likely exponentially increase. The issue with general-purpose AI platforms such as ChatGPT is they were trained using code of varying quality that often contains vulnerabilities that are now sometimes incorporated into the code they generate. On the plus side, however, many developers have little to no application security expertise, so it’s just as feasible that ChatGPT will create more secure code than a human developer. Regardless of how the code was created, however, no one will know for sure how secure it is without scanning it first.

    Hopefully, as AI progresses, the quality of the code being generated will only continue to improve. Until then, DevOps teams should continue to assume all code is suspect until proven otherwise.

  • What Is the Future Workforce and How Will it Impact DevOps Teams?

    What Is the Future Workforce and How Will it Impact DevOps Teams?

    The rapid changes in technology, work patterns and demographics are ushering in a new era for the labor market known as the future workforce. In this context, DevOps teams—tasked with developing and delivering software quickly and efficiently—are facing novel challenges and opportunities. 

    This article will explore the key characteristics of the future workforce, from remote working to the gig economy, and explores how these changes will impact the roles, practices, and skill sets of DevOps teams. Understanding these dynamics is crucial for both staying competitive and fostering innovation in an ever-evolving professional landscape.

    What Is the Future Workforce?

    The future workforce refers to the evolving nature of the labor market, shaped by factors such as rapid technological advancements, demographic shifts, and changes in work patterns and organization. It’s a concept that’s important to understand given its profound implications for businesses, employees, and society at large.

    The future workforce is already here, and it’s changing the way we work. With every passing day, traditional work models are being challenged and redefined, leading to a professional landscape that’s increasingly diverse and dynamic.

    By exploring the future workforce, you’re not just preparing for changes that may affect your career or business. You’re also discovering opportunities for growth and innovation. Whether you’re an employee looking to future-proof your career, a business owner seeking to attract and retain top talent, or a policymaker aiming to foster economic development, understanding the future workforce is crucial.

    The Composition of the Future Workforce

    Remote Workers

    One of the most significant shifts in the future workforce is the rise of remote workers. As technology continues to evolve, more and more people are choosing to work from home or any location of their choice. This trend is driven by many factors, including the desire for a better work-life balance, the need to save time and money on commuting, and the opportunity to work in a more comfortable and personalized environment.

    Remote working isn’t just good for employees; it’s also beneficial for businesses. Companies that embrace remote work can tap into a global talent pool, reduce overhead costs and increase productivity. 

    However, managing a remote workforce requires a different set of skills and strategies. For instance, businesses must invest in technology to facilitate communication and collaboration, establish clear expectations and performance metrics and foster a culture of trust and accountability.

    Gig Economy

    Another key feature of the future workforce is the gig economy, characterized by temporary, flexible jobs often facilitated by digital platforms. The gig economy includes a wide range of work arrangements, from freelance work and contract-based projects to short-term jobs and on-demand services. In the gig economy, you’re not tied to a single employer or a rigid work schedule, giving you greater flexibility and control over your work.

    The gig economy offers many benefits, such as the ability to earn additional income, the flexibility to work when and where you want, and the opportunity to pursue a variety of work experiences. However, it also comes with challenges. Gig workers often face job insecurity, lack of benefits, and financial instability. Therefore, navigating the gig economy requires careful planning and management.

    Diverse Demographics

    The future workforce is also marked by increasing diversity. This includes not just racial and ethnic diversity but also diversity in terms of age, sexual orientation, disability status and other characteristics. As society becomes more diverse, so does the workplace. This trend reflects not just demographic shifts but also changes in societal attitudes and legal frameworks.

    Diversity in the workforce is not just a matter of fairness and equality, it’s also a business imperative. Numerous studies have shown that diverse teams are more innovative, creative, and effective. Companies need to foster an inclusive culture, implement fair recruitment and promotion practices, and address unconscious bias and discrimination.

    Future Workforce and the Implications for DevOps Teams

    As the nature of the workforce evolves, DevOps teams, traditionally centered on rapid and efficient software development, are increasingly distributed across various locations and time zones. This shift towards a distributed workforce presents unique challenges and opportunities for DevOps practices.

    Distributed Team Dynamics in DevOps

    The essence of DevOps lies in a continuous cycle of collaboration and improvement. In a distributed setting, this requires enhanced communication strategies to ensure that team members are consistently aligned with project goals and timelines. Utilizing collaborative tools and platforms becomes crucial in bridging the geographical gaps. Regular virtual meetings and real-time collaborative environments are pivotal for maintaining team cohesiveness.

    Continuous Integration and Deployment (CI/CD) in a Distributed Setting

    Managing a CI/CD pipeline in a distributed team demands meticulous planning and coordination. DevOps must adapt to different time zones and work schedules, ensuring that the pipeline remains efficient and uninterrupted. This involves automating as many processes as possible and establishing clear protocols for code integration, testing, and deployment, thus reducing bottlenecks and ensuring continuous delivery.

    Infrastructure Management Across Borders

    In distributed teams, infrastructure management must focus on clarity and accessibility. This means maintaining comprehensive documentation ensuring all team members, regardless of location, have a clear understanding of the entire infrastructure. Emphasizing cloud-based solutions can offer a centralized and accessible platform for all team members, thus simplifying remote infrastructure management.

    Emphasizing Security in a Distributed Environment

    Security challenges are amplified in a distributed setup, as team members may access company resources from various, potentially unsecured networks. DevOps teams must implement stringent security protocols and regular training to mitigate these risks. This includes the use of VPNs, regular security audits, and ensuring that all team members are up-to-date with the latest security practices.

    Nurturing a Unified Culture

    Despite physical distances, cultivating a strong, unified team culture is vital. This involves not just the regular technical sync-ups but also creating opportunities for informal interactions and team building. Encouraging open communication and transparency can help in building trust and a sense of community among team members.

    Skill Sets for DevOps in a Future Workforce

    As DevOps teams navigate the future workforce, there are several key skill sets that will become increasingly important.

    Security Skills

    As mentioned earlier, security will be a major concern in the future workforce. DevOps teams will need to have strong security skills, including understanding of security principles, knowledge of security tools and technologies, and the ability to implement secure coding practices.

    It will also be important to stay up-to-date with the latest security threats and trends, as the landscape is constantly evolving.

    Soft Skills

    While technical skills are undoubtedly important, the value of soft skills in the future workforce should not be underestimated. Skills such as communication, teamwork, problem-solving, and adaptability will be essential for success.

    As teams become more distributed and work becomes more complex, the ability to effectively communicate and collaborate will be key. Additionally, the fast-paced nature of technology means that adaptability and the ability to learn quickly will be highly valued.

    Collaboration and Project Management

    In the future workforce, collaboration and project management skills will be crucial. DevOps teams will need to be able to work effectively with a diverse range of stakeholders, from developers and operations staff to business leaders and customers.

    This involves being able to manage projects effectively, from planning and execution to monitoring and controlling. Knowledge of project management methodologies, tools, and techniques will be highly beneficial.

    Conclusion

    In conclusion, the future workforce will bring about significant changes to the professional landscape. As we navigate this new terrain, it’s important for DevOps teams to be aware of these changes and to develop the necessary skills to thrive. By focusing on continuous integration and deployment, infrastructure management, unified communication, and security, DevOps teams can stay ahead of the curve and continue to deliver high-quality software products.

  • Five Great DevOps Job Opportunities

    Five Great DevOps Job Opportunities

    devopsy.kinsta.cloud is now providing a weekly DevOps jobs report through which opportunities for DevOps professionals will be highlighted to better serve our audience.

    Our goal in these challenging economic times is to make it easier for DevOps professionals to advance their careers.

    Of course, the pool of available DevOps talent is still relatively constrained, so when one DevOps professional takes on a new role it tends to create an opportunity for others.

    The five job postings shared this week are selected based on the company looking to hire, the vertical industry segment and, naturally, the pay scale being offered.

    We’re also committed to providing additional insights into the state of the DevOps job market. In the meantime, for your consideration:

    Indeed.com

    MedStudy
    Remote
    Senior DevOps Engineer
    $125,000 to $165,000

    SimplyHired.com

    Raytheon
    Tewksbury, Massachusetts
    Technical Fellow – DevSecOps/Cloud Native
    $122,000 to $155,000

    CareerBuilder.com

    State Street Corp.
    Quincy, Massachusetts
    Azure DevOps Engineer
    $120,000 to $202,500

    Dice.com

    USEReady
    New York, New York
    Senior Azure DevOps Engineer
    $120,000 to $160,000

    LinkedIn

    Northrop Grumman
    Dulles, Virginia
    Senior Principal DevOps Engineer
    $107,300 to $199,600

  • The Future of Jenkins in 2024

    The Future of Jenkins in 2024

    As software development practices evolve, the tools that support them must also adapt to stay relevant. Jenkins, the venerable automation server used by many DevOps teams, is at such a crossroads as it faces the changing landscape of cloud-native applications and Kubernetes adoption. 

    This article examines Jenkins’ current utility, particularly its features that have made it a staple in CI/CD practices, and addresses the question of whether it will maintain its relevance in 2024 and beyond.

    How Jenkins is Used by DevOps Teams

    CI and CD

    Jenkins has become an integral part of many DevOps teams due to its CI/CD capabilities. Continuous integration (CI) is a software development practice where developers regularly merge their code changes into a central repository. Continuous delivery (CD) is the practice of delivering the software in short cycles to ensure that it can be reliably released at any time.

    Jenkins supports the CI/CD approach in a number of ways. First, it allows developers to automate code integration. This means that whenever code changes are pushed to the repository, Jenkins can automatically build and test the project. Second, Jenkins allows for the continuous delivery of software by automating simple deployment processes (although it lacks full deployment orchestration capabilities).

    Build Pipeline Visualization

    Another key feature of Jenkins is its build pipeline visualization. This feature allows DevOps teams to visually represent the process of software delivery from code integration to deployment. The pipeline visualization provides a clear and intuitive representation of the software delivery process, making it easier for teams to understand and manage the process.

    Build pipeline visualization in Jenkins is customizable, allowing teams to tailor it to their specific needs. For example, it can be customized to show the status of each stage of the delivery process, from code integration to testing to deployment. This allows teams to quickly identify any issues or bottlenecks in the process and address them.

    Automated Testing

    Automated testing is another area where Jenkins shines. With Jenkins, DevOps teams can automate the process of testing their code by running scripts and integrating with automated testing tools as part of the build process.

    Jenkins supports a wide range of testing frameworks and tools, allowing teams to choose the ones that best fit their needs. Moreover, Jenkins can be configured to automatically run tests whenever changes are made to the code. This ensures that any issues or defects in the code are detected early and can be addressed promptly.

    Workflow Scripting

    Workflow scripting is another key feature of Jenkins in DevOps teams. With Jenkins, teams can script their workflows, automating the process of software delivery. This allows teams to standardize their workflows, ensuring that each delivery process is consistent and predictable.

    Jenkins supports the Groovy scripting language for workflow scripting. This means that teams can use the power and flexibility of Groovy to script their workflows. Moreover, Jenkins provides a user-friendly interface for scripting workflows, making the process easy even for those who are not familiar with Groovy.

    Current Usage and Adoption Statistics

    As of 2023, Jenkins remains a leader in the CI/CD space. With its extensive plugin architecture and large user base, it is used by thousands of organizations worldwide. According to the 2022 DevOps Survey by the Cloud Native Computing Foundation (CNCF), Jenkins was used by over 50% of respondents for automation and CI/CD, maintaining a significant presence in the market.

    According to the Jenkins website, there are over 1 million active Jenkins users and more than 200,000 active installations worldwide, with the platform handling 1 million+ jobs per day. It had about 44% of the global market share for CI/CD in 2023.

    The growth trajectory of Jenkins, however, has shown signs of plateauing when compared to newer, more cloud-native-focused CI/CD tools. This observation is backed by Google Trends data, reflecting a steady but not sharply increasing interest in Jenkins over recent years.

    Despite facing competition from emerging tools designed for cloud-native development, such as GitHub Actions, GitLab CI and CircleCI, Jenkins has responded by evolving its ecosystem. The creation of Jenkins X is a strategic move to cater to Kubernetes users and address some of the criticisms related to cloud-native development. However, as we’ll discuss, Jenkins X has not been readily adopted by the industry as of yet.

    Limitations of Jenkins in Cloud-Native Environments

    While Jenkins is a powerful tool for DevOps teams, it has serious limitations in cloud-native environments. These limitations stem from the fact that Jenkins was originally designed for traditional, monolithic applications, not for the dynamic and distributed nature of cloud-native applications.

    Statefulness

    One of the critical limitations of Jenkins in cloud-native environments is its inherent statefulness. Cloud-native architectures typically favor stateless applications, which are easier to scale and manage in dynamic environments like Kubernetes. 

    Jenkins, however, relies on maintaining state—it stores configuration, build history and user data, making it challenging to scale and manage efficiently in a cloud-native setup. This statefulness requires persistent storage, which complicates deployments in distributed systems where resiliency and horizontal scaling are key. Moreover, the risk of data loss or inconsistency increases in cloud-native environments, particularly during scaling operations or when recovering from failures.

    Configuration Complexity

    Jenkins is often criticized for its complex configuration requirements. Setting up Jenkins in a cloud environment involves intricate configurations that are not only time-consuming but also prone to errors. This complexity is exacerbated when integrating with modern cloud-native tools and services, requiring extensive customization and maintenance of plugins. 

    In addition, Jenkins’ traditional master-slave architecture was not designed for dynamic cloud environments, where resources need to be provisioned and deprovisioned rapidly. This leads to a significant operational overhead for DevOps teams.

    Immutable Infrastructure

    Adopting an immutable infrastructure approach is a cornerstone of cloud-native environments, promoting the idea of replacing or rebuilding servers rather than modifying them. 

    However, Jenkins’ traditional model does not align well with this principle. It typically requires modifications to its runtime environment for updates or changes, contrasting with the cloud-native approach of immutable deployments. This can make it challenging to maintain consistency and reliability in cloud-native systems where automation and minimal manual intervention are paramount.

    Microservices Limitations

    Jenkins was originally designed for monolithic architectures and doesn’t naturally fit into microservice-based applications, which are prevalent in cloud-native environments. In microservices architectures, applications are broken down into smaller, independently deployable services. 

    Jenkins, however, tends to treat applications as monolithic units, making it less efficient for handling multiple, independent microservices. This limitation affects its ability to provide fine-grained control over individual services’ build, test and deployment processes. Consequently, Jenkins may struggle with the high degree of automation, flexibility and scalability required in microservices environments.

    What is Jenkins X?

    Jenkins X is an open source project that provides pipeline automation, built-in GitOps, and preview environments to help teams collaborate and accelerate their software delivery at any scale. It is an improved version of the original project, designed specifically for Kubernetes, a popular container orchestration platform.

    Jenkins X streamlines the technical aspects of building, testing, and deploying software. It automates the installation of popular tools like Helm and Draft, making it easier for developers to get started. It also provides pre-configured pipelines so teams can start delivering software right out of the box.

    Jenkins X also introduces a new Jenkinsfile format, Jenkinsfile.yaml, which provides a more straightforward and human-readable way to describe pipelines. This new format, combined with the automation provided by Jenkins X, helps reduce the complexity of pipeline configuration and management in Kubernetes.

    Limitations and Criticisms

    Jenkins X has not been widely adopted by the software industry and has not achieved the respect and prominence of its predecessor, Jenkins. Let’s review the main limitations and criticisms of the tool.

    Lack of Maturity

    Jenkins X’s relatively recent entry into the market means it has not had the time to mature like its predecessor. This lack of maturity can manifest in several ways, including fewer features compared to established tools, fewer community-tested plugins, and potentially more bugs or unresolved issues. Due to the fast-paced evolution of cloud-native technologies, tools need time to adapt and stabilize; Jenkins X is still in this phase of its lifecycle.

    Moreover, a mature tool typically has extensive documentation and a large community of users who can offer support and share best practices. While Jenkins X has seen growth in its user base, it still lags behind more mature CI/CD solutions in these areas. This can lead to challenges when teams are looking to solve complex problems or when they require advanced support.

    Limited to Git Projects

    Another criticism of Jenkins X is that it’s limited to Git projects. While Git is the most popular version control system, it’s not the only one. Some teams may use other systems like Mercurial or SVN, and these teams would be unable to use Jenkins X.

    Even within the world of Git, Jenkins X has limitations. For example, it doesn’t support all Git hosting platforms. While it works with popular platforms like GitHub and Bitbucket, it doesn’t support others like GitLab. This can be a significant limitation for teams that use unsupported platforms.

    Community Support

    Finally, there are concerns about community support for Jenkins X. While the project is open source and theoretically has the potential for wide community involvement, some critics argue that it’s primary source of support is CloudBees, the company behind Jenkins.

    These critics worry that if CloudBees were to withdraw its support, the project could falter. They also argue that the project’s focus on certain tools and platforms (like Kubernetes and Git) reflects CloudBees’ business interests more than the needs of the broader DevOps community.

    Conclusion

    In conclusion, Jenkins’ role in the CI/CD landscape has been pivotal, and its continued evolution with projects like Jenkins X demonstrates an effort to adapt to the needs of modern, cloud-native environments. While Jenkins X has yet to reach the widespread adoption and maturity of its predecessor, its specialized focus on Kubernetes and GitOps reflects the shifting priorities in software development.

    Jenkins, despite showing signs of plateauing in growth, still possesses a strong user base and an established presence in the market, supported by a vast plugin ecosystem and a robust community. Its limitations in cloud-native contexts—such as managing statefulness, configuration complexity, and supporting immutable infrastructure—pose challenges that Jenkins X seeks to address.

    As we approach 2024, the relevance of Jenkins will likely hinge on its ability to integrate more seamlessly with cloud-native technologies and the willingness of the community to evolve its ecosystem. The breadth of its adoption and the depth of its integration in existing development pipelines mean Jenkins will continue to be a significant player in the DevOps toolchain. However, its long-term relevance will depend on the project’s ability to innovate and remain adaptable in a landscape that is rapidly embracing cloud-native solutions.

  • Survey Surfaces Significant Platform Engineering Gains

    A survey of 100 software engineers working at organizations in the U.S. and Western Europe published today found nearly all (99%) have embraced platform engineering to some degree as a methodology to manage DevOps workflows at scale, with more than half (53%) having done so in the last year.

    Conducted by Port, a provider of a proprietary internal developer portal (IDP) platform, the survey also found 83% of respondents have also incorporated GitOps workflows into their platform engineering practices.

    The survey also found 85% are working for organizations that have either started deploying IDPs or plan to do so in the coming year. However, what constitutes an IDP is not exactly clear, with more than a third (35%) that have implemented one reporting they are relying on spreadsheets to manage their IDP. A little over half (53%) of respondents, in contrast, are using an IDP to provide developers with self-service capabilities for setting up environments to write code that either was custom built, is based on open source Backstage software originally developed by Spotify or a commercial IDP platform.

    Among the 85% of respondents using or planning to use an IDP, the main measure of success is to improve developer productivity (56%), followed by reduced time to deployment (25%). Despite those initiatives, only slightly more than a third (34%) said IDPs are helping DevOps teams enforce software engineering standards.

    Roni Floman, chief marketing officer for Port, said overall, the survey suggests developers are wasting a lot of time on tasks that have little to do with writing code. For example, the survey finds that prior to embracing platform engineering, developers spent three to four hours a day on non-core activities, resulting in weeks being required to eventually deploy software in a production environment.

    The biggest challenge organizations face when embracing platform engineering is convincing developers that a centralized team has their best interests at heart. Many application development teams embraced DevOps as a best practice in the first place to escape the tyranny of a centralized IT team. The issue is that, as a result, many of them now find themselves managing tasks that have little to do with writing code. Platform engineering seeks to strike a balance between giving developers the ability to adopt new tools when they see fit and the benefits of having a dedicated platform engineering team that automates processes on their behalf.

    Unless platform engineering teams find a way to get developers to buy into the effort, however, it’s unlikely they will succeed, noted Floman.

    Each organization will need to determine for itself what level of platform engineering makes sense for them to implement, given their unique culture. In most cases, a platform engineering initiative will start small before increasing in size and scope as momentum is gained. In the meantime, the most important thing any platform engineering team clearly needs to do in the short term is engage developers. After all, the best way to get support for any change to a DevOps workflow is, as always, to convince developers it was their idea in the first place.

  • 5 Reasons to Move Beyond SRE to Observability

    5 Reasons to Move Beyond SRE to Observability

    Recently, I was asked on a podcast to explain the relationship between site reliability engineering (SRE) and observability and why I believe organizations need to move their focus from the former to the latter. Those are great questions, but to answer them accurately, I first need to point out that many organizations claim to be doing SRE or claim to be doing observability but aren’t.

    One big thing that SRE and observability have in common is that they are both often erroneously equated with monitoring.

    SRE ≠ Monitoring

    Google is credited with pioneering the SRE movement with the publication of the “Site Reliability Engineering” handbook in 2016. As the SRE movement gained momentum, organizations of all sizes pored over the handbook and began applying its principles. However, very few organizations are of the size and sophistication of Google regarding the scale of their IT operations and engineering resources.

    So, as these “normal” organizations realized how difficult it was to follow the Google SRE approach in its entirety, they often opted instead to simply apply what they could. For many, the chapter on monitoring became the focus, so much so that monitoring has become synonymous with SRE in far too many organizations today.

    Let me be clear: The role of a site reliability engineer is not to monitor alerts. The role of an SRE is to define how the engineering team should take ownership of their service. SREs are responsible for establishing a culture and creating engrained processes that are focused on the quality and reliability of infrastructure.

    SREs guide the engineering team on how an application or service should be observed and monitored, including what parameters should be looked at, what alerts they should have, and what routing path the alerts should go through. An SRE instructs on best practices, explores the tools that are being used and determines how to gather reliable data with consistency throughout the organization.

    Many organizations we work with say they want to do SRE this way, but they’re not there yet. They are still stuck on monitoring every single metric they can find.

    Observability ≠ Monitoring

    Similarly, a lot of companies I meet say that they do observability, but what they are doing is just monitoring. They monitor every single CPU of every node of every pod of every machine that is running. They have alerts for some of these, and they may even have a playbook for some of them. This is not how SRE is supposed to work, and it’s certainly not what observability is all about.

    More importantly, it’s not scalable as an organization grows to hundreds or thousands of developers and different teams that all share the same IT environment.

    Two Viewpoints: Horizontal and Vertical

    Now that we’ve established that SRE and observability are alike in that neither should be equated with monitoring, let’s contrast the two. SRE and observability are different in that they have different perspectives on the IT domain.

    SREs see the world horizontally. They conceive of their IT domain on a horizontal plane where they can observe the capacity of resources being used. They see the Kubernetes cluster, and they see the cloud utilization. And they care about ensuring that what is deployed into the production environment is secure.

    Although they see the pieces they manage on the horizontal infrastructure plane, they don’t see the ultimate impact on the application or customer on the planes “above.”

    Observability is looking at the world vertically—that is, seeing how an application is or isn’t meeting customer needs. The whole goal of observability is to know if my application is serving my customers at the service level that I agreed to. With a vertical view from application up to customer needs and business impact, I don’t care how many pods are being run, how many nodes are being deployed or what comprises the cloud infrastructure underneath my application, as long as it works.

    I do care about security insofar as I want to avoid introducing security vulnerabilities into the organization. But beyond that, all I need to know is that the application can meet the customer’s expectations and the service level objectives (SLOs) that we have established are being met, as well.

    Therein lies the heart of the matter: For a company to make the transition to observability, it needs to build the observability system around establishing and meeting SLOs.

    The Challenges of Transitioning to a Vertical Perspective

    Companies must move beyond an SRE and DevOps organization to being an observability and SLO organization. Only by doing this will organizations be capable of understanding the trade-offs within their IT environments between cost, security and availability and the ultimate impact those trade-offs will have on business objectives.

    Today, making this transition — moving beyond SRE to observability — is difficult for a wide variety of reasons, not the least of which are:

    Alert Fatigue. Companies today are monitoring too many things they shouldn’t care about, and as a result, engineers are suffering from alert fatigue. With this, you face the danger of a higher probability of missing the alerts that you do care about and making sure that you address them promptly.

    Ideally, observability solutions eliminate the irrelevant and unimportant alerts, add context to alerts that might need investigating, and correlate response data and docs to accelerate and coordinate the appropriate response of on-call responders.

    Tool sprawl. Many of the companies we work with use a wide variety of separate tools for observability. Observability requires access to the data all of these tools produce, and problems can persist if the tools operate in data silos.

    However, the problem can be solved if there is unified data collection across the toolset, ideally using OpenTelemetry. Cross-tool and cross-stack insights are particularly important for security purposes. Another issue with tool sprawl is that true observability requires that these tools, which each typically address just one aspect of observability, somehow all work together.

    Unfortunately, current systems and processes lack the “connective tissue” to offer a consolidated observability solution.

    Complexity. As we’ve seen in the results of our annual DevOps Pulse survey, the mean-time-to-resolution (MTTR) is going up instead of down, despite the number of tools that are available and the advancements made by the industry in recent years.

    Complexity is a large part of the problem, specifically concerning Kubernetes. In our 2023 DevOps Pulse Report, we found that almost 50% of respondents cited Kubernetes as their main challenge to gaining full observability into their environment.

    The adoption of Kubernetes is happening at lightning speed—even faster and higher than the adoption of cloud technology. But it’s not just the adoption of one Kubernetes—there are so many different flavors of Kubernetes, whether it’s Kubernetes running on managed services like AWS EKS or AKS or Kubernetes running on serverless with AWS Fargate. And that’s just to name a few of many, many types of Kubernetes out there.

    All of these options create flexibility, but wherever you create flexibility, you also create complexity. Complexity in the infrastructure increases the time it takes to troubleshoot and resolve issues.

    Cost. Most of us have figured out that products that include every feature under the sun are a waste of money. We don’t need expensive and extraneous clutter. Likewise, gathering and processing too much irrelevant monitoring data adds significantly to costs. Investing in observability platforms that are overloaded with bells and whistles you simply don’t need is similarly costly.

    The ideal observability platform taps AI and automation to help you easily see what’s most important to the business and respond quickly to core issues with precision and advanced insights.

    Culture change. Going from monitoring to observability is akin to making a cultural quantum leap. Observability requires a different organizational structure and assigns different responsibilities to the teams. The transition requires change management skills and patient, thoughtful execution.

    Though these challenges are significant, the observability industry is making rapid progress and organizations can expect to see solutions and technology providers that overcome these challenges shortly. So, be on the lookout for great opportunities coming down the pike.

    In the meantime, I challenge you to change your perspective from horizontal to vertical. Set your organization on the path to move beyond DevOps and SRE to true observability, where your teams will not just be alerting and chasing issues for troubleshooting but working to establish real SLOs and driving toward those to enable the strategic goals of the business.

  • KubeCon 2023: Dell, DevOps and DevRel

    KubeCon 2023: Dell, DevOps and DevRel


    Speaker 1: This is Techstrong TV.

    Alan Shimel: Hi everyone. Hey, we’re back here live in Chicago, KubeCon + CloudNativeCon, day two, continuing our coverage, we’ve got some great people lined up to bring you today. We started just now with Dan Garfield from Argo and Codefresh, and my next guest is my friend Brad Meltzer…

    Brad Maltz: Maltz.

    Alan Shimel: I screwed this up… He’s my friend, and why do I think Meltzer?

    Brad Maltz: I don’t know, it’s a good New York name.

    Alan Shimel: No, I knew a Richard Meltzer.

    Brad Maltz: There you go.

    Alan Shimel: I’ll tell you a great story about him off camera, he was a tech entrepreneur, a miserable failure of a tech entrepreneur.

    Brad Maltz: Okay.

    Alan Shimel: His wife though, invented the things, you know how you’ve got holes in Crocs?

    Brad Maltz: Yes.

    Alan Shimel: His wife invented the things that go into those holes. He closed down his venture backed startup, his wife sold those to Crocs, and they’ve lived happily ever after.

    Brad Maltz: And I hope he’s watching this.

    Alan Shimel: Richard Meltzer. He’s from Boulder, Colorado. Hey man, how are you, Meltzer?

    Anyway, that took me down a rabbits nest. Brad is with us… Actually shout out, right? Dell Technologies is sponsoring our broadcast this year from KubeCon again, as they did in Amsterdam last year, and a large part of it is due to Brad, Brad is a director…

    Brad Maltz: Senior director of-

    Alan Shimel: Senior director.

    Brad Maltz: Of the DevOps portfolio and DevRel.

    Alan Shimel: There you said it. Now a lot of you may be asking at home, wow, I didn’t know Dell was involved in DevOps and DevRel, or in CNCF.

    Brad Maltz: Yep.

    Alan Shimel: I got a Dell, right? I got a Dell box-

    Brad Maltz: You’ve got your laptop.

    Alan Shimel: I got the Dell server and stuff like that, but there’s more to today’s Dell than the boxes. So Brad, I don’t want to embarrass you, but I’m going to put you on the spot here.

    Brad Maltz: Go for it.

    Alan Shimel: Talk to us about, I want everyone at home to understand what your group does and how involved you are, not just in CNCF, but in the DevOps community, the DevRel community.

    Brad Maltz: Yeah, so basically over the past year and a half, we’ve been making sure to kind of expand our community outreach, specifically around the DevOps stuff. When I took over the role in product management to help kind of build out further our container strategy, our infrastructure as code strategy, we didn’t realize that we needed a DevRel-like function to help kind of expand our community outreach, our advocacy back into Dell.

    And the reason for that is, what a lot of people don’t know is, I mean, we play across the entire ecosystem of CNCF, right?

    Alan Shimel: Absolutely.

    Brad Maltz: We bring Containers and Kubernetes solutions to market, we play in the AIML space, the security spaces. We’re enabling ecosystems around us with our technology.

    So because of that, having DevRel was extremely important. We spun up podcasts, we have what we call our DevOps Dispatch, which we’re actually recording here at CNCF, and you can get that on YouTube and Spreaker. We have developer.dell.com which we relaunched last year, and now it’s kind of taken off, hands-on labs and blogs and a whole bunch of stuff on there. So for us, the evangelism’s important, but the advocacy for our end users is more important back into Dell.

    Alan Shimel: Got it. So we talked about the… I don’t want to use the word infrastructure, but the infrastructure of how you’re reaching out.

    Brad Maltz: Infrastructure matters.

    Alan Shimel: Absolutely. But I want people at home to understand that behind that infrastructure though is real solutions.

    Brad Maltz: Exactly.

    Alan Shimel: Right? Because part of the whole Dell Technologies thing, it’s solutions. It’s not just a PR marketing kind of… Though we see it here on the show floor, and the podcast and all these things. Let’s talk about the solutions you guys bring.

    Brad Maltz: Yeah, so I mean, a great example is, and this show is actually a big one for us, we just recently have launched our APEX Cloud platforms, and we did one with Azure Stack, we just did one with Red Hat with OpenShift, and that’s actually one of the big things here.

    And what you’re going to see more and more of from us is the ability to take our compute, with our storage, our networking, integration with our ecosystem partners, but give you more of that easy button experience, give you more of the turnkey experience, or even the DIY. We’re always been good at the DIY.

    Alan Shimel: Yeah, that was DNA…

    Brad Maltz: But right now, can we get you more of those easy buttons, right? And that’s exactly where something like ACP for Red Hat here, is if you just want to be able to get OpenShift up and running from the factory as quickly as possible with the least amount of hands as possible, you’re looking at things like our solutions like ACP. And the trick is when you look at solutions, are they just white papers, [inaudible 00:04:57], which are really invaluable to certain people?

    Or is it a factory delivered end-to-end platform experience that delivers that Cloud-like experience and developer experience, on top of the infrastructure, plus plus.

    Alan Shimel: Guys, let’s not minimize that, that makes life a lot easier. I mean, I think back to the first DockerCon… It wasn’t the first, but it was the first one in Austin, because before that DockerCon was in Seattle, this is going back a while. And I saw Kubernetes there, I think it was maybe 0.8 was the release, it wasn’t-

    Brad Maltz: It was early.

    Alan Shimel: It was early. I came home, because at the time, we hadn’t launched Cloud Native Now, and before that it was Container Journal, we hadn’t launched it yet, we were still coming up with the names, and we were toying around with names with Docker in it, which would’ve been a mistake… Well on multiple levels.

    But I came home and told the team, I said, “Look, everybody at DockerCon is talking about this thing called Kubernetes, but it’s never going to catch on. It’s so God damn hard, I don’t know how anyone would use it.”

    Brad Maltz: Why do you think you didn’t bet on that?

    Alan Shimel: Well, this is why I still work and I’m not retired, Brad.

    Brad Maltz: Okay.

    Alan Shimel: Yeah… Another brilliant insight from Alan Shimel… So now with that being said, I’ll stand by my original point, Kubernetes is still hard.

    Brad Maltz: Yes,

    Alan Shimel: It is. I don’t care, I’ll work till I die, I guess, but it’s hard.

    Brad Maltz: Kubernetes is hard, and I think… So Kubernetes hit a maturity point, right? So definitely it won.

    Alan Shimel: No doubt.

    Brad Maltz: And everybody needs it. It’s leading the Cloud Native application kind of abstraction battle, so it’s there, but that doesn’t mean you don’t need to be a jack of all trades to be able to understand all the nuances in the abstraction. And you basically have to be able to operate everything under the covers of Kubernetes to make Kubernetes work properly.

    Alan Shimel: Absolutely.

    Brad Maltz: So what is the real long-term easy button? That’s I think an open question right now for Kubernetes. Opportunity.

    Alan Shimel: Absolutely, I don’t want to get [inaudible 00:07:10], maybe the easy button is something other than Kubernetes?

    Brad Maltz: That is always a potential.

    Alan Shimel: Yeah. But let’s get back to our point here though, so now you get Red Hat OpenShift, right?

    Red Hat OpenShift is probably, I guess the most, certainly in the top two Kubernetes platforms, if you will, if you’re using Kubernetes. And it’s still a little hard, right? I mean, you could go download it from Red Hat-

    Brad Maltz: You can get it running, but you’ve still got to have some knowledge behind it to do the basics.

    Alan Shimel: But this is where the easy button comes in.

    Brad Maltz: Yes.

    Alan Shimel: And also, I want to make clear, when we talk about this easy button, a lot of people say, look, why do I get it from Dell? I don’t want hardware, I’m hosting it in the cloud.

    Brad Maltz: But are you? That’s the question. So when people talk about-

    Alan Shimel: I wouldn’t have asked you if it was the… Okay…

    Brad Maltz: With cloud, it’s always, yeah, you have the super easy button in the public cloud, they’ve done an amazing job there. But you get to deal with things like egress fees, you got to deal with things like costs for ongoing costs for a lot of services behind that. And at some point people start to become cost conscious, so that’s one angle that you deal with.

    The second angle, in this new AI world that we’re now officially in as of 2023, you do start to wonder where’s your data living? Where do you want your data to live? And you’ve got the governance compliance side of it. Not security as much, but it’s more the ownership governance. And we’re seeing a lot of people say, you know what, with all those GPUs, there’s a cost and a governance angle to hosting it in my data center, in a Colo, Cloud adjacent and Cloud aware.

    Alan Shimel: Yep.

    Brad Maltz: So that’s where I see things like ACP for Red Hat 100% making sense.

    Alan Shimel: I agree with you 100%. I think there’s another angle here though, and that is this: Unless you’re really in it, and you may not realize this, but Kubernetes on bare metal, Kubernetes in a data center, not in the public cloud, has always been a big component of the Kubernetes footprint.

    Brad Maltz: Yes.

    Alan Shimel: Everybody just assumed, puts the words Cloud Native and Kubernetes Cloud Native, that it’s all in the big three clouds, right?

    Brad Maltz: Yep.

    Alan Shimel: Well, even beyond Oracle, IBM and the rest, but there’s always been a Kubernetes on-prem.

    Brad Maltz: There always has been, and there always will be.

    Alan Shimel: It’ll continue, it will be-

    Brad Maltz: I think it’s going to grow.

    Alan Shimel: Right, well, I think for the reasons you’ve outlined, right? People are worried about control, they are worried about compliance, they are worried about how’s AI play in all this and cost containment and FinOps and everything else.

    So I think that again is an insight that if you’re not really wired into the Kubernetes community, you don’t-

    Brad Maltz: You don’t think about it.

    Alan Shimel: Recognize… Yeah, excellent. Let’s talk about the show a little bit, so you guys are podcasting here live as you said, but what about conversations? I don’t know, I heard today there’s maybe eight, maybe up to eight to 10,000 people or something like that.

    Brad Maltz: Feels like that, yep.

    Alan Shimel: Conversations with people; what are you hearing? What are you seeing?

    Brad Maltz: A lot of the conversations right now are actually… So I’ve had a lot of AI discussions, which-

    Alan Shimel: So do we.

    Brad Maltz: I mean I expected it, but they’re kind of interesting because they’re not just about how do I build AI things, it’s how do I use AI operationally?

    And I think that’s the nuance that I’m seeing CNCF, maybe in the forward-looking view of the world, is how do we apply AI in the operational side of things like Kubernetes and security and all of that. That’s been a handful of, not a large percentage of conversations. There’s always… Actually the easy button thing, honestly, that’s probably been one of the biggest things.

    People are just, they don’t have enough skills out there, and actually one of the other things is Platform engineering. So one of the things you can see on my shirt, right? We have this-

    Alan Shimel: I saw it, I saw it when you came in.

    Brad Maltz: This is our logo that we have here, at Amsterdam, we kind of have this DevOps operating model yin yang where Dev and Ops have to play well together, cats and dogs have to come and be nice.

    Well enter Platform engineering, and these folks building the platforms that are like products inside of the end user environment, they need to adopt and embrace the DevOps operating model in their world. Platform engineering has been one of the buzzwords, I think it has been a big conversation for us here as well.

    Alan Shimel: Absolutely. Hey, just a quick plug for Techstrong, if you don’t mind, on the topic of operationalizing AI.

    We actually, I mentioned to you off camera, we did this hackathon about two months ago at our office with some of the founders of the DevOps movement, around operationalizing AI. And we recorded it-

    Brad Maltz: Oh, that’s awesome.

    Alan Shimel: We recorded all the sessions and we’ve just about got done editing now to make it manageable, and it’ll be out on Techstrong TV, I think in the next week or so. So if operationalizing AI is something you are into, go check that out. Edited, created totally by our Techstrong video team and starring some really cool people, so-

    Brad Maltz: That’s awesome.

    Alan Shimel: Looking to hear that about it. All right, enough of my own plugs. Brad, what else have you got for us?

    Brad Maltz: I mean, right now I think it’s just an exciting time to be in CNCF, in the community, in the industry, right?

    I mean, what’s interesting, I had seen, funnily enough a meme, that popped up in one of my social media threads, it talked about over 2000 years, the acceleration was like: The horse and buggy to the horse and buggy and everything was very flat, and all of a sudden the last 100, 150 years… Right now it feels like this year, and the past of one or two years, technology is accelerating at such a fast rate that we as an industry, can we keep up with it skills wise and people wise and career-wise?

    I feel like going into the next few years, we’re definitely going to have this skills challenge, and I think that’s one thing that I’m going to be focusing on a lot is how do we enable the industry, as technology just keeps evolving around us? I think that’s a big thing personally for me.

    Alan Shimel: So I will tell you, I’m a little older than you, a little… I don’t disagree with you except I think it’s even bigger than… It’s not just about this industry.

    Brad Maltz: Yep.

    Alan Shimel: I think the kinds of changes we’re seeing now is almost akin to when the internet first went public, right? So this is how I divide things, there are technology innovations that have a profound impact on the technology industry. I’ll give you a perfect example, the cloud. The cloud changed a lot of how we do tech, right?

    I mean, your grandma may say, “Where’s your pictures, grandma?”

    And she says, “They’re in the cloud…”

    Whether they were in the cloud or in the server [inaudible 00:14:33] or whatever, it didn’t make a difference to grandma, but it made a difference to us in this industry, we had to know about cloud security and deployments and everything that goes along with cloud and it kind of rocked our world.

    Then there are technology innovations that rock civilization: the internet rocked civilization, think about life before the internet. It’s a very different-

    Brad Maltz: Cell phones.

    Alan Shimel: Cell phones rocked civilization. So there are things that transcend technology markets, and I think we’re in one of those layers right now where things like AI and quite frankly, look, quantum is going to be real-

    Brad Maltz: At some point, it’s just going to magically happen to everybody.

    Alan Shimel: Boom. I read an article last week the very first time they broke RSA 256.

    Brad Maltz: Yeah, I saw that.

    Alan Shimel: With quantum. That’s crazy stuff, if you’re not up on it out there. But I feel like all of these things are converging to create another civilization changing and it couldn’t come at a better time because God knows we need it.

    Brad Maltz: We do. I’m with you, AI is going to be the next… It’s not even going to be, it is the next thing. And one last note on that for me, when we talk about in product management and Dell Technologies land, like our end users are people? Not anymore… The end users of our technology might actually be the AI, so we have to figure out what is the personality of an AI in the future? There’s a lot of things to think about.

    Alan Shimel: What is the AI wanting and looking for?

    Brad Maltz: That’s it.

    Alan Shimel: Nuts. All right. Hey Brad, you know what we didn’t mention? Hey, people who want to go visit the website, what’s the url?

    Brad Maltz: Obviously at dell.com, we have developer.dell.com now, so please focus on developer.dell.com. Go there, you can get all the latest events, newsletters sign up, hands-on labs, you name it. And you can reach out to me on LinkedIn, and if you have any questions, we’ll help you out.

    Alan Shimel: Fantastic. All right, we are live here in Chicago. We’re going to be back with our next guest in a second in KubeCon. Go check out developer.dell.com, and many thanks to Dell Technologies for sponsoring us here at KubeCon. We’ll be back in a minute.

  • KubeCon 2023: CTO.ai’s Developer Control Plane

    KubeCon 2023: CTO.ai’s Developer Control Plane

    Speaker 1: This is Techstrong TV.

    Alan Shimel: Hey, everyone, we’re back. We’re here in Chicago at KubeKon. We’re wrapping up our day two coverage, our last guest for day two. We’ll be back tomorrow, though. But let me introduce you to Kyle Campbell, right?

    Kyle Campbell: That’s right.

    Alan Shimel: Kyle is the founder of cto.ai and we’re going to find out about cto.ai and a little bit about what they’re doing here at KubeKon. But before we do that, Kyle, first of all, welcome.

    Kyle Campbell: Thank you.

    Alan Shimel: Second of all, let’s hear a little bit about Kyle.

    Kyle Campbell: Yeah, thanks.

    Alan Shimel: Tell us your kind of journey.

    Kyle Campbell: Yeah, well, first of all, great to meet you in person. I’ve talked in the past. Yeah, so my journey, I’ve told this story before, a little unconventional. I grew up in Nova Scotia in Canada, a small town. Been on the internet since the age of eight and just had no interest in the formal past. So I’ve been building software from the early days of the .com boom. I may not look at it, but I got some of the scar tissue. But I was self-taught software engineer, so open source was the key to my success and good developer tools.

    Alan Shimel: Sure.

    Kyle Campbell: And I came up through the cloud and open source era and then started founding developer platforms in 2014. The first company I built was a developer platform, the real estate space. Zillow acquired it in about eight months, which was interesting.

    Alan Shimel: Very.

    Kyle Campbell: And then I bootstrapped a DevOps agency quite successfully and started to find that there was a lot of opportunity for next generation developer platforms, which led me to cto.ai.

    Alan Shimel: Excellent, man. What a great story too. You still up in Nova Scotia?

    Kyle Campbell: I’m not. I moved to the other side of the country. I live in British Columbia now.

    Alan Shimel: Good for you.

    Kyle Campbell: Love the outdoors. Spend a lot of time with my son camping, fishing, and trying to get outdoors and just enjoy the beautiful-

    Alan Shimel: Loving it. Yeah, no, it’s beautiful. I mean, not that Nova Scotia’s not beautiful. It’s brutal in the winter, but it’s a beautiful country, part of the country.

    Let’s talk cto.ai now. So look, I’ve founded multiple companies myself. Every founder I’ve ever interviewed or spoken with in 30 years, they don’t just say wake up and say, “Oh, I feel like founding a company today.” There’s kind of like Richard Dreyfuss in Close Encounters of the Third Kind, right? There’s something driving you like, “I got to do this. This needs to get done.” What was driving you that needed to get done here with cto.ai?

    Kyle Campbell: Yeah. I mean, as I described my past, a lot of my journey was self-taught and stand on the shoulders of giants. And really important thing for me was developer experience and ease of use and tooling early on in my career because that enabled me to really drive my competencies as a developer and keep up with these people that had computer science degrees and master’s and all these things, right?

    Alan Shimel: Certainly.

    Kyle Campbell: So when I thought about that and I also thought about where the future’s going and my passion for platform engineering, it became pretty obvious to me that what was missing in the market was a set of tools that were designed to embrace the future of developer experience and how AI can impact that from code to cloud.

    So in 2016 or so, I started experimenting with the idea, and through 2020, I decided to formally launch cto.ai as a developer control plane is what we call it. The way to think about it is it’s a modern CI/CD platform where teams can compose their workflow across build, deployment, test, and preview. And as they work with these tools, they can interact with them in the CLI Slack, GitHub, talk to these workflows through sort of a prompt based model. And we collect telemetry data that allows them to then measure that against DORA metrics, which is-

    Alan Shimel: It’s standard.

    Kyle Campbell: … yeah, it’s a standard and I think, frankly, an empirical way to measure the developer experience. We don’t try to measure developer productivity. We think that’s the wrong question to ask. The question is how do I measure the experience the developer has in the same way that I would measure the experience my users have with my product? And if what we’re doing is building platforms to enable developer experience, we need a natively integrated way to measure that. And we also think that that measurement is a way to pave a future between how the developers experience those tools and how AI can support the developer experience and enhance developers with, frankly, superpowers over time.

    Alan Shimel: So I was recently at a couple of user conferences, big DevOps companies, and it was interesting. Three conferences all use the same metric, which is that developers only spend about 30% of their time developing.

    Kyle Campbell: State of DevOps Report 2018, I think?

    Alan Shimel: But it was in there and it’s been kind of verified in several others. What do you think about that? Is it good thing, bad thing, something to be proud of, something we should be working on? What’s the deal?

    Kyle Campbell: Yeah. Well, I think a pretty practical point of view in that as a software engineer, my goal is to release features that customers love and drive business value. And if I can do that at a higher velocity while maintaining quality, I mean, I think that that is a way that I, as an individual, can contribute to the success of the business and the team.

    But I think what often happens is we get really obsessed about the individual developer. And I think any developer who looks at the idea that they only spend 30% of their time adding value isn’t going to like that very much. And I think we need to reframe the conversation away from developer productivity towards developer enablement and look at the tooling and the process that the developer experience promotes and how developers go from code to cloud and ask ourselves as a business leader, as a CTO who we work with a lot, is the tooling and the workflow that we’re supporting our team with and that developer experience, what they’re experiencing, is that driving results?

    And I think DORA metrics is an empirical way to measure that, obviously, through anecdotes and surveys, but what we’ve really innovated on is creating a vertical integration with the tool chain that allows you to measure that in real time and then iterate on the tools quickly. And some of the teams can really own that themselves. And what the businesses should be doing is zooming out and asking themselves, “Yeah, how do we maximize the amount of time developers spend without individualizing that consideration?” There’s an innerloop and there’s an outerloop. And what DORA is really good for is measuring the outerloop of how we work in aggregate of teams. We need next generation platforms that make this data and this context more accessible to business leaders.

    Alan Shimel: I don’t disagree with anything you said there, so we’re there with that. What about have you guys released any news or anything? What do you got going on around the show?

    Kyle Campbell: Yeah, so for the last while, we’ve been focused on really building a rock solid workflow and tooling to basically set the premise of that next generation composable CI/CD vision. We’ve fed that data into DORA Metrics. You can now report on DORA metrics in real time, save those reports, share them with whoever one-on-ones, retros, so kind of up to you. And we’re starting to experiment with some data science, but something that’s really exciting that we just kind of put into production last week. We haven’t really officially announced, so I guess this is a first is we’ve released our first kind of AI-

    Alan Shimel: Heard it here first.

    Kyle Campbell: … yeah, heard it here first. Our first AI feature set, which is AI code review. And what we’re doing is we’re letting teams start with these sort of base models for how they can leverage AI in the code review process to get developers’ feedback earlier. But then, we want them to be able to do is enhance that model to really customize it to their preferences on their own kind of hardware, to customize those models to take into consideration their own specialized requirements and obviously protect proprietary information that’s so core to their beliefs. So we launched that into production, announcing it here first.

    Alan Shimel: Really?

    Kyle Campbell: And we’re looking for early adopters who can kind of test it out and help us stress test it and figure out how do we further enhance the context of that model with some of the information that is derived in these DORA metrics as well.

    Alan Shimel: So here, we’re talking to this camera. Developers out there. You’re looking for them to kick this around a little bit. Kick the tires.

    Kyle Campbell: That’s right. Yeah.

    Alan Shimel: How do they do it?

    Kyle Campbell: You’re a developer and you’re interested in how AI can support your CICD workflow, specifically code review, come over to cto.ai, sign up, send a message. I’d love to talk to you personally, software development yourself, and love to hear what you think, what you think are the limitations and hesitations, and more importantly, how do you think we can enhance this with other use cases? Because I think there’s a whole exciting set of use cases for AI and software delivery that is going to help software developers.

    Alan Shimel: Absolutely.

    Kyle Campbell: We embrace-

    Alan Shimel: I had this conversation in an earlier interview today. Look, for people who aren’t tech, you show them an AI interface and some of the kind of parlor tricks it could do and they think it’s magical.

    Kyle Campbell: Yes. Arthur C. Clark.

    Alan Shimel: Right.

    Kyle Campbell: Yeah.

    Alan Shimel: Now, we know it’s not magic. It’s just putting one word in front of the other or one… but there are some uses that AI really shine certain. So it’s not meant to replace Google Search nor is it meant to replace software developers.

    Kyle Campbell: No.

    Alan Shimel: But it can empower software developers to be 10x more effective. And one of the ways it could teach you to code, right? You could put code in there and say, “Explain it to me.” It could review code, right? So either it’s writing code or it’s reviewing code. You shouldn’t have it doing both probably, but…

    Kyle Campbell: It’s true.

    Alan Shimel: Right. But if it’s using it for review, what a great use of the technology.

    Kyle Campbell: Yeah. We’ve seen that the number one thing that slows down time to market in feature sets for developers is waiting for code review. And while I’m not sure that it’ll be the same thing as you and I pair programming and getting into the nitty-gritty details, if we can make sure that every developer can get a code review instantly just by adding a label and then that we can tailor the quality of that code review with more context that is supported by how the team thinks about quality. I think this is an important example of how we can accelerate the needs of developers and the developer experience with AI that still leaves all the control in the hands of the developer to decide, “Is this rational? Is this a hallucination? Is this the appropriate time?” But the feedback loop that we can get from this is, I think, a really great beachhead and why we chose to start there.

    Alan Shimel: Absolutely. And we’ll see. I don’t think we scratched the surface yet on how we’re going to use AI, but this is certainly a real definitive first step that I see us going with, right?

    Kyle Campbell: I think so. And I think the call to action for other software vendors out there is to think about reinstrumenting what they’re offering to prepare for this because I think there’s a necessary hesitance around AI. I think rightly so. But if we can think about how we can take control of it, how softwares can take control of it. Software engineers are perfectly suited to be some of the first stewards of these problems. Just like we see AI and code generation, I think the next natural step is to support it within code review. And then we’ll start looking at how smarter deployments, smarter rollbacks, and obviously, operations can be enhanced with AI. And this place is a perfect example of people trying to solve that problem.

    Alan Shimel: Absolutely. Absolutely. And here’s the other thing. I’ve been in technology a long time. You don’t put these genies back in their bottles.

    Kyle Campbell: Right.

    Alan Shimel: Once they’re out, they’re out. And so like it or not, they’re here. And I think you could… if you can’t beat them, join them.

    Kyle Campbell: You can’t stop Moore’s Law. I mean, this the pathway that the world is on.

    Alan Shimel: No, you’re not. You’re just not going to stop it. That’s the way it is. It’s great stuff, man. I love the attitude. I love having you on here. Cto.ai. Again, if you’re looking to help Kyle out, kick the tires on this AI code review product they got coming on, it’s fantastic. So let’s check it out.

    Kyle Campbell: All right. Thank you so much.

    Alan Shimel: All right. Hey, Kyle, enjoy the rest of your KubeKon. cto.ai wrapping up day two in Chicago at KubeKon. We’re going to be here tomorrow morning. I think we’re on at 10. We’re only here till two tomorrow because it wraps early tomorrow. But we’ll be back with a full load. We hope you’ve enjoyed today. On Demand is available at Techstrong TV. And so if you missed anything, do check it out. This is Alan Shimel. We’re out.

  • Atlassian Delivers on Generative AI Promise for DevOps and ITSM

    Atlassian Delivers on Generative AI Promise for DevOps and ITSM

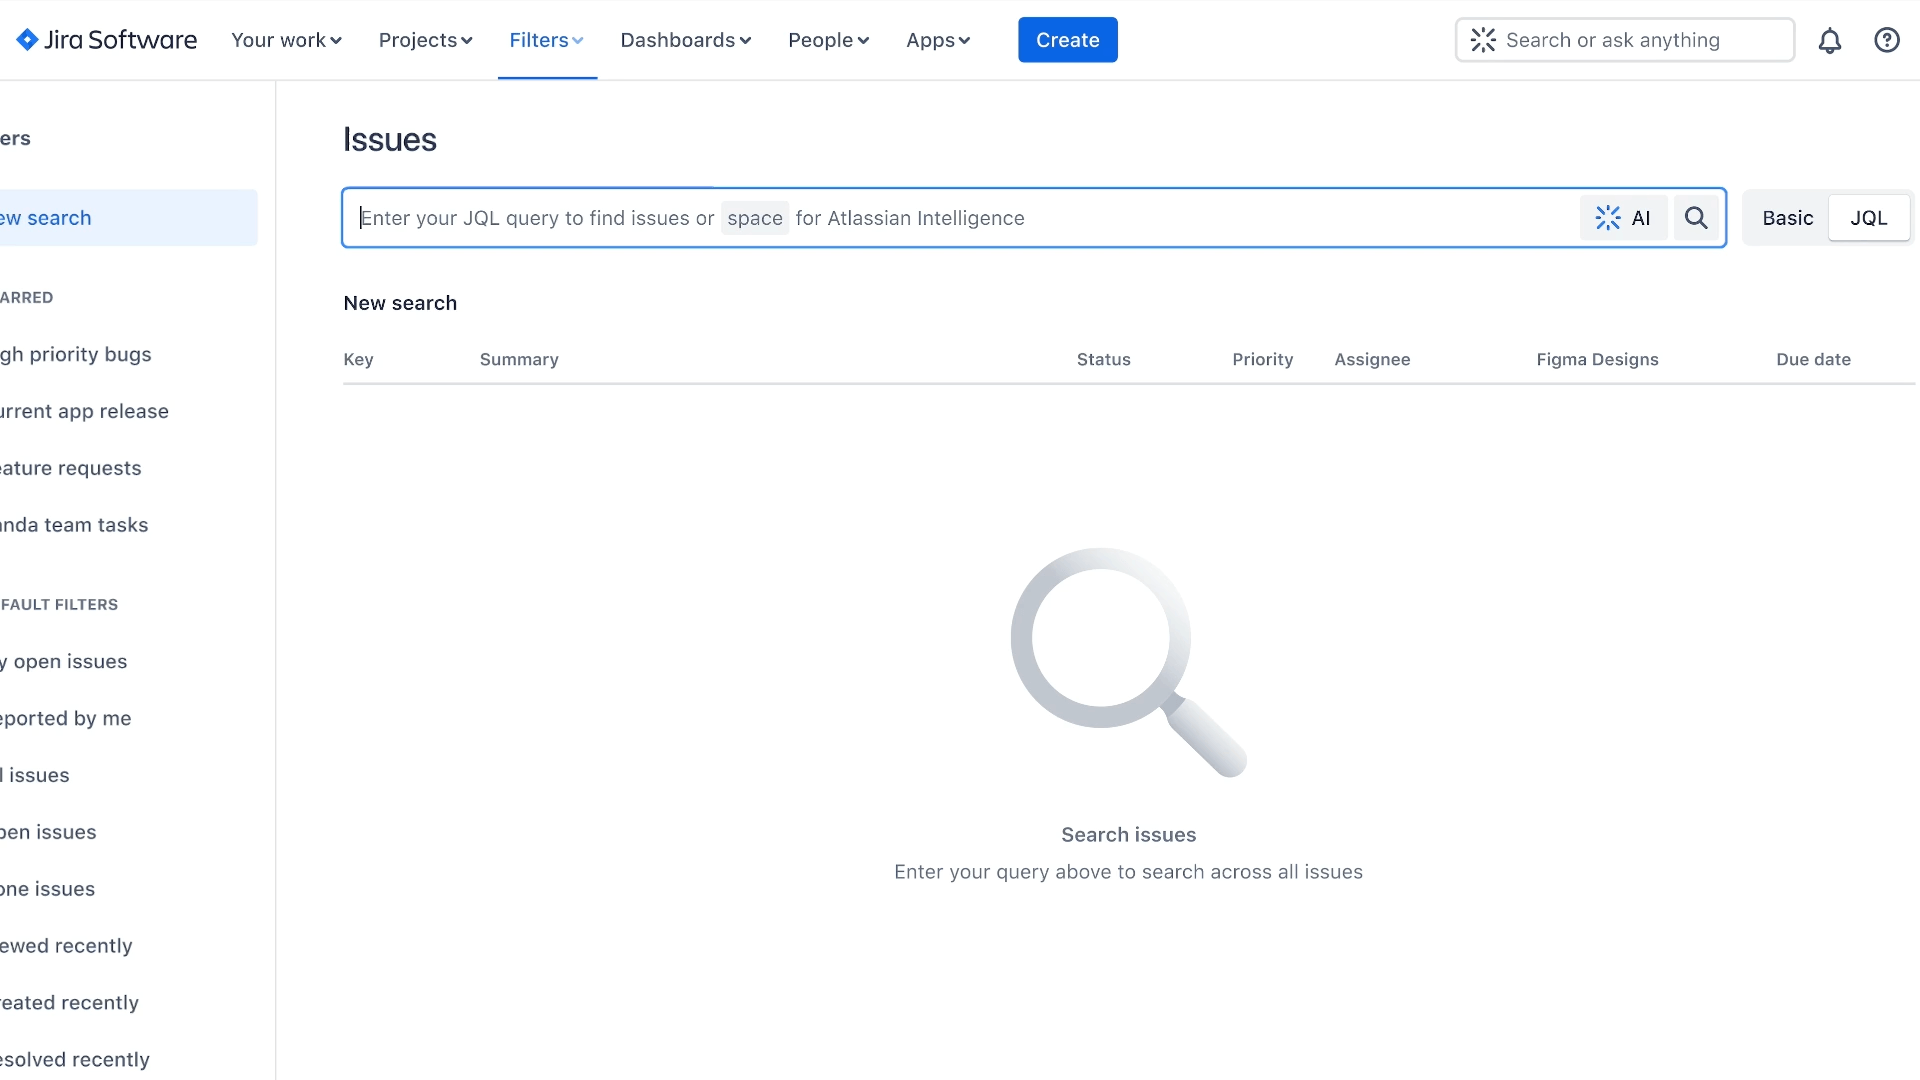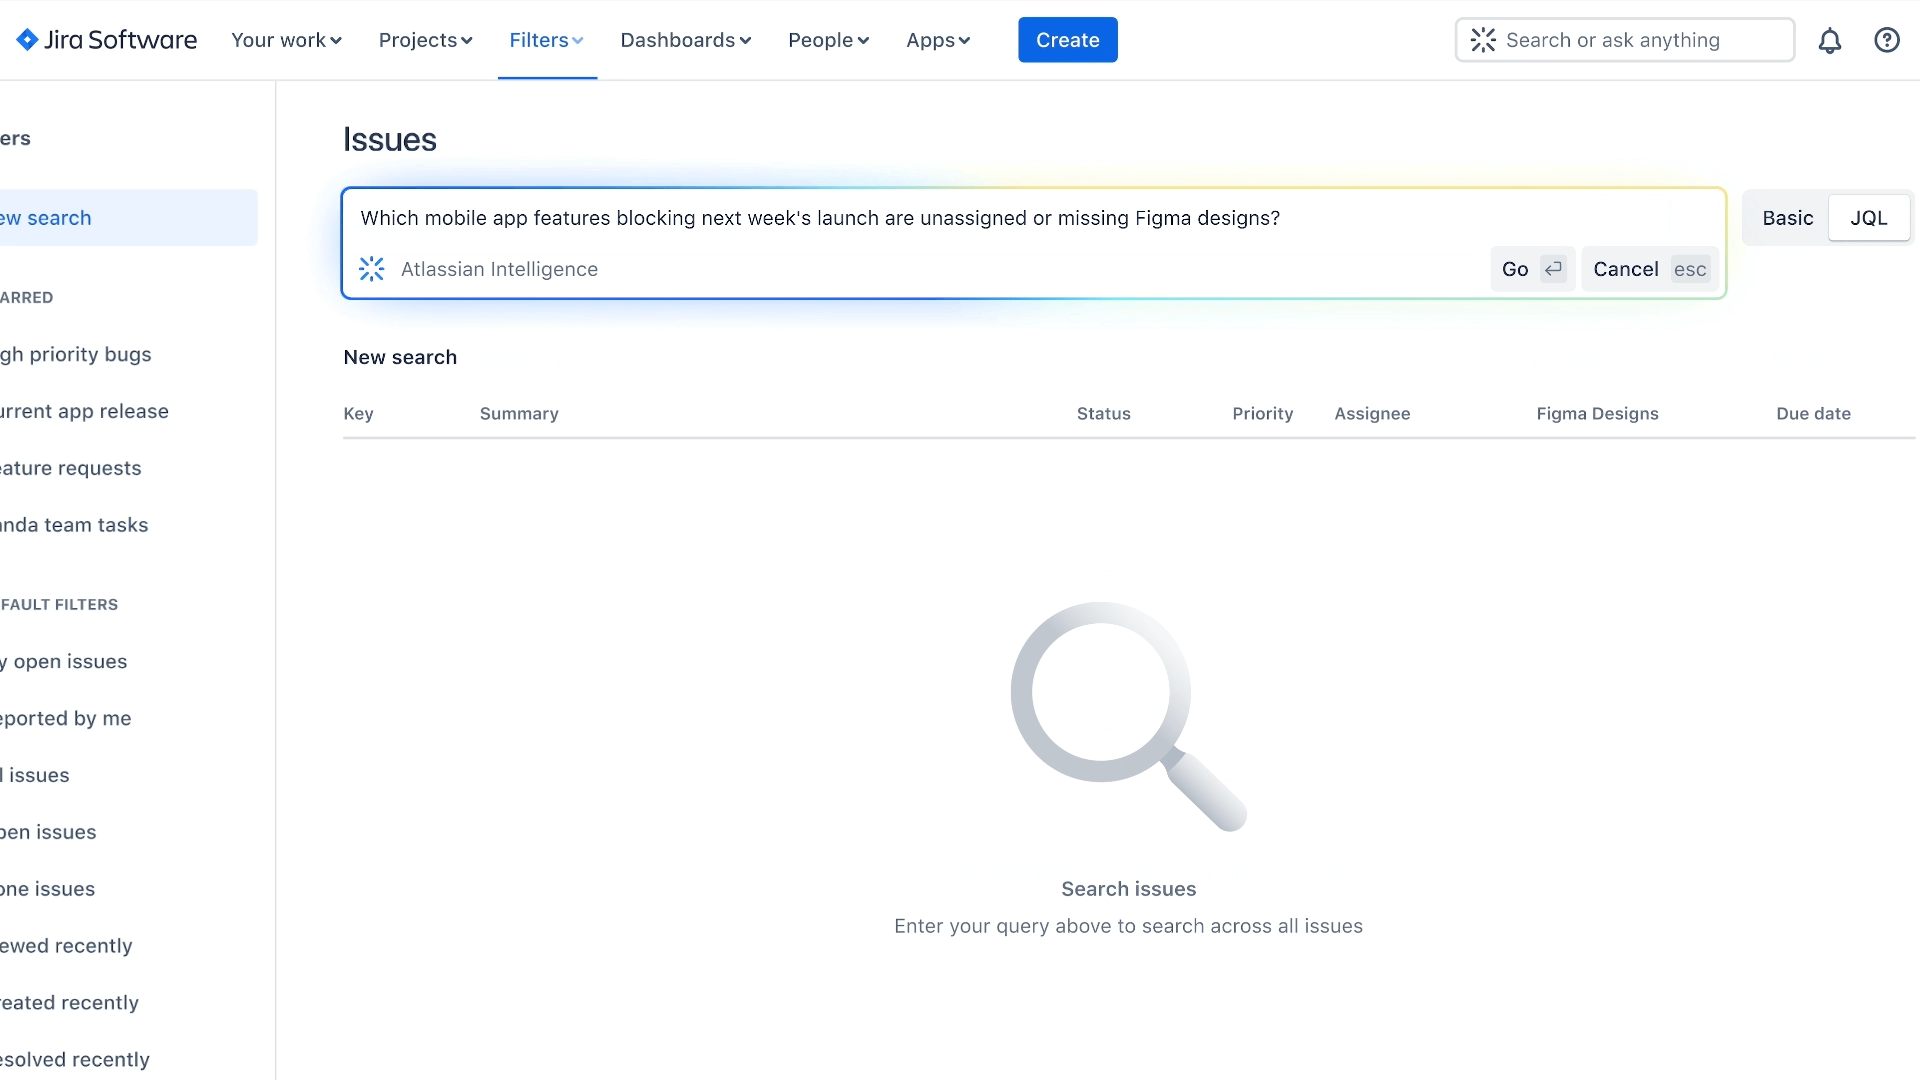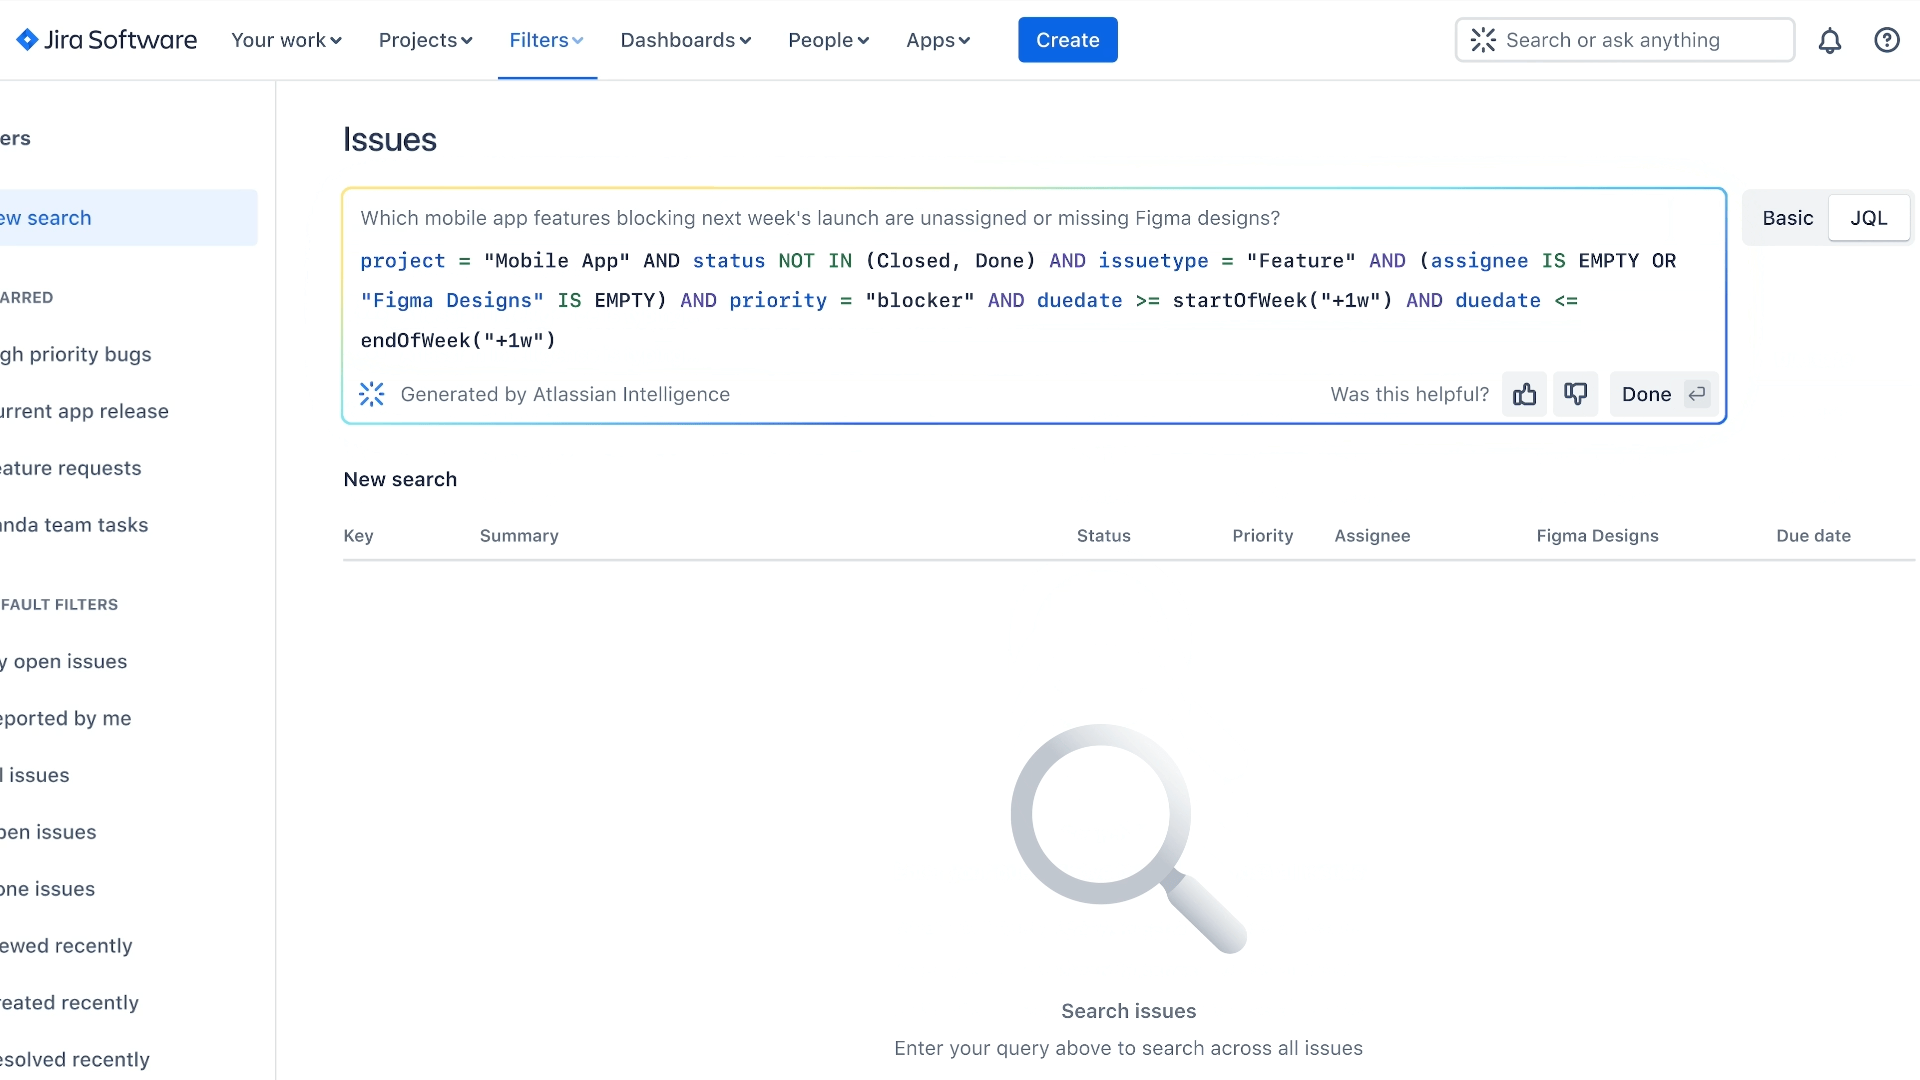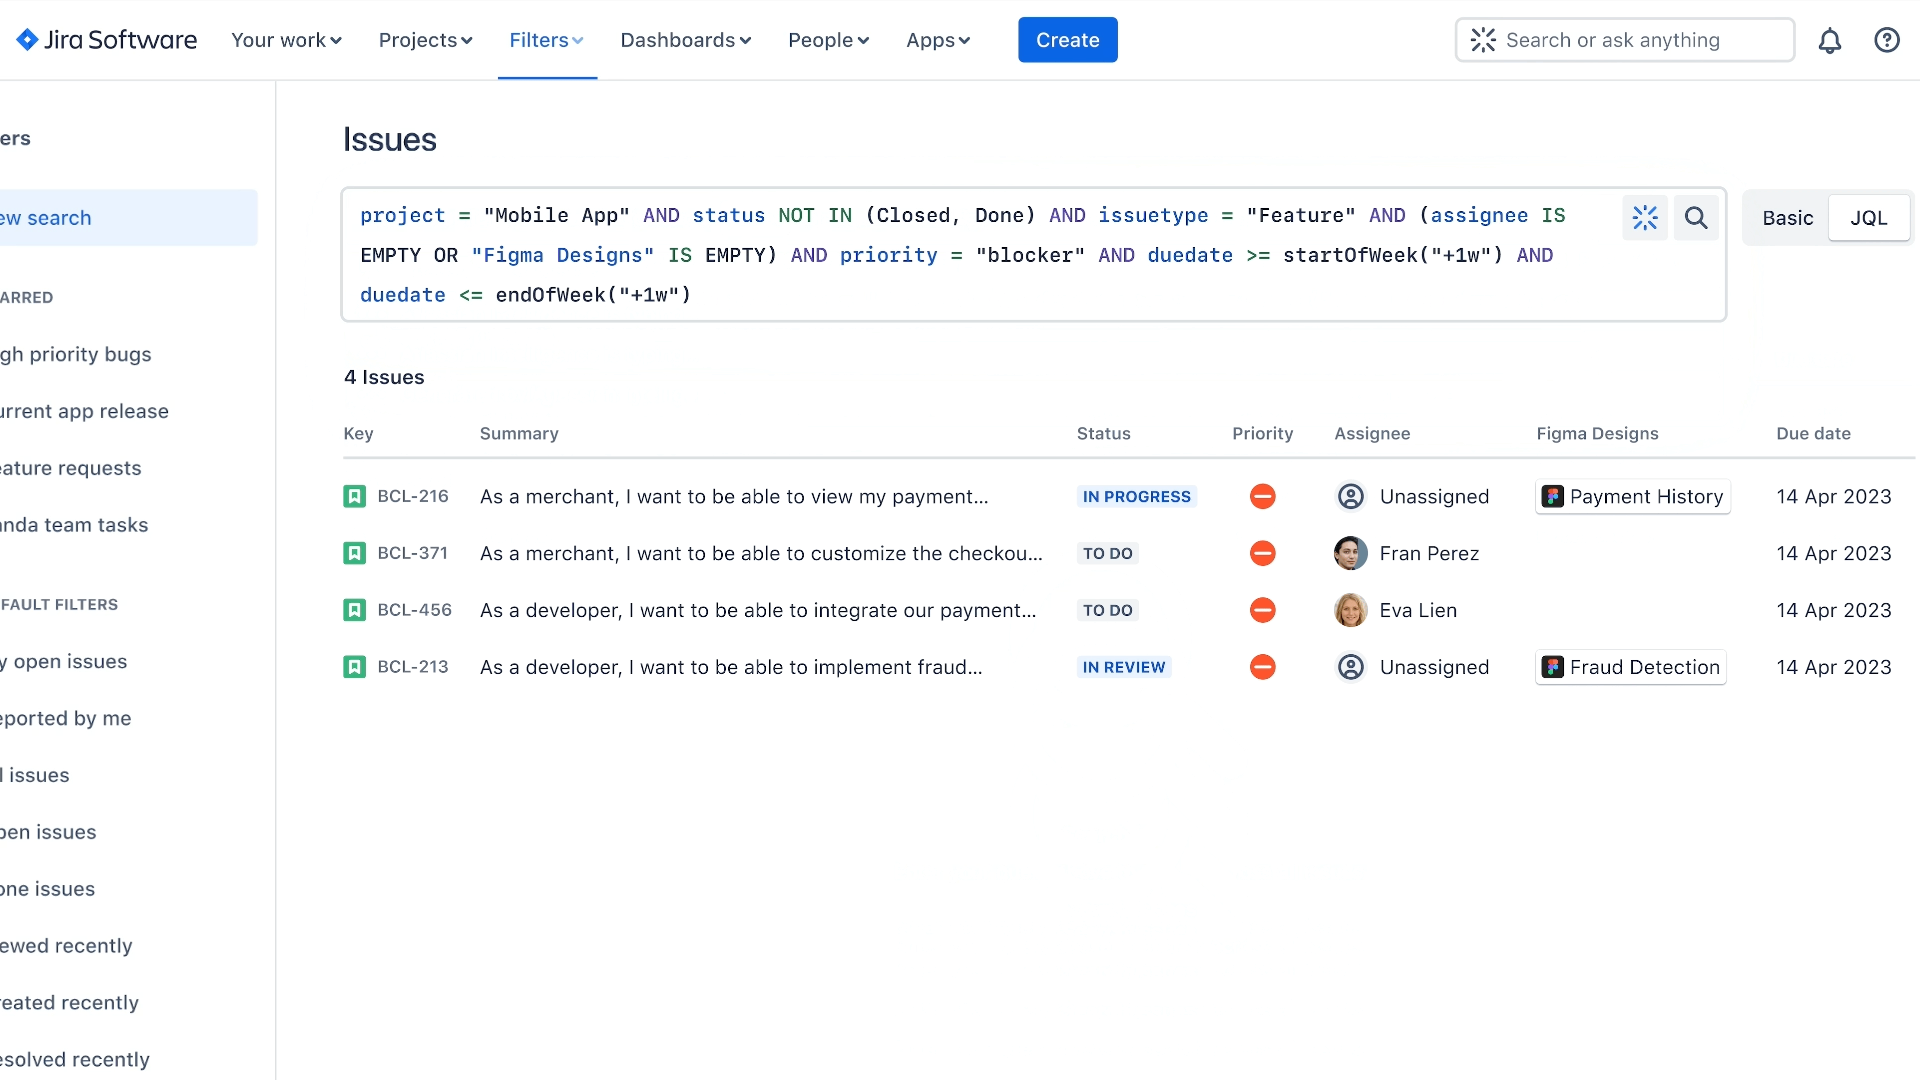
    During a virtual Unleash event, Atlassian today announced its generative artificial intelligence (AI) capabilities are now generally available across its Jira and Confluence suite of tools for managing IT and DevOps workflows.

    In addition, Atlassian also committed to adding generative AI capabilities to its Bitbucket continuous integration/continuous deployment (CI/CD) platform to enable DevOps teams to review pull requests and leave comments automatically with suggested changes around syntax and code conventions via a natural language interface. Developers will also be able to autogenerate pull request descriptions from commit messages.

    Matt Schvimmer, head of products for the Agile and DevOps division of Atlassian, said the capabilities provided by Atlassian Intelligence will reduce the level of toil and stress DevOps teams experience at a time when the velocity at which applications are being developed and deployed only continues to increase.

    Atlassian reported nearly 10% of its more than 265,000 customers have already leveraged Atlassian Intelligence since the launch of the beta program. Organizations, for example, can instantly create user stories within Jira Software tickets, change the tone of a customer response within Jira Service Management, create summaries, launch workflow requests via prompts and generate a starting point for a test plan in Confluence.

    Natural language capabilities, currently available for Confluence, will shortly be generally made available for Jira. An ability that promises to help demystify company-specific concepts, jargon or acronyms is also available now in beta, with support for Jira Software and Jira Service Management to shortly follow.

    There is little doubt at this juncture that AI will be pervasively applied across both ITSM and DevOps workflows. As those advances are made, it should also become feasible to reduce the level of toil these teams regularly encounter. At the same time, the level of scale at which ITSM and DevOps workflows can be effectively managed should also increase substantially.

    Each organization will need to decide how quickly to incorporate AI into those workflows, but hopefully, the level of burnout experienced by IT personnel will be sharply reduced as more tasks are automated. Less clear is the impact AI will have on the size of IT teams required to provide those services, but for the foreseeable future, there will always be a need for some level of human supervision.

    In the longer term, the war for IT and DevOps talent that has been waged now for multiple decades should diminish as managing these workflows becomes more accessible, noted Schvimmer. Organizations will not need to rely so much on the expertise of a handful of specialists, he added.

    Organizations, however, would be well-advised to make sure AI is embraced from both the bottom up and the top down to ensure optimal adoption, said Schvimmer.

    In the meantime, IT teams should take an inventory of the processes that are likely to be automated by AI today with an eye toward restructuring teams as more tasks are automated. Ultimately, the goal should be to let machines handle the tasks they do best to enable the IT staff to provide services that deliver more value to the business.