Category: Application Performance Management/Monitoring

  • Bionic Extends Application Security Posture Management Platform

    Bionic Extends Application Security Posture Management Platform

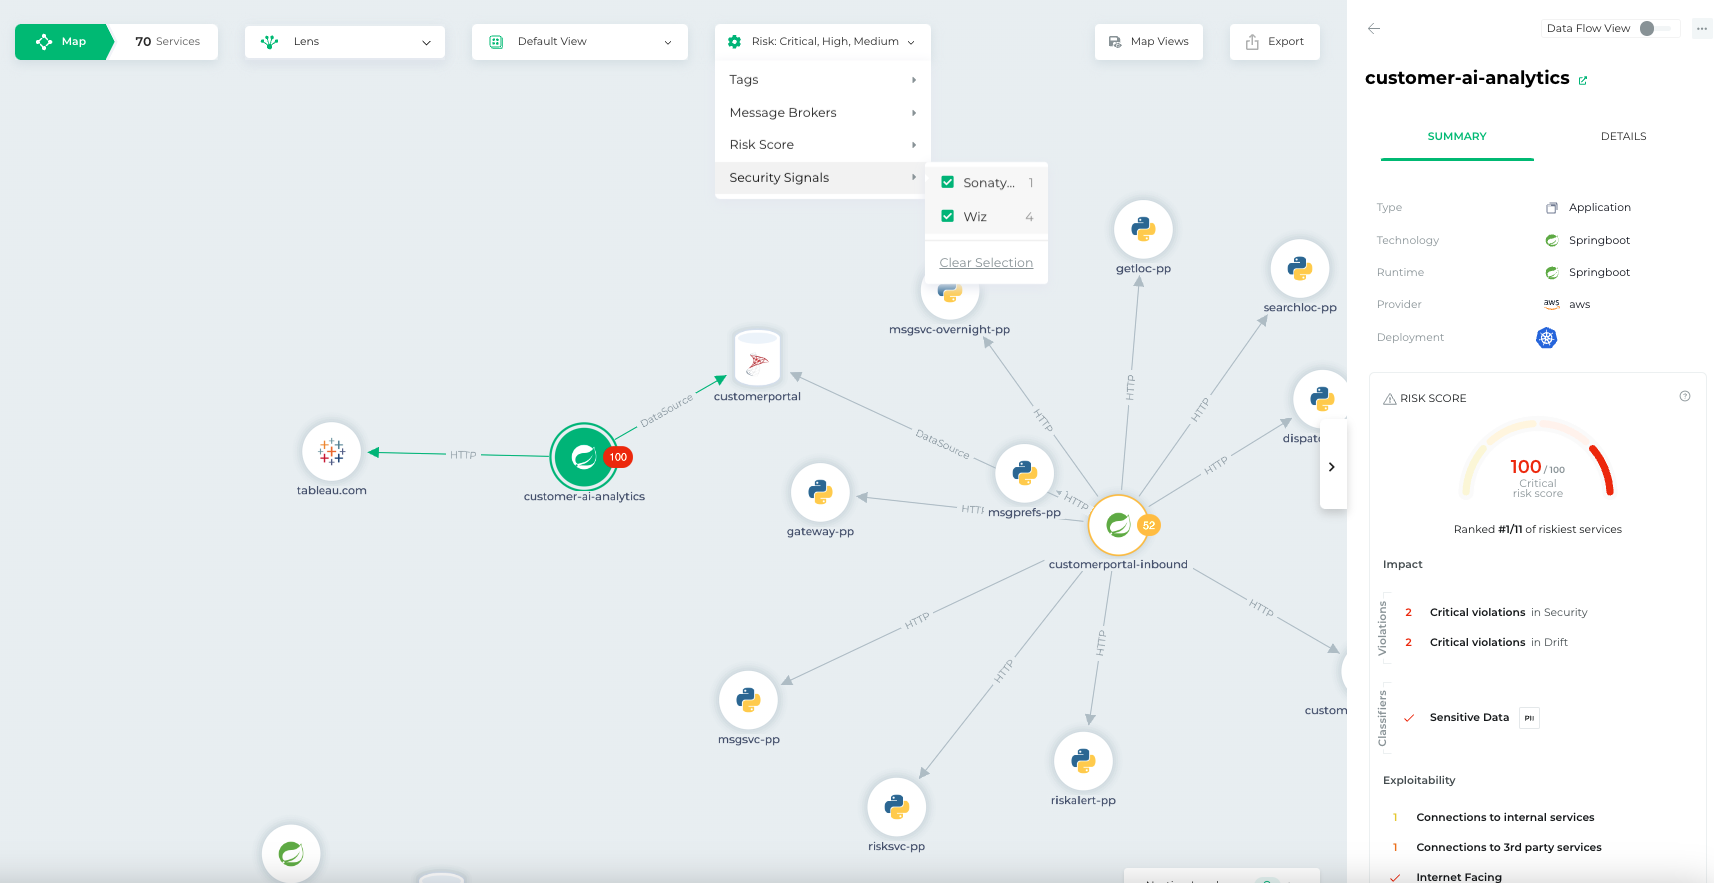
    Bionic this week added a pair of tools to its application security posture management (ASPM) platform that make it simpler to triage threats based on severity and attach a risk score.

    Josh Cho, senior director of global systems engineering at Bionic, said the Bionic Signals and Business Risk Scoring tools ingest data from third-party security tools to provide analytics capabilities. The first two vendors with which Bionic has integrated its ASPM platform are Wiz and Sonatype.

    The goal is to partner with additional vendors that provide unique cybersecurity capabilities that don’t compete with one another, said Cho.

    The agentless Bionic ASPM platform enables organizations to manage application risks by continuously collecting data from services and their dependencies, application programming interfaces (APIs) and DevOps data flows both in pre-production environments and after applications are deployed. Bionic then assesses any changes made to those environments based on a set of cybersecurity policies it provides. If an issue is discovered, the platform will create an alert informing the appropriate development team of best practices that eliminate the issue.

    While there is a lot of effort being made to shift more responsibility left toward application developers, there is often not enough cybersecurity context provided, said Cho. Bionic’s ASPM platform aggregates data from multiple tools to enable DevSecOps teams to better prioritize their remediation efforts, he added.

    It’s not clear how much organizations have embraced DevSecOps best practices, but one of the issues that needs to be addressed is the often-conflicting alerts generated by the various tools being used. Bionic is making a case for an ASPM platform that synthesizes data from multiple sources to streamline DevSecOps workflows.

    One way or another, more organizations will be embracing DevSecOps to better secure their software supply chains as more regulations are mandated. The challenge they face today is that most application developers—and the DevOps teams that support them—don’t have a lot of cybersecurity expertise. As a result, it becomes difficult to discern which vulnerabilities require immediate attention and which can be addressed in a regular update. In some instances, an alert generated by a cybersecurity team may not even been relevant—because the application in question is not internet-facing or the impacted module has not been loaded.

    In fact, it’s that very lack of context that often results in application developers disregarding the alerts generated by cybersecurity teams. Whenever there is a breach, however, cybersecurity teams always demand to know why their alert was ignored.

    No developer, of course, deliberately sets out to build and deploy vulnerable applications. In the race to meet delivery deadlines, there are always going to be tradeoffs. The issue then becomes keeping track of the cybersecurity technical debt that accumulates over time. An ASPM solution provides a means to keep track of that debt to enable DevSecOps teams to keep the risk in perspective.

  • How to Avoid Risk When Using Multiple Low-Code Platforms

    How to Avoid Risk When Using Multiple Low-Code Platforms

    Organizations are still increasing their use of low-code/no-code (LCNC). But this adoption isn’t always consolidated around one tool—frequently, multiple low-code/no-code platforms are used under the same roof. In fact, Gartner predicts that by 2024, 75% of large enterprises will be using at least four low-code development tools for both IT application development and citizen development initiatives.

    Utilizing multiple low-code/no-code platforms simultaneously introduces some security concerns. This is partially due to a lack of standard policies to govern different platforms in the same way. Low-code platforms are often incompatible with traditional IT security processes, like vulnerability scanning, manual code reviews and runtime security monitoring. Organizations going all-in on citizen development need safe ways to use low-code/no-code platforms. So, how can they safely enable this innovation without hindering productivity?

    I recently met with Michael Bargury, CTO and co-founder, Zenity, about securing LCNC systems. Bargury, who oversees the OWASP Low-Code Top Ten list, has significant insight into both the benefits and drawbacks of low-code/no-code platforms. Below, we’ll review the potential risks of using multiple low-code platforms and consider ways to mitigate these concerns.

    Why Companies Have Multiple Low-Code Platforms

    Interest in low-code has been rising, and low-code/no-code adoption continues to accelerate across enterprises. According to Bargury, large enterprises often don’t get a choice in the matter—low-code tools are arising organically, and it’s challenging to keep a lid on their proliferation.

    One way this occurs is that low-code becomes embedded into the SaaS platforms everyone already uses. Software platforms integral to business operations, like Salesforce, Microsoft Office and ServiceNow, have arguably mutated into low-code platforms, making them more like cloud providers than SaaS vendors, said Bargury.

    The other way low-code platforms emerge is through bottom-up transitions, says Bargury. This could be a specific knowledge worker working in a subset of the business to automate a domain-specific operation or integrate various tools. Then, there are the platforms, like OutSystems, Mendix or Mulesoft that specifically target professional developers.

    Organizations going all-in on citizen development may build a center of excellence and focus efforts on a single platform. And low-code platforms targeting developers will sometimes encourage more consolidation. Yet, “different platforms solve different use cases better,” explained Bargury. As a result, you will usually have a few converging in the same enterprises.

    Potential Security Concerns of Multiple Low-Code Platforms

    The emergence of low-code is similar to the bring your own device (BYOD) movement. IT and security leaders fought to avoid it at one point, but nowadays, everyone does it. So, what are the security implications if low-code becomes similarly ubiquitous? Well, no matter how it’s generated, low-code-bred programs are still applications susceptible to the same logical problems. And unfortunately, compared to your typical traditional code development life cycle, low-code development is fraught with discrepancies, says Bargury.

    Immature CI/CD Pipelines

    Some platforms do not offer the kind of mature CI/CD process one would expect from a software development platform. For example, there may be no way to create tests or separate your environments. Since there’s no coherent and consistent way to push code from development into production, you lack a way to apply secure development across platforms. “You don’t have a way to ensure every piece of software is up to your standards,” said Bargury.

    Opaque Underyling Codebases

    In traditional software development, you apply your own security reviews to ensure applications don’t contain risks. This includes shift-left scanning, security gates, manual reviews to catch mistakes early on and runtime scanning to catch unknown vulnerabilities in production. But there aren’t always parallels in low-code development. Low-code solutions typically have their own way of doing things with fewer standards, and they avoid exposing the underlying code and Git, said Bargury.

    Lack of Visibility

    As such, with low-code obfuscation, you lose a degree of visibility into how an application runs. Logs may be insufficient or wholly inaccessible. It’s also tricky—or at times impossible—to set up runtime monitoring, let alone scan various platforms. This means that low-code users can’t leverage powerful observability tools to identify errors and remediate security holes.

    Lack of Unified Policies

    Finally, establishing common authorization and permissions across multiple low-code development platforms is another hurdle. Since low-code vendors have their proprietary building blocks, you’re unable to leverage something like OPA or Kyverno to create and unify policies. Lacking shared policies across tools makes it challenging to verify that best practices have been implemented, says Bargury.

    How to Secure Multi-LCNC

    Low-code can grant much creative potential. But, knowing the above risks, what should IT be doing to reduce risks around low-code—especially when using multiple platforms? Well, Bargury shared several steps to help cybersecurity leaders start safely addressing the emergence of increasingly low-code capabilities.

    1. Take low-code development under the application security umbrella. First, low-code must be brought under the security umbrella, if it isn’t already. “It should be part of their mandate,” said Bargury. Shift the responsibility to professionals well-trained in resolving threats.
    2. Understand your surface area. As a basic security tenant, you can’t secure what you don’t know. Thus, Bargury recommends increasing your visibility into each low-code platform by collecting logs when possible and centralizing your analysis.
    3. Create automated guardrails. Next, it’s critical to identify your risks and set guardrails for your low-code users—especially when citizen development is involved. The OWASP framework provides a good overview of common risks and mitigation advice across robotic process automation (RPA), integration and low-code. In general, it’s important to design permissions with the rule of least privilege in mind. This can help reduce the chance of vulnerabilities like LCNC-SEC-03: Data Leakage and Unexpected Consequences and LCNC-SEC-01: Account Impersonation.
    4. Address gaps within the development life cycle (SDLC). Lastly, low-code platforms often provide the building blocks to secure applications, but it’s still up to you to ensure they are safely used. Cybersecurity teams should continually audit the low-code SDLC to ensure holes don’t persist.

    You’re Responsible for Securing Low-Code Development

    Low-code development platforms aren’t 100% safe from harm. It’s not out of the question for hackers to abuse low-code platforms and turn them against their owners. For example, Microsoft’s Detection and Response Team (DART) reported how a hacker group used entry to a low-code tool to remain hidden within an organization for six months, using credential stuffing to access an administrative account. By creating automations, they were able to use internal discovery tools and exfiltrate secrets and data that could have been used for privilege escalation.

    As you can see, there are legitimate concerns for low-code, especially at scale. However, security responsibility is not always that transparent. To date, there isn’t an equivalent of a shared cloud responsibility model in the realm of low-code development. As such, at the end of the day, you need to take the reins to own the applications that you build and ensure everything is secure.
  • Cycloid Adds Templates to Simplify GitOps Workflows

    Cycloid Adds Templates to Simplify GitOps Workflows

    Cycloid today added a Bootstrap Stacks capability that provides DevOps teams with the ability to build Git templates or use ones created by the company to define cloud computing environments.

    The capability is accessed via a portal added to the Cycloid platform for automating software delivery. It also makes it simpler for DevOps teams to reuse templates that are compatible with Terraform or Kubernetes environments as needed.

    In the months ahead, Cycloid plans to release Headers, a metadata tool that automatically populates project parameters in display pages and a project management tool to provide a unified view for each development environment, including continuous integration/continuous delivery (CI/CD) pipelines, documentation, automation, logs, cloud costs and carbon emissions.

    Cycloid founder Benjamin Brial said the templates provide a layer of abstraction that makes it simpler to implement GitOps workflows. As a best practice, GitOps enables DevOps teams to unify the management of code to provision IT infrastructure and software delivery. However, providing access to a Git repository alone is insufficient, said Brial. DevOps teams need access to a set of templates that automate the process and eliminate what is otherwise a complex set of tasks, he noted.

    Easily discovered templates also eliminate organizations’ tendency to create redundant automations simply because a development team was unable to find an existing framework that another team already created, added Brial.

    That approach also enables DevOps teams to more easily embrace platform engineering principles to centralize the management of DevOps using a Bootstrap Service catalog embedded within the Cycloid platform, said Brial. That capability makes it possible to enforce GitOps policies in a way the developers will have to respect because the automation frameworks are readily available, he added.

    It’s not clear whether organizations are embracing platform engineering. Historically, adoption of DevOps workflows in most organizations has tended to flow from the bottom up. As a result, it’s fairly common for multiple application development teams within an organization to have adopted multiple DevOps platforms to manage workflows. Advocates for platform engineering are making a case for eliminating many of those redundant platforms in favor of a corporate standard.

    At the core of any approach is the assumption that centralization will reduce costs by eliminating redundancy. Issues can arise, however, when centralization results in loss of flexibility. Many of the teams that adopt DevOps want to be able to add and replace tools as they see fit. If there is a corporate standard that narrows their tool options, it’s just a matter of time before those teams start to look for ways around the corporate standard.

    Each organization will need to strike a balance between flexibility and the need to bring some order to DevOps workflows. In the meantime, however, the pace at which multiple software development initiatives are being launched is likely to force a platform engineering conversation that, in many cases, many organizations have postponed longer than anyone cares to admit.

  • Quali Adds Governance and Cloud Cost Control Tools to Automation Platform

    Quali Adds Governance and Cloud Cost Control Tools to Automation Platform

    Quali today revealed it added governance and cloud cost management tools to its Torque platform for automating IT infrastructure management.

    David Williams, senior vice president for market strategy at Quali, said the added governance tools will make it possible to enforce security, compliance and consumption policies as IT environments are launched using the automation blueprints that Torque enables IT teams to create.

    At the same time, IT teams can now also define consumption policies based on cloud runtime or regions employed within a cloud computing environment. In addition to taking advantage of dashboards to visualize consumption of cloud resources, IT teams can also use Torque to identify cloud waste including detached, inactive and overprovisioned instances. They can pause, right-size or tear down environments to reduce costs and eliminate the possibility of a billing surprise at the end of the month, noted Williams.

    Torque also enables IT teams to detect drift and then update live cloud environments to remediate any that fall out of scope, he added.

    Quali has been making a case for an environment-as-a-service approach to managing IT. That approach is based on a set of triggers for controlling infrastructure via a software-as-a-service (SaaS) platform that can be invoked either via an application programming interface (API) or a graphical user interface (GUI).

    In addition to providing a set of infrastructure provisioning guardrails that prevent mistakes from being made, Torque makes it possible to automatically deploy complete application environments on top of infrastructure provisioned as code using blueprints rather than relying on low-level Terraform scripts. The goal is to increase developer productivity by enabling IT teams to create self-service portals that developers can use to spin up environments.

    That approach is becoming more appealing as many organizations begin to adopt platform engineering as a method to centralize the management of DevOps workflows, noted Williams. In fact, as part of that effort, many organizations are starting to unify the management of cloud and on-premises IT environments, he added.

    While many developers routinely provision IT infrastructure using tools such as Terraform, many of them lack the cybersecurity expertise required to ensure cloud computing environments are configured properly. Developers also tend not to remember to de-provision cloud resources when no longer needed; over time, those factors contribute to unnecessarily increased cloud costs.

    Ultimately, the goal is to find ways to centrally manage IT environments to reduce costs and improve cybersecurity without inhibiting the pace at which developers are building innovative applications, said Williams.

    At the same time, as application environments become more complex, it is becoming even more challenging to provision and manage IT environments at a time when many organizations are reluctant to hire additional IT staff, he noted.

    One way or another, IT environments will become more automated. The issue is determining how best to organize the IT teams managing those environments as tasks that once required a lot of manual effort are increasingly automated.

  • Leaders in Resilience See ROI From Observability

    Leaders in Resilience See ROI From Observability

    Observability is maturing throughout the software industry. Observability is often defined as merging metrics, logs and traces to get a fuller picture of an application’s state. This can help pinpoint disruptions or security incidents and offer a clearer path to remediation. Observability is touted to advance the application monitoring practices of yesteryear, but are investments paying off?

    According to recent findings, many organizations are using observability tools and seeing a positive outcome. A full 73% of organizations reported using observability tools for over a year. And impressively, 86% of observability leaders said the ROI on their observability tools has exceeded their expectations. The practice appears to be paying dividends for organizations that have gone “all-in” with mature observability processes.

    The State of Observability 2023 report released by Splunk demonstrated how observability leaders are reaping a positive return from observability tools. According to the report, observability is helping to meet performance expectations, avoid downtime and enhance resilience in general. However, not all organizations are on the observability maturity bandwagon. Below, we’ll examine some of the key trends from the report and consider the benefits of refining your observability efforts.

    Now that observability is more commonplace, dedicated roles are emerging to support these initiatives. In fact, 87% of respondents now employ specialists who work exclusively on observability projects. Site reliability engineers likely make up a portion of these experts, as observability data can be used to advance efforts around meeting service-level objectives (SLOs).

    But although observability might be more common than a few years ago, not every observability practice is mature or standardized. Just 40% have a formal approach to resilience that has been institutionalized organization-wide. Because of this, only 43% are confident in their team’s ability to meet its application reliability and performance objectives. It should be noted that this number increases significantly for those with more mature observability adoption, which we’ll expand on below.

    Furthermore, not all applications are cloud-native. Organizations reported operating and maintaining, on average, 165 internally developed business applications, half of which are hosted in the public cloud and half of which are on-premises. Due to the persistence of legacy modalities, observability tools must continue to support a hybrid architecture if they are to be comprehensive and useful.

    And although we’ve previously covered how many organizations are drowning in a sea of observability data, observability leaders now say their ROI on observability tools far exceeded their expectations. Perhaps this indicates that, with more open standards, analysis centralization and fewer false positives, teams are finding ways to avoid observabiliy tooling sprawl.

    Lastly, the report unveiled desires to loop AI and ML into the observability pipeline. In fact, 66% of observability teams already use AI/ML, while 26% are in the process of deploying the technology. And 91% said AIOps is an important enabler of their observability goals. Certainly, AI is becoming a pervasive instrument to accelerate many areas, including observability.

    Benefits of Observability

    An impressive 64% reported that their investment into observability has exceeded their expectations. So, what are some of the top benefits of observability? Well, the report found the topmost benefits to be areas like decreasing problem detection and resolution times, identifying “true positive” incidents, and enhancing application security.

    Observability is being deployed as a tool to evolve traditional security efforts, as it uncovers a deeper understanding of application behaviors. This can help security teams correlate errors to specific diagnoses and spot potential threats in a quick manner. As such, 59% said observability helps them uncover security issues thanks to the intelligence capabilities of observability solutions. And 55% say they can uncover more security vulnerabilities thanks to the visibility afforded by observability.

    Observability can also be used to improve visibility into hybrid architectures. A full 86% said it’s important to have flexible observability solutions that cover hybrid architectures, though half identify this as an area for improvement. Although we like to think that cloud-native development is the status quo, many enterprises still oversee a mixture of on-premises, private cloud and multi-cloud environments. A unified, agnostic observability layer is thus essential to peek into all these disparate environments to grapple with disparate data outputs.

    The Leaders of the Observability Pack Win

    Service interruptions can have negative consequences for organizations, including lower customer satisfaction, loss of revenue and loss of customers. In fact, 76% of respondents reported downtime can cost up to $500,000 per hour.

    Thankfully, observability has emerged to help improve overall resilience and avoid these negative repercussions. But, to truly reap the benefits, you must have a mature practice in place. As defined by the report, “observability leaders” have a more formal approach to resilience and have standardized this across their organization. And 89% of those leaders are completely confident in their ability to meet their application availability and performance requirements. The catch-22 with observability is that you must invest more energy into formalization and knowing when the effort is worthwhile is a moving target.

    A solid observability practice is supported by standardized metrics, logs and traces across the organization. Furthermore, to make observability behave correctly, you will need flexible tooling that can leverage data from multiple sources, such as the network, infrastructure, servers and databases.

    The State of Observability 2023 report surveyed 1,750 observability practitioners from around the globe, making it the most extensive study on observability to date. For more insights, you can pick up a copy of the report behind an email gate here.

  • 92% of Devs Use AI, Survey Says ¦ Intel One Mono Font

    92% of Devs Use AI, Survey Says ¦ Intel One Mono Font

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: GitHub touts unbelievable AI stats, and Intel’s beautiful open source typeface. (more…)

  • Four Ways to Modernize Your Enterprise Monoliths

    Four Ways to Modernize Your Enterprise Monoliths

    In a perfect world, every application would run like Netflix–by which I mean every application would be cloud-native, microservices-based, containerized and, in all other senses of the word, modern. Unfortunately, not every application can be transformed in these ways. Some of the most important enterprise applications–like those powered by SAP or Oracle–don’t lend themselves to architectural transformations simply because the vendors don’t support that strategy. As much as organizations might wish that they could re-architect legacy apps from the ground up, the reality is that they just can’t.

    Fortunately, though, all hope is not lost if you have an enterprise app that you can’t containerize or “microservices-ize.” Even if you can’t “break down your monolith”–to quote the standard advice you’ll find if you read articles about how to modernize legacy apps–there are a variety of practical steps you can take to make legacy, monolithic applications look and feel (in most respects) like modern, cloud-native apps.

    Here are four ways to make your enterprise monolithic apps more cloud-friendly, even if they’re not technically cloud-native.

    Use Cloud Automation to Modernize Legacy Application Management

    Most enterprise apps are compatible with the cloud in the sense that you can host them on cloud-based virtual machine (VM) instances using services like Amazon EC2.

    By taking advantage of cloud hosting for enterprise apps, organizations can also leverage cloud automation tools, such as autoscaling policies and rules that automatically start or stop VMs. In this way, it becomes possible to deploy enterprise apps in a highly scalable, automated way. You get something that resembles Kubernetes-based orchestration, except your apps don’t actually run in containers on top of Kubernetes. They’re just monoliths that benefit from cloud automation tools.

    Deploy Load Balancers to Optimize Performance

    Load balancers, which automatically manage network traffic flowing to and from applications, are another critical tool that organizations can easily leverage when they migrate legacy applications to the cloud.

    Although configuring load balancers for enterprise apps hosted in the cloud is not a strict requirement, doing so can substantially improve application performance and reliability because load balancers help to ensure that requests are directed at application instances best able to handle them. They prevent situations where one instance of your application is overwhelmed with traffic while another sits idle.

    Again, this is something that platforms like Kubernetes also do for microservices apps. But, as I’ve explained, you don’t actually need your app to run as microservices to take advantage of load balancing. You can do it with monolithic legacy apps, too.

    Adopt an Everything-as-Code Strategy

    When your app lives in the cloud and is managed by cloud automation tools, it becomes possible to manage most aspects of application operations via code. Specifically, you can:

    ● Use infrastructure-as-code (IaC) tools to automate infrastructure provisioning and setup.
    ● Automate application configuration management using code rather than applying configuration changes manually.
    ● Codify operational processes, such as application updates and backups, instead of relying on manual operations.

    Practices like these, which enable a strategy known as everything-as-code, significantly reduce the amount of time and manual effort that engineers spend managing applications. They also provide consistency and minimize the risk of errors due to human oversight. And there’s no reason why you can’t leverage these practices for legacy apps as well as modern ones.

    Integrate Legacy Apps With Modern Toolchains

    If your enterprise app is hosted on-premises, you probably manage it using tools and processes designed solely for it. But when you move an enterprise app to the cloud, it becomes possible to manage the application using the same integrated toolchain you deploy for other applications and processes.

    You can, for example, take advantage of cloud-based monitoring tools to continuously collect data about application performance and generate automated alerts when something is wrong. Likewise, you can regularly create image-based backups of your application.

    This toolchain-based operational strategy is another way to streamline enterprise application management, even in situations where you can’t rewrite or containerize the application itself.

    Conclusion: Getting More From Legacy Apps

    Just because you have a legacy enterprise app that you can’t transform into microservices doesn’t mean you have to settle for legacy management and operational practices. Modern automation tools combined with modern operational strategies like everything-as-code make it possible to achieve an enterprise application management experience that closely parallels that of fully modern, cloud-native apps, regardless of which architecture your app actually uses.

  • Grafana Labs Slashes Time to Create Observability Dashboards

    Grafana Labs Slashes Time to Create Observability Dashboards

    At its GrafanaCON 2023 event today, Grafana Labs updated its core platform for visualizing data which makes it simpler to set up dashboards in minutes. The updates are part of a celebration of the 10th anniversary of a tool that is now widely used by DevOps teams.

    Ryan McKinley, a distinguished engineer for Grafana Labs, said Grafana 10 should help make DevOps more accessible to a wider range of practitioners with limited experience working with observability tools. The latest release also makes it simpler to share knowledge with external stakeholders via public dashboards, he added.

    In addition, Grafana 10 adds expanded role-based access control (RBAC) capabilities and streamlined implementation of the secure access markup language (SAML) to ensure authentication.

    Grafana Cloud has also been updated to provide a secure way to connect to data residing in an on-premises IT environment or in a cloud with the observability platform the company provides via a software-as-a-service (SaaS) platform.

    Finally, Grafana Labs is also making the engine it created to visualize data more accessible to third-party developers that are embedding visualizations based on Grafana within their applications, noted McKinley.

    Grafana Labs

    There are now more than 150 plugins for various data sources that have been made available to more than 20 million users of the Grafana visualization framework. Not all those users are working in DevOps environments, but Grafana is widely used to enable observability across increasingly complex IT environments. The Grafana Cloud seeks to capitalize on that popularity by adding a service that uses an instance of open source Grafana Mimir software to store data collected in a format originally defined for the open source Prometheus monitoring tool.

    It’s still early days as far as adoption of observability is concerned, but it’s apparent that as application environments become more complex, the plethora of monitoring tools that DevOps teams rely on will need to be streamlined. Observability platforms promise to unify logs, metrics and traces to simplify launching queries to identify the root cause of an issue.

    The rate at which DevOps teams will embrace observability will naturally vary, but the biggest obstacle might not be the platforms themselves. Instead, the issue is understanding what queries can help DevOps teams better understand the root cause of an IT issue before there is a major disruption. In the long term, it’s expected that machine learning algorithms will leverage the data collected by observability platforms to automatically identify issues that might lead to a disruption long before it actually occurs.

    Of course, the result of any query that gets launched needs to be visualized in a way that is easily understood. Grafana Labs is now making a case for a more integrated approach that, at its core, employs its visualization tools to make it simpler to discern what’s occurring in IT environments. After all, no matter how talented any DevOps team may be, it’s still not possible to manage what was never seen in the first place.

  • Survey Finds Cloud Management Strategies Shifting

    Survey Finds Cloud Management Strategies Shifting

    Even though organizations continue to consume cloud resources inefficiently, they continue to increase the amount of money allocated. These were among the findings of a global survey of 1,000 technology practitioners and decision-makers conducted by Forrester Consulting on behalf of HashiCorp.

    The survey found a full 94% of respondents reported that their organization struggled with cloud waste. Top factors contributing to avoidable cloud spending included overprovisioning resources (50%), idle or underused resources (50%) and a lack of needed skills (43%). Nevertheless, more than half of respondents (56%) said they boosted their cloud spending in the last year compared to 22% which reduced it.

    At the same time, however, 92% of respondents said they are moving toward adopting, standardizing or scaling platform teams as part of an effort to centralize the management of cloud services, but only 39% are scaling the use of platform teams throughout the organization. The survey also found, however, that organizations are addressing skills shortages by adopting a common operating model/shared automated workflows (58%), reskilling/upskilling (56%) and working with partners (43%).

    The survey also found many organizations are also committed to multi-cloud computing, with nearly three-quarters (73%) reporting this strategy is helping them reach their business goals. Another 19% said they expected this strategy to help them achieve their business goals in the next year.

    The most-cited reasons for adopting a multi-cloud strategy were reliability (51%), cost reduction (48%), security and governance (45%), digital transformation (45%) and scalability (45%). Only 10% had no choice but to go multi-cloud due to acquisitions or other issues.

    Security (88%), availability (84%) and scalability (84%) were identified most often as being important/very important multi-cloud success factors, followed closely by regulatory/compliance requirements (82%), staffing and skill levels (82%), budget (80%), visibility into cloud infrastructure (78%), automated tooling (77%) and platform teams (75%).

    The top cloud initiatives were data protection (77%), followed by secrets management and access control (both at 75%), the survey finds. The top security concerns were password/credentials/secrets leakage (50%) followed by data theft (49%), phishing (46%) and ransomware (42%).

    Overall, respondents said the biggest benefits of having a multi-cloud computing strategy were a stronger security posture (74%) and helping attract, motivate and retain skilled staffers (68%).

    Chris Van Wesep, senior director of product marketing for HashiCorp, said it’s clear organizations are purposely using multiple clouds to reduce costs by pitting one cloud service provider against another. The challenge organizations face when using that approach is they need to define a consistent set of development processes that can be used across multiple clouds to keep total costs under control.

    Organizations that embrace multi-cloud computing are also more likely to implement security best practices because of their need to consistently manage multiple cloud computing environments, he added.

    Of course, there is always going to be a great disparity between high- and low-performing organizations. The survey found that about 25% of survey respondents are high performing, with an equal number falling at the other end of the spectrum. The rest fall somewhere in between those two ends of the spectrum. The issue is that the gulf between the high and low ends of that spectrum appears to be widening as more organizations fail to muster the level of skills and expertise needed to succeed in the cloud era.

  • Cycode Leverages eBPF to Secure CI/CD Pipelines

    Cycode Leverages eBPF to Secure CI/CD Pipelines

    Cycode today added a Cimon extension to its application security platform that uses extended Berkeley Packet Filtering (eBPF) to thwart cyberattacks against continuous integration/continuous delivery (CI/CD) pipelines.

    Alex Ilgayev, head of security research for Cycode, said Cimon uses eBPF to inspect network connections, running processes and file modifications within a pipeline to learn standard behaviors. Armed with those insights, Cimon will then surface any anomaly in real-time, he added.

    DevOps teams can then craft and embed security and compliance rules within their pipelines based on the severity of the anomalies discovered, said Ilgayev.

    eBPF makes it possible to run sandbox programs at the kernel level without adversely impacting performance. In effect, eBPF bridges the boundary between kernel and user space by enabling developers to combine and apply logic across multiple subsystems that, historically, were completely independent of one another. That approach enables, for example, a security tool to scale to the point where it can identify threats at much higher levels of throughput to improve overall scale at a time when the volume of cybersecurity attacks continues to increase.

    Cycode is taking advantage of eBPF to enable DevOps teams to not only defend against known attacks involving malicious package installation, typosquatting, repojacking, dependency confusion, dependency hijacking and other types of dependency attacks but also zero-day threats, noted Ilgayev.

    Cycode provides a platform for mapping metadata and events using graph technology that makes it simpler for application development and cybersecurity to consolidate alerts generated by their DevSevOps tools. Most recently, Cycode added a Cycode Application Security Orchestration and Correlation (ASOC) module that will automatically discover all the tools that make up a DevSecOps workflow without requiring any integration effort.

    The approach enables the Cycode platform to discover, for example, dependency issues that would otherwise be missed by software composition analysis (SCA) or static application security testing tools (SAST).

    While a lot of progress has been made in terms of adopting DevSecOps best practices, many organizations are still struggling with securing their software supply chains. Most of the members of a DevOps team have limited cybersecurity expertise, so they need the help of a cybersecurity professional to determine what specific actions are required to remediate a vulnerability. Cybersecurity professionals, conversely, don’t have a lot of application development expertise.

    As the number of regulations specifically focused on application security steadily increase, every organization that builds software will soon need to embrace DevSecOps to better secure software supply chains. Unfortunately, developers have too often viewed cybersecurity as an obstacle to deployment while cybersecurity teams have historically considered developers to be a primary cause of the breaches they are expected to clean up. The first step toward bridging that divide is, of course, to realize that application developers and cybersecurity teams need to be invested in each other’s success.