Category: Application Performance Management/Monitoring

  • Latest eBPF Advances Are Harbingers of Major Changes to IT

    Latest eBPF Advances Are Harbingers of Major Changes to IT

    The open source community advancing the extended Berkeley Packet Filter (eBPF) gathered at a virtual eBPF Summit today that featured a demonstration of eBPF being used in a Windows environment. eBPF enables applications to run within a sandbox in the Linux microkernel.

    Microsoft has signaled its intent to employ eBPF within Windows like the latest version of Linux already does today. That capability makes it possible to, for example, run networking, security, observability and storage software closer to the kernel to dramatically improve performance versus running that software in user space.

    Liz Rice, chief open source officer for Isovalent, a provider of networking software based on eBPF, said that while it’s clear eBPF will have a major impact on IT, the transition to eBPF won’t be a single event. Instead, it will be more of an evolutionary process that will occur as organizations upgrade their operating systems and the various tools and applications they employ.

    The eBPF Foundation, an arm of the Linux Foundation, was formed to expand the use of eBPF across all operating systems. Members of the eBPF Foundation include Facebook, Google, Isovalent, Microsoft and Netflix.

    In effect, eBPF changes the way operating systems are designed. It bridges the boundary between kernel and user space by enabling developers to combine and apply logic across multiple subsystems that were historically completely independent. That approach enables, for example, a security tool to scale to the point where it can identify threats at much higher levels of throughput at a time when brute-force cyberattacks are overwhelming existing cybersecurity tools.

    Similarly, networking, storage and observability tools should be able to run at much higher levels of scale. That’s especially critical for DevOps teams embracing observability platforms that need to dynamically process massive amounts of data in near-real-time.

    Less clear is the degree to which eBPF might one day drive convergence across distinct categories once multiple tools and applications run at the microkernel level.

    IT organizations would be well-advised to ask their vendors when they plan to support eBPF as they plan their upgrade cycles. It’s not likely IT teams are going to want to upgrade every tool and application that can benefit from eBPF all at once. In fact, updates to these applications that don’t support eBPF might even be postponed in the knowledge that a much larger and arguably more critical update is on the immediate horizon.

    In the meantime, as the number of organizations running the latest versions of Linux continues to increase, more hands-on experience with eBPF will be gained. IT teams may not need to concern themselves with what is occurring in the microkernel of the operating systems, but they should at least understand how eBPF ultimately helps reduce the total cost of running IT and how it makes the Linux microkernel more programmable. Those IT teams, however, will soon discover how stark a difference in performance there will be.

  • Survey Surfaces Spike in Generative AI Usage Across IT

    Survey Surfaces Spike in Generative AI Usage Across IT

    A survey of 800 DevOps and application security operations (SecOps) leaders published today found nearly all (97%) are making use of generative artificial intelligence (AI).

    Conducted by the market research firm Sago on behalf of Sonatype, the survey found that beyond writing code, a full 45% of the 400 security operations professionals have already embedded generative AI into their workflows compared to 31% of the 400 DevOps professionals.

    Security operations teams also reported greater time savings than their DevOps counterparts, with 57% saying generative AI saves them at least six hours a week compared to only 31% of DevOps respondents that saw the same benefit.

    The top benefits cited by security operations teams is increased productivity (21%) and faster issue identification/resolution (16%) compared to faster software development (16%) and more secure software (15%) cited by DevOps professionals.

    It’s still early days as far as embedding generative AI in workflows is concerned, but it’s clear the ability to write code faster is trumping concerns about the increased number of vulnerabilities that might find their way into application environments. The most widely used generative AI platforms are trained on a massive corpus of data that includes code of varying quality. As such, a lot of the code generated by a general-purpose AI platform will likely have as many errors, including vulnerabilities, as the code used to train it.

    The level of faith organizations will place in that code will be heavily influenced by use cases. A script used to automate DevOps workflows that are not externally facing may be one example of where a general-purpose AI platform can boost productivity. In other instances, code that contains vulnerabilities that find their way into a web application might be much more problematic.
    Despite those concerns, however, the survey finds nearly three-quarters (75%) of all respondents feel pressure to use generative AI.

    There are, of course, already large language models trained on code that has been vetted by software engineers. In the months ahead, the code generated by AI platforms specifically designed for that purpose should significantly improve.

    Sonatype CTO Brian Fox said it’s only a matter of time before IT organizations focus more on ensuring the generative AI platforms are tuned for specific tasks. In the meantime, however, application security may get worse before it gets better, with more than three-quarters of DevOps respondents noting that generative AI will result in more vulnerabilities in open source code. Only 58% of security operations professionals are similarly concerned.

    It will be up to the engineers that make up these teams to bring discipline to code quality practices and make sure the code running in a production environment is of high quality, regardless of how it was created, noted Fox. For the moment, the issue is that AI augmentation is now occurring at a faster pace than the AI advances that should one-day help DevOps teams cope with increasingly larger codebases, he noted.

    Survey respondents are also concerned about who might own the code generated by AI. A total of 40% said developers or the organizations they work for should own the copyright for AI-generated output, and most of them agreed developers should be compensated for the code they wrote if it’s used in open source artifacts in LLMs (DevOps 93% versus SecOps 88%). A total of 42% of DevOps respondents and 40% of SecOps respondents said a lack of regulation could deter developers from contributing to open source projects.

    DevOps and SecOps leads both want more regulation: Asked who they believe is responsible for regulating the use of generative AI, 59% of DevOps leads and 78% of SecOps leads said both the government and individual companies should be responsible for regulation.

    At this point, the proverbial generative AI genie is out of the bottle, so there is no going back. The issue that remains to be seen is how DevOps and security operating teams will adjust to that new reality.

  • Tips for Increasing Developer Velocity in the AI Age

    Tips for Increasing Developer Velocity in the AI Age

    These days, everyone is trying to improve release frequencies. Under mounting pressure to deliver more, many software teams are considering new strategies to enhance their developer velocity, like AI-assisted code development and platform engineering. AI has been a boon for automatic code generation, but all the code in the world doesn’t matter if you can’t deploy it into production efficiently.

    Another point is that velocity isn’t always measured productively, said Dori Exterman, chief evangelist of Incredibuild and a self-proclaimed ‘productivity freak.’ Too often, managers place value on quantitative elements, such as points per sprint and unrealistic metrics, when they really should be considering the quality of these components and how easy they are to maintain in the long run.

    I recently chatted with Exterman and other experts about tactics organizations can use to enhance their development velocity. Below, we’ll consider some helpful methods, from optimizing testing automation to creating internal development platforms (IDPs) and evolving your CI/CD processes. Essentially, optimizing the plumbing will be necessary to match the productivity of instant code generation—otherwise, the vision of continual release will remain stunted.

    New AI, Same Plumbing…

    No tech article today can mention developer productivity enhancements without a nod to AI. Just take the interest in Copilot, for example. Among GitHub Copilot users, 40% of the code they’re checking in is now AI-generated and unmodified, according to a Microsoft executive. And GitHub reported that 88% of Copilot users feel more productive when using the tool.

    In contrast to past hype cycles, the latest AI wave is not just a passing fad—it will have long-lasting effects, said Exterman. However, most of our current DevOps processes were constructed for manual code writing, not for the era of AI-assisted development.

    If you quadruple the amount of water you use but use the same plumbing system, you can’t push more water through, said Exterman. Similarly, if you amplify the amount of code you’re producing but don’t evolve your build processes, staging and testing, then DevOps suddenly becomes the new blocker.

    Ways to Accelerate Developer Velocity

    So, how can we improve development efficiency and productivity in the age of AI? Here are some actionable strategies for overcoming these bottlenecks and improving developer velocity.

    Accelerating the Plumbing

    Exterman stresses the importance of leveraging AI to enhance the foundational processes of development. This involves using techniques such as distributed computing and smart test selection to streamline build and testing processes. By optimizing these foundational steps, development teams can ensure that their coding efforts translate into efficient and rapid progress.

    Optimizing Testing through AI

    AI’s potential not only lies in code generation—it extends to optimizing testing processes. Exterman suggests tools like Launchable that allow AI to prioritize tests that matter most. This strategic approach to testing enables teams to focus on high-impact areas while maintaining comprehensive test coverage.

    Embracing Test Automation

    Exterman underscores the importance of comprehensive test automation. Rapid iteration loops are essential for maintaining velocity, and automation facilitates fast feedback cycles. This approach ensures that each code change undergoes rigorous quality checks, preventing errors from propagating downstream.

    Keeping an Eye on Technical Debt

    One of the potential downsides of increasing programming velocity is the accumulation of more technical debt. As more development occurs, the temptation to compromise on documentation, unit testing and best practices grows. Exterman emphasizes that velocity must be pursued in tandem with managing technical debt to ensure the long-term health of projects.

    Investing in Platform Engineering

    Recently, we’ve witnessed a paradigm shift toward platform engineering. Just over half of IT organizations have already embraced platform engineering, according to the 2023 State of DevOps Report. Exterman emphasizes the need for a robust internal developer platform that supports the seamless transition of code from development to staging and production. For instance, tools like Terraform and Earthly play a pivotal role in establishing testable environments and reproducible builds.

    “Bring more data services closer to the developers,” said Venkat Ramakrishnan, VP, product management and engineering, Portworx by Pure Storage. “Choose platforms that provide easy-to-deploy services that developers can consume and provide visibility and control into the underlying costs.”

    Enabling Observability

    Observability, according to Exterman, is also important for gauging efficiency. The ability to continuously monitor and log processes enhances the overall development cycle. One report from Splunk even found that 64% report their investment into observability has exceeded their expectations. Tools from New Relic and Datadog, for example, offer insights that tie quality, delivery and productivity together, enabling teams to make informed decisions.

    Evolving CI/CD With Continuous Merge

    One method to progressing CI/CD is continuous merge, a new concept that can be implemented with tools like gitStream that aims to decrease the window between a pull request, review and merge.

    “CI/CD has done wonders to improve the quality and efficiency of the software development toolchain, but it mainly focuses on things that happen after code has been written and reviewed,” said Ori Keren, CEO and co-founder of LinearB. “Continuous merge is a mindset that extends CI/CD practices further upstream to improve the quality and efficiency of the code review process. We’ve reached a point where code review times frequently cause the most significant delays in the software delivery process; continuous merge is how we fix that.”

    Using Cloud-Agnostic Platforms

    Cloud-native development has become more popular as organizations seek to design software architectures bred for the natural scalability of the cloud. Simultaneously, both technology and business motivators are resulting in a multi-cloud condition. In this scenario, IT really needs agnostic, open platforms to retain flexibility and reduce bottlenecks.

    “Enable developers to build their apps in a cloud-agnostic way so they can scale their apps globally,” said Ramakrishnan. “Much of developer and app momentum is lost when scaling apps. Helping the application teams architect it right by providing cloud-agnostic application platforms like Kubernetes enables developers to move faster, scale faster and reach their customers everywhere.”

    Measuring Developer Velocity

    The above tips should help improve velocity, but how exactly should you measure success? Well, measuring developer velocity goes beyond simply tracking the number of points completed in a sprint, reiterated Exterman. He emphasizes the importance of focusing on the ability to deliver high-quality products to the market swiftly. He underscores the need for a fast feedback loop for addressing bugs and iterating quickly. AI plays a role here, too, aiding in test writing and enabling continuous delivery.

    End Benefits of Improved Developer Velocity

    Exterman concludes by highlighting the real-world benefits of increased developer velocity. Faster bug-fixing and release cycles, particularly crucial in industries like gaming, result in improved user experiences and customer satisfaction. He emphasized the significance of aligning key performance indicators (KPIs) and objectives and key results (OKRs) with the aspects that truly matter, promoting a culture of measured and sustainable progress.

  • Oracle Bill is 5x Client’s Budget ¦ Toyota Out of Space

    Oracle Bill is 5x Client’s Budget ¦ Toyota Out of Space

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: Birmingham looks like the Detroit of the UK—is it Oracle’s fault?
    Plus: Was Toyota’s factory failure caused by running out of disk space? (more…)

  • Grafana Labs Delivers Open Source Code Profiling Tool

    Grafana Labs Delivers Open Source Code Profiling Tool

    Grafana Labs this week released version 1.0 of an open source tool that collects data about an application’s code to aid debugging, troubleshooting and optimization efforts. The tool makes it simpler to identify the specific lines of code driving a process or task within an application.

    Ryan Perry, engineering director for Pyroscope at Grafana Labs, said Grafana Pyroscope 1.0 combines a tool acquired last year from a company he led with Grafana Phlare, a code profiling tool that Grafana Labs previously developed. The combination of the two tools provides a more precise code-tracking capability with an underlying database that is designed to scale horizontally, he added.

    For example, Grafana Pyroscope 1.0, which supports extended Berkeley Packet Filtering (eBPF) running on Linux systems, can now ingest, store and query workloads from any project of any size. Grafana Pyroscope 1.0 has already been used to profile more than 50,000 application instances at a rate of more than 6,000 unique profiles per second.

    The code profiling tool was added to Grafana Cloud Profiles, the hosted continuous profiling tool that Grafana makes available as a service, earlier this month.

    While the primary use case for Grafana Pyroscope is to troubleshoot applications, organizations are also using it to identify and then remove dead code within an application as part of a larger application modernization initiative, noted Perry. As updates to applications are made over several years, organizations frequently find that subsets of the application code are no longer needed, said Perry.

    The goal going forward is to add support for features such as flame graphs in GitHub pull requests, canary deployments, profile-guided optimization (PGO), integrating profiling with load testing tools such as Grafana k6 and integration with visual editors such as VS Code.

    In addition, Grafana Labs is committed to working with the OpenTelemetry project led by the Cloud Native Computing Foundation (CNCF) to ensure Grafana Pyroscope remains aligned with the OpenTelemtry effort to develop an OTel-native profiling tool. Grafana Pyroscope 1.0 will provide the ability to ingest data from that tool and contribute client-side instrumentation capabilities the company has developed.

    Grafana Labs is also working toward improving client-side software development kits (SDKs) to add more real-time agent management features, such as sampling controls, ad hoc profiling capabilities and alternative instrumentation options.

    Finally, Grafana Labs plans to improve eBPF integration for languages such as Python, Java and .NET.

    DevOps teams naturally spend a lot of time trying to optimize application performance and troubleshooting issues that arise long after an application is initially deployed. Code profiling tools are emerging as a tool that makes it much simpler to aggregate metrics, logs and traces and surface actionable insights that make debugging and troubleshooting applications much less tedious. The challenge is finding the time to identify and proactively address potential issues before they become another incident to manage.

  • Google Adds App Modernization Tools to Generative AI Platform

    Google Adds App Modernization Tools to Generative AI Platform

    Google this week added automated refactoring capabilities to the generative artificial intelligence (AI) tools it makes available to write code on Google Cloud.

    In addition, Duet AI for Google Cloud is now integrated with Google’s Apigee API Management and Application Integration services. This makes it possible to design, create and publish application programming interfaces (APIs) using simple natural language prompts.

    These additions to the preview of Duet AI for Google Cloud were announced at the Google Cloud Next 2023 conference and are scheduled to be generally available later this year. The new capabilities promise to reduce the time and effort required to modernize applications.

    For example, DevOps teams can now convert code written in C++ into Go and migrate that application to Cloud SQL, the managed relational database service that Google provides. Via a natural language interface, these tasks are launched via a prompt from directly within a development environment.

    Priyanka Vergadia, a developer advocate for Google, told attendees these capabilities will reduce the need to rely on consultants to migrate applications and take up much less time. In addition, the overall quality of the code should improve using large language models (LLMs) that have been trained using code written by Google developers and best practices defined by Google software engineers.

    Organizations will save time and effort because the need for developers to understand how existing application code was constructed is eliminated, she noted.

    Google has also started to work with select enterprise IT teams to allow Duet AI to incorporate knowledge from their libraries and codebases to generate more context-aware code suggestions.

    In addition to writing code, Google is making a case for also using Duet AI in Google Cloud to monitor performance and troubleshoot IT issues by identifying correlations across application environments. For example, natural language prompts can be translated into PromQL queries to analyze time-series metrics. Duet AI can also provide intuitive explanations of complex log entries in Logs Explorer for easier root-cause analysis and provide suggestions for how to fix issues that surfaced in an error reporting tool.

    Duet AI is also incorporated into the Google BigQuery service to help developers write SQL and Python code to access and analyze data. It can generate full functions and code blocks, auto-suggest code completions and explain your code and SQL queries. Via a single SQL statement, a query can connect tables with the foundational AI models Google makes available via its Vertex AI service.

    At the same time, IT teams can optimize prompts using BigQuery Studio tools, perform text analysis or generate new attributes to enrich a BigQuery data model. Duet AI also enables IT teams to generate vector embeddings in BigQuery to create semantic searches and recommendation queries.

    It’s not clear whether generative AI capabilities will automate entire DevOps and DataOps workflows just yet, but many of the tasks that once required automation scripts will soon be automated by AI models embedded within DevOps platforms. The challenge and the opportunity is to determine how to make those capabilities available to drive DevOps workflows at unprecedented scale.

  • Gremlin Adds Detected Risk Tool to Chaos Engineering Service

    Gremlin Adds Detected Risk Tool to Chaos Engineering Service

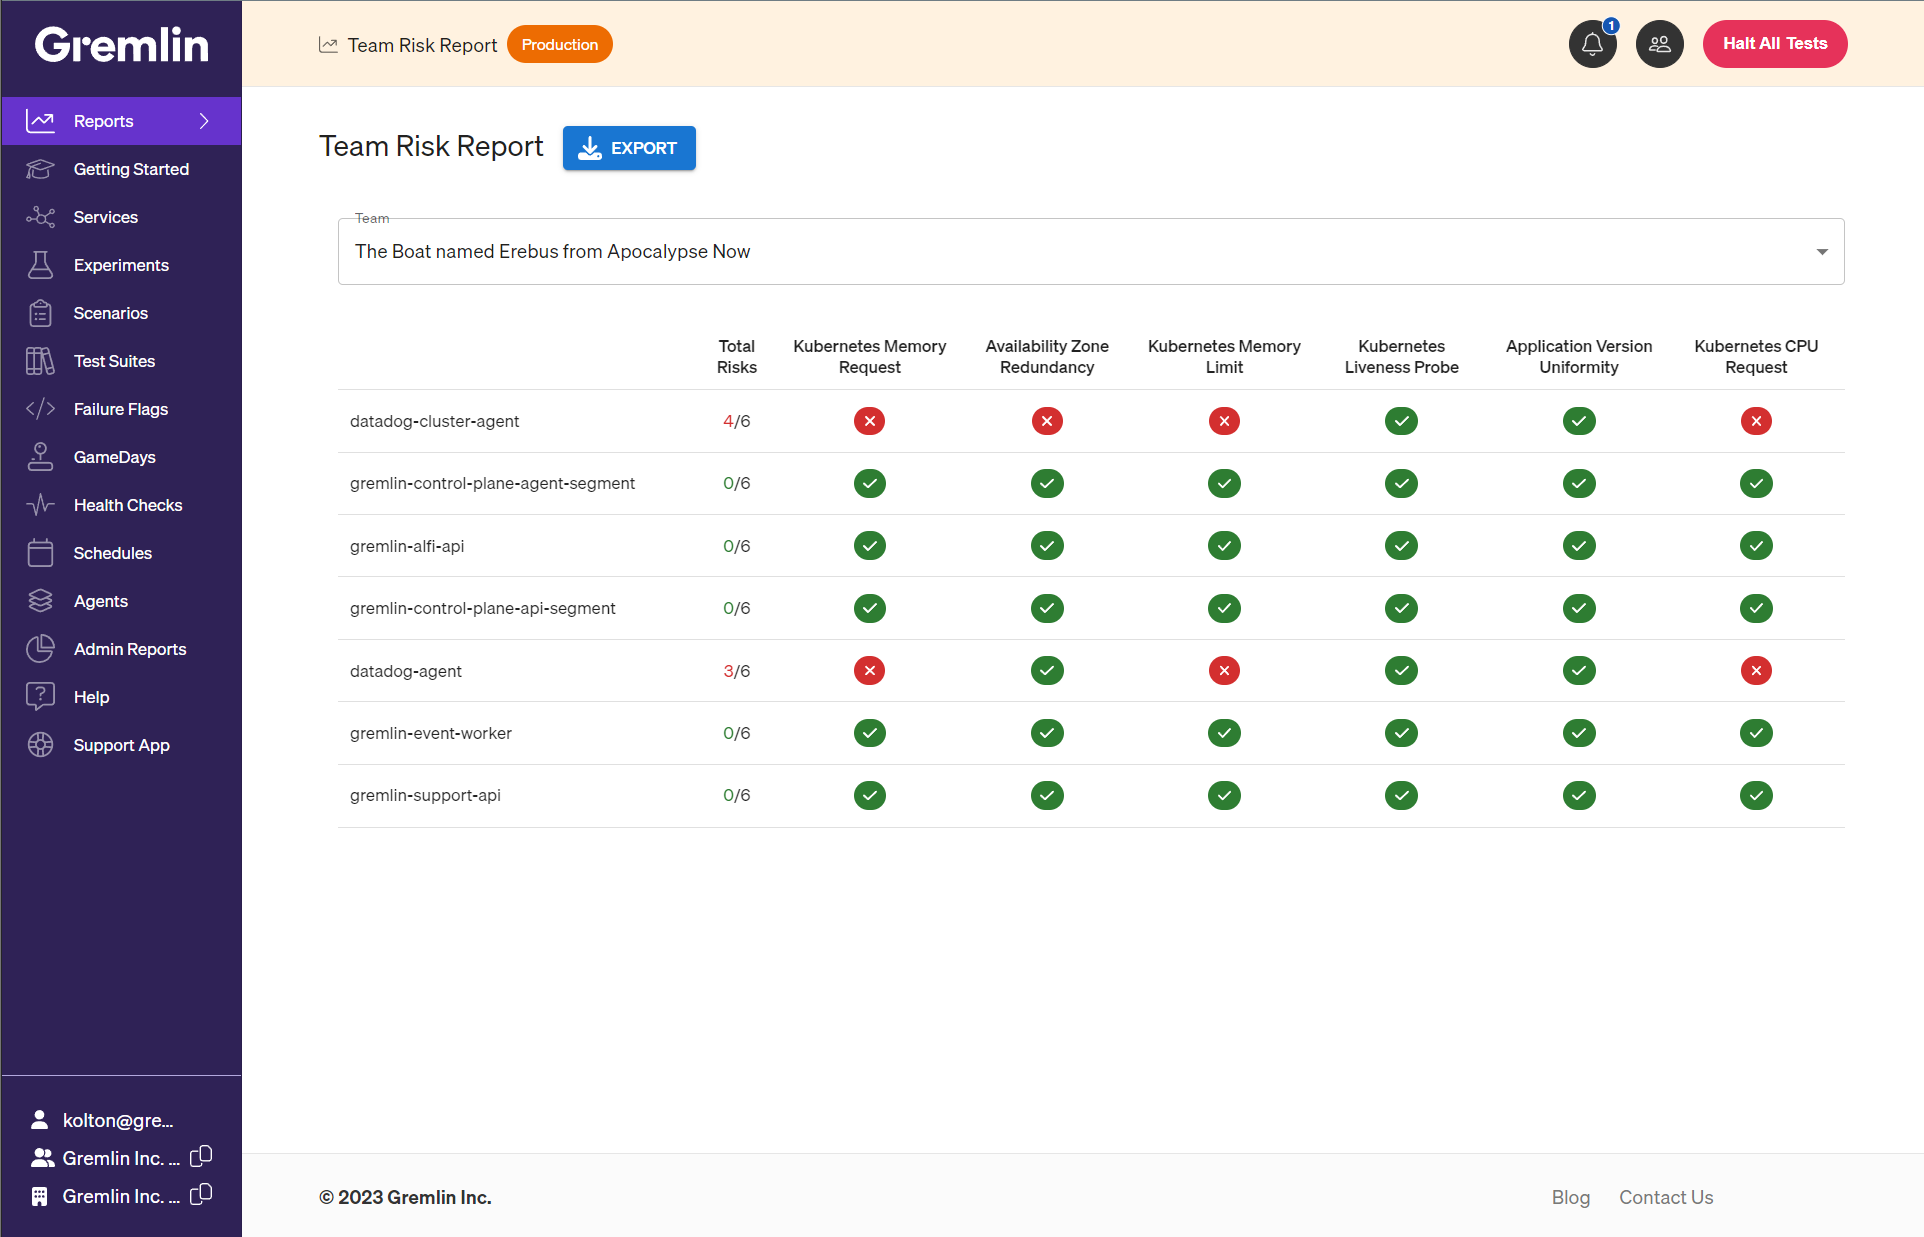
    Gremlin today added a risk detection capability to its chaos engineering service that automatically identifies issues that could cause outages along with recommendations to resolve them.

    Enabled by agent software deployed in an IT environment, the Detected Risk tool makes it possible to benefit from chaos engineering techniques without needing to construct experiments or run reliability tests.

    Gremlin CTO Kolton Andrus said that approach eliminates much of the friction that previously limited adoption of chaos engineering best practices to improve the resiliency of IT environments.

    Chaos engineering is rooted in a resiliency testing philosophy that posits applications should be able to keep functioning regardless of any service or infrastructure failure. Most IT organizations, however, don’t have the expertise required to build the tools required to test resiliency based on the “Chaos Monkey” principles—pioneered by a Netflix project by that name—that, for example, randomly turns services off to see if an application fails.

    Each DevOps team will need to evaluate Gremlin’s recommendations before implementing them, but the overall goal is to provide IT teams with a better understanding of the level of risk attached to, for example, a misconfiguration of a server. To do so, the tool uses a scoring mechanism provided by Gremlin, noted Andrus.

    The challenge is that as IT environments become more complex, the level of dependencies between applications and infrastructure continues to increase. It’s often impossible for DevOps teams to manually keep track of all the hidden dependencies that might exist when IT environments are continuously being updated.

    In theory, of course, adopting cloud-native applications based on microservices should make IT environments more resilient as calls to application programming interfaces (APIs) are rerouted in the event of an outage. Nevertheless, there are almost always dependencies that get overlooked as these applications evolve, which creates a potential single point of failure.

    Naturally, not every IT team is always comfortable with the concept of deliberately breaking things to better understand what issues might cause an outage. As organizations become more dependent on software to drive critical processes, however, a more proactive approach to ensure resiliency is required, added Andrus.

    In fact, business leaders are becoming less tolerant of outages that result in lost revenue, so DevOps teams are being held to a higher level of accountability. DevOps teams may appreciate the value of a blameless culture that encourages everyone to learn from their mistakes, but IT leaders still get fired when there are too many outages, noted Andrus.

    Less clear is the degree to which the rise of artificial intelligence might affect chaos engineering. At the very least, AI models should make it easier to assess levels of risk, but the cost of using those technologies to achieve that goal is substantial, especially when platforms that provide the same outcome already exist.

    Regardless of approach, however, when it comes to resiliency, everyone agrees that the value of application uptime is now beyond measure.

  • Apica Acquires LOGIQ.AI to Unify Observability

    Apica Acquires LOGIQ.AI to Unify Observability

    Apica, a provider of a synthetic monitoring and observability platform, has just raised an additional $10 million in funding and has agreed to acquire LOGIQ.AI. LOGIQ.AI is a provider of a data fabric infused with machine learning algorithms.

    Jason Haworth, chief product officer for Apica, said the data fabric developed by LOGIQ.AI will be incorporated into the Apica Ascent platform in the third quarter. The LOGIQ.AI addition will apply artificial intelligence (AI) in a way that both optimizes and enriches data collected by the company’s observability platform.

    At the core of the Apica Ascent platform is an indexing engine built on top of a Kubernetes platform that aggregates data such as logs, traces and network packets from multiple sources. As part of that process, the platform reduces storage costs by trimming excess data that can be stored in a data lake it provides or a third-party data lake a customer prefers.

    At the same time, Apica also enables DevOps teams to both normalize data collected from multiple sources and enrich it to add additional context, said Haworth.

    The overall goal is to provide a unified view of all IT data to accelerate faster root cause analysis and reduce the total cost of collecting the data required, he added.

    Apica is making a case for an observability platform that goes beyond collecting data from DevOps platforms. As IT environments become more complex, IT teams need to be able to correlate data collected from a wide range of data sources to accurately determine the root cause of an issue, said Haworth.

    The challenge is managing the massive amount of data that needs to be continuously collected, stored and analyzed to achieve that goal, he added. The acquisition of LOGIQ.AI will enable Apica to embed a data fabric that employs machine learning algorithms and other data science techniques to make it feasible to observe complex IT environments at scale, noted Haworth.

    It’s still early days as far as observability is concerned, but it’s clear that IT teams need to move beyond monitoring a pre-determined set of metrics to manage complex and dynamic application environments. The rate of change to application environments as updates are made requires an ability to query data to determine the root cause of issues that could be caused by any number of dependencies.

    The issue is that even when IT teams have access to an observability platform, they may not have the knowledge and expertise required to craft the queries needed to determine the root cause of an issue. Machine learning algorithms will play a major role in enabling IT teams to proactively discover issues that they can investigate using the suggested queries.

    It’s only a matter of time before most IT organizations unify observability data within a single platform. That will make it simpler for them to collaborate across teams and should result in fewer disruptions as IT issues are discovered more quickly. After all, the best kind of IT incident is the one that never happened or that was too trivial for anyone outside of IT to even notice.

  • Styra Makes Source Code Available for Enterprise Edition of OPA

    Styra Makes Source Code Available for Enterprise Edition of OPA

    Styra is now making the enterprise edition of the Open Policy Agent (OPA) available under a source license that enables IT teams to modify or change the underlying code as they see fit when integrating it with other applications.

    Enterprise OPA is a drop-in replacement for OPA, agent software for implementing policy-as-code that is already available under an open source license. Styra’s enterprise edition provides access to a version that provides better performance, native integrations for a suite of data sources and additional capabilities such as policy decision analysis.

    Previously, Enterprise OPA was only available in either a binary or container format. While these formats enable Enterprise OPA to be widely used, they limited it from being built directly into applications for performance optimization because no access was provided to source code.

    Chris Hendrix, director of product management for Styra, said the source license also provides organizations with an assurance that they will be able to continue to modify Enterprise OPA in much the same way as they modify the open source edition.

    It’s not clear how many DevOps teams are managing policy-as-code within their pipelines, but as application security regulations become more stringent, it’s only a matter of time before most of them do so in one way or another. Styra’s approach relies on a Rego programming language that some DevOps teams have found challenging, however. To make it simpler, the company is working on a low-code approach that would help make Enterprise OPA more accessible, said Hendrix.

    In addition to encouraging more DevOps teams to use Enterprise OPA under a source license, Syra is clearly moving to make it more attractive to replace existing instances of OPA with a more robust implementation licensed from the company. No one knows how many instances of the open source edition of OPA advanced under the auspices of the Cloud Native Computing Foundation (CNCF) are running in production environments. But as those applications become more complex, the need for deeper levels of integration enabled by a faster version of OPA becomes more apparent.

    OPA enables developers to programmatically embed compliance controls without waiting for a compliance team to make them available. That ultimately makes it simpler to ensure that the proper controls have been implemented before an application is deployed in an on-premises IT environment. That capability also makes it easier to document which controls have been applied to make any audit less time-consuming.

    Shifting responsibility for compliance controls to the left also enables DevOps teams to better understand which controls address specific regulatory mandates incorporated into most applications versus which controls might be specific to a specific regulation. Armed with those insights, it then becomes simpler to incorporate policy-as-code within a DevSecOps workflow.

    Hopefully, more applications running in production environments will soon be secure by default. Naturally, one of the first places to start is by making sure the compliance controls needed to achieve a baseline level of security have been pervasively implemented.

  • New Relic Extends AI to Identify Alert Coverage Gaps

    New Relic Extends AI to Identify Alert Coverage Gaps

    New Relic this week added additional artificial intelligence (AI) capabilities to its observability platform that make it possible to detect and resolve alert coverage gaps.

    Camden Swita, a senior product manager for New Relic, said it’s not uncommon for DevOps teams to discover an issue that the existing alerts they put in place were not designed to address. New Relic is adding machine learning algorithms at no additional cost that are designed to identify anomalies indicative of those potential issues. The platform then surfaces recommended alerts that DevOps teams can apply or further customize as they see fit, he added.

    Those machine learning algorithms ensure DevOps teams are tracking the right thresholds to ensure there are no blind spots that could adversely affect application performance, noted Swita.

    New Relic is employing both predictive and generative AI to enable DevOps team to detect and resolve issues faster. The company has been using machine learning algorithms for predictive AI for several years and, more recently, started providing early access to a generative AI tool dubbed Grok.

    The overall goal is to make the capabilities of an observability platform more accessible, Swita said. This is accomplished by surfacing issues without requiring a software engineer to craft intricate queries to interrogate metrics, logs and traces, he noted.

    The AI capabilities also serve to reduce the amount of alert noise; it’s now possible to more easily understand the root cause of an issue and reduce the total number of alerts that might otherwise be sent, he added.

    While there’s no doubt AI will help democratize DevOps by making it possible to write scripts and better manage workflows, it might be a while before DevOps teams trust the recommendations made. AI models typically require some time before they understand how an IT environment functions, and not every initial recommendation may be valid. In time, however, DevOps teams will find themselves increasingly supervising processes that AI models are executing.

    In addition, there are competing approaches to building large language models (LLMs) that drive generative AI. For example, it’s not clear whether chaining LLMs together will be more efficient than creating a single large ‘parent’ LLM that has ‘child’ relationships with smaller LLMs, noted Swita.

    In the meantime, DevOps teams would be well-advised to list tasks that are likely to be automated by AI models. Many of them will tend to be manual tasks that most software engineers don’t especially relish, so in that regard, there’s naturally a lot of interest in AI. It remains to be seen, however, whether various forms of AI might one day automate an entire DevOps workflow. In fact, most DevOps engineers are going to set a high bar for AI models that, at the very least, will be expected to perform a task as well as humans before it’s trusted completely.