Tag: trust

  • Trust in Cloud Providers is a Developer Issue

    Trust in Cloud Providers is a Developer Issue

    Earlier this summer, we worked with ClearPath Strategies to ask developers about the level of trust they have in their various cloud service providers. What we learned spoke volumes: While developers’ familiarity and comfort with Amazon, Microsoft and Google position these well-known cloud providers as market frontrunners, developers often do not agree with the companies’ values.

    The research project gathered insights from more than 800 developers at small and mid-sized businesses, those with less than 500 full-time employees, across a wide variety of industries and geographies worldwide. You can download the summary report here (no signup required).

    In ClearPath Strategies’ report, senior analyst Stephanie Fairchild said that “approximately 20% of developers believe that the big three hyperscalers will engage in behaviors that include leveraging their brands to stifle competition, focusing on shareholders more than customer needs, hosting or working with customers that developers find morally objectionable, monetizing user data for their own use and locking them in with proprietary tools. Criteria such as security and performance clearly take priority over these trust issues for developers, but it’s interesting to note that a sizable portion of developers are thinking about how their values align with those of their service providers.”

    • Trust plays an important role in developers’ choice of a cloud hosting provider, but needs take precedence; when prioritizing needs or values, developers report they prioritize needs over their values 73% of the time.
    • The top three reasons cited for developers’ preference of their chosen third-party cloud provider: Security, trust and quality of service.
    • Survey respondents indicated that both hyperscale and alternative cloud providers deliver equally effective performance and security.

    The report cited three top criteria for choosing a third-party cloud provider: Security, trust and quality of service. Survey respondents felt that hyperscale and alternative cloud providers deliver equally effective performance and security. Interestingly, although 73% of respondents said they prioritize needs over values when making a purchasing decision, approximately 20% said they don’t trust the big three providers (AWS, GCP and Azure) in what could be considered key moral areas.

    It’s no secret that the extensive functionality and brand awareness of hyperscalers make them popular choices for developers, but an alternative cloud provider like Linode, DigitalOcean, OVHcloud or Hetzner can be a more trustworthy partner for innovative upstarts—one that likely offers better pricing and doesn’t threaten or compete with their business. And when an alternative cloud provider meets a developer’s functional needs—which is nearly always the case—developers can have the best of both worlds: A provider they can trust to meet their needs and one that shares their values. 


    To hear more about cloud-native topics, join the Cloud Native Computing Foundation and the cloud-native community at KubeCon+CloudNativeCon North America 2021 – October 11-15, 2021

  • Building Trust Into Your Product by Design

    Building Trust Into Your Product by Design

    In today’s world, every tool, every solution and every technology has the potential to do both good and bad. Good, if used according to the way it was designed, but bad if it falls into the wrong hands, or is manipulated or abused. As the ‘Peter Parker’ principle says, “With great power comes great responsibility.”

    As the COVID-19 pandemic continues and consumers look to digital communications to maintain some sense of normalcy and connectedness during these desolate times, the onus is on us, industry leaders, to ensure that the products and services being developed to connect and communicate with disparate employees, customers, and partners aren’t weaponized by bad actors.

    The best way to do this? By building trust into your design.

    You Have to Define Trust to Know How to Build Trust

    According to Merriam-Webster, the dictionary definition of trust is “one in which confidence is placed.” But the reality is that in today’s world, there are many ways trust can be perceived.

    Think of the automotive industry, where trust can be tangibly seen in the growth and success of certain car brands over decades. There, trust can be seen as ‘brand loyalty,’ or customers who repeatedly purchase from the same brand because they trust the company and trust the product.

    Trust in technology is the same. It has to be engineered and cultivated, but at the end of the day trust in the product must be mirrored by consumer trust in the organization. The two go hand in hand.

    The best way to approach building and sustaining trust when developing new products boils down to three key things: integrity, third-party accountability and consistency. Integrity stems from delivering high grade products and solutions, in conjunction with demonstrating accountable, transparent communications at the organizational level. Third-party validation further underscores that integrity, and restates the quality of products and services being delivered from a third-party perspective. And finally, consistency; being able to deliver exemplary products and solutions on a continual, consistent basis – the most essential ingredient in maintaining and bolstering trust among customers.

    Transparent Communication is Key

    As we enter 2021, the threat landscape is fraught with bad actors looking to take advantage of the latest threat vectors and emerging technology. As our lives continue to transition from physical to digital, and as more personal information is stored online, companies have to prioritize proper and timely communication about cybersecurity incidents.

    This brings us back to organizational trust being foundational for trust in a product. If you’ve seen the Netflix documentary ‘The Social Dilemma’ you know that social media is an oft-cited example of technology being misused or manipulated by bad actors. But after Twitter suffered a social engineering attack in July, the platform issued a swift update to its users. They were open, prompt and transparent in their analysis of the event, and highlighted not only the updated safety precautions put in place in response to the breach, but also underscored their ongoing commitment to trust and transparency within the Twitter community.

    Incidents like these, though harmful in the short term, can be less detrimental if addressed and communicated in a timely, transparent manner. There’s a saying, ‘It’s not what happens to you, but how you react to it that matters.’ The same goes for proper breach disclosure within the tech industry as a whole.

    Trust has Never Been More Foundational to the Business of Building

    As we enter 2021 and the COVID-19 pandemic rages on, more companies than ever are finding themselves in the business of building. Healthcare providers are drumming up new ways to digitally engage with patients and providers outside the physical confines of a hospital. Financial services organizations are adding more immediate, personalized ways to engage with customers when, where and how they need it. Educators are creating new digital solutions to keep millions of children, learning from home for the foreseeable future, engaged. And retailers are rebuilding the in-store experience for customers entirely online.

    With so much building going on around us, it’s important to keep in mind that the building process today requires not only outlining what you’re trying to build and defining how you intend to use it, but also analyzing how it can potentially be abused, manipulated or rendered ineffective.

    Consistently running your products and solutions against the latest threat models is one way to ensure your products’ security posture is up to date with the latest attack vectors. Another idea is to incorporate ‘security champions’ into your product development process and teams, to act as mini consultants who evaluate potential cybersecurity vulnerabilities. Once you’ve incorporated methods like these, turning to a third party to assess and sign off on your product’s cybersecurity resiliency is a good way to validate your products’ security adherence and effectiveness in the face of ever-evolving threats.

    Trust and Development Should go Hand in Hand

    At its core, trust and development should go hand in hand. Developers don’t need to recreate the wheel every time – there are plenty of libraries available online to leverage and pull from. What’s most important is for developers to understand the libraries they’re using to build, and ensuring that proper security protocols are built in from the start.

    Trust can seem like a huge lift, or an unnecessary distraction on the way to an MVP, product launch or update. I assure you, this is not the case. No matter how big the effort may appear, investing in trust – and the various methods, ways and changes that harden your products and services against abuse – will pay dividends down the line. Customers will trust your product and your company, and will, therefore, be more likely to remain loyal. If nothing else, keep in mind that building trust takes time, effort and consistency, while losing trust can happen in the blink of an eye.

  • DevSecOps and Development: Making the World Safer One Application at a Time

    DevSecOps and Development: Making the World Safer One Application at a Time

    If you have been around software development much at all in the past five or 10 years, then you’ve certainly heard of DevOps and know it’s here to stay. And it is very likely that you have also heard the term “DevSecOps” even more recently. With today’s extensive proliferation of application capabilities being delivered through services—and all the inherent complexity that comes with the delivery systems for them—it’s no wonder that cybersecurity has moved to the forefront for many companies. In fact, according to research from Stratistics MRC, the current global application security market is growing at a CAGR of 23.4 percent and is expected to reach more than $10 billon by 2023.

    But it is one thing for there to be an interest in cybersecurity; it’s another thing entirely to implement it well—and that is where the conversation gets more interesting. Today, the name of the game in application security is all about bringing the role of the developer into the fold and equipping developers to code, fix and maintain security as part of the software development process. In an article on DevSecOpsDays.com, DevOps thought leader and author Jon Willis offers the following comments:

    Fast forward to February 2017. I was speaking at the RSA Conference in San Francisco and I started seeing for the first time people talk about security as an interesting new way of integrating it into DevOps. They were unapologetically calling it DevSecOps. They were talking about this in a way that included security as a systems (end to end) approach to the traditional DevOps pipeline.

    This was not the first time I had heard people talk about security and DevOps.

    The thing that most caught my eye was that this approach was clearly putting the ownership of security on the developer. I immediately thought back to Werner Vogels’, the CTO of Amazon, statement of “You Build It, You Run It”, back in 2006. However, what I was hearing this time was “You Build It, You Secure It”. This thing they were calling DevSecOps was describing a holistic and systems approach to security as part of the software delivery pipeline.

    This notion of developer empowerment being a critical aspect to success was something I heard again and again at the recent 2018 Black Hat USA Conference. You can read more about my experience at Black Hat in this DZone article. But how do you effectively bring developers into the security fold? That is what we will explore in this multi-part series.

    In this first article, we will focus on what I (and many others) believe is the single most important factor for long-term success: the organizational culture. And by culture I am talking about the day-to-day environment of the organization the developer is a part of, and how they are (or are not) allowed to do their work. A successful DevOps culture is one that promotes collaboration to foster innovation and speed delivery, and the following two sections of this article depict perhaps the two most critical components for a strong DevOps culture: leadership and trust.

    It All Rises and Falls with Leadership

    Many would easily agree with the notion that long-term success for DevSecOps in an organization needs executive support and buy-in—and they would be correct—but real success needs much more than just budget approval and a shifting of resources. It needs ownership. It needs visibility. It needs truth-telling and that is where leadership comes in. According to the PuppetLabs “2018 State of DevOps Report,” 64 percent of C-Suite respondents firmly believed that security teams are involved in technology design and deployment, but only 39 percent of actual team members agreed. Bridging that kind of a gap requires breaking down traditional silos and evolving for better communication and transparency. The same survey also found that high-performing organizations were 24 percent more likely to use automated security policy configurations—a clear indication of tighter cooperation between security teams and the operations teams maintaining production environments.

    So, what are some of the key ingredients of successful leadership in this space? Glad you asked. Here are some things to look for:

    • Balance: Is the organization able to balance lowering technical debt with new work?
    • Shared ownership: Does everyone see how they contribute to business success and how their role impacts it? Is security included in that?
    • Shared learning: As projects progress and complete, is information moving across teams and projects? Are there best practices, lessons learned, etc., that are communicated both internally and externally?
      • Another way to think of this one: Is the level of “tribal knowledge” in your organization getting reduced?
    • Shared Vision Goals: Does everyone see and understand what matters most? Do they know the core metrics and KPIs, and how what they do impact them? Can they see their own success and bottlenecks?

    To have great success, you need leadership that defines the key standards, actively facilitates learning and collaboration and then provides the freedom necessary for innovation to occur. And there is another reason why you need it: Great leadership builds trust. Let’s explore that next.

    Your Speed of Delivery is Directly Proportional to Your Level of Trust

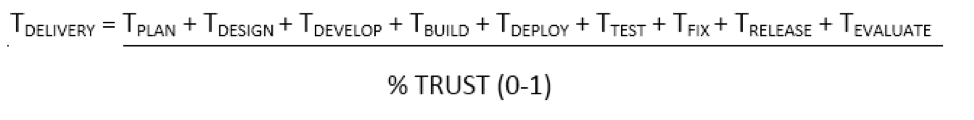
    The best depiction I have seen that correlates the speed of delivery with trust is this simple equation shared with me by DevOps Technical Evangelist Al Wagner from our mutual friend and Senior IT Specialist Lee Reid. It can also be found here. It simply states:

    Where “T” simply stands for time. In this simple equation, you can see that the HIGHER the percentage of trust is in the organization, the LOWER the overall value of the Time to Delivery will be, which is what we are all after. What that tells us is that today, businesses cannot tolerate a trade-off between speed and quality—you need both simultaneously.

    But how to you calculate trust?  In this model we are not talking so much about the work habits of the individuals as much as we are considering the outcome of each part of the process.  We  have to consider how often each of these areas “gets it right” versus how much we have to go back and rework.  Lee provides this example based on a client scenario:

    On a given project team the plan has about a 50/50 chance of being right, and the design is about 85 percent right, and the developers will get about 90 percent of the implementation right, and the testers have about 90 percent of the test cases right, and the release team has about 95 percent reliability of having the right stuff together to release, then your trust factor is something like

    .5 x .85 x .9 x .9 x .95 = 32 percent Trust

    Putting that back into the simple equation above, this level of trust means that your delivery time is three times longer than it could be.

    When my children were in elementary school and doing homework, I used to tell them that sometimes the best way to go fast is to go slow. The point was that if you wanted to solve problems you first had to understand them. Rushing to a formula or just trying combinations of numbers doesn’t work well and it ends up taking you twice as long to get done. This notion of trust and DevSecOps is similar and when you make the initial investment to build trust it can make a real impact.

    While it is true that adding application security to the Tplan and Tdeisgn parts of the process will initially increase those values, having application security as part of the software delivery process from the start—instead of at the end of a release cycle—will naturally cause the values for TDevelop, Tfix, and TEvaluate to shrink. This is largely because you are NOT having to go back to rework security into those areas midstream. It could also actually shrink Tplan and Tdesign over the life of the project for the same reason. In addition, the overall level of trust goes up because the risk that is associated with the delivered items decreases. We are more confident that artifacts are secure if vulnerabilities were identified early and fixed then.

    If you would like to learn more about how you can build trust, lower risk and make real business impact with application security, or to learn more about the potential impact of cognitive capabilities and artificial intelligence on your development efforts, download this complimentary Ponemon Institute study.

    — Rob Cuddy

  • Strategies to Build Trust in DevOps

    Strategies to Build Trust in DevOps

    I’ve been a member of the DevOps community a long time (literally since before it was ever even called “DevOps”). I was a pre-publication reviewer for both “The Phoenix Project” and the recently published “The DevOps Handbook,” and I’m always interested in seeing the outcomes successes software teams have and the failures they overcome, including trust.

    While DevOps has proven to be effective in organizations of all sizes—startups and enterprises alike—there are still many who have not yet begun their DevOps journey, so I thought I might share some of my own experiences while introducing DevOps into an enterprise IT group.

    When I was the VP of Operations at Big Fish Games, I had the responsibility for production operations at Big Fish’s three production data centers in Seattle, Virginia and Luxembourg. I also had responsibility for internal corporate IT and information security. Our production operations supported around a million game downloads per day. Games were localized into 11 different languages. We processed essentially every major currency, and right before I left Big Fish, we started taking Bitcoin as well. From an IT perspective, Big Fish Games was a global eCommerce company selling digital widgets on the internet. We had around 800 employees in our five offices in Seattle, Ireland, Oakland, Luxembourg and Vancouver, BC.

    My first attempt to introduce DevOps at Big Fish failed miserably due to cultural misunderstandings and a fundamental lack of trust between the development and operations teams.

    You absolutely need some minimum baseline level of trust in your organization if you are to have any chance at implementing DevOps. Trust is important because you are blurring traditional boundaries between development and operations responsibilities. Including development in production operations can be scary for operations teams. It just feels wrong from a historical ITIL-type perspective, and operations teams may know development as “the people who always break things.” At the same time, it can be scary for development to involve operations in the development process because they may know operations as “the team that always says ‘No.’”

    Building Trust

    Successfully merging the priorities and goals of development and operations teams to create one cohesive DevOps effort can fail due to cultural misunderstandings and, oftentimes, a fundamental lack of trust. I used three specific strategies to overcome these challenges.

    Lose the Term ‘DevOps’

    At Big Fish Games, application development teams equated DevOps with developers carrying pagers: an idea that they really did not like. They were highly resistant to this. Every time I brought up DevOps, they thought I was engaged in a secret plot to make the developers carry pagers. What I found interesting about this was that I had no intention of asking developers to carry pagers.

    The term “DevOps” covers a large range of continuous improvement techniques. Some organizations have developers carry pagers, and it works for them, but this is certainly not a prerequisite for DevOps. What was worse, I had no idea they were thinking this because they were afraid to bring it up for discussion. We failed in our first attempts to implement DevOps because the trust level between development and operations teams was so low that we couldn’t even tell each other what we were thinking.

    I realized two things from this experience:

    • Getting rid of a term that scared both development and operations teams would eliminate an unnecessary distraction preventing these teams from coming together to focus on common goals.
    • We needed to do something about the trust issues between development and operations before we could succeed with DevOps.

    Once I realized this, I immediately stopped using the word “DevOps.” Instead, I talked about continuous improvement and specific continuous improvement methodologies that we wanted to implement, and how these new adoptions would result in shared, organizational-wide growth.

    Focus on Methods That Benefit Other Teams

    When deciding which of these DevOps, a.k.a. “continuous improvement,” techniques we wanted to implement, I specifically chose ones that would benefit development teams as opposed to ones benefiting operations or other teams. The development teams noticed this over time. They could see I was doing this and that I (the person who ran operations) was going out of my way to help them. This helped build trust. This wasn’t a one-time thing. We did this consistently.

    Here’s another simple failure example: I noticed while managing release efforts that release schedules for the various development teams ranged from a couple weeks to a couple months—too long for a hyper-competitive industry like gaming. I asked the development teams if they would like our release engineering team to support daily code releases or even multiple code releases per day. I thought this was an innocuous question. In fact, I thought I was being a little clever by playing dumb here. I assumed I would get an enthusiastic high-five along with a, “Yes, we’d love that! How soon can you make that happen?!”

    I was surprised when I received a violent “No! We don’t want that!” This confused me for a while until I realized that the development team thought I was in cahoots with the product management team to put the squeeze on them. In my mind, I was offering to make their release process more lightweight so they could break up their work into smaller, more frequent releases with less stress for everyone, but I didn’t understand their fears and problems. I wasn’t looking at it from their perspective and here was the trust issue rearing up again. They misinterpreted my intentions as nefarious.

    I pictured them being able to release code whenever they want, which seemed like something they would like. In their minds, they pictured a product manager constantly randomizing them with demands for new features to be released right there while the product manager was leaning over their shoulder. This was not the kind of problem you could resolve with logic. The solutions and working procedures I was proposing were so far outside the development team’s experience that they couldn’t extrapolate through simple logic from their current state to the world I was describing.

    Maximize Daily Interactions Between Development and Operations Teams

    It’s easy to distrust someone you don’t know personally or you don’t have to see every day. It’s a lot more difficult to hate on someone you know and work with on a daily basis.

    One of the DevOps techniques that I implemented early on was embedding a dedicated operations liaison into each development team. This liaison acted as an advocate for that development team back into operations and they helped smaller development teams navigate their work through a large, complex, centralized operations organization. The operations liaison attended daily development team standups, group meetings and project meetings. This program was a huge success. Development teams saw how their operations liaison helped expedite their work through the operations organization and advocated for their development team’s interests inside operations.

    After the development teams got used to working with their operations liaison on a daily basis, we pushed a bit farther and got the development teams to agree to include operations in architectural discussions at the beginning of application design. At first, our development teams were skeptical that operations could provide useful input here, but the important thing is we had developed enough mutual trust that they were not fearful of including operations in the discussions. They were skeptical that we would add any value, but they weren’t afraid that we would cause them problems. This was a big win.

    Although it felt a little weird to our development teams to include operations in design discussions, they quickly saw how obtaining input from operations early on, before a product was built, resulted in better quality and fewer headaches for everyone when we launched into production. I also made sure that we put our most senior and diplomatic operations team members into this role.

    In conclusion, it is worth repeating that trust is a prerequisite for any organization to succeed with DevOps. This is due not only to problems arising from fuzzy definitions of what DevOps is and is not, but also the seemingly dangerous idea of blurring the boundaries between development and operations organizations. Whatever your definition of DevOps is, fostering an increased level of trust between development and operations teams as a prerequisite for your DevOps journey will ensure that even greater trust—and the positive business impact that comes with it—are your outcomes as well.

    Good luck!

    About the Author / Paul Farrall

    Paul Farrall is the VP of Operations for Skytap. He was most recently vice president of Operations at Big Fish Games where he led the rollout of global infrastructure for the Big Fish cloud gaming platform and implementation of the Big Fish DevOps program. Prior to Big Fish, Paul was the Director of Operations and Chief Information Security Officer at Intelius, a Bellevue e-commerce company. Previous companies also include AT&T Wireless in Bothell, Washington, and GetThere.com in Palo Alto, California (now Sabre). Connect with him on LinkedIn and Twitter.
     

  • Trusting Continuous Delivery

    Trusting Continuous Delivery

    DevOps, continuous delivery and the pipeline for faster software development are fundamentally different from traditional software development. It’s such a different approach and a different culture that it can take some time before Dev and Ops teams embrace and trust it—a necessary step for DevOps to make progress in any organization. By mixing containers and their value proposition into DevOps, this new software creation and deployment paradigm can readily foster that trust.

    What Continuous Delivery Brings

    DevOps and continuous delivery offer application development using containers, providing the required level of trust to get over that hump and move things forward. According to David N. Blank-Edelman, a DevOps veteran and currently technical evangelist at Apcera, the following container features lead to trust because they answer Dev and Ops concerns:

    • Containers are resource-friendly replacements for virtual machines, built to encase the coder’s development environment
    • Containers are the complete package format replacement, possessing everything you need to run an app
    • Containers create an abstraction that enables development and its results to sit in a host in any of a number of infrastructures including on-premise and inside any of several public cloud providers
    • Containers are the fastest means to launch short-lived, purpose-built testing sandboxes as part of a continuous integration process
    • Containers are the end result of a build pipeline (artifact-to-workload)
    • Containers form the boundary for loosely coupled components as part of a larger app or service. Such is the case, for example, when each part of a microservice-based app lives in its own container

    According to Blank-Edelman, the aforementioned features imbue trust because they satisfy the following Dev and Ops queries:

    • Is the container allocated to use only the resources it should?
    • What resides in that container / workload?
    • Where did that container come from? Is it OK from a security, coding and business requirements perspective?
    • Where is the container permitted to live and run such as in what cloud, environment, country, and in proximity to other containers technically?
    • Can the container communicate with only the things it should such as other containers and any hypervisor or other management resource? “If I move the container to another location, do the answers to these same questions still apply?” asks Blank-Edelman.

    Though these questions express concerns in direct and simple language, experienced DevOps engineers who have felt the frustration of building development processes and attendant infrastructure understands these are difficult questions to satisfy. Without modern containerization efforts to sustain DevOps, development and production goals grow further out of reach.

    The Importance of Policies

    As containers undergird DevOps and continuous delivery, policies support containers. Developers input changes and innovations in code to the continuous delivery pipeline. Developers then respond to the needs of the growing code in a nurturing fashion, fixing errors and enabling new features. This pipeline works when automation, together with each progressive step in the development process, lays a foundation for the next step in a predictable and reliable manner.

    “Here’s where it gets tricky: First, not only do you have to be able to answer the trust-related questions for each step, but it is entirely possible (and entirely likely in an enterprise environment) that different people/teams will share control of and input to each step on that path,” says Blank-Edelman. With so much collaborative effort in play juggling all these pieces, policies are necessary to configure these steps, address networking and other elements, and control the component parts of the process ahead of time and everywhere along the way.

    Policies that make particularly good container watchdogs include those that set steps in the DevOps/continuous delivery pipeline apart, hemming them in on all sides. “Just like having your papers in order makes for an easier border crossing when you travel abroad, so, too, does having your policies reflect the trust required to move from one step to another,” says Blank-Edelman.

  • The complexity of communication: Are we all Masters of Disaster?

    The complexity of communication: Are we all Masters of Disaster?

    To better the communication between people in tech teams is one important issue in daily work. Although we all grew up with communication from our early childhood on, we know, that communication often fails. But what do we all do about this discrepancy? Why do we accept eyes wide open these frequently painful failures? Why don´t we really care about misunderstandings and their consequences? Are we all Masters of Disaster?

    The answer is: Communication is a very complex topic on both sides of the game – on the sender´s side as well as on the receiver´s. To get aware of what is going wrong in our communication we have to do some very hard stuff: self-reflexion (which is indeed sometimes painful and hard to bear), changing familiar behaviors and leaving the comfort zone. This is really hard work besides all the tasks of our daily job! Additionally to a strong will, we need persistence, patience and most of the time aid from the outside to be successful in changing our communication! But in the end this entire struggle is worth it!

    In DevOps teams, where “ship fast” is taken over from “ship faster” to fulfill the goals of “continuous of everything”, a well accepted and effective, but appreciating communication is the basic skill for success. This means that building a successful team is comparable with building a house: if you spend enough in a strong and solid fundament, it will carry the house you want to build on it for a long, long time. But you have to consider, which kind of house you want to build to develop the fundament.

    In cross-functional teams with high demands – those teams we actually find in the tech industry – communication is the fundament of whatever is built on it. Communication is part of the culture and it is the tool

    • people get in contact with each other
    • knowledge is shared
    • goals and visions are shared
    • feedback is given
    • failures and success are shared
    • appreciation is shown.

    People in such demanding environments need to trust and rely on each other. Or do you want to share your knowledge with someone you do not trust? The success of the team depends on the relationships between all teammates including the leader. Relationship and trust are built among other things through the way we communicate with each other. No it is time to say, that communication is not only what we are saying with the words we are using. Communication goes far beyond the meaning of the words. Remember “Cce” – Communication causes emotions! Even in the tech world, which is still a male dominated world, communication causes emotions and feelings – although lot of people may refuse this.

    With speaking about the complexity of communication it means that there are on the one hand three different parts of sending a message and the impact on the receiver. On the other hand there are lots of possibilities how to interpret the messages. Lots of possibilities – this seem to be a source for many misunderstandings! Now be aware that an immense part of our communication – sending as well as receiving – happens in our subconscious!

    Most probably you have heard about the three different parts of communication: the verbal communication and the nonverbal communication with its subitems ´paraverbal communicationand ´body language.

    The verbal communication is about the wording, the language, the syntax, the grammar and yes, it is also about the logic! There you are: “Things have to be logical, then everything is fine, isn´t it?” Sorry, but: “No, it isn´t!” It is even not half of the truth. Here is the reason, why so called one-track specialists often have problems to convince others, although everything they say is absolutely right and logical. At this point the nonverbal communication appears on the human playing area! The paraverbal part of communication contains facts like the volume, the speech rate and melody, the intonation and articulation and at least the tone of the voice. This is completed by the body language with the fascial expressions the gestures, the body posture, eye contact, body chemistry and the clothing. If the expression of all three components is the same – then everything is fine! If the verbal communication says “YES” and the nonverbal communication “NO” – then people tend to believe in the nonverbal communication because its impact is much higher than the impact of the words.

    Just one example at the end: at one of the DevOpsDays I have joined this year, I saw one young speaker. I guess, he is really an expert in his topic and the idea and content of his talk was excellent. But he didn´t manage to appear convincing and convinced: a wrinkled shirt, a loose jeans, unkempt hair, barefoot in his sandals, a lousy body posture and a bored facial expression. You can say that this is a superficial point of view. Maybe – but that is the way it works! Communication always needs a holistic approach – and seemingly superficial points of view are influencing the our feelings and the way we interpret messages! Or to say it the other way round: if you want to convince somebody and make her/him trust you, you have to focus on all parts of communication! It is the same when you want

    to share knowledge, give feedback or want to lead a team. Communication is more than just the words!

    In the next blog post you will read about the chain of communication!

  • The Art of DevOps

    The Art of DevOps

    This is the third in a series of posts on DevOps. The first written by my colleague Lee Reid was titled The Simple Math of DevOps. The second The Calculus of DevOps was written by IBM client, and my friend Carmen DeArdo of Nationwide. Lee introduced mathematically improving delivery throughput by leveraging DevOps to improve Trust. And Carmen used Calculus to imply that the business value of IT can be improved by adopting DevOps to increase the frequency of releases. In my post I would like to visit the art of DevOps , or the art of adopting DevOps by picking up right where Carmen left off – by looking at the culture side of adopting DevOps.

    Lee and Carmen have already alluded to some basic premises behind DevOps as an approach – reducing batch sizeand improving collaboration. These result in reducing complexity, increasing throughput, and improving trust. Let’s talk about how to get there.

    As I have worked with customers adopting DevOps, across company sizes, across industries and countries, there are four common threads that make DevOps adoption successful, leveraging all three aspects of DevOps adoption – culture, process and automation. These are:

    1. Reduce batch size: The most effective way to manage risk and quality, while increasing speed is to reduce the batch size in each iteration or ‘sprint’. This is a mind shift to release smaller, more frequent new versions. Where it is not possible to release new versions that frequently to customers, release small batches to a pre-production area. The deliverable in pre-production is tested and made customer-ready, and then released to the customer at formal release dates. As Lee and Carmen have both discussed, reducing batch size is a pre-requisite to improving both trust and business value.
    2. Shift-left Operational engagement: Get operations engaged right from the beginning of a project/initiative. This has been a core principle of DevOps. Do not leave Ops in a silo that one throws code over the wall to, but have them engaged in the development process, right from requirement inception stage. This allows Ops to have visibility into what is coming from Dev; allowing them to deliver the right production-like environments, as and when needed to Dev and Test teams. It also allows Ops to shift operational concerns left, left into the minds of developers, making them more Ops conscious and engaged in what happens after they hand-off to Ops.
    3. Continuous funding: This is a significant change in an organizations funding model to enable continuous availability and engagement of SMEs and business functions, previously not engaged on a continuous basis – like security, legal, marketing, etc. Carmen in his post mentioned several examples of ‘waiting for…’ work, someone else to do something and environments. Another ‘waiting for’ in enterprises is for funding. Funding is typically provided in a waterfall manner, with specific hard dates (Months, quarters, fiscal year) and gates, not suitable for a Continuous Delivery model. Funding too should be continuous.
    4. Create a ‘Product Management’ team: This team includes a Designer, Development lead, operations lead and an Architect at the minimum (4-in-box). They own the ‘product’ through its entire lifecycle, and beyond transient projects. They are responsible for long-term thinking, design thinking, evolutionary architectural thinking, and overall ownership of the product, from concept to end-of-life.
    5. Setting up a DevOps Center of Excellence (CoE): This center of excellence is not an administrative organization or a ‘tools/enablement group’, but a place where DevOps adoptees come to learn from each other and share expertise and lessons learnt. As organizations adopt and scale DevOps adoption, this CoE also becomes a source of DevOps coaches, helping teams and programs adopt DevOps, and own the organizations DevOps framework – their own flavor of DevOps.

    Adopting DevOps is an art. It is not as simple as hiring a consultant who can show how to improve processes; it is not just buying and adopting tools to automate manual tasks; and it is not going through ‘fall-back-into-the-arms-of-the-person-behind-you’ exercises to build trust. It is a combination of all three – process improvement, organizational and cultural change, and automation with tools to replace manual processes. Adopting these in any enterprise, outside of startups, requires overcoming organizational inertia. By changing culture not by edict, but by showing the need and value of change. By building trust, not through meetings, but with improved communication and transparency. By improving business value, not by measuring mandated KPIs, but by improving organizational agility and throughput. Overcoming organizational inertia, by delivering towards a common goal for the business, irrespective of where in the organization one is, and what role one has. By developing a culture where everyone takes responsibility of delivering value to the business.

    Watch the webcast series hosted by devopsy.kinsta.cloud in partnership with IBM or download a copy of DevOps for Dummies book for more information.

    About the Author/ Sanjeev Sharma

    SanjeevSanjeev Sharma, CTO and Distinguished Engineer – DevOps Technical Sales and Adoption, IBM Cloud Unit, is a 20-year veteran of the software industry with expertise in DevOps, Mobile Development and UX, Lean and Agile Transformation, Application Lifecycle Management and Software Supply Chains. He is a DevOps Thought Leader at IBM and speaks regularly at conferences. He has written several papers and is the author of the DevOps for Dummies book.


    Contact Sanjeev on linkedintwitter

  • The Calculus of DevOps

    The Calculus of DevOps

    This is the second in a series of blogs, partnering with Lee Reid, who wrote the first installment “The Simple Math of DevOps” and Sanjeev Sharma both of who are outstanding DevOps Thought Leaders from IBM.

    I am picking up on Lee’s mathematical DevOps model to apply a calculus perspective, a “calculus of DevOps” if you will, (OK, not quite core Big Bang Theory Calculus but rather approaching it from the aspects of engineering queuing theory).

    One of the cultural challenges that DevOps poses is, that some aspects of it run counter to engineering principles that many of us learned with respect to capacity and response time.   When I worked at Bell Labs, we would apply queuing theory to determine how to best package information to be sent across the network. A basic premise revolved around a tradeoff between throughput and response time. On one hand, the more messages that were packed into the packet, the more the payload would improve capacity because the overhead of processing the packet of information would be spread across the messages.   However, waiting to accumulate enough call processing information meant that the packets would be transmitted less frequently, increasing the response time.

    A simple example of this would be making trips to the grocery store. If one wanted to spend the least amount of resources (time, gas, car wear, etc.) on shopping, then one would make less frequent trips and then buy a larger amount of food. So if the Smith family made one trip a month and spent 2 hours, then their average time per week spent on shopping would be 30 minutes.   If the Jones family went every week and spent an hour, then they would be spending twice the time and four times the gas on grocery shopping. However if the Smith family run out of an item (say cereal), they would have to wait, on average 2 weeks before this was replenished. The Jones family average on any item that they ran out of would be 3.5 days in comparison.

    So when the 2014 DevOps report was published[1] which states that areas that deploy more frequently get customer feedback more quickly, that is to be expected. But what’s not expected is that these organizations also have higher productivity.   So exactly what is happening here that seems to be in a basic conflict to the principles of throughput and response time?

    Keeping up with the JONESES

    If we think of a pre- DevOps state for a medium to large enterprise, it may be typical for applications to only be released (deployed into production) a few times a year to provide business functionality. (I assume there are more frequent releases for “unplanned work” like defects and other changes or operational work). For the sake of this discussion, let’s call this the Smith Application. So from a business perspective, the business wants to pack as much work into the Smith releases as possible given they only have a few cracks a year at getting new business functionality into production.

    SMITH APPLICATION CHARACTERISTICS:

    • Deliver Business Value 3 times a year (every 4 months)
    • Cost is C1
    • Business Value (BV) delivered is V1
    • Average time from concept (e.g. Story) being ready to be pulled from the backlog to the time it is delivered to the customer is 2 months plus any additional wait times (e.g. prioritization)
    • BV delivered per year is 3*V1
    • Cost per year is 3*C1

    Now let’s transport over to the Jones Planet where the application is released into production with new business capabilities at the end of every 2 week iteration.   In this case the business is more concerned with providing a constant demand flow into IT than they are with debating over whether a given feature/story is going to be included in this particular release.   Instead there is a constant prioritization (or continuous planning) process that ensures the highest value work is being fed into the IT pipeline.

    JONES APPLICATION CHARACTERISTICS:

    • Deliver Business Value 26 times a year (every 2 weeks)
    • Cost is C2
    • BV delivered is V2
    • Average time from concept (e.g. Story) being ready to be pulled from the backlog to the time it is delivered to the customer is 1 week plus any additional wait times
    • BV delivered per year is 26*V2
    • Cost per year is 26*C2

    Based on the previous engineering analysis, we would expect the following:

    1. SMITH annual cost (3C1) < JONES Annual Cost (26C2)
    2. SMITH annual BV (3V1) > JONES annual BV (26V2)

    So the tradeoff (we would believe) JONES is making by delivering more frequently is that they are spending more money and are delivering less business value on an annual basis.

    However the data from the previously referenced DevOps report is just the opposite. In fact the findings are that enterprises that deploy smaller units of work more frequently have much higher quality and much higher productivity (Capacity). So what’s going on here?

    A NEW PARADIGM

    If you go up to any IT team (even an agile one) and ask them why they don’t deploy business value more frequently, they will generally refer to the following types of wait states of waste that they encounter:

    • Waiting for work (lack of consistent flow)
    • Waiting for somebody else to do something (dependencies from other teams)
    • Waiting for environments (contention)

    One major root cause of this is the dependencies that arise from large enterprises packing a lot of work into infrequent releases. From a planning perspective, the process is elongated due to prioritization discussions because being on the wrong side of the line can mean delay amounting to months, in delivering a product to a customer.   Ask a business portfolio leader what their highest priority is for IT and I am guessing they can tell you in a matter of seconds. However, most large organizations can spend several months a year planning their annual portfolio of work for IT. Some organizations spend more than 50% of their new project build time prior to a single story entering an agile development team’s backlog!

    From a development perspective, packing a lot of work into releases means many more dependencies that have to be managed across initiatives and impacted applications. From a testing perspective, downstream environments (ST, UAT) have to manage much more information in terms of application versions and especially test data that complicate and slow down the process. The complexity of test data increase is proportional to the number of pairwise relationships that exist within the datasets required for testing.   As such, the testing complexity will increase non-linearly (perhaps proportional to the square of the dependent systems) and from a release and change perspective; there is a lot of coordination necessary given how much is being changed at one time.

    All of this work to manage all of the dependencies found in medium to large enterprises completely eliminates any potential savings one might get from batching work into a single delivery. In addition, the possibility of having to pull some work out of a release (due to quality or business readiness or some other reason) sometimes leads to complicated source code management (feature branches in some cases) that further complicate the process of merging frequently into the trunk. These types of practices also serve to drive up technical debt. So looking at the problem from this angle shows why results we are seeing make perfect sense.

    Productivity is inversely proportional to the number of dependencies in a release

    As Lee related to in the initial blog, a lot of an organization’s success depends on trust. And one factor of trust is clarity which speaks to understanding the changes that each release is bringing to the IT and customer environments. So a factor that is working against trust is the notion of delivering more things less frequently and better controlling change somehow, is a good notion.

    Trust is inversely proportional to the number of dependencies in a release

    There is another hidden component of waste associated with “big bang” initiatives. Go back to our grocery example for a moment. Chances are that the Smith monthly excursion results in buying some stuff they end up not using. Perishable items are not spread out very well when they aren’t purchased more frequently. Likewise in IT planning, we tend to put a bunch of stuff in our IT Delivery basket that we don’t know for sure that we will need and we end up with a lot of wasted effort for features that are hardly used or not needed at all. Some enterprise estimates are that 50-65% of what they put into large releases does not actually result in true value to the business. Doing more frequent releases allows a constant discovery process to better guide the usage of IT resources on what is truly of value.

    Waste is proportional to the size of a release.  

    In other words:

    Yield (Value per IT investment) is proportional to the frequency of releases.

    REVISTING THE MATH OF DELIVERY TIME

    So if we revisit Lee’s model

    Lee Reid Blog equationand apply the “Calculus of Release” as we stated above, there are increased costs associated with having larger and less frequent releases in medium/large enterprises.

    • Planning cost TPLAN
    • Development complexity TDESIGN + TDEVELOP + TBUILD
    • Testing Complexity TTEST
    • Release and Change Management Complexity TRELEASE + TDEPLOY + TEVALUATE

    TRUST % – Even if everything was proportional between the JONES and SMITH models, the component of trust that impacts clarity, consistency and collaboration, is much lower for large (SMITH) releases.  Given that TRUST has a multiplicative impact, this alone can account for the results found in the studies.

    CULTURAL CHALLENGE

    While clearly one needs to be sensitive to the changes being introduced into the business, having the ability for the business stakeholders to pull capability when they want it and having it available more frequently is not only good for customers but also has extreme benefits from an IT perspective in terms of increased productivity and reduction of technical debt. The challenge is to convince leaders in both the business and IT areas on the merits of doing more continuous planning and frequent deliveries.   Unicorns may have led the way in this type of thinking but it is actually the horses that will benefit most from this type of culture shift because it is the horses[2] that have the most to gain in mitigating the dependency factor which can undermine quality, productivity and cycle times.

    Read more about the topic in the next blog of this series The Art of DevOps by Sanjeev Sharma.

    [1] “2014 State of DevOps Reports”, Puppet Labs, IT Revolution, https://puppetlabs.com/sites/default/files/2014-state-of-devops-report.pdf

    [2] “The Phoenix Project”, Gene Kim, Kevin Behr, George Spafford, http://www.amazon.com/The-Phoenix-Project-Helping-Business/dp/0988262592


    About the Author

    CarmenCarmen DeArdo is the Director of Application Development Tools and Technologies at Nationwide Insurance. Carmen is responsible for driving continuous delivery utilizing DevOps, Lean and Agile techniques across Mobile, Distributed and Mainframe and other technologies. This includes recommendations and implementation of technologies used across the development life cycle (e.g. IBM Rational tool suite, open source technologies).