Tag: traces

  • Cisco Extends Scope and Reach of Observability Platform

    Cisco Extends Scope and Reach of Observability Platform

    Cisco this week expanded the scope of its observability platform by adding predictive and generative artificial intelligence (AI) capabilities along with log analytics and a Core Web Vitals tool to make it simple to ensure web pages don’t lose their search engine ranking because of poor user experience.

    In addition, Cisco is now leveraging extended Berkeley Packet Filters (eBPF) in the kernel of Linux operating systems to provide visibility into Kubernetes workloads and a session replay capability for cloud-native applications. In addition, Cisco has allied with Komodor, a provider of a Kubernetes management platform, to gain additional visibility into these environments.

    Cisco also added digital experience monitoring (DEM) capabilities based on real user monitoring (RUM) and the full-stack observability it provides following its recent acquisition of Accedian, a provider of an analytics platform for monitoring end-user experiences.

    Finally, Cisco added a Data Security Posture Management (DSPM) Observability module to the company’s Business Risk Observability platform based on the same core platform.

    Announced at a Cisco Live EMEA event, these latest updates are part of an ongoing Cisco effort to extend the reach of its observability platform well beyond DevOps workflows.

    Gregg Ostrowski, executive CTO for Cisco AppDynamics, said as part of that effort, Cisco is making it simpler to aggregate telemetry data for the AI for IT operations (AIOps) capabilities it provides by pulling directly from platforms such as Cisco ThousandEyes and Cisco DNA Center as well as from third-party partners such as VMware, Zabbix and ServiceNow. Similarly, Cisco is now leveraging eBPF to collect data from Kubernetes environments.

    Ostrowski added that the overall goal is to reduce the amount of instrumentation effort that IT teams would have to undertake to instrument highly distributed IT environments.

    There will still be a need to instrument applications, but the collection of telemetry data from the underlying IT infrastructure environment is going to be increasingly automated, he noted. In the meantime, it’s become less expensive to instrument applications using open source OpenTelemetry agent software, added Ostrowski.

    In general, Cisco, in addition to enabling organizations to rationalize existing tools, is also making a case for improving collaboration by, for example, making use of natural language capabilities enabled by generative AI to launch queries and provide summarizations.

    At the same time, Cisco is partnering to add additional capabilities, such as the ability to monitor machine learning algorithms via an alliance with Aporia and AS/400 systems via an alliance with Perform IT.

    Ultimately, Cisco is betting that observability across the entire enterprise IT environment is going to become more unified as organizations increasingly look to correlate business processes with specific IT events, including indications of cybersecurity breaches. It’s not clear how far down that path enterprise IT organizations are just yet, but given the total cost of observing and monitoring IT environments today, there is more pressure than ever to find more cost-effective approaches to holistically managing IT. The challenge, as always, is unifying all the existing fiefdoms in IT organizations that have already embraced a wide variety of tools and platforms they are hesitant to give up.

  • Observe Inc. Brings Generative AI to Observability

    Observe Inc. Brings Generative AI to Observability

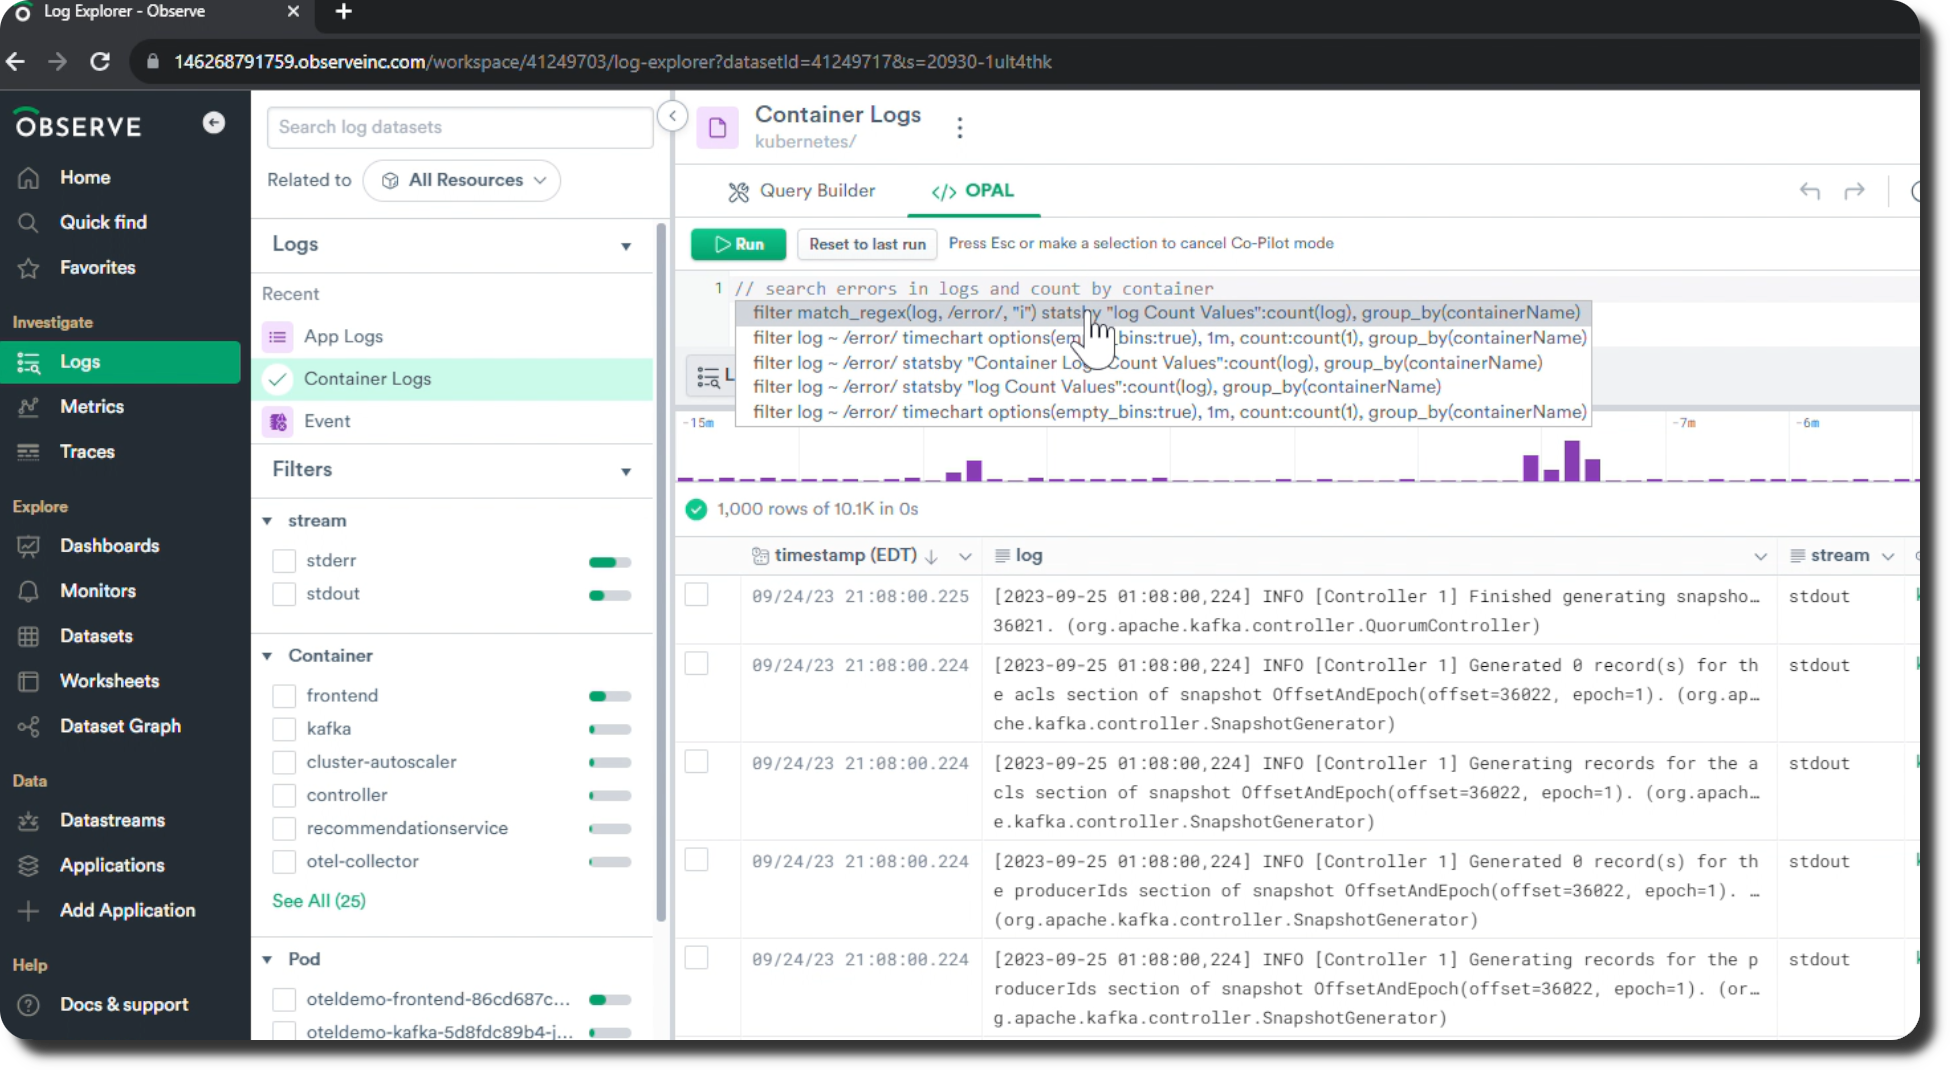
    Observe, Inc. today revamped the Hubble user interface to its observability platform that has been infused with generative artificial intelligence (AI).

    Fresh from raising an additional $50 million in funding, Observe CEO Jeremy Burton said as the company’s software-as-a-service (SaaS) platform continues to be infused with AI using multiple large language models (LLMs), it’s becoming apparent that observability is rapidly becoming democratized.

    Most IT organizations still rely primarily on legacy monitoring tools to track a set of predefined metrics. Observability platforms have arisen to aggregate metrics, logs and traces to enable DevOps teams to launch queries and surface the root cause of performance issues or IT incidents. The challenge is that most observability platforms have required IT teams to master a proprietary query language such as Observe’s RegEx.

    However, with the rise of generative AI tools, it is now possible for IT professionals of all skill levels to employ a natural language chatbot to generate a RedEx query, noted Burton. A RegEx generation tool also parses data to add structure to logs on-the-fly, and there is also an OPAL Co-Pilot that generates OPAL code in response to natural language inputs.

    Observe

    The Hubble interface furthers those capabilities by simplifying the onboarding experience anytime there is a new member added to an IT team, he added. Hubble also expands the range of data access options available, including a public application programming interface (API), a command line interface (CLI), export to CSV and data sharing to the Snowflake cloud platform.

    IT teams are also coping with an explosion of telemetry data generated by modern distributed applications based on microservices architectures. Legacy observability and monitoring tools were not designed for these data volumes, so when there is an incident, the mean-time-to-resolution (MTTR) is increasingly extended. In contrast, the Observe platform now features a ‘Live’ mode that enables data to be queried in 20 seconds or less from when it was created.

    Other capabilities include an assistant embedded in Slack to help users troubleshoot issues and summarize threads for incident response.

    While it’s still early days as far as the adoption of observability platforms are concerned, there is already no shortage of options. The pending acquisition of Splunk by Cisco next year will cause more organizations to reevaluate their IT management options, so the pace at which organizations are transitioning to cloud-hosted observability platforms should increase, noted Burton. Even after the merger is completed, it might be several more months before Cisco integrates its AppDynamics platform with the observability platforms that Splunk added to its IT operational analytics platform, he added.

    In the meantime, IT environments are only going to become more complex. It won’t be feasible for most IT teams to manage highly distributed computing environments without some help from AI. The challenge, as always, will be finding the budget dollars needed to deploy an observability platform before the number of increased IT incidents makes the need for one painfully obvious.

  • Mezmo Simplifies Management of DevOps Telemetry Data

    Mezmo Simplifies Management of DevOps Telemetry Data

    Mezmo has added additional capabilities to streamline the flow of telemetry data within DevOps workflows as part of an effort to make it simpler to surface insights and reduce the total cost of observability.

    The company has also added integrations with more data sources to the Telemetry Pipeline platform, along with controls that make it simpler to optimize data storage and usage. For example, an Events-to-Metrics Processor capability identifies and extracts metrics from logs to make them easier for third-party tools to consume.

    Mezmo CEO Tucker Callaway said these additions collectively make it simpler to surface insights that will make DevOps workflows more efficient. Previously, the company added capabilities such as rollback and redeploy, sequential parsing, error history management and data sample management to enable DevOps teams to manage telemetry data more efficiently.

    In effect, Mezmo is making it easier to apply engineering best practices to the massive amounts of telemetry data generated across DevOps workflows, he noted.

    No one knows for certain if all that data will require the addition of data engineers to DevOps teams, but as DevOps continues to evolve, it’s clear there is a need to cost-effectively manage data at scale. DevOps teams that embrace observability are quickly discovering that storing logs, traces and metrics for an extended amount of time can quickly become cost prohibitive. Naturally, there’s a lot more sensitivity to those costs during challenging economic times.

    In theory, of course, various forms of artificial intelligence should automate data engineering best practices, but in the meantime, there simply isn’t enough data engineering expertise available. The need for a platform to optimize the flow of telemetry data across DevOps workflows is becoming more acute.

    It’s not clear how quickly DevOps teams are embracing observability, but it’s clear that relying on predefined metrics to monitor IT environments is no longer sufficient. DevOps teams need to be able to query telemetry data to, for example, identify bottlenecks created by dependencies between microservices. Resolving those issues can’t be slowed down by a lack of data to query. Most problems can usually be traced back to a recent update to an application, but there are always going to be some issues that require access to historical data. That historical data should be quickly and easily available, especially since application downtime directly equates to lost revenue for many organizations.

    Observability, regardless of cost, is rapidly becoming a requirement for DevOps teams’ success as application environments become more complex in the cloud-native era. Dependencies between the microservices that make up those applications are too difficult to track and analyze without the aid of an observability platform. The challenge is not every observability platform provider is equally concerned about how much it costs to store all that data. Striking the right balance between the amount of telemetry data collected and the cost of storing it has become a much larger concern.

  • Webb.ai Launches AI-Based Continuous Root Cause Analysis

    Webb.ai Launches AI-Based Continuous Root Cause Analysis

    Webb.ai today opened an early access program access to a Continuous Automated Root Cause Analysis platform that uses artificial intelligence (AI) combined with a knowledge graph to dynamically keep track of and analyze changes to IT environments.

    Manish Gupta, CEO of Webb.ai, said the platform uses a mix of machine learning algorithms and generative AI capabilities based on large language models (LLMs) to aggregate alerts into higher-order insights that are presented in natural language to members of a DevOps team.

    That approach differs from legacy approaches because it tracks causal relationships between changes versus relying on probabilistic models that tend to create a lot of false positives, he noted.

    Webb.ai is also taking advantage of Kubernetes clusters to enable its platform to scale up and down as needed when analyzing data, added Gupta. That platform is also more efficient than other approaches to observability that require IT teams to store massive amounts of data. In contrast, the Continuous Automated Root Cause Analysis automatically surfaces anomalous events that DevOps teams can choose to save rather than requiring them to save all the metrics, logs and traces that would otherwise need to be tracked, he noted.

    Most IT incidents can be traced back to the most recent changes made to an IT environment. The challenge is as IT environments have become more complex, it’s not feasible for humans to keep track of those changes without relying on AI and a knowledge graph, said Gupta.

    As businesses become more dependent on software to drive digital processes, the cost of downtime is exponentially increasing. The need to identify the root cause of an IT incident as fast as possible has become a critical requirement, he added.

    Webb.ai doesn’t see AI technologies replacing the need for DevOps professionals and site reliability engineers (SREs) for at least another 10 to 15 years. In the meantime, many tasks that today are completed manually will be increasingly automated, said Gupta. A DevOps engineer dragged out of bed at 2:00 A.M. to address an issue does not want to have to sift through alerts. Instead, generative AI tools will summarize the issue at hand with recommendations on resolving it, noted Gupta. In effect, DevOps teams will be augmented by AI so they can manage IT environments at even higher levels of scale, he said.

    There is always going to be some sense of fear and loathing when it comes to AI, but ultimately, AI should reduce the burnout rates that today adversely affects any organization’s ability to retain DevOps professionals. Far too much time is spent trying to identify the root cause of a slowdown in a cloud-native application’s performance that could be caused by any number of issues involving one dependency or another. The frustrating thing, of course, is that while it may take days to identify the root cause of an issue, it often takes just a few minutes to resolve.

  • Mezmo Adds Free Community Plan for Managing Observability Data

    Mezmo Adds Free Community Plan for Managing Observability Data

    Mezmo this week added a free trial and a community plan for the Mezmo Telemetry Pipeline service to make it simpler for DevOps teams to store and manage the large amounts of telemetry data they are collecting.

    Mezmo CEO Tucker Callaway said as more DevOps teams embrace observability to minimize disruptions to application environments, they are struggling to manage the explosion of data being created. The Mezmo platform makes it possible to apply data engineering best practices to manage that data using a set of drag-and-drop visual tools, he added. A set of data transformation tools also makes it simpler to extract metrics embedded in the logs, summarize events and metrics and then forward those metrics to downstream platforms for analysis.

    The free edition of the platform makes it possible for organizations to begin to apply those capabilities without any upfront costs required, noted Callaway.

    It’s not clear to what degree DevOps teams may need to add data engineering to manage all the telemetry data being collected. It’s already apparent that the cost of storing and managing all that data is becoming a significant issue as more applications are instrumented. In fact, it’s nearly impossible to manage cloud-native applications without being able to observe interactions between the microservices used to construct them.

    Log management has always been a challenge, but with the addition of traces, the amount of telemetry data being collected to surface metrics has increased. The Mezmo platform makes it possible to set a daily or monthly hard limit on the volume of logs stored or, alternatively, set soft daily or monthly quotas that can apply throttling logic to ensure mission-critical log data will continue to flow.

    DevOps teams can also make use of soft limits to reallocate storage resources from one team to another based on how much log data might be generated for a specific amount of time.

    Reducing storage costs has naturally become a higher priority during challenging economic times, so there’s a lot more pressure for DevOps teams to be more efficient. Finance teams are reducing costs by, for example, applying quotas to the amount of storage resources being made available to individual DevOps teams. The days when cloud storage resources were made available indiscriminately are over.

    It’s not clear how quickly DevOps teams are embracing observability, but it is certain that relying on predefined metrics to monitor IT environments is no longer sufficient. DevOps teams need to be able to query telemetry data to, for example, identify bottlenecks that are often created by dependencies between microservices. The issue is striking a balance between the amount of data being collected and the cost of storing it all.

    Regardless of approach, observability is rapidly becoming a requirement for DevOps teams to succeed. In fact, there is already no shortage of observability platforms to choose from. The issue is that not every observability platform provider is equally concerned about the cost of storing all the data being collected.

  • Why Observability is Important for Development Teams

    Why Observability is Important for Development Teams

    Observability, which allows development teams to understand better how their systems behave in production, is critical to successful software delivery. According to Gartner, by 2026, 70% of organizations that successfully applied this practice will achieve shorter latency for decision-making, enabling competitive advantage for target business or IT processes.

    Observability allows development teams to identify and diagnose issues quickly to make decisions that improve overall software delivery performance. Let’s take a closer look at why this practice is critical for development teams.

    Differentiating Observability and Visibility

    To better understand observability, it’s essential to clear up a common misconception – that observability and visibility are the same. Two critical differences exist between the two. Visibility allows development teams to look at the surface-level aspects of an application or system. In contrast, observability provides deeper insight into what an application is doing in production. Being equipped with a deep knowledge of observability allows developers to be more productive within their respective organizations.

    Impact on Developer Productivity

    With observability, developers can identify and diagnose issues within applications quickly, giving them more time to fix bugs and time for resolution, which are both critical success factors for software delivery. Observability allows organizations to quickly identify and respond to potential problems, such as operational issues or security breaches, before they become issues that impact customers or users. While there is no such thing as perfect software, observability helps developers quickly find and fix issues, bottlenecks, inefficiencies, etc., so they can get back to doing what they love: Creating new software.

    With the benefits of observability, developers naturally gravitate toward tooling and technology. There are many tools available for developers to take advantage of, and development teams must learn how to use these tools to integrate them into their applications and services. Let’s explore some of the more popular options.

    The Shift to Cloud-Native Tools

    The shift to cloud-native tools is driven by the increasing popularity of cloud computing and its benefits, such as scalability, cost-effectiveness and flexibility. The move to cloud-native has made an enormous impact on observability efforts. Having good tooling and processes available positively impacts observability efforts because it’s a critical aspect of the developer communities’ systems. Overall, the shift to cloud-native tools is driven by the need for organizations to take advantage of the benefits of cloud computing and the need for more efficient and flexible deployment and scaling of applications.

    Some of the most common tools in observability include:

    These tools offer developers greater insight and knowledge into how applications behave. The cloud-native approach necessitates a new way to aggregate all of these operations.

    Conclusion

    With observability, developers can understand how their systems work in production. These systems act in different ways depending on the environments they run in. Therefore, organizations must do more to provide developers with sufficient observability because of the limited visibility into the overall system performance.

    Observability allows developers to act quickly and remedy issues before they go into production and organizations can better measure success relative to the application’s performance. Hours of developers’ time are spent manually debugging and troubleshooting when organizations could have a system in place to do this automatically and allow developers to get back to what they love doing most: Creating software. Observability helps organizations make better-informed decisions, improve operations and performance and achieve their objectives more effectively.

  • Grafana Labs Acquires Pyroscope to Add Code Profiling Capability

    Grafana Labs Acquires Pyroscope to Add Code Profiling Capability

    Grafana Labs this week announced it acquired Pyroscope and plans to merge Pyroscope’s open source continuous profiling project with the open source continuous profiling database that Grafana Labs launched last year.

    Richard Hartmann, director of community at Grafana Labs, said after logs, metrics and traces, continuous profiling is now the fourth pillar of observability that enables DevOps teams to identify how much infrastructure resources any given piece of code is consuming. That capability is critical for everything from controlling costs to improving performance to limiting the amount of carbon generated by an application both before and after an application is deployed, he added.

    The resulting Grafana Pyroscope project will be natively integrated with Grafana Labs’ open source dashboard project to make it simpler to visualize profiling data and correlate it with metrics, logs, and traces. Grafana Labs is also committing to adding profiling capabilities to the fully managed Grafana Cloud observability platform.

    Pyroscope currently makes a plug-in for Grafana available in addition to a cloud instance of Pyroscope. Integrating Pyroscope with the Grafana Labs portfolio will make it simpler for DevOps teams to visualize issues before there is a major disruption to an application environment, said Hartmann.

    It’s still early days as far as the adoption of observability platforms is concerned, but it’s apparent that as application environments become more complex, the plethora of monitoring tools that DevOps teams rely on will need to be streamlined. Observability platforms promise to unify logs, metrics and traces in a way that makes it simpler to launch queries to identify the root cause of an issue. The rate at which DevOps teams will embrace observability will naturally vary, but the biggest obstacle might not be the platforms themselves. Instead, the issue is understanding what queries can help DevOps teams better understand the root cause of an IT issue. Visualization tools, in combination with code profiling tools such as Pyroscope, should make it simpler to surface those issues.

    Grafana Labs is also enabling organizations to better address sustainability concerns that have emerged as more policies are enacted to encourage organizations to reduce the overall size of their carbon footprints. The European Union, especially, has been enacting policies that provide organizations with a range of incentives to encourage greater efficiency from IT environments. It won’t be long before more DevOps tools and platforms provide greater visibility and control over the amount of infrastructure application code is consuming to achieve sustainability goals.

    In the meantime, overall observability should continue to improve as organizations move beyond continuous monitoring to gain insights into how application environments are behaving. As IT environments become more complex, tools that monitor a set of pre-defined metrics are no longer enough to ensure application resiliency. The challenge—and the opportunity—is to determine how to take observability to the next level before the next inexplicable application performance degradation.

  • New Relic Reports Major Spike in Volume of Log Data

    New Relic Reports Major Spike in Volume of Log Data

    New Relic today shared a report based on anonymized data it collects that showed a 35% increase in the volume of logging data collected by its observability platform.

    The report also identified logs generated by NGINX proxy software (38%) as being the most common type of log, followed by Syslog (25%) and Amazon Load Balancer (20%).

    In addition, Fluent Bit is the most commonly used open source processor and forwarder tool (38%) among IT teams that have adopted the New Relic platform. Another 16% are using New Relic infrastructure agent, followed by 14% that send log data directly to New Relic via an HTTP endpoint.

    The report also found 50% of all logs ingested by language agents come from Java applications, followed by .Net (26%), Ruby (22%) and Node.js (2%).

    Jemiah Sius, director of developer relations at New Relic, said as more cloud-native applications are deployed, the volume of log data that is collected is only going to increase as open source OpenTelemetry tools are more widely adopted. In addition, IT teams will also be collecting metrics, traces and events to better pinpoint the root cause of issues using observability platforms such as New Relic One, he added.

    Amazon Web Services (AWS) is now, of course, one of the biggest sources of log data. The New Relic report noted that the serverless AWS Lambda service is the most widely employed source of log data among AWS customers that employ the New Relic One platform. However, use of the AWS Firehose service for extracting, transforming and loading (ETL) data has grown sharply in the last year, noted Sius.

    The New Relic report found while only 32% of New Relic accounts that use AWS have adopted Firehose, there has been a 62% increase in adoption year-over-year.

    Log data is usually the first thing any IT team consults whenever there is an issue, but as the volume of log data increases it’s becoming more difficult to associate log data with specific IT events. The issue that each IT team will have to come to terms with is how much log data to store alongside metrics, traces and other data formats to help them proactively identify the root cause of an IT issue.

    Observability platforms, in the meantime, promise to make it possible to query that log data to identify relationships between events. The goal is to enable IT teams to investigate issues before they can disrupt IT services rather than merely reacting to events after they have unfolded, said Sius.

    The hope, of course, is that machine learning algorithms will soon automatically identify issues before most IT teams even know there is a problem. Given the overall complexity of modern IT environments, it’s unlikely most IT teams even know what queries to launch to identify the root cause of an issue. Instead, as machine learning algorithms become more familiar with what constitutes normal IT events, it will become simpler for those algorithms to surface the issues that are actually worth IT’s attention.