Tag: SRE

  • Survey Reveals Slight Decline in Level of SRE Toil

    Survey Reveals Slight Decline in Level of SRE Toil

    The amount of routine toil that site reliability engineers (SREs) perform declined slightly in the last year even though IT environments in general are becoming more complex to manage.

    An annual survey of 300 SREs conducted by Catchpoint, a provider of an IT monitoring platform, in collaboration with VMware and the DevOps Institute suggests that the amount of toil—defined as low-level manual tasks—declined 15% in the last year.

    Only 22% of respondents claim to be scientifically measuring toil, so, to a degree, the survey results are apocryphal. Overall, the survey, published this week, finds SREs are, not surprisingly, spending the bulk of their time on responding to incidents and outages, followed by participating in postmortem analysis and on-call rotations. The primary sources of toil cited in the survey are too much technical debt, lack of alignment of priorities and goals, lack of appreciation of business value, lack of training and support and lack of collaboration.

    In terms of automation adoption, the most common use cases cited are release management, infrastructure management and application management. The tools most commonly employed by SREs are used to monitor infrastructure, networks and application performance. Adoption of artificial intelligence (AI) tools to manage IT operations (AIOps) remains low. The survey also finds respondents are roughly split evenly between centralized (42%) and decentralized (38%) approaches to managing IT. Another 20% said they have adopted a hybrid approach. Lack of visibility across the stack (53%) was the most cited cloud application monitoring challenge.

    The survey also finds only half of respondents continually refine their service level objectives (SLOs).

    Leo Vasiliou, director of product marketing for Catchpoint, said it’s clear that SREs are becoming more proactive in terms of preventing and containing the impact of IT incidents. The challenge they face is lack of visibility and context as those IT environments become more complex. Complexity is increasing, in part, because of the rise of cloud-native computing platforms running microservices-based applications that have lots of dependencies.

    Less clear right now is the percentage of IT environments managed by SREs today. In theory, a single SRE can do the same amount of work as multiple IT administrators by automating processes using various DevOps tools rather than relying on traditional graphical tools. However, SREs are hard to find and retain. It’s also not always apparent to what level of automation needs to be attained to qualify to be an SRE or, for that matter, what certifications may be required. Interest in becoming an SRE is rising, in part, because they typically command higher salaries.

    In the meantime, it’s clear organizations will need to find ways to automate the management of IT to a much greater extent. Most organizations cannot afford to hire a small army of IT professionals to manage IT environments that become more complex with each passing day. Everything from DevOps best practices and next-generation observability tools that promise to provide more context to AI platforms will all be part of the mix. The challenge is finding a way to implement those tools before IT management spins further out of control.

  • Using Chaos Engineering to Build Resilient Systems

    Using Chaos Engineering to Build Resilient Systems

    Over the past decade, chaos engineering has become one of the most popular approaches in DevOps. It’s uniquely adapted to complex cloud-based systems and has the potential to succeed where more conventional approaches may not.

    Chaos Engineering Explained

    Traditionally, DevOps teams worked with systems hosted on single servers. They would analyze logs with a fine-toothed comb, looking for potential anomalies. They implemented automated tests to ensure the system worked to spec.  They employed root cause analysis to debug applications.

    Modern systems use cloud-based distributed architectures and are much too complex for this approach to be successful; they contain hundreds, and sometimes thousands of instances.  In many cases, their behavior can be chaotic, making it nearly impossible to predict.

    Because of this, modern systems need to be designed for resiliency from the outset. Chaos engineering was developed to foster resilient system design by deliberately anticipating failure modes.

    Two Steps to Chaos

    Here’s how it works. After characterizing a state of “health” for their system, DevOps teams perform a chaos experiment. Just like physics or chemistry experiments, chaos experiments involve setting up two versions of a system: the experimental version and the control.

    The experimental system is then subjected to a barrage of virtual kicks and punches which could range from injecting faults to disrupting a data center. DevOps teams then pore through the resulting logging data, attempting to understand how the chaos experiment affected the state of the system.

    Chaos engineering has two major differences from conventional DevOps practice. First, while conventional forms of testing supply a controlled input and test for a predefined output, chaos experiments are far more open-ended. They’re designed from the outset to expect the unexpected, requiring analysis of the whole system to give novel insights.

    Second, they are performed on live systems. This makes chaos engineering controversial, as its experiments have the potential to affect real users. Still, it makes it much more powerful than alternative approaches. Chaos engineering encourages resilient design by taking genuine risks with systems in the wild.

    Why Companies Embrace Chaos Engineering

    Chaos engineering has been around for over a decade. In that time, it’s been adopted by several of the biggest names in tech. Netflix, the company that pioneered the approach, is still the most well-known for their use of fault injection.

    In 2008, Netflix was moving from an in-house data center to the cloud. They knew that, as they expanded, their application would undergo massive horizontal scaling.  Because any one of its thousands of instances could fail at any moment, it needed to be resilient.

    They created the first chaos experiment, Chaos Monkey. This worked by randomly turning off instances in Netflix’s live application to check it was fault-tolerant. This practice sounds dangerous, but it encouraged Netflix engineers to design resilient system architectures.

    Chaos Monkey sounds bananas, but it worked. In its first five years of operation, there was only one failure which was promptly fixed by an on-call engineer. That failure was caused by Chaos Monkey itself.

    Facebook is another big company to adopt chaos engineering. They created Project Storm in the wake of 2012’s Hurricane Sandy.  Although the hurricane itself didn’t affect Facebook, it served as a wake-up call. A storm hitting one of Facebook’s data centers could wreak havoc.

    In 2014, Facebook took the step of turning off traffic to one of their data centers. Although no end users were affected, traffic loading went haywire on all sorts of different subsystems.

    Once Facebook had successfully identified this weakness in their system’s resilience, they could preemptively design traffic management software that would be resilient in the face of a live data center shutdown.

    As more and more companies use cloud computing and hyperscale data centers, chaos engineering is likely to become an essential feature of DevOps strategy.

    Applying Chaos Engineering In Your Company

    Chaos engineering is the ideal approach for complex, distributed systems. Chances are, your DevOps team either runs their application in the cloud or is planning to migrate to it.

    Serverless computing, in the guise of systems like Kubernetes and Heroku, is popular with an increasing number of organizations. Now it’s common for systems to contain hundreds or even thousands of instances, hosted in massive data centers.

    So far, we’ve only seen chaos engineering from 10,000 feet. It’s time to look at how you can make it work on the ground.

    First, we need to understand the roles observability and monitoring play in chaos engineering.  To successfully implement chaos experiments, there needs to be a high level of system visibility.

    Dealing with Data

    Marius Moscovici outlines four strategies for extracting valuable insights from data. He discusses the importance of detecting anomalies in your data stream, something a chaos engineer needs to be good at.

    Whether it’s the haywire traffic in Facebook’s Project Storm or the deactivation of Netflix instances, chaos experiments rely on the ability to diagnose unusual patterns in data.

    1. Profiling Normal System Behavior

    In order to detect anomalies, you need to have a good idea of what your system normally does. In their book on chaos engineering, Netflix used the analogy of human vital signs. Just as doctors know that 98.6°F is a normal human body temperature, their IT counterparts need to characterize a “normal” state of “health” for their DevOps system.

    Many log analysis and observability tools in the market offer machine learning capabilities to help achieve this.

    2. Detecting Anomalies Across The Board

    Anomaly detection should be integrated into every step of your data analysis. You need to be able to detect anomalies across the board, not just in places you happen to be looking at. Because chaos engineering, unlike more conventional forms of testing, is designed to reveal new and unexpected information it’s vitally important to have a completely open data strategy.

    3. Data Scientists On the Lookout

    Always be on the lookout for potentially anomalous behavior. Chaos engineering will require your company to take its DevOps strategy to a new level, both in terms of your team’s mindset and the sophistication of their logging tools.

    Because chaos engineering requires you to analyze all available data without making assumptions, it’s necessary to leverage machine learning to extract patterns from your logs.  Chaos engineering requires a scientific mindset and an appreciation of the power of data.

    4. Create Alerts

    Finally, make sure that anomalous behavior is being flagged and that the team is aware when it occurs. If possible, dynamic alerts should be used to avoid false positives and alert fatigue which is common with static thresholds.

    Engineering with Chaos

    More and more organizations are migrating to the cloud and building highly distributed application infrastructures. DevOps teams are being forced to confront chaos and complexity on a daily basis.

    While the complexity of modern IT systems has necessitated chaos engineering, it has also enabled it. In a chaotic world, chaos engineering brings the order of an engineering approach.

  • CloudBolt Adds Cloud Cost Tool to Hybrid Management Platform

    CloudBolt Adds Cloud Cost Tool to Hybrid Management Platform

    CloudBolt Software this week added cost management capabilities for Amazon Web Services (AWS) and Microsoft Azure public clouds along with codeless integrations with additional platforms to its hybrid cloud management platform.

    Grant Ho, chief marketing officer for CloudBolt, said the Spring Release of the company’s platform, now generally available, enables IT operations teams to rely much less on custom code to integrate the various elements of a hybrid cloud computing environment. The Spring edition adds support for the VMware vRealize Automation 8 automation platform, the configuration management database provided by ServiceNow as a cloud service and the IP address management platform from SolarWinds.

    CloudBolt

    In the wake of the COVID-19 pandemic, CloudBolt is betting more organizations will look to centralize IT management as part of an effort to reduce the total cost of IT. The cost management capabilities added to the platform enable IT teams to position themselves as more of an independent arbiter of where certain classes of workloads should run, based on cost, at a time when organizations have never had as many options as they do today, noted Ho.

    A recent survey published by CloudBolt found 80% of respondents are prioritizing real-time insight into cost optimization and security remediation. A total of 71% want self-service to be easy for end users, while 62% want an approach to integration that doesn’t require deep domain knowledge or special expertise.

    A full 94% of respondents also noted hybrid cloud computing will be critical to digital transformation. A total of 92% also noted that empowering end users through self-service IT is a digital transformation accelerator, while 99% said successful automation depends on streamlining integrations.

    More than three quarters (78%) noted they lack the visibility necessary to optimize cloud deployments. More than half (56%) also admitted their self-service offerings fail to meet user needs and more than three-quarters (76%) still rely on some form of custom coding when it comes to integration.

    Most enterprise IT organizations are trying to strike a balance between cost and flexibility as IT environments become more distributed. Each time a new platform is added to an IT environment, the total cost of IT rises because additional consoles for managing those platforms need to be staffed. The challenge is finding a way to centralize the management of IT in a way that reduces the number of consoles that have to be mastered without requiring every business unit to standardize on a platform that locks an organization into a single provider.

    It’s unclear to what degree IT organizations will rely on traditional IT service management (ITSM) platforms manned by administrators versus DevOps platforms deployed by site reliability engineers (SREs) to achieve that goal. However, one way or another, the cost of distributed computing environments needs to be reduced, even as they are becoming more complex. The primary issue now is deciding how best to achieve that goal in an IT environment where every application owner tends to view themselves as master of their own IT domain.

  • Chicken Soup for the SLO

    Chicken Soup for the SLO

    Since time immemorial, humans have struggled to communicate. From myth to the modern era, our most memorable stories often involve individuals or groups seeking to be understood in order to avoid conflict. Be it the biblical allegory of Babel to the more recent Star Trek: The Next Generation episode of “Darmok,” a deep fascination with how people communicate seems to have collectively gripped our imaginations.

    It should come as no surprise, then, that communication between disparate teams and roles in the development of distributed software systems is a fascinating topic. There’s an almost primal struggle in the workplace—a dichotomy between “features” and “stability”—that teams have sought to overcome for decades. Indeed, much of the discipline of software engineering has implicitly evolved as a response to the needs of engineers to communicate with other parts of the business.

    How, then, do we improve this communication and build empathy toward our fellow developers, our coworkers, our PMs, our managers? We need a way to communicate with them, to express “how things are going,” how reliable our service or system is. Let’s step back, though, because this is only a small window we’re looking through—we need to communicate these desires and goals to a greater audience; Our bosses, their bosses, our customers, the entire world. Organizations rise and fall on their ability to communicate effectively.

    In the natural sciences, we observe that the tendency of a system is towards entropy; Energy tends to dissipate in the absence of a constraint. So, too, do human systems lose productivity as their scale and complexity increases. The rise in popularity of Agile methodologies and DevOps thinking tracks with this. They are, ultimately, designed to help us communicate better about needs and priorities. Site reliability engineering (SRE) is the latest in this line of disciplinary developments, providing rigor to the question of, “How do I operate very large scale systems in dynamic environments?”

    One of the more popularized elements of the SRE playbook is the concept of the service level objective, or SLO. To excerpt the excellent Implementing Service Level Objectives by Alex Hidalgo, a SLO is “a proper level of reliability targeted by a service,” a calculation of the amount of ‘bad’ events that can occur as part of the normal operation of a service. As Alex notes, the idea of SLOs and SRE have become almost inseparable in our collective consciousness—organizationally, it’s seen as strange to have one without the other.

    Let’s dive a bit deeper into what an SLO actually is. Again, I will excerpt and paraphrase from Alex’s book (it’s very good; you should read it if you’re interested in this topic). A SLO is simply a target, a set of defined criteria that represent some objective that you’re trying to reach. In a very general sense, the SLO expresses the threshold of ‘good’ to ‘bad’ events that you’re willing to tolerate over a time period. This simple ratio, however, unlocks a great deal of interesting and important ways of thinking about performance and reliability. It gives you, and your team, the ability to reason and communicate about reliability in a very quantitative and qualitative way.

    Now, you may be asking yourself what the qualitative component of a SLO is—after all, aren’t these measurements quantitative by definition? It’s in this dichotomy that I believe the true power and utility of SLOs lie; they’re not just a measurement of what you’re doing, they’re a communication vehicle for how you’re doing. Error budgets come out of this line of thinking—they represent the space between the current state of your SLO and its boundary.

    In plainer terms, it’s a measurement of how much you can miss your target before it becomes a problem. If my SLO targets 99% reliability, I have about three and a half days of unreliability a year to play with—or, about 14 and a half minutes a day. This way of measurement is certainly helpful in driving and determining engineering decisions, as it allows us to make snap judgements about how to prioritize the seemingly opposing buckets of “feature work” and “reliability work.” If we’re getting close to burning up our error budget for the month, do more reliability work. If we’ve got slack, do more feature work. Easy, right?

    How to Make Friends and Influence Budgets

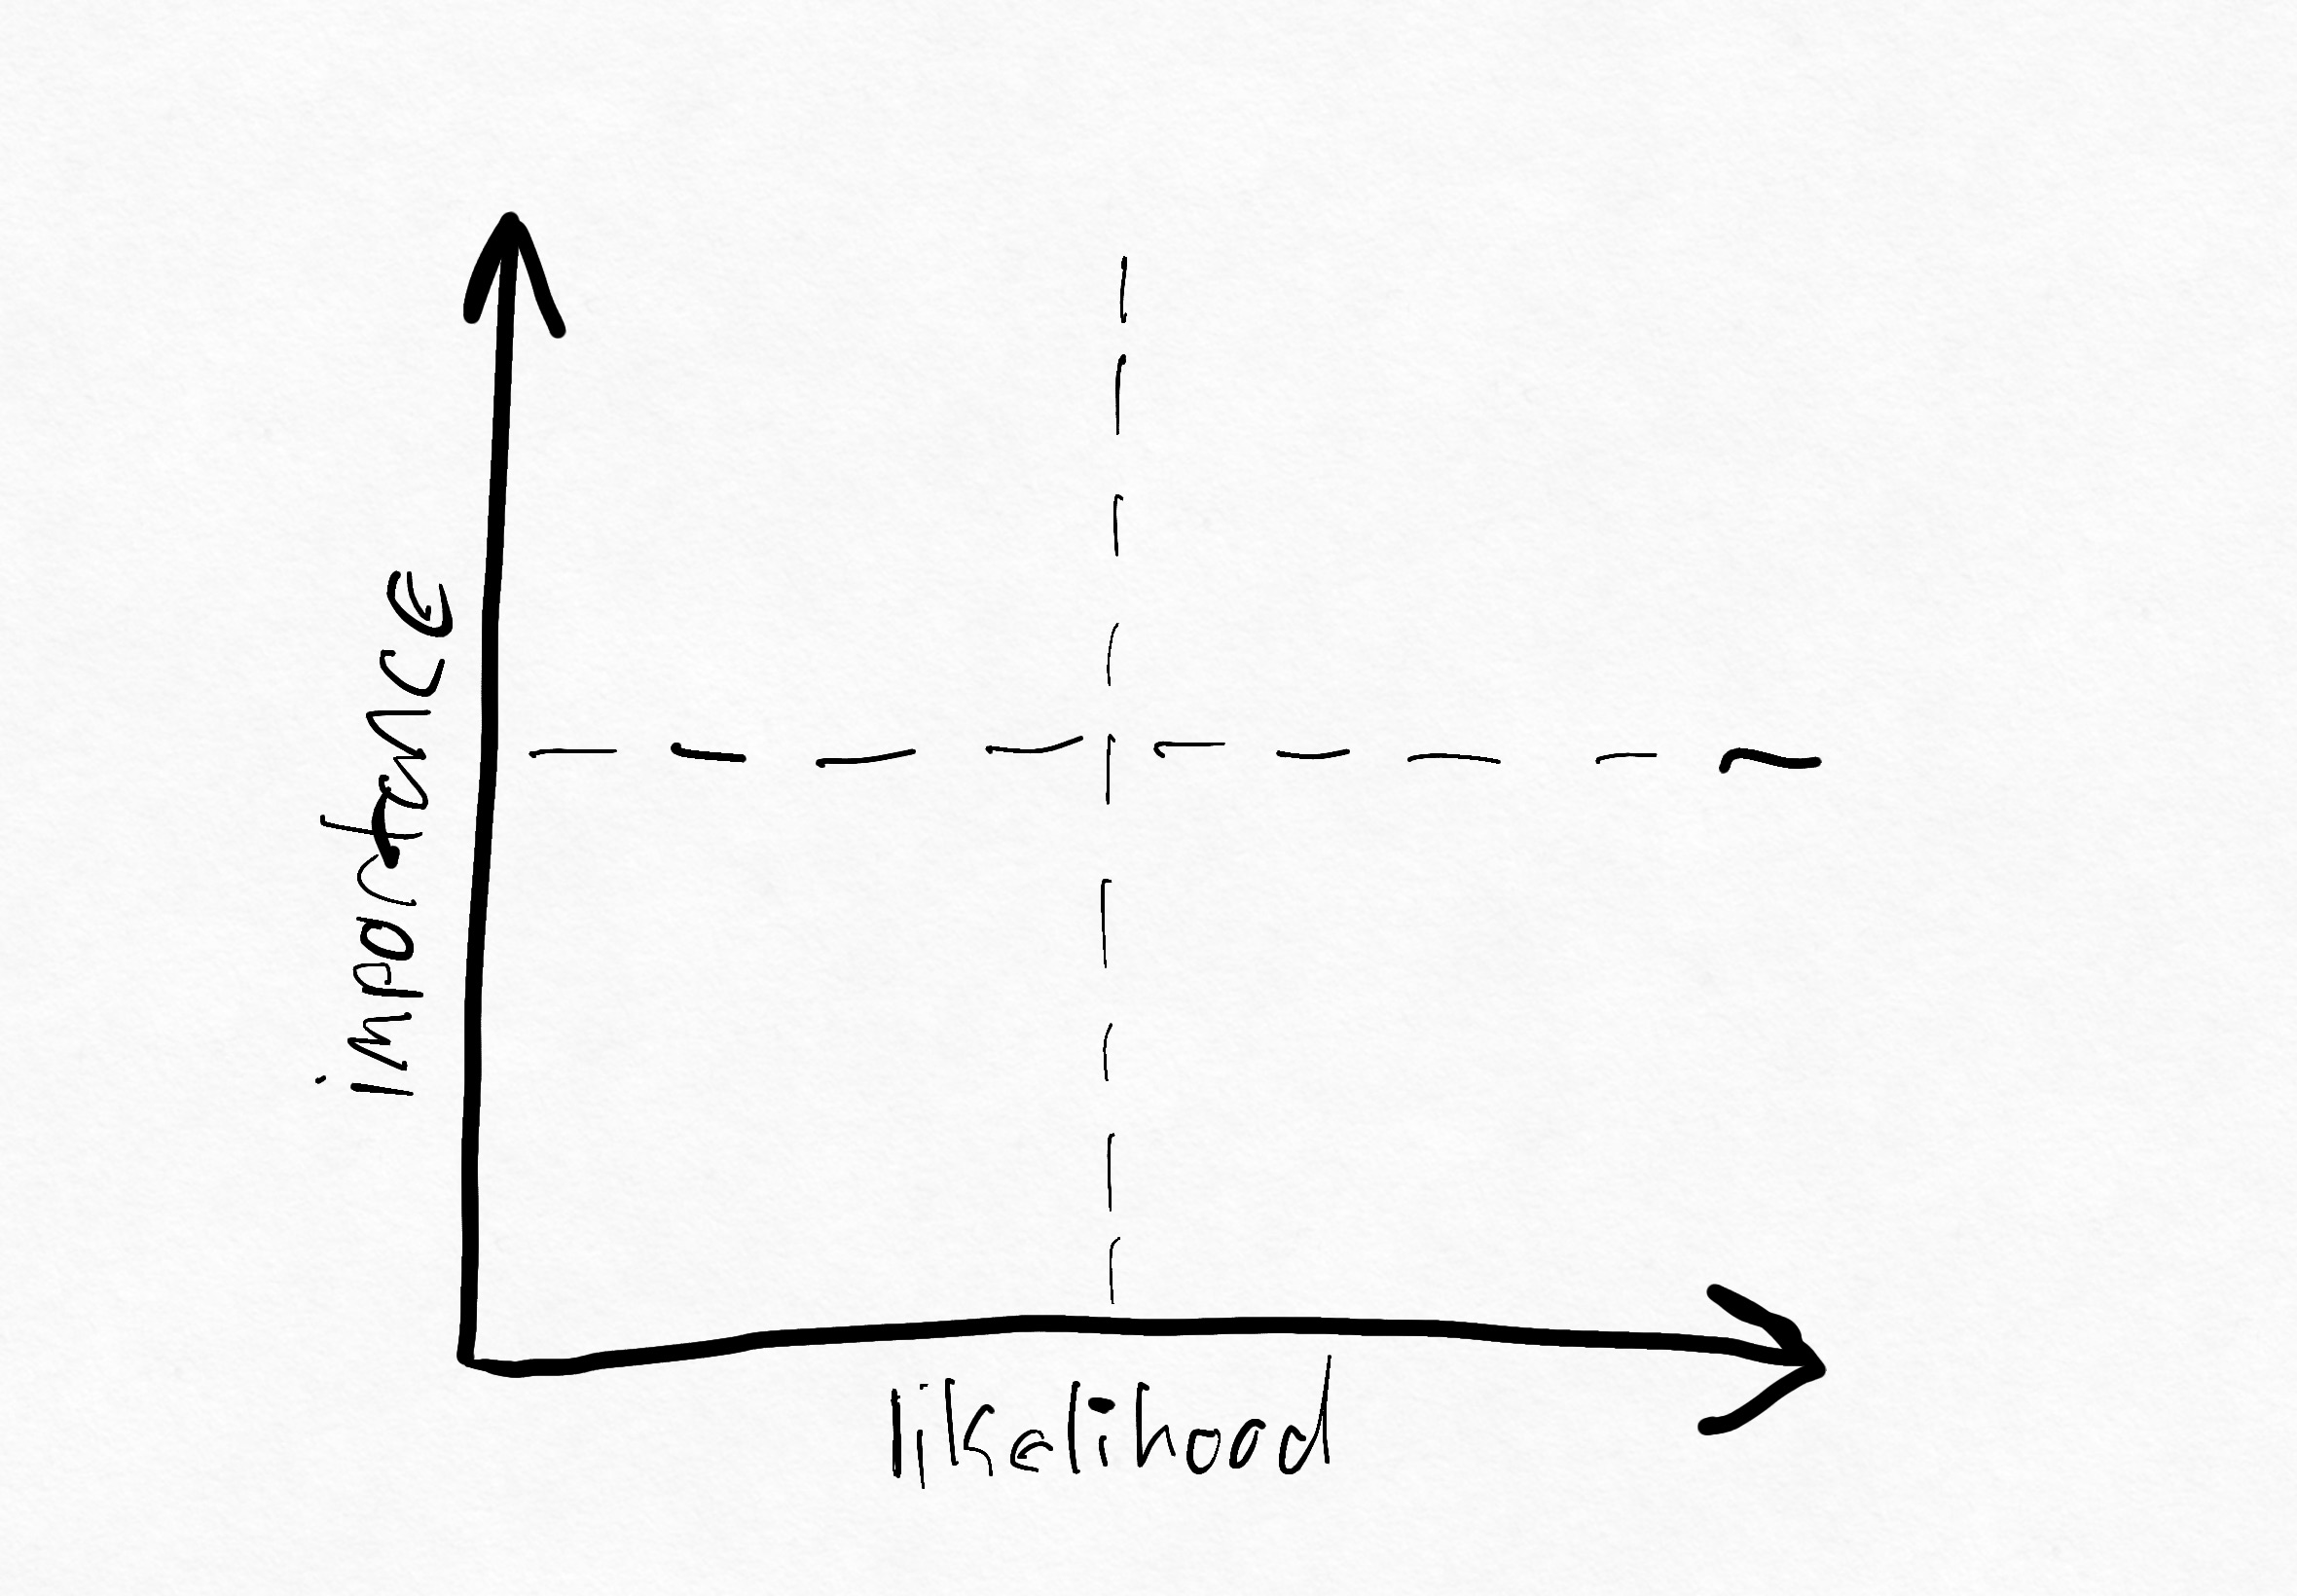
    Reliability, SLOs, error budgets—these are all helpful ways to quantify performance and availability in software. There’s another way to consider them, though, and it’s through the lens of risk. If you’ve earned an MBA, you’re probably familiar with a ‘risk heat map.’
    SLO heatmap

    The x-axis on this quadrant represents the likelihood of a problem occurring; the y-axis represents the importance of that element. This is generally extensible to any element of a business—everything from your sales force to your customer success team to the availability of your data center or cloud resources.

    In many ways, this simple quadrant is responsible for many of the decisions that influence your work. While a business does many things, the business of operating a business can be thought of as an ongoing and unceasing process of risk management and abatement.

    The stuffy, MBA-fueled world of Six Sigma and process management doesn’t play terribly well in the more creative arenas of software development and maintenance, I’ve found. Much of this has to do with—you guessed it—risk. In manufacturing, the costs of failure or defects can be extremely high. Component defects can sideline million or billion dollar supply chains; projection and planning failures can disrupt just-in-time inventory and a single stuck ship or sudden winter storm can cause months or years of disruption to national or global economies. We should count ourselves fortunate that the actual costs of failure in a software system are so light; while us-east-1 going down for an hour would be bad, it probably wouldn’t wreck the global GDP for six months.

    The translation of ‘lower-level’ concerns, such as software system reliability or employee turnover, into ‘higher-level’ risk concerns acts as a curtain between the operational and the managerial aspects of a company. It is this curtain that we must consider when thinking about the true advantages, and the revolutionary potential, of SLOs. Remember, a SLO represents a ratio between ‘good’ and ‘bad’ and gives us a threshold value. These SLOs can be overlaid onto our risk maps extremely easily; SLOs for more critical services and processes rise to the top, newer services move to the right.

    In essence, we can give our SLOs a qualitative score with regard to overall business risk, and use this to shape the overall business direction. This is crucial, as in the absence of better qualitative measurements, businesses will often grasp at quantitative reliability measurements—“pages fired or tickets opened,” to quote Hidalgo. He continued, “[T]hese are prone to be inaccurate due to false positives or the whims of the people opening the tickets.” The types of measurements that we often rely on, such as categorization by severity or ‘mean time to x’ fail to accurately classify reliability or how it impacts the user experience.

    Let’s illustrate by example—a huge part of conversations about SLOs is talking about how they should be framed in terms of users; happier end users, happier engineers, happier managers and so forth. SLOs that correspond to user journeys—for instance, “Adding an item to the cart succeeds 99% of the time.”—are straightforward to understand from the perspective of an end user. We can discuss this in terms of risk by applying an importance and likelihood score to the SLO itself. If our site is an e-commerce platform, then the importance of the cart is very high. Since our threshold is very small (1%), then the likelihood of this risk is also very high—we don’t have a lot of wiggle room!

    A SLO for a targeted ad service might read, “A contextually appropriate display ad is served within 30ms 90% of the time.” In this case, our ad business might not be of high importance in terms of our business risk, so we should reduce the importance of the SLO. In addition, our threshold is very large, so we should reduce the likelihood of violation (since we have a lot more wiggle room). Over time, these positions and scores can (and should) change—perhaps the advertising segment of our business becomes more valuable, so we re-prioritize it on our risk maps.

    By speaking this language and quantifying our data in different ways, we can pull back the curtain between operational and managerial sectors and use it to influence things outside our immediate sphere.

    “Mommy, why is there a SLO in the house?”

    There’s an aphorism about war and fighting that goes, “Generals are always prepared to fight the last war.” I’ve seen this myself at every company I’ve worked for over the years—we tend to be reactive, rather than proactive, in planning and preparing for strategic business challenges. Some of this is due to the fact that none of us are oracles capable of divining the future, but much of it simply has to do with the aforementioned cycle of risk management that drives business planning and decision making. When introducing SLOs to a wider audience, you need to be able to plan for the pushback that executives and managers will almost certainly have to this new way of thinking.

    When you think about it, though, there’s not a lot of difference between what an SLO is trying to represent, and what an OKR or KPI or any other goal-oriented system is trying to represent. In each case, we’re creating some heuristic to sort events into ‘good’ and ‘bad’ cases, then creating a threshold of ‘Now there is a problem’ based on the ratio between them. In essence, this is, really, how you measure anything as a percentage.

    You could translate goals for your sales, marketing, customer success or people ops teams into SLOs. For example, “30% of POCs should convert into closed-won opportunities” is, basically, an SLO already, and is perhaps an existing goal for your salesforce. There are two big advantages to thinking about these as SLOs: consistent reporting and error budgets.

    Consistently reporting on SLOs means that you can express team and company goals in the same format and language across the entire organization. This brings teams together in a shared purpose, and allows for a shared language about how reliability benefits everyone. Being able to roll up reporting about how things are going not only encourages more shared ownership of goals, it helps you build connections and linkage between how different types of work align with each other towards a shared prosperity. More importantly, SLO reporting gives extremely clear signals about how teams—regardless of their function—should be addressing failure.

    If a consistent language around reliability is what builds empathy, error budgets are what unlocks creativity and problem solving for addressing issues in the business. In too many cases, organizations are loathe to give individual contributors, or even teams, the flexibility to experiment and measure the results of those experiments due to inertia, top-down command-and-control style processes or just the fear of screwing up.

    Let me give you an example—suppose your marketing team has a demo that generates a certain percentage of leads every month. Without a defined SLO for this demo’s performance, it becomes extremely difficult to change anything about how this demo works. Why? Because there’s a tendency for things to settle at their current state—we’re all so consumed with moment-to-moment crises or new work that evaluating the performance of existing things can be challenging.

    The work required to justify a change eventually outweighs the actual work being done to make the change, and so change withers on the vine and processes stagnate. Now, imagine that this demo flow had an SLO associated with it, something like “10% of clicks to our demo should result in a valid email capture.” Suddenly, we can report on this in a consistent fashion and, more importantly, we have a massive amount of headroom for experimentation. We can justify work being done to improve this flow in the context of not only its current status (are we running better or worse than our target?) but also in the context of our other goals (are we producing enough MQLs, in general, to support the sales funnel?) and prioritize appropriately.

    Ultimately, we can’t change the fact that there’s a bias towards dealing with the last thing that happened, but that’s not really the point. What we can change is how we think about expressing what’s happening now, and building a consistent language and verbiage around addressing these problems. SLOs are designed, broadly, as a way to communicate the reliability goals of complex distributed software systems. What is a business of people other than a complex distributed human system?

    As thinking, tooling, and processes around SLOs continue to mature (such as the recently announced OpenSLO specification), I’m excited to see what the future has in store for us. At the end of the day, we should be striving to reduce hierarchy, increase autonimity, and build collective ownership in the socio-technical systems that we rely on as human beings; SLOs are just another piece of this ever-evolving puzzle.
  • The Evolution of SRE and Developer Roles

    The Evolution of SRE and Developer Roles

    As an industry, we’ve seen cultures and roles shift throughout IT teams — specifically, the role of ITOps site reliability engineers (SREs), various developer roles and the culture of DevOps. Most of these roles operated – or still operate – in silos, and didn’t understand (or care to understand) how each other’s role worked. More importantly, they didn’t know how to work together. But these roles are starting to overlap, driven by the increase in demand for customer experience and, subsequently, in intelligent observability, or observability with AIOps. Before we dive into the ‘how’ behind the overlap, let’s look at how each of these roles performs today.

    Developer

    While the specifics of what a developer does varies by project, the overarching responsibilities haven’t changed much since the introduction of the role. Simply put, developers write code to create and improve product functionality.

    IT Operations and SRE

    Traditionally, an IT operations professional focused on operating the code a developer put into production; aka keeping the lights on. However, we’re now seeing evolution of the role of highly skilled operations pro to that of an SRE who oversees automation and features surrounding the product, like CI/CD pipelines, infrastructure-as-code and the ability to monitor and observe the services and components within.

    QA

    Traditionally, QA would test the code the developer wrote and move it down the deployment pipeline. But we’re moving away from traditional QA. Now, the role sets up an automated framework for the developer so they can automate tests — similar to how the SRE sets up the CI/CD pipeline and observability framework to build, test, deploy, verify and monitor their code.

    DevOps

    DevOps has, in some cases, evolved from a practice and culture into a role. The DevOps engineer prepares the automation and the CI/CD pipeline for the developer to push out their code to test and, ultimately, production. But let me be clear – I believe the idea behind the practice of DevOps is that the practitioner does everything — they own testing frameworks, CI/CD pipeline and infrastructure. They own end-to-end product development and operation, so when anything does go wrong, they know exactly what to do, where to go and how to fix it.

    In the end, if a SRE can develop everything around the product code and knows how to fix the product — isn’t an SRE actually a developer? What if we have a really skilled developer who sets up the automation and observability framework to get their code from their keyboard to the user as quickly as possible — without breaking anything, of course — while also building and improving all the infrastructure and components surrounding the product? Isn’t the developer an SRE, or at least performing site reliability engineering?

    The short answer, in my opinion, is yes. And there’s one guiding force behind this amalgamation, this crossover; ultimately, this evolution: intelligent observability.

    The role of observability with AIOps

    Traditionally, and with the use of many tools, DevOps practitioners and SREs have had to — manually — battle floods of data coming in from all their endpoints, services and products. This can feel like a never-ending struggle. It can lead to a lot of toil and time spent on maintenance, when what developers really want is focused time to do what they love – write code, create and innovate. Not to mention, the result has a negative impact on the customer experience.

    But now, new tools are surfacing to support the everyday needs of SREs and DevOps practitioners. For example, intelligent observability, or AIOps, applied to observability data like events, metrics, traces, changes and logs, gives teams clearer insight into not only where complex data is coming from, but why an issue is happening and what action they need to take to resolve it. They can spend less time operating and more time innovating.

    As these roles continue to evolve, it’s important SREs and DevOps practitioners remain agile and willing to adjust to keep up with the latest technologies supporting their day-to-day workflow. AI can be the key to keeping the incident count down and the customer experience up.

    Looking Ahead

    If you’re currently in one of these roles, consider how you are practicing. Whether you’re a developer, a QA engineer, a DevOps practitioner, or an SRE, have you evolved your role to fit your company and customers’ needs right now? As these roles overlap with the application of intelligent observability throughout your development life cycle, it’s possible to deliver better products and fix reliability issues faster. It’s up to you to decide if you want to embrace the evolution of your role and intelligent automation or stay put and risk falling behind.

  • How to Spot SRE Adoption Barriers

    How to Spot SRE Adoption Barriers

    It’s no secret that site reliability engineering (SRE) adoption is growing. The operating model, it seems, is pivotal for digital transformations across the enterprise. According to the Upskilling 2021: Enterprise DevOps Skills Report, 22% of respondents (up 7% from last year) cited SRE as the approach they need to continue automation in 2021.

    Common Adoption Barriers

    However, for some companies, adopting SRE principles and practices isn’t always easy. Ahead of the upcoming SKILup Day conference focused on SRE (Register for SKILup Day: SRE here), I asked several DevOps Institute Ambassadors and SRE subject matter experts to provide insights into the barriers of SRE adoption. Here’s what they shared:

    Marc Hornbeek, CEO and Principal Consultant at Engineering DevOps Consulting and author of the book, “Engineering DevOps”

    “The primary barrier for SRE adoption is executive vision and team alignment around a goal to transform to SRE practices. SRE affects the entire organization’s practices, roles and investment priorities. Without an executive sponsor, SRE transformations are not going to go far.”

    Stephen Walters, Solution Architect at xMatters, Inc.

    “Culture, and in particular, cultural change, is the greatest barrier to SRE adoption. As much as everything about the human race, the things that got us to being the creatures we are today, is about evolution, which is change, and we are not particularly good at it. Or, more specifically, the bigger the change, the more resistant we are to it. It has always been a great oxymoron in IT philosophy that in order to “transform,” you must change, but that transformation is occurring because we are not good at change. So it was with agile in the early days. Organizations wishing to transform to agile (small, iterative change) would do so under a transformation project, which would typically be waterfall (big bang). Big change, big cultural resistance. The key is to implement transformation in smaller, agile chunks. They are more easily accepted and testable, and also easier to roll back or adapt if they do not work or are not acceptable. All of the benefits of agile development apply to agile transformation.

    The second greatest barrier is, then, “buy-in,” where the simple answer is, unfortunately, show the end user “what is in it for them.” This will typically override the enterprise-scale view of “what is in it for us?” but, over time, with any cultural transformation, this is one of the things that should change, iteratively, and also be a focus for developing a more holistic and empathetic culture.”

    Shivagami Gugan, Chief Technology Officer at CX Tech Unicorn

    “Any organization, irrespective of whichever level of maturity they currently exist on today, can adopt SRE and improve their business outcomes. However, the key underlying principles of SRE and its applicability should be understood properly. There is a lot of hype around transformation and the first barrier is about understanding what SRE means within your organizational context. I find most of the time, people try to imitate what highly mature companies like Google or Spotify or some other cloud-born company does, and this usually results in failures. SRE is the purest form of the implementation of DevOps. SRE is about removing the silos in a product life cycle to achieve business outcomes in a safer, faster, cheaper and better manner. If this is understood clearly, the first barrier gets removed.

    The second barrier is this complicated vision of boiling the ocean – doing 100% Agile, 100% DevOps or 100% SRE. This doesn’t work, especially when you have heritage systems of records, on-premises services and heritage infrastructure and a whole lot of baggage built over several years (sometimes decades) which is the usual case for most companies. So be very clear in choosing target areas.

    The third barrier is when you think SREs specialize in building operational reliability, but do not have anything to do with the development or the deployment phases of the life cycle. Reliability is everyone’s problem – the technical product manager, the developer, the tester, the support engineer; not just the SREs. The reality of the SRE role is to ensure services availability and reliability by supporting the other teams that own these services. SREs are enablers, they are collaborators, and their goal is to ensure that the services are overall resilient, reliable and that incremental value is delivered in a continual manner. When an organization understands that implementing SRE is an underpinning cultural change that affects all parts of the organization, then it becomes easier to remove the main barriers.”

    Lisa Chan, Head of Software Engineering & DevOps at PETRONAS

    “Not all organizations have the luxury of having an Ops team composed of skilled developers, which is a key success factor for the adoption of the SRE working model. In my case, I’m in an IT organization of 1,800 folks that has supported an oil and gas company since its inception 40 years ago. We serve a captive market of an integrated energy business with more than 100 companies under its portfolio. As a result, there is a legacy landscape of more than 2000+ applications. The IT organization still maintains the common “Dev is Dev, and Ops is Ops” anti-pattern. Even though we are in transition towards a working model that is more collaborative, it is unrealistic to expect our 300 Ops personnel to reskill themselves to be developers, because many of them have traditional skill sets along the typical Ops silos; e.g., networking, database admins, server admins, data center management, call center agents, etc.”

    BMK Lakshminarayanan, Value Stream Architect at Bank of New Zealand

    “Building the SRE practices and skills within enterprises are always challenging, as some are still embroiled with old ways of thinking. The thinking, associated techniques, available tools and limited skills are constraining SRE adoption in most enterprises.

    Renaming the system admins to SREs neither helps nor makes SRE experts. Investing in expensive tools doesn’t help, either. Any adoption and transformation is a gradual process. A typical medium to large enterprise has a few hundred systems, applications and services with various operating systems to support, database platforms to manage and hundreds of application databases to monitor or administrate. To this complexity, add all the dependencies of other services and components, as well. Hence, redefining the SLOs, SLAs and SLIs for these services, automating everyday maintenance tasks, understanding the toil, building resilience and fault-tolerant characteristics within these systems and applications are uphill tasks for most enterprises.”

    Identifying Other Common Adoption Barriers

    Many other common barriers for enterprises are:

    • Availability of up-to-date system and application information in a centralized platform
    • Observable nature of legacy systems
    • Understanding the dependencies and service levels (Promise Theory)
    • Availability of the right tools for the right job
    • Skills – old ways do not open new doors.
    • Time – time and space for people to upskill, train and experiment.

    Want to learn more about SRE and how to overcome these adoption barriers? Join us for SKILup Day: Site Reliability Engineering on May 20. Register here: https://devopsinstitute.com/sre-2021/.

  • Report: The State of DevOps Automation

    Report: The State of DevOps Automation

    In the race to accelerate digital transformation initiatives, organizations are encountering more incidents, more downtime, and longer resolution times. In fact, 90.4% of organizations saw an increase in incidents since the pandemic began, according to a recent Transposit report.

    In a completely digital economy, service downtime takes a higher toll. For ITOps teams, working remotely also requires new strategies to organize a team’s response to issues. Amid rising incidents, 94.1% of organizations have increased their focus on service reliability engineering (SRE) practices.

    Transposit just released their 2021 State of DevOps Automation report, which surveyed over 500 IT, DevOps, and SRE professionals across the U.S. The report sheds light on the state of remote work as it relates to incident response processes, reveals increased demand for SREs and highlights the automation they’re using to narrow the resolution time gap. Below, we’ll explore the report’s key takeaways and discover what sort of DevOps automation is trending.

    Remote Work Slows Incident Response

    Try as they might, videoconferencing and group chat solutions like Zoom and Slack just can’t compete with in-person collaboration. According to the survey, 93.6% of ITOps and software teams reported it takes longer to resolve incidents while working remotely.

    Since the pandemic began, 97% of teams have adopted remote work, and 90.4% have experienced increased service incidents. It doesn’t bode well that incidents are increasing as incident response time lags.

    The report findings frame remote work as a top hurdle to resolving issues — 46.1% reported that not being physically in the same room to collaborate on fixing issues was a top concern. But remote work is only one element; others cite changing processes and a lack of visibility into who’s responsible for maintaining code as another challenge.

    Incident Response Hangups

    To make up for these concerns, organizations are investing in incident response strategies. The report found that 56.4% of companies are adopting communication and collaboration tools, with automation tools at 52.3% and integration tools at 43.9%.

    Though the report showed greater investment in those tools, it also identified a persistent communication gap. When conducting postmortems, it can be challenging to correlate human action to incident responses. More than half (57.4%) of respondents felt it’s hard to piece together human actions and team communication during incidents. This context is essential to make sense of mean-time-to-response (MTTR) metrics.

    Interestingly, the report found 96.4% of respondents believe mining insights from human data, like Slack channels or group emails, could help improve incident responses. It appears that having a clearer way to harvest and query incident-related data throughout the entire response process is a universal concern.

    SRE Goes Mainstream

    As I previously reported, the SRE role continues to evolve and gain favor. The report similarly hypothesizes that, based on the survey results, the SRE title is going mainstream. Out of 295 respondents surveyed, 98% said they increased SRE practices in the last 12 months, and 62.4% said they would be expanding SRE efforts in 2021.

    In 2021, SREs will likely remain a hot commodity in hiring. However, these individuals will face mounting complexity in addressing real-time incidents for complex distributed systems. They will also likely be tasked with automating manual processes, as 51.7% of respondents reported that a lack of automation is the top cause of slow incident resolution.

    Automation Goals and Barriers

    40% of companies surveyed now have at least one dedicated full-time staff member working to create in-house tools or bots to automate incident responses. So, what sort of automation is common in the SRE field? The report shows SREs constructing custom scripts to automate things like:

    • Customer communication
    • Recording MTTR metrics
    • Automating infrastructure
    • Corporate communication
    • Auto-generating runbooks
    • Creating or updating tickets

    But, automating these processes is not all that easy. As a top barrier to automation, DevOps professionals collectively cite a lack of documentation. It seems by replacing tribal knowledge with up-to-date, shared documentation, teams could quickly unlock some gains. So, make documentation accessible, and provide copy-and-paste abilities for sample scripts.

    SRE and Automation to the Rescue

    The study demonstrates how the remote economy has increased both the number of incidents and the mean response times to address them. To fill this gap, organizations increasingly turn to site reliability engineering practices to automate incident responses. By leveling up DevOps with SRE, teams could reduce errors and improve overall availability as development teams progressively deliver new features.

  • Why Developers Should Care About Resilience

    Why Developers Should Care About Resilience

    Recently, a friend reminded me of a joke we used to have when we were both developers at a huge software corporation (we won’t mention names, but back when printers were a thing, you probably owned one of theirs). We didn’t develop printers. We developed performance testing and monitoring tools.

    We were the dev team, which was completely separate from the QA team and from the Ops team (yes, I’m that old – we didn’t even call it DevOps back then). Support was part of a completely different organization and “business” was something that happened in an altogether different galaxy. That is, until a customer had an issue.

    When an important customer had an issue, we definitely felt it at R&D. Managers called hourly to check on status, and we would have intense conversations with the support team who would then, in turn, have intense discussions with the customer. If we, the software engineers developing the product, ended up on the same call with both support and the customer, it was a sure sign that things were bad. You knew that millions of dollars were on the line, and, consequently, that pressure was high. But most of all: you knew that we would do anything we could to solve the problem, because we needed those millions of dollars to be paid, so that we could keep getting paid. And so, we kept the coffee flowing.

    This is where the joke part comes in. We used to have a system for managing support tickets, collecting information, tracking time and assigning it to the relevant software or support engineer, so everyone would know who was in charge. Today, you probably use Zendesk, ServiceNow or one of their alternatives. We used a home grown system, of course.

    Our joke was this: the purpose of the system was not to track and measure and propagate the handling of customer issues. The purpose of the system was to indicate someone else is now responsible for solving the problem. Or, if you would rather paraphrase one of my favorite Douglas Adams jokes, the issue is now under a Somebody Else’s Problem field.

    Because solving customer issues is difficult and frustrating, and being pressured by business could ruin a software engineer’s day. This is because when you’re a happy code monkey, and all you want to worry about is writing beautiful code and releasing cool features and drinking some coffee, solving a customer issue gets in your way.

    You end up spending too much time sifting through endless logs, crossing your fingers and trying to reproduce an issue that only happens at 2 a.m. on a Friday, usually when a blue zebra is passing by. Spending your time on a heated support call is less fun than, say, drinking coffee quietly with your friends.

    As R&D managers, we understand that our developers want nothing to do with solving customer issues. We want to make sure they are motivated and happy and efficient, and that they are free to challenge themselves by learning the latest buzz-worthy technologies and thinking up ways to introduce those into our product in a way that will make our customers happy.

    Additionally, as R&D managers, we are far more likely to understand the business impact of having too many support tickets or having support tickets that take too long to resolve. We know that the loss on such cases is twofold:

    1. The customer that faced an issue and is waiting for a solution may become frustrated, and the company may lose their business.
    2. Our engineers are busy solving that customer issue instead of delivering new value to the business.

    Therefore, as R&D managers, it is our responsibility to make sure that our engineers have the tools to handle these issues as efficiently as possible when they come up. It is our responsibility to make sure they are motivated, and that they understand the business impact of solving a customer issue as quickly as possible. And whenever possible, it is our job to make sure that they make our application as reliable and stable as possible to begin with.

    That ensures that we have test coverage, and the right knowledge, practices and tools to ensure that we have as few customer issues as possible to begin with.

    Happily, changes in dev culture usually means that “support” and “business” and even “customers” are not as far away as they used to be. When developing a SaaS platform, your developers often have an almost intimate, real-time ability to track what users are doing and how it impacts their experience. The culture of DevOps has done a lot for breaking the silos that used to separate the dev team from the support team, and to make sure that all members of the team engage and understand how the code they write and the issues they resolve help our customers.

    I hope you already found the way to motivate your team to solve such issues, and that they have enough time to drink coffee. If you and your team are still struggling, we suggest bringing in a live debugging tool that can help them solve customer issues even faster, by making sure they have all the data they need at their fingertips, and that they can instantly reproduce any issue in a live, remote environment. Live debugging tools give your engineers a developer-friendly experience, and also gives them the power to reduce issue resolution time, too. Now, all you need to worry about is that your engineers have enough coffee.