Tag: service mesh

  • 5 Time-Saving and Problem-Solving Technologies for DevOps Teams

    5 Time-Saving and Problem-Solving Technologies for DevOps Teams

    DevOps has transformed almost every aspect of software development, taking us from the dark ages of big-bang deployments every 12 months to the reality of releasing software multiple times per day. However, DevOps professionals have to overcome several hurdles to successfully implement and sustain the DevOps culture within the organization. Let’s review some of these challenges—and five technologies that can help.

    Cultural and Organizational Differences

    One persistent challenge for DevOps teams in a mature setting is navigating cultural and organizational differences. These differences often manifest in varied working styles, communication methods and priority management across teams. For instance, development teams might prioritize rapid innovation, while operations teams focus on stability and security, leading to conflicts. Managing these diverging priorities requires constant negotiation and alignment, which can be time-consuming and complex. 

    Furthermore, as organizations grow and incorporate diverse teams, including remote and international members, ensuring cohesive communication and understanding becomes even more critical. This diversity, while beneficial, brings challenges in terms of aligning on common goals and working practices, often leading to delays and misunderstandings that impede efficient workflow.

    Complexity of Automation

    In mature DevOps environments, the complexity of automation can become a significant day-to-day challenge. As the infrastructure and application landscape grows, the automation scripts and tools that were once efficient can become unwieldy and difficult to manage. Keeping these automation processes up-to-date with the constantly evolving technology stack is a never-ending task, requiring significant time and resources. 

    Additionally, the integration of new tools or updates to existing ones often introduces complexity, leading to potential errors and downtime. This complexity not only slows down the deployment process but also requires DevOps teams to invest time continuously in learning and adapting to new tools and methodologies. Ensuring that automation is both robust and flexible enough to handle a dynamic environment is a delicate balance that DevOps teams must constantly maintain.

    Cross-Team Collaboration

    Effective cross-team collaboration is vital for DevOps teams but can be challenging in day-to-day operations. The interdependence between various teams–such as development, operations, QA and security–requires a high level of coordination, often hindered by differing goals, tools and terminologies. Communication barriers can lead to misalignment on project objectives, causing delays and inefficiencies. 

    Moreover, in a fast-paced DevOps environment, keeping everyone on the same page regarding updates, changes and issues requires meticulous attention. This is compounded when teams are distributed geographically, as time zone differences and cultural nuances add another layer of complexity. Regular synchronization meetings, clear communication channels and shared tools are necessary, but managing these effectively without causing meeting fatigue or information overload is a continuous challenge.

    Consistency and Standardization

    Maintaining consistency and standardization across various projects and teams is a significant challenge for mature DevOps teams. As the number of services and microservices increases, ensuring that each adheres to the same set of standards for coding, security and deployment becomes increasingly difficult. Inconsistencies can lead to significant problems in integration, testing, and deployment, slowing down the entire delivery process. 

    Furthermore, as different teams may prefer different tools and practices, creating a standardized environment that accommodates everyone’s needs without compromising on efficiency or quality is a complex task. Regular audits, effective governance and a balance between flexibility and standardization are essential to manage this challenge, but they require constant effort and vigilance.

    5 Lesser-Known Technologies That Can Help

    While there is no one technology that can completely alleviate the above challenges, there are several tools that can help. Let’s review five technologies that can make the life of a DevOps team just a little bit easier.

    Chaos Engineering Platforms

    If you’re part of a DevOps team, you’re probably all too familiar with the panic that ensues when a system fails unexpectedly. Chaos engineering platforms aim to save you from such unforeseen surprises by embracing the philosophy of ‘breaking things on purpose.’

    Chaos engineering involves intentionally introducing failures into systems to understand how they respond and to identify potential weaknesses. By doing so, DevOps teams can proactively find and fix issues before they manifest in production, thereby saving significant time and preventing potential downtime.

    Platforms like Gremlin and Chaos Monkey offer controlled environments for running these chaos experiments, providing teams with valuable insights and recommendations. In the long term, this can not only save time but also instill a sense of confidence and resilience in your systems.

    Application Dependency Mapping

    Application dependency mapping (ADM) is a process that helps DevOps teams visualize and understand their applications and their dependencies. It is a crucial technology that aids in quickly diagnosing and rectifying application performance issues, thereby saving time.

    ADM provides a holistic view of the application architecture, showing how different components interact with each other. This comprehensive visibility is invaluable during troubleshooting as teams can easily pinpoint problematic areas and rectify them without having to sift through mountains of code.

    Furthermore, ADM is crucial when planning for application changes or upgrades. Understanding how changes in one component may affect others helps in preventing potential disruptions, leading to smoother and faster software delivery.

    Policy-as-Code Solutions

    Policy-as-code is a practice where policy definitions are codified and managed as code files within version control systems. This approach offers a host of benefits that can save time for DevOps teams.

    Policy-as-code solutions enable automatic enforcement of policies, eliminating the need for manual checks. This significantly reduces the time taken to ensure compliance and allows teams to focus more on developing and delivering quality software.

    Moreover, since policies are managed just like any other code, they can be versioned, tested and reviewed before being deployed. This allows for a more streamlined and error-free policy management process, saving valuable time and effort. Tools like Open Policy Agent and HashiCorp Sentinel are commonly used to implement policy-as-code in DevOps environments.

    Service Mesh Technologies

    Next on the list is service mesh, a dedicated infrastructure layer for managing service-to-service communication in a microservices architecture. Service mesh technologies offer a range of features that can save time for DevOps teams.

    One of the primary benefits of a service mesh is its ability to offload common communication concerns from individual services to the mesh itself. This includes functionalities like load balancing, service discovery, and traffic management. By doing so, it saves DevOps teams the time and effort required to implement these functionalities within each service.

    Additionally, service mesh technologies provide detailed observability of the service communication, making it easier for teams to monitor, troubleshoot and optimize their applications. Istio and Linkerd are two common open source options for implementing service mesh.

    Codeless Test Automation Tools

    Codeless test automation tools represent a significant shift in the way DevOps teams approach software testing, offering a more efficient and less time-consuming method. These tools allow the creation of automated tests without the need to write extensive code, making test automation accessible to team members who may not have deep coding expertise.

    Using a graphical user interface, codeless test automation tools let users design tests by simply dragging and dropping elements into a workflow. This approach not only accelerates the test creation process but also simplifies the maintenance and updating of tests as applications evolve. Additionally, these tools often integrate seamlessly with various CI/CD pipelines, ensuring that automated tests can be easily incorporated into existing DevOps workflows.

    With the speed at which technology is advancing, it’s crucial for DevOps teams to stay updated on the latest tools and technologies that can help them optimize their processes. The technologies listed in this article can significantly save time for DevOps team and make complex DevOps workflows a little smoother.

  • Deploying a Service Mesh: Challenges and Solutions

    Deploying a Service Mesh: Challenges and Solutions

    A service mesh is a dedicated infrastructure layer that enables communication between microservices in a distributed application. It helps to abstract the underlying communication infrastructure, such as network protocols and load balancing and provides a consistent interface for microservices to communicate with each other.

    In a service mesh, each microservice in the application is represented as a “service” within the mesh, and the mesh acts as a proxy between the services, routing requests and responses between them. It also includes a control plane, which manages and configures the proxy instances and provides observability and monitoring capabilities for the services.

    Some of the benefits include:

    • Improved observability: A service mesh provides visibility into the communication between microservices, which can be helpful for debugging and monitoring the performance of the application.
    • Resilience: It can help to make microservices more resilient by providing features such as retries, timeouts and circuit breakers, which can help to prevent cascading failures.
    • Security: A service mesh can help to secure communication between microservices by providing features such as mutual TLS (mTLS) and rate limiting.
    • Ease of use: It provides a consistent interface for microservices to communicate with each other, which can make it easier for developers to build and manage distributed applications.

    Why is a Service Mesh Important?

    A service mesh is important because it helps to abstract the underlying communication infrastructure for microservices-based applications, which can make it easier for DevOps teams to build and manage these types of applications.

    One of the main benefits is that it provides a consistent interface for microservices to communicate with each other, which can make it easier for developers to build and manage distributed applications. For example, a service mesh can provide features such as load balancing, retries and timeouts, which can be useful for ensuring the resilience and reliability of the application.

    It can also help to improve observability for microservices-based applications by providing visibility into the communication between the microservices. This can be helpful for debugging and monitoring the performance of the application, which can, in turn, make it easier for DevOps teams to identify and resolve issues more quickly.

    What are the Main Deployment Challenges?

    There are several key challenges that a DevOps organization may face:

    • Complexity: Service meshes can be complex to set up and manage, especially in large, distributed applications. This can make it challenging for organizations to implement and ensure that it is configured correctly.
    • Operational overhead: Service meshes can add a layer of complexity to the application stack, which can increase the operational overhead of managing the application. This can be especially challenging for organizations that are not used to operating one.
    • Cost: While service mesh software is typically open source, the need to run a sidecar container alongside every container can increase the compute capacity needed to run a Kubernetes cluster.
    • Integration with existing systems: They can be difficult to integrate with existing systems and processes, especially if the organization has not previously used a service mesh. This can make it challenging to get the full benefits.
    • Lack of expertise: Service meshes are relatively new technologies, and there may be a lack of expertise within the organization. This can make it challenging for organizations to get started and ensure it is used effectively.
    • Performance overhead: Service meshes can add a performance overhead to the application as they introduce an additional layer of proxying between microservices. This can make it challenging to ensure that the application is performant and scalable.

    Best Practices to Ease Service Mesh Pain

    Here are a few best practices that can turn service mesh deployments from a pain to a pleasure.

    Use Configuration-as-Code in a GitOps Approach

    Using configuration as code in a GitOps approach is a best practice to improve reliability and maintainability.

    GitOps is a way of managing infrastructure and applications using Git as the single source of truth. In a GitOps approach, all configuration and deployment information is stored in Git, and changes to the infrastructure and applications are made by committing code changes to Git.

    Using configuration-as-code in a GitOps approach can help to improve the reliability and maintainability of the service mesh in several ways:

    • Version control: Storing configuration-as-code in Git allows you to track changes to the service mesh configuration and roll back changes if necessary. This can help improve the service mesh’s reliability by making it easier to identify and fix issues.
    • Collaboration: Git allows multiple people to work on configuration at the same time, which can make it easier to collaborate on changes and ensure that the service mesh is properly maintained.
    • Automation: GitOps approaches often use automation tools, such as continuous integration and delivery (CI/CD) pipelines, to automatically deploy changes to the service mesh when code is committed to Git. This can make it easier to manage and maintain and can help to improve its reliability by reducing the risk of errors.

    Focus On Developer Experience

    Ensuring a positive developer experience is a best practice because it can help to improve the productivity and effectiveness of the development team. A positive developer experience means that developers can easily understand and use the service mesh, and that it does not introduce unnecessary complexity or frustration into their workflow.

    Here are some ways to improve the developer experience:

    • Provide clear documentation: It is important to provide clear and comprehensive documentation on how to use the service mesh, including examples and tutorials. This will make it easier for developers to understand and use.
    • Integrate with existing tools and processes: The service mesh should integrate seamlessly with the existing tools and processes that the development team is already using. This will help to minimize disruptions to the team’s workflow and make it easier for them to work with.
    • Provide support and training: It is important to provide support and training to help developers understand and use the service mesh effectively. This can include online resources, in-person training, and support from the vendor.

    Reduce Costs With Low-Cost Cloud CPUs

    A service mesh increases the cost of an entire containerized deployment because it requires deploying a sidecar container alongside all workloads. When running on Amazon Web Services (AWS), the AWS Graviton processor can ease deployment by reducing the cost of running service mesh infrastructure.

    The AWS Graviton processor is a custom ARM-based processor designed specifically for use in Amazon Web Services (AWS) environments. It is optimized for running workloads commonly found in the cloud, such as microservices and containerized applications.

    Using the AWS Graviton processor can help to reduce the compute costs of a service mesh because it is generally less expensive than other processors, such as Intel Xeon processors. The AWS Graviton processor is also designed to be highly efficient, which can help reduce the service mesh’s overall resource utilization. This can help to reduce the cost.

    Choose the Right Control Plane

    Choosing the right control plane is a best practice because it can impact the performance, reliability and maintainability of the service mesh. The control plane is the central component that manages the proxy servers and enables you to configure and monitor the communication between microservices.

    Here are some considerations for choosing a good control plane:

    • Compatibility: It is important to choose a control plane that is compatible with the rest of the service mesh infrastructure, as well as with the application and its dependencies. This will ensure that the control plane can operate effectively and support the needs of the application.
    • Performance: The control plane should be able to handle the traffic and data volumes of the application without experiencing performance degradation. It should also be able to scale up or down as needed to meet changing demand.
    • Reliability: The control plane should be reliable and able to withstand failures without interruption. It should also provide features such as circuit breaking, retries and timeouts to help improve the resiliency of the service mesh.
    • Ease of use: The control plane should be easy to use and understand, with clear documentation and a user-friendly interface. This will make it easier for the DevOps team to manage and maintain the service mesh.
    • Integration with other tools: It is important to consider how the control plane integrates with other tools and systems, such as monitoring and logging tools, and how it can be integrated into the overall workflow of the organization.

    Conclusion

    In conclusion, deploying a service mesh can be a complex and challenging process, but it can also provide significant benefits in terms of improving the reliability, scalability and security of a cloud-native application. 

    Some of the key challenges include complexity, operational overhead, integration with existing systems, lack of expertise and performance overhead. 

    To overcome these challenges, it is important to choose the right service mesh, use configuration-as-code in a GitOps approach, choose the right control plane and ensure a positive developer experience. By addressing these challenges and following best practices, organizations can successfully deploy a service mesh and reap the many benefits it has to offer.

    Image Source 


  • API Gateway Vs. Service Mesh: What’s the Difference?

    API Gateway Vs. Service Mesh: What’s the Difference?

    In the average microservices architecture, app programs trade the stability and rigidity a call stack offers for the network’s flexibility. Consequently, latency, security and traceability issues that were previously absent become a service call concern. 

    Service mesh is the resulting solution to eliminate these issues and allow developers to focus on more important business solutions. The caveat is the functionality overlap that exists between a service mesh and an API gateway. But while the two are similar, there are also key differences between both options. Here’s what you need to know.

    Defining a Service Mesh

    A service mesh is a comprehensive architectural pattern set designed to deal with enterprise concerns like instability, debugging and security. These concerns arise when a team moves from a call stack to network calls. 

    For instance, a function call via a call stack recognizes the constant availability of the requested function. On the other end of the equation, a network call doesn’t offer this functionality. 

    A service mesh is the preferred option because it assists the system’s client endpoint in managing network instability. The primary method for solving this network instability is frontrunning retries transparent from the client app’s viewpoint. 

    The service mesh also assists the server’s endpoint by rerouting incoming requests to the server node that’s best able to deal with the incoming request. The choice of server node is a function of previously determined policies for routing incoming traffic.

    The ideal service mesh is installed with two layers: The control plane and the data plane. The latter is a proxy for any connection’s server and client endpoints. 

    The data plane also enforces policies from the former while running operation metrics to a monitoring tool. Conversely, the control plane layer manages all attending service policies alongside the data plane’s operation. 

    service mesh

    Image Source

    Key Features of a Service Mesh

    The average service mesh has a number of primary features. 

    But there are a few things that bear mentioning. Say your app development team is working on a small business phone system. This particular service implementation doesn’t need every feature listed below. It depends on your team’s specific needs and traffic setup.

    Traffic Routing

    This feature enables the service mesh to route requests based on preset configuration or a predetermined policy. The system may prioritize traffic from specific client applications. Alternatively, a service mesh can re-route traffic to different service versions for:

    • A/B testing
    • Canary release
    • Service versioning

    Observability

    Service mesh implementations feature proxies that record service calls for individual clients and services. This feature takes the manual burden of the call-logging process away from the developers. 

    Plus, teams can leverage downstream analysis and monitoring tools to report on system availability and overall performance. These monitoring tools also provide a framework for basic tracing across all call chains. 

    The observability capabilities of a service mesh extend beyond the above. For example, some coding work can allow developers to improve call chain monitoring to allow for accurate tracing for enterprise business transactions.  

    Common service mesh observability features include: 

    • Latency, error rate and throughput alerts
    • On-demand service dashboards and graphs depicting the connection between individual services
    • Tracing the journey a business transaction or request makes through the service mesh

    Image Source

    Security Policies

    An application with multiple independent services has a huge attack surface. Essentially, each independent service is a vulnerable entry point that requires protection. A service mesh has proxies on both the server and client endpoints to secure any communication between both terminals. 

    A service mesh also improves security by eliminating the dependence on developers to manually program security into every service. Instead, the server proxies will handle authorization, authentication and encryption for each independent service. The resultant effect is a zero-trust security framework.  

    Identity

    A service mesh manages who can access individual services. It also maintains a real-time log of stakeholders accessing each service and when they did so. The system validates identity through JSON Web Tokens (JWTs) while allowing authorization depending on the requesting service and the stakeholder. 

    Encryption

    Compliance, security and data protection are key considerations. Well, communication between all services in a service mesh is fully encrypted. The control plane is responsible for certificate management functionality including certificate rotation and generation. 

    Furthermore, a service mesh uses mutual TLS where both server and client endpoints whitelist the certificates that can operate on the other side of any connection. A service mesh provides robust mutual TLS authentication, allowing for seamless system authentication and encryption. 

    Resilience

    This feature defines the ability of a service mesh to insulate developers in scenarios where the principal service function goes offline. In some instances, the proxy may follow an alternative service path or switch to a backup framework. 

    For illustration, streaming giant Netflix has a personalized user recommendation feature that suggests titles to its users. If this service goes offline, a service mesh system can ensure a switch to a default recommendation feature with zero personalization. Only when this backup fails will the system return an error code. 

    A service mesh assures developers that when a service fails, the proxy has done all it can to manage communication errors. In some cases, the mesh can ensure optimal performance by switching to a different service with the lowest latency.

    Examples of configurable resilience patterns for a service mesh include 

    • Circuit breaker patterns
    • Rate limiting
    • Retry policies

    Another illustration of a service mesh’s resilience is the ability to build chaos engineering capabilities. The service mesh can inject itself into the endpoints within the network, providing the observability required to monitor a chaos test. 

    Image Source

    What an API Gateway Entails

    Whether the team is working on contract management software for small business or an expense calculator app, the choice of API can determine the results of your team’s app development efforts. But more than the choice of API, proper management is another crucial talking point. The best results come with a system that identifies incoming calls, directing them to the appropriate resource. 

    API gateway is the future of DevOps and is the solution to that need. It’s the technology framework for routing API client calls to the ideal application. It also processes the call, forwarding resulting responses to the client’s network.

    At the technical level, an API gateway isn’t a must-have. Find a developer with a digital business card, hire them, and they can always program an embedded code responsible for call request routing. The only caveat to this alternative is the manpower and resources necessary to program and insert codes for individual call requests. As such, it’s always better to have an API gateway to handle this task. 

    An API gateway is a more innovative solution because extensive coding always holds the possibility of risks and errors. Furthermore, these errors can complicate app development stages like maintenance, bug fixing and application testing. 

    The API gateway ensures all API requests reach their intended destination with zero diversion. Plus, it also offers the following added functionalities:

    • API request monitoring
    • Shifting API requests between individual nodes
    • Request balancing for multiple instance situations

    The Major Differences Between API Gateway and Service Mesh

    An important digital workplace definition that differentiates both frameworks is the placement location. The API gateway is necessarily present on public-facing systems. Other key areas where an API gateway and service mesh differ include:

    Observability

    Observing the performance of the average API gateway is a more concrete task. The framework can provide actionable data insights like how long the API takes to respond to requests, problematic features, and their impact on network traffic. 

    With the service mesh, the ability to spot performance issues is a given. However, the system can’t ascertain any effects of performance lags on end-user response and experience. Therefore, while troubleshooting is easy, gauging the extent of the problem’s impact is more complicated. 

    The Communications They Handle

    Both frameworks manage different communication nodes—one handles internal discussions and the other external ones. The API gateway is the component responsible for routing external communications. For example, the API gateway handles chatbot connections, purchase orders and visits to specific pages. 

    Conversely, the service mesh is responsible for internal communications in the system. For illustration, a discussion between multiple microservices under the same app environment will fall under the service mesh’s purview. 

    In other words, the API gateway manages client-server discussions. Meanwhile, service-service communications are for the service mesh. 

    Management

    Both frameworks may have some areas of overlap, but the amount of management each one requires isn’t one of them. API gateways are simpler to manage and develop. As such, they’re easier for your app development team to manage. 

    The deployment for an API gateway happens just once, regardless of the service app. Plus, post-deployment centralization and monitoring are easy tasks. 

    In contrast, a service mesh is more complicated and tedious to manage. Your app development team must deploy the service mesh function for individual app systems. 

    Compatible Tools

    Most API gateway tools and software resources are highly expensive. Plus, they’re compatible with every popular app architecture. 

    The other end of the equation offers more accessibility. There are countless service mesh tools and resources for varied functionality. Plus, the majority of these support tools come at zero cost because they are open source.  For example, there’s Envoy and Istio, both of which are free and open source. 

    However, you shouldn’t expect to enjoy cross-platform compatibility across these service mesh tools. For example, Istio is only compatible with Google. On the other hand, AWS App Mesh—another service mesh tool—is compatible with AWS Cloud. 

    Image Source


    Difference  API Gateway  Service Mesh
    Existing Functionalities
    • Useful for API requests between the client and server
    • Compatible with external API requests and internal calls. 
    • Handles internal communications 
    • Best for improving the portability of service-to-service calls 
    Digital Transformation Functionality
    • Longer app delivery cycles 
    • Zero security risks
    • Useful for effective microservices management 
    • Speeds up the network’s delivery cycle 
    • Security risks due to open loopholes when the program runs alone
    Operations Reroutes API calls present outside of the given application environment  Works within the application architecture 
    Maturity Level API gateway is mature technology. It has been a core developer tool for several years now Service mesh is still a relatively new technology and requires more research and development
    Security Processing Automated security protocol Manual security systems 
    Usage Complexity Application complexity remains constant with endpoints remaining unchanged  Business scalability can be complex as each update comes with new endpoints 

    Can Service Mesh and an API Gateway Be Used Together?

    The unlikeliest of brands often form marketing partnerships. In the same way, there are instances where using both a service mesh and an API gateway is a logical and feasible idea. 

    While differences exist between an API gateway and a service mesh, it’s not an “either/or” situation.

    Cloud contact center teams looking to streamline communications at both the internal and external levels are already leveraging both technologies. And you can also leverage both systems to achieve the following:

    Improved Innovation

    Effective API use, especially during external interactions, requires internal resource optimization, which is better when teams deploy a service mesh alongside an API gateway. 


    Image Source

    Accelerated Digital Transformation

    Leveraging both resources improves enterprise digital transformation rates. Plus, any application with both technologies will enjoy a unified API gateway for internal service mesh management. If there are any linked applications, the unified API makes them simpler to handle.

    Increased Security Scalability

    Scalable container security is achievable when you deploy a service mesh and API gateway together. The service mech will boost the system’s interservice connectivity while the API gateway acts as a central point for all client-server requests. 

    The API gateway also provides the much-needed technical support for increased proxy security. It also fosters quick threat detection and resolution at the proxy level. 

    API Gateway and Service Mesh are Different

    Both the API gateway and service mesh are designed to simplify communication while also reducing any coding responsibility on the app development team. While both systems can ensure network calls through an enterprise contact center reach the target destination, they’re structurally different.

    Above, we’ve highlighted the key differences between both frameworks. But despite these differences, both systems are compatible and can work together for improved app development. We recommend leveraging a service mesh and an API gateway together for better security, innovation and app scalability.

  • Service Meshes Are on the Rise – But Greater Understanding and Experience Are Required

    CNCF conducted a microsurvey of the cloud native community at the end of 2021 to discover how organizations are adopting service meshes. 

    Cloud native is driving digital transformation, with organizations keen to capitalize on the agility and flexibility it provides to their business and operations. But as more applications and services are deployed using a diverse technology stack, it has become a challenge to deliver and manage performance and availability.

    A service mesh provides an answer, creating a dedicated layer that handles service-to-service communications that ensures consistency and reliability of services, security, and observability. Moreover, a service mesh available off-the-shelf, as a community-driven, open source project, means organizations can avoid the challenges and overhead of building their own, thereby reducing the support burden.

    It’s no surprise that service mesh has become a key component of cloud native infrastructures. Of the 253 survey respondents, 70% run a service mesh in production or development, and 19% in evaluation mode. Some said they are running a service mesh for clients who had high levels of adoption. Those not implementing a service mesh formed a distinct minority – fewer than 10%. 

    Service mesh adoption is running hand-in-hand with the rollout of Kubernetes clusters. The majority of participants (65%) run or plan to run between two and ten Kubernetes clusters on a service mesh. Another 11% are operating or planning to operate between 11 and 25, with just 10% going further with 26 or more clusters.

    The number of projects and products has mushroomed in response to the spread of service mesh. The differences between them vary according to the breadth of features, ease of deployment, use cases (such as edge), or optimization for different levels of the network stack. Participants picked from a list of 15 projects or products they currently use or plan to use in the next year. Two led the field: Linkerd and Istio with 72% and 34%, respectively – a clear expression of confidence in open source. 

    It’s all about features

    We explored the factors influencing people’s choices by asking which features and capabilities drive their organization’s adoption of service mesh. Security is a top concern, with 79% putting their faith in techniques such as mTLS authentication of servers and clients during transactions to help reduce the risk of a successful attack.

    Observability came a close second behind security, at 78%. As cloud infrastructure has grown in importance and complexity, we’ve seen a growing interest in observability to understand the health of systems. Observability entails collecting logs, metrics, and traces for analysis. 

    Traffic management came third (62%). This is a key consideration given the complexity of cloud native that a service mesh is expected to help mitigate. As organizations seek to run more sophisticated, blue/green deployment scenarios, traffic management can apply to a range of capabilities, including discovering endpoints and services, controlling API calls between services, and hiding or exposing services.

    In fourth place was reliability with 56%. Potential issues here include latency, lack of bandwidth, security incidents, the heterogeneous composition of the cloud environment, and changes in architecture or topology. Respondents want a service mesh to overcome these networking and in-service communications challenges.

    Support for multi-cluster communications was of significant interest, with 87% in total classifying it as important. Breaking that figure down revealed where organizations are in their deployment: 50% described multi-cluster communications as “somewhat” or “very” important, while the 37% who said it was not important at the moment but would be in the future may be in the development stage, pilot mode or, running a relatively simple production-level service mesh.

    Users expect to implement a broad array of service mesh features in the coming year. The most popular (46%) is header-based routing control, making it easier to implement more sophisticated capabilities such as A/B testing and blue/green deployments.

    A cluster of features came next. The ability to detect and manage the presence of shadow traffic/dark traffic will be important for 29%, suggesting a desire to collect system data that is as accurate as possible by accounting for traffic that analytics tools might otherwise miss. 

    Extending the service mesh to work with non-Kubernetes environments was important for 27%. Kubernetes might have become a fundamental building block of cloud native, but this response indicates the strong presence of alternative environments. Extending a service mesh to encompass those is consistent with the bigger drive to eliminate silos in IT infrastructure and management. Similarly, plug-ins to environments such as WebAssembly were important for 25%. 

    Interestingly 25% also gave “none of the above” as their choice of new feature. Rather, authorization and authentication emerged as the most common response.

    Challenges remain

    There’s plenty of interest in service mesh, but there are hurdles to adoption, so we asked survey participants to rank them. First, non-technical challenges: the top three will be familiar to any newer technology – shortage of engineering expertise and experience (47%), architectural and technical complexity (41%), and a lack of guidance, blueprints, and best practices (36%). 

    When questioned about technical challenges, respondents reported struggling in various areas. Integration topped the list (32%), followed by reliability and consistency (26%), defining policies (22%), monitoring and tracing (22%), and policy management (21%).  A quarter of respondents threw in additional challenges under “none of the above.” When asked to explain further, they listed CI/CD integration, difficulty troubleshooting, and problems with specific products.

    Methodology

    The microsurvey was designed by CNCF and conducted between November and December 2021 among 253 members of the CNCF and Kubernetes communities. 

    Of 253 respondents:

    • just over two fifths (43%) were from Europe
    • 30% were from North America
    • 17% were from Asia 
    • the rest (10%) were from Australia and Oceania, South and Central America and Africa.

    Just over a fifth (21%) – the single largest group of respondents – represented organizations with 100-499 employees.

    • slightly fewer (19%) were from organizations with 10-49 employees
    • 13% represented organizations with 50-99
    • 10% were from organizations with 500-999 employees, another 10% with 1,000-4,999.
    • 18% had more than 5,000 employees
    • 8% had a headcount smaller than 10

    The most common job function was Site Reliability or DevOps Engineer, specified by 51.38% of respondents.

    • 36.36% were software architects
    • 25.69% were back-end developers

    47.83% of the respondents worked in the software/technology industry, and 17% – the next largest group – in financial services.

  • When to Use API Management and Service Mesh Together

    When to Use API Management and Service Mesh Together

    Though sometimes described as competing architectures, API management and service mesh have slightly different use cases and can actually work well together. Whereas API management provides the business logic for outside-facing traffic, a service mesh excels at handling intercommunication between microservices. An organization could certainly adopt both simultaneously across their projects. So, when does it make sense to use both API management and service mesh?

    I recently chatted with Mark Cheshire, director of product, Red Hat, to discuss the nuances between API management and service mesh. According to Cheshire, API management and service mesh can work quite well side-by-side for particular use cases. For example, a large organization using service mesh could benefit from applying API management that wraps microservices in a usable contract for internal departments. Or, API management could help a company expose specific APIs from the mesh to outside partners.

    When to Combine API Management with Service Mesh

    Say you already have service mesh—do you need API management, as well? Cheshire offered four questions to keep in mind that may influence your decision.

    1. Consider the number of connections and the number of consumers: Is it many-to-one or one-to-many?

    Within a monolithic application, communication is more centralized—there is more of a one-to-one relationship. However, when you break apart services into microservices and reuse them across an organization, a service may now have many consumers. This is a good indication you need an API management approach for the interface.

    “When environments get larger and larger, you can’t manage that as a flat mesh,” explained Cheshire. “You need some kind of organizational grouping by line-of-business or by the functions that you may have.”

    API management can create more formal interfaces between internal groups in a large organization that likely have little to no contact with one another. For example, perhaps the customer data team needs a formal method to connect with the sales organization. Or, maybe a security team supporting a login microservice needs to access financial details from an accounting division.

    2. What sort of access control and limiting does the system require?

    Consider what access control is necessary to secure your environment and avoid service disruption. A service mesh will typically use a zero-trust approach, applying mutual TLS over every ingress to each microservice. API management can also bring authentication controls and more advanced authorization and traffic mechanics.

    API management can provide a streamlined way to apply fine-grained controls for inter-domain traffic that follows the business logic. This helps assign access to specific resources to different requesting parties, such as read-only access for basic users or update access for admins. Amid increasing API attacks, setting fine-grained policies and permissions around your endpoints is becoming increasingly important to avoid data overexposure. This imperative increases as the binary between external and internal traffic fades with more public cloud use, remote work and third-party contractors.

    API gateways also place greater emphasis on communication rules and patterns. Rate limiting, for example, is very important to avoid collapsing entire networks, explained Cheshire. In addition to rate limiting, filtering, pagination and content negotiation are also standard API management capabilities that further optimize the exchange between the client and server.

    3. Do you require documentation for the services?

    In a monolithic setup, you likely have all developers sharing the same repository, explained Cheshire. This may still be true within an internal network of distributed microservices wherein each microservice is independent, yet developers can still access each other’s repositories. When you’re connecting services inside a domain, it’s often just the code itself (and perhaps some in-line commenting) that represents the contract between services.

    However, north-south traffic requires much more formalization, he said. Formal contracts are often necessary when one domain is communicating with another within the same company. In this scenario, there’s less tribal knowledge around how things work. API management is useful, in this case, to produce a developer portal with human-readable documentation that explains the methods, request types, URL structures and sample calls. This makes it much easier for someone without preexisting knowledge of the system to integrate with it.

    This formal contract is often generated from a specific file, such as OpenAPI Specification, which has emerged as industry-standard metadata for describing REST APIs. Groups can use OpenAPI to automatically generate documentation and even drive specification-first development. All in all, standardizing the way you document APIs and microservices can significantly improve the knowledge-sharing around how services connect.

    4. What is the nature of interactions?

    Another trait to keep in mind is the nature of interactions between services, Cheshire said. He divided systems into two large types: First is a graph model, in which any service can connect to any service. The second is a hierarchical model in which north-south traffic enables one service to have multiple consumers. A hierarchical model is necessary for productization and SaaS since it creates a single intercept point to the underlying resources. Maintaining hierarchy here is vital to retain simplicity, as you wouldn’t want the consumer to be able to hit all private microservices in a connected graph (unless that’s the intent!).

    API management thus enables the sharing of APIs on the mesh. “While they both use communication proxies, and while there are parallels in function, the differences in domain set them apart, and most companies will see significant benefits from using them together,” wrote Dino Chiesa and Greg Kuelgen on the Google Cloud blog.

    Better Together

    In summary, API management and service mesh go well together. “The two are complementary and can work together,” added William Morgan, CEO, Buoyant. Joaquim Moreno wrote, “they are not mutually exclusive; we should think about them as different layers in your infrastructure.”

    Specifically, combining the two is beneficial when:

    • Exposing and productizing APIs on the mesh
    • Formalizing inter-service communication in large corporate networks
    • Applying fine-grained access control; rate limiting for API-based microservices
    • Standardizing services with more formal documentation
    • Interaction is a more hierarchical communication model
    • Providing access to partners
    • When you need to externalize data to third-party plugins or integrations

    “The worlds of APIs and services mesh are becoming ever more closely connected,” said Cheshire. And API management won’t stop at REST—as developers adopt new integration styles like Kafka, GraphQL and asynchronous formats, the solutions will evolve. “It’s essentially a governance layer for all your integration points.”

    Large companies that seek to standardize inter-domain traffic within organizations will likely benefit from API management. But API management also offers the potential to productize internal infrastructure. Another benefit is that an API management gateway may also monitor and log requests, helping spot actors at the perimeter and keeping a helpful tally of incidents.

    Of course, adopting both API management and service mesh may be overkill for some scenarios. And, it’s good to remember that introducing additional layers inherently increases overall latency. It’s up to developers and architects to weigh the options and determine what’s appropriate for their unique environment. To enable this, a healthy culture of open communication is important to ensure teams are on a similar page across divisions, to avoid mismatched adoptions that only increase technical debt.

  • How Are API Management and Service Mesh Different?

    How Are API Management and Service Mesh Different?

    The use of APIs and microservices is increasing—a recent study from F5 estimated that the industry is approaching 200 million total APIs. As organizations expand their use of APIs and microservices, they inevitably require some form of service management architecture. There are primarily two major design options for implementing this: An API management system or a service mesh.

    The key distinction between API management and service mesh can be framed using the four cardinal directions. API management is typically adopted for REST services that face external developers—referred to as north-south traffic. On the other hand, service mesh is more commonly used by internal suites of microservices to help control lateral, or east-west, communication. There are more nuances between each, as we’ll cover below, but this is essentially how they’re adopted in practice.

    However, this binary is becoming blurred as collections of enterprise digital applications expand and access to cross-company business domains begins to look and feel more like consuming a third-party SaaS. Furthermore, some suggest that with the right controls, service mesh can cater to external users in the same way API management does. What’s more, service mesh and API management are complementary—they can coexist within the same organization and even be deployed in the same projects.

    I recently chatted with Mark Cheshire, director of product at Red Hat, about the emergence of both API management and service mesh. According to Cheshire, both approaches accomplished similar goals but evolved very differently. Below, we’ll revisit why these two paradigms emerged and compare and contrast them. In a separate article, we’ll consider when it’s best to integrate them both.

    What is API Management?

    API management is most often associated with north-south traffic. By exposing your API to the outside world, you enable other developers to connect it to their systems and leverage your data and functionality like building blocks.

    API management arose in response to the rise of web APIs. API management is a broad concept encompassing many functions required to expose an API endpoint to the outside world. This can include authentication, authorization, request routing, documentation, rate limiting, monitoring, logging, monetization and life cycle management. A key goal is to make integration easier for the developer consumer. Architecturally, API management follows a gateway pattern. Consumers issue requests to the gateway which then performs routing to the underlying services.

    For APIs, the big catalyst was the emergence of Web 2.0, Cheshire explained. Numerous startups began consuming RESTful APIs to connect their web properties and partner ecosystems. Companies also found REST APIs to be a much more straightforward integration approach than SOAP and SOA. They also saw the ease-of-use benefits and adopted API-first designs within their internal infrastructure.

    As of 2021, over 70% of APIs are built for internal use. So, do all these services need API management? It depends. “If you communicate externally, you need API management,” explained Cheshire. But, it’s a grey area for services within an enterprise, he says, though inter-domain traffic often could benefit from API management.

    A diagram of API management capabilities, from 3scale
    A diagram of API management capabilities, from 3scale

    Strengths

    • Can enable north-south traffic
    • Protects the boundary of an application
    • Designed to ease external developer consumption
    • Potential for monetization, subscription plans
    • Typically plug-and-play; easier to support
    • Many solutions on the market
    • Developer experience and docs
    • Analytics and reporting

    Weaknesses

    • May be heavier than service mesh
    • Fewer open source options; vendor lock-in
    • Analysis paralysis in comparing solutions

    What is Service Mesh?

    Service mesh is most often associated with controlling east-west communication between internal services. Service meshes like Linkerd, Istio and Kuma make it easier to reimplement similar logic—such as networking, observability, traffic management, security policies and routing—across many microservices from a single control plane.

    Service mesh was born to address slightly different challenges than API management. “The transition from monolithic to microservices is all about east-west traffic,” Cheshire said. Companies found it slower to innovate monolithic applications and thus broke them up into microservices that communicate via APIs. But these microservices all needed similar operational capabilities, which would be cumbersome to repeat over and over for each service.

    “For one monolithic app blown into microservices, you may not even need a service mesh,” said Cheshire. “However, when you have hundreds or thousands, that’s when applying service mesh becomes critical.”

    Istio service mesh architecture
    Istio service mesh architecture

    Architecturally, service mesh is typically divided into a data plane and a control plane. The service mesh deploys a sidecar proxy that sits alongside each individual service. Istio, for example, utilizes the Envoy proxy. Other meshes like Linkerd use their own proxy.

    Strengths

    • Fits the microservices architecture paradigm well
    • Good for traffic routing; improving resiliency
    • NIST-recommended architecture for achieving zero-trust
    • Many open source options
    • Fits large microservices deployments

    Weaknesses

    • Requires a more hands-on approach
    • Potentially more maintenance to support
    • Unnecessary for a single service
    • Requires filter chain add-ons for north-south abilities

    Comparing API Management and Service Mesh

    API management is predominantly aligned with externalizing APIs to partners. When you do so, maintaining the contract with a consumer is more important to meet SLAs. Thus, API management commonly delivers life cycle management abilities, such as versioning. API management is necessary even if you are exposing a single API, as this service needs to be adequately documented and secured. That being said, these tenants can also be relevant to developers reusing software within an organization—there’s something to be said for adopting a product mindset when dealing with internal APIs.

    On the other hand, service mesh is more aligned with controlling internal networks. Microservices are rarely deployed alone; typically, multiple microservices make up an application. And, many more might exist throughout an organization for unique purposes. Service mesh thus helps maintain consistency throughout large networks of decoupled microservices. Service mesh is also a rapidly growing field, experiencing an explosion of new development and production use. A Cloud Native Computing Foundation (CNCF) report found that service mesh use rose in production by 50% in 2020 alone.

    To put the comparison another way, William Morgan, CEO, Buoyant described how API management is more about business logic, whereas service mesh handles intra-cluster operations:

    “API gateways typically handle ingress concerns, not intra-cluster concerns, and often deal with a certain amount of business logic, e.g. ‘User X is only allowed to make 30 requests a day’. By contrast, a service mesh like Linkerd is focused on operational concerns (e.g. instrument these calls and report their success rate; secure this communication between these pods) and purposefully avoids the mixing of business and operational logic; and focuses on communication between the services on the cluster.”

    Though service mesh and API management achieve slightly different aims, both layers make it easier to reuse web-based services. And, they certainly can be used in conjunction. For example, you could build API-first microservices with service mesh and simultaneously use API management to expose certain domains. In another article, we’ll consider when it’s best to integrate the two technologies.

  • HashiCorp Previews Updates to Consul Service Mesh

    HashiCorp Previews Updates to Consul Service Mesh

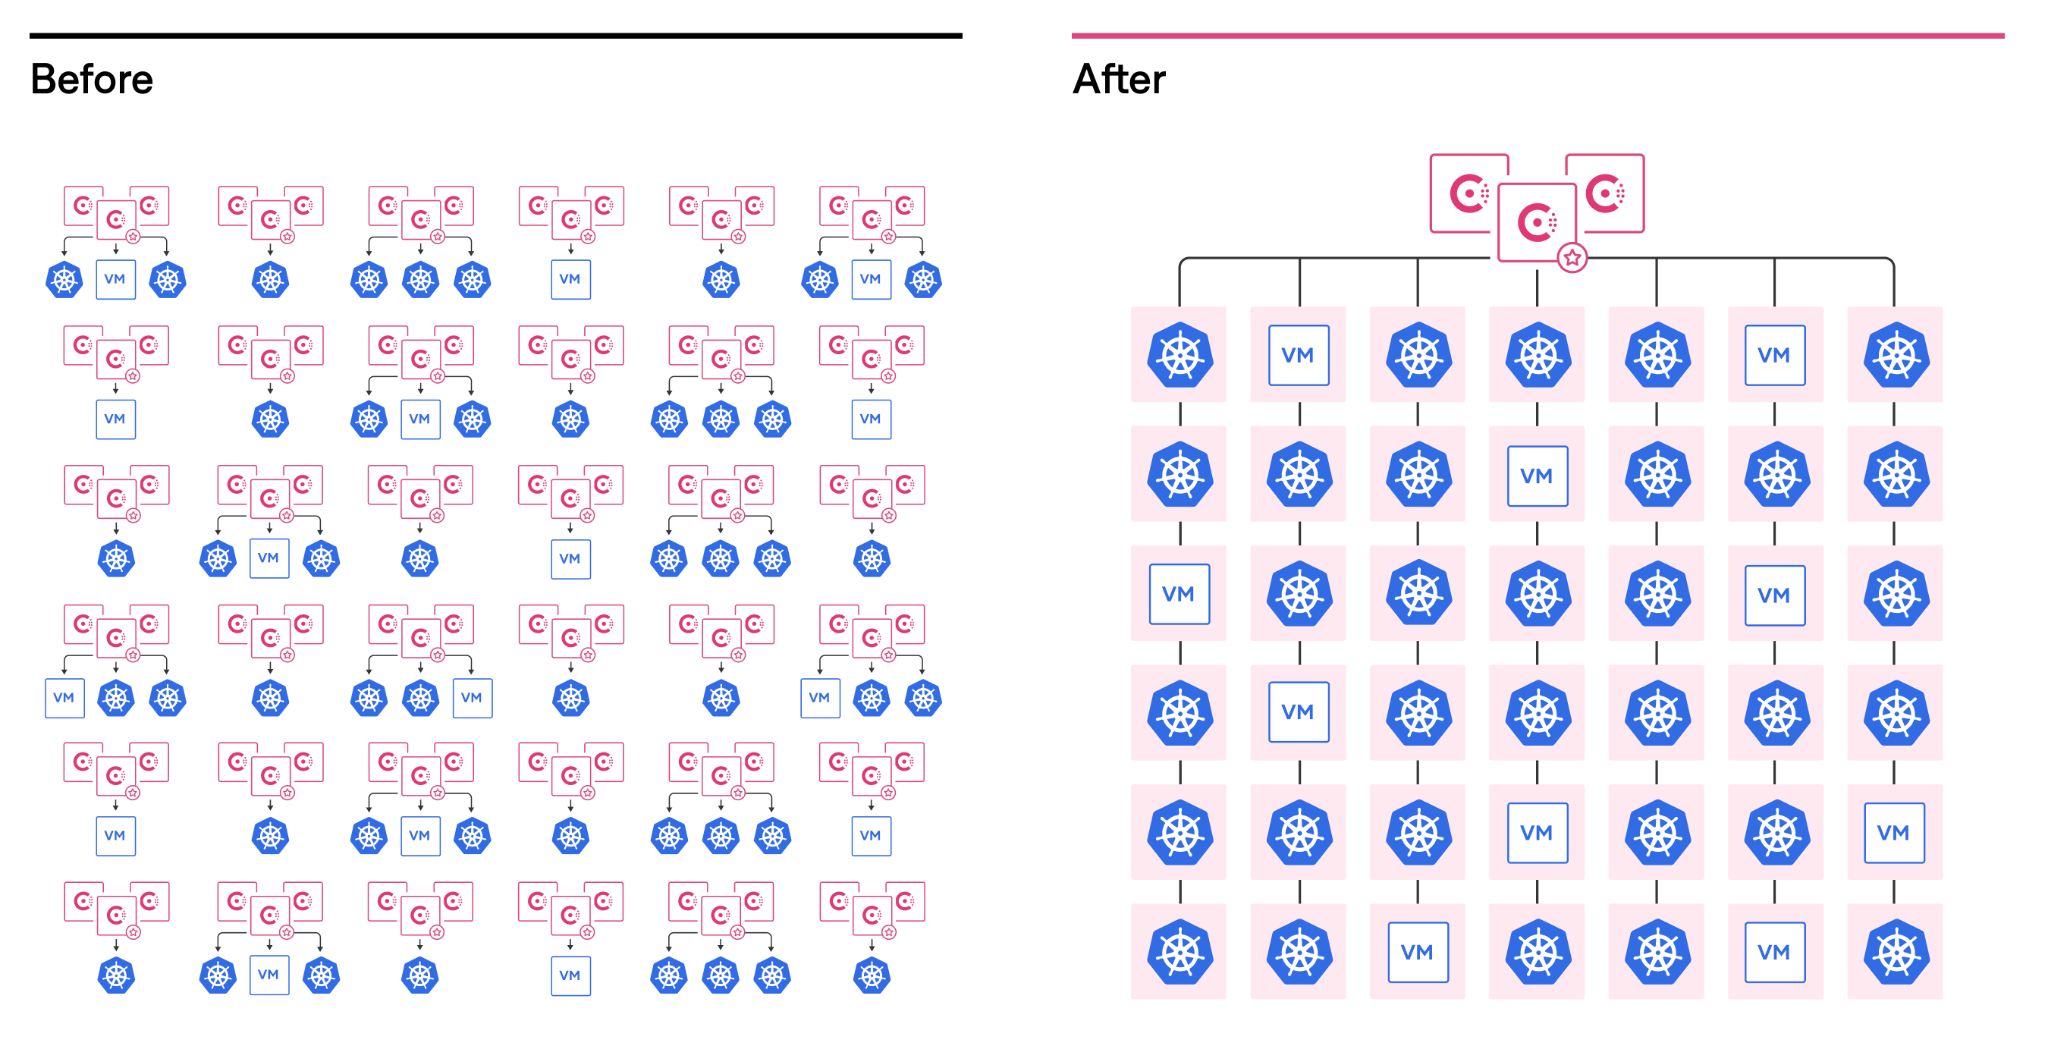
    During an online HashiConf Global conference, HashiCorp today made available a beta of an update to its open source Consul service mesh for virtual machines and Kubernetes clusters that makes it possible for multiple administrators to share the same instance of a multitenant service mesh.

    Version 1.11 of Consul will also add support for a command line interface (CLI) for Kubernetes that will provide an alternative to Helm charts for installing Consul on those clusters.

    Raymond Austin, director of product marketing for HashiCorp, said it’s become apparent that there is a need for a higher level of abstraction for managing application programming interfaces (APIs) that is easy to deploy across both legacy IT environments based on virtual machines and cloud-native environments based on Kubernetes clusters.

    Of course, in many cases, those Kubernetes clusters are deployed on top of virtual machines. However, there are also now more instances of Kubernetes being deployed on bare metal platforms at, for example, the network edge.

    As IT environments become more complex, a service mesh makes it simpler to discover, access and secure APIs that are now rapidly proliferating across the enterprise. That transition requires a more dynamic approach to not only managing APIs but also the network services those APIs depend on, added Austin.

    HashiCorp is betting that many IT organizations will prefer to rely on a lightweight open source platform supported by a single vendor rather than relying on more complex open source service mesh offerings being developed under the auspices of a consortium.

    It’s still not quite clear who within an IT organization is assuming responsibility for deploying a service mesh. Most often, it’s a development team that makes the initial decision. However, as IT operations teams become more aware that service meshes represent a capability that needs to be horizontally made available across multiple applications, it may be only a matter of time before some organizations decide to standardize on a single service mesh to reduce operational overhead, noted Austin.

    Service meshes will also play a critical role in simplifying management of networking and security services at a higher level of abstraction within a larger DevOps workflow.

    It’s still early days as far as service mesh adoption in the enterprise is concerned, but there are already a large number of service mesh options. In fact, there may never be a single dominant service mesh platform. Interoperability standards still need to be ratified that enable organizations that have standardized on different service meshes to apply policies to microservices spanning hybrid cloud computing environments.

    Of course, not every IT organization requires a service mesh yet, either. Many IT teams can still get by using a traditional proxy server or an API gateway until the number of microservices-based applications deployed starts to achieve critical mass. One way or another, however, the more APIs there are to manage, the more inevitable it becomes that an IT team will deploy a service mesh.