Tag: service level objective

  • Chicken Soup for the SLO

    Chicken Soup for the SLO

    Since time immemorial, humans have struggled to communicate. From myth to the modern era, our most memorable stories often involve individuals or groups seeking to be understood in order to avoid conflict. Be it the biblical allegory of Babel to the more recent Star Trek: The Next Generation episode of “Darmok,” a deep fascination with how people communicate seems to have collectively gripped our imaginations.

    It should come as no surprise, then, that communication between disparate teams and roles in the development of distributed software systems is a fascinating topic. There’s an almost primal struggle in the workplace—a dichotomy between “features” and “stability”—that teams have sought to overcome for decades. Indeed, much of the discipline of software engineering has implicitly evolved as a response to the needs of engineers to communicate with other parts of the business.

    How, then, do we improve this communication and build empathy toward our fellow developers, our coworkers, our PMs, our managers? We need a way to communicate with them, to express “how things are going,” how reliable our service or system is. Let’s step back, though, because this is only a small window we’re looking through—we need to communicate these desires and goals to a greater audience; Our bosses, their bosses, our customers, the entire world. Organizations rise and fall on their ability to communicate effectively.

    In the natural sciences, we observe that the tendency of a system is towards entropy; Energy tends to dissipate in the absence of a constraint. So, too, do human systems lose productivity as their scale and complexity increases. The rise in popularity of Agile methodologies and DevOps thinking tracks with this. They are, ultimately, designed to help us communicate better about needs and priorities. Site reliability engineering (SRE) is the latest in this line of disciplinary developments, providing rigor to the question of, “How do I operate very large scale systems in dynamic environments?”

    One of the more popularized elements of the SRE playbook is the concept of the service level objective, or SLO. To excerpt the excellent Implementing Service Level Objectives by Alex Hidalgo, a SLO is “a proper level of reliability targeted by a service,” a calculation of the amount of ‘bad’ events that can occur as part of the normal operation of a service. As Alex notes, the idea of SLOs and SRE have become almost inseparable in our collective consciousness—organizationally, it’s seen as strange to have one without the other.

    Let’s dive a bit deeper into what an SLO actually is. Again, I will excerpt and paraphrase from Alex’s book (it’s very good; you should read it if you’re interested in this topic). A SLO is simply a target, a set of defined criteria that represent some objective that you’re trying to reach. In a very general sense, the SLO expresses the threshold of ‘good’ to ‘bad’ events that you’re willing to tolerate over a time period. This simple ratio, however, unlocks a great deal of interesting and important ways of thinking about performance and reliability. It gives you, and your team, the ability to reason and communicate about reliability in a very quantitative and qualitative way.

    Now, you may be asking yourself what the qualitative component of a SLO is—after all, aren’t these measurements quantitative by definition? It’s in this dichotomy that I believe the true power and utility of SLOs lie; they’re not just a measurement of what you’re doing, they’re a communication vehicle for how you’re doing. Error budgets come out of this line of thinking—they represent the space between the current state of your SLO and its boundary.

    In plainer terms, it’s a measurement of how much you can miss your target before it becomes a problem. If my SLO targets 99% reliability, I have about three and a half days of unreliability a year to play with—or, about 14 and a half minutes a day. This way of measurement is certainly helpful in driving and determining engineering decisions, as it allows us to make snap judgements about how to prioritize the seemingly opposing buckets of “feature work” and “reliability work.” If we’re getting close to burning up our error budget for the month, do more reliability work. If we’ve got slack, do more feature work. Easy, right?

    How to Make Friends and Influence Budgets

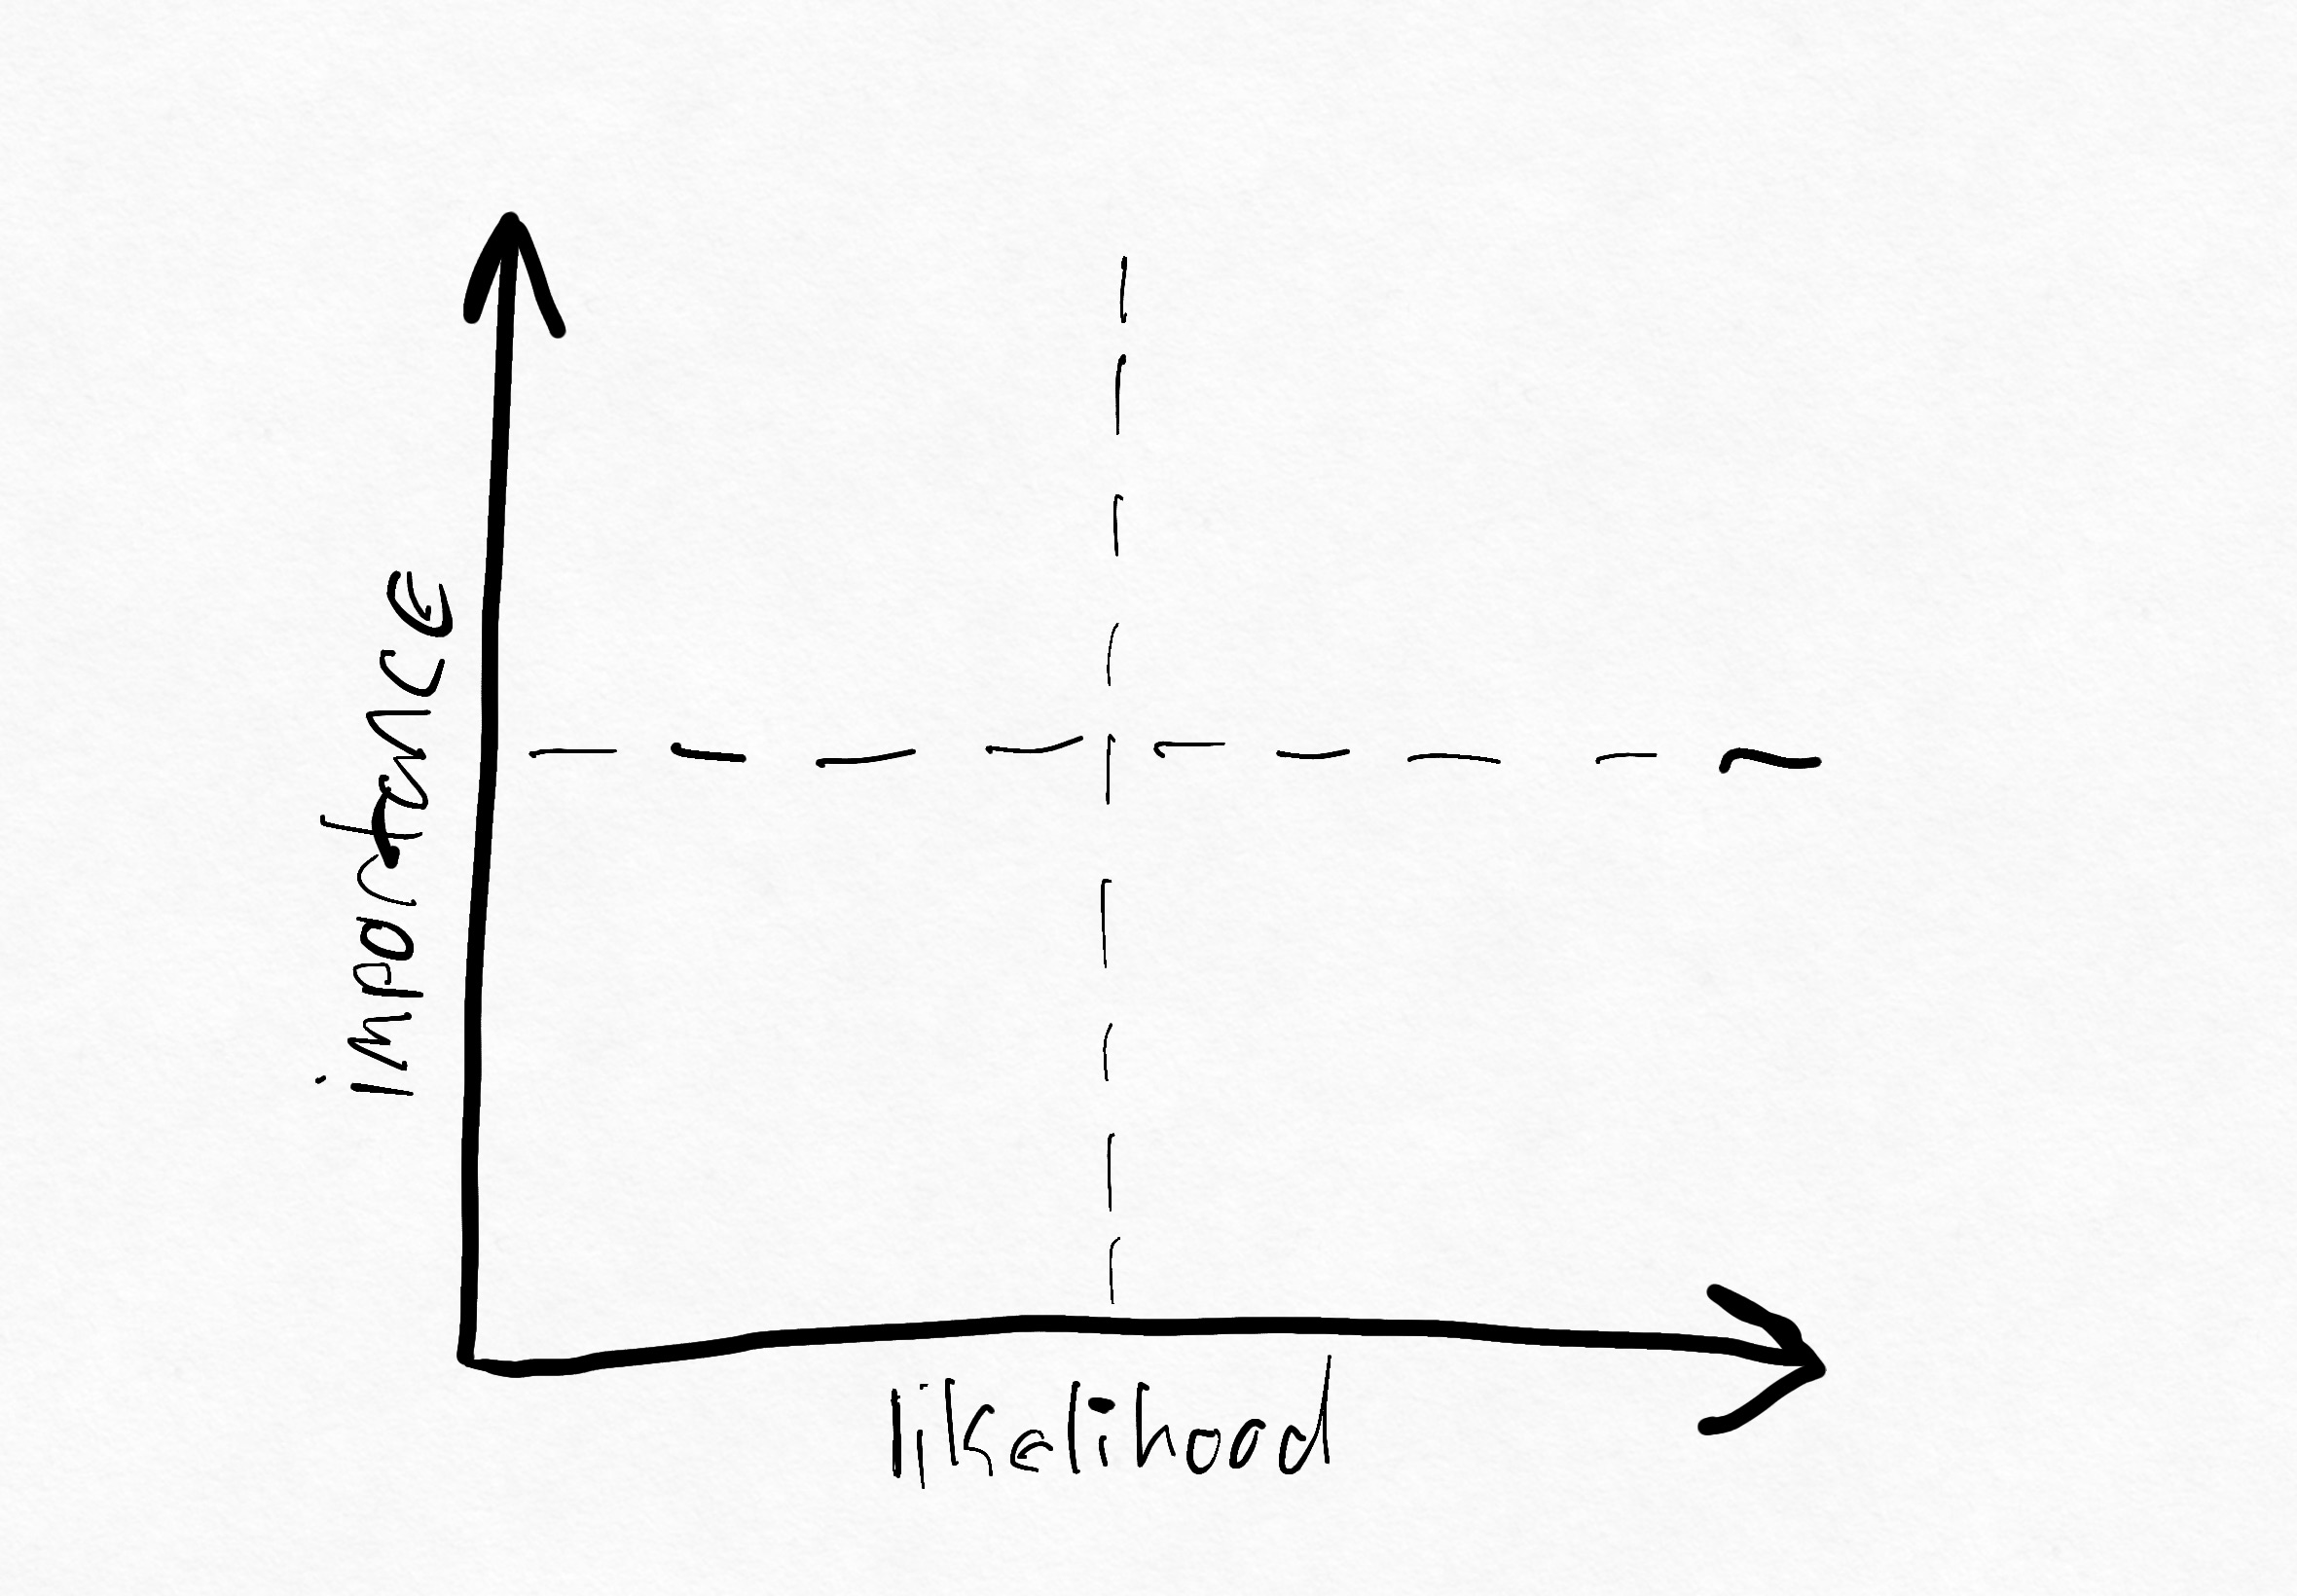
    Reliability, SLOs, error budgets—these are all helpful ways to quantify performance and availability in software. There’s another way to consider them, though, and it’s through the lens of risk. If you’ve earned an MBA, you’re probably familiar with a ‘risk heat map.’
    SLO heatmap

    The x-axis on this quadrant represents the likelihood of a problem occurring; the y-axis represents the importance of that element. This is generally extensible to any element of a business—everything from your sales force to your customer success team to the availability of your data center or cloud resources.

    In many ways, this simple quadrant is responsible for many of the decisions that influence your work. While a business does many things, the business of operating a business can be thought of as an ongoing and unceasing process of risk management and abatement.

    The stuffy, MBA-fueled world of Six Sigma and process management doesn’t play terribly well in the more creative arenas of software development and maintenance, I’ve found. Much of this has to do with—you guessed it—risk. In manufacturing, the costs of failure or defects can be extremely high. Component defects can sideline million or billion dollar supply chains; projection and planning failures can disrupt just-in-time inventory and a single stuck ship or sudden winter storm can cause months or years of disruption to national or global economies. We should count ourselves fortunate that the actual costs of failure in a software system are so light; while us-east-1 going down for an hour would be bad, it probably wouldn’t wreck the global GDP for six months.

    The translation of ‘lower-level’ concerns, such as software system reliability or employee turnover, into ‘higher-level’ risk concerns acts as a curtain between the operational and the managerial aspects of a company. It is this curtain that we must consider when thinking about the true advantages, and the revolutionary potential, of SLOs. Remember, a SLO represents a ratio between ‘good’ and ‘bad’ and gives us a threshold value. These SLOs can be overlaid onto our risk maps extremely easily; SLOs for more critical services and processes rise to the top, newer services move to the right.

    In essence, we can give our SLOs a qualitative score with regard to overall business risk, and use this to shape the overall business direction. This is crucial, as in the absence of better qualitative measurements, businesses will often grasp at quantitative reliability measurements—“pages fired or tickets opened,” to quote Hidalgo. He continued, “[T]hese are prone to be inaccurate due to false positives or the whims of the people opening the tickets.” The types of measurements that we often rely on, such as categorization by severity or ‘mean time to x’ fail to accurately classify reliability or how it impacts the user experience.

    Let’s illustrate by example—a huge part of conversations about SLOs is talking about how they should be framed in terms of users; happier end users, happier engineers, happier managers and so forth. SLOs that correspond to user journeys—for instance, “Adding an item to the cart succeeds 99% of the time.”—are straightforward to understand from the perspective of an end user. We can discuss this in terms of risk by applying an importance and likelihood score to the SLO itself. If our site is an e-commerce platform, then the importance of the cart is very high. Since our threshold is very small (1%), then the likelihood of this risk is also very high—we don’t have a lot of wiggle room!

    A SLO for a targeted ad service might read, “A contextually appropriate display ad is served within 30ms 90% of the time.” In this case, our ad business might not be of high importance in terms of our business risk, so we should reduce the importance of the SLO. In addition, our threshold is very large, so we should reduce the likelihood of violation (since we have a lot more wiggle room). Over time, these positions and scores can (and should) change—perhaps the advertising segment of our business becomes more valuable, so we re-prioritize it on our risk maps.

    By speaking this language and quantifying our data in different ways, we can pull back the curtain between operational and managerial sectors and use it to influence things outside our immediate sphere.

    “Mommy, why is there a SLO in the house?”

    There’s an aphorism about war and fighting that goes, “Generals are always prepared to fight the last war.” I’ve seen this myself at every company I’ve worked for over the years—we tend to be reactive, rather than proactive, in planning and preparing for strategic business challenges. Some of this is due to the fact that none of us are oracles capable of divining the future, but much of it simply has to do with the aforementioned cycle of risk management that drives business planning and decision making. When introducing SLOs to a wider audience, you need to be able to plan for the pushback that executives and managers will almost certainly have to this new way of thinking.

    When you think about it, though, there’s not a lot of difference between what an SLO is trying to represent, and what an OKR or KPI or any other goal-oriented system is trying to represent. In each case, we’re creating some heuristic to sort events into ‘good’ and ‘bad’ cases, then creating a threshold of ‘Now there is a problem’ based on the ratio between them. In essence, this is, really, how you measure anything as a percentage.

    You could translate goals for your sales, marketing, customer success or people ops teams into SLOs. For example, “30% of POCs should convert into closed-won opportunities” is, basically, an SLO already, and is perhaps an existing goal for your salesforce. There are two big advantages to thinking about these as SLOs: consistent reporting and error budgets.

    Consistently reporting on SLOs means that you can express team and company goals in the same format and language across the entire organization. This brings teams together in a shared purpose, and allows for a shared language about how reliability benefits everyone. Being able to roll up reporting about how things are going not only encourages more shared ownership of goals, it helps you build connections and linkage between how different types of work align with each other towards a shared prosperity. More importantly, SLO reporting gives extremely clear signals about how teams—regardless of their function—should be addressing failure.

    If a consistent language around reliability is what builds empathy, error budgets are what unlocks creativity and problem solving for addressing issues in the business. In too many cases, organizations are loathe to give individual contributors, or even teams, the flexibility to experiment and measure the results of those experiments due to inertia, top-down command-and-control style processes or just the fear of screwing up.

    Let me give you an example—suppose your marketing team has a demo that generates a certain percentage of leads every month. Without a defined SLO for this demo’s performance, it becomes extremely difficult to change anything about how this demo works. Why? Because there’s a tendency for things to settle at their current state—we’re all so consumed with moment-to-moment crises or new work that evaluating the performance of existing things can be challenging.

    The work required to justify a change eventually outweighs the actual work being done to make the change, and so change withers on the vine and processes stagnate. Now, imagine that this demo flow had an SLO associated with it, something like “10% of clicks to our demo should result in a valid email capture.” Suddenly, we can report on this in a consistent fashion and, more importantly, we have a massive amount of headroom for experimentation. We can justify work being done to improve this flow in the context of not only its current status (are we running better or worse than our target?) but also in the context of our other goals (are we producing enough MQLs, in general, to support the sales funnel?) and prioritize appropriately.

    Ultimately, we can’t change the fact that there’s a bias towards dealing with the last thing that happened, but that’s not really the point. What we can change is how we think about expressing what’s happening now, and building a consistent language and verbiage around addressing these problems. SLOs are designed, broadly, as a way to communicate the reliability goals of complex distributed software systems. What is a business of people other than a complex distributed human system?

    As thinking, tooling, and processes around SLOs continue to mature (such as the recently announced OpenSLO specification), I’m excited to see what the future has in store for us. At the end of the day, we should be striving to reduce hierarchy, increase autonimity, and build collective ownership in the socio-technical systems that we rely on as human beings; SLOs are just another piece of this ever-evolving puzzle.
  • How IT Ops Can Exceed Service Level Objectives in Digital Transformations

    How IT Ops Can Exceed Service Level Objectives in Digital Transformations

    The pace of change can be managed successfully by defining service level objectives and more in dev environments

    Mobile applications, data lakes, microservices, data visualizations, SaaS integrations, automations, IoT data streams, machine learning models—in proof of concepts, pilots and scaling production environments, for customer-facing capabilities and employee workflows—all of these technical capabilities are developed, deployed and enhanced faster today more than ever before.

    I spoke to Jason Walker, field CTO at AIOps platform BigPanda, about how the speed of deployment, the breadth of technology services transforming businesses are developing, the greater security threats, and the increase in reliability and performance requirements impact IT Ops.

    Walker believes that of all the things we’re trying to do in IT—more, faster, smarter, safer, innovative, secure, reliable—it’s the speed that’s the driving force. “The most significant impact is velocity; the dev-test-deploy cycle time is drastically reduced,” he said. “Without the right guardrails, that breeds unnecessary complexity and a gradual loss of operational awareness.”

    He explained that much of the barriers that once slowed down development teams are addressable today when developing service-based architectures on the cloud. “Developers realize that the traditional constraints, either technical dependencies or organizational capability, are much reduced,” Walker noted. “Developing in the cloud for a cloud-based service, leveraging an ecosystem of microservices for inputs, an agile team can move very quickly.”

    Why IT Ops Can’t Slow Down Transformations

    IT Ops can’t easily say “no” or “slow down” to business stakeholders investing in digital transformation to improve customer experiences and gain competitive advantages with data, analytics and machine learning. Some IT leaders attempted that command-and-control approach during the early days of public clouds, but today, DevOps practices, SRE responsibilities and AIOps capabilities are integral to mainstream IT Ops teams in keeping up with transformational velocities.

    So instead of saying “no,” progressive IT Ops teams say “yes, but” by defining service level objectives, (SLOs), capturing service level indicators (SLIs) and managing to error budgets.

    Walker agreed. “SLIs, SLOs and error budgets are a very useful way to manage the critical inputs and outputs at the interfaces between microservices and at a high level across the business service, allowing developers to keep changing the ‘interior’ pieces.“

    These tools change the operating model and mindset across the entire IT organization by exposing trade-offs to business stakeholders. For example, if a web application has a 99.9% SLO, the whole IT team has a 0.1% error budget. If the SLO is missed, a service level policy identifies areas of investment to improve performance, reliability, security and automation or to address technical debt.

    What IT Teams Should Do to Implement Service Level Objectives

    Defining service level objectives helps bring business stakeholders, development teams, SREs and IT Ops together and align on reliability objectives and trade-offs. It’s an important step, but not sufficient for teams that want to exceed service levels during digital transformation.

    Walker offered several technical recommendations for IT Ops groups transitioning to service level objectives:

    1. Where there are dependencies between microservices and interfaces, frequent check-ins between adjacent teams are required.
    2. APIs, inputs and outputs, need to remain consistent over time and changes communicated and receipt confirmed.
    3. Knowledge management processes delivering accurate, up-to-date documentation have to be baked into the SDLC to prevent the generally small, modular teams from sprawling away from each other and developing incompatibilities.
    4. Consolidated change awareness for operations is also a must-have. Whether changes are human or automated, they have to be tracked and relatable to service events and alerts.
    5. The later phases of the SDLC, when cloud-native, containerized microservices are running and supporting customers, have to be monitored. A monitoring strategy is necessary to ensure effectiveness and minimize the work and noise involved.
    6. Synthetics and client telemetry can be very useful macro-indicators of overall service performance. As with all monitoring efforts, actionability is key. Signal-to-noise in monitoring has to be measured.

    These are balanced recommendations, with the first two focused on how development teams engineer microservices and the last two on how IT Ops teams use monitoring and AIOps to implement actionable SLIs. The middle two recommendations on knowledge and change management processes help the entire organization stay in sync through a fast-paced operating environment.

    “The velocity, flexibility and variability of this type of development means leaders at all levels need to understand and align the strategic and tactical goals, and to prevent their teams from drifting away from business goals,” Walker said.

    Why AIOps is a Force Multiplier for IT Transformation

    So, the business leaders align on service level objectives, development teams engineer observable containerized microservices, IT Ops executes a monitoring strategy and the CIO ensures communication, collaboration and knowledge sharing. Is that all that’s required?

    The issue is that most IT Ops teams are understaffed and get overwhelmed supporting the new cloud-native microservices, legacy systems and everything in between. To address the gap, IT leaders are investing in AIOps, and even hundred-year-old enterprises are successful at adopting machine learning and automation to accelerate IT Ops.

    Automation and machine learning event correlation applied to monitors, alerts and observable artifacts are the force multipliers. Open-box machine learning enables IT Ops to triage incidents and improve their mean time to resolution, while automation reduces manual efforts and keeps teams in sync. Organizations that are modernizing applications and supporting hybrid clouds require these capabilities to manage the complexities, run at business speed and manage databases, microservices and applications to higher service level objectives.

    As Walker noted, increasing velocity is important for responding to customer opportunities and changing conditions. Driving faster digital transformations is more achievable today when IT Ops leverages automation and AIOps to stabilize speed with reliability and performance.

  • Ten Years Later — What Is Cloud Native?

    Ten Years Later — What Is Cloud Native?

    Ever since the term cloud native made its debut in 2010, its usage has grown in popularity. Today cloud native is used as a qualifier for innovative, leading edge applications, platforms and systems or cloud-savvy organizations and processes.

    However, what is cloud native exactly? There are some definitions, there are many opinions, but first and foremost there is a lot of confusion: Is my system already cloud native if I follow a microservice-based architecture? Is my system already cloud native if I run containers? Do I have to change development and operations?

    In this post, we cut through any uncertainty and ambiguity and provide an accurate and concise definition of cloud native systems.

    However, first, we have to discuss a set of prerequisite concepts.

    Application + Platform = System

    Frequently, in our day to day conversations, we use the terms application, platform and system interchangeably. Yet in this blog post, we draw a strict distinction:


    • Application: An application is the set of components that are designed and implemented for a specific use case.


    • Platform: A platform is the set of components that are designed and implemented independently of a specific use case.


    • System: A system is the combination of an application and a platform. Generally, we refer to an application as being hosted on a platform.


    End users do not interact with applications or with platforms only; end users interact with systems. Consequently, we will focus our discussion on system-level properties, not application—or platform-level properties.

    Application + Cloud Platform = Cloud System

    A cloud platform is a service provider that enables a service consumer to request and release resources on demand via an Application Programming Interface (API).

    According to this definition, a cloud platform is any service provider that enables a service consumer to request and release resources on demand:


    • Public Cloud Platform: A public cloud platform is a service provider that offers resources outside of its own organization.


    • Private Cloud Platform: A private cloud platform is a service provider that offers resources within its own organization.


    Consequently, a cloud system is any application that is hosted on a cloud platform. However, what is a cloud native system? 

    Responsiveness, Scalability and Reliability

    The distinction of cloud native systems versus non-cloud native systems is drawn along the lines of responsiveness, scalability and reliability. 

    In a nutshell, responsiveness is a system’s ability to meet the users’ expectations. In order to quantify responsiveness, we rely on a set of four related concepts: 

    • Service Level Indicator: A service level indicator is a quantitative observation about the behavior of a system.
    • Service Level Objective: A service level objective is a predicate (a function that yields true or false) on a service level indicator that determines whether the behavior of a system meets an objective.
    • Error Rate: The error rate is the ratio of the number of observations that do not meet their objectives to the number of observations in total for a fixed time interval.
    • Error Budget: The error budget is an upper limit on the error rate.

    Based on the above, we can now define responsiveness of a system as the ability of the system to keep its error rate below its error budget.

    These concepts are best explained with a tangible example: Consider a web application processing HTTP transactions, that is, accepting HTTP requests and returning HTTP responses.

    Service Level Indicators

    Here, we define two SLIs.


    • SLI Latency: determines the latency of a transaction, that is, the time when the request enters the system to the time the response leaves the system. 


    • SLI Result: determines the result of a transaction, that is, the status code of the response.


    SLIs are recorded at the edge of a system, here the Ingress component, to exclude any variation that is outside our control and focus on the performance of the system that is within our control. For example, we do not want to include any variation in observed latency or observed results originating in the users’ network connections. However, we do want to focus on the performance of the system once Ingress accepts the request until Ingress returns the response.

    Next, we define two SLOs.


    • SLO Latency: For this example, we define the SLO Latency to be met if a transaction’s SLI Latency is less than 250 milliseconds.


    • SLO Result: For this example, we define the SLO Result to be met if a transaction’s SLI Result is not in the HTTP 500 range.


    Finally, we set the value of the error rate’s time interval to a 30-day sliding window and the value of the error budget’s to 1%.

    By definition, this system is responsive if the ratio of the number transactions over the last 30 days that do not meet their SLOs to the number of transactions over the last 30 days in total does not exceed 1%.

    Scalability and Reliability

    At this point we have the necessary tools to define scalability and reliability:

    • Scalability is responsiveness in the presence of load.
    • Reliability is responsiveness in the presence of failure.

    So Finally, What Is Cloud Native?

    With the definition of cloud systems and the definition of responsiveness in place, we can now define cloud native systems: A cloud native system is a cloud system that is scalable and reliable by construction.

    The operator “by construction” is in stark contrast to “by requirement”: The design and implementation of a cloud native application guarantees scalability and reliability within the limits set by the service level objectives and error budgets.

    According to this definition a cloud native application must be able to:

    • Autonomously detect and mitigate the presence of load.
    • Autonomously detect and mitigate the presence of failure.

    Discussion

    This post defined the term “cloud native” as a property of a system, not as a property of organizations or processes.

    The defining criteria of a cloud native system are scalability and reliability by construction. Here, the employment of microservices (an architectural choice) or containers (a technological choice) is not a defining criteria of cloud native systems. If you want to know more, head over to—or better yet, get involved with—the Cloud Native Computing Foundation, a Linux Foundation project founded in 2015 with the mission to build a sustainable ecosystem for cloud native systems.

    — Dominik Tornow