Tag: security

  • DevOps Chat: Mark Nunnikhoven, Trend Micro on Hybrid Cloud

    DevOps Chat: Mark Nunnikhoven, Trend Micro on Hybrid Cloud

    devopsy.kinsta.cloud sits down with Mark Nunnikhoven, VP Cloud Research at Trend Micro. We discuss hybrid cloud, hybrid cloud security, DevSecOps and more. Mark is very involved in research on the latest threats and trends in cloud security. This is a great interview that I think you will find very interesting.

    As usual, the transcript of our conversation follows:

    Alan Shimel: Hi, this is Alan Shimel, devopsy.kinsta.cloud, here for another DevOps chat, and I’m joined today by Mark Nunnikhoven of Trend Micro. Mark, welcome to DevOps Chat.

    Nunnikhoven: Thanks for having me, Alan.

    Shimel:  I hope I didn’t mangle your name too bad, did I?

    Nunnikhoven: No, it was perfect. It’s a tricky one. It looks really menacing, but ends up being relatively simple after you’ve heard it a few hundred times, so –

    Shimel: Absolutely, very good. So, Mark, I asked you to join us today—I think we had done a webinar and talked a bit offline about, you know, some of the challenges around securing hybrid cloud and, you know, versus obviously people moving stuff to the cloud, people still have stuff in their data center, and what’s good for one may not necessarily be good for the other, but what’s good for both might be an entirely different thing. And I wanted to just spend a little bit of time with you talking about the challenges of securing the hybrid cloud.

    Nunnikhoven: Yeah, it’s definitely an interesting topic that I don’t think gets enough attention, so I’m glad we can have this chat.

    Shimel: Yep. Before we jump into it, though, Mark, I’d be remiss if I didn’t give you a chance to just let people know, I did mention you’re with Trend Micro, but what is your role there?

    Nunnikhoven: Yeah, I’m the vice president in charge of cloud research. So I look at how organizations are tackling security in the cloud, in hybrid environments for, you know, traditional servers and workloads, containers, serverless, sort of anything that’s breaking new ground. It’s a lot of fun and there’s a lot of really interesting stuff happening.

    Shimel: Great. So, Mark, you know, I think I started us off by saying there’s people who are making solutions for the cloud, there’s people making solutions for the data center, the ARM RAM. And what’s good for one is not necessarily good for the other, and then, of course, most of the world is living in some sort of hybrid environment.

    Nunnikhoven: Yeah.

    Shimel: What do we do?

    Nunnikhoven: [Laughs] That’s a great question, ’cause, you know, I’ve seen—working with organizations around the world, I’ve seen sort of all of the possible scenarios, I think at least the major ones that people kind of come to thinking might work, and they sort of range from we’re going to force data center processes and controls into the cloud, which is a recipe for disaster. You know, they’re very different environments, to the opposite, of we’re gonna take everything that’s working in the cloud and we’re gonna force it on the data center, to, you know, we’re gonna run two completely different environments in completely different ways, and essentially double the workload. None of those is really satisfactory. Sort of the best route forward tends to be looking at what’s working in the cloud and trying to push a lot of those concepts into the data center. But you still need to make adjustments for the reality that the data center is very, you know, sort of slow and very high level of rigor and very formulaic, and, you know, very well-established. So you do need to make adjustments, but, you know, the goal is to get one way of doing things with allowances for the difference in both environments.

    Shimel: Yep. And Mark, as you said, that may be the goal, but, you know, from day one, you obviously—you need a plan to get there. And can you maybe share with our audience a little bit, where do you see the logical steps, if you will, to getting there?

    Nunnikhoven: Yeah, and I think that’s a really good way to phrase it, you know, because we can all—we all love the architecture Powerpoints and you go the events and you get real excited about what the eventual design and implementation will look like. But getting there can be really ugly and really messy. I think the biggest thing, and it’s unfortunately the thing that people tend to forget about, is looking at not just the security, but the operations processes and controls that you’re using today, and why you’re using them. And I think that’s the big piece that people miss, is, you know, why am I using something like an intrusion prevention system, or why am I using anti-malware or why do I have this change review board for any sort of operational change I want to make. And once you start to dig into the why you do these things, you realize that the implementation can change, as long as you’re still meeting that why.

    So, you know, we put intrusion prevention in place so that we make sure that any time we open up traffic to this server, that we verified it is actually secure web traffic like we’re expecting. Once you know that’s the reason, then you can look and say in my data center, that makes sense to have a big perimeter appliance doing that job, whereas in the cloud, it makes more sense to have something running on the host, doing that same job. So you’re still getting the same answer to why. It’s just the how is different in each environment. So it’s—you’ve got to dig into those, and it starts to clarify what you’re doing.

    Shimel: Got it. Mark, what are we seeing—I mean, what—obviously at Trend, you’re probably talking with a lot of customers. Are they coming from the cloud down with their solution? In other words, buying a cloud solution and building—or from the data center up, if you will?

    Nunnikhoven: A lot of the time we’re seeing the data center up, simply because it’ll be one team within a larger organization. So we’re talking mainly, you know, traditional enterprise and large governments. And it’ll be one team that’s gone and said we’re gonna push everything and build it new in the cloud, and when they start to kick off that process, they start to get a lot of existing policy and existing culture enforced on them. So they’ll get, you know, specifically the security. They’ll get people saying, well, you need this, you need to make sure that, you know, you go across these boundaries in your design, you’re networking a certain way. So they start to try to take those same designs, which are great in the data center, but horrible in the cloud, and they try to push those into the cloud, and they usually end up failing. And then about six months afterwards realize that they need to take a new approach, because it is a completely different environment.

    Shimel: Got it. And, you know what, Mark, I’m a firm believer that at least for the foreseeable future, five, 10 years, hybrid cloud is the—is the dominant, right, the dominant usage pattern that we’ll see from people. Is this yours as well?

    Nunnikhoven: Yeah, 100 percent. And for me, it’s simple economics. As much as you want to be in the cloud, if that’s the case, if bought in even, you know, you’ll see it at the major events from the big cloud providers. They’ll pull up big enterprises who are—their CEO or the CIO is, you know, yelling from the top of their lungs that they’re gonna be all in on the cloud. Even in those scenarios, they’re still going to take 12 to 18 months to move out of their data centers.

    But the reality is most enterprises have already made a multimillion dollar investment in technology that’s working. It might not be working as fast as they want, but you can’t walk away from that. The cost savings in the cloud, if they’re there, are not that significant that you’re gonna leave millions on the table. So the reality is, you know, for a standard data center life cycle, so like you said, a five to seven year term, you’re gonna be dealing with two environments. And it’s not just that it’s two environments, it’s two environments that are completely different. It’s very much apples and oranges. So you do need a different approach.

    Shimel: Got it. And, Mark, I don’t want to put you on the spot, but what Trend Micro specifically, what kind of solutions are you guys, you know, working with customers on?

    Nunnikhoven: Yeah, so one of our big push, and we’ll just hit it real brief, because we don’t want it to be a sales pitch at all, it’s just we have a platform called Deep Security, and we built it with the principle of trying to put security as close to the data and application as possible. And because of that, we’ve been able to adapt it for multiple cloud use, for data center use, for the hybrid scenario quite well, because we’ve taken a lot of the principles that work in the cloud and made it so that you can leverage them where it makes sense in the data center. So a lot of automation, a lot of programmability, and a lot of intelligence in the products so you don’t have to worry about the nitty-gritty of dealing with security day to day, unless it’s really urgent and requires you to intervene.

    Shimel: Excellent. And, I mean, Trend is obviously not the only one doing this, Mark. When we talk about cloud too, I wanted to ask you this, public versus private clouds, where are you seeing this kind of—you know, are we—you know, to me, a private cloud is—goes hand in hand with hybrid, right? But there are people who are doing public cloud and data center, and that’s hybrid as well.

    Nunnikhoven: Yeah, and I find for me, you know, private was a real big push back from a lot of the incumbent data center vendors, and, you know, we’ve kind of gotten out of that hype phase and into the reality of it. And I tend to see what a private cloud is, is somebody who’s taken the data center and adapted a lot of the cloud processes and the ideas behind a public cloud and implemented them within their data center, which can be a really good thing. So you can get on-demand resources, so you just query in API instead of sending out a ticket and getting a bunch of people to do work. You know, getting that accountability, getting that accessibility and that visibility that we’re used to in the public cloud, getting that in the data center.

    So I think the ideal hybrid scenario is leveraging private cloud/public cloud. A lot of people aren’t there with their data center, because implementing change takes a long time. There’s a lot of cultural change, a lot of tooling change. So you’ll see them with sort of more the traditional data center approach. But if they want to be successful over the next few years, they need to start pushing more of those private cloud ideas internally, because that will help them have one set of processes and tools across both the public and the private cloud.

    Shimel: Makes sense, makes sense. And Mark, what about people, though, who just say, you know what, I’m—I’m biting the bullet, I’m just gonna do cloud, you know, or I’m just gonna do data center. You know, first of all, nothing is forever, obviously, right? You could say that today, but things change. Is the Trend Micro solution, specifically, let’s say, is it one that will work with one, but that scales to the other? Or, in other words, how do we stay out of dead ends?

    Nunnikhoven: Yeah, and specifically from us, this is something we’ve been dealing with with our customers over the last few years, because we’ve got customers who are 99 percent in the cloud and 1 percent in a data center somewhere, and the exact opposite. And it really—you know, every culture and enterprise is unique in what their blend and their mix of those environments is. So having the tool be agnostic to that is really important. So, you know, we’ll scale from protecting one system, to protecting 100,000 systems, with the same platform, very, very easily.

    And I think there are a lot of projects out there, you know, not just commercial offerings from Trend Micro, but we’re seeing this a lot in the operational monitoring space. So, you know, things like Ryman or Logstaff, which are two great open source projects to help you correlate data, they work equally well in the cloud as they do in the data center, and I think that’s really a big win for people, is that you need to put the assets in the environment that makes the most sense, but you should be able to use modern tools in both. And that’s a real big, important point for people to take away, is that you want to be—even if you’re in a traditional sort of slowing evolving data center environment, you want to be making sure that you’re leveraging some of the great advances we’ve made in security and in operational tools.

    Shimel: Excellent, excellent. Mark, we’re coming near the end of our time, as this always seems to go quick. But let’s talk a little bit about the research that you’ve been doing, and just give our audience maybe a little insight. What are you kind of researching now? What do you find really interesting?

    Nunnikhoven: Yeah, the biggest area I’m focusing on right now is the rise of what’s been deemed the serverless architecture. So obviously sort of a poor choice of names. There are servers somewhere. But it’s the idea of leveraging a function as a service as something like Microsoft du jour functions or AWS Lambda, where you’ve just got code that you input that runs in a sandbox on someone else’s system and you don’t have to worry about any of that. So scaling and operational tasks are kind of out the door, but these are heavily leveraging SaaS services and you’re sort of picking the best aspects of multiple providers, and stitching it together into one big application. And there’s a lot of really interesting advantages for the business there, because you’re focusing purely on delivering value to your users.

    But from a security perspective, now you’ve got multiple parties and systems that you have to trust, that have to work together, that have to share security controls, and then that is normally only one application in a suite of others. So you’ve got serverless applications, you’ve got applications that are running on containers, and then traditional applications. So I’ve been looking at not just the serverless, but how you do you address all of these in a consistent manner, so that you can apply security to the data where it’s being processed.

    Shimel: Excellent. Mark, we are butting up against time here, but one last question, and it’s one I frequently ask our guests here on DevOps Chat. If you had to recommend one book to our audience to read, not necessarily the last book you read or anything like that, but one book they should read, what’s your recommendation?

    Nunnikhoven: Yeah, that’s always a tough question. I love reading, so I’m always reading three or four books at a time. And, you know, it’s a safe assumption that this audience has already read “The Phoenix Project.” If they haven’t, they should. My latest favorite in this space is called “The Art of Monitoring.” It’s by James Turnbull, and it’s a look at how to implement metrics and measurements around running applications, regardless of where they are. So it talks about logging, it talks about real-time alerting, and it’s a really great approach, in that, you know, it’s always looking at results. So not just collecting data for data’s sake, but it sort of walks you through how all of this stuff should roll up to give your teams some actionable insight on how your application is doing. It’s a really great book.

    Shimel: Got it, interesting. Well, Mark, thank you so much for being this episode’s guest, of DevOps Chat. We’d like to maybe have you back on sometime and talk to us about more of the research you’re doing. Continued success to you and Trend Micro, and just thanks again. This is Alan Shimel, for DevOps Chat, and thanks for joining us. Until next time.
  • 3 Simple Steps to Rugged DevOps 101

    3 Simple Steps to Rugged DevOps 101

    As the CEO of WhiteSource, I regularly consult enterprises about building and enforcing their open-source security policies.

    In the course of my consultations, I discuss open-source security protocol with many software companies and enterprises, and I’m often baffled by the fact that many organization aren’t boosting their software development performance and speed by bringing their development and operations teams together via DevOps. In fact, only 25 percent of enterprises are currently doing DevOps. I mean, if you were a CTO and someone said you could make your software development 200 times faster and reduce unplanned work/rework by 22 percent, wouldn’t you jump at the chance?

    Now, I know DevOps still is not being implemented even though it has proven to improve deployment rates, so I shouldn’t be surprised that security isn’t joining the DevOps party. But I am. Just imagine the benefits of giving security the DevOps treatment. There’d be no more (or, at least, significantly fewer) last-minute security issues, no more unrealistic security policies, and engineers, IT and security professionals who actually understand each other and improve their own processes to work better together. This is the essence of rugged DevOps.

    Implementing rugged DevOps is a huge decision for any enterprise, and it requires a lot of planning and time to implement. However, you don’t need to completely remodel your organization to start enjoying some of what rugged DevOps has to offer.

    So, what can you start doing today?

    Shift Left Your Security

    DevOps is all about shifting left security to find security issues as early in the software development life cycle (SDLC) as possible. The earlier you find an issue, the cheaper and easier it is to fix.

    So, how can you shift left your security? Start by integrating security tools into your continuous integration (CI) process to find vulnerabilities as soon as they’re added to your build and sometimes even your repositories. Tools exist that can integrate with your build tools and identify potential issues in your build.

    Also available is a browser plug-in that allows developers to detect security vulnerabilities while they are searching for open-source components online. This tool helps developers say no to vulnerable components long before downloading or integrating them with their code.

    Shifting left security is the hardest part of any enterprise’s rugged DevOps journey. Yet by taking some small steps, you can start to enjoy the benefits of DevOps with a twist of security.

    Adopting a Micro Approach to Security

    Just as operations has adopted a DevOps mindset to understand and become involved in development, it’s now security’s turn.

    Security needs to stop being on the outside of development, looking to control it through detailed security policies. Instead, it needs to take an active part in it, steering it toward security. Security can do this by focusing on understanding development and deployment processes, and searching for possible quick wins.

    From my own experience, every time a security team takes the time to understand the peer code review process, small changes are made with significant contribution to code security.

    I also often notice that security teams are unaware that some developers may still use the old “copy and paste” method in using open-source components. This makes it impossible to track known open-source vulnerabilities. Once security teams understand this, they can improve guidelines to ensure they are not blindsided.

    The good news is you don’t have to overhaul your whole organization to give security a micro-makeover. Your security team simply needs to start getting into the finer details rather than planning long-term security programs and road maps.

    Speaking the Same Language

    A good sign that an enterprise is doing DevOps is when developers and operations call software issues by the same name. This means the two teams have defined their issues and objectives together, and are working toward joint goals. The same is 100 percent true for rugged DevOps.

    If development sees a problem in terms of unplanned work, operations sees a glitch and security sees a vulnerability, collaboration will be very difficult. Introducing a shared vocabulary for issues throughout software development is an effective way to get your professionals on the same page.

    With this shared vocabulary, development and security can sit together and define shared key performance indicators (KPIs). For example, development’s goal of faster deployments can be linked with security’s aim of reducing mean time to release (MTTR). Once each team knows what the other wants to achieve, they can understand how to help each other.

    At the end of the day, security is more likely to be taken seriously if it is understood. And this is key. With the typical enterprise ratio of 100:10:1 development, operations and security professionals, security needs all the friends it can get.

    Ready to Try Rugged DevOps on for Size?

    As you can see, you don’t need to turn your enterprise upside down or even have a rugged DevOps team to start getting some of its benefits. Just follow these three steps, and your enterprise can get a taste of what rugged DevOps has to offer.

    So what about you? Are you ready to take rugged DevOps for a test drive?

    About the Author / Rami Sass

    Rami SassRami Sass is an experienced entrepreneur with deep background in R&D and product management. At Eurekify. and later CA, became an expert in designing and implementing complex security management and compliance software systems, and in delivering them to the market. Currently he is co-founder and CEO of WhiteSource.

  • Simplify and Streamline Hybrid Cloud with DevOps

    Simplify and Streamline Hybrid Cloud with DevOps

    The cloud is not new. The virtues of the cloud have been proclaimed incessantly for years, and most businesses have embraced cloud servers and services on some level. The realities of data security and the need to leverage existing investments in IT infrastructure, however, generally result in some sort of hybrid cloud setup, with servers and applications that span both local data centers and cloud providers. Hybrid cloud deployments can be complex and volatile, which is where DevOps comes in.

    I wrote a report recently for devopsy.kinsta.cloud that takes a closer look at the pros and cons of hybrid cloud, and the symbiotic relationship with DevOps. “DevOps Enabling the Hybrid Cloud” examines how DevOps tools and practices streamline management of such an environment. It also looks at some of the security implications and how DevOps can address those concerns.

    The report explains, “Speed and flexibility are imperative for organizations that want to remain competitive. Organizations that strive to lead understand that IT must be viewed as a strategic advantage—a powerful tool for driving innovation and creativity. The hybrid cloud provides a bridge from legacy hardware and assets to cutting-edge concepts such as containers and serverless computing for organizations that do it right.”

    One truism addressed in the paper is that customers—whether they’re external customers of your company or the users within the company that rely on IT services and applications—don’t know or care where your applications or data are delivered from. They know that they want stuff to just work when they need it to work. It’s up to IT to determine the most efficient and effective way to achieve that goal, and to provide a seamless, frustration-free experience. Sometimes that means relying on cloud servers and services, and sometimes it means using local infrastructure.

    I spoke with Justin Foster from Trend Micro about the overlap of hybrid cloud and DevOps, and specifically about unique security issues with hybrid cloud environments. He stressed that legacy tools and traditional approaches to security are not sufficient for the more dynamic hybrid cloud environment. As explained in the report, “Security has to be baked in from the beginning and throughout the development life cycle.”

    A pure cloud infrastructure is unlikely for any established company. It may be achieved eventually through attrition, but there’s no getting around the fact that there already are servers and applications in place. The hybrid cloud approach is the right solution in most cases, and DevOps tools and practices are essential to help manage and secure the hybrid cloud effectively.

    Click here to download the report: “DevOps Enabling the Hybrid Cloud.”

  • Why Your Organization Needs DevOps

    Why Your Organization Needs DevOps

    The recently released fifth annual “State of DevOps Report” by Puppet has once again brought with it fresh insights into what drives high-performance teams. The report, which comes at a time when DevOps has ceased to be a buzzword, provides proof of why more and more businesses across the world are adopting DevOps to improve their organization’s performance, revenues and profitability. DevOps has truly come of age and this year’s “State of DevOps Report” clears any doubts fence-sitters may have about the effectiveness of the DevOps approach.

    The 2016 report reasserts that unparalleled IT and organizational performance is a result of a team effort spanning development and operations. The report also highlights the importance of improving the entire product life cycle—from initial product planning, to quality and security assurance, to customer feedback—to speed up delivery while improving quality, security and business outcomes. You can read the full report here.

    In today’s competitive business environment, DevOps has emerged as a vital solution that helps organizations meet ever-growing industry demands. The “2016 State of DevOps Report” helps us understand how the practices associated with DevOps affect IT performance and organizational performance. Let us examine the findings of the report to ascertain how DevOps can benefit your organization.

    Why Does Your Organization Need DevOps?

    The “2016 State of DevOps Report” makes it plain and simple that companies that incorporate DevOps practices get more done. According to the report, high-performing IT organizations deploy 200 times more frequently than low performers, with 2,555 times faster lead times. They have 24 times faster recovery times and three times lower change failure rates. High-performing IT teams spend 50 percent less time remediating security issues and they spend 22 percent less time on unplanned work and rework, the report states.

    Performance

    If we boil down the report findings into actual benefits of adopting DevOps, we could say that DevOps enables continuous software delivery with less complex problems to fix and faster resolution of problems. This essentially means that you can deploy faster and more effectively in more stable operating environments and add value rather than just fixing or maintaining.

    DevOps can revolutionize the performance levels of organizations and allow them to deploy at a rate never seen before. It has certainly enabled organizations such as Etsy, Netflix, Facebook, Amazon, Twitter and Google deploy hundreds and thousands of code per day while delivering world-class stability, reliability and security. You can find out how different organizations have implemented DevOps to their benefit in this YouTube video.

    Security

    Higher performance is not the only payoff in the DevOps culture. Organizations that adopt DevOps practices are known to have better information security. The “2016 State of DevOps Report” clearly states that organizations that integrate information security objectives into daily work spend 50 percent less time remediating security issues than low performers. This has a positive impact on IT performance and security outcomes.

    Any organization, irrespective of size, can employ DevOps to achieve high performance levels and meet business goals while cutting down on costs related to fixes and remediation security issues.

    How DevOps Transforms Teams

    Consider this scenario: In an organization that does not apply the DevOps methodology, the development team writes code and develops a product, which is then sent to the testing team that verifies if the code meets the requirements. The operations team steps in to run the product only after this process is complete. The DevOps philosophy was created to break the silos that teams operate in and effect better collaboration and performance.

    The culture shift DevOps brings about in organizations is substantial, and since culture is a key factor responsible for a company’s performance, application of the DevOps philosophy provides measurable and non-measurable results. A few of them are:

    Employee Engagement

    DevOps is neither a method nor a tool, it’s a culture! In organizations that observe the DevOps culture, the development and operations teams work outside silos, releasing products faster, thereby increasing operational efficiency. This is made possible by the operations team giving the developers constant feedback about the code and troubleshooting problems with the user experience in mind. This continuous learning and delivery practice allows cross-functional teams collaborate as one team with one goal, thus facilitating higher performance levels. The improved organizational culture and enhanced employee engagement can help organizations not only in retaining great talent but also in recruitment.

    Organizational Success

    The “2016 State of DevOps Report” effectively explores the relationship between employee engagement and organizational success and goes on to show that there is a strong correlation between these two factors. The report states that employees in high-performing organizations are more than twice as likely to recommend their organization to a friend as a great place to work.

    Organizations can greatly benefit from adopting the DevOps culture. The “2016 State of DevOps Report” shows that high-performing organizations are widening their lead against lower-performing organizations. This can be attributed to the increased productivity and creativity of highly engaged employees that helps them provide better experiences to customers.

    Organizations can achieve great business results by reinvesting the human time, creativity and energy saved by reducing rework and downtime through DevOps. Herein lies the ROI of DevOps—the competitive advantage that organizations get by investing in a philosophy that positively affects bottom-line results!

    About the Author/ Pallavi Poojary

    Pallavi Poojary1Pallavi Poojaryis a writer with Edureka, an online learning company with more than 250,000 learners spread across the globe. She writes on hot technologies and skills that are in demand today, including DevOps, Big Data and Project Management, to name a few. She is a believer in transformation of careers through learning
  • Checks and Balances to Build Stronger Code

    Checks and Balances to Build Stronger Code

    Every software development needs coding; without it, nothing can be developed. The quality of the software depends on the way its developers write code. It’s an essential part of the system and the behavior of the system depends on it. A small mistake in coding may make the software vulnerable and unstable.

    Quality engineering works hard to find bugs to avoid potential problems with the software. QA engineers spend numerous hours and put tremendous effort into finding any problems with the software and reporting it to the developers.

    Cost of fixing the defects at various level.


    The cost of fixing defects at a latter stage increases exponentially; hence, you need more hours of QA engineers and developers to fix and run the entire release cycle again. If we can save some amount of time and effort, we can utilize resources in a more productive way.

    Can we make sure code is better-written, more tightly secure and has no potential bugs, and the right libraries are used?

    If we can implement it, we can at least make sure developers are checking to make sure there is less friction in the code?

    Here are few checks that can be implemented during creation or before passing code to QA to ensure it’s less buggy.

    Code Review

    In code review, the coder sends it to someone else for the review. It’s really a great way to verify the written code by a second pair of eyes to catch any glitch, logic or possible mistakes overlooked by the coders.

    This is part of the development process to make sure nothing is released without a second opinion. There are many ways and tools available to perform code review. These can be implemented and integrated with the source control tool. More on code review and details can be found here.

    Unit Test

    Unit testing tests a piece of the code by writing small code around it via supporting data and mocking it to test scenarios. It commonly is written by developers during the development, then run during source code compilation or independently according to various languages.

    This testing provides extra early warning to find problems before handing it off to quality check. Unit test coverage could provide details on how much has been covered by unit test cases. There are many ways to figure out the coverage.

    Static Code Analysis

    Static code analysis is the way to analyze at a very basic level without running the software or performing any testing. It can be done at compilation time or at development time by using client-side tools.

    Analysis tools look for any possible or hidden bugs, such as never-ending loops, or programming flaws. These tools do analysis based on a similar pattern but each in a slightly different way.

    Coding Guideline

    Each developer may write code in his/her own style with varying degrees of differentiation. This may create big problems when it comes to handing over of a project to different teams or coders. It may take tremendous amount of time to understand what’s been written by somebody else.

    To reduce this potential headache, organization may implement a coding guideline, or style of writing code for developers, to make sure everybody follows one systematic way that can be understood easily by other team members. There are different tools available for various coding languages.

    Library Check

    Open-source projects and other freely available tools in GitHub are making life easier for developers to use them in their projects as libraries. At same time, they can introduce several other problems with the software if libraries are not tested properly, including security vulnerabilities, untested components or licensing issues.

    There are many tools to help developers to verify their libraries.

    In Summary

    There may be many other verifications and checks required by an organization. Above are the very basic checks that can be implemented during the development phase to rule out any discrepancies related to security or legal issues. Checks could be implemented at the client side, where developers write code or during the continuous integration phase.

    There are many tools available in the market or the open-source community that can be used to verify and secure code to avoid unrealized bugs. It’s in the best interest of any organization to keep its software bug-free and reduce the amount of unnecessary resources working on such issues that could be caught early.


    Other References – http://www.scmtechblog.net/2016/08/code-quality-check.html

  • Hybrid Cloud: How to Avoid Twice the Problems

    Hybrid Cloud: How to Avoid Twice the Problems

    Regardless of how enthusiastically you embrace the cloud, unless you’re a brand new business, you have already have an infrastructure running your applications. Odds are, you’re either renting space in one or more data centers. Or maybe long ago you reached the tipping point and built a data center or two of your own.

    Regardless, moving to the cloud is going to be a process. You’re going to be working on a scale of months, if not years. During that time, how do you manage and secure assets that are in more than one environment—especially when those environments are radically different?

    The Data Center

    Your data center environment is probably well-established. You’ve got a mature technology stack, a high level of rigor around manual processes and a traditional “castle walls” perimeter-based approach to security.

    Specialized teams are in place for the networking infrastructure, operating system management, security, data center logistics and other areas. Each team does a great job running the day-to-day of their areas and planning for the five-to-seven-year life cycle of their technologies.

    The challenge here is that this structure has lead to a slow, stable cadence around innovation and encourages each team to work in their own silo. Common ground and management is established through a formal change management process. This results in stability, but at a very high cost when it comes to rapidly iterating on ideas.

    The Cloud

    In stark contrast, the cloud is constantly changing. New technologies are deployed quickly, systems such as continuous integration/continuous deployment (CI/CD) enforce what used to be a manual process and capacity planning is basically a thing of the past.

    Just as the cloud is delivered in a different manner, teams working in the cloud also are delivering in a very different manner.

    When assets are available on demand and at a higher level of abstraction, a lot of the work associated with deploying a new application is handled by automation, allowing you to focus on solving problems for your customers.

    Reconciliation

    It’s clear that the data center and cloud are two very different environments. How do you reconcile having assets in each without simply duplicating all of your tooling and processes?

    Tools

    Start with the tools that your teams are using today. Odds are, the set of tools you’re leveraging in the cloud more closely aligns with what you want to achieve around application delivery.

    Cloud-first tools also are more likely to be able to handle the rapid pace of change and the large-scale environments normal to the cloud. These traits make it easier for cloud-first tools to adapt to the data center.

    Make sure you’re pushing your cloud-first tools in to the data center and not the other way around.

    Responsibilities

    Leveraging more cloud services from a variety of providers means that the day-to-day operational and security responsibilities are spread out among teams and organizations. This can pose some serious challenges if not addressed properly.

    You need to ensure responsibilities are defined clearly for all involved and there is a spirit of cooperation so that you can avoid finger-pointing when things hit the fan.

    Remember that service level agreements (SLAs) represent the worst-case scenario. Solutions and services always should beat the stated SLA. If a team or organization you’re working with is consistently blowing their SLA or barely meeting it, it’s time to re-evaluate their involvement.

    Process

    Your processes define how the responsible teams are going to use the tools you’ve deployed. Data center processes are the weak spot in joint hybrid environment processes.

    The traditional workflows typically are too slow and require too much manual work to support the style of work the cloud promotes. Take the processes you use in the cloud (think CI/CD), map out where you absolutely have to make exceptions for the data center, and use those as your baseline processes.

    The goal here it to double down on your DevOps culture shift and force it into the data center. You want to maximize your current data center investment while not slowing down the culture transformation you’ve started with DevOps.

    Security

    The last piece of the puzzle (at least a high level) is security. It’s crucial you view security as a unified layer across all of your environments.

    Security is challenging enough without creating additional work for your teams.

    Security controls need to integrate with your preferred cloud service providers and be applicable inside the data center. The traditional perimeter is gone, and tools that still try to defend your data under that principle are needlessly increasing your risk.

    Modern controls need to be applied as close to the workload and data as possible. They need to present a unified front across environments and still handle the speed and scale of the cloud.

    That may seem like a tall order, but there’s a lot of work being done in the vendor and open-source communities to modernize the approach to hybrid security rapidly.

    The Way Forward

    Even in a best-case scenario, you’re going to be dealing with hybrid environments for months–if not years–to come. Doubling your workload or ignoring the challenges will only make matters worse. It’s best to tackle the problem head on.

    Here are the three keys to remember:

    1. Aim for one set of processes,
    2. Push cloud tools into the data center, and
    3. View security as a unified layer.

    This is a difficult task. You are not going to get it right the first time. The key is to ensure your teams are working together, communicating regularly and iterating often.

    What are your experiences managing hybrid environments? Let me know on Twitter, where I’m @marknca, or leave a comment below.

    BTW, if you’re looking for a deeper dive on the topic of hybrid environments, watch my webinar hosted by devopsy.kinsta.cloud, “Handling The Realities of Hybrid Cloud.” Watch below or over on the Trend Micro site.

  • DDoS Defense: Can You Tell Friend from Foe?

    DDoS Defense: Can You Tell Friend from Foe?

    In many organizations, networks are at the core of the business, enabling not only internal functions such as human resources, supply chain and finance, but also the services and transactions the business depends on for revenue. That makes network availability critical. Any interruption of access from the outside world turns off the revenue spigot, impacting profit and creating a poor user experience that can damage customer satisfaction and result in customer loss. The worse the outage, the worse the damage. That’s why speed is so important in detecting, diagnosing and responding to denial of service (DoS) and distributed denial of service (DDoS) attacks.

    One of the chief challenges in responding to an attack is to distinguish friend from foe. Without a way to drill down into traffic details and examine host-level traffic behavior, it can be difficult to tell the difference. Traditional network analysis technologies based on pre-cloud architectures have been too limited in their compute and storage capacity to do more than perform predefined alerting and summary reports. That’s just not enough information to really get to the heart of what’s happening in a complex networking scenario.

    Fortunately, new big data techniques allow us to dig deep into huge volumes of network traffic details so that it’s possible to understand what is really going on. With a properly implemented big data platform, you can pivot your views of data to gain insight rapidly, in operational time frames, so you can act to mitigate an attack or remediate a more innocent but still painful network issue. We’ll examine data that is readily available through common network traffic flow telemetry exports such as those provided by routers and switches enabled by NetFlow, sFlow or IPFIX.

    Starting at the Top

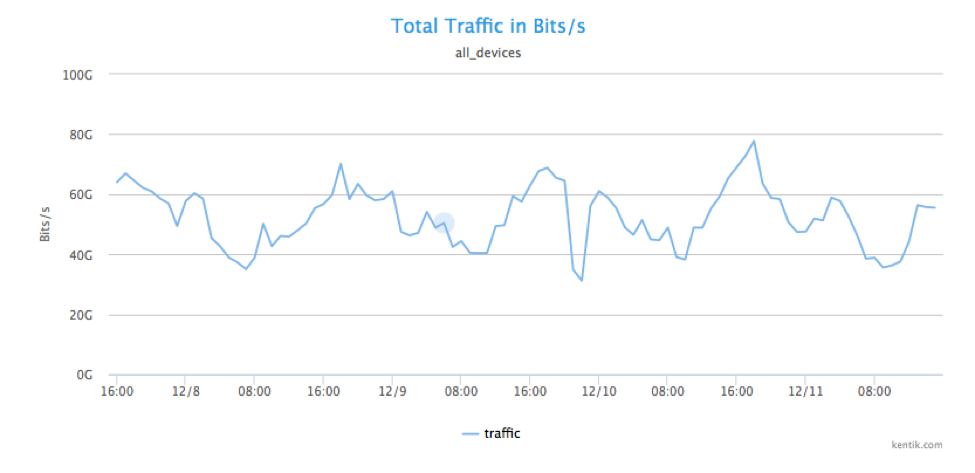
    Let’s say we’re seeing symptoms of an attack in our infrastructure. We’ll use traffic flow summary data to quickly scan total traffic in bits per second just to see if anything stands out.

    Picture1

    There’s no obvious traffic spike from this view, but then again the network we’re looking at is running at an average of 60 Gbps, so that doesn’t mean there aren’t worrying things going on at deeper levels of the network.

    Analyzing Source Geography

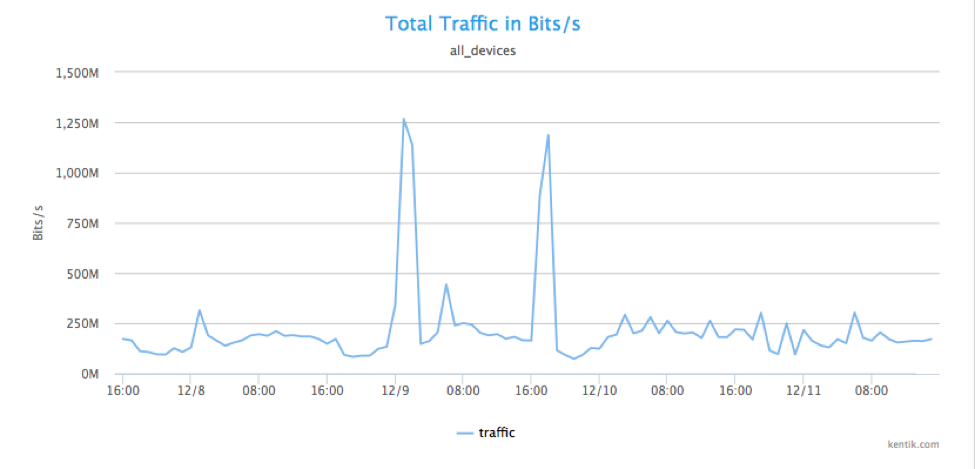
    One of the things that big data is good at is fusing many data sources together. By combining NetFlow data with GeoIP, we can look at traffic by source geography. In this case, the network doesn’t get a lot of traffic from China, so what happens when we filter total traffic by China as source?

    Picture2

    A ha! That analytical pivot produces a graph above, showing two obvious spikes that are well above average. Below, we zoom in on the time of the spikes.

    Picture3

    Analyzing Unique Source IPs

    The spikes themselves are suspicious, but is this just a large data file transfer? We can find out by looking at how many different source IPs are sending traffic. To look at host-level details, note that we’ve gone beyond the point where you can use summary information. At this point, we are analyzing raw NetFlow record details.

    Picture4

    Those raw NetFlow details sure are useful, because there is, in fact, a huge increase in the number of unique source IP addresses sending traffic to particular destination IPs. This tells us that we’re not looking at a large file transfer from a single machine, but a highly distributed set of senders. Botnet much?

    Who’s Getting Hammered?

    The next step is to  to determine which IP or IPs are getting all this (probably unwanted) traffic from 14,000 or so individual host IPs.

    Picture5

    The ability to dig into high volumes of host-level NetFlow details again proves its utility. We can see that the main target is a solitary destination IP address. There’s really only one likely explanation for traffic from thousands of hosts in a country which you have no business dealings with to a single IP that suddenly spikes from nearly nothing to more than 1 Gbps: This is a DDoS attack. Note that this isn’t a mega attack, but it still can cause real problems for whatever is running on that individual host and anything else that depends on it. If it’s your DNS server, the attack might make it impossible for lots of other servers and applications to function.

    Going Deeper

    Now that we know it’s a DDoS attack, we shouldn’t stop because we don’t know whether that attack is coming from other countries besides China. We pivot our analysis again to widen our lens.

    Picture6

    Lo and behold, there is indeed DDoS traffic coming from multiple countries, including the United States, Japan, Russia, Sweden, China, Taiwan, Brazil and Estonia. Good to know.

    Characterizing the Attack

    Next, we want to know specifically what type of traffic we’re seeing and what that tells us. We’ll group the traffic coming from all those source host IPs by protocol.

    Picture7

    Clearly, this is  UDP-based attack. Now we’ll look at the destination port(s).

    Picture8

    We can see that the UDP traffic is being sent to multiple ports, and it’s obvious that we’re experiencing a DNS redirection/amplification attack occurring on port 53, with a lot of port 0 UDP packet fragments being generated as collateral traffic.

    Is Something Underneath This Attack?

    So far we’ve gotten a lot of insight into the details of the DDoS attack from full NetFlow details. But is this volumetric DDoS the main event, or are we being distracted from looking for other, less obvious threats? We can see a lot of packets being sent to port 4444 (green line in graph).

    Port 4444 is the UDP port for the Kerberos service, and is—at least for Windows machines—a well-known target for buffer overflow attacks, often used to insert trojans such as Hlinic and Crackdown.

    So, potentially there are two types of attacks going on in parallel: a DDoS attack and a buffer overflow trojan insertion. Many security blogs and publications note that DDoS attacks often are used to obfuscate other exploits. This very well may be an example of that technique.

    Getting a Handle on Attack Mitigation

    Characterizing the attacks leads us to mitigation. One way is to take the attack traffic and group it by x/24 source network addresses:

    Picture9

    We now can take two mitigation steps:

    • Ask our upstream ISP to drop this traffic or send it to a scrubbing service or device, if we have one.
    • As an added precaution, drop all traffic from these countries going to port 4444 on our own routers.

    Conclusion

    One of the benefits of being able to dig into full-resolution NetFlow data is that you can get operationally useful insights without needing in-line devices. You also get more freedom to employ a portfolio of mitigation methods. Big data is the way forward if you want to have full details at your disposal to deal with DDoS attacks.

    About the Author / Alex Henthorn-Iwane

    AlexAlex Henthorn-Iwane is the Vice President of Marketing at Kentik. He has more than 20 years of experience bringing new technologies in networking, security and software to global markets. Henthorn-Iwane leads the global marketing strategy for Kentik and help the company bring its innovative story and solutions to network-dependent organizations around the world. Connect with him on LinkedIn, Twitter or SlideShare.
  • Delivering DevOps’ Business Value

    Delivering DevOps’ Business Value

    DevOps is an interesting space to be operating in right now. More than just culture or a set of tools and processes, DevOps delivers speed and agility that can be truly meaningful for the business. Unfortunately, for most large enterprises, the path to the benefits isn’t always well-known and isn’t assured.

    Over the last five to 10 years, a number of DevOps tools and solutions have emerged: Puppet, Chef, Jenkins, Git, SaltStack, Elasticsearch … and the list keeps growing. Originally, these tools were sought by developers and system engineers for their ease of use and low cost of ownership: You could download it, use it the same day and solve your specific problem. The issue for enterprises,  however, is that nature abhors a vacuum; the problem one developer addressed with Chef is being fixed with Puppet by another developer in a different business unit. Group A is using Jenkins, Group B is using Chef Delivery. In short, after five to 10 years of technology adoption by developers and system engineers, the tooling landscape in the DevOps space is packed to the rafters with competing technologies, all of which are solving similar problems with overlapping features.

    So why should this matter to you at all? Without careful planning, consideration and execution, your business will derive little value from this DevOps exercise.

    Here are a few common pitfalls we see far too often:

    Too Many DevOps Tools Doing Too Few Things

    Building Rube Goldberg devices looks neat on paper, but those mousetraps fail very often in real life. The more tooling and solution handoffs you have, the greater your likelihood of failure: the less likely you are to be able to scale horizontally or vertically, the more toolsets you need to maintain, and the more skills you need on your team. Convoluted messes do not yield speed and agility. If it feels wrong, it probably is. If it is overwrought, look to remove complexity from the landscape.

    Reintroducing Risk and OpEx Spent on Menial Tasks

    As an organization you’re onboarding risk, hidden costs and a lot of the things you just spent the last 10 years automating away: tribal knowledge, lack of governance, lack of compliance, lack of third-party auditability and reporting. Many enterprises spend millions of dollars making it so their admins and developers could spend time on more valuable workstreams, just to throw them back into the salt mines of making continuous integration (CI), continuous delivery (CD) and infrastructure-as-code “work” over umpteen toolsets. The goal isn’t for DevOps to “work”; the goals need to tie to some tangible (i.e. measurable) business benefits. Anything can be made to work, but far fewer IT programs deliver value. Be the people who deliver real value.

    Taxation Without Representation

    All of the stakeholders need a seat at the table. Whether that means forming a SWAT team from operations (all infrastructure domains and security), development, QA or a permanent DevOps matrix organization, all vested interests need a say in how the process and tooling develops for all impacted domains (which is just about everything) across all environments (i.e Dev, Test, QA, Production). Far too often we see one set of stakeholders acting as the service provider for another group of stakeholders playing the role of customer. This is a solution for and by Development and Operations.

    Congratulations, you’re having a baby. Let’s make sure it’s not ugly, okay?

    About the Author / Jesse Langhoff

    Web_Langhoff_Jesse-7633-EditJesse Langhoff is co-founder and CEO of Raindance, a cloud and automation consultancy serving enterprises nationwide. With over 15 years of experience in leveraging technology to address business challenges, Jesse works with customers to determine the optimal path to meeting their goals through the use of automation and solutions provided by the leading vendors in the space. Areas of expertise include strategy and assessments, private/hybrid cloud services, process automation and orchestration, DevOps and operations as a service. Jesse holds an MBA from University of St. Thomas – Opus College of Business.
  • The DevOps Force Multiplier: Competitive Advantage + Security

    The DevOps Force Multiplier: Competitive Advantage + Security

    Several years ago, DevOps started hitting the eyes of enterprise business leaders when news outlets such as The Wall Street Journal and Forbes began reporting that the IT culture and methodology was helping adopters to gain a competitive advantage. Since then, we’ve seen story after story about how DevOps-focused employees are becoming the driving force behind the software and applications the world relies on for everything from mobile banking transactions to ride-hailing to gaming. Even the Pokemon company can’t get enough DevOps engineers.

    It looks as if DevOps soon may be recognized as more than just a force for fast and agile software development and deployment. Evidence is emerging that it also may be having a positive impact on security.

    Security Researcher Sees Trend

    Screen Shot 2016-07-21 at 9.03.00 AM
    Bugcrowd Security Researcher OJ Reeves

    Bugcrowd Researcher OJ Reeves sees his fair share of weak security. As a full-time white-hat penetration tester and researcher running attack simulations for enterprises that want to improve their defenses, he’s seen everything from unpatched vulnerabilities in software to the perilous journeys overshared credentials take as they’re passed between multiple administrators across various communications channels.

    Recently, Reeves noticed that in our facepalm-ridden world of security blunders, organizations with a DevOps focus seem to have better security.

    “DevOps is young and still being defined differently across organizations,” said Reeves. “I have noticed recently that when I engage with businesses that employ DevOps-focused people, a security mindset often accompanies.”

    The reasons behind why DevOps is assisting with creating more secure environments are wide and varied, Reeves cited several.

    DevOps Checks Boxes — All of Them

    “Check box security” can be a bit of a dirty-word term when it comes to protecting systems and data, as it frequently refers to compliance—something many cybersecurity and risk professionals consider to be the bare minimum when it comes to protecting data and systems. At the intersection of DevOps and security, it actually can mean something very different, Reeves said.

    “Organizations that actually have DevOps people in place tend to do a better job checking all boxes and making sure security is in place,” he said. “When you have a DevOps person who is doing the job properly, they (organizations) have a much better chance of defending themselves.”

    DevOps Makes Fewer Mistakes

    One company Reeves attacked had developers, operations and infrastructure employees in place but no DevOps-focused team members. He noticed right away that there was no clear definition of who was responsible for security or who was in charge of protecting application life cycles.

    “There were credentials everywhere—all spread out and all mismanaged in different ways,” he noted. “You don’t want anyone with malicious intent, who can compromise a developer’s’ desktop, to get access to credentials.”

    When running simulations for organizations with DevOps employees in place, he’s observed that those kinds of mistakes happen less frequently.

    “More often than not I’ve found that the credential management process is much better when DevOps people were present. When there is a person in charge, who is also conscious of how others are using credentials, a credential security champion tends to emerge,” he said.

    DevOps Communicates

    Reeves, like many other practitioners I’ve spoken with, emphasized that communication between IT members is critical to effective defense. That’s something he said DevOps-focused organizations seem to be especially good at doing.

    When privy to conversations taking place between developer, security and DevOps employees, Reeves has noticed that everyone involved is interested in improving processes all around—processes which include security.

    “Direct human interaction that takes place between those who are responsible for defense tends to result in improved security,” he added. “Just the fact that awareness for these [security] issues is being raised and discussions are taking place is having a positive impact.”

    Reeves indicated the discussions taking place within DevOps environments he’s observed are focused on the right things.

    “These human-to-human interactions make things more secure and they pay attention to organizational security, where we should be having our discussions,” he noted. “Let’s not talk about the latest AV (anti-virus), etc.; security is an organizational process and problem. The best security in the world doesn’t matter if employees in the organization aren’t aware of what’s taking place.”

    DevOps: Harder to Crack

    At the end of the day, companies such as Bugcrowd and pen testers such as Reeves are paid to find exploitable gaps in systems so they can be closed before the nefarious can take advantage of them. While DevOps isn’t typically thought of as a security enabler, organizations that don’t have dedicated DevOps employees may want to consider Reeves’ parting words: “When organizations I am researching have a DevOps focus, it is generally more difficult for me to compromise them.”

  • Intersections: DevOps, Release Engineering and Security

    Intersections: DevOps, Release Engineering and Security

    With emerging ideas, innovation and talents, the lines between DevOps, release engineering and even security are rapidly blurring. I invite you to sit down for a moment with principal consultant, J. Paul Reed, and listen to his take on what the intersection between these once individualized fields entails—and may even foreshadow.

    Derek Weeks: Good morning, Paul. There’s a lot those pursuing DevOps can learn from release engineering practices. I know you’ve got a lot of experience to share, so let’s get started.

    J. Paul Reed: Good morning, it’s good to be here. My background is release engineering, although these days I am actually called a DevOps consultant. I have about 15 years experience doing that. That’s what my presentation is about: sort of the intersection between DevOps, rugged DevOps and release engineering, and wanting to explore that with the security and rugged DevOps communities.

    J. Paul picture

    Weeks: In your presentation, you touched on the culture between security and DevOps and also release engineering—that a number of organizations have challenges with, and that’s the “Culture of No.” There’s a lot of, “Hey, we want to move faster at higher velocity. We have new requirements that we’re trying to push out to market, and we have these new practices that we’re moving forward with. Can security come and play with the DevOps team?”

    Reed: I actually put up a tweet that a lot of people liked on one of my slides: “If your answer to every question is ‘no,’ do not be surprised when people start pouring effort into ways to not even ask.” This idea that if your answer to everything is “no,” then that is seen as a bug or a blockage like on the internet, and organizations will just route around it. I think security found that out in a very visceral, hard way. In release engineering, it’s the same thing.

    —

    “If your answer to every question is ‘no,’ do not be surprised when people start pouring effort into ways to not even ask.”

    —

    One of the reasons that Git became so popular is because developers didn’t have to ask if there was permission to create branches. They created an entire infrastructure and ecosystem around not having to ask. I think that’s one of the risks we run, and it’s one of the similarities.

    One of the interesting things we’re finding with DevOps—because that idea of getting new traction and people do want to move faster—is we can frame the work that we do in the context of that pipeline. By identifying and optimizing some of the business value that is part of that pipeline, businesses are receptive. Developers are receptive. Different parts of the business are receptive in ways I’ve almost never seen in my career, and it’s great to be a part of that. From a rugged DevOps or security perspective, I think if we could move that work into the pipeline, not only do we make it visible in terms of the costs and trade-offs, but then also we could possibly do more. It’s part of that whole. There are lots of presentations talking about this idea of shift left, that you can shift that work from your perspective further up into the stream so that you can address it earlier and actually have a chance at fixing the problem.

    In talking with Josh Corman and a lot of the rugged DevOps people, they always talk about how at the end of that process, they would rubber stamp: “Yes, this is secure.” Because even if wasn’t really secure and it was bad, what were you going to do? As a release engineer, that resonated with me because we felt like that all the time. We were kind of doing a bunch of work at the end, and there was no time to do it right. So a lot of times, it was skimped on.

    Weeks: When you think about the way traditional security works, how early can we think about rugged DevOps shifting left?

    Reed: Yeah, I don’t think it’s so much about getting everything right at the beginning, per se. I think that the question is how far forward can we shift into that process. I think if you can shift that all the way to the beginning, that is possible. The beginning is where you define your pipeline.

    A lot of people define that pipeline as commits, that is developers writing code. Some people will define it actually at the product management stage, so even earlier than that. Or that kind of agile story phase, I think you could certainly integrate it there. This is sort of what I was exploring in my presentation. I open with the slide on what is the intersection of release engineering and Rugged DevOps, and I say I don’t actually know. It’s a very emergent field.

    —

    “There’s no shortcuts to production…They put the financial resources and the engineering resources into building the pipeline that moves code quickly through it.”

    —

    I spend the next few slides talking about sort of the crossover in making that bar. There are a lot of similarities there. I think when you’re talking about pushing that stuff forward, it’s about the more tools that you can make part of that pipeline, like release engineering tools. So for us, that might be something like: How do we track what developers create as dependencies in the work that they’re doing? So how do we make that a little bit easier in time for them to say, “Yeah, I’m using this version of that, and it’s integrated here from a release engineering perspective.” Then from the security perspective, you can take that information and use it to do different types of security testing or penetration testing. If you can move that earlier in the process, that’s what it will do. Then how early you do that really is a function of how good you get at this sort of thing.

    I don’t think we’ve seen this with security entirely yet. We’re still recognizing the value with release engineering and companies are hitting it out of the park. They just put everything in there and continue delivering pipeline. There’s no shortcuts to production. There’s no back door to get stuff deployed. They put the financial resources and the engineering resources into building the pipeline that moves code quickly through it. Then once you do that, you can augment that pipeline with more and more features, if you will. One of those might be moving security way forward in that process.

    Weeks: Are there old ways to do things that just won’t work in the new universe and you have to adopt new tools or practices?

    Reed: I do hear a lot of, “Well, we can’t do X because of Y” — “Y” being one of those cut old ways that you’re talking about. One of the things we continually see at conferences is idea of the answer being, “We can’t do X because of the old way.” In fact, in security, you see this all the time: “I can’t do X because of audit compliant stuff.” But case study after case study says: If you’re willing to rethink the framing on the way you do audit compliance and work with your auditor—if you’re willing to look at the problem slightly differently—then you can achieve those results. Because we have all this proof, when people say, “Oh, we can’t do X because of the old way,” my question is, “Are we thinking of the problem in an old frame or in a more traditional framing that is not sewn enough?”

    Now that’s not to imply the concerns people bring up are invalid. That’s the initial question that you had, which was about people. If they have a lot of knowledge, they might be worried, “Well, I can’t automate things this way as well as I can test them.” I talked in my presentation about how release engineering is undergoing a fundamental shift. I’m very upfront about the fact that if you are a release engineer and you are not building continuous delivery pipeline and involved in the support and service of that continuous delivery pipeline, your job is probably not going to be there in five to 10 years. That’s just the way the world works. A lot of people think, “Oh, okay, that’s unfortunate,” or whatever.

    —

    “If you are a release engineer and you are not building continuous delivery pipeline and involved in the support and service of that continuous pipeline, your job is probably not going to be there in five to 10 years.”

    —

    I’ll give you a QA (quality assurance) example that I thought was really innovative.

    Organizations spend a bunch of time automating a test and the initial response is, “Well, if you automate all of those tests, what are the QA engineers going to do?” It turns out that because QA engineers are so good at looking at a product and coming up with the requirements, they need a lot of that totally valuable knowledge forwarded into the value stream. They are having those QA engineers doing requirements analysis and working with product management to firm up the actual requirements that go into the continuous delivery pipeline. What was fascinating about it was that it’s not that the organization was, “We are going to automate you out of a job and then we’re going to fire you, so go automate yourself into a script.” People are like, “I’m a person, not a machine.” You have that whole conversation, and they end up doing more interesting work.

    They put them working on that continuous delivery pipeline in the requirements analysis. It’s totally different than what you might expect. It’s going to be the same with security and release engineering. For security especially, we’re going to see a lot of that work go. There’s a set of compliance work you can do in an automated fashion. Once that is automated, I see a lot of discussion about red team, blue team … kind of wargaming type of thing. And it frees up time to do that and to work as a team in that way. Because you can’t automate all those things, or at least today you can’t. I think everybody in the security space would agree that it’s more interesting work than running around, if you’ve got a huge project, with a black binder with a bunch of rules.

    Weeks: One of the concepts that really resonated with you was the software supply chain. How does that concept fit with doing release engineering right and doing rugged DevOps right or incorporating security into DevOps?

    Reed: Yeah, the supply chain idea is something that was fascinating the first time I heard it. In fact, it’s one of the things that Josh and I spent a bunch of time talking about it when we first met. I think it’s a great way to frame a problem. I’m sad that I didn’t think of it, actually, and the reason is because release engineers think about that all the time. We’ve thought that was our role for 20 to 30 years, for as long as release engineering has been around. It’s this idea of knowing what the dependencies are, dependency management tracking and trying to make sure that you don’t pull in bad dependencies—whether they are tainted because of the license or containing malicious software. This problem has only gotten worse with open-source software, and that’s also something that from a supply chain perspective we talk a lot about.

    —

    “I told this story about an engineer who was missing a DLL from the build. They just Googled for the DLL and downloaded it, and threw it on all the build machines. That was pretty scary.”

    —

    That was one of the things that I wouldn’t think keeps release engineers up at night as much as it keeps security engineers up at night. Where is our software coming from, and what issues may it have in it? That’s not something traditionally developers, for whatever reason, seem to think about and that’s not to denigrate them. A lot of times they’re under deadlines, like we are. They go to the internet. They grab whatever version of the library. In fact, the one I usually see is the upgraded version because there’s some API that they need or something like that. There’s a concern there, when you think about it, of where that’s coming from. I told this story about an engineer who was a missing DLL from the build. They just Googled for the DLL and downloaded it, and threw it on all the build machines. That was pretty scary.

    One of the slides in the presentation I think is really critical is: “If you have one vulnerable library in your product, that is a security problem. If you’ve got multiple versions of the same library and multiple versions of those are vulnerable, that’s a release engineering problem.” That’s one of the best ways upfront that release engineers can contribute to rugged DevOps and contribute to the security space in terms of helping to detangle that problem. More interestingly, once you’ve detangled that problem, you have to figure out how to make it so that that just doesn’t turn into spaghetti again.

    I’ve detangled that problem multiple times usually, by the way, not so much in a security context but in a licensing context.

    —

    “If you have one vulnerable library in your product, that is a security problem. If you’ve got multiple versions of the same library and multiple versions of those are vulnerable, that’s a release engineering problem.”

    —

    The way you do that, again, is shifting left. Moving that forward where you have a way that as developers put libraries into the product, new code that isn’t written by them because there’s a dependency there that was well-documented. You can do that audit in kind of a continuous fashion so that maybe an artifact that you build is a list of library conversion. Then from an automated security testing perspective, we can compare that against a list of CD (continuous delivery) use or known issues.

    Weeks: I did a lot of research at Sonatype on the software supply chain and one stat boggles my mind. Out of the top 100 components companies were downloading, they downloaded an average of 27 versions of each of those components in a single year. When you think about the complexity and the technical debt, and if there’s security debt in that at all, you only need 100 parts and yet you’re using 2,700 parts. Why would you ever want to do that?

    Reed: One thing I’ll point out is that I think the industry’s moving in some sense in the wrong direction. What mean by that is you’ve got your Java you’ve built in this to make it really, really, really easy. From the command line, you just pick up libraries from the internet. Who knows where they came from. Node makes this trivial. In fact, Node was built around npm, the package manager. All of that is online. In fact, it’s even worse. One of the things I get called in to help with a lot these days is—and I kind of giggle at this, just because of the dichotomy—people were so interested in Git for so long because it was like offline Git, offline commit. It’s great, right? You can build offline, and people always use the example of when I’m commuting home on the train, I can commit blah, blah, blah, and that was the big reason for doing it.

    Now we’ve moved with Node and some of the tooling around Java so that our software builds literally require us to talk to the internet to download packages. There’s this big push for offline operations. But it’s fine that no download needs 68 billion versions of libraries, and everything is “self-contained.” But if you’re going to look at a Node package, it’s got versions of those things stocked in there. That’s a feature, not a bug. Right? In certain platforms—you see this with RubyGems, when the Ruby Gems site went down, nobody could deploy their web applications. That’s a fundamentally broken engineering design in my opinion. Not that it’s easy for developers to get that. But that our build processes, our deployment processes, rely on those things. And they rely on us as developers to say, “I want version 1.2.4 of that library, and that 1.2.4. is the same version that you use.”

    I posted a slide about versioning, and that’s a very release engineering problem. As an example, Open SSL made a mistake in their versioning and instead of bumping the version like they should have, they repackaged binary. I suspect the reason that they did that is because they published all the CVEs (common vulnerabilities and exposures) with that version number and everybody is like a hawk watching Open SSL. So they couldn’t bump the version number easily. Open SSL can’t be flexible in their release engineering anymore because they’ve been so traditionally horrible at it. Right? We’ve made it really easy to stuff all of those components into our products, but we really don’t know what we’re stuffing in there.

    If you look at it, we end up worrying about a lot of the same things. I think a lot of the nuts to crack, if you will, in the rugged DevOps community are maybe 50 [percent] to 80 percent release engineering problems. Strengthening that extra feature of security in there, to make that part of it, especially with the supply chain, will work really well.

    —

    “A lot of the nuts to crack, if you will, in the Rugged DevOps community are maybe 50 [percent] to 80 percent release engineering problems. Strengthening that extra feature of security in there, to make that part of it, especially with the supply chain, will work really well.”

    —

    Weeks: J. Paul Reed, thank you very much. It was a pleasure talking to you, I really enjoyed the conversation. We’ll look forward to seeing you again soon.

    Reed: Awesome. Thank you.

    If you loved this interview and are looking for more great stuff on rugged DevOps, I invite you to download this awesome research paper from Amy DeMartine at Forrester, “The Seven Habits of Rugged DevOps.”

    Amy DeMartine

    As Amy notes, “DevOps practices can only increase speed and quality up to a point without security and risk (S&R) pros’ expertise. Old application security practices hinder speedy releases, and security vulnerabilities represent defects that can leave a company open to cyberattacks. But DevOps practitioners can leap forward with both increased speed and quality by including S&R pros in DevOps feedback loops and including security practices in the automated life cycle. These new practices are called Rugged DevOps.”