Tag: resilience

  • Blue-Green Deployment: What Are the Options?

    Blue-Green Deployment: What Are the Options?

    Blue-green deployment is a change management strategy for software releases. Blue-green deployments require two identically configured hardware environments. One environment is active and serves end users while the other remains idle.

    Blue-green deployments are typically used for applications with strict uptime requirements. First, new code is released to staging environments and fully tested. Once the code is reviewed, the team adjusts the router configuration to redirect application traffic to the staging environment. This staging environment then becomes the production environment.

    If problems are found after the switch, the team switches traffic back to the old production environment and continues running the original version. Once the new code is validated in production, the team can update the code in the idle production environment, and use it to test the next release. For more background, see this detailed blog about the blue-green deployment pattern.

    Blue-Green Deployment Benefits

    Here are some of the main advantages of blue-green deployments.

    Standby System
    A blue-green deployment always ensures a server is on standby, providing a crucial backup when the system fails. In addition to facilitating software updates, this approach improves risk management, allowing you to switch to the backup server during a malware breach.

    Redirecting traffic to the other system version is easy because it has the same infrastructure. The system can stay live and functional while the teams fix issues.

    Smooth, Fast Releases
    A blue-green deployment allows product owners to push software to production quickly. It offers the flexibility to release an update at any time, with no downtime required. End-users don’t feel the impact of each release. DevOps teams can also benefit from smooth releases because they don’t have to race to meet deadlines for scheduled outages.

    Simple Rollback Process
    Rolling back an update is also fast in a blue-green deployment. Simple rollbacks reduce the risk of experimenting in a production environment. You can implement rollbacks by setting the application to read-only or using a load balancer to handle active transactions during the cutover. This can be significant for Kubernetes security because if security vulnerabilities are discovered in the cluster, you can easily roll back to a previous safe version.

    No Downtime
    A blue-green deployment allows you to avoid downtime, whether scheduled or unexpected. You can shift users to the other model during maintenance checks and fixes. Upgrades can occur anytime because there is no need to wait for times with lower traffic (i.e., midnight).

    Testing in Production
    Testing in production allows you to check a live product’s functionality, showing how it performs in the real world. The drawback of this approach is that it can expose end-users to bugs during testing. A blue-green deployment lets you test the product in an inactive production environment, minimizing the risk of bugs making it to the live environment.

    Blue-Green Deployment in Kubernetes

    Many development teams are migrating to Kubernetes as an environment for development, testing and production deployments. Kubernetes makes it easy to deploy applications and can also be used to automate blue-green deployments.

    However, Kubernetes does not provide out-of-the-box blue-green deployments. It has a Deployment object that allows “rolling updates”—this allows you to update your applications without downtime by incrementally replacing pods with the latest version of an application.

    This is similar to a blue-green deployment but doesn’t offer all the benefits. Rolling deployments can make it difficult to roll back if there are issues with the new version. You might require Kubernetes health checks to determine the status of pods within a deployment. Applications might take time to roll out, while the pure blue-green pattern allows you to switch over to a new version instantly.

    Blue-Green Deployment in Kubernetes: What are the Options?

    Argo Rollouts
    Argo Rollouts is a set of Kubernetes controllers and CRDs that provide advanced deployment features for Kubernetes such as blue-green and canary deployments, experiments, and other progressive delivery capabilities.

    Argo Rollouts optionally integrates with Kubernetes ingress controller implementations and service meshes, leveraging traffic shaping to incrementally switch traffic to new versions during updates. Rollouts can also query and interpret metrics from other systems to validate key KPIs, and automatically promote or roll back releases.

    Flagger
    Flagger is a progressive delivery tool that automates the release process of applications running on Kubernetes. It reduces the risk of introducing a new software version into production by gradually migrating traffic to the new version while measuring metrics and performing conformance testing.

    Flagger implements multiple deployment strategies (canary releases, A/B testing, and blue-green deployments) and integrates with various Kubernetes ingress controllers, service meshes, and monitoring solutions.

    GitLab CI/CD
    GitLab is a collaborative DevOps platform and open-source code repository for large software development projects.

    In addition to a code repository, GitLab also provides CI/CD automation and issue tracking. GitLab repositories allow the hosting of different software versions and entire development pipelines, allowing users to roll back software and environments in case of unexpected problems.

    GitLab supports both manually triggered deployments and scheduled deployments to Kubernetes production systems, using progressive deployment (including blue-green deployment).

    CircleCI
    CircleCI is a CI/CD platform that helps engineering teams build, test, and deploy software, while viewing code changes in real-time in a dashboard UI.

    CircleCI can be deployed to virtually any target and can be easily configured to integrate with other services, for deployment strategies such as feature flags, blue-green and canary deployments. It supports both fully automated deployment processes or a process with manual approvals, with the ability to easily customize deployment configuration.

    Conclusion

    In this article, I explained the blue-green deployment pattern, its benefits, and how it can be beneficial for Kubernetes deployments. I introduced four tools that can help you implement blue-green deployments in your Kubernetes clusters:

    ● Argo Rollouts – Part of the open source Argo project. Includes Kubernetes controllers and CRDs that provide advanced progressive deployment features.
    ● Flagger – An open source progressive deployment tool for K8s that supports canary releases, A/B testing, blue-green, and more.
    ● GitLab CI/CD – Supports both manually triggered deployments and scheduled deployments to Kubernetes production systems.
    ● CircleCI – Supports deployment to Kubernetes clusters, with deployment strategies such as feature flags, blue-green and canary deployments.

    I hope this will be useful as you learn to implement progressive deployment patterns in your Kubernetes environment.

  • SRE Vs. DevOps: The Wrong Question?

    SRE Vs. DevOps: The Wrong Question?

    The age-old question about the competition between DevOps and SRE sets up a false dichotomy. DevOps is a methodology while SRE is a team within operations. Although the two are often pitted against one another, developers also embody the skills and the capabilities to implement fixes. 

    Traditionally, application changes were reactive. The process of SRE formalizes problem resolution playbooks for better efficiency within the development life cycle. This has changed substantially over the past few years with DevOps seeing more traction and mainstream adoption.

    So what is the modern relationship between DevOps and SRE and how can they best be used together? Let’s understand DevOps first.

    Defining DevOps 

    According to Chef’s Embrace DevOps guide, DevOps is about transforming the way companies run; part of that transformation is understanding that companies should focus on managing people rather than products. DevOps evolved over the last decade and was originally born into the world of software. The adoption of cloud technologies, changes in the tech stack architecture, SaaS platforms, and security regulations have all impacted DevOps culture

    Some of the fundamentals of modern DevOps are:

    Everything-as-code: The current state of IT architecture has adopted an “everything-as-code” approach. Infrastructure, configuration, compliance and security can all be transformed into code.

    Automate everything: Codifying everything enables standardization of processes and policies across the organization. The processes are simplified into repeatable functional code, and this makes it easier to automate the development and deployment processes while significantly reducing human errors.

    Validation: There are many tools used for continuous integration, delivery and deployment in addition to other tools used for maintaining infrastructure and compliance. Without validation, there would be no way to know if everything is functioning as needed and it would be difficult to ensure seamless delivery in a highly agile environment.

    Above all, teams adopting DevOps methodologies take end-to-end responsibility of managing the application development life cycle (develop, deploy and maintain). They bridge the responsibilities gap between Dev and Ops into one team. 

    SRE Focus Areas 

    Successful site reliability engineering (SRE) teams focus on the volume of performance metrics and the process of shifting left the responsibility for managing and mitigating risk. Fundamentally, they share the same values as developers in creating efficient applications. However, SRE teams focus on introducing efficiencies based on incidents that occur and sometimes need development teams’ intervention to shift the risk left in the product development cycle. 

    Troubleshooting is one of the main responsibilities of SRE teams since they have to manage incidents. As a result, SRE teams have a strong knowledge of product design which is essential for product reliability, rollouts and reducing recovery time. Scalable automation is also a big part of the challenge SRE teams face. Oftentimes, tasks are done manually and this can increase the likelihood of human error. A solution is implementing a policy-as-code approach in concert with developer teams.

    It should be noted that when it comes to the responsibility and scope of work between SRE and DevOps, the lines are blurred—especially with the proliferation of APIs and when evaluating microservices. The types of tools being used are a differentiator since SRE teams measure efficiency through monitoring, detection and incident reporting systems. 

    Breaking the Silos 

    Modern organizations will fail when divided into silos. Developers understand that to optimize their internal processes, they need to use a DevOps methodology and involve SRE teams. For example, a startup growing and looking to scale needs development teams that are performing SRE functions with strong operational knowledge. It requires buy-in and understanding of every team member to know their role and the needs of the organization as it grows and responsibilities shift. 

    These fundamental values are crucial for an enterprise looking to achieve an efficient CI/CD pipeline. In a reactive cycle, SRE teams step in and are responsible for some parts of operations, but the DevOps paradigm is different because it integrates the responsibility of deployment, monitoring and remediation throughout the entire team. 

    Organizations embracing DevOps practices should embrace SREs’ expertise and welcome their practices into developer teams. SREs can leverage automation to fix issues as they occur and also make changes in software architecture to avoid such issues in the future. Compared to the reactive approach, developer teams are incentivized to keep things constantly running. 

    Scaling DevOps practices requires shared responsibility. Of note, developers have to answer when the phone rings and this can cause chaos in engineering teams responsible for large enterprise-grade applications with fast time-to-market and frequent update cycles.

    A Modern Perspective

    Efficiency is a core value shared by both SRE teams and the DevOps methodology. When organizations can fully integrate operations within the DevOps cycle, those silos can be broken down and integrate a shift left mentality. The traditional reactive remediation cycles won’t cut it anymore. Proactivity is essential for today’s lightning-fast application needs and continuous updates. 

    Application problems can be addressed immediately when approached with modern tooling and a policy-as-code approach enabling developers and SREs teams to work together. The modern relationship between DevOps and SRE teams should be one of coexistence. Both are needed for successful scalability within the enterprise. Many once thought SRE teams and developers couldn’t coexist in harmony, but debunking that myth helps organizations optimize their collaboration efforts. 

  • Secure Software Summit: Applying Chaos Engineering to Software Security

    Secure Software Summit: Applying Chaos Engineering to Software Security

    Today’s software systems are, essentially, controlled chaos—and lightly controlled chaos, at that. This makes it exceptionally challenging to model the behavior of those systems. Our systems are quickly becoming larger and larger, with more and more moving parts. It is not uncommon for enterprises to have over 1,000 microservices and millions of containers running thousands of applications containing many thousands of open source libraries. 

    Why are things growing more complex? Because from microservices to CI/CD pipelines, from service meshes to blue/green deployments, all these new practices and new technologies help us make our applications and infrastructure more resilient and scalable. The downside is the ever-increasing complexity, which is actually accelerating. 

    In addition, software has officially taken over every layer of the networking and hardware stack (which sounds like an oxymoron, but it’s containers and virtualization turtles all the way down until you hit bare metal). Software is, by definition, easy to rewrite. Thus, the ease of changing software has further increased the number of changes we make to systems. Which adds still more complexity. In fact, software only ever increases in complexity; never decreases in complexity. Software is always trying to do more and encompass more. For that reason, even when you try to simplify software, you just move the complexity around rather than eliminating it. 

    Introducing Turbulence

    Here is how Netflix, the organization that pioneered chaos engineering, defines the practice: “Chaos engineering is the discipline of experimenting on a distributed system to build confidence in the system’s ability to withstand turbulent conditions.” Turbulence is the opposite of order, but it’s where all systems end up.

    In the beginning of a system’s life cycle, there is always an orderly plan for deployment and operations. You always have a clean diagram of your resources, code repositories, containers and always a nice 3D diagram of AWS instances you will deploy to and the network topology. 

    In reality, our systems are never this simple. After the system goes live, that is when we start learning about how it actually operates through unforeseen events like when marketing asks to refactor the pricing module or an outage to the payments API forces you to hardcode a token or a DNS outage—well, you know about DNS outages. In the span of a year or two, you go from 300 to 800 microservices and you have to add Kubernetes clusters and a container network interface (CNI) to properly secure the networking of those clusters. And so on and so on. The bottom line? Almost all production systems evolve into a state that we do not understand and cannot easily map back to our original systems diagram. 

    Chaos engineering is a mechanism for dealing with this growing level of complexity. The basic idea behind chaos engineering is asking the computer or application or network (or any other environmental element) a series of questions. Consider a legacy system like a mainframe. How did our legacy systems become so stable? They are well-documented. Engineers feel confident in how the system operates. The question is, was the system always that way? Is the system the same one that they originally designed? The answer is “No.” 

    Legacy systems actually went through a trial-by-fire; a constant parade of unforeseen surprises. These surprises were, effectively, questions. Through these surprises, engineers learned how the system would actually operate (or wouldn’t operate) in the face of chaotic and unforeseen events. This process created iterative feedback that helped the engineers learn how to make the system continuously more stable. 

    The point of chaos engineering is to generate this same type of feedback loop without the pain, stress and repercussions of unforeseen (and generally unwanted) events. Thus, chaos engineering is a proactive way of introducing adverse conditions to ensure that the system can still do what it’s supposed to do when unforeseen events transpire. Because everything today is software and change is constant, the questioning must also be constant. 

    For example, chances are that in the time since we originally designed any given system, it has changed a lot. This means some or all the mitigation and resilience we programmed in—retry logic, failovers, circuit breakers—are old news, designed for an older system. When triggers for those conditions actually occur, those mechanisms of resilience we designed may not perform as we had intended.  

    Chaos engineers proactively ask the question, “Under the conditions in which you are designed to perform, do you do what you are supposed to?” We introduce the conditions themselves in a controlled manner with a limited blast radius to put the system to the test and verify that our assumptions line up with the intended reality. The practice of chaos engineering is intended to be performed on live, running systems without the risk of taking down critical production assets or ambushing unsuspecting applications and their associated DevOps and development teams. This helps engineering teams reduce uncertainty by building confidence in their understanding of their systems by providing them with enhanced context. It turns out that, when engineers are presented with better context, it considerably improves their ability to make smarter, well-informed decisions where resilience is concerned. 

    Chaos Engineering for Cybersecurity

    Cybersecurity is a context-dependent discipline, dependent on how well you understand the systems you are protecting.  Software engineers are constantly changing the system. And they must have the flexibility to change it because their primary task is to constantly move towards business value. Yet to effectively apply cybersecurity practices, we must know what we are trying to secure. From that knowledge, we then can know what we most need to secure and how to do it on a given system in its most current state. 

    Before an engineer can understand how to build robust security measures that provide effective cybersecurity, the engineer must first understand the system. This reliance on the “system first” is a foundational driver for why our security systems and controls—even the immutable and ephemeral ones—experience considerable engineering drift over time. We are continuously burdened by the dependence on a stateful understanding of the system.  

    Without having some sort of testing or instrumentation feedback loop in our post-deployment world, we don’t know there is a problem with our security until there is an actual problem. Finding out that the room is on fire after the house has been burning for hours is too late. The result is the self-defeating series of reactive incident fire drills, war rooms and outages that we find ourselves in today. If we do not change this reactive crisis loop of chasing the tiger’s tail, it inevitably leaves us taking two steps back for every step we take forward with engineering teams. 

    When this drift goes undetected, we are left with our wounds exposed and attackers salivating at the meal to come.  Engineers always prefer to find evidence and sources of drift through some internal engineering failure or controlled test rather than experiencing a successful real-world attack. Over time, there is a constant drift between the system and security; engineers are constantly changing the system. As a result, there is frequently a lack of recalibration between systems and the security designed to protect them. The way to achieve this recalibration is through continuous testing or experimentation. 

    Testing is not chaos engineering. Testing is a verification and validation of something you know as either true or false. This could be vulnerability to a specific CVE or exposure to an attack pattern. In experimentation, you are trying to derive new information and explore the unknown unknowns. From this exploration, you seek to create a  better understanding of how a system reacts and then share that with the people who are designing the system.

    Live security incidents are not effective measures of detection because, by then, it is already too late in the life cycle to effectively address the problem. Worse, incidents cause stress, fear and irrational behaviors. People freak out. Not surprisingly, a security incident is not a good learning environment. Yet security incidents serve the same purpose: Asking questions about a system or systems and helping teams see how to improve them. Chaos engineering offers a better way to create these questions under conditions where it is easier to learn and observe system behaviors, providing clues to improving security. In other words, the purpose of security chaos engineering is to help us proactively understand our systems and where the security gaps are before an adversary has a chance to take advantage of them.

    There are multiple use cases for security chaos engineering including:

    • Incident response: Testing efficacy of run books, response plans, and determining whether data collection and alerting systems work as intended
    • Security control validation: Introducing conditions that should induce behavior from one or more controls and observing behavior
    • Security observability: Introducing unexpected attacks or breaches to see if your systems report and observe the incident accurately
    • Compliance monitoring: Applicable across all chaos engineering events by documenting that systems do what they say they are supposed to do

    A Practical Example

    A team I headed wrote an open source application, ChaoSlingr, designed to generate chaos engineering events for security experiments. The application consisted of three serverless functions to generate the experiment, apply it to infrastructure and then monitor the resulting impact on the system. 

    One example of how we used ChaoSlingr was an exercise where we induced an open port. Enterprises and engineers inadvertently open ports in firewalls all the time. Sometimes this is a result of misconfiguration. It may also be the result of a software upgrade after which the developer or AppSec engineer forgot to reset the port to the proper security settings. In theory, firewalls should automatically detect an unauthorized open port.

    For the experiment, we selected a set of resources that had opted-in to our experiments, selected a security group and opened the port. At the time we were relatively new to Amazon Web Services. We were surprised to find that the firewall only detected an unauthorized port opening 60% of the time. We discovered clear evidence of configuration and security tool drift. 

    We also noticed that a cloud-native configuration and management tool we had deployed was identifying and alerting the unauthorized port opening almost 100% of the time. We then realized that correlating and responding to incident events of an unauthorized port opening was complicated; it was hard to map the incident back to the log data describing how our systems responded to the event. We added a metadata pointer to each alert, allowing us to more easily correlate the information and save valuable time finding the affected security group and port. 

    In short, the exercise gave us excellent context on where our systems were drifting and failing to keep up, which of our systems were the most reliable and whether we could quickly and easily respond to these incidents by chasing down the right log files. 

    Security Chaos Engineering Programs Build Trust

    In any environment where we are managing complex systems, trust is critical. You must trust that your systems will handle unforeseen events gracefully and not cost your company money or reputational currency. You must trust that the people designing and building your systems are constantly trying to improve them.  You must trust that the security teams protecting your systems are up to the task. As systems grow more and more complex, the number of unknown unknowns multiplies. As humans, with our limited processing capacity, we cannot solve for unknown unknowns at scale, continuously. This is the task of security chaos engineering and the processes around it: To create a programmatic way to experiment against and find answers to unknown unknowns. Your systems, developers, customers and your CEO will thank you for it.


    About Secure Software Summit
    The Secure Software Summit brought together the world’s leading innovators, practitioners and academics of secure software development to share and teach the latest methods and breakthroughs on secure coding and deployment practices. If you are about developing, releasing and securing software, delivering new features fast and building things right from the start, click on the link below to get access to all of the sessions from this summit.

    https://go.shiftleft.io/secure-software-summit-2022-replay


  • The Evolution of Incident Management

    The Evolution of Incident Management

    Have you ever thought about the history of incident management?

    If you’re an SRE, you might be so caught up in the day-to-day work of managing reliability and responding to incidents that you never take time to step back and reflect on the evolution of your role and your responsibilities. And that’s a shame because SREs didn’t invent incident management concepts and strategies on their own.

    On the contrary, the way SREs think about incident response, structure incident management teams and rank the priority of incidents owes much to incident management strategies developed in the offline world decades ago. To understand fully what it means to be an SRE today, you have to appreciate this deep history of incident management and response.

    So, let’s take a look at that history and examine where modern incident response concepts originated.

    Historical Problems in Incident Management

    Societies have always had incidents, of course. Fires, floods, infrastructure breakdowns and similar crises have been happening for millennia.

    For most of history, however, humans lacked an efficient, purposeful way to manage these sorts of incidents. Response efforts were ad hoc, and their effectiveness owed more than a little of their success to sheer luck.

    Particular challenges included:

    • Lack of effective, consistent communication between stakeholders.
    • Varying organizational structures which made it hard to identify leaders, coordinate response efforts and delegate tasks.
    • Inconsistent response strategies.
    • Differing approaches to assessing the priority of incidents.

    Historically, organizations may have been able to handle incidents well enough if the incidents required response from only one, small group. But the more stakeholders involved, the harder it was to respond quickly and effectively.

    Putting Out Fires: The Birth of the ICS

    Things began to change for the better when stakeholders started thinking about better ways to put out fires—literally.

    By the 1960s, fire chiefs in California realized that they were struggling to respond effectively to the wildfires that broke out every summer. Each year brought worse blazes than the last, with more land burned and more buildings lost. The Laguna fire of 1970 brought matters to a head and was the catalyst for a new approach to incident response for fire agencies.

    After assessing what was going wrong, the fire chiefs determined that it wasn’t a lack of equipment or personnel. It was poor coordination among the various firefighting agencies that responded to blazes. Lacking a clear chain of command and a systematic approach to firefighting, the agencies struggled to deploy their resources rapidly and, thus, effectively.

    To fix the problem, California fire chiefs developed what became known as the Incident Command System, or ICS. The ICS defined a hierarchy for incident response with an incident commander at the top. It also defined several categories of incident response processes including operations, planning, logistics and finance. And it established a consistent set of terms that stakeholders can use to describe their actions during incident response, which makes it easier to communicate clearly.

    Although the ICS was initially conceived to fight fires, it became the de facto standard for organizing incident response strategies of all types.

    From ICS to NIMS

    The history of incident response doesn’t end with the ICS. A new chapter began in the early 2000s when the U.S. federal government developed an even more comprehensive approach to incident management called the National Incident Management System, or NIMS.

    NIMS was born in the wake of the September 11, 2001, terrorist attacks, which underlined the importance of efficient communication not just between different agencies of the same type (like fire departments), but of entirely separate organizations. To achieve this, NIMS expanded upon the principles of the ICS.

    In addition to adopting most of the incident command principles and practices included in the ICS, NIMS included standards for coordinating the distribution of resources. It also embraced the concept of the emergency operations center, which is in some ways similar to a network operations center in the digital world.

    In some respects, NIMS resembled a compliance framework (although to be clear, that’s not what it is). It includes fourteen management principles, similar to compliance controls, that organizations must implement to manage incidents using a NIMS approach.

    Incident Management Today

    Obviously, putting out forest fires and responding to terrorist attacks is pretty different from dealing with data center failures or a buggy application deployment. ICS and NIMS weren’t designed for site reliability engineering or IT teams specifically.

    Still, the influence of ICS and NIMS on the way SREs think is clear enough. Terminology like “incident commander” comes from these frameworks. So do concepts like shared accountability for incident response processes and the importance of involving all stakeholders—not just technical teams—in incident response.

    ICS and NIMS may not be acronyms familiar to most SREs. But they should be, because they are the historical sources of the incident management philosophies that form the foundation for SRE work today and offer valuable lessons for any SRE on the job today.

  • Site Reliability Engineering (SRE) Comes of Age in 2022

    Site Reliability Engineering (SRE) Comes of Age in 2022

    The site reliability engineer (SRE) role is still gathering steam across organizations. In January 2022, LinkedIn listed SRE as the 21st job with the highest global demand throughout the past five years. That’s pretty high for such a specific tech role. And, looking to the future, it appears the SRE practice will only continue to gain adoption as a method to support high availability, reliability and improved digital customer experiences. The SRE approach is also essential to meet service-level agreements (SLAs) and internal service-level objectives (SLOs).

    I recently met with Kurt Anderson, SRE architect, and Emily Arnott, content writer from Blameless to get their take on the top trends and predictions for the SRE practice in 2022. According to the Blameless team, 2022 will likely see increased adoption of the SRE role throughout companies and across internal departments.

    Just as manufacturing sets high standards for its quality assurance, digital applications now require the same high reliability to meet inflated user expectations. To address these new realities, SREs have their work cut out for them—they must confront how to unify disparate DevOps tools and must drill farther down to unearth specific user experience qualms—all without adding to alert fatigue.

    Increasing SRE Adoption

    As mentioned above, the SRE role has seen tremendous growth in recent years and doesn’t show signs of slowing. SRE as a practice was first popularized by Google in 2015. Today, they define it simply as “what happens when you ask a software engineer to solve an operational problem.” This equates to maintaining high levels of reliability for digital services by creating errors budgets, designing SLAs/SLOs and optimizing process automation over time.

    To Arnott, we’re still seeing SRE adoption take off at an exponential rate as more and more companies embrace Google’s SRE doctrine. “During the pandemic, more and more companies were forced to adopt a digital strategy. Reliability has to be fundamental to that strategy.” Arnott foresees SRE becoming a fruitful role at startups, which may initially have been intimidated by the prospect.

    “The practice of SRE is a scale issue,” Anderson explained. It can be difficult for time-pressed companies to enact an SRE program when their attention is already so divided. However, as new requirements force warp-speed innovation, we’re seeing greater DevOps adoption. And the SRE role, consequentially, is becoming more of an imperative.

    More Unification of Multi-Tool Condition

    Most DevOps professionals would agree—we live in a multi-tool world. For example, multi-cluster management concerns are bringing a plethora of new tools to the fold. And computing environments are just as diverse, often combining multiple clouds and composed of hybrid estates that house various clusters of microservices. Even within the same organizations, different teams may opt for differing DevOps tooling. Anderson believes that SREs can bring “more unification to a fractured DevOps adoption across a single company.”

    As companies adopt more software, there’s inevitably some degree of tool sprawl, Anderson said. For example, there may be competing methods to monitor the use of digital services. The platform team may be using Datadog, an app team may be using New Relic and another team may be using Prometheus. These tools don’t speak the same language and generate different logs, creating silos.

    For Arnott, the future involves accepting the innate complexity of the microservices era and using an agnostic layer that can receive data from anywhere to identify meaningful incidents.

    Observability Gets a Bigger UX Emphasis

    The SRE role is definitely a trend that has been growing and will continue to grow in importance, Anderson said. And as more organizations turn digital, it’s becoming necessary; with this shift comes enormous pressure to exceed user experience expectations. “Competition and people’s expectations are so high right now,” said Arnott. “If you are unreliable, it’s unacceptable these days.”

    Whereas DevOps focuses more on getting applications into production, SRE takes a more UX-focused approach. Take Netflix, for example, which has invested heavily in a core SRE team that ensures robust and reliable user-facing services. “A key underpinning to keeping our customers happy and streaming is a strong focus on reliability,” according to the Netflix Technology Blog.

    To cater to this new paradigm, teams will require a deeper understanding of observability based on particular cohorts of users, said Arnott. SREs require precise user experience contexts, such as an uptick of lags or increased error responses. But they also must discover the contributing factors behind these bugs. “SLOs and error budgets are like taking your temperature—they tell you if something is wrong. They don’t tell you why you have a fever.”

    SRE Takes Cues From Manufacturing

    As reliability becomes more and more central to a company’s brand presence, it’s only natural that something that important would be elevated into the executive suite, Anderson explained. As a reference example, he pointed to the fact that manufacturing industries often appoint a chief reliability officer. In traditional manufacturing, product lines undergo a statistical process control with rigorous testing to ensure quality. Analogous positions exist across industries, such as chief quality officers in financial services.

    The takeaway is that as reliability becomes more of defining competitive metric, tech companies may require a similarly high-level C-suite position to align on that idea and to direct teams to implement SRE practices. Of course, the necessity for such a title will entirely depend on organizational size and makeup.

    Greater Reliance on SLOs to Avoid Broken SLAs

    A service-level agreement (SLA) is typically a formal contract built around the reliability of a digital service with an external partner, which, if breached, may result in financial penalties or other forms of restitution. This agreement could exist between a software provider and an end user but is more strictly enforced in a B2B context.

    On the other hand, a service-level objective (SLO) is more of an internal target. SLOs are often set at a lower threshold than SLAs. For example, perhaps an SLA ensures a user login fails no more than 10 out of one million attempts, but the SLO is set at two out of one million.

    Setting internal SLOs helps keep engineers abreast of modest customer experience issues before they become a major incident that results in fines. “Some companies treat SLOs as just another alert; they should be representative of user experience,” said Anderson. It makes sense that as SRE initiatives begin to mature, companies will slowly start to adopt even more competitive goals to deliver superior user experiences and avoid unsatisfied partners.

    Final Thought: Don’t Play The Blame Game

    A big part of the SRE doctrine is the concept of blameless postmortems. Because when you’re in the middle of an incident, the worst thing to do is point fingers. “Blaming triggers a defense mechanism and when you’re in a defensive mode, you can’t respond well,” said Anderson.

    Instead, it’s better to keep an open mind when performing these retrospectives—accept that what occurred happened for a reason, and seek to discover that reason to make positive improvements. “What can we change at a systemic level to become more resilient?” inquires Arnott. “What is the origin of that mistake? What information was lacking? What communication should have happened to prevent this?”

    Typically, accidents don’t occur intentionally or due to incompetence but rather due to holes in the process. By not playing the blame game, companies are better positioned to fix issues as they progressively release new features. Then, hopefully, with the right SRE approach in place, teams can advance their digital services to meet the high stakes of today’s modern user experience expectations.

  • 2022 Will Be the Year of the Cyber ‘Shift Show’

    2022 Will Be the Year of the Cyber ‘Shift Show’

    As ransomware continues to plague organizations across industries, remote work continues and innovation brings with it new threat vectors for bad actors to exploit, 2022 is poised to be another messy year in cybersecurity.

    In July 2021 alone, organizations lost $45 million to ransomware. What’s more, ransomware costs are projected to reach $265 billion by 2031. The firm Cybersecurity Ventures predicted that “there will be a new attack every two seconds as ransomware perpetrators progressively refine their malware payloads and related extortion activities.” But ransomware isn’t the only cybersecurity concern business leaders should be thinking about heading into the new year.

    As businesses increasingly turn to digital channels like applications and websites to drive everyday business and customer interactions, those endpoints present new threat vectors for bad actors to potentially exploit. According to Okta’s 2021 Businesses @ Work report, large organizations (think AWS, Zoom, Box) deploy an average of 175 consumer and developer-facing applications, with smaller companies averaging slightly less at 73.

    What’s more, upticks in malicious activities like application cloning, credential harvesting and app spoofing will continue to cause headaches. In 2021, organizations and consumers across all sectors were forced to confront new and emerging bad actors in cyberspace. One example: The Android banking Trojan SharkBot (first discovered in October 2021), could implement overlay attacks to steal login credentials and credit card information and could intercept banking communications sent via SMS. To date, the botnet is thought to have targeted banking applications and cryptocurrency exchanges across the UK, U.S. and in Italy.

    But there is a way that organizations can bolster their cybersecurity wherewithal today to future-proof their business against the cybersecurity threats and concerns that will proliferate in the new year: It starts with “shifting left” and embracing DevSecOps within your organization.

    Bracing for Impact

    One of the ways organizations can better prepare and defend their organizations against the rise of cyberattacks to come is by adopting a developer security philosophy known as shifting left. In other words, building security into your DevOps strategy from the start. In industry circles, this practice is also known as embracing DevSecOps.

    DevSecOps involves cultivating a flexible partnership between engineers, operations and security teams to build security into all DevOps processes. Essentially, aiming to mitigate the bottlenecks of older security models on the CI/CD pipeline. DevSecOps also requires increased communication and collaboration between development, IT and security teams to ensure that security practices like testing are done in iterations throughout the code development life cycle. According to Gartner, by 2022, 90% of software development projects are projected to leverage DevSecOps practices—a 50% increase from 2019.

    But to be sustainable, cybersecurity needs to be embedded into all facets of the DevOps process—from production to testing to deployment. But even then, it’s important to remember that DevSecOps alone isn’t a security silver bullet. It’s a starting point. And as cybersecurity becomes all the more essential to bolstering business success and resiliency, it’s the least your organization should be doing in 2022.

    DevSecOps Alone Won’t Cut It

    While DevSecOps serves as a mission-critical foundation for scaling business resiliency, it won’t equip your organization to withstand the ongoing onslaught of attacks in cyberspace alone. Since most of the time, businesses are fighting nations in cyberspace—and far too often, that’s a losing battle.

    In 2022, as threat vectors widen and worsen, it will be essential for organizations to innovate with cybersecurity top-of-mind, across all facets of the development, deployment and production pipeline. Adopting DevSecOps practices across your organization, or shifting left, is one way organizations can bolster business resiliency as we head into yet another unpredictable year in cyberspace.

  • What Chaos Engineering Is (and Isn’t)

    What Chaos Engineering Is (and Isn’t)

    The birth of chaos engineering happened somewhat accidentally in 2008 when Netflix moved from the data center to the cloud. The move didn’t go as planned.

    The thinking at the time was that the data center locked Netflix into an architecture of single points of failure, like large databases and vertically scaled components. Moving to the cloud would necessitate horizontally scaled components, which would decrease the single points of failure. But the move to horizontally scaled cloud deployment practices did not produce the boost to uptime of the streaming service that they expected.

    The specific methods for making a system robust enough to handle instances disappearing was not important. It might even be different depending on the context of the system. The important thing was that it had to be done, because the streaming service was facing availability deficits due to the high frequency of instance instability events. In a way, Netflix had simply multiplied the single-point-of-failure effect.

    Enter Chaos Monkey. Chaos Monkey gave the company a way to proactively test everyone’s resilience to a failure, and do it during business hours so that people could respond to any potential fallout when they had the resources to do so, rather than at 3 a.m. when pagers typically go off.

    Then, Dec. 24, 2012, happened. Amazon Web Services (AWS) suffered a rolling outage of elastic load balancers (ELBs). These components connect requests and route traffic to the compute instances where services are deployed. As the ELBs went down, additional requests couldn’t be served. Since Netflix’s control plane ran on AWS, customers were not able to choose videos and start streaming them.

    To ensure that all of these teams had their services up to the task, an activity was created to take a region offline. Well, AWS wouldn’t allow Netflix to take a region offline (something about having other customers in the region) so, instead, Netflix simulated the activity; labeled “Chaos Kong.”

    Fast-forward to about 2015. Netflix had Chaos Kong working on large-scale vanishing regions and had introduced Chaos Monkey, which worked on small-scale vanishing instances.

    In these early days of chaos engineering at Netflix, it was not obvious what the discipline actually was. There were some catch phrases tossed around about “pulling out wires,” or “breaking things,” or “testing in production,” paired with many misconceptions about how to make services reliable, and very few examples of actual tools to help support that work.

    To formalize the discipline, I was given the task of developing a charter and roadmap for a chaos engineering team at Netflix in early 2015. I built and managed that team for three years. My co-author of “Chaos Engineering: System Resiliency in Practice,” Nora Jones, joined the chaos engineering team early on as an engineer and technical leader. She was responsible for significant architectural decisions about the tools we built as well as overseeing implementation.

    To start, I sat down with my teams to formally define chaos engineering. We specifically wanted clarity on:

    • What is the definition of Chaos Engineering?
    • What is the point of it?
    • How do I know when I’m doing it?
    • How can I improve my practice of it?

    We researched resilience engineering and other disciplines in order to come up with a definition and a blueprint for how others could also participate in chaos engineering. After about a month of working on a manifesto of sorts, we produced the Principles of Chaos Engineering. The discipline was officially formalized:

    “Chaos Engineering is the discipline of experimenting on a distributed system in order to build confidence in the system’s capability to withstand turbulent conditions in production.”

    This definition established that it is a form of experimentation, which sits apart from testing. It also mentions “turbulent conditions in production” to highlight that this isn’t about creating chaos. Chaos engineering is about making the chaos inherent in the system visible. The point of doing chaos engineering is to build confidence.

    The principles go on to describe a basic template for experimentation, which borrows heavily from Karl Popper’s principle of falsifiability. In this regard, chaos engineering is modeled very much as a science rather than a technique.

    What Chaos Engineering Is

    The principles define the discipline so that we know when we are doing chaos engineering, how to do it and how to do it well. The more common definition for chaos engineering today is, “The facilitation of experiments to uncover systemic weaknesses.”

    The steps of Chaos Engineering experimentation are as follows:

    1. Start by defining “steady state” as some measurable output of a system that indicates normal behavior.
    2. Hypothesize that this steady state will continue in both the control group and the experimental group.
    3. Introduce variables that reflect real-world events like servers that crash, hard drives that malfunction, network connections that are severed, etc.
    4. Try to disprove the hypothesis by looking for a difference in steady state between the control group and the experimental group.

    By design, there is great latitude in how to implement these experiments.

    Experimentation Versus Testing

    Testing, strictly speaking, does not create new knowledge. Testing requires that the engineer writing the test knows specific properties about the system that they are looking for in advance. Complex systems are opaque to that type of analysis—humans are simply not capable of understanding all of the potential side effects from all of the potential interactions of parts in a complex system. This leads us to one of the key properties of a test.

    Tests make an assertion, based on existing knowledge, and then running the test collapses the valence of that assertion, usually into either true or false. Tests are statements about known properties of the system.

    Experimentation, on the other hand, creates new knowledge. Experiments propose a hypothesis, and as long as the hypothesis is not disproven, confidence grows in that hypothesis. If it is disproven, then we learn something new. This kicks off an inquiry to figure out why our hypothesis is wrong. In a complex system, the reason why something happens is often not obvious. Experimentation either builds confidence, or it teaches us new properties about our own system. It is an exploration of the unknown.

    No amount of testing in practice can equal the insight gained from experimentation, because testing requires a human to come up with the assertions ahead of time. Experimentation formally introduces a way to discover new properties. It is entirely possible to translate newly discovered properties of a system into tests after they are discovered. It also helps to encode new assumptions about a system into new hypotheses, which creates something like a “regression experiment” that explores system changes over time. Because chaos engineering was born from complex system problems, it is essential that the discipline favors experimentation over testing.

    Verification Versus Validation

    Using definitions of verification and validation inspired by operations management and logistical planning, we can say that chaos engineering is strongly biased toward the former.

    Verification

    Verification of a complex system is a process of analyzing output at a system boundary. A homeowner can verify the quality of the water (output) coming from a sink’s faucet (system boundary) by testing it for contaminants without knowing anything about how plumbing or municipal water service (system parts) functions.

    Validation

    Validation of a complex system is a process of analyzing the parts of the system and building mental models that reflect the interaction of those parts. A homeowner can validate the quality of water by inspecting all of the pipes and infrastructure (system parts) involved in capturing, cleaning, and delivering water (mental model of functional parts) to a residential area and, eventually, to the house in question.

    Both of these practices are potentially useful, and both build confidence in the output of the system. As software engineers, we often feel a compulsion to dive into code and validate that it reflects our mental model of how it should be working. Contrary to this predilection, chaos engineering strongly prefers verification over validation. chaos engineering cares whether something works, not how.

    Note that in the plumbing metaphor we could validate all of the components that go into supplying clean drinking water, and yet still end up with contaminated water for some reason we did not expect. In a complex system, there are always unpredictable interactions. But if we verify that the water is clean at the tap, then we do not necessarily have to care about how it got that way. In most business cases, the output of the system is much more important than whether or not the implementation matches our mental model. Chaos engineering cares more about the business case and output than about the implementation or mental model of interacting parts.

    What Chaos Engineering Is Not

    There are two concepts that are often confused with chaos engineering, namely breaking stuff in production and anti-fragility.

    Breaking Stuff

    Occasionally, in blog posts or conference presentations, we hear chaos engineering described as “breaking stuff in production.” While this might sound cool, it doesn’t appeal to enterprises running at scale and other complex system operators who can most benefit from the practice.

    A better characterization would be “fixing stuff in production.” Breaking stuff is easy; the difficulty lies in mitigating blast radius, thinking critically about safety, determining if something is worth fixing, deciding whether you should invest in experimenting on it—the list goes on.

    Breaking stuff could be done in countless ways, with little time invested. The larger question here is, how do we reason about things that are already broken when we don’t even know they are broken?

    “Fixing stuff in production” does a much better job of capturing the value of chaos engineering, since the point of the whole practice is to proactively improve availability and security of a complex system. Chaos engineering is the only major discipline in software that focuses solely on proactively improving safety in complex systems.

    Anti-Fragility

    People familiar with the concept of anti-fragility, introduced by Nassim Taleb, often assume that chaos engineering is essentially the software version of the same thing. Taleb argues that words like “hormesis” are insufficient to capture the ability of complex systems to adapt, and so he invented the word “anti-fragile” as a way to refer to systems that get stronger when exposed to random stress.

    An important, critical distinction between chaos engineering and anti-fragility is that chaos engineering educates human operators about the chaos already inherent in the system so that they can be a more resilient team. Anti-fragility, by contrast, adds chaos to a system in hopes that it will grow stronger in response rather than succumbing to it.

    As a framework, anti-fragility puts forth guidance at odds with the scholarship of resilience engineering, human factors and safety systems research. For example, anti-fragility proposes that the first step in improving a system’s robustness is to hunt for weaknesses and remove them. This proposal seems intuitive, but resilience engineering tells us that hunting for what goes right in safety is much more informative than investigating what goes wrong.

    The next step in anti-fragility is to add redundancy. This also seems intuitive, but adding redundancy can cause failure just as easily as it can mitigate against it, and the literature in resilience engineering is rife with examples where redundancy actually contributes to safety failures. Perhaps the most famous example is the 1986 Challenger disaster. The redundancy of O-rings was one of three reasons that NASA approved the continuation of launches, even though damage to the primary O-ring was well known internally for over fifty of the prior launch missions over the span of five years.

    There are numerous other examples of divergence between these two schools of thought. Resilience engineering is an ongoing area of research with decades of support, whereas anti-fragility is a theory that exists largely outside of academia and peer review. It is easy to imagine how the two concepts become conflated, since both deal with chaos and complex systems, but the spirit of anti-fragility does not share the empiricism and fundamental grounding of chaos engineering. For these reasons, we should consider them to be different pursuits.

    A combination of real-world experience applying the original four principled steps to experimenting on systems at scale, paired with additional thoughtful introspection, led the chaos engineering team at Netflix to push the practice further than experimentation. These insights became the “Advanced Principles,” which guide teams through the maturity of their chaos engineering programs and help set a gold standard toward which we can aspire—we’ll cover these in a follow-up post.

  • Using Chaos Engineering to Build Resilient Systems

    Using Chaos Engineering to Build Resilient Systems

    Over the past decade, chaos engineering has become one of the most popular approaches in DevOps. It’s uniquely adapted to complex cloud-based systems and has the potential to succeed where more conventional approaches may not.

    Chaos Engineering Explained

    Traditionally, DevOps teams worked with systems hosted on single servers. They would analyze logs with a fine-toothed comb, looking for potential anomalies. They implemented automated tests to ensure the system worked to spec.  They employed root cause analysis to debug applications.

    Modern systems use cloud-based distributed architectures and are much too complex for this approach to be successful; they contain hundreds, and sometimes thousands of instances.  In many cases, their behavior can be chaotic, making it nearly impossible to predict.

    Because of this, modern systems need to be designed for resiliency from the outset. Chaos engineering was developed to foster resilient system design by deliberately anticipating failure modes.

    Two Steps to Chaos

    Here’s how it works. After characterizing a state of “health” for their system, DevOps teams perform a chaos experiment. Just like physics or chemistry experiments, chaos experiments involve setting up two versions of a system: the experimental version and the control.

    The experimental system is then subjected to a barrage of virtual kicks and punches which could range from injecting faults to disrupting a data center. DevOps teams then pore through the resulting logging data, attempting to understand how the chaos experiment affected the state of the system.

    Chaos engineering has two major differences from conventional DevOps practice. First, while conventional forms of testing supply a controlled input and test for a predefined output, chaos experiments are far more open-ended. They’re designed from the outset to expect the unexpected, requiring analysis of the whole system to give novel insights.

    Second, they are performed on live systems. This makes chaos engineering controversial, as its experiments have the potential to affect real users. Still, it makes it much more powerful than alternative approaches. Chaos engineering encourages resilient design by taking genuine risks with systems in the wild.

    Why Companies Embrace Chaos Engineering

    Chaos engineering has been around for over a decade. In that time, it’s been adopted by several of the biggest names in tech. Netflix, the company that pioneered the approach, is still the most well-known for their use of fault injection.

    In 2008, Netflix was moving from an in-house data center to the cloud. They knew that, as they expanded, their application would undergo massive horizontal scaling.  Because any one of its thousands of instances could fail at any moment, it needed to be resilient.

    They created the first chaos experiment, Chaos Monkey. This worked by randomly turning off instances in Netflix’s live application to check it was fault-tolerant. This practice sounds dangerous, but it encouraged Netflix engineers to design resilient system architectures.

    Chaos Monkey sounds bananas, but it worked. In its first five years of operation, there was only one failure which was promptly fixed by an on-call engineer. That failure was caused by Chaos Monkey itself.

    Facebook is another big company to adopt chaos engineering. They created Project Storm in the wake of 2012’s Hurricane Sandy.  Although the hurricane itself didn’t affect Facebook, it served as a wake-up call. A storm hitting one of Facebook’s data centers could wreak havoc.

    In 2014, Facebook took the step of turning off traffic to one of their data centers. Although no end users were affected, traffic loading went haywire on all sorts of different subsystems.

    Once Facebook had successfully identified this weakness in their system’s resilience, they could preemptively design traffic management software that would be resilient in the face of a live data center shutdown.

    As more and more companies use cloud computing and hyperscale data centers, chaos engineering is likely to become an essential feature of DevOps strategy.

    Applying Chaos Engineering In Your Company

    Chaos engineering is the ideal approach for complex, distributed systems. Chances are, your DevOps team either runs their application in the cloud or is planning to migrate to it.

    Serverless computing, in the guise of systems like Kubernetes and Heroku, is popular with an increasing number of organizations. Now it’s common for systems to contain hundreds or even thousands of instances, hosted in massive data centers.

    So far, we’ve only seen chaos engineering from 10,000 feet. It’s time to look at how you can make it work on the ground.

    First, we need to understand the roles observability and monitoring play in chaos engineering.  To successfully implement chaos experiments, there needs to be a high level of system visibility.

    Dealing with Data

    Marius Moscovici outlines four strategies for extracting valuable insights from data. He discusses the importance of detecting anomalies in your data stream, something a chaos engineer needs to be good at.

    Whether it’s the haywire traffic in Facebook’s Project Storm or the deactivation of Netflix instances, chaos experiments rely on the ability to diagnose unusual patterns in data.

    1. Profiling Normal System Behavior

    In order to detect anomalies, you need to have a good idea of what your system normally does. In their book on chaos engineering, Netflix used the analogy of human vital signs. Just as doctors know that 98.6°F is a normal human body temperature, their IT counterparts need to characterize a “normal” state of “health” for their DevOps system.

    Many log analysis and observability tools in the market offer machine learning capabilities to help achieve this.

    2. Detecting Anomalies Across The Board

    Anomaly detection should be integrated into every step of your data analysis. You need to be able to detect anomalies across the board, not just in places you happen to be looking at. Because chaos engineering, unlike more conventional forms of testing, is designed to reveal new and unexpected information it’s vitally important to have a completely open data strategy.

    3. Data Scientists On the Lookout

    Always be on the lookout for potentially anomalous behavior. Chaos engineering will require your company to take its DevOps strategy to a new level, both in terms of your team’s mindset and the sophistication of their logging tools.

    Because chaos engineering requires you to analyze all available data without making assumptions, it’s necessary to leverage machine learning to extract patterns from your logs.  Chaos engineering requires a scientific mindset and an appreciation of the power of data.

    4. Create Alerts

    Finally, make sure that anomalous behavior is being flagged and that the team is aware when it occurs. If possible, dynamic alerts should be used to avoid false positives and alert fatigue which is common with static thresholds.

    Engineering with Chaos

    More and more organizations are migrating to the cloud and building highly distributed application infrastructures. DevOps teams are being forced to confront chaos and complexity on a daily basis.

    While the complexity of modern IT systems has necessitated chaos engineering, it has also enabled it. In a chaotic world, chaos engineering brings the order of an engineering approach.

  • Chicken Soup for the SLO

    Chicken Soup for the SLO

    Since time immemorial, humans have struggled to communicate. From myth to the modern era, our most memorable stories often involve individuals or groups seeking to be understood in order to avoid conflict. Be it the biblical allegory of Babel to the more recent Star Trek: The Next Generation episode of “Darmok,” a deep fascination with how people communicate seems to have collectively gripped our imaginations.

    It should come as no surprise, then, that communication between disparate teams and roles in the development of distributed software systems is a fascinating topic. There’s an almost primal struggle in the workplace—a dichotomy between “features” and “stability”—that teams have sought to overcome for decades. Indeed, much of the discipline of software engineering has implicitly evolved as a response to the needs of engineers to communicate with other parts of the business.

    How, then, do we improve this communication and build empathy toward our fellow developers, our coworkers, our PMs, our managers? We need a way to communicate with them, to express “how things are going,” how reliable our service or system is. Let’s step back, though, because this is only a small window we’re looking through—we need to communicate these desires and goals to a greater audience; Our bosses, their bosses, our customers, the entire world. Organizations rise and fall on their ability to communicate effectively.

    In the natural sciences, we observe that the tendency of a system is towards entropy; Energy tends to dissipate in the absence of a constraint. So, too, do human systems lose productivity as their scale and complexity increases. The rise in popularity of Agile methodologies and DevOps thinking tracks with this. They are, ultimately, designed to help us communicate better about needs and priorities. Site reliability engineering (SRE) is the latest in this line of disciplinary developments, providing rigor to the question of, “How do I operate very large scale systems in dynamic environments?”

    One of the more popularized elements of the SRE playbook is the concept of the service level objective, or SLO. To excerpt the excellent Implementing Service Level Objectives by Alex Hidalgo, a SLO is “a proper level of reliability targeted by a service,” a calculation of the amount of ‘bad’ events that can occur as part of the normal operation of a service. As Alex notes, the idea of SLOs and SRE have become almost inseparable in our collective consciousness—organizationally, it’s seen as strange to have one without the other.

    Let’s dive a bit deeper into what an SLO actually is. Again, I will excerpt and paraphrase from Alex’s book (it’s very good; you should read it if you’re interested in this topic). A SLO is simply a target, a set of defined criteria that represent some objective that you’re trying to reach. In a very general sense, the SLO expresses the threshold of ‘good’ to ‘bad’ events that you’re willing to tolerate over a time period. This simple ratio, however, unlocks a great deal of interesting and important ways of thinking about performance and reliability. It gives you, and your team, the ability to reason and communicate about reliability in a very quantitative and qualitative way.

    Now, you may be asking yourself what the qualitative component of a SLO is—after all, aren’t these measurements quantitative by definition? It’s in this dichotomy that I believe the true power and utility of SLOs lie; they’re not just a measurement of what you’re doing, they’re a communication vehicle for how you’re doing. Error budgets come out of this line of thinking—they represent the space between the current state of your SLO and its boundary.

    In plainer terms, it’s a measurement of how much you can miss your target before it becomes a problem. If my SLO targets 99% reliability, I have about three and a half days of unreliability a year to play with—or, about 14 and a half minutes a day. This way of measurement is certainly helpful in driving and determining engineering decisions, as it allows us to make snap judgements about how to prioritize the seemingly opposing buckets of “feature work” and “reliability work.” If we’re getting close to burning up our error budget for the month, do more reliability work. If we’ve got slack, do more feature work. Easy, right?

    How to Make Friends and Influence Budgets

    Reliability, SLOs, error budgets—these are all helpful ways to quantify performance and availability in software. There’s another way to consider them, though, and it’s through the lens of risk. If you’ve earned an MBA, you’re probably familiar with a ‘risk heat map.’

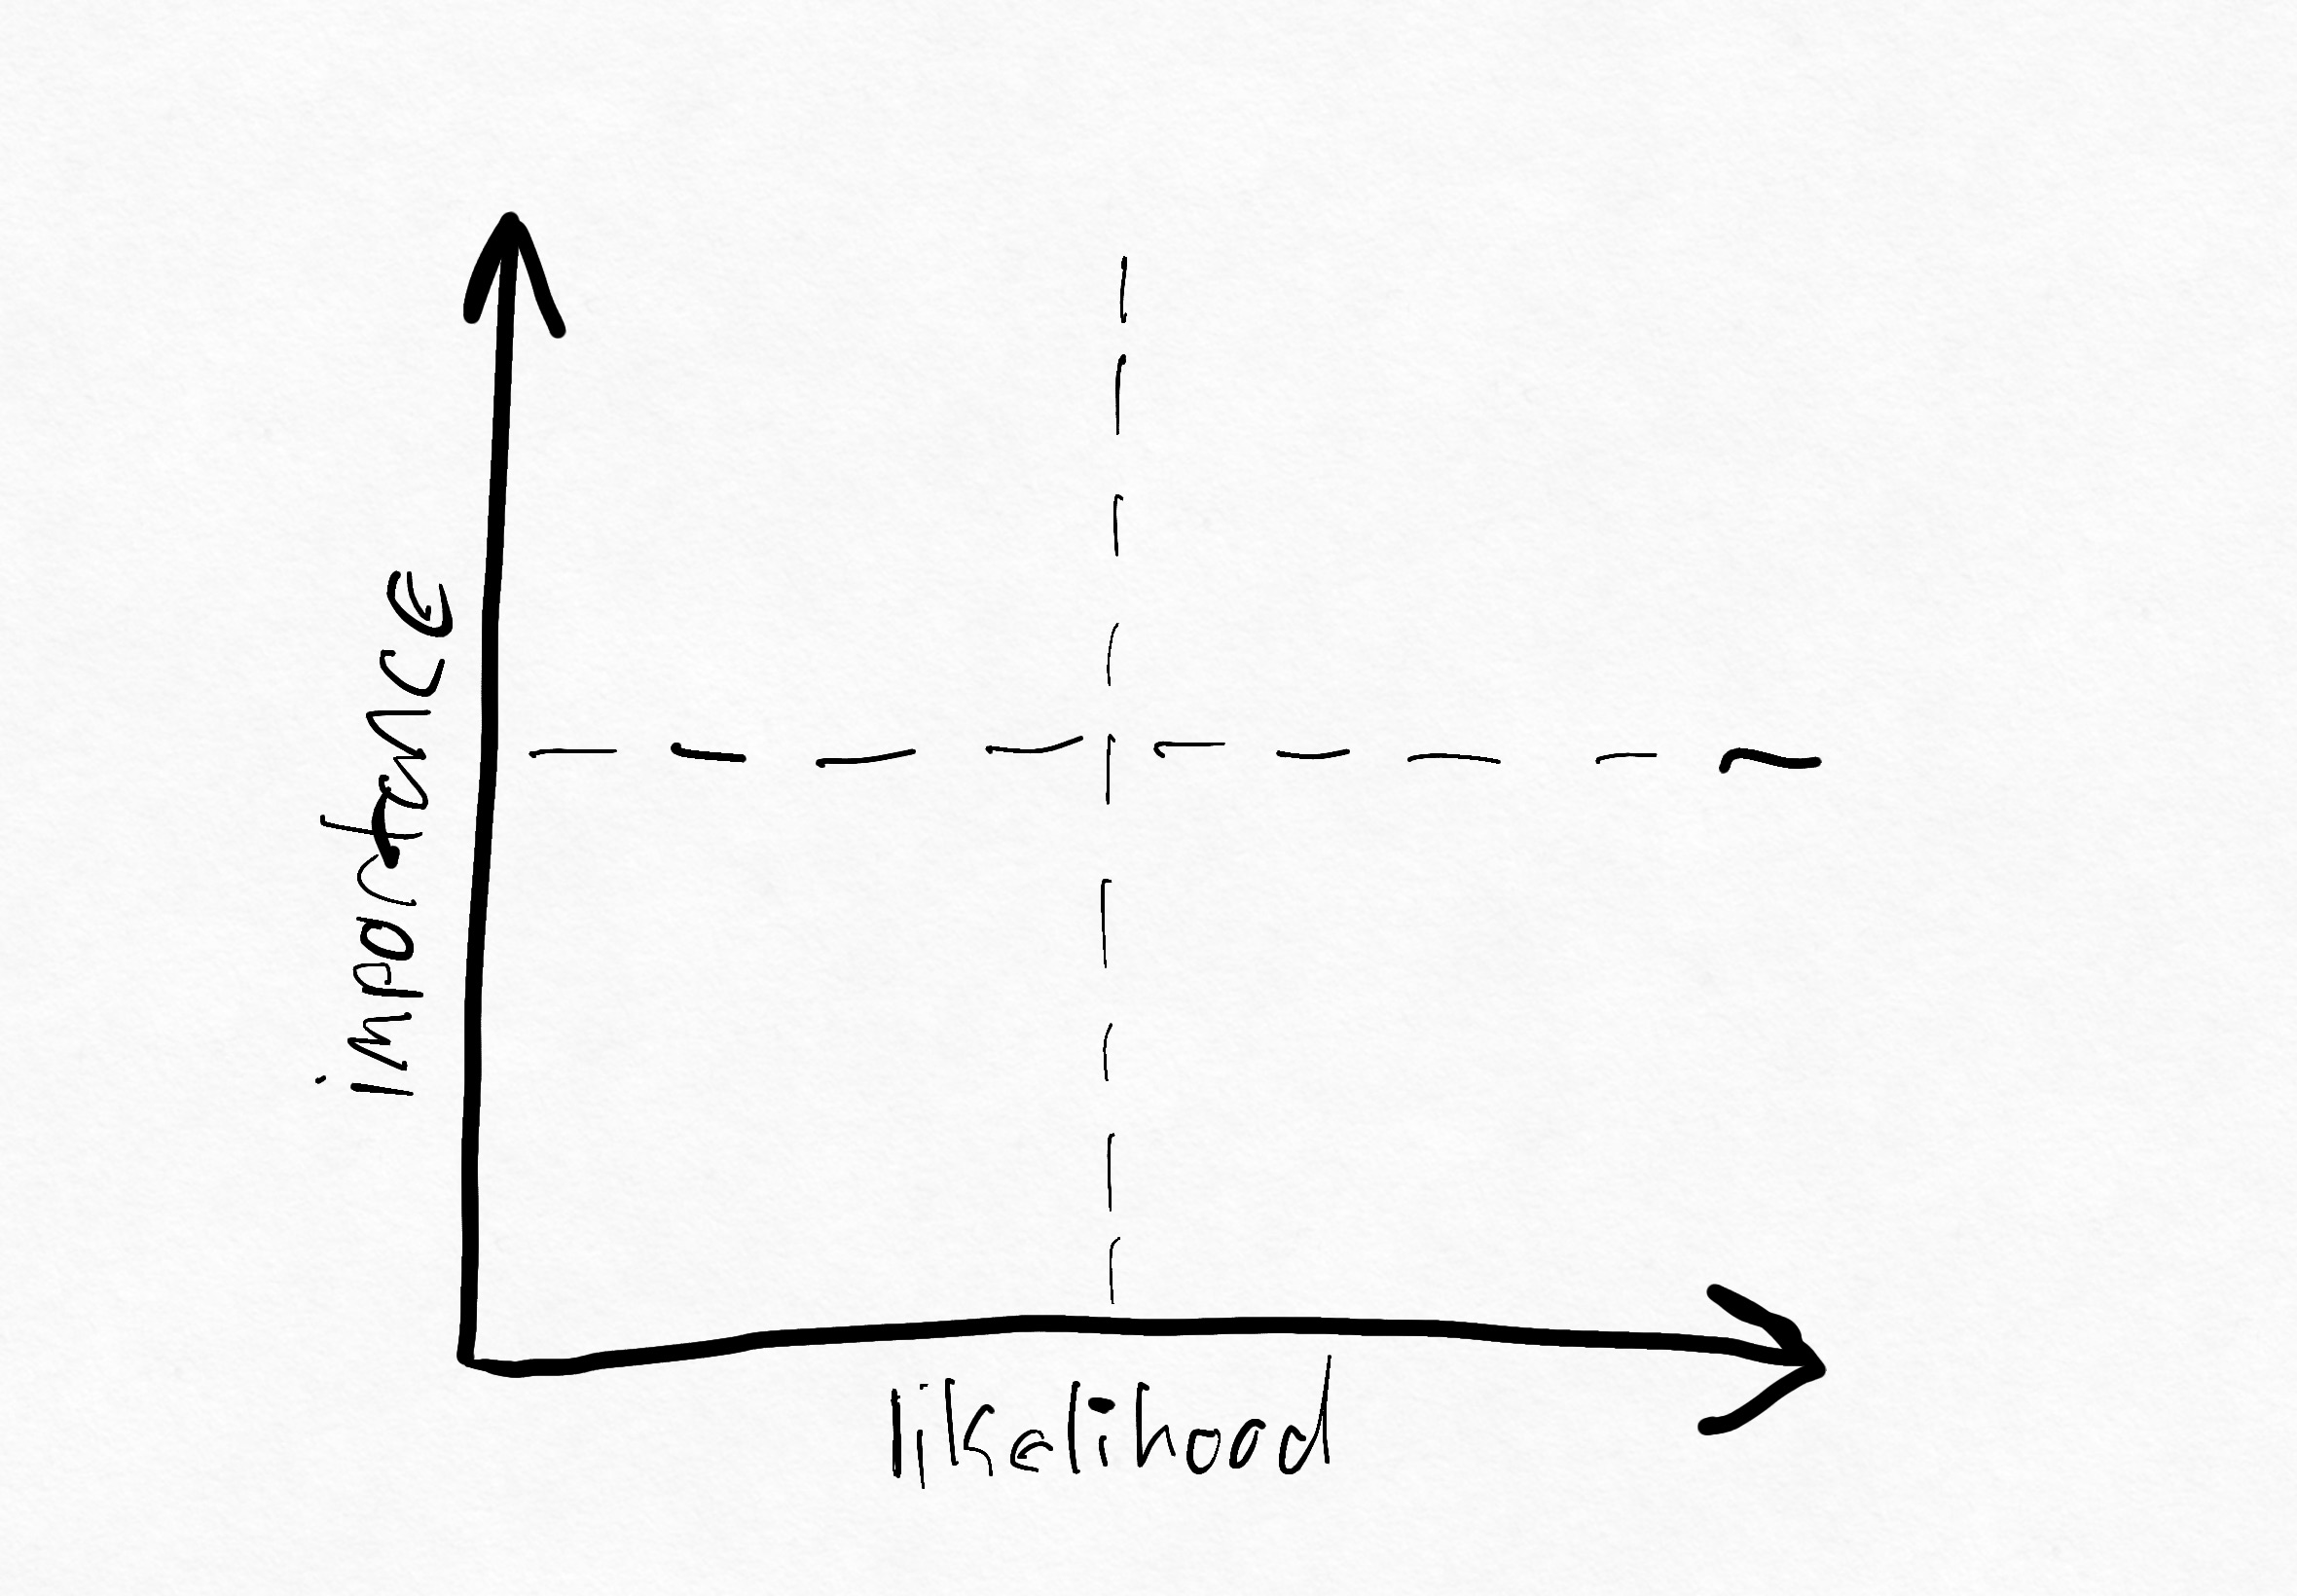
    SLO heatmap

    The x-axis on this quadrant represents the likelihood of a problem occurring; the y-axis represents the importance of that element. This is generally extensible to any element of a business—everything from your sales force to your customer success team to the availability of your data center or cloud resources.

    In many ways, this simple quadrant is responsible for many of the decisions that influence your work. While a business does many things, the business of operating a business can be thought of as an ongoing and unceasing process of risk management and abatement.

    The stuffy, MBA-fueled world of Six Sigma and process management doesn’t play terribly well in the more creative arenas of software development and maintenance, I’ve found. Much of this has to do with—you guessed it—risk. In manufacturing, the costs of failure or defects can be extremely high. Component defects can sideline million or billion dollar supply chains; projection and planning failures can disrupt just-in-time inventory and a single stuck ship or sudden winter storm can cause months or years of disruption to national or global economies. We should count ourselves fortunate that the actual costs of failure in a software system are so light; while us-east-1 going down for an hour would be bad, it probably wouldn’t wreck the global GDP for six months.

    The translation of ‘lower-level’ concerns, such as software system reliability or employee turnover, into ‘higher-level’ risk concerns acts as a curtain between the operational and the managerial aspects of a company. It is this curtain that we must consider when thinking about the true advantages, and the revolutionary potential, of SLOs. Remember, a SLO represents a ratio between ‘good’ and ‘bad’ and gives us a threshold value. These SLOs can be overlaid onto our risk maps extremely easily; SLOs for more critical services and processes rise to the top, newer services move to the right.

    In essence, we can give our SLOs a qualitative score with regard to overall business risk, and use this to shape the overall business direction. This is crucial, as in the absence of better qualitative measurements, businesses will often grasp at quantitative reliability measurements—“pages fired or tickets opened,” to quote Hidalgo. He continued, “[T]hese are prone to be inaccurate due to false positives or the whims of the people opening the tickets.” The types of measurements that we often rely on, such as categorization by severity or ‘mean time to x’ fail to accurately classify reliability or how it impacts the user experience.

    Let’s illustrate by example—a huge part of conversations about SLOs is talking about how they should be framed in terms of users; happier end users, happier engineers, happier managers and so forth. SLOs that correspond to user journeys—for instance, “Adding an item to the cart succeeds 99% of the time.”—are straightforward to understand from the perspective of an end user. We can discuss this in terms of risk by applying an importance and likelihood score to the SLO itself. If our site is an e-commerce platform, then the importance of the cart is very high. Since our threshold is very small (1%), then the likelihood of this risk is also very high—we don’t have a lot of wiggle room!

    A SLO for a targeted ad service might read, “A contextually appropriate display ad is served within 30ms 90% of the time.” In this case, our ad business might not be of high importance in terms of our business risk, so we should reduce the importance of the SLO. In addition, our threshold is very large, so we should reduce the likelihood of violation (since we have a lot more wiggle room). Over time, these positions and scores can (and should) change—perhaps the advertising segment of our business becomes more valuable, so we re-prioritize it on our risk maps.

    By speaking this language and quantifying our data in different ways, we can pull back the curtain between operational and managerial sectors and use it to influence things outside our immediate sphere.

    “Mommy, why is there a SLO in the house?”

    There’s an aphorism about war and fighting that goes, “Generals are always prepared to fight the last war.” I’ve seen this myself at every company I’ve worked for over the years—we tend to be reactive, rather than proactive, in planning and preparing for strategic business challenges. Some of this is due to the fact that none of us are oracles capable of divining the future, but much of it simply has to do with the aforementioned cycle of risk management that drives business planning and decision making. When introducing SLOs to a wider audience, you need to be able to plan for the pushback that executives and managers will almost certainly have to this new way of thinking.

    When you think about it, though, there’s not a lot of difference between what an SLO is trying to represent, and what an OKR or KPI or any other goal-oriented system is trying to represent. In each case, we’re creating some heuristic to sort events into ‘good’ and ‘bad’ cases, then creating a threshold of ‘Now there is a problem’ based on the ratio between them. In essence, this is, really, how you measure anything as a percentage.

    You could translate goals for your sales, marketing, customer success or people ops teams into SLOs. For example, “30% of POCs should convert into closed-won opportunities” is, basically, an SLO already, and is perhaps an existing goal for your salesforce. There are two big advantages to thinking about these as SLOs: consistent reporting and error budgets.

    Consistently reporting on SLOs means that you can express team and company goals in the same format and language across the entire organization. This brings teams together in a shared purpose, and allows for a shared language about how reliability benefits everyone. Being able to roll up reporting about how things are going not only encourages more shared ownership of goals, it helps you build connections and linkage between how different types of work align with each other towards a shared prosperity. More importantly, SLO reporting gives extremely clear signals about how teams—regardless of their function—should be addressing failure.

    If a consistent language around reliability is what builds empathy, error budgets are what unlocks creativity and problem solving for addressing issues in the business. In too many cases, organizations are loathe to give individual contributors, or even teams, the flexibility to experiment and measure the results of those experiments due to inertia, top-down command-and-control style processes or just the fear of screwing up.

    Let me give you an example—suppose your marketing team has a demo that generates a certain percentage of leads every month. Without a defined SLO for this demo’s performance, it becomes extremely difficult to change anything about how this demo works. Why? Because there’s a tendency for things to settle at their current state—we’re all so consumed with moment-to-moment crises or new work that evaluating the performance of existing things can be challenging.

    The work required to justify a change eventually outweighs the actual work being done to make the change, and so change withers on the vine and processes stagnate. Now, imagine that this demo flow had an SLO associated with it, something like “10% of clicks to our demo should result in a valid email capture.” Suddenly, we can report on this in a consistent fashion and, more importantly, we have a massive amount of headroom for experimentation. We can justify work being done to improve this flow in the context of not only its current status (are we running better or worse than our target?) but also in the context of our other goals (are we producing enough MQLs, in general, to support the sales funnel?) and prioritize appropriately.

    Ultimately, we can’t change the fact that there’s a bias towards dealing with the last thing that happened, but that’s not really the point. What we can change is how we think about expressing what’s happening now, and building a consistent language and verbiage around addressing these problems. SLOs are designed, broadly, as a way to communicate the reliability goals of complex distributed software systems. What is a business of people other than a complex distributed human system?

    As thinking, tooling, and processes around SLOs continue to mature (such as the recently announced OpenSLO specification), I’m excited to see what the future has in store for us. At the end of the day, we should be striving to reduce hierarchy, increase autonimity, and build collective ownership in the socio-technical systems that we rely on as human beings; SLOs are just another piece of this ever-evolving puzzle.

  • 3 Reasons Why Automation is Critical

    3 Reasons Why Automation is Critical

    We’re hearing a lot about the “outcome economy”—how businesses must be results-oriented to meet evolving customer demand and gain greater market share. Today’s marketplace is connected, always on and increasingly competitive. Companies are adopting what we call an “as-a-service” approach to achieve better outcomes fast, consuming and leveraging leading-edge technologies such as cloud and automation.

    As IT systems grow exponentially, and cloud solutions proliferate, non-automated, manual systems increasingly are becoming a major business liability. Today’s systems are simply becoming too big and complex to run completely manually, and working without automation is largely unsustainable for many enterprises across all industries.

    Automation involves a set of tools, processes and insights that allows IT environments to self-modify and adjust, and some enterprises have started using intelligent automation to drive a new, more productive relationship between people and machines.

    For example, IT automation is often used to auto-scale and load-balance large fleets of servers, manage global content distribution based on geographic demand, enable self-healing of IT systems and manage security mostly with limited ongoing manual intervention.

    Moreover, automation enables the ability to adapt and improve the service experience without manual intervention. However, while these tools offer new strengths and capabilities, they are meant to complement and enhance human skills.

    Effective automation depends on adequate insights collected from all the systems relevant to the service experience and business outcome you’re trying to augment. Insights from data is necessary to create opens paths to automated predictions and ultimately using machine learning, or artificial intelligence, as part of a full scope the as-a-service construct.

    Specific insights known as telemetry allows signals to be harvested and interpreted so automation can better adjust production systems to maintain a healthy business. The insight gathered from such analytics allows automation to validate and compose modification rules. For example, sensors that detect a supply chain issue could automatically reroute or fine-tune related functions, such as dispatch or logistics, to solve or generate a workaround for the issue. The business flow can adapt and realign automatically with the ultimate goal of improving the customer experience.

    Automation Creates High Resiliency

    Two common business outcomes that depend on efficient automation are highly resilient systems and experimentation platforms.

    Highly resilient systems include automation that can detect, avoid, heal and remediate any deviations from normal, healthy business function. To detect deviations, automation capabilities need to understand what the “steady state” of the system is and what constitutes the “health” of the system under varying conditions. For each detected deviation from an established steady state, a specific automation is triggered that attempts to return the system back to the steady state.

    The best way to determine if resiliency automation works effectively is through a process known as “fault injection.” Highly resilient systems run under constant fire drills in which operations insert faults into the system while developers continuously build responding resiliency automation.

    Automation also can provide a higher degree of experimentation and increase agility, two key attributes of as-a-service economy. Automatically provisioning a component such as a virtual machine, for example, is only a piece of the puzzle since automation is most valuable when it contributes to improving a customer experience or delivering a business outcome.

    A platform that’s constantly testing, experimenting and developing allows companies to try new ideas in production quickly without fear of failure or outage. When confidence in system resiliency is high, it allows businesses to test new things directly in production (A/B testing). If an experiment fails, there is no harm done as automation returns the system to steady state. If an experiment succeeds, it is quickly absorbed into the production itself.

    A fast, efficient experimentation platform enables businesses to react faster to failures and successes—and pivot accordingly without excess wasted resources. For example, a retail company might change a shopping basket feature for 1 percent of its customers. With constant measurement and instrumentation, the company can automatically derive insights, determine if the change is effective and create a chain of automated reactions. If, say, the demand spikes for a new offering based on a limited customer pilot, the system can reset stocking levels ahead of geographic or further customer segment rollout. This ability increases a company’s agility and adaptability, improving the customer experience and delivering on the most important factors determining success in today’s as-a-service business environment.

    Moving forward

    In this fast-paced marketplace, it is becoming clear that automation is the next critical step in IT maturity—building trust into IT systems and enabling innovation of new capabilities.

    However exciting, impactful and resourceful automation is, it is important to note that automation will not replace people. Machines and artificial intelligence will be the newest recruits to the workforce, bringing new skills to help people do new jobs, reinventing possibilities across the business spectrum. The companies that succeed with automation take a “people-first” approach, adapting their enterprise’s organization, culture, skill and experience to use automated technology.

    Although automation becomes critical to stability when systems grow to global scale, it also provides great benefits to smaller systems. Every modern enterprise should start thinking about an automation strategy. Companies that aren’t experimenting with automation are going to be outpaced quickly by the competitors that are quick to analyzing data, yielding insights that make their processes more agile and unchains their systems and infrastructure from undue age-old complexities.

    About the Authors

    Marshall Wells_PhotoMarshall Wells, Managing Director, Hybrid Cloud

    Marshall Wells is a managing director at Accenture, focusing on Accenture’s Hybrid Cloud platform. He holds an MBA in Finance from theUniversity of California, Berkeley and a BS in Chemical Engineering from Colorado School of Mines.


    Miha_PhotoMiha Kralj, Managing Director, IT Strategy and Cloud Computing Transformation

    Miha Kralj is managing director at Accenture, where he is responsible for Accenture’s IT Strategy and Cloud Computing Transformation platforms. In this role, Kralj helps to define core cloud strategies that help clients transform traditional IT, creates and delivers IT transformation programs, and identifies the right cloud disposition for various workloads.

    Prior to assuming his current position in 2015, Kralj served as principal architect at Amazon Web Services, leading the domain of IT Transformation and modern IT delivery. Before that, he was senior technology director at Microsoft, where he designed Enterprise Architecture offerings through assessments, planning and value realization.