Tag: Puppet

  • Puppet: Best Practices

    Puppet: Best Practices

    This is 4th part of the multi-part series covering Automation, provisioning and Configuration Management. In this article best practices for Puppet shall be covered.

    Puppet, one of the most well-liked configuration management tools, can also turn out to be complicated at times. In this post I’m going to briefly go through a few practices that have emerged as good, recommendable and high-level best practices. I would like to share some of them with the world so that the beginners get an advanced start.

    1). Use Modules when possible:

    Puppet modules are something everyone should use. If you have an application you are managing, add a module for it, so that you can keep the manifests, plugins (if any), source files, and templates altogether.

    2). Keep your Puppet content in Version Control:

    There is NO reason, not to use a version control system while developing puppet manifest/modules. You can pick your favorite systems — popular choices being Git, Mercurial or Bazaar which prove to be particularly useful due to the ease that they provide in managing multiple branches of code.

    Version control is well-supported by the Puppet ecosystem. It is possible to use a mature Software Development Lifecycle to manage the development and maintenance of your Puppet manifests, tightly integrated with a branch-based workflow that truly realizes the ideals of “infrastructure-as-code.”

    Using version control helps in opening up of lot of additional possibilities with puppet, like better tracking of changes, testing your Puppet manifests in an isolated environment, promoting your configuration from environment to environment, etc. Version control even provides a free backup for your configuration code.

    By making a use of a collaboration tool like Github or Bitbucket, you and your team can easily revise each of the changes separately before they are applied. This results in much better, more sustainable Puppet code. Placing all your Puppet files under version control is counted as one of the best Puppet practice and whenever you are ready to “deploy” any kind of changes to your Puppetmaster, you just have to sync the working copy on the server with the code in the version control repository.

    3). Make use of Environments:

    Environments are isolated groups of Puppet agent’s nodes. A Puppet master server can serve each environment with completely different main manifests and module paths. Puppet has this concept of Environment that helps in applying your configuration changes on less critical servers first and after the changes has been tested and ready, then promoting those changes to production. This frees you to use different versions of the same modules for different populations of nodes, which is useful for testing changes to your Puppet code before implementing them on production machines.

    Staging and production are two Puppet environments that are used where Staging environment is used at an initial provisioning of a server to all pre-production boxes and production servers make use of the Production environment. Both environments are tied to a specific branch in Git repository i.e., “master” branch in Git is production and “staging” branch is staging.

    4). Use dry-runs:

    Even with the best precautions taken, sometimes your Puppet manifest doesn’t do exactly what you expected. Things can get messy at times whenever you actually get to run the Puppet agent to apply your configuration updates on your servers. For example, if it would update a config file and restart a production service this could result in unplanned downtime. Also, sometimes manual configuration changes are made on a server which Puppet would overwrite.

    To reduce the risk of problems, you can use Puppet’s agent in “dry run” mode (also called noop mode, for no operation) using the following options:

    puppet agent […] –verbose –noop –test

    By making use of this practice you will be able to see the difference for all files that would modify as well as validate things according to your expectation. It will help Puppet agent to only show what it would do, not what it did.

    5). Managing Puppet modules with librarian-puppet:

    Handling module dependencies can sometimes become a source of worries, especially when several numbers of people are working on Puppet code and each one demand to test it on their own computer. Librarian-puppet is a bundler for your puppet infrastructure that helps in providing sanity to the process by automatically managing your module dependencies.

    Librarian-puppet manages your modules/ directory based on your “Puppetfile”. The tool will install, update or remove modules automatically when you run it, always matching what’s specified in the Puppetfile. Your Puppetfile becomes the authoritative source for what modules you require and at what version, tag or branch.

    Once using Librarian-puppet you should not modify the contents of your modules directory. The individual modules’ repos should be updated, tagged with a new release and the version bumped in your Puppetfile. It will help resolving and installing modules’ dependencies and become aware of compatibility issues.

    Librarian-puppet simplify deployment of your Puppet infrastructure by automatically pulling in modules from the forge and git repositories with a single command thus saving you from installation and managing your modules manually. Deployment normally comes up with following two simple steps:

    • Sync your main sources with your code repository (ex: git pull)
    • Run librarian-puppet to synchronize your installed Puppet modules

    Don’t use Git dependencies with any version specifier

    6). Keep sensitive data safe:

    Today Data security is the key concern for any organization. Some data always needs to be kept safe. For example, for maintaining the data security it may be required to put in your Puppet code in passwords, private keys, SSL certificates and so on.

    Don’t put Puppet code in version control unless you’re absolutely aware of the risks you’re taking while doing so.

    If you’re already a bit familiar with Hiera which is a Puppet tool, you know why it’s a good idea to separate your data from your Puppet manifests. In case you aren’t familiar, though, using Hiera leases you write and use reusable manifests and modules. After you store your organization-specific data in Hiera, Puppet classes can request the data they need from your Hiera data store.

    Hiera allows you to store data about your servers and infrastructure in YAML or JSON files. From usage, you’ll see that most data in Hiera files is not confidential in nature… so should we refrain from using version control for Hiera files just because of a few elements that are unsafe? CERTAINLY NOT!!!!!!!!!!!!

    The trick is to use Hiera’s ability to combine multiple data sources or backend

    or

    What you can do is split Hieradata files into 2 types: YAML files for your “main” Hieradata files and JSON files to store your “secured” data. Those JSON files are not to be put under version control and are stored securely on a single location i.e., “the Puppetmaster”. This way, very few people can actually see the contents of the sensitive files.

    7). Producing abstractions for you high-level classes:

    Wrapping up all the uses of modules into a covering or let’s say into a wrapper classes provides higher-up maintainability of the Puppet code in time. For example, Assume you want to setup a reverse proxy server using an existing Nginx module. Instead of directly assigning the ‘nginx’ class on your nodes and setting all of the required stuff up, create instead a new class called, say, ‘proxy_server’ with the attributes you want to consider for your proxy server as class parameters. Assigning the ‘proxy_server’ class on your node not only better states your intent, but it also creates a nice little abstraction over what you consider as a “proxy server”. Later on, if you decide to go away from Nginx (highly improbable) or use another Nginx module (more probable!), then you’ll probably just need to change the content of your “proxy_server” class, instead of a bunch of tangled node definitions.

    In the End:

    Puppet isn’t the only Configuration management (CM) tool available, but it is the most mature, with a large community of active module developers. Implementing these practices will help you in getting the most out of the Puppet.
  • 31 Reference Architectures for DevOps and Continuous Delivery

    31 Reference Architectures for DevOps and Continuous Delivery

    At QCon London, David Farley (@davefarley77) told the audience that “continuous delivery changes the economics of software delivery”.  I could not agree more.

    If you have been drawn to the evangelists like David Farley, Jez Humble, and Gene Kim, you’ll know that high performance IT organizations are seeing a massive payoff in their continuous delivery investments.  Industry leaders big and small are sharing noticeable results:

    • 8x more frequent production deployments
    • 50% lower change failure rates
    • 12x faster service restoration times when something went wrong

    5 Principles

    How are they achieving these results?  They are following a few key principles that David and Jez outlined in their seminal book, Continuous Delivery (highly recommended).  The principles outlined in their book and in David’s QCon presentation are as follows:

    • Deliver fast
    • Automate almost everything
    • Keep everything in version control
    • Build quality In
    • Empower the team 

    Reference Architectures for DevOps and Continuous Delivery

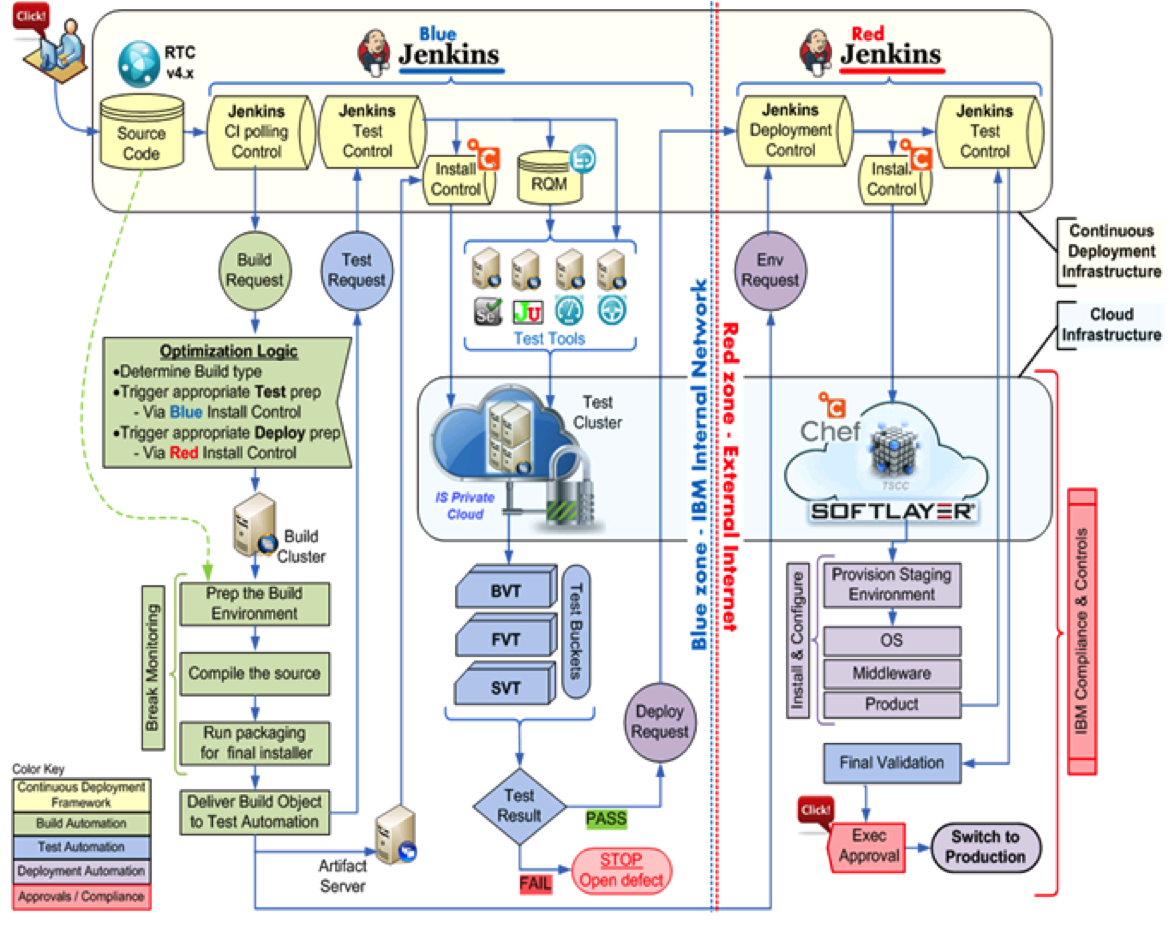
    In their book, they also provide insight to continuous delivery tool chains and processes which highlight build tools, CI platforms, testing suites, artifact repositories, and many other components. There are numerous examples of reference architectures available, and each of them vary in levels of detail, tools highlighted, and processes followed.  Yet, there is a constant theme among the tool sets: Jenkins, Maven, Nexus, Subversion, Git, Docker, Puppet/Chef, Rundeck, and Sonar seem to show up time and again.

    To help you along your continuous delivery and DevOps journey, I have compiled a set of 31 reference architectures created by users across the continuous delivery and DevOps communities.

     CD and DevOps tool chain

    Each architecture is accompanied by a link to the original presentation or blog where the architecture was referenced to ensure you have access to the full context of the discussion. You can also freely download the presentation from SlideShare where we now have over 7,000 views.

    Offer to help others: If you have a reference architecture to share, please consider posting a link to it in the comments section below.  I am sure others would love to see it and learn from it.

  • Automation, Provisioning and Configuration Management with PUPPET

    Automation, Provisioning and Configuration Management with PUPPET

    This is 3rd part of the multi-part series covering Automation, provisioning and Configuration Management. In this follow up article best practices for Puppet shall be covered.

    Why Puppet?

    While every system administrator comes up with more progressive systems to be managed, the automation of every mundane task is increasingly significant.

    Instead of achieving in-house developed scripts, it is necessary to share a system that can be used by everyone, irrespective of one’s employer. But undoubtedly, this is not possible manually.

    So, Puppet has been developed to benefit the sysadmin community in building up and sharing of all mature tools, which prevent the replication of a problem which is being resolved by many.

    Following are the key methods followed by Puppet:

    1). It supports a powerful framework, and is responsible for simplifying most of the technical tasks required to be done by the sysadmin.

    2). The sysadmin’s work is written in form of code, easily sharable as the other pieces of code, in the puppet’s custom language.

    The Puppet usage accelerates your work as a sysadmin, as it supervises and handles all the details. You can download the code from other sysadmins to help you get your work done even faster. Most of the Puppet implementations make use of one or more modules already developed by others. One can find hundreds of modules developed and shared by the community.

    What is Puppet?

    Puppet is an open-source IT automation tool developed by Puppet Labs. Its written in Ruby; composed of a declarative language for expressing system configuration; a client and a server for distributing it; and a library for realizing the configuration. Puppet helps in automation, deployment and scaling of applications in the cloud or on site.

    The basic design objective of Puppet is to come up with a powerful and expressive language backed by an influential library that makes you write your own server automation applications in just a few lines of code. Its intense adaptability and open source license lets you add up the required functionality. And, you can also share your innovations with others.

    System Components:

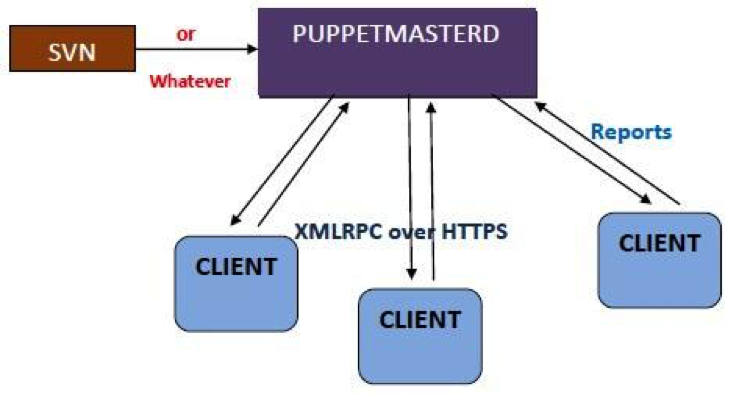
    Puppet in general is used in a client/server formation, with all your clients talking to one or more central servers. Every single client contacts the server at regular intervals i.e. every half hour, by default. It even downloads the latest configuration and makes it sure that it is in sync with the configuration. The moment it’s complete, the client is able to send a report back to the server and can also refer to the changes required.

    Following diagram displays the data flow in a usual puppet operation:

    Puppet1

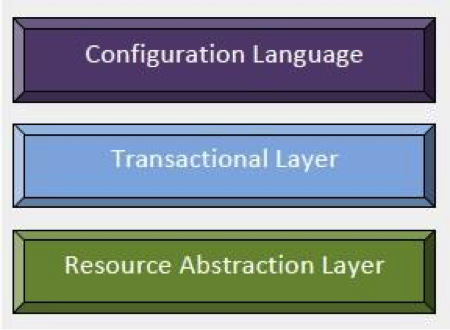
    Puppet’s functionality is framed as a heap of individual layers. Each layer is duty-bound to a fixed aspect of the system with a tight control on how information transfers between these layers.

    puppet2


    Fig2

    How Does Puppet Work?

    The Puppet agent acts as a daemon that runs on all the client servers where configurations are required, and the servers to be managed by Puppet in the future. Now all the clients to be controlled will have puppet agent installed in their systems. This puppet agent also known as a node in Puppet will have a server designated as the Puppet master.

    Puppet Master: This machine restrains the entire configuration for different hosts, and runs as a daemon on this master server.

    Puppet Agent: This is the daemon that will run on the entire server that is to be managed with the help of Puppet. At a specific time interval, the Puppet agent will go and inquire the configuration from the puppet master server.

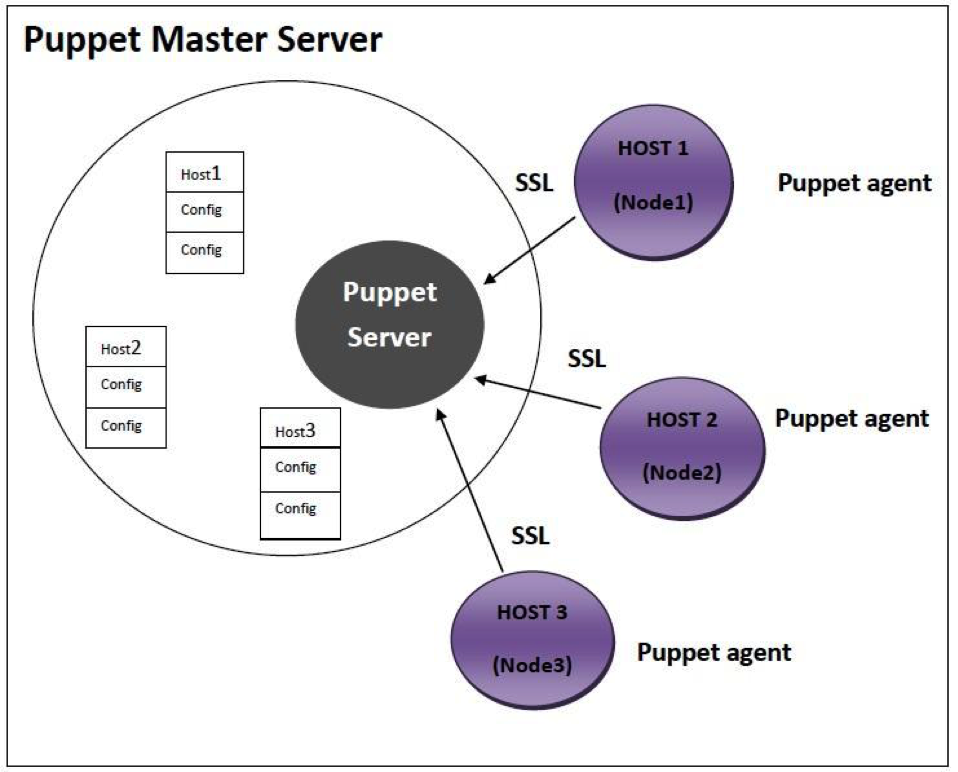
    Now the connection network between the puppet agent and master is built in a secure encrypted channel with the support of SSL. For example, if the Puppet agent has already applied for a necessary configuration and there are no new changes, it will do nothing. By default, the puppet agent will go and fetch the required config data from the puppet master in every 30 minutes.

    From the above diagram it is clear that puppet master server has all the configuration options available for Host 1 or Node1, Host 2 or Node 2 and Host 3 or Node 3.

     puppet3

    Following are the steps that are always followed whenever a puppet agent of any node makes up a connection between a node and a puppet master server to fetch the data.

    Step 1: Every time a client node makes a connection to the master, the master server examines the configuration to be applied to the node.

    Step 2: The Puppet master server takes and assembles all resources and configurations be applied on the node, and brings it together to make a catalog. Now, this puppet is given to the puppet agent of the node.

    Step 3: According to the catalog, the Puppet agent will apply configuration on the node and then reply. It will also submit the report of the configuration applied to the puppet master server.

    Who would find Puppet useful?

    An organization that would like to decrease the cost of maintaining its computers could benefits from using Puppet. Since the return on investment is related to several factors such as the current administrative overhead, diversity among existing computers, and cost of downtime. It might be complex for an organization to determine if it should invest in any configuration management tools, much less Puppet.

    In general, any organization should make use of server automation if any of the following are true:

    1. It comes up with a higher server administration costs
    2. Either because of contracts or opportunity cost, it pays a high price for downtime.
    3. It contains loads of servers that are fundamentally identical or nearly identical.
    4. Flexibility as well as agility is required in server configuration.

    Conclusion:

    Puppet refers to the two different things

    • The language in which code is written
    • The platform that manages infrastructure.

    Puppet is both a simple and a complex system. It is composed of several moving sections wired all together quite loosely. It is a structure that can be used for all configuration problems. Our future success rests on the structure becoming more powerful and simple, for it should be   approachable while gaining capability.

  • Puppet Labs talks Docker and containerization

    Puppet Labs talks Docker and containerization

    Last week Puppet Labs released a new version of Puppet Enterprise that brought forward a number of new features, including those to Puppet Node manager that helps automate the provisioning of infrastructure from containers to bare metal, as well as a new AWS module that helps automate provisioning, configuration and management of AWS resources using Puppet. As a part of the release, Puppet announced it was officially supporting a Puppet module for Docker that has been kicking around Puppet Forge since the containerization tool went open source.  With 90,000 downloads behind it and many more customers clamoring for advice on how to better automate workflows in Puppet-controlled infrastructure while using Docker, the module had gained critical mass. devopsy.kinsta.cloud took the announcement as an opportunity to catch up with Gareth Rushgrove, senior software engineer with Puppet and author of the Docker module, to discuss containerization and how Puppet is working to help customers take better advantage of container environments.

    What do you consider some of the biggest challenges when deploying containers in the real world? And how is Puppet Labs hoping to help customers get the most out of Docker?

    I think the first thing is really just…


    –THIS STORY HAS BEEN MOVED TO CONTAINER JOURNAL–


  • 11 DevOps start-ups funded for a busy 2015

    11 DevOps start-ups funded for a busy 2015


     Slides

    [seoslides embed_id=”4b8ee43e173e” script_src=”https://devopsy.kinsta.cloud/embed-script/11-devops-start-ups-funded-busy-2015/title/” overview_src=”https://devopsy.kinsta.cloud/slides/11-devops-start-ups-funded-busy-2015/” site_src=”https://devopsy.kinsta.cloud” site_title=”devopsy.kinsta.cloud” title=”11 DevOps start-ups funded for a busy 2015″ /]
    Advance slides with arrow buttons or touchscreen

  • Scripts or Machine Images, What is the Best Way to bootstrap

    Scripts or Machine Images, What is the Best Way to bootstrap

    Between the advent of handy tools, like Chef and Puppet, and virtual machine infrastructures, like VMWare and AWS, I feel like there has been a great debate about how to bootstrap machines.   It seems like there are two extremes.  On one side is heavy reliance on machine images (AMIs, in AWS speak) or scripting (recipes, in Chef speak) on the other with a bunch of grey in the middle.  Naturally, there are pros and cons with each so let’s explore them.

    Machine Images

    The great thing about machine images are you get from zero to a fully functional machine in the time it takes to create the virtual machine.  This can be an extremely valuable thing when you need to spin up or down quickly.  However, they become dated with the rate at which your configuration changes.

    Scripts

    With the all scripts approach you are immune to the out of date issue encountered with machine images.  The big drawback is that it can take a long time to spin up a new machine off of scripts, especially when you have to compile one or many components.  In my opinion, this approach is most valuable when your system configuration changes quickly and there is some tolerance with regard to spin latency.

    Either approach is suitable for things like auto-scaling and unlocks the elasticity of the cloud, so which is the best?  To help you decide on which approach, or blend there of, best suits your situation. These may seem obvious, but I think you must weigh three major trade-offs or benefits afforded by scripting or imaging.

    • Time to being service ready

    How much time can you afford to spend from the time you start bootstrapping a new machine until handling live traffic?  To meet our on-demand scale requirements, at Clip, we have a target of 10 minutes from when the virtual machine is requested to handling live traffic.

    • Resilience to change

    How dynamic is your environment?  How often are new services deployed, dependencies added, or code deployed?  At Clip, we add new services on a fairly regular basis and our systems change frequently from both the code and dependencies stand point.

    • Cross platform support

    How many platforms do you need to support?  Platform, in this case, could be interpreted as operating systems, cloud providers and/or virtual or physical hardware.  To date we have been able to minimize any cross platform issues.

    Since we value flexibility and have the luxury of an acceptable spin up time of 10 minutes, we have chosen to lean heavily on Chef for our bootstrap process and only use basic machine images.  However, as the product and business requirements evolve, the time to being service ready is gaining more emphasis, so our process will also change.  At other companies, spin up time is so important, their CI system builds a new machine image for each version of the product that is deployed, so they can scale as quickly as possible.  Regardless of the technology or process used, it is most important to satisfy business needs in terms of service ready time, resilience to change and cross platform support and continue to adapt as the requirements change.

  • DevOps with Purpose: It’s about your tools!

    DevOps with Purpose: It’s about your tools!

    This is Part Three in a four-part series. In Part One, I focused on the critical first step of defining DevOps with a purpose by thinking about DevOps in the context of your organization’s applications. In Part Two, I provided four tips to fostering a DevOps culture in your organization.

    By now you’ve hopefully noticed the emphasis on “your” in this series, because, at the end of the day adopting DevOps is about your business, your applications, and your culture. In this third part of the series, I’m going to discuss your tools.

    In IT, we’re indundated with tools. Developers have their favorite tools and sys admins do too, so do the project office, the service support group, and the QA team. There are IT tools purchased by our organization years ago that we are using and others we aren’t, tools we’ve recently started using, and others we are considering at any given point in time. There are also general-purpose tools the company wants us to use for things like document sharing, instant messaging, and so on. It’s got to the point where a lot of IT organizations say, “we have two of everything like Noah’s ark”, yet they still want more tools.

    Part of the reason is that, as IT practitioners, we like gadgets and tools. We like the fact that they can help us do things and can amplify our own abilities, but we also know they can fragment information and can blindside us when someone uses a tool to do something that others weren’t aware of.

    Do we really need more tools to do DevOps?

    DevOps has a close association with the Agile Software Development movement, and one of the core tenets of the Agile Manifesto is to value “Individuals and Interactions over processes and tools”. Nevertheless, it’s hard to find a DevOps talk or article that doesn’t discuss the need for tools like git, docker, jenkins,  puppet, chef, and so on. The reason for this is actually pretty straight-forward: continuous integration and continuous delivery are best done through automation so we can follow a repeatable method and roll things back quickly if there are issues.

    At a more basic level, however, we need to acknowledge that there are really two types of tools:

    • Tools that help us amplify our abilities as individuals (e.g. I can drive a nail into a board with a hammer much more effectively than with my hand or a rock because of the strength of the hammer’s material and the principle of leverage)
    • Tools that help us coordinate work across many humans, thereby, amplifying our individual abilities (e.g. I can build a house much faster and with better quality by leveraging different experts’ skills and using a shared set of blueprints for building construction, plumbing, electrical, heating/cooling, and so on)

    The same distinction holds true for software development, deployment, and operations. One individual can theoretically gather requirements, build the software, test the software, deploy the software, and support the software  while simultaneously project manage their personal time. Most computer science students have done this in fact at one time or another, but when we are talking about enterprise applications that support core business functions it clearly doesn’t make sense because of the amount of effort required at each step and the specialized skills necessary for a high level of competency in each area.

    What this means is that we absolutely need tools that amplify our abilities, or that of our individual teams, i.e. the hammers; but we also need to invest in tools that help us coordinate work across teams, i.e the shared sets of blueprints.

    Tools That Amplify Individual / Team Abilities

    A lot of the tools attention in the DevOps community has been focused on: source code management systems like git or bitbucket; requirements planning tools like jira or rally; build tools like Jenkins; automation tools like puppet, chef, and ansible; and project management tools like MS project or AtTask. These tools help us amplify work in each of these respective areas just like hammers, saws, drills, and screwdrivers perform specific functions when building a house and often follow a natural sequence (first you hammer boards in place to create a wall, then hammer on the sheet rock, then saw or drill holes in the sheetrock, screw in electrical outlets and fixtures, and so on.)

    Just like building a house has a natural sequence, so does the sequence of tools from code to deployment and it’s often referred to as the DevOps “tool chain”. This brief article isn’t intended to cover each area of the typical DevOps tool chain (I could have also added bug tracking, automated testing, and other categories too), the point is you need to take time to define what the DevOps tool chain should be for your organization and to do so intentionally with a purpose, taking into account the tool investments your organization already has, the needs and skillsets of your organization, and your own practical budget realities.

    Do you have experience in using and self-supporting open source tools or do you have a preference for commercially provided tools?, Are you comfortable having multiple requirements tools in different teams or business units, or do you want a single standard? Only you can answer these questions for your organization. There is no prescriptive formula for these types of DevOps tools, although I’ve mentioned a number of commonly used ones.

    Tools that Amplify Work Across Teams

    The second area you should focus on are tools to help coordinate work and amplify our abilities across teams, i.e. bridging the inherent gaps in the DevOps tool chain, a subject that has received less attention in the DevOps community to-date. This makes sense because it’s human nature to think first about our own function and team. However, this silo thinking is one of the core problems DevOps was developed to address; the long-time focus on tools for specific IT “work stations” has actually entrenched the cultural silos of development, QA, operations, and project office in IT. For example, most IT organizations have two totally separate systems for tracking issues – in operations, it’s the service desk application and for code issues in development it’s the bug tracking application – and there is little or no relationship between them. In fact,  you are lucky if an incident in the service desk can be tied to a bug tracking number.

    If we are adopting DevOps in order to optimize the flow of new software releases to support business agility, then we need to look at how we will coordinate work and avoid information distortion and loss when different teams are using different, disconnected tools. In addition to your tool strategy for optimizing individual DevOps workstations, therefore, you also need to have a strategy for the tools that are going to help you effectively manage flow across those workstations.

    Most DevOps transformation efforts start small with a core team of perhaps a dozen or so members, and their often located in one physical location. In this scenario, you might be able to make do with regular face-to-face meetings and general-purpose communication tools like email, instant messaging, and a SharePoint site or Wiki with MS Office documents. The scope of your cross-team collaboration tools aligns with the scope of your DevOps effort and you might be able to rely on people interactions to unify the tool chain.

    But as you scale your DevOps efforts to larger, distributed teams across time zones and multiple business units and applications, your cross-team tools approach should scale as well. The point-to-point nature of instant messaging, ignored reply-all emails, and SharePoint ‘document dumps’ aren’t effective in coordinating the efforts of dozens or hundreds of developers, testers, admins, and project managers.  Information gets lost, information gets overlooked, and the gaps in your tool chain expand. A feature misses a commit and doesn’t get into the build and isn’t deployed. An operational requirement is missed so the test environment isn’t configured properly and the release gets pushed. Three weeks are spent solving a performance issue through code when it could have been addressed faster via hardware. A legacy application dependency in production is overlooked and the new mobile app doesn’t work in production as it did in test.

    There is an emerging class of purpose-built IT collaboration tools, such as ITinvolve, that enable the creation of cross-team workspaces where information is proactively shared as IT teams and tools get work done. This helps large, distributed cross-functional teams collaborate more effectively with each other in-context to raise questions, provide answers, and incorporate what’s happening up and down the DevOps tool chain in their individual work.

    For example, the developer will have better visibility into when the next build is going to occur and can ensure the feature is committed in time or can reach out to the build engineer in the workspace to request a delay in order to ensure the feature makes it in. The operations engineer can have earlier and better visibility into operational requirements so he can ensure the test environment is configured properly and avoid unnecessary delays. The legacy application dependency in production can be reproduced in test to ensure the application works properly once moved to production. And so on. By eliminating the handoff gaps and information loss across the DevOps tool chain, you can reduce risk of communication issues, solve problems more holistically rather than individually, and better achieve the goal of improving business agility.

    In the final part of this series, I will bring together the themes of the first three articles to demonstrate how you can chart a DevOps plan based on your Applications, your Culture, and your Tools to A.C.T. with greater agility.

    About the Author

    matthew Matthew Selheimer is Chief Technical Evangelist and SVP of Marketing at Houston-based ITinvolve. Reach him at matthew@itinvolve.com


  • Trolling PuppetConf: Surveying Configuration Management

    Trolling PuppetConf: Surveying Configuration Management

    Troll (Internet)

    In Internet slang, a troll (/ˈtroʊl/, /ˈtrɒl/) is a person who sows discord … by starting arguments or upsetting people,[1] by posting inflammatory,[2] extraneous, or off-topic messages in a… community …with the deliberate intent of provoking readers into an emotional response[3] or of otherwise disrupting normal on-topic discussion.[4] 

    -Wikipedia

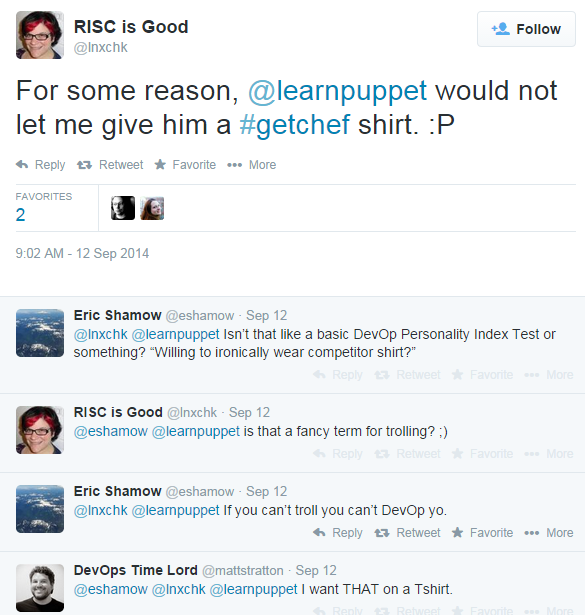
    When I stopped by the Chef booth at Velocity Santa Clara this year Nathen Harvey was out of XL t-shirts. I happened to have a Puppet shirt on at the time too, but it was just a lucky coincidence. Nathen’s always advocated using something (anything) to automate your infrastructure, as the ‘A’ in the CALMS model for devOps stands for automation, but the look on his face when I crossed his line of sight was as delightfully awkward as it could have been. Nathen told me he’d get me a Chef shirt if I got him my address back in Atlanta. I had been meaning to do it before I made it out to PuppetConf, but a tweet from Mandi Walls ultimately ended up prodding me into action.

     cheftroll

     To Nathen’s word, he got me a shirt in under a week, and in plenty of time for #PuppetConf.

    chef

    chefShirt


    I think “Stirring up delight” was the right shirt to send me too. I was half worried I’d get a shirt that was much more confrontational, putting me at risk of getting jumped and having my lunch money stolen. Lucky for me pretty much everybody that noticed the shirt thought it was funny. At least anyone who said anything to me about it. A proper troll is going to get at least one person a little bit angry though, right? Anyone that recognized I was in a Chef shirt happened to create an opportunity for me to ask a few questions, so I did.

    1. Have you used Chef, Puppet, CFEngine, or any other configuration management tools?
    2. Which do you prefer?
    3. Why do you prefer that particular tool?
    4. Why does the competition between these tools help or hurt our industry?
    5. Where do you see these tools in five years?

    I got pretty consistent answers just talking to people, and the Q&A often evolved into a natural conversation, which I prefer. (Another devOps principle I like to practice is shut the hell up and listen). I also put up fliers with a link to a survey while at the conference in an attempt to gather some empirical data. Truth be told, the survey was the real troll.

    One of the best talks I saw at PuppetConf was by Lindsay Holmwood, call The DevOps Field Guide to Cognitive Biases. I wasn’t familiar with the term before the conference but I think I had the idea. I also know I still don’t fully understand it. Watch the video and check out the books Lindsay suggests at the end. It’s pretty deep stuff. I really like his advice on having engineers manage and managers engineer to help break these biases down, as it creates a lot of empathy between the two groups.

    Given my own cognitive biases, I wouldn’t have filled out the survey if I had seen one of the flyers I posted. The flyer said nothing about a home school project for twin girls, which would have had a much better chance of getting my attention. Instead, it just asked folks to fill out the configuration management survey with the promise of cookies for their trouble. I’m pleased to say the tech community will respond to surveys for cookies even when crudely marketed. While I have enough responses to do sound statistical analysis, I know my data isn’t sufficiently stratified and probably doesn’t represent the larger population of the configuration management community. In other words my data lacks diversity.

    My daughters’ home school project is to start a business, and the twins decided to launch Gemini Snacks. Their company is pretty much an online bake sale to allow them to give back to all the hospitals and organizations that have helped them and cheer up the kids that can’t go home yet.

    The deal I made with my daughters was simple. I would print out flyers for PuppetConf to get survey responses to help me write this article. I would thank as many people as we could for filling out the survey by sending them some cookies, and I would hire their company to bake and ship those cookies. If people filled out the survey my kids would be in business.

    There was a strong enough trend in the responses that I can discuss those now with confidence despite a lack of diversity in the data. Of course I got a lot of responses from Puppet users, but I also heard from people using CFEngine, Chef, Ansible, Salt, and bconfig2. A lot of people weren’t using anything and just recently picked up Puppet.  I ran into a few folks that had used three or more tools at one point or another and could give comparisons which were really interesting. Here are the main conclusions I’ve been able to draw so far.

    A Rising Tide Floats All Boats

    Most organizations are still sshing into a lot of hosts to handle things, sometimes they do it with scripts. Configuration management (CM) tools are still becoming a fully adopted standard. I have heard users of every CM application in the market say it really doesn’t matter what tool you’re using, automate your infrastructure with something. As a result this is still very much a growing sector in the tech industry.

    Don’t get into a Configuration Management Bake-Off

    Bake-Off is the word that was used, and more than one person put it that way specifically. I don’t know what you’d call setting up test environments to try different CM tools before making a decision, but I’d call it a bike shed of yak shaving myself. Bake-Off is probably more familiar people anyway. My opinion is you should either be using Puppet or Chef, but if you’re not using any configuration management tool at all it’s advised that you start.If you can’t help but take more than one for a spin before committing then keep it short and sweet. You’ll be better off taking the time to commit to one and put the work into making the transition quickly than trying to figure out the easiest way to do it. This automation will take some effort. The key thing to understand is the right tool depends on your environment.


    There’s a Lot of Respect and Appreciation for CFEngine

    CFEngine is a trailblazing academic project that gained a lot of popularity in the early days of CM. The adoption of the software in the open source community really proved the viability of CM as we know it. While the application isn’t seeing continued growth now that there’s competition with newer tools in this space, several people went out of their way to emphasize the immense respect they have for the product and its founder, Mark Burgess, as CM wouldn’t be as evolved without them.


    Puppet: Preferred by Ops Folks because it’s Easy to Configure

    The main thing the ops crowd seems to prefer about Puppet is that it’s easy to configure. I had a book recommended to me  at the conference called, “Switch: How to Change Things when Change is Hard”, by Chip and Dan Heath. The book describes a “Project Mood Chart” used by IDEO, a product design firm, to brace their clients for adversity.

    productMoodChart

    When a new project starts we’re optimistic and hope for the best. We inevitably face adversity during the course of our work, and while this adversity is always frustrating it does lead us to insight. Empowered by our new perspective on the problem we can proceed to a viable solution with confidence.

    I believe this is how Puppet evolved out of CFEngine. Luke Kanies, the founder and CEO of Puppet, was an early contributor to CFEngine. I can see Luke following this curve, gaining insight on the configuration difficulties the CFEngine community was experiencing, and going on to found Puppet, confident he had a product better adapted to industry since it was easy to configure.


    Chef: Preferred by Devs because it Allows them to Treat their Systems Like Objects

    I can see this same curve being followed as Chef came out of Puppet as well. With ease of use comes a lack of robustness. Puppet’s advantage over CFEngine is it’s easier to configure, but there seems to have been a point of frustration within the development community that lead to the creation of Chef. Developers like to treat things like objects, which should be obvious if you have any experience with object oriented programming. Abstracting the complexity of the software we write so it can be configured by end users that are not developers is challenging. Since Chef allows its users to treat their systems like objects, the difficulty surrounding the abstraction of any complexity into a declarative model is circumvented.

    Which is the main reason ops folk don’t like Chef as much, because they’re not programmers. If you’re in an organization with a mature operations department that’s not so interested in learning to code, Puppet ‘s declarative model for describing systems is going to be a better fit. However, if you have developers doing most of the operations work out of necessity in a small shop or an operations group that’s doing more software development for internal tools, especially if they like Ruby, Chef may be a better fit for your organization.


    Ansible: Symbiotic Orchestration

    The best things anyone had to say about Ansible is that it’s great for orchestration. It seems to be competing more directly with mcollective, a framework Puppet Labs supports for orchestration tasks. Mcollective can be used with both Chef and Puppet, and the same appears to be true for Ansible. Ansible is also agentless, managing nodes over SSH. Depending who you talk to this can be a good or a bad thing. By not running an agent the nodes aren’t dealing with the overhead that would come with it, but you’ve also lost the ability to monitor your systems as tightly as you could if they were running an agent. I’m under the impression CM is trying to move us away from SSH loops. While I don’t think it’s fair to write Ansible off as an overblown SSH loop, I am of the opinion that the advantages provided by agents running on each node in your environment are well worth the overhead. It will be interesting to see if Ansible’s relationship with other configuration management systems continues to evolve into a symbiotic orchestration provider or if another product, like mcollective, continues on to fill that void.

    Salt Isn’t Really Configuration Management Software, but it’s Fast

    Salt is a remote execution platform build on zeroMQ that was designed with speed in mind. Everything salt’s being used for, including CM, has been an afterthought to the fast remote execution platform at the heart of the project. The constant connection the nodes (called minions) maintain with their master definitely contribute to the speed of the system. This would lead me to believe Ansible is the slowest of the four technologies discussed here, since it doesn’t run an agent at all, and Chef and Puppet would fall somewhere in the middle since they run an agent on their nodes but it isn’t on constant communication. (This is an educated guess on my part. Please let me know if you can speak to the speed concern from personal experience.)

    I have run into a few businesses that deal with high speed financial systems that use salt for a lot of things, including CM, but only because it’s fast. If you have systems that demand split second responses to failure and change, salt may help solve a lot of problems your organization is currently facing. I’m not convinced it’s that easy to use.

    Salt seems popular with groups that want to avoid Ruby like it’s the plague or folks that are so horribly comfortable in a CLI that using a GUI just seems unnatural. I think these are terrible reasons to select a tool, since it’s directly avoiding the ‘adapt or die’ mentality that the devOps community embraces. Still, depending on your environment and the adversity you’re dealing with, these may be entirely reasonable grounds to use salt instead of another technology. I’d be less concerned if you told me you picked salt because it’s fast though.

     The Survey is Still Open

    I hope you like what you read here but I’m sure somebody doesn’t agree with me at all. The good news is you can still fill out the survey and let me know. When my data looks sufficiently diverse I’ll publish another update, and there’s a decent chance you’ll get some cookies for you time too. I’d also like to thank everyone that took the time to discuss this with me. Gene Kim, John Willis, Chris Webber, Charles Johnson, Dawn Foster, Kara Sowles, everyone at Puppet Labs, and of course Nathen Harvey and Mandi Walls, all helped to make PuppetConf a huge success and a memorable experience for me. I’ve learned way more than I expected from the experience and I’m excited to see how the competition in this space plays out in years to come. Competition is a good thing. As different challenges arise and as projects go through mood swings I believe we’ll see two things happen: The communities for these tools will adapt them to adjust to the environment they’re operating in, and at some point enough adaptation will lead us to a new set of tools all together. I for one am really excited to see what happens.

  • Using Docker & Ansible by John Minnihan @Gluecon 2014

    Using Docker & Ansible by John Minnihan @Gluecon 2014

    Continuing our series of videos from the DevOps track at Gluecon this past year, our next video is “Why Docker + Ansible Make Chef and Puppet 100% Unnecessary by John Minnihan, ModernRepo”  Again many thanks to CloudSoft for recording and making these videos available to us to post. Also the picture above is from the Ansible website originally.

    This presentation sounds pretty controversial if you just look at the title. Actually John is not advocating throwing away your Puppet or Chef scripts.  If you already have Chef or Puppet set up and you like the way it is working, there is no reason to change.  However, John believes that Docker with Ansible can negate the need to use either of these tools going forward. John is primarily talking about a greenfield situation here I believe.  Anyway, the video like the previous ones in this series are about 30 minutes. Enjoy!

  • Security automation with DevOps: show me the code!

    Security automation with DevOps: show me the code!

    Last week Andrew Storms put up a good post hinting at the promise of security automation in [SecDevOps: Security Automation By Example – The Firewall Change]. He included an example of automating a series of actions when a firewall rule is changed. It’s a good article, although I’m increasingly convinced there’s no such thing as SecDevOps. In my book, it’s all DevOps, but that’s fodder for another post (when I’m not battling a stomach bug). However, what Andrew describes is more of what I consider an automated assist. It isn’t necessarily full automation, since it triggers on a manual firewall rule change. Ideally we rarely manually change a firewall (or Security Group) rule, and rely more on self-configuring based on policies. Yeah, I know, the usual analyst BS, so here’s a bit of process, and a bit of code. Let’s approach this differently. Take Andrew’s process, but let’s have the security group or host firewall self configure based on the asset. My example is going to be Amazon Web Services specific, since I have some code snippets to show off how it works. (Sorry, I don’t have the time or intestinal fortitude to write out all the code today; seriously, where did this bug come from?!?) There are two techniques I generally see forming the core of dynamic Security Group policy enforcement:

    1. Tags
    2. Configuration Management integration

    Some cloud services, like AWS, support tags at the object (in this case, instance) level. These tags can tie internally to policies while also being consumable for external tools. Here is a policy I use that restricts access to an object if the “SecurityStatus” tag is “IR” (for “Incident Response”):

    {  
      "Version": "2012-10-17",  
      "Statement": [  
        {
          "Action": "*",
          "Condition": {  
            "StringEquals": {
              "ec2:ResourceTag/SecurityStatus": "IR"
              }
              },
              "Resource": [
              "*"
                          ],
              "Effect": "Deny"
          }
          ]  
        }         
    

    I could apply that tag manually or automatically, and in either case the instance can no longer be managed by any account this policy is applied to. Now this doesn’t help us change firewall/Security Group rules, since you can’t manage those directly in EC2 based on tags (but I had the policy handy to demo, so there you go). For that to work, you need to write your own code to scan for tags and then take actions. I don’t have exactly the right code examples on hand. but here are some snippets to get you close. Most of these are cribbed from my SecuritySquirrel proof of concept on GitHub. They are all in Ruby, using the AWS 2.0 developer preview SDK. First, to pull a list of all instances with a certain tag, you can use the following:

    def testing
     # testing some tag code
     instancelist = @@ec22.describe_tags(
     filters: [
     {
       name: "key",
       values: ["SecurityStatus"]
     }
     ]
     )
     puts instancelist.to_h
    end  
    

    That shows everything with the SecurityStatus tag (instances and values, shown as a hash), but you could also filter on value. From there, you could pull the instance IDs with a map (you might want to further filter only on instances, but if you made it this far you can figure that out):

     instances = instancelist.map(&:resource_id)  
    

    Then you can pump those into a method to change the Security Group. Here’s the one from SecuritySquirrel that places an instance into a “Quarantine” group:

    def quarantine
      #this method moves the provided instance into the Quarantine security group defined in the config file.
      puts ""
      puts "Quarantining #{@instance_id}..."
      quarantine = @@ec22.modify_instance_attribute(instance_id: "#{@instance_id}", groups: ["#{@QuarantineGroup}"])
      puts "#{@instance_id} moved to the Quarantine security group from your configuration settings."
    end  
    

    Want to trigger some scanning? Here’s a code snippet to trigger a Qualys scan on an instance from a virtual appliance in your AWS account (keep in mind, I’m skipping a bunch of important pieces, like configuring the service and authenticating):

      instance_IP = instance_details.reservations.first.instances.first.private_ip_address
     timestamp = Time.new
     scan =(HTTParty.post("https://qualysapi.qg2.apps.qualys.com/api/2.0/fo/scan/",
          :basic_auth => @qualysauth,
          :query => { 
            :action => "launch",
            :scan_title => "SecuritySquirrel Scan at #{timestamp}", 
            :ip => "#{instance_IP}",
            :option_title => "Initial Options",
            :iscanner_name =>  "us-west-2" 
          },
          :headers => { "X-Requested-With" => "ruby httparty"}))
          puts "Launching Qualys scan named: SecuritySquirrel Scan at #{timestamp}"  
    

    Or want to change the CloudPassage Halo host firewall rules? Well, that code uses a pre-release of their Ruby SDK, so I’ll save it for another day (I’m not employed by them, but they let me play with the pre-release gem). These examples are all based on tags, but remember that if you use a tool like Chef or Puppet you can do the exact same thing based on what software is configured and running within the instance. For example, you could create a policy to quarantine all SSL when the Heartbleed vulnerability hit by closing off port 443 on any server running the vulnerable OpenSSL package, then remove the rule when it is updated to the patched version. I’m a bit rusty since I don’t code every day, but I could probably pop that code off in an hour or two, it isn’t that hard. Also my tool is designed for demos, and doesn’t run in the background, but clearly you could have it running all the time, adjusting things based on tags or even attributes of software deployed in the instance. Security automation is insanely powerful. It can completely automate complex security tasks, or, as in Andrew’s example, supplement manual activities and policy changes. Hopefully my snippets give you some ideas, and pop me over any good examples if you are willing to share.