Tag: network security

  • The Importance of NetSecOps in Network Management

    The Importance of NetSecOps in Network Management

    The IT landscape has changed beyond recognition in the past decade or so. The vast majority of businesses now operate largely in the cloud, which has had a notable impact on their agility and productivity. A recent survey of 1,900 IT and security professionals found that 41% of organizations are running more of their workloads in public clouds when compared to just one quarter of respondents in 2019. Even businesses that were not digitally mature enough to take full advantage of the cloud will have dramatically altered their strategies in order to support remote working at scale during the COVID-19 pandemic.

    However, with cloud innovation so high on the boardroom agenda, security is often left lagging behind, creating a vulnerability gap that businesses can little afford in the current heightened risk landscape. The same survey found the leading concern about cloud adoption was network security (58%).

    Managing organizations’ networks and their security should go hand-in-hand, but, as reflected in the survey, there’s no clear ownership of public cloud security. Responsibility is scattered across SecOps, NOCs and DevOps, and these teams don’t consistently collaborate in a way that aligns with business interests. We know from experience that this siloed approach hurts security, so what should businesses do about it? How can they bridge the gap between NetOps and SecOps to keep their network assets secure and prevent missteps?

    Building a Case for NetSecOps

    Today’s digital infrastructure demands the collaboration – perhaps even the convergence – of NetOps and SecOps to achieve maximum security and productivity. While the majority of businesses do have open communication channels between the two departments, there is still a large proportion of network and security teams working in isolation. This creates unnecessary friction, which can be problematic for services-based businesses that are trying to deliver the best possible end user experience.

    The reality is that NetOps and SecOps share several commonalities. They are both responsible for critical aspects of a business and have to navigate constantly evolving environments, often under extremely restrictive conditions. Agility is particularly important for security teams to keep pace with emerging technologies, yet deployments are often stalled or abandoned at the implementation phase due to misconfigurations or poor execution. As enterprises continue to deploy software-defined networks and public cloud architecture, security has become even more important to the network team, which is why this convergence needs to happen sooner rather than later.

    We somehow need to insert the network security element into the NetOps pipeline and seamlessly make it just another step in the process. If we could automatically check whether network connectivity is already enabled as part of the pre-delivery testing phase, that could, at least, save us the heartache of deploying something that won’t work. And then, if we do need to open new ports, an automated process that could also raise a change request would save even more time. Better yet, if it’s one of those “make this like that” changes, the change could be automatically implemented on the firewalls – in minutes, not weeks.

    With NetSecOps, application developers can get creative without worrying about security slowing them down, and network security teams can sleep soundly, knowing that risk and compliance checks are built in to the continuous delivery process with a full audit trail, so they can even get time back to do some fun stuff.

    If we could do all this with only the rare cases of new connectivity requiring approval by security, the NetSecOps dream could become a reality, allowing fast, high-quality delivery. With NetOps and SecOps working together, organizations can establish a collective approach to network management and security, offering equal opportunity for both teams to present and prioritize issues and agree on the fundamental rules from the start; a match made in heaven.

  • How SD-WAN Is Driving Business Continuity in a COVID World

    How SD-WAN Is Driving Business Continuity in a COVID World

    The coronavirus outbreak has thrown the economy into flux, creating changes to entire industries that would have been unpredictable a few months ago. While demand for travel has decreased dramatically, other businesses such as grocery chains, financial services and retailers are under immense pressure to serve customers in new ways. Enterprises with thousands of employees have been forced to work from home on a moment’s notice. For the IT departments powering these industries, SD-WAN will be key in increasing visibility for newly remote companies, ensuring company data is heavily guarded and managing demand for products.

    As stay at home orders made their way across the U.S., companies with thousands of employees had to immediately start working from home, many for the first time. In other words, companies were forced to navigate a completely remote workforce with little opportunity to put the infrastructure and tools in place to support its employees. Without adequate time to prepare for a smooth transition, a number of issues arose, such as realizing that IT departments didn’t have insight into the user experience of business applications for their employees’ home networks. As a result, they were unable to monitor performance and usage patterns to anticipate potential issues for employees. IT workers were unable to remotely troubleshoot and fix networking issues, increasing pain points across teams and decreasing overall productivity.

    SD-WAN Becomes IT’s Saving Grace

    This is where an AI-Driven SD-WAN can play a major role in managing remote enterprise networks to deliver better experiences and ultimately boost productivity. By providing full visibility into what’s happening across the network, AI-driven SD-WAN solutions can ease the burden of a remote workforce by proactivity responding to real-time issues. The sources of problems across the network can be vast. Intelligent SD-WAN systems not only find the root causes of problems, but also provide solutions. This can save IT departments significant time and effort in troubleshooting an issue, improving the remote IT operational experience as well as the employee work from home experience. 

    Doubling Down on Secure SD-WAN

    Security is another network concern that comes into play when employees work from home. There is an overwhelming amount of confidential data flowing across each network, and in this new environment, enterprises must take extra precautions to ensure data is heavily protected. As employees move out of the office, they’re relying more on home and public networks, moving sensitive corporate data to insecure spaces. 

    IT teams are increasingly relying on SD-WAN to help improve network security by encrypting traffic and segmenting the network to minimize damage if breaches do occur. Secure SD-WAN incorporates security solutions including firewall, anti-spam and web filtering. These solutions work together to prevent remote employees from accidentally leaking data or causing network security disruptions that can affect the rest of the workforce. SD-WAN is critical in improving a company’s overall security posture. By implementing a secure SD-WAN solution, companies can have more peace of mind, and employees can focus on their task at hand.

    The Role of SD-WAN in Evolving Supply Chains

    As employees spend more time working and living at home, their new consumer behaviors are quickly changing overall demand and forcing supply chains to evolve accordingly. Companies have scrambled to get a handle on their supply chains, and SD-WAN has become a key component in managing the demand for products; by shifting to the cloud and integrating SD-WAN into product inventory, companies can have access to cloud resources to power their inventory systems. For example, by integrating SD-WAN into grocery store chains, individual stores have been able to communicate with each other and support constantly changing customer needs. An increased demand for yeast at one store can be balanced by a decrease in demand in another. Enterprises can use the inventory system to allocate their products accordingly and record patterns to provide restocking guidance that is up to date as consumer behaviors continue to evolve.

    The Bottom Line

    Ease of management, security and visibility are the key pillars to ensure business continuity for enterprises in a COVID world, and by doubling down on SD-WAN, organizations can benefit from all three.

    SD-WAN is quickly becoming the unsung hero in this shift to remote work by giving organizations the network visibility IT managers require as well as extra security precautions that are more critical than ever. And as businesses and our ways of working continue to evolve with the times, SD-WAN will enable employees across organizational networks to communicate safely and securely.

  • Managing a New Kind of Complexity in Software-Defined Networking

    Managing a New Kind of Complexity in Software-Defined Networking

    Software-defined networking (SDN) has moved up the enterprise IT agenda in recent years. And it’s easy to see why–in theory, SDNs are far quicker and easier to control and alter than traditional networks. By using open protocols to apply controls from the network edge, SDNs enable network engineers to shape traffic from a single centralized console, rather than working with individual switches across the network.

    In turn, this makes software-defined networks far more agile than traditional networks, with opportunities for automatic load balancing, streamlined processes, on-demand provisioning of new applications and traffic flows–in short, a network that works much harder for the organization. So, it’s no surprise that organizations are embracing SDN. A 2019 Verizon study found that while just 15% of respondents said their companies had implemented SDN, 57% expected to do so within two years.

    However, deploying SDNs can introduce new challenges for network staff revolving around complexity–in particular, complexity in relation to managing network security. Let’s take a closer look at what this means.

    A Shift in Complexity

    Any organization that moves to a software-defined environment essentially moves from datacenter-focused firewalls into a model where its security policies are defined by software within its fabric. This requires a far more granular level of security policies, on a much larger scale and with far more agility, than in traditional networks. Why? Because security controls are much more diverse.

    In a traditional setup, network security policy is relatively monolithic. A set of servers is protected by a perimeter firewall, filtering so-called north-south traffic that enters the network from the outside. Traditionally, east-west traffic within the datacenter itself is not subject to any filtering, which introduces security risks–particularly in terms of enabling malicious parties to laterally explore the environment once they have compromised a single endpoint.

    By contrast, in an SDN environment, built-in firewalls are considered part of the infrastructure. It is likely that the organization will have multiple tenants, each containing a unique set of granular security policies dictating which assets can connect to which other assets within the SDN fabric. An SDN environment is likely, for example, to incorporate one contract with Cisco Application Centric Architecture (ACI), VMWare NSX distributed firewalls and so on. There is a lot of complexity to manage.

    Ultimately, the organization in question needs to identify which elements within the newly software-defined network need to connect to each other. Then, create granular security policies that enforce this, dividing the network into smaller zones to prevent lateral infiltration by malicious parties. In short, they need to introduce micro-segmentation. 

    Managing Micro-Segmentation

    There are two main challenges associated with micro-segmentation from a security point of view. First, the organization needs to define the micro-segmented zones, and second, it needs to enforce and maintain the security policies that enable that micro-segmentation.

    How do we define micro-segmentation zones? This is all about understanding the assets within your environment, which databases contain the most sensitive data and therefore need to be segmented off from each other, which assets are talking to each other and how traffic is flowing throughout the network. Crucially, all this should be contextualized in terms of business applications–in other words, you need to understand the traffic that makes business applications work. This enables you to design a micro-segmentation architecture–and the security roles to enable it–that are centered around your business-critical services. Solutions that automatically discover and map all of the traffic flows within and through a datacenter are invaluable at this point.

    Then we move onto enforcement and maintenance of those rules on an ongoing basis, and this is where a security policy management solution is truly critical. All this complexity and dynamism cannot be managed manually. Each time a new business application is introduced, or an existing one removed or amended, the security policies also need to change–and these changes could be happening on a daily or even an hourly basis in a large organization.

    Automating the Management Process

    So, given the flexibility and rapid changes that SDN enables, how should organizations approach managing and maintaining security policies across their entire enterprise network? The most effective way is with an automation solution that holistically supports the SDN environment and its security controls, alongside existing traditional on-premise firewall estates.

    It’s important to note that the SDN deployment will be subjected to the same compliance and auditing requirements as existing networks. The security management solution must be capable of providing visibility across both physical and virtual network functions so that the overall compliance status can be centrally monitored and logged for audit purposes.

    Automated security policy management solutions generate filtering policies based on enabling only the traffic required for every application in the datacenter. This is a way of approaching intent-based networking, which comes back to looking at the components of each individual application and how they are communicating with each other. Furthermore, automated security policy management solutions audit and record every single change that is made across the network, making it easier to demonstrate compliance continuously.

    With the right automation solution, IT and security teams can eliminate time-consuming, error-prone manual security processes, such as connectivity discovery and mapping, migrating and ongoing maintenance of their environments. This frees up the teams to strategically maximize the benefits of the SDN deployment, and reap its rewards of increased flexibility and enhanced network security.

  • Can DevSecOps Prevent a Zombie Apocalypse?

    Can DevSecOps Prevent a Zombie Apocalypse?

    Making consistent progress within any DevSecOps initiative often can be an overwhelming undertaking. Developers tend to outnumber operations dramatically, with little to no security accountability. This leaves DevSecOps doomed to work with the same network security stack that was originally designed decades ago for on-premises environments. Still, the expectation is to support shrinking deployment cycles on cloud-native and hybrid environments without compromising on security standards.

    To deliver on such a tall order, DevSecOps teams are armed with security groups and access lists (which are more of the same distributed firewall technologies) to secure a perimeter that essentially no longer exists. This article will help you figure out how much time you have left before your CI/CD pipeline is overrun by zombies (quite literally) and what you can do about it.

    Why Cloud-Native Environments Choke on Rule-Based Network Management

    Rule-based management of network infrastructure has worked for decades—and no doubt will continue to support many enterprises well into the future, unless your production environment includes a public cloud footprint that supports continuously deployed release cycles. That’s when things start to get a little weird. Instead of letting go of the binary perimeter premise (inside versus outside) and redefining it completely, security practitioners have essentially re-created multiple virtualized perimeters in the public cloud. In theory, you could spin up at least as many perimeters as you have running instances. Unfortunately, the same network rules that worked well for the one perimeter break down in a virtualized environment that has hundreds of instances supporting dynamically changing requirements. In fact, the very nature of the cloud is driven by business logic at the application layer, which is decoupled from network infrastructure by design. This creates a Catch-22 situation for cloud-native security pros, forcing DevSecOps teams to manually map network rules to highly agile and virtualized business logic. No human can realistically deliver results over time (and stay sane). The reality is, rule-based network management can never keep up with the requirements of cloud-native business logic.

    With Great Agility Comes Security by Bureaucracy

    Regardless of how skilled DevSecOps teams are, or how motivated they are to lead the brave new world of continuously secure deployment, the harsh truth tends to be disappointing. While DevSecOps presumably aspires to deliver agility without compromising on security, practitioners spend much of their time doing just that. Trapped by a security culture that has favored bureaucracy over automation for decades, DevSecOps tends to perpetuate the very dichotomy that triggered the emerging practice. In a cloud-native culture driven by innovation and automation, agility comes first. This inevitably becomes an exercise in futility—the more agile your deployment, the more vulnerable you become. That means giving up on the very idea that rule-based network management is a viable security methodology. The complexity of managing several dedicated security groups (up to five) for every instance rapidly spins out of control. Given the imperative to maintain the cloud’s agile environment, many teams consciously sacrifice security on the altar of agility, leaving a gaping attack surface vulnerable to unrestricted access.

    Welcome to Cloud-Native Multi-Perimeter Security

    The challenge is to prevent any unauthorized code (benign or otherwise) from infiltrating cloud deployments before any sensitive data or workloads are compromised. In the absence of robust automation to support this process, the challenge is often ignored. When that doesn’t work, the solutions often remain in the realm of bureaucracy, focusing on anecdotal symptoms without addressing the root cause.

    The inevitably grim question is not if your deployment is at risk, but how vulnerable you are and how soon is likely too late. The results are measurable and often disturbing. Below is the standard KPI checklist most DevSecOps are familiar with:

    1. Rogue workloads unauthorized by CI/CD pipeline. These are typically addressed by discovery tools and ad-hoc network scans but are all too often accepted as a necessary evil.
    2. Faulty network rules. Microsegmentation initiatives often lead to unexpected inter-workload communication.
      Workloads deployed via the CI/CD pipeline could fail to communicate effectively—or worse, communicate to support counterproductive or even malicious activity.
    3. Unexpected workload communication to Third-Party PaaS. A case in point is workload communication to a database such as S3, which could lead to a data breach. Well-documented cases include leaders, such as Accenture and Time Warner, that unwittingly enabled public access to S3 buckets storing sensitive customer data and access credentials.
    4. Network Security Configuration Mistakes. Vulnerabilities introduced by network security configuration often go unchecked for months. Such unrestricted access is commonly cited as the attack vector that enabled unauthorized actors to infiltrate a gaping cloud-native attack surface.
    5. Zombie Workloads Consuming Resources. At best, you’re just wasting resources. All too often, one of those zombie workloads is busy cryptojacking, mining cryptocurrency on your company’s buck unnoticed. Cryptojacking is so rampant, it has overtaken ransomware in 2018 as the most popular attack vector.

    The bad news is, no cloud deployment can eradicate the above issues entirely, using familiar technologies. However, you can mitigate some of the damage: Scan your network more regularly using your favorite open source tool (check out a great example implemented on Netflix Security Monkey presented by Ryan Hodgin). Never leave an entire network flat granting anyone unrestricted access. Ideally, take the time to evaluate new technologies designed to secure cloud-native deployments.

    DevSecOps teams are gradually accepting that cloud-native deployments require a fundamental paradigm shift to sustain a defensible security posture without sacrificing agility. Many believe (this author included) that we are witnessing a cloud-native security revolution, much like the one triggered by the internet in the 1990s. DevSecOps can certainly address the symptoms described above, but security policies will continue to fail miserably if they both remain entrenched at the network layer and rely on bureaucracy.

    — Ran Ilany

  • It’s Time to Break Up with Your WAF

    It’s Time to Break Up with Your WAF

    If the only reason you have a web application firewall (WAF) is for compliance, you deserve better. It’s time to replace it with something that provides not only compliance, but real security value as well.

    In the land of web application security, there are a few not-so-well-kept secrets, arguably none bigger than this: The WAF survived not by being excellent, but by being mandated.

    The WAF is an antiquated technology that was created to help stem the rise of application security vulnerabilities, which had been overwhelming organizations with their frequency of discovery. Static and dynamic analysis tools dumped huge quantities of bugs onto development teams that had no possible way to fix so many code issues.

    Meant as a stop gap measure to address this problem, the WAF made it possible to filter out rampant SQLi, command execution and XSS attacks that were threatening to consume all of the development and security team’s available resources. The idea behind the WAF was that the application bugs and security flaws would be triaged for now, and then eventually fixed in the code at the root of the problem.

    At the time, a drop-in web application security filter seemed like a good idea. Sure, it sometimes led to blocking legitimate traffic, but such is life. It provided at least some level of protection at the application layer—a place where compliance regimes were desperate for solutions. Then PCI (Payment Card Industry) regulations got involved, and the whole landscape changed.

    PCI requirement 6.6 states that you have to either have a WAF in place or do a thorough code review on every change to the application. Given the unappealing nature of the second option, most organizations read this as a mandate to get a WAF. In other words, people weren’t installing WAFs due to their security value—they just wanted to pass their mandatory PCI certification. It’s fair to say that PCI singlehandedly grew the WAF market from an interesting idea to the behemoth that it is today.

    And the WAF continues to hang around, an outdated technology propped up by legalese rather than actual utility, providing a false sense of security without doing much to ensure it. If that isn’t enough for you to show your WAF the door, here are four more reasons why WAFs should be replaced.

    The Minimum WAF Rules Approach is Broken

    A common side effect of a WAF implementation is the blocking of legitimate traffic. In the application security business, we call these false positives. Don’t be fooled by this innocuous phrasing—what it means is that customers aren’t able to buy things they want, or upload their latest vacation photos or generally use the functionality of your applications. It’s the kind of experience that can quickly turn current customers into former customers.

    To combat WAF false positives, most companies run the bare minimum number of rules to get by. This means that only the most obvious and most egregious attacks are caught, while everything else just sails right past the filter. Simple rules mean easy-to-bypass rules, leaving you with an ineffective WAF.

    Learning Mode is Broken at Speed

    One way that WAFs try to cut down on false positives and avoid breaking valid traffic is through a “learning mode.” In learning mode, the WAF learns what normal traffic looks like versus what malicious traffic looks like and protects accordingly. A lot can be said about how tough it is to get learning mode right, even under perfect conditions, but let’s skip to the real problem we see in production environments.

    Learning mode takes time. WAFs that need to learn to recognize “normal behavior” require a certain amount of traffic review before they can actively block everything else. It may take a few hours to learn safe application traffic patterns.

    When you move from waterfall to agile and DevOps, deployment speed gets faster and faster. The application code changes weekly, daily or even hourly. If you deploy using anything close to a modern cadence, putting the WAF in learning mode on every code change means you are always in learning mode. Essentially, any kind of learning mode, when applied to modern application development techniques, just can’t keep up with the pace of production.

    Monitoring Mode Really Isn’t Compliance

    The fact that WAFs have survived due to legal mandates rather than effectiveness isn’t the only open secret in the business. You also won’t be shocked to hear that most companies never put their WAF into active blocking mode. After all, blocking mode has high false positive rates and breaks your legitimate traffic, so it’s the way to go only if you’re hoping to break your application.

    Instead, the WAF is run in monitoring mode, where it watches traffic and logs any event as an attack. When it’s time for audit, the WAF gets flipped on for a short bit, then back off again. In reality, of course, some auditors don’t even care if you have it in active blocking mode. Just having a WAF in place is good enough for them.

    Running your WAF in monitoring mode is not an effective control. All it does is add a false sense of security and additional overhead to the security team to evaluate logged events. In this scenario, you’re spending money where it doesn’t need to be spent while adding close to zero defensive measures.

    CDN-based WAFs Were for Convenience, not Effectiveness

    The last not-so-fun thing about WAFs is their daily care and feeding. Your WAF adds complexity to your network, and having to dynamically scale it in the cloud is not exactly easy. Enter the content delivery network (CDN). Since most shops are already using a CDN to offload web application woes, why not add a WAF at the CDN layer? This meets compliance (yay!) and we don’t have to manage it (double yay!).

    For many enterprises, this idea is the win-win that has allowed the WAF to persist even as its usefulness has been questioned. The problem with the CDN-based WAF, though, is that you end up running the WAF with a minimum set of rules again (see above or here), leaving the door open to all kinds of attacks. In fact, in my work at Signal Sciences, many customers use our web protection platform behind their CDN-based WAF and discover tons of real attacks that happily made it through the CDN.

    If compliance is your main goal, go ahead and use a CDN-based WAF. If you want real defense, look elsewhere.

    Achieve Compliance and Real Security at Speed

    If this article sounds a little too familiar—if all you’re getting from your WAF is compliance—then it’s time to replace it. There are new options for adding defense at the web application layer and achieving compliance at the same time—for example, using runtime application self-protection (RASP) or next-gen WAF to provide application-aware defensive coverage. This means that, instead of just checking a box for PCI, you can be actively defending against the OWASP Top 10, account takeovers, instrument business logic and fight off bots, all without interfering with legitimate customer activity.

    Don’t settle for compliance alone. You can achieve both compliance and real protection—and that’s what your business and your customers deserve.

    — James Wickett

  • What the Current DDoS Landscape Means for DevOps

    What the Current DDoS Landscape Means for DevOps

    Businesses, governments, hospitals, schools, charities and even individuals—they’re all the same to a DDoS perpetrator. If you have a website, it’s likely to be targeted by a distributed denial of service (DDoS) attack at some point.

    DDoS has the potential to shut down your site for days and create havoc with an organization. They can be expensive and—most worrisome—can taint your reputation and discourage users and customers from ever returning if your site is unavailable on any given occasion.

    Perpetrators have been known to exploit network packets and all types of vulnerabilities, including writing custom code dedicated to knock down a specific application or service, to overburden systems or stop them outright.

    Attack Motivation

    There are plenty of threat actors ready to launch a DDoS barrage. Some of them include:

    • Hacktivists using DDoS to express their discontent with businesses, governments and individuals.
    • Cybercriminals relying on pre-made scripts and tools to take sites down. Some instigators are simply looking for a way to vent their anger or frustration. Some may use commonly available DDoS-for-hire websites instead of running the attacks from their own network.
    • Extortionists who blackmail sites, demanding money in exchange for stopping (or not carrying out) a DDoS threat.
    • Business competitors seeking ways to exclude rivals from significant events (e.g., Cyber Monday), or attempting to completely shut them down.
    • State-funded threat actors engaging in cyber warfare to silence critics and opponents. They also can target civic infrastructures to cripple opposing countries.
    • Attackers who attack just because they can, or for no obvious reason, other than test their ability to carry out an attack.

    DDoS Types and Trends

    But DDoS events don’t just disrupt service. According to “Cloud Security Alliance Guide to Cloud Computing,” hackers are also using them to steal information and infect computers for a variety of nefarious purposes.

    In addition, DDoS assaults are growing rapidly in both number and volume. International Business Times states they’ve become more commonplace because readily available tools and cheap online services let anyone aim an attack against a company or individual server.

    DDoS attacks can be divided into three types, with numerous (and unique) variations within each.

    Volume-based attacks saturate the bandwidth of a site. Imperva Incapsula, a cloud-based security and acceleration provider, faced the largest such attack on its record in 2Q 2016, peaking at 470 Gbps. Like many other complex, high-rate assaults, attackers used small payloads to achieve a high packet forwarding rate—a dangerous new tactic that has become common.

    The main purpose of such attacks is to take down mitigation services by sending out a rapid burst of packets at a rate many anti-DDoS appliances can’t handle.

    Protocol attacks (aimed at the OSI layer 4) consume server resources such as firewalls and load balancers. Network layer attacks have grown in size, number and sophistication. Those using multiple vectors have climbed to a record-high 36.1 percent, reports Incapsula. On average, it mitigated a 50+ Mpps attack every three days in that quarter.

    Network layer attack duration increased in the same period, with 13 percent lasting for over an hour. The longest persisted for more than 10 days in a row. While most are in the hit and run category—using short bursts launched against the same target—an uptrend points to the prevalence of events lasting more than six hours.

    Application layer assaults (targeting layer 7) are comprised of seemingly legitimate HTTP requests, attributed to bad bots that have also grown in sophistication. An ongoing salvo of requests originating from numerous masked IP addresses can bring your web application down in no time, by creating stress on the web servers, database servers or other elements of the web application.

    The largest such event mitigated by Incapsula in 2Q peaked at 108,288 RPS (requests per second). The longest ran its course over 67 days, while 59 percent lasted less than 30 minutes. The company attributes this to an increased number of “casual” offenders.

    Examining Risk

    The Open Web Application Security Project (OWASP) offers a brief look at risk assessment:

    • “… inadequate resources, requires attention if system architecture was not designed to meet traffic demand overflows … left unchecked, [it can] result in DoS symptoms absent an actual attack.
    • “… perhaps the largest risk factor is not technical … An organization should avoid taking action that can make them a target of a DoS attack unless the benefits of doing so outweigh the potential costs or mitigating controls are in place.
    • “Other risk factors may also exist depending on [your] specific environment.”

    The first item above can apply to any website. While one might think that the second might only be applicable to political entities, what about ecommerce sites based on competitive pricing? Unless strong DDoS defenses are in place, such a site won’t last long in today’s ultra-competitive digital world.

    So what can an organization do about fending off DDoS attacks? With assaults becoming both easy to launch and more sophisticated with each passing day, it’s imperative to keep up to date regarding the evolving threat landscape.

    Securing Your Apps

    Using software and plug-ins for which the latest security patches have been applied is a great start. Penetration testing is a highly recommended critical step before going live. Here, OWASP offers a complete online guide to assist you in your efforts.

    OWASP also offers several examples showing where code vulnerabilities may have been overlooked, ranging from user-specified object allocation to locking customer accounts.

    Once your app has gone live, monitoring site traffic to benchmark volume and visitor types helps ensure its reliability, as unwanted traffic can be detected and quickly addressed. Assessing traffic flow summaries is a start, followed by such tasks as examining IP source geography and unique source IPs hitting your site.

    But data analysis is only a start. SANS Institute offers this guide to help you learn more about successfully mitigating a DDoS attack.

    Most importantly, your operations team can create a response plan to minimize the impact of an assault. An effective plan includes procedures for your customer support and communications teams, as well as keeping CxO executives in the loop.

    Choosing the Right Mitigation Option

    Find a mitigation strategy that works best for your specific business needs. Planning includes prioritizing your concerns and examining the benefits of various mitigation options against your security budget. This is where it’s potentially more cost-effective to engage specialty security services (and their dedicated teams) rather than to try to “roll your own.”

    Ensure the DDoS protection you currently have offers the scalability and security capabilities needed to keep your site and server from crashing in the event of an attack.

    About the Author  / Ben Herzberg

    ben-herzbergBen Herzberg is security research group manager for the Imperva Incapsula product line at Imperva. Ben’s a  developer, hacker and technical manager, deeply interested in different technologies and focused on information security. He enjoys developing something new that just wasn’t there before, or solving a puzzle in a different way. Connect with him on LinkedIn and Twitter.

  • DDoS Defense: Can You Tell Friend from Foe?

    DDoS Defense: Can You Tell Friend from Foe?

    In many organizations, networks are at the core of the business, enabling not only internal functions such as human resources, supply chain and finance, but also the services and transactions the business depends on for revenue. That makes network availability critical. Any interruption of access from the outside world turns off the revenue spigot, impacting profit and creating a poor user experience that can damage customer satisfaction and result in customer loss. The worse the outage, the worse the damage. That’s why speed is so important in detecting, diagnosing and responding to denial of service (DoS) and distributed denial of service (DDoS) attacks.

    One of the chief challenges in responding to an attack is to distinguish friend from foe. Without a way to drill down into traffic details and examine host-level traffic behavior, it can be difficult to tell the difference. Traditional network analysis technologies based on pre-cloud architectures have been too limited in their compute and storage capacity to do more than perform predefined alerting and summary reports. That’s just not enough information to really get to the heart of what’s happening in a complex networking scenario.

    Fortunately, new big data techniques allow us to dig deep into huge volumes of network traffic details so that it’s possible to understand what is really going on. With a properly implemented big data platform, you can pivot your views of data to gain insight rapidly, in operational time frames, so you can act to mitigate an attack or remediate a more innocent but still painful network issue. We’ll examine data that is readily available through common network traffic flow telemetry exports such as those provided by routers and switches enabled by NetFlow, sFlow or IPFIX.

    Starting at the Top

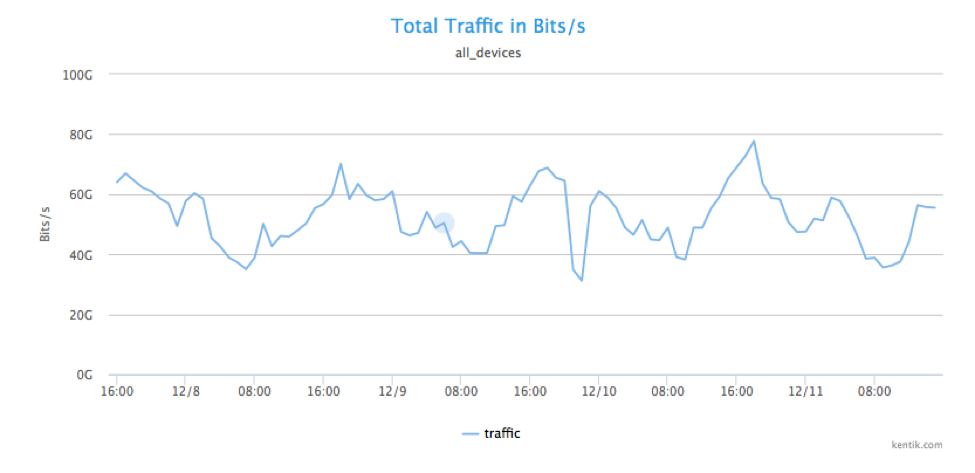
    Let’s say we’re seeing symptoms of an attack in our infrastructure. We’ll use traffic flow summary data to quickly scan total traffic in bits per second just to see if anything stands out.

    Picture1

    There’s no obvious traffic spike from this view, but then again the network we’re looking at is running at an average of 60 Gbps, so that doesn’t mean there aren’t worrying things going on at deeper levels of the network.

    Analyzing Source Geography

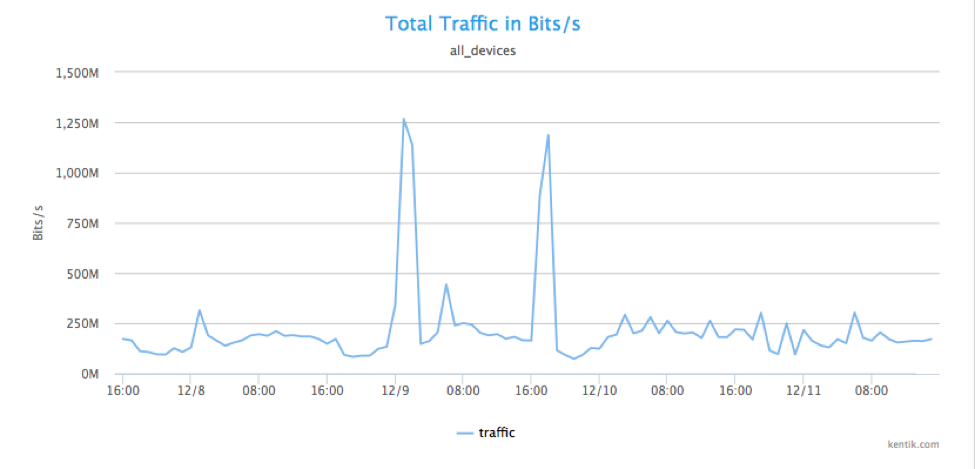
    One of the things that big data is good at is fusing many data sources together. By combining NetFlow data with GeoIP, we can look at traffic by source geography. In this case, the network doesn’t get a lot of traffic from China, so what happens when we filter total traffic by China as source?

    Picture2

    A ha! That analytical pivot produces a graph above, showing two obvious spikes that are well above average. Below, we zoom in on the time of the spikes.

    Picture3

    Analyzing Unique Source IPs

    The spikes themselves are suspicious, but is this just a large data file transfer? We can find out by looking at how many different source IPs are sending traffic. To look at host-level details, note that we’ve gone beyond the point where you can use summary information. At this point, we are analyzing raw NetFlow record details.

    Picture4

    Those raw NetFlow details sure are useful, because there is, in fact, a huge increase in the number of unique source IP addresses sending traffic to particular destination IPs. This tells us that we’re not looking at a large file transfer from a single machine, but a highly distributed set of senders. Botnet much?

    Who’s Getting Hammered?

    The next step is to  to determine which IP or IPs are getting all this (probably unwanted) traffic from 14,000 or so individual host IPs.

    Picture5

    The ability to dig into high volumes of host-level NetFlow details again proves its utility. We can see that the main target is a solitary destination IP address. There’s really only one likely explanation for traffic from thousands of hosts in a country which you have no business dealings with to a single IP that suddenly spikes from nearly nothing to more than 1 Gbps: This is a DDoS attack. Note that this isn’t a mega attack, but it still can cause real problems for whatever is running on that individual host and anything else that depends on it. If it’s your DNS server, the attack might make it impossible for lots of other servers and applications to function.

    Going Deeper

    Now that we know it’s a DDoS attack, we shouldn’t stop because we don’t know whether that attack is coming from other countries besides China. We pivot our analysis again to widen our lens.

    Picture6

    Lo and behold, there is indeed DDoS traffic coming from multiple countries, including the United States, Japan, Russia, Sweden, China, Taiwan, Brazil and Estonia. Good to know.

    Characterizing the Attack

    Next, we want to know specifically what type of traffic we’re seeing and what that tells us. We’ll group the traffic coming from all those source host IPs by protocol.

    Picture7

    Clearly, this is  UDP-based attack. Now we’ll look at the destination port(s).

    Picture8

    We can see that the UDP traffic is being sent to multiple ports, and it’s obvious that we’re experiencing a DNS redirection/amplification attack occurring on port 53, with a lot of port 0 UDP packet fragments being generated as collateral traffic.

    Is Something Underneath This Attack?

    So far we’ve gotten a lot of insight into the details of the DDoS attack from full NetFlow details. But is this volumetric DDoS the main event, or are we being distracted from looking for other, less obvious threats? We can see a lot of packets being sent to port 4444 (green line in graph).

    Port 4444 is the UDP port for the Kerberos service, and is—at least for Windows machines—a well-known target for buffer overflow attacks, often used to insert trojans such as Hlinic and Crackdown.

    So, potentially there are two types of attacks going on in parallel: a DDoS attack and a buffer overflow trojan insertion. Many security blogs and publications note that DDoS attacks often are used to obfuscate other exploits. This very well may be an example of that technique.

    Getting a Handle on Attack Mitigation

    Characterizing the attacks leads us to mitigation. One way is to take the attack traffic and group it by x/24 source network addresses:

    Picture9

    We now can take two mitigation steps:

    • Ask our upstream ISP to drop this traffic or send it to a scrubbing service or device, if we have one.
    • As an added precaution, drop all traffic from these countries going to port 4444 on our own routers.

    Conclusion

    One of the benefits of being able to dig into full-resolution NetFlow data is that you can get operationally useful insights without needing in-line devices. You also get more freedom to employ a portfolio of mitigation methods. Big data is the way forward if you want to have full details at your disposal to deal with DDoS attacks.

    About the Author / Alex Henthorn-Iwane

    AlexAlex Henthorn-Iwane is the Vice President of Marketing at Kentik. He has more than 20 years of experience bringing new technologies in networking, security and software to global markets. Henthorn-Iwane leads the global marketing strategy for Kentik and help the company bring its innovative story and solutions to network-dependent organizations around the world. Connect with him on LinkedIn, Twitter or SlideShare.
  • Why do you need to implement a DevOpsSec team?

    Why do you need to implement a DevOpsSec team?

    Just 20 years ago, organizations relied on a single wall of defense to secure their applications and networks. Fast forward to 2015 and that large fence is no longer adequate. With the proliferation of mobile, cloud and SaaS technology adding to the complexity of ever-advancing systems and networks, it becomes much more important that teams across an organization work together as one, toward a common goal. We’ve already seen enterprises adopting new methods of organizing internal structures to increase collaboration through DevOps, but as security continues to be top of mind for organizations, many are looking to further this approach by including the security team in the DevOps conversation. With a DevOpsSec team, organizations can work toward delivering software that is not just reliable, but also secure.

    Introducing security to DevOps provides the means to this protection by reducing the number of bugs and vulnerabilities during the build process before code hits production systems. Moving security as close as possible to the code and data will bring a large number of high value benefits to an organization.

    The first benefit of introducing security to DevOps is the enablement of team collaboration through tight feedback loops. Development, operations and security teams all have different goals and are motivated by different things, which are often contrary to the other teams. To ensure that these groups don’t work as adversaries within an organization, DevOpsSec encourages them to work together, pulling from all parties’ strengths and building a collaborative and engaging environment. This collaboration offers transparency into the assorted issues that arise within each team, establishing a deeper level of understanding and respect across the board.

    The second benefit is that DevOpsSec provides a wider perspective across previously siloed teams. As a result of greater team collaboration, Dev, Ops and Sec teams are able to gain more insight into how the other teams operate. This widened perspective decreases friction between them, further revealing common goals and generating more natural solutions. Overall, the assortment of perspectives results in more efficient strategies for the organization in keeping its systems secure.

    Lastly, the implementation of DevOpsSec ensures faster response time to issues. As applications and systems become more distributed and complex, it becomes more difficult to identify and fix bugs and vulnerabilities. Developers are writing and pushing code faster than ever before, and what used to be monthly or longer release cycles can now be measured in hours. This is due in part to the fact that code is being used both inside and outside our networks, requiring more thorough network security. The new normal will be found in developing DevOpsSec teams and moving the security as close as possible to the code and data. Through more continuous review processes and more ownership over code in production, the merging of DevOpsSec can mean faster times in closing feedback loops and will ultimately help organizations to operate more efficiently.

    So what will an organization look like after implementing DevOpsSec? As a result of the cross pollination between teams, organizations will have curated an elevated platform for innovative ideas, gained greater insights across teams and developed faster response times to help the business run smoother. With DevOpsSec in affect, organizations will better understand and anticipate security issues and the decisions required to diminish them.

  • Combining SecOps and DevOps

    Combining SecOps and DevOps

    Security has to be top of mind for most any company that is moving, or has moved, to the cloud. And, businesses know they need to act swiftly to ensure that any new products or services they’re dreaming up do not expose them to risk.

    How can they do that when the fast-moving nature of the cloud is leaving proper security practices in the dust? The problem today is that today’s security solutions are proprietary, too slow and take too many resources.

    Bottom line, the security model that has served most businesses well was never built for speed, and is simply unsustainable for opportunities in today’s cloud-centric world. Today, security solutions must be agile, lightweight, loosely coupled and extensible.

    On the front lines at various companies you’ll see a new type of cooperation –  where two teams most directly involved in a potential solution, development and security – are breaking down the traditional (and often opposing) silos and collaborating more openly to drive secure innovation from the start.

    We’re seeing a new “marriage” of SecOps and DevOps that creates a whole new mentality for driving innovation inside and outside of organizations. This new mentality allows security and DevOps to find common ground to make it easier for organizations to align their security goals with the delivery of their products at today’s rapid speed of business.

    While businesses are changing internal structures to address cloud security, there are also a number of new solutions that can be deployed against a company’s clouds and deliver security intelligence back to the DevOps teams.

    These kinds of tools are especially important for start-ups and SMBs that face unique challenges securing their businesses from cyber attacks and preventing data breaches.

    By encouraging greater collaboration between security and DevOps, and relying on outside solutions to assess and identify potential threats as new products and services are developed, businesses of all sizes can feel a higher level of confidence that they’re addressing security concerns by enforcing industry-leading security practices every step of the way.

    About the Author:/Tim Prendergast

    tim p Tim Prendergast co-founded Evident.io to help others avoid the pain he endured when helping Adobe adopt the cloud at a massive level. After years of building, operating, and securing services in AWS, he set out to make security approachable and repeatable for companies of all sizes. Tim led technology teams at Adobe, Ingenuity, Ticketmaster, and McAfee.

  • Embracing a culture of continuous incident response

    Embracing a culture of continuous incident response

    In a world of continuous development and rapid iteration combined with being connected online 24/7/365, you are bound to encounter threats. In fact, attackers use automated tools so you are under constant siege from continuous threats. The natural response is to implement some form of continuous incident response.

    The standard development model involves different stages of requirements gathering, writing code, and beta testing, resulting eventually in a defined, periodic software release. That model is being replaced by the DevOps culture of continuous development. Security faces a similar transformation from the pervasive legacy model of the “us vs. them” protect-the-perimeter model to a new system of continuous incident response that addresses the current threat landscape in the real world.

    There is no “us”, and there is no “them”. There is no perimeter. Your authorized users are actually more likely to expose sensitive data, or compromise your systems—whether intentionally or inadvertently—than external bad guys. Your authorized users are also just as likely to be “outside” of the mythic perimeter—connecting from personal smartphones or tablets, or logging in from a Starbucks across town. The traditional security model is simply not equipped to deal with today’s technologies or threats.

    So, what is continuous incident response? I spoke with TK Keanini, CTO of Lancope, who explained, “Some people when thinking about process think of it as a linear model where there is a beginning and end; a better way to model adaptive processes is with a loop and continuous incident response is a loop.”

    He elaborated, “Borrowing from John Boyd’s OODA loop, continuous incident response is where there is an observation, orientation, decision and action cycle that outpaces or runs at a faster tempo than the adversaries.”

    Zane Lackey, director of security engineering for Etsy.com, gave a presentation at the Hacktivity conference on the topic of “Attack-driven Defense”. The concepts he described are essentially the sort of logic and pattern that need to be applied for continuous incident response.

    There are a few key elements organizations need to embrace in order to effectively implement continuous incident response. The first is the loop Keanini described. In order to be “continuous”, you have to continue to cycle through the various phases. There is no “end”.

    One of the crucial components of continuous incident response is continuous monitoring. It isn’t good enough to scan the network once a month, or once a week, or even daily. The threat landscape is constantly changing and evolving, and you have to be continuously monitoring for new vulnerabilities, new attack techniques, and anomalous or suspicious activity that might indicate a security incident is occurring.

    Another important factor is to view continuous incident response as a cross-functional business process. Keanini stated, “I think continuous incident response—when implemented well—touches all critical parts of the business, not just IT. Making it an IT thing is just too narrow and people who experiment in this manner are destined to fail.”

    Companies that have a DevOps mindset, or have adopted DevOps principles will find it easier to relate to the concept of continuous incident response. DevOps organizations are not constricted by the departmental barriers of traditional companies. The hierarchy and red tape of an org chart can get in the way of effective continuous incident response, but DevOps businesses have a more open, fluid organizational structure that makes it much easier to adapt to the dynamics of both operating on, and responding to threats from the Internet.

    Adopting continuous incident response may be easier said than done. It is a different approach to security, which may make it more difficult to get buy-in and support from executive management. You may also encounter resistance from the IT admin and existing security personnel because they’re used to doing things the old-fashioned way, and change is uncomfortable.

    Keanini sums it up well, though. “Just step back and ask yourself how important being connected to the Internet is to your business or customers—and then just consider that continuous incident response is the cost of doing business on the Internet.”