Tag: NetOps

  • Bridging the Network Automation Skills Gap

    Bridging the Network Automation Skills Gap

    With the introduction of network programmability and APIs for everything from management systems to devices themselves, the modern network landscape has evolved to being managed like software. This shift from hardware-focused networks to software-centric functions has had a profound effect on network management techniques and skillsets required to keep pace with the changing ecosystem.

    A recent EMA survey notes that skills gaps associated with network automation are an issue for 96% of enterprises. Even respondents with significant network automation initiatives in place felt their solutions stretched the abilities of their network teams. Network automation can expose skills gaps where network engineers might lack experience with new tools and software development. At the same time, application development teams, who likely would be included in building an in-house network or automation software solution, will also lack networking skills. Hybrid skills with both development and networking expertise are rare and available only at a premium.

    This journey to network automation can be difficult, especially given the required technical skills that are not in abundance within many organizations. Simplifying network automation and empowering a broader set of participation through capabilities to easily create and manage automation workflows presents a key opportunity for organizations to not only mature efforts around network automation, but to also execute against broader business digital transformation objectives.

    Four Keys to Democratizing Network Automation

    The key to democratizing network automation and bridging the skills gap is to provide NetOps teams with the ability to easily design and build network automation without having to re-tool, build custom code or learn specialized software skills. There are four key elements required to effectively democratize network automation in the enterprise.

    Easy Onramp for Non-Developer

    Automation is typically accomplished through writing code in a particular programming language. For a person without any programming skills (or even minimal skills), they must first learn how to code before they can even attempt their first automation task. This is very difficult in terms of time and interest. Additionally, many network engineers see the amount of work it would take to learn to write code, and become disinterested. There has to be a new set of tools and methodology to empower these people to automate their work without the long road of learning to become programmers. It’s important to invite as many people to the automation table as possible including IT, security, cloud and NetOps teams, to streamline business processes.

    Capture Network Tribal Knowledge

    Within the organization, there is already existing embedded tribal knowledge that is incredibly valuable. By harnessing and transferring that knowledge into an automation workflow without a lot of programming, it provides an accelerated path to network automation. The goal is to leverage traditional network automation and management practices (Scripts, CLI) for re-use across the organization.

    Network engineers with years and years of experience have a valuable set of processes and procedures they’ve built up inside their heads, and this wealth of information is a valuable asset. Unfortunately, this information is rarely documented and is normally passed on by activity and word of mouth. This is the type of tribal knowledge that needs to be captured, preferably through automation workflows that can be used in a task, documented in the workflow and modified over time to improve it or change it as the infrastructure changes.

    Integrate DevOps Principles

    Augment network automation with CI/CD pipelines and API services. These are well known solid principles that are already used in other domains outside of networking and pay big dividends when applied to the automation of complex networks. When we look along the horizon of the network automation journey, these same CI/CD practices will be adopted by future networking teams and allow them the same advantages of reliability and velocity within the network.

    Enable Cloud Architect Participation 

    It is important to have networking people that can understand the networking constructs of the cloud, as well as cloud teams that understand how it integrates and operates within the network. Enabling cloud architect participation in network automation will allow for the real-time feedback and control of cloud-based applications and infrastructure critical to modern networks.

    Cloud networking is increasing in complexity and will soon require the skills and experience of network engineers to help solve the problems of cloud networking. Traditionally, cloud and networking teams have been separated because their technology domains have been siloed and there was very little interaction required between the teams. As technologies like SD-WAN have been adopted, the line of responsibility between cloud and network teams has blurred. Cloud and networking teams will need an automation platform that can be used by both to create workflows and automate between both domains. Business technology decisions are forcing these two groups together, and they must have a way to use their own tools, but also have a platform to collaborate automation between them.

    As applications and services are becoming more complex, distributed and require connectivity and policy enforcement across a diversity of domains (such as cloud, SD-WAN, data center, wireless and network applications), the management of these network concepts requires us to re-think how we have traditionally managed networks. As network automation plays an increasingly larger role in enterprise networks, a byproduct of the complexity is a skills gap that threatens to slow or stymie enterprise initiatives.

    By making the onramp to network automation easier for non-developers through capturing tribal knowledge, integrating DevOps principles and enabling cloud architect participation, enterprises better ensure a successful migration to network automation across multiple domains.

    — Rich Martin

  • F5 Networks Launches Next-Gen ADC Based on NGINX

    F5 Networks Launches Next-Gen ADC Based on NGINX

    F5 Networks this week launched version 3.0 of its NGINX application delivery controller (ADC) that adds application programming interface (API) management tools, analytics and monitoring tools, a service mesh, a certificate manager, a developer portal and integrations with multiple continuous integration/continuous deployment (CI/CD) platforms.

    Ken Bocchino, director of product management for NGINX at F5 Networks, said as the first major update to the NGINX Controller since F5 Networks acquired NGINX last year, the 3.0 release represents a concerted effort to reduce the total cost of DevOps by bundling many capabilities that previously would have needed to be acquired separately.

    In addition, NGINX Controller 3.0 reduces the complexity associated with building DevOps workflows because all the components that make up NGINX Controller have been pre-integrated, said Bocchino.

    Based on the open source NGINX proxy server, NGINX Controller is the mechanism through which commercial capabilities are provided and supported as part of the NGINX Plus subscription service offered to enterprise IT customers. Previous iterations of ADCs were much more infrastructure-centric than application-centric, noted Bocchino.

    While F5 Networks naturally would prefer IT organizations to consume all those services, Bocchino said the ADC has been designed in a modular fashion to enable organizations to consume services exposed as REST APIs as they see fit. A future version of the NGNIX proxy server will be able to support multiple types of service meshes, including the lighter-weight offering created by the NGINX team that will become available later this year as part of NGINX Controller 3.0, he said.

    Bocchino noted F5 Networks envisions the NGINX Controller playing a major role in driving further convergence across network operations, security and DevOps teams. NGINX Controller 3.0 facilitates that goal by providing a self-service portal along with role-based access controls and modular workflows that eliminate the need for tickets to be issued to achieve every IT task.

    It’s not clear at what rate that convergence is occurring. However, F5 Networks last year published a survey of DevOps and NetOps teams that suggests there is still a wide gap between NetOps and DevOps teams. The survey found only a little more than a third (38%) of DevOps teams cited the “integration of toolsets across vendors/devices” as a challenge to network automation. In contrast, almost half of NetOps respondents (47%) noted a lack of integration as a problem, second only to a lack of automation expertise (49%).

    F5 Networks by acquiring NGINX is betting than most organizations that have already embraced NGINX proxy server software would rather extend those existing capabilities versus replacing their ADC with a new stack of software based on, for example, the rival open source Envoy proxy server being developed under the auspices of the Cloud Native Computing Foundation (CNCF).

    How the proxy server war and associated ASC platform wars will play out is still anybody’s guess. What is clear is that DevOps teams will need to access a wide range of programmable networking and security services easily to take DevOps to the next level.

    — Mike Vizard

  • IoT, AIOps and OMG!

    IoT, AIOps and OMG!

    The task of keeping networking straight while expanding the definition of network to include both physical and virtual networking has fallen heavily upon the op-centric side of DevOps–or what I like to call devOPS. What is defined as networking has grown, sometimes at a ridiculous rate. While the terms are familiar, how you manage them in truly virtualized environments is different than traditional hardware management. More agile, but different.

    And that means those who deal with networking in DevOps have to know more, manage more and debug more–all while working on other parts of the DevOps toolchain. It’s been a slog through increasing capability with increasing workload.

    There is a confluence of new and different things that promise to set this lopsided progress right. We’ll look at them individually, then talk about the sum of the parts.

    Internet of Things (IoT)

    For most of us, when we hear IoT, we think of millions of devices slamming data into a centralized service. iPhones, for example, returning information to Apple. Or highly specialized devices such as utility meters that report far more frequently than humans could go out and read them. But IoT is many things, and increasingly IoT is networking devices. They hold a wealth of information about the state of the network at any given moment, and that information is increasingly being funneled into APIs that IT or management apps can take advantage of. Considering that some of those management apps are also getting data from application tooling and server health status, there is a wealth of information coming together in one place.

    AI Operations (AIOps)

    A networking device can be doing a lot in any given second, and generating data as it works. Servers can be on their way offline when they feed the information out, or maybe sitting idle and wanting more work shipped their way. Application bottlenecks might be identified in the wealth of application tooling information, but buried under the wealth of other response data being shipped back. AIOps aims to help the devOPS side deal with these issues by limiting what makes it to human attention and drawing correlations between issues. Finding that an over-burdened network connection is associated with an apps performance degradation is an easy one to talk about, even though it is pretty simplistic. AIOps can make the connection before a human gets involved, and then the staff member can decide what to do about the actual root cause.

    It’s not at all perfect yet–we’re not generally talking about AIOps making a ton of decisions, rerouting traffic or spinning up new instances to resolve issues at this point–but it is definitely in the “useful tool” category. The cost in person-hours to analyze and reduce problems is definitely cut by the use of AIOps as it exists today, and that benefit will only grow moving forward.

    The biggest problem is the one that bedevils all data interchange, and in fact is the biggest issue in the world of big data–data standardization.

    Enter OMG

    No, my OMG in the headline wasn’t what you thought. It was the Object Management Group (OMG). They’ve been around forever, and have done a pretty good job of developing useful standards, particularly in the area of data interchange. I’ve followed them for a long time, and used their standards since … well, anyone remember CORBA? That was my first set of OMG standards.

    Now they’ve started an Artificial Intelligence Platform Task Force (AIPTF). This group will be looking at all areas of AI to set standards, but the interesting bits for this blog will be in data standardization and communication. Standardizing data and how it is communicated is the next big step in this process, and hopefully the OMG will set us down that path. They’re not specifically looking to address infrastructure big data needs, but their work will likely guide AIOps moving forward. And there is huge potential in that movement. If AIOps gets some standards that help it to be more proactive, we may actually end up with auto-fixing algorithms for obvious and easy issues. We already have the systemic ability in container managers to increase the number of instances serving an application if the existing ones get over-loaded, if we could expand that type of auto-growth to include networking issues and consider cores used by instance to find the best solution. Members of the team that are more devOPS will have more time to focus on new development. And that’s a huge plus.

    The Future is Bright

    Whether the work at OMG benefits us will depend upon whom is involved in the various subgroups they have planned to implement, and cooperation with other ongoing efforts at standardization. Yet I’m hopeful that, like with that original CORBA spec, they will provide a roadmap that others can follow to put us on the path to the much-maligned self-healing network. Giving devOPS a chance to keep up, while leaving them ultimately in control of what happens. Current iterations of AIOps do this to a lesser extent, but more inputs and more automated analysis of those inputs will only make AIOps more powerful. Standardization will make AIOps more able to make use of data and better focused on their specific problem at hand. I see the confluence of all three trends to be a huge positive to the industry if we manage to take advantage of it. And some vendor out there will see the potential, taking advantage of it for us, we just have to find them and use their solutions.

    Meanwhile, paw through the data available to you by hand again, and keep knocking those walls down.

    — Don Macvittie

  • Catchpoint Expands Network Monitoring Service Reach

    Catchpoint Expands Network Monitoring Service Reach

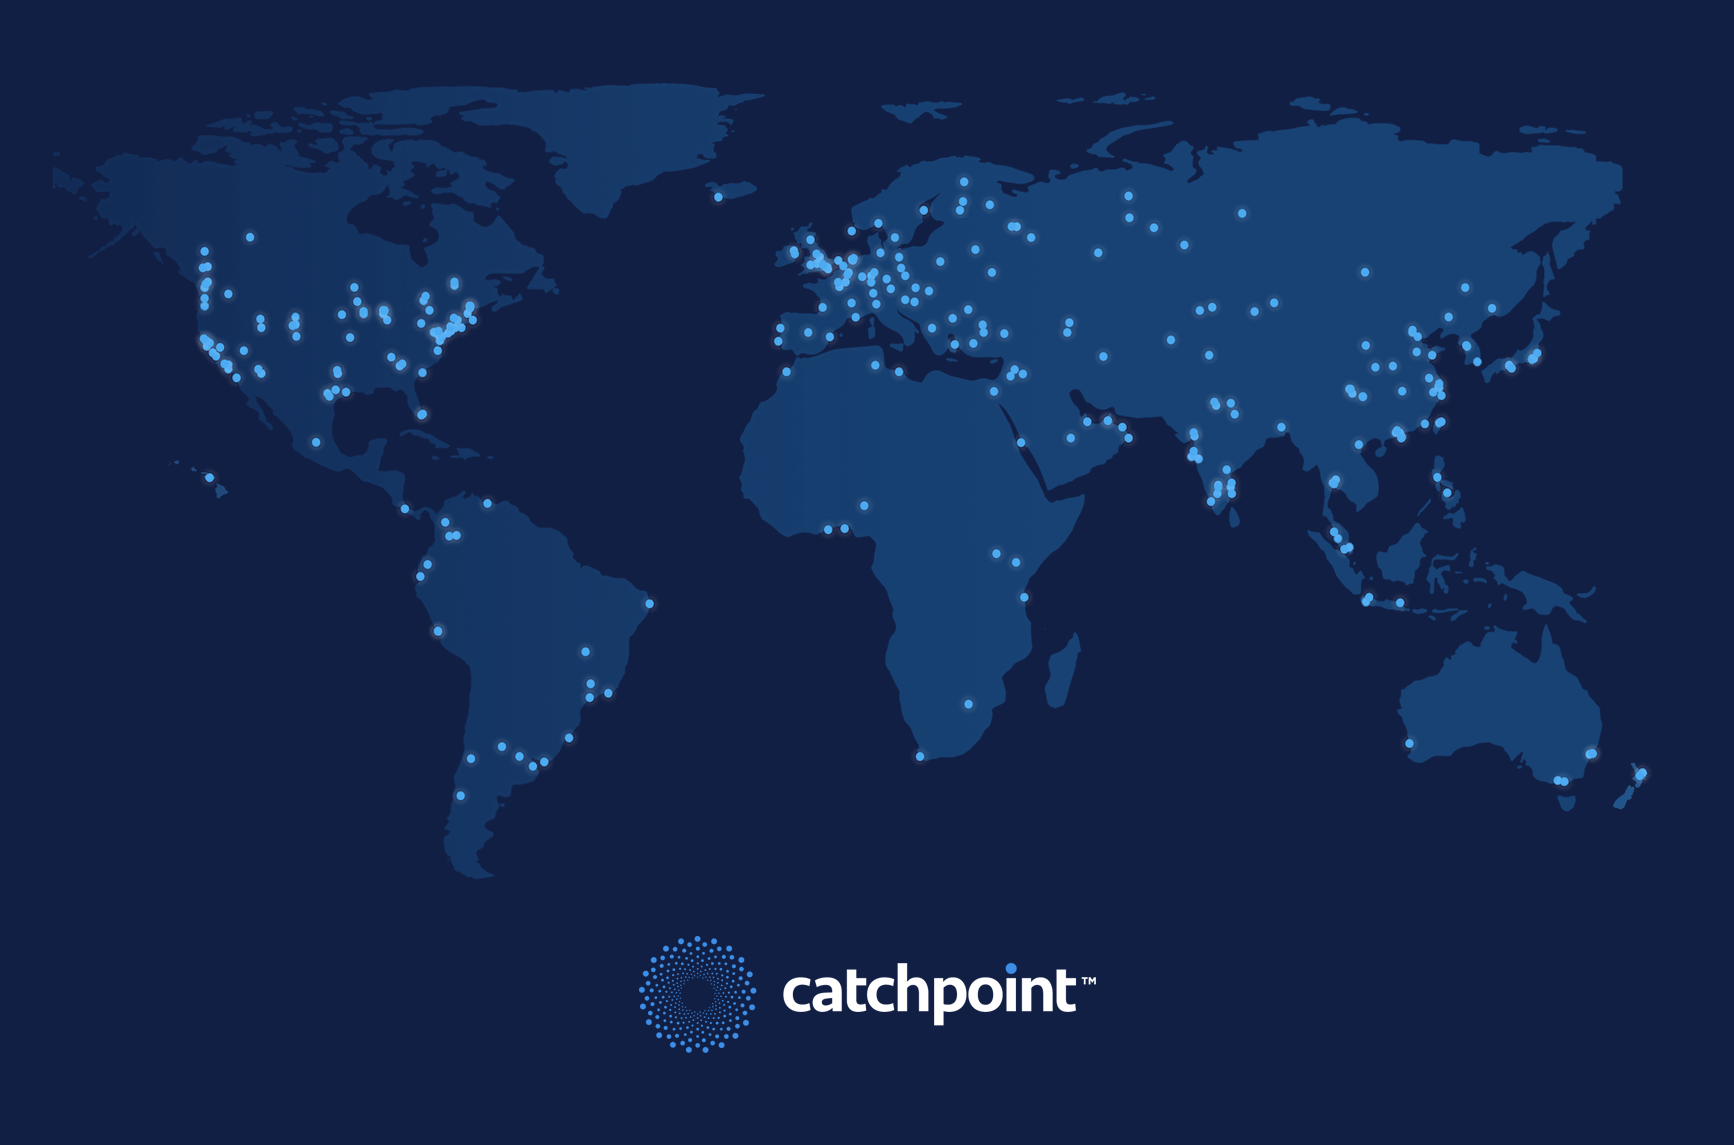
    Catchpoint has expanded the number of locations worldwide from which it is gathering telemetry data for its networking monitoring service to more than 825 sites.

    Drit Suljoti, chief product officer for Catchpoint, said as applications continue to become more distributed, the worlds of DevOps and network operations (NetOps) converge. DevOps teams need more visibility into how network latency issues anywhere in the world are impacting the digital experiences of their end users, said Suljoti.

    The Catchpoint monitoring service now extends to 200 cities worldwide, including 140 nodes in mainland China. In addition to monitoring critical backbone locations, Catchpoint has placed nodes in 133 public cloud locations and is now offering a free and seamless migration for companies looking to adopt a next-generation digital experience management (DEM) platform in place of Gomez and Keynote services from Dynatrace that recently were retired, said Suljoti.

    In much the same way DevOps teams rely on a variety of tools to monitor applications, they also need access to a service that continuously monitors the networks on which those applications depend, Suljoti said. That requirement has become more critical as the number of latency-sensitive applications such as those based on microservices increases, noted Suljoti. As organizations depend on those applications to drive a variety of digital business processes, visibility into how the network is impacting the application experience of end users can easily degrade, he added.

    Most organizations already have tools to monitor network performance within their own data center. However, creating the monitoring framework required to identify network performance issues across a global wide area network (WAN) would be cost-prohibitive for most organizations. When it comes to deploying applications that span multiple WANs, most DevOps teams are essentially blind.

    It’s still not clear within many organizations who is responsible for monitoring WAN services. Historically, NetOps teams have held this responsibility. However, Suljoti said that as DevOps processes continue to expand and mature, there is a more collaborative approach emerging that incorporates network monitoring tools within testing frameworks that organizations create within the context of a continuous integration/continuous deployment (CI/CD) process.

    In the meantime, pressure on existing WAN networks will only increase. In the absence of 5G services, the number of applications competing for access to bandwidth increases. Many organizations have no idea whether network service providers are really meeting the commitments they agreed to as part of the service level agreement (SLA) provided. As more application performance issues get traced back to the underlying network, frustration with the quality of network services is only going to mount. Before they can call network service providers to account, DevOps teams will need access to analytics that clearly show service level commitments are not being met.

    Of course, that may only elicit an apology from the network service provider. At the very least, however, DevOps teams will be able to make a much more informed decision concerning how they want to route application traffic going forward.

    — Mike Vizard

  • Embracing the Product Development Cycle

    Embracing the Product Development Cycle

    Nowadays, a truly successful product calls for purposeful investment in the people that will ultimately use it in their specific environments.

    We all know technological development is hyperactive and unpredictable. Ultimately, we want to be able to create cutting-edge tech, deploy it wherever it’s needed and have it operated by skilled staff that understand all the nuances. We need to be able to move fast, adapt on the fly and do so with security mechanisms that fire on all cylinders–irrespective of environment.

    The best way ahead is to actively engender a more informed user base that can apply experience and context. There are big benefits to be had by doing this. With the right investment and infrastructure, the aim is for informed and confident end users to form symbiotic relationships with the vendor, helping to guide product and solution development on an ongoing basis. Operational challenges are not static, so the technology in place to meet them certainly shouldn’t be.

    Vendors need to embrace the mindset that a product’s lifecycle needn’t be clunky, disrupted by diversions or constrained by boundaries. It is all about continually engaging and listening to every contributor to a product’s existence: customers, partners, engineers, support staff–the whole ecosystem. Collaborate, innovate, feedback, improve and repeat. The future is a dynamic continuum of constant innovation and improvement.

    As part of F5’s transformation to a multi-cloud application services company, we had to train hundreds of engineers around the world with a new set of foundational skills in cloud, automation, orchestration and DevOps methodologies. Essentially, the process entails developing training content to test with a selection of key users. Areas of improvement are identified, and these are then built into the product. The cycle is repeated.

    It may sound simple but you’re not going to get the substantive, actionable feedback you need without instilling the right culture. For this, you need a lot of training and documentation. You need to guide the way with strategic credibility and maintain confidence. Above all, you need to be patient and listen.

    At F5, we’re constantly building out the mechanisms for how we train in conjunction with our development efforts. A big part of that is integrating adequate feedback loops—both on the training and products front. If a customer hits a wall, what did we learn? How can we contribute via open source? How do we leverage what we learned to make our products and people better?

    We’re not just building automation and orchestration solutions. We’re aligning to the methodology around DevOps and the software process. We’re designing as if it were a giant distributed software project that happens to run on and integrate with the F5 platform. All of this gives us the means to start a new conversation with customers, one that is entirely based on how to achieve successful outcomes. Sometimes we may assent to, for example, the introduction of a new feature. Sometimes, we’ll push back. We will always be agile, adaptable and collaborative. It is never anything less than an eye-opening journey. It needs to be. We have no interest in directionless wheel-spinning, nor do our customers.

    Another major benefit of our approach is it explicitly and effectively helps NetOps become a true partner of DevOps. This means projects are no longer bounced around in silos, bottlenecks are eliminated and the results speak for themselves. Going through this process and making these shifts have fundamentally changed F5’s ethos and identity. We had to change in order to fully engage with the bleeding edge, with the way container ecosystems are built, the way microservices are built or the way software is developed in the modern age.

    — Hitesh Patel

  • DevOps and Networking: Working to Achieve Nirvana

    DevOps and Networking: Working to Achieve Nirvana

    Enterprises don’t own the cloud, just the experience. If there’s an outage or even a hiccup in the performance or network service, it’s on the network and application teams (not the cloud provider) to fix it. But often with problems in the cloud comes finger-pointing, as network and application teams look to determine liability and responsibility when it comes down to crisis situations.

    There is no question that applications are growing more complex, as is the infrastructure to power those applications. According to the 2019 “Stack Overflow Developers Survey,” comparing year to year the amount of time it takes for software engineers to become effective on teams is increasing. This trend could be, in part, due to the amount of tooling and rise of an operate-what-you-build model (e.g., the dawn of the full lifecycle developer). As our applications become more distributed—and to cope with scaling and availability demands—skill sets that traditionally were infrastructure and development-based have begun to blur.

    Networking Shifting Left

    Networking-centric capabilities such as service meshes (e.g., Istio and Linkerd) and container networking interfaces (e.g., Calico and WeaveNet) are gaining a lot of traction and visibility in the cloud-native application development world. Though SDN infrastructure has been shifting left toward development pipelines, application development teams are learning networking concepts. However, the core networking infrastructure is still maintained by the networking teams.

    This paradigm of software-defined infrastructure is creating a learning curve for multiple teams. With the dawn of NetOps, software development lifecycle (SDLC) principles are being introduced to the networking teams. Traditionally, ticket- or service-driven networking teams can participate in iterations and they are now building the next generation of cloud-agnostic networking capabilities. With NetOps, there is more interaction and innovation. But change is not without resistance; the dynamic nature of modern infrastructure and the short-lived nature of pre-emptible/ephemeral infrastructure do not bode well for static networking rules.

    Networking Team Pressures Today

    With infrastructure headed to the trifecta of clustering, replication and load balancing, networking teams have to deal with many more dynamic addresses than before. Static ports and addresses that used to be loaded into networking tickets are now being replaced with wide ranges and service addresses powering the networking stack of our cloud-native and containerized workloads. Adding to the complexity, the networking team is leveraging public cloud infrastructure. The infrastructure that the networking teams are responsible for is leaving the data center and distributed web infrastructure technologies, such as distributed domain name systems (DNS) and content delivery networks (CDNs), are common for the networking teams to be involved with. Like the application development teams, the amount of new technology hitting the networking teams is increasing.

    One of the great advantages of using public cloud infrastructure is the ability to quickly expand or contract available resources. With this ability, we can spin up and down test environments to try out changes and even the infrastructure level that was not even possible. With this, we have the ability to integrate more. The application development team, which has been iterating for some time, now has common ground with the networking team to try out iterations.

    All in a CIDR

    To illustrate the needed collaboration between networking and application teams, let’s look at an example:

    In one of the biggest incidents of my career, my company was migrating pieces of our platform to a public cloud vendor. Because the organization was early on in this transformation, a lot of minutiae was yet to be flushed out. We were packaging classless inter-domain routing (CIDR) calculations into our first-time VPC configurations—a task the development team was responsible for at the onset of our cloud migration. It was my job to enter this for my service. Instead of a /8 CIDR, I implemented a /16 CIDR. A seemingly small miscalculation on several configs turned into an incident, blocking a majority of traffic hitting the service. The mistake was quickly corrected, but the incident response framework was well on its way to being executed.

    So, who was responsible? I was the one who created the configuration and pushed to production, so this was my fault. But in retrospect, the best solution would have been to involve the networking team immediately in these types of changes. Because the application development teams were vanguarding into the public cloud, however, we cut out the networking team. This was an organizational problem that needed to be addressed. If we were going to deploy into a data center successfully, the networking teams needed to look over my requests and catch my CIDR error.

    Silver Lining, Right?

    During this CIDR incident, I was trying to look at the silver lining: Since we can’t access our application, that means the instances/app must have a lot of extra capacity, right? Untimely, yes, but the analogy did make sense with the silver lining. We were getting billed by a public cloud vendor and because there was a drop in usage, our bill technically should have been lower. But it still impacted the customer. The money saved in our incident was outweighed by external measures (revenue and brand damage). A cloud outage and a subsequent dip in digital experience can have a massive impact on revenue, averaging $38,855 per hour of outage. During high impact or busier times, this number can be much more.

    DevNetOps Nirvana

    The adage of bringing everyone to the table early proves to be valuable. Each team in an organization can have a strategic impact and improve architecture in multiple parts of the stack. Different teams have different sets of skills and can have mutual respect for the vertical skills of each of the teams. In the end, a transparent and positive relationship between network and application teams will help with network remediation and outage prevention. And, the closer the teams can work together and the more they can communicate, the more their investments and efforts can contribute to the business bottom line and quicker remediation long term.

    — Ravi Lachhman

  • F5 Networks Acquires NGINX to Meld NetOps with DevOps

    F5 Networks Acquires NGINX to Meld NetOps with DevOps

    As part of an effort to better align DevOps and network operations (NetOps), F5 Networks plans to acquire NGINX, a provider of widely employed open source loading balancing software.

    The two companies revealed in a call with financial analysts that the primary goal of the $760 million deal is to meld the two companies’ combined expertise to develop application delivery controllers (ADCs) that are optimized for modern applications based on microservices.

    F5 Networks CEO François Locoh-Donou said F5 Network plans to continue operating NGINX as an independent brand in addition to maintaining support for the NGINX open source community. NGINX CEO Gus Robertson will become general manager of the NGINX business unit. NGINX founders Igor Sysoev and Maxim Konovalov also plan to stay on.

    Locoh-Donou also disclosed that while NGINX software is employed today at more than 375 million sites, the company only generated $26 million in revenue in 2018, mostly by providing commercial support to enterprise customers. F5 Networks will move to combine investments both companies have been making in containers to deliver a next-generation ADC optimized for microservices-based applications spanning multi-cloud computing environments, he said.

    As part of that strategy, however, both companies will need to come to terms with Envoy, an open source load balancing project led by the Cloud Native Computing Foundation (CNCF). Envoy is already providing the foundation for multiple service mesh projects that make load balancing a feature of a higher-level mechanism for managing services running on a Kubernetes cluster. Obviously, F5 Networks hopes to fulfill an opportunity to manage multiple instances of service meshes running on multiple Kubernetes clusters that.

    In fact, Locoh-Donou cited industry research that forecasts by 2022 there will be more than 198 million workloads running on some form of a microservices-based architecture. In contrast, 44 million workloads are expected to be running on legacy platforms.

    Locoh-Donou said F5 Networks also expects to leverage NGINX to expand its presence in application programming interface (API) management and associated web application services, which he noted collectively represent multibillion-dollar market opportunities.

    The decision to acquire NGINX reflects the inevitable melding of NetOps and DevOps, he added, noting that inconsistent approaches to managing application service across emerging microservices-based environments are a recipe for creating unstable IT environments.

    While it’s still a little too early to determine to what degree NetOps will be subsumed into DevOps processes, Locoh-Donou said F5 Networks plans to advance adoption of NGINX software by educating its core base of NetOps administrators on how microservices applications are deployed across extended networks and the rigors of the DevOps processes required to manage them.

    Both F5 Network and NGINX made a name for themselves by interconnecting IT environments made up largely of virtual machines. While virtual machines are not going away anytime soon, so-called cloud-native applications built using containers running on Kubernetes clusters require a different approach to delivering infrastructure services. The challenge facing the combined company is finding a way to deliver those services in a way DevOps teams want to consume.

    — Mike Vizard

  • Cisco Looks to Build DevOps Community

    Cisco Looks to Build DevOps Community

    Cisco Systems is making a concerted effort to create an era of détente between networking professionals and the rest of the IT operations teams that have embraced DevOps practices.

    Susie Wee, senior vice president for the DevNet community at Cisco, said the goal is to provide network operations (NetOps) teams the skills required to programmatically expose a range of self-service capabilities to developers.

    At the same time, Cisco is encouraging developers to deploy applications directly on routers and switches that now incorporate general-purpose processors. Those processors would run applications in a way that significantly reduces network latency, while the custom ASICs that Cisco develops would continue to handle all the networking functions.

    Wee said that dichotomy is now driving Cisco to classify two classes of developers within its DevNet community. The first is aimed at traditional application developers and the second community is more focused on managing infrastructure as code.

    Cisco is now extending that latter initiative into the realm of software-defined wide area networks (SD-WANs). The company has added integrated firewall, intrusion prevention and URL-filtering technologies to its SD-WAN platform. In addition, there are code samples, videos, learning labs and sandboxes available on Cisco DevNet that are intended to make easier to learn how to programmatically manage Cisco SD-WANs using open application programming interfaces (APIs).

    Cisco claims to now have 530,000 developers participating in DevNet. One the one hand, the company is trying to entice NetOps teams that have been reluctant to give up legacy command line interfaces to modernize their networking environments. On the other hand, Cisco is trying to attract more application developers who increasingly find themselves encountering latency issues as they move to deploy applications in highly distributed computing environments, such as an Internet of Things (IoT) application.

    Over time, Cisco and other providers of network operating systems also will be moving away from monolithic architecture to embrace microservices, which would make it possible to programmatically invoke networking services on a more granular level.

    Of course, there may be some developers who would prefer to programmatically take control over networking along with the rest of the IT infrastructure. But Cisco is clearly betting most organizations will want to make it easier for their NetOps and DevOps teams to work more closely together. Today, most enterprise IT organizations can spin up a virtual machine in a matter of minutes; provisioning the network connections to that virtual machine, however, is still measured in days and weeks.

    Other networking infrastructure companies besides Cisco have realized the need to make networking more programmable. But in terms of the resources the company is making available to solve that problem, it would appear to ready to make a significantly larger commitment.

    — Mike Vizard

  • Boxes vs. Services: The Infrastructure Equation

    Boxes vs. Services: The Infrastructure Equation

    Infrastructure is changing as more services replace the need for hardware-based architectures

    There has been a lot of change in the last few years, and that change shows no sign of slowing down. I’m one of those people who likes to know they could work offline if needed, yet in this day and age if you want me to install a fat client on my laptop, I go looking at your competition.

    Granted, for me the selection of these apps is small—I like having Office on my desktop to be able to use it to write or create presentations at will, regardless of whether I’m connected—but for most people, it is growing at a faster pace. The idea of buying a monolithic system that you have to install and maintain is becoming less and less appealing.

    That same syndrome is occurring in the data center, too, but with a twist. It is largely infrastructure that is feeling this pinch. Just prior to cloud/container mania, the idea was that each non-compute box in your infrastructure was a platform. It offered you a ton of functionality, all designed to simultaneously lock you in and help you get your job done. All in all, it wasn’t a bad trade-off, and we can see the same idea in the large public cloud vendors.

    The difference is, with an infrastructure box, you were making a serious investment upfront that offered you other functionality to sweeten the deal. Once that investment was made, it was natural and realistic to want to take advantage of the bundled platform functionality rather than search for yet another box to drop in your network.

    Containers and what survived of software-defined networking (SDN) have changed all of that. The ability to quickly spin up something in software that fits your needs perfectly and can be automated with your DevOps toolchain makes the idea of a platform box—with its high cost of entry and bells and whistles you will never use but might have to lock down—seem quaint.

    In the agile/DevOps world, boxes for low-level infrastructure are still necessary. Don’t get me wrong on that. If you are a large org, you are using one of a few vendors to do core switching and routing. But top-level (layer 4-7 and 8) networking is not something you would use those static boxes for.

    It used to be that all networking functionality was the same—it needed to be rock-solid and slow to change to guarantee that apps were functional. Over the last few years we have seen a move from “all networking is networking” to “this is low-level stuff that must be rock-solid, that is closer to application layer stuff that we can change rapidly, and thus need not be in the ‘rock solid’ category.” Load balancing is a great example of this (and yeah, I used to work for F5, which is the king of load-balancing): Load balancing was a network function that you went to a hardware vendor for if you were beyond a certain size. The resulting physical box might serve one or 100 apps and required specialized training or experience to manage.

    Today, load balancers are a systems function that you go to a software vendor for and work into your network with as many copies of the software load balancing as you needed. Or you turn on load balancing within your container management system and manage it there. Either way, it fits in with your agile/DevOps environment better, and is easier to get budget for your project.

    I expect to see this change intensifying. There is power in physical boxes for some things, but there is also power in portability and packaged deployment scripts. And a physical box is not portable to a public cloud, nor is it readily dropped into container management tools (though container management integration is getting better in most network security/performance appliances). Portability and ease of use will win over technical edge, in my opinion. Not because people are cheap and lazy, but because portability is key to agility and they are too busy.

    There are still things that just aren’t that portable, and I have yet to see convincing tools to make them that portable. Data is my go-to example because it is easy. If you have 2TB of data, your portability options are limited. For those with 2PB of data, there is no real option; the app is going where ever the data is, and that data is unlikely to move. Oh, if you were motivated, there are ways to move that much data, but then you’ve just shifted the problem to the new platform, because the data is still largely non-portable, and apps will have to go where the data is. Again.

    But for most functionality? Anything that can be made into highly portable software will be. And that software will run wherever it is most needed or most beneficial to the user.

    All in all, this is a good result. Multi-core, multi-network, multi-terabytes of memory PCs can rival many appliances for speed and functionality, and portability plus ease of integration makes software a winner. Just stay aware of where/when a physical box still makes sense, because the world doesn’t change as fast as high-tech marketing wants you to believe. A working appliance that does what is needed quickly should not be ripped out just because a software solution is available.

    But you knew that. Because you all rock. Keep kicking it, and use whatever solution serves the business best—which is a different equation for every business.

    — Don Macvittie

  • NetOps vs. DevOps: New Data is Enlightening

    NetOps vs. DevOps: New Data is Enlightening

    Traditionally, we have seen development—and, by extension, DevOps—as having a less-than-cordial relationship with network operations (NetOps). Since the goals of the two groups are sometimes at cross purposes—DevOps wants access to make everything run automated, and NetOps wants to control a production environment so that it is stable—we’ve naturally talked in those terms.

    I’m a developer who learned other skills, including operations, along the way. I can manage to get things done on F5 Networks or Cisco Systems gear, but I’ve sat with true experts while they worked their magic and have a lot of respect for the NetOps crowd. So this topic has always been of interest to me.

    Now, according to a recent survey conducted by F5 Networks, we can see that the animosity we have all been lead to believe is there really isn’t. There is also a press release here, and surprisingly, it offers more information from the survey than the blog does.

    There is a ton of interesting data about rate of automation, views of other teams and deployments in the survey results, making it well worth a read-through.

    While DevOps and NetOps remain at odds regarding how much pipeline access should be available via self-service and automation, for the most part both groups view the other as on the right track. Eighty-two percent of DevOps and 76 percent of NetOps agree that each other prioritizes “the right things.” Clearly, there is common ground across the digital divide in at least goals and focus, if not always in the organizational chart.

    This, to me, says that DevOps is having the proper impact on the organization. That what’s important is getting prioritized on both sides of the pipeline. Or it says that this was always the case, and DevOps has had little impact. Historical surveys, however, seem to indicate that there was not always this level of belief between the two groups.

    Interestingly enough, there has been a lot written about whether your DevOps methodology should be operations- or development-driven, but networking has always been a bit off to the side. Not the type of operations that historically is discussed in DevOps; it sat with teams such as Security and QA working with DevOps but not generally a part of the DevOps teams.

    The results here would indicate that network automation is occurring at a healthy clip (makes a guy want to look at vendor APIs again, and see what’s changed to enable this fact), and if the majority of DevOps people are saying the NetOps team is focused on what’s important, likely the integration into DevOps is further along than pundits have portrayed.

    Though the results indicate that many DevOps teams want more access and control of network operations than they have, this is likely the natural outgrowth of the different views these teams have always had. Network operations’ goal is rock-solid infrastructure. DevOps’ goal is speedy delivery. These two things can be at odds relatively easily.

    I’m hoping that F5 offers us more access to data than a blog and a press release, but honestly what is in those two is enough to get you pondering about the state of NetDevOps (or whatever we’re calling it this week) versus the perception.

    Disclaimer: I am a former F5 employee, and have a positive view of the company and its products. My wife is also F5’s Principal Technical Evangelist, and had a hand in this survey. While this doesn’t impact writing about survey results, you’ve been informed.

    — Don Macvittie