Tag: Influxdata

  • InfluxData Makes Processing Observability Data at Scale More Efficient

    InfluxData Makes Processing Observability Data at Scale More Efficient

    InfluxData today made available an update to its open source time series database that can now analyze metric, event and trace data in a single datastore with unlimited cardinality in terms of how they are aggregated.

    The company is now making available a single-tenant instance of InfluxDB as a managed service alongside its already-existing multi-tenant cloud service that is based on a serverless architecture.

    Finally, InfluxData also announced that later this year it will make available InfluxDB 3.0 Clustered and InfluxDB 3.0 Edge to provide a curated version of the database that organizations can deploy themselves where they best see fit.

    InfluxData CEO Evan Kaplan said InfluxDB has been developed to support a wide range of emerging applications that require access to time series data, including the observability platforms core to DevOps workflows that require visibility into metrics, events and trace data.

    Over the past three years, InfluxDB has been revamped to run on a columnar engine, dubbed IOx, that leverages the open source Apache Arrow memory format and written in the Rust programming language. Kaplan said that approach makes it possible to continuously ingest, transform and analyze hundreds of millions of time series data points per second without limitations.

    At the same time, InfluxDB takes advantage of high compression object storage to reduce the total cost of storing all that data. It also provides interoperability with Open Data Architecture (ODA) to integrate with data lakes based on open source platforms such as DataFusion, Flight SQL and Parquet that are being advanced by the Apache Software Foundation.

    The arrival of version 3.0 of InfluxDB comes as many DevOps teams are starting to struggle with the amount of observability data being generated. DevOps teams want to be able to move beyond monitoring a set of pre-defined metrics and query data in a way that enables them to surface anomalies indicative of a potential issue before there is a major disruption to an application service.

    One of the major challenges today is the tradeoff between how much data is collected and analyzed versus the cost of processing and storing it. InfluxDB provides a mechanism for analyzing high cardinality data involving metrics, events and traces cost-effectively.

    Observability is, of course, only one of several use cases for a time series database capable of processing data in near-real-time. As organizations embrace digital business transformation initiatives, they need to be able to process data in near-real-time at the point where it is being created and consumed. Those applications won’t necessarily replace existing applications based on batch-oriented processing but, over time, they create two distinct classes of applications that process data in fundamentally different ways. The challenge, as always, will be defining the DevOps workflows required to manage applications running on multiple distinct types of architectures.

  • InfluxData Delivers Revamped Database for Real-Time Processing

    InfluxData Delivers Revamped Database for Real-Time Processing

    InfluxData has made good on a promise to deliver a next-generation time-series database that enables observability and monitoring tools used by DevOps teams to ingest high volumes of data more cost-efficiently.

    In addition, for the first time, the latest iteration of the InfluxDB database supports the de facto standard SQL query language. Developers can run unlimited time-series workloads and contextualize data by any dimension without restrictions using SQL or existing tools such as the InfluxDB application programming interface (API), Flux scripting language or the InfluxQL query language

    Brian Gilmore, director of internet-of-things (IoT) and emerging technologies for InfluxData, said InfluxDB is now based on a columnar engine, dubbed IOx, that leverages the open source Apache Arrow memory format and the Rust programming language accessed via a multi-tenant InfluxDB Cloud service that company manages on behalf of application developers. Use cases that require processing large volumes of data such as metrics, events, traces and other high cardinality data can now be queried in milliseconds, he noted.

    The goal is to make this latest incarnation of InfluxDB available via a managed cloud service before providing IT teams with a version they can install themselves.

    The arrival of a revamped InfluxDB architecture comes as the amount of data being generated across application environments continues to rapidly expand. Many DevOps teams are especially struggling with ways to process and store all the data being generated by cloud-native applications made up of microservices generating a steady stream of logs, metrics and traces.

    InfluxData, of course, has ambitions for its database that go beyond application development and deployment environments. Edge computing platforms, for example, will increasingly process and analyze data in real-time at the point where it is generated and consumed. Similarly, applications infused with machine and deep learning algorithms will require databases that can process data at scale. Regardless of the use case, however, it’s apparent more IT teams will be embracing DataOps best practices alongside DevOps to manage data as applications are deployed and continuously updated.

    It remains to be seen how many observability and monitoring tools might embrace this latest iteration of the InfluxDB database, but it’s clear DevOps teams should expect to see major advances as the underlying databases upon which these platforms depend continue to evolve. The goal is to ultimately eliminate the tradeoff that now often occurs between how much data is collected and analyzed versus the cost of processing and storing it.

    In the meantime, DevOps teams will need to decide whether they want to manage databases themselves as more managed services become easier to invoke in the age of the cloud. Most database selections these days are made by development teams that aren’t especially eager to take on the tasks normally performed by a database administrator. A managed service essentially outsources responsibility for managing a database to a services provider instead of requiring IT teams to hire a DBA themselves.

    One way or another, however, the speed at which data can now be processed in real-time should sharply reduce the need to rely on existing and cumbersome batch-oriented approaches to processing data.

  • InfluxData Announces InfluxDB Edge Data Replication

    New capabilities combine the power of cloud with the precision of the IoT edge to optimize time series data processing

    San Francisco, CA, June 15, 2022 – InfluxData, creator of the leading time series platform InfluxDB, today announced Edge Data Replication, a new capability for centralized business insights in widely distributed environments. Edge Data Replication enables developers to collect, store and analyze high-precision time series data in InfluxDB at the edge, while replicating all or subsets of this data into InfluxDB Cloud. With Edge Data Replication, InfluxData delivers on both platform breadth and simplicity, scaling time series data processing in a new way that embraces the precision of the edge and the power of the cloud.

    Modern applications are highly distributed across architectures and produce enormous volumes of time series data at the edge. Effectively managing the data in these applications and associated assets is a time-consuming, resource-intensive process, and developers often don’t have the capabilities or budgets to manage hundreds or thousands of data pipelines. InfluxDB Edge Data Replication changes the way developers and operators process time series data across distributed environments using a new edge database configuration that durably queues and mirrors select datasets to the cloud. The availability of Edge Data Replication marks a critical first step in InfluxData’s journey to solve key time series data integration and orchestration challenges for customers building distributed Industrial and Internet of Things (IoT) applications in energy, manufacturing, aerospace, and other high-tech industries.

    “Data has gravity, and much of it is created far from clouds and data centers. This pulls applications out to the edge, where the data is born and produces its greatest value. Unfortunately, most databases don’t acknowledge or respect these emerging hybrid edge-cloud environments,” said Rick Spencer, Vice President of Products, InfluxData. “Edge Data Replication sets a new benchmark for time series platforms by combining the power of cloud with the precision of the edge – a best of both worlds solution that’s key to tomorrow’s distributed applications.”

    According to Gartner®, “Enterprises are now employing machine learning models and computing at the edge in order to preprocess data rather than just migrating data to the cloud. Rather than one-way archiving, early adopters are doing multidirectional synchronization of data between edge, core data center and public cloud. Two-way synchronization allows enterprises to make use of the elastic nature of the compute infrastructure found among cloud service providers. Furthermore, with the upcoming expansion of edge computing, there will be a growing need for solutions that enable data workflow among edge, storage and multiple public cloud providers.”

    Unlock Centralized Business Insights with Edge Data Replication

    InfluxData’s Edge Data Replication creates a new and intuitive experience for developers building at the edge by allowing data from an InfluxDB instance to automatically replicate to InfluxDB Cloud with a simple configuration setting. By leveraging Edge Data Replication in tandem with the full power of the InfluxDB platform, including Flux, InfluxDB’s native data scripting language, users can: Integrate edge and cloud DataOps: Connect edge and cloud workloads to automatically mirror data from InfluxDB edge sources to InfluxDB Cloud instances in real-time.

    • Reduce cloud ingress and egress costs: Filter and aggregate data intelligently from InfluxDB at the edge before replicating it to InfluxDB Cloud. Downsampling data with Edge Data Replication delivers faster processing and reduced transfer costs.
    • Transform data before transfer: Dynamically add context to edge data that is needed for processing in the cloud. Cloud processing may require extra dimensions to query on or feature engineering.
    • Enforce edge/cloud consistency: Withstand planned and unplanned disruptions in network connectivity by queueing data at the edge until it can be safely transferred to the cloud.
    • Full data workflow at the edge: Full support for applications at the edge by enabling data preprocessing close to the data sources.

    “Loft Orbital’s mission is to deliver space infrastructure as a service to give our customers rapid access to space,” said Caleb MacLachlan, Head of Software Integration, Loft Orbital. “Our network edge extends onto our spacecraft in low Earth orbit, requiring real-time access to highly distributed mission-critical data. With Edge Data Replication, it’s easier than ever for us to centralize our time series data while ensuring we don’t lose data from edge storage locations.”

    “Every year there are 10 times more IoT edge devices deployed. Developers know that expectations for consistency, efficiency, and reliability are growing at a similar rate,” said Rick Spencer, InfluxData. “With this kind of scale, IoT developers need excellence in local operations, taking advantage of granular data for real-time insights and control, while also having a centralized view across all of the edge operations, sometimes at an enormous scale. The combination of Edge Data Replication, InfluxDB at the edge, and InfluxDB Cloud makes building such IoT applications not only possible, but also incredibly simple.”

    Edge Data Replication is available immediately for InfluxDB users. For more information to get started, visit the InfluxData website.

    Gartner, “Market Guide for Hybrid Cloud Storage,” Julia Palmer, Raj Bala, 3 May 2021. GARTNER is a registered trademark and service mark of Gartner, Inc. and/or its affiliates in the U.S. and internationally and is used herein with permission. All rights reserved.

    About InfluxData

    InfluxData is the creator of InfluxDB, the leading time series platform. We empower developers and organizations, such as Cisco, IBM, Siemens and Tesla, to build real-time IoT, analytics and cloud applications with time-stamped data. Our technology is purpose-built to handle the massive volumes of data produced by sensors, systems or applications that change over time. Easy to start and scale, InfluxDB gives developers time to focus on the features and functionalities that give their apps a competitive edge. InfluxData is headquartered in San Francisco, with a workforce distributed worldwide. For more information, visit www.influxdata.com.

  • InfluxData Launches InfluxDB University

    San Francisco, CA, March 9, 2022 – InfluxData, creator of the leading time series platform InfluxDB, today announced the launch of InfluxDB University (InfluxDB U), an online education platform for customers and developers working with time series data. InfluxDB University focuses on giving developers the technical skills they need to build applications with InfluxDB through both on-demand and live instructor-led courses taught by InfluxData and industry experts. Courses on InfluxDB University are available today at no cost.

    “We think about the developer first in everything we do, ensuring they have the tools and resources needed to build and integrate applications with time series data,” said Brian Mullen, Chief Marketing Officer, InfluxData. “We meet developers where they are on the learning curve. Whether they’re brand new to InfluxDB or an advanced builder of time series applications, every developer can easily find the path and course work that is most relevant and most attuned to their individual journey.”

    The launch of InfluxDB University reinforces InfluxData’s commitment to delivering faster Time to Awesome™ to developers building applications with InfluxDB. Delivered through an intuitive learning platform, InfluxDB University courses offer technical resources and teach best practices to reduce the time and effort to build real-time applications. Participants can choose weekly trainings and workshops, led by qualified instructors who answer questions live during sessions. Alternatively, participants can select on-demand, self-paced courses if they prefer an independent learning experience.

    “InfluxDB University eliminates many of the common barriers to application building with time series data, which reinforces InfluxData’s commitment to developer happiness,” said Dr. Angelo Fausti, Software Engineer, Vera C. Rubin Observatory. “There’s a wealth of knowledge in these courses, and InfluxData is a true partner committed to ensuring we have the skills we need to be successful.”

    “InfluxData supports developers wherever they are in their time series journey,” said Jamie Milton, Senior Analytics Consultant, Fort Digital. “As a partner, we are excited to have InfluxDB University as a resource to continue to educate and support our customers to adopt best practices and get the most out of their time series data.”

    InfluxDB University is now live with introductory courses covering key elements of the platform, including InfluxDB Cloud, Telegraf and the Flux querying language. Additional courses cover more advanced topics around InfluxDB Enterprise and building IoT applications with InfluxDB. InfluxData will continue to add new courses and expand course content as new products and features are added to InfluxDB.

    To get started with InfluxDB University, visit www.influxdbu.com. For more information about how developers and organizations are using InfluxDB, visit the InfluxData website or sign up for a free cloud trial. To join the InfluxDB community, visit the InfluxData Community Slack channel.

    About InfluxData
    InfluxData is the creator of InfluxDB, the leading time series platform. We empower developers and organizations, such as Cisco, IBM, Siemens and Tesla, to build real-time IoT, analytics and cloud applications with time-stamped data. Our technology is purpose-built to handle the massive volumes of data produced by sensors, systems or applications that change over time. Easy to start and scale, InfluxDB gives developers time to focus on the features and functionalities that give their apps a competitive edge. InfluxData is headquartered in San Francisco, with a workforce distributed worldwide. For more information, visit www.influxdata.com.

  • InfluxData Simplifies AppDev for Time-Series Databases

    InfluxData Simplifies AppDev for Time-Series Databases

    During an online InfluxDays North America 2021 Virtual Experience conference, InfluxData today expanded the capabilities of its application development tools using its Flux query language on top of its time-series database.

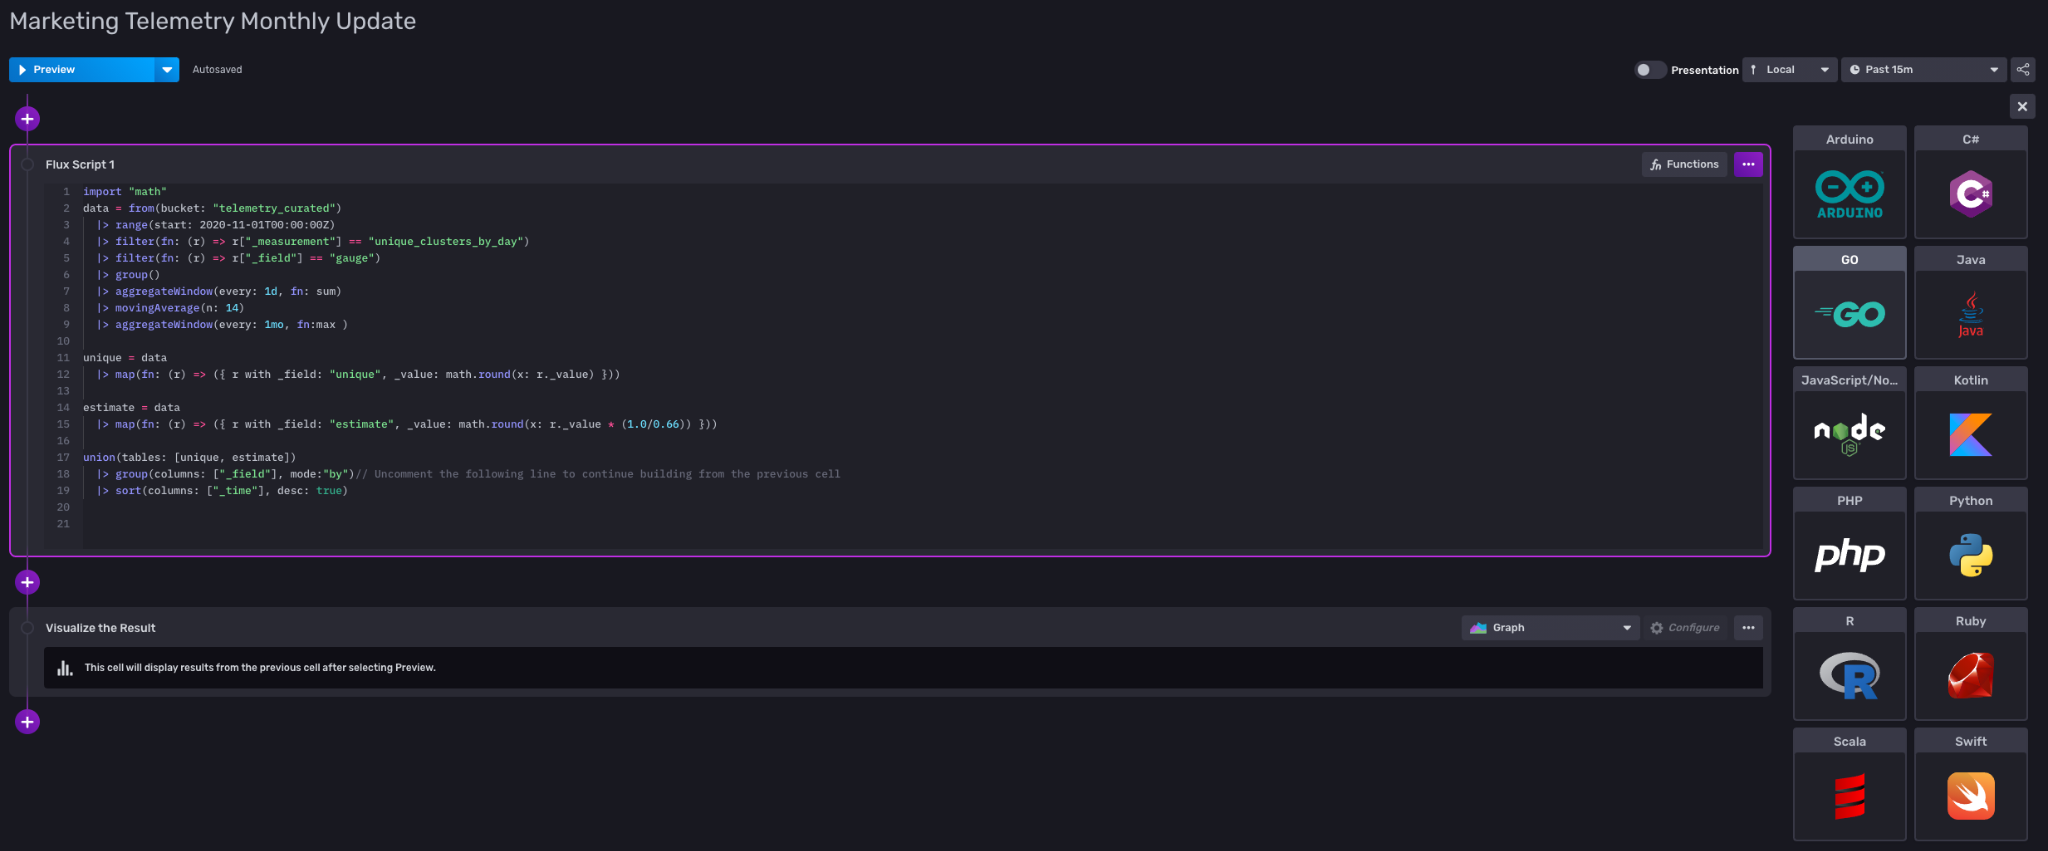
    The company has enhanced its InfluxDB Notebooks tool to enable developers to quickly set up an alert, build a task or write a Flux script without having to leave their browser.

    In addition, developers can compose Flux queries to be included in client code that can then be autogenerated within applications written in more than 10 different programming languages. There is now also an extension of Visual Studio Code that makes it simpler to create Flux scripts, query InfluxDB, create Flux tasks and manage buckets.

    Finally, InfluxData added the ability to explicitly define the schema of a bucket within InfluxDB to safeguard against unwanted changes; an application programming interface (API) tool, dubbed API Invocable Scripts, to make it simpler to define parameterized Flux scripts and the ability to send notifications from Alerta, WebEx Teams and ServiceNow to the InfluxDB Cloud platform.

    Tim Hall, vice president of product for InfluxData, said the overall goal is to reduce the level of complexity developers encounter when building applications that run on a time-series database. Many of those applications are now core to digital business transformation initiatives that require data to processed and analyzed over time. In effect, time-stamped data adds yet another dimension to any application, noted Hall.

    Time-series databases are typically employed by either an independent software vendor (ISV) to create, for example, a monitoring application, or an enterprise IT team that is building an application that lends itself to data that needs to be tracked over some period of time.

    In most instances, applications built on a time-series database are being deployed alongside, for example, relational databases that are generally invoked using SQL. As a result, InfluxDB has made it simpler to join data across relational and time-series data via SQL integrations the company added to Flux, noted Hall.

    DevOps teams, of course, are not always anxious to add another database they need to support, but as applications continue to evolve, more organizations are employing a mix of purpose-built databases to develop applications as the volume of data that organizations are trying to manage and analyze continues to grow.

    In the longer term, it’s clear time-series databases will play a critical role in driving digital business transformation initiatives. The challenge most organizations are now struggling with is determining which of these initiatives to prioritize. A time-series database coupled with the developer tools provided by InfluxData will enable IT teams to build the applications that drive those processes much faster, said Hall.

    In the meantime, IT teams would be well advised to at least become more familiar with time-series databases, because knowing the time when an event occurred is becoming a bigger application requirement. After all, knowing when something happened is now just as important as the record of what actually occurred.

  • InfluxData releases InfluxDB Notebooks to enhance collaboration for teams working with time series data

    SAN FRANCISCO — April 14, 2021 — InfluxData, creator of the leading time series database InfluxDB, today announced the general availability of InfluxDB Notebooks, a new capability that improves communication for software development teams, ultimately enhancing productivity within InfluxDB Cloud. InfluxDB Notebooks is the first of the company’s new capabilities designed to make it easier for developers to collaborate around time series data within the platform.

    Developers rarely work alone; they almost always work in teams. One of the challenges of working together is communication — developers need seamless communication to streamline their development activities. InfluxDB Notebooks addresses this challenge by allowing developers to discuss time series data analyses and trends inside the platform rather than switching conversations to third-party messaging applications, which can slow them down significantly. This new capability allows users to create a durable artifact that shows teams how time series data is analyzed to solve business problems.

    “Development teams are more distributed than ever, but until now, they haven’t had the tools they need to seamlessly communicate around time series data,” said Russ Savage, director of product management at InfluxData. “To solve this problem, we’ve reimagined InfluxDB as a way to collaborate around data, not just store it. This new approach will dramatically save time for developers, so they can focus on building software.”

    With InfluxDB Notebooks, developer teams can quickly:

    • Design time series data pipelines with dynamic data, live code, and real-time visualizations — all with inline explanatory notes — effectively showing their work and sharing it with others
    • Share incident investigations to explain root cause following service outages, and build runbooks to avoid future outages
    • Document how IoT sensor data has been collected, normalized, enriched and downsampled to facilitate preventive maintenance and forecast device obsolescence

    InfluxDB Annotations will soon follow InfluxDB Notebooks and is another new capability that enables adding notes directly on dashboard cells to more quickly highlight and explain the meaning of anomalies in time series data and coordinate troubleshooting efforts. It will be used to capture context and share details about ongoing investigations into outlier data points that are underway. This will save teams time by eliminating the need for multiple people to repeat the same investigation.

    These new capabilities support better collaboration workflows between developers, SREs, and every stakeholder involved in time series collection, enrichment, and analysis. InfluxDB Notebooks lets teams weave together computational information such as code, data and statistics with narrative, and graphs, while InfluxDB Annotations helps developers share contextual clues so they can quickly determine the root cause of incidents and restore services faster.

    For more information about InfluxDB Notebooks, see the product documentation page and watch our Notebook Concepts video.

  • InfluxData advances possibilities of time series data with general availability of InfluxDB 2.0

    The leading open source software features enhanced IoT and edge capabilities & company launches new project for innovative storage engine

    SAN FRANCISCO — InfluxData, creator of the time series database InfluxDB, today announced the general availability of the next-generation open source platform for time series data, InfluxDB 2.0. Developers can now ingest, query, store and visualize time series data in a single unified platform, leverage new tools and integrations, and use familiar skills — making it faster and easier than ever to develop and deploy modern time-based applications. In addition, the company announced a new open source project to reimagine storage.

    The amount of data being produced is expected to grow exponentially from 45 zettabytes in 2019 to 175ZB in 2025, primarily from applications, networks, containers, and a projected 60 billion IoT devices — and most of this is time-stamped data (IDC, 2020). While there is a tremendous opportunity for organizations to leverage this data to enhance customer experiences, improve employee and process productivity, and to create competitive advantage, it will be challenging to store and analyze the large volumes and high-frequency streams of data. These workloads will require rapid ingestion, advanced querying, and edge processing to maintain resource and cost efficiency, and maximize the value to end users. InfluxDB 2.0 is built to handle these data challenges of the future.

    InfluxDB 2.0 is a time series platform for building IoT, analytics and monitoring applications powered by time series data. New features in InfluxDB 2.0 are designed to reduce the amount of time developers spend writing code to get started and manage existing projects, including:

    • Flux – the first functional query and programming language built specifically for time series data, which makes it possible to enrich and transform data, build forecasts, and identify anomalies and correlations

    • InfluxDB Templates – a growing gallery of single-file monitoring configurations for common use cases, like network and IoT sensor monitoring, that allow users to share their expertise and get up and monitoring in minutes

    • Edge functionality – able to aggregate and analyze time series data at the point of ingestion, where it’s most valuable to take action

    • Client libraries – support for writing and querying from popular languages, dramatically easing integration with other applications and empowering teams to use existing programming language skills

    InfluxDB 2.0 is also tightly integrated with InfluxDB Cloud, the serverless, elastically scalable, fully managed time series database platform. With a shared API, it’s easy to move data and workloads between InfluxDB 2.0 and InfluxDB Cloud, and powerful to use them together as components of a single time series platform designed to give developers the flexibility and tools to meet changing business and application requirements.

    “Developers today are looking for open source software, delivered as a managed service,” said James Governor, RedMonk co-founder. “InfluxDB 2.0 responds to this convergence with an integrated OSS, edge and cloud services play designed to make it easier to build and manage high-scale time series-based applications.”

    The company also unveiled plans for the next-generation storage engine — project InfluxDB I0x. InfluxDB I0x is a new powerful storage engine designed to execute increasing query workloads over time. InfluxDB I0x lifts restrictions on cardinality, data size and cluster size that are inherent in the open source version of InfluxDB 2.0 — expanding the possibilities for workloads across thousands of servers and petabytes of data — a significant jump from current and other product allowances. Most time series solutions are designed around a rigid database structure, which limits the ability to work with high- cardinality data, but InfluxDB I0x separates storage from compute by using object storage as the durability layer and a management layer to control many stateless query, ingest, and indexing servers running ephemerally in Kubernetes. It also significantly broadens the InfluxDB ecosystem using industry-standard protocols and persistence, like Apache Arrow Flight and Apache Parquet. The InfluxDB I0x project expands the permissiveness of open source and is dual-licensed with MIT and Apache 2.0 to emphasize InfluxData’s commitment to pure open source. Dix opened the InfluxDB I0x project codebase repository during his talk at InfluxDays North America and now welcomes comments.

    “We’re driven by our commitment to developer productivity and are eager for our community to start using InfluxDB 2.0 so they can start doing more with time series data,” said Paul Dix, CTO and founder of InfluxData. ”But InfluxDB 2.0 is just the start of our journey. We want developers to build awesome apps with our open source software, uninhibited by licensing restrictions and limitations.”

    InfluxDB 2.0 is MIT License permissive — one of the most liberal open source licenses. InfluxDB 2.0 is the successor to InfluxDB 1.0, which was made generally available in September 2016. Over the last four years, there have been millions of downloads of the open source software and there are currently more than 400,000 daily active instances around the world.

    It’s quick and easy to get started with InfluxDB 2.0. For existing InfluxDB users, it’s a seamless upgrade from 1.x versions that can be done by downloading InfluxDB 2.0 and running a single command to transfer data. New users can get started by downloading and installing InfluxDB 2.0, and can be collecting time series data in under one minute.

    About InfluxData
    InfluxData is the creator of InfluxDB, the leading time series platform. We empower developers and organizations, such as Cisco, IBM, Lego, Siemens, and Tesla, to build transformative IoT, analytics and monitoring applications. Our technology is purpose-built to handle the massive volumes of time-stamped data produced by sensors, applications and computer infrastructure. Easy to start and scale, InfluxDB gives developers time to focus on the features and functionalities that give their apps a competitive edge. InfluxData is headquartered in San Francisco with a workforce distributed throughout the U.S. and across Europe. For more information, visit www.influxdata.com and follow us @InfluxDB.

  • InfluxDB Cloud extends to Microsoft Azure Cloud — now available on all major cloud platforms

    InfluxData looks to accelerate IoT application development with PTC through strategic product integration


    SAN FRANCISCO — July 22, 2020 — InfluxData, creator of the time series database InfluxDB, today announced that InfluxDB Cloud is now available on Microsoft Azure, furthering the company’s commitment to increase accessibility to developers. With this announcement, InfluxDB Cloud is now live on all three major cloud platforms — Microsoft Azure, Google Cloud and Amazon Web Services. In addition, InfluxDB will become the time series engine for PTC’s market-leading ThingWorx® Industrial IoT (IIoT) platform.

    “InfluxDB Cloud empowers developers to derive new insights from their data, and with usage-based pricing, ensures they never have to worry about added costs of overprovisioning or risk their application being unavailable when they need it,” explained Evan Kaplan, CEO of InfluxData. “The addition of Microsoft Azure, one of the dominant cloud platforms, has further extended the global reach of our cloud offering. Alongside our strategic alliance with PTC, we have created a comprehensive marketplace that provides developers with the fastest time to results. With InfluxDB Cloud, developers can get up and running in minutes and easily scale their IoT or DevOps projects as needed on the cloud of their choice.”

    InfluxDB Cloud now available on all major cloud platforms 

    The recent and sudden transition to remote working has accelerated moves to the cloud, with business leaders increasingly looking to cloud services to support digital transformation. This comes at a time when many companies — aware of vendor lock-in and keen to abstract their applications so they can be moved across clouds — are trending towards multi-cloud strategies. Now available across all major cloud platforms, InfluxDB Cloud has been built from the ground up as cloud-native, running as a stateful application on Kubernetes. This makes it the first and only serverless time series data platform with flexible and transparent usage-based pricing and a free tier to broaden access to all developers.

    “Two major areas of growth for companies today are time series databases and cloud deployment. The deployment of InfluxDB Cloud on Microsoft Azure provides an ideal environment for customers to develop and run their applications,” said Ayelet Steinitz, Head of Global Strategic Alliances at Microsoft. “Organizations can accelerate the roll-out of applications and benefit from unified billing and support, and integrations with key Microsoft Azure technologies.”

    InfluxData & PTC working to accelerate IIoT solution development

    InfluxData’s collaboration with PTC is designed to help companies accelerate the development of IIoT solutions. InfluxDB Cloud will be sold, delivered, and supported directly by PTC, for deployments of ThingWorx hosted in PTC’s cloud environment. PTC has deeply integrated its ThingWorx platform with Microsoft Azure, its preferred cloud platform for the industrial sector.

    “We believe that speed of development and deployment will be critical in rolling out new IIoT solutions,” said Chris Baldwin, Vice President of ThingWorx Product Management at PTC. “By embedding InfluxDB into ThingWorx, InfluxData and PTC aim to simplify and accelerate developers’ ability to collect, process, store and analyze even larger time series data workloads in multiple areas of their IIoT deployment.”

    Embedding InfluxDB into ThingWorx will enable customers to generate data insights from tens of thousands of internet-connected devices and sensors, each with a multitude of measurements, and generating hundreds of thousands of writes per second.

    About InfluxData
    InfluxData is the creator of InfluxDB, the open source time series database. Our technology is purpose-built to handle the massive volumes of time-stamped data produced by IoT devices, applications, networks, containers and computers. We are on a mission to help developers and organizations, such as Cisco, IBM, Lego, Siemens, and Tesla, store and analyze real-time data, empowering them to build transformative monitoring, analytics, and IoT applications quicker and to scale. InfluxData is headquartered in San Francisco with a workforce distributed throughout the U.S. and across Europe. For more information, visit www.influxdata.com and follow us @InfluxDB.


  • Time Series Virtual Summit Speaker Spotlight: Jon Herlocker and Miroslav Malecha

    Time Series Virtual Summit Speaker Spotlight: Jon Herlocker and Miroslav Malecha

    The Time Series Virtual Summit will bring together InfluxData community members for a unique learning experience focused on the impact of time series data. Presented in a virtual reality environment, the event will take place on July 16, at 10 a.m. EDT.

    Miroslav Malecha
    Jon Herlocker

    Jon Herlocker, president and CEO at Tignis, is one of the speakers that will be presenting at the Time Series Virtual Summit.

    Jon invites anybody who has the responsibility to turn large quantities of sensor data from physical plants or manufacturing lines into business value to attend his session, “How an Analytics Platform Detects Reliability Threats and Eliminates Obstacles Impeding Results Using InfluxDB.”

    “Viewers will see Tignis’ unique physics-driven approach to machine learning for physical plants and manufacturing lines,” said Jon. “We’ll also share our approach to using InfluxDB to accelerate delivery of our solution to our customers.”

    Jon will discuss how Tignis uses IoT sensors to reduce unexpected downtime at manufacturing plants and school campuses. Attendees will learn how by using a time series database they can improve their competitive advantage and accelerate their go-to-market strategy.

    “Time series data from physical plants and manufacturing lines can be turned into significant business value, and we have proven that InfluxDB can be an effective component of that,” said Jon.

    Another time series specialist that will be sharing his knowledge and his experience with InfluxDB is Miroslav Malecha, director of product management at Bonitoo.

    In his session, “Using Time Series for Geo-Temporal Analysis,” Miroslav will discuss how to use InfluxDB’s Flux for Geo-Temporal analysis. He’ll briefly cover what Flux is, how to use specific Flux geo functions and finish with a quick demo of how to use InfluxDB.

    You can hear from Jon, Miroslav and more time series experts at the Time Series Virtual Summit. To check out the agenda, the full lineup of speakers and to register (for free), visit the Time Series Virtual Summit website.

  • Time Series Virtual Summit Speaker Spotlight: Al Sargent and Samantha Wang

    Time Series Virtual Summit Speaker Spotlight: Al Sargent and Samantha Wang

    The Time Series Virtual Summit will bring together InfluxData community members for a unique learning experience focused on the impact of time series data. Presented in a virtual reality environment, the event will take place on July 16, at 10 a.m. EDT.

    Samantha Wang
    Al Sargent

    Al Sargent and Samantha Wang of InfluxData are on a mission to help developers understand how time series databases provide real-time observability and monitoring.

    “The best software engineering teams in the world understand that time series data is different; it can’t be managed using a traditional database, and requires a purpose-built database,” said Al Sargent, senior director of product marketing at InfluxData.

    Al will be the first speaker to take the virtual stage at the Time Series Virtual Summit. During his presentation, he will explore the unique challenges of managing time-series data, why time series data needs to be treated differently than other data types and what to look for in a time series database.

    Any developer that’s building applications using time series data (or planning to), such as data from IoT sensors, monitoring data or customer usage data will benefit from Al’s educational session.

    Another great session you must definitely attend is “Monitor your Cloud Metrics with Time Series” by Samantha Wang, product manager at InfluxData.

    Samantha will discuss the importance of time series data for cloud monitoring, and how you can view your metrics in real time with InfluxDB Cloud.

    “I will walk through how to write metrics into InfluxDB Cloud using Telegraf and how users can take their analysis one step further with Flux,” said Samantha. “Lastly, I will review InfluxDB Templates, one of our newest community InfluxDB products, that provides a packaged solution for various common monitoring use cases.”

    Join Al and Samantha to learn more about time series databases and understand how InfluxDB Cloud can be your end-to-end solution for writing data to monitoring and alerting — all optimized for time series data.

    You can hear from Al, Samantha and more time series experts at the Time Series Virtual Summit. To check out the agenda, the full lineup of speakers and to register (for free), visit the Time Series Virtual Summit website.